

I’m Adam Conway, an Irish technology fanatic with a BSc in Computer Science and I'm XDA’s Lead Technical Editor. My Bachelor’s thesis was conducted on the viability of benchmarking the non-functional elements of Android apps and smartphones such as performance, and I’ve been working in the tech industry in some way or another since 2017.
In my spare time, you’ll probably find me playing Counter-Strike or VALORANT, and you can reach out to me at adam@xda-developers.com, on Twitter as @AdamConwayIE, on Instagram as AdamConwayIE, or u/AdamConwayIE on Reddit.
Sign in to your XDA account
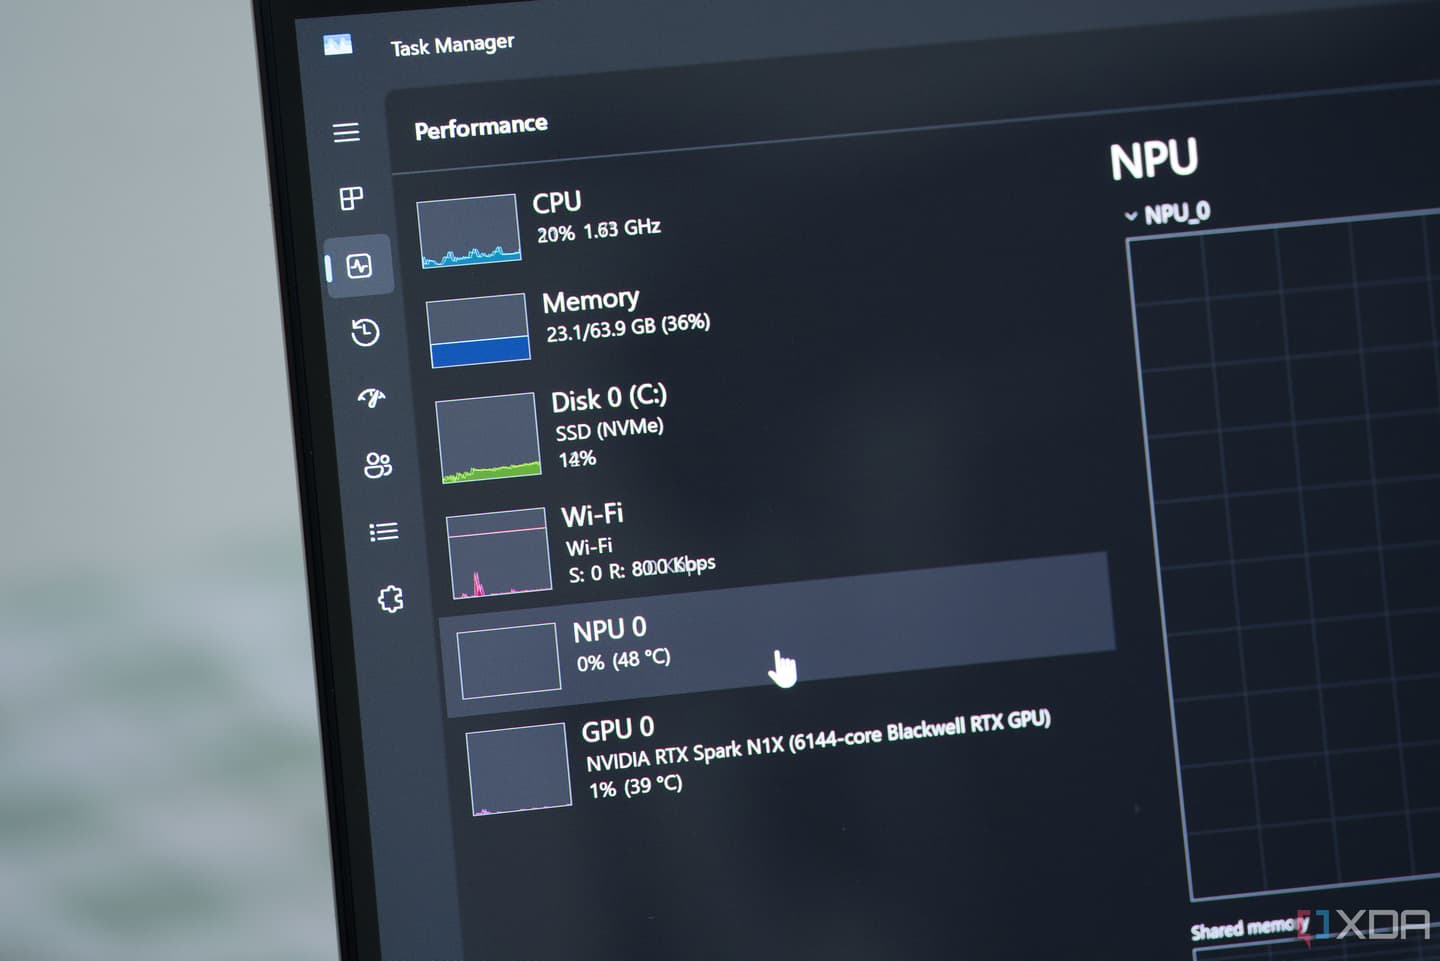
I'd previously run Cyberpunk 2077 on Lenovo's ThinkStation PGX, and when the RTX Spark was announced, I described it as the same GB10 hardware Nvidia already sells in the DGX Spark, just running Windows. However, the HP OmniBook Ultra 16 I've been testing has something that GB10 doesn't appear to have: an NPU.
Nvidia has said very little about the NPU in RTX Spark. German publication ComputerBase managed to siphon some details at Nvidia's San Francisco event, where the company revealed that it's a 55 TOPS accelerator intended solely for Copilot+ features. While Windows lists it in Task Manager and Device Manager, third-party software can't access it through the normal interfaces. Aside from that and Nvidia's own block diagram, there's very little public information to go off of.
I spent about a week going through firmware, drivers, and Nvidia's developer tools to understand what this NPU actually was. Initially, I suspected it was just a virtual device exposing the GPU to Windows for Copilot+ certification, but that's not what I found. It has its own registers, clock, and power rail, and the evidence points to a descendant of Nvidia's Deep Learning Accelerator (DLA) architecture, complete with RISC-V processors.
I eventually got real neural networks running on the NPU with correct results, and proved that the GPU wasn't secretly doing the work. After that, I was able to get it running in INT8 as well, which is a mode that Nvidia says this platform doesn’t support. It runs a full ResNet-50 correctly in INT8, but it isn't any faster than FP16, which is part of what makes the NPU so strange. Getting to this position required piecing together Nvidia's beta development tools, and the investigation led me back to GB10. Its firmware contains references to a DLA that Linux can't see, raising another question: is the hardware actually missing, or is it simply disabled?
Windows sees the NPU as its own device
Nvidia's driver calls it something else

Unfortunately, the Device Manager doesn't really help when it comes to figuring out what exactly the NPU in the RTX Spark is. For starters, a simple "NVIDIA NPU" entry shows up alongside the RTX Spark GPU in the Device Manager, rather than under "Neural processors" in the case of other NPUs. What's more, both devices use Nvidia's nvlddmkm driver, which made me wonder whether Nvidia was just using a Tensor core or set of Tensor cores in order to fulfill Microsoft's NPU requirement for Copilot+. In reality, Nvidia's driver simply handles the NPU as a separate adapter, and HP's firmware contains a "DLA Support" setting and ACPI logic for hiding the NPU from Windows.
Looking at the firmware, though, turned out to be significantly more helpful. HP's ACPI tables define a device called DLA0 with two memory-mapped register windows of its own: 256 KiB at 0x19000000 and 64 KiB at 0x31380000, plus a pair of interrupts. The primary window sits among the SoC's other peripherals, just below the audio DSP cluster, while the GPU is a separate PCI device mapped from 0x24000000 to 0x27FFFFFF. Nvidia's own block diagram places the DLA/NPU on the RTX Spark's SoC die alongside the display, camera, and audio blocks, with the GPU on a separate die connected over Nvidia's C2C link.

Interestingly, the firmware says that the NPU's memory access is cache-coherent with the CPU, and Windows shows it as being behind the IOMMU. The driver also reveals the device as an "NVIDIA NPU", internally referred to as "NVIDIA_DEV.DLA", and the file lists six DLA hardware revisions, suggesting the block is intended for multiple chips.
We can see a similar story from nvidia-smi, although it counts the NPU as a second GPU. Querying the device specifically sees the NPU identify its own brand as "NPU" with an architecture called "NPU3" and a UUID beginning with "DLA-." It also has an independent clock domain that idles at 430 MHz and tops out at 1,562 MHz, while also reporting its own separate power consumption.
Windows clearly treats it differently to a regular GPU, too. Its driver uses MCDM, the compute-only version of Windows' display driver model intended for accelerators without display output. DXCore identifies it as NPU hardware, and Windows' scheduler assigns it a single engine called NPU_0. It also refuses compute shaders, and reports support for machine learning rather than general-purpose compute.
All of this was deeply interesting, but it didn't prove that there was a physical NPU in silicon that was performing its own computations. After all, it still could have just been a front end that hands work to the GPU. To rule that out, I needed to run something on it.
Running code on the NPU means assembling Nvidia's beta tools by hand
None of it is available out of the box

Nvidia's retail driver includes cuDLA, the API Nvidia uses for its Jetson accelerators. It detects one DLA device with hardware version 2, the generation used in Jetson Orin. However, only hybrid mode works, meaning that every DLA task must be submitted through a CUDA stream on the GPU, and cuDLA's standalone mode simply said it was an "unsupported operation" every time I tried to use it. I had enough to communicate with the hardware, but running anything requires a compiled network, and the only way to build something for the DLA was to use TensorRT.
Thankfully, Nvidia's TensorRT 11.4 restored DLA support exclusively for Windows on Arm, though it's currently in beta. Jetson, DriveOS, and Linux SBSA deployments aren't supported here, and the DGX Spark is a Linux SBSA device.
There are quite a few restrictions with this version of TensorRT, too. For starters, every layer has to run on the DLA without GPU fallback, the batch size is fixed at one, shapes must be static, and computation only uses FP16. What's more, Nvidia warns that engines built with this release may need rebuilding once DLA support reaches general availability. So if you build something for the RTX Spark's NPU right now, it might not work in the future. As it turns out, INT8 does work if you go around TensorRT, though it doesn't help as much as you'd think, which we'll get to.
At first, I looked to use the pip version of TensorRT, but it detected zero DLA cores because it couldn't find cudla.dll. After some brief testing with a shim to try and get it working, I discovered that the official Windows on Arm DLL was already published by Nvidia, referenced in the CUDA 13.4 release notes. After that, the final missing piece was nvdla_compiler.dll, the DLA compiler itself. I eventually tracked this down to the Windows on Arm TensorRT Enterprise version, and with that, I was ready to go.
My first test was deliberately simple: four 3*3 convolution layers with ReLU, compiled in FP16 for the DLA alone. TensorRT produced a 3.1 MB "loadable," which is a binary compiled for the DLA. Running it meant loading that into cuDLA, registering CUDA input and output buffers for the DLA to access, and submitting the task through a CUDA stream.
To my surprise, it actually worked. My network ran at approximately 550 inferences per second, with results matching my NumPy reference to within 0.057%. I'd successfully executed a neural network through the DLA, but the most important part that I needed to establish was whether the GPU was doing the actual computation.
The GPU isn't doing the NPU's work
I made sure that it's a real NPU

I monitored both the GPU and the NPU while the DLA ran the network on a loop. NPU_0 reached 76% utilization at 1,053 MHz, while the GPU stayed totally idle. For comparison, a simple FP32 loop on the GPU saw its usage spike to 96% while drawing 49 W of power, so if the GPU's shader cores were performing those convolutions, I'd definitely know.
One other part of how this NPU works in Windows had me questioning the original theory I had regarding what this thing actually is, and that was the Task Manager. When running my tests, its GPU "3D" graph jumped to 99% utilization (thereabouts) while the NPU performed its convolutions. As it turns out, hybrid mode keeps the GPU's CUDA queue occupied while it waits for the DLA to finish, and I could see that the NPU's usage also spiked up at the same time. It's just that Task Manager reports hybrid mode's occupancy as utilization, even though the GPU isn't actually doing much at all.
What dictates the 3D usage depends on how the work is sent, too. My small test network sends the NPU around 550 short tasks a second and sees 3D utilization reach 100%, but a larger network that sends fewer, longer tasks left it at just 16% while the NPU sat at 86%. It doesn't get in the way of other CUDA work, either. I ran a separate process that launched a basic CUDA kernel every 5 ms, and its median latency was 0.15 ms while ResNet-50 ran on the DLA, compared with 0.18 ms with the DLA idle.

My final test sought to rule out my Tensor Core theory, so I wrote a Tensor Core matrix multiplication instruction loop that achieved 95.2 TFLOPS on its own, before running it at the same time as the DLA in a shared CUDA context, with GPU utilization at roughly 91%.
Run together, the Tensor Core benchmark reached 99.1 TFLOPS, while DLA throughput increased slightly from 590.7 to 611.2 inferences per second. Neither workload lost performance (and those small gains are just run-to-run variance), which basically proved that the DLA has its own compute hardware and only relies on the GPU for hybrid-mode scheduling.
At this point, now that I'd established it was a real NPU, I decided to put it through its paces.
It's faster than the CPU, but it isn't more efficient than the GPU
Not in FP16, and not in INT8 either

To measure peak throughput, I built a heavier benchmark with eight 3*3 convolutions at 256 channels. The DLA achieved approximately 5.2 TFLOPS in FP16 at an average clock of 1.47 GHz, drawing between 2.5 W and 3 W. In a later run, the clock peaked at 1,561 MHz with a throughput of 5.6 TFLOPS. Whether I used structured 2:4 sparse weights or not provided no speedup in FP16, and the biggest factor turned out to be how much work goes into each DLA task. A single layer per task managed only around 2.5 TFLOPS, while chaining 32 3*3 convolutions into one task reached 6.07 TFLOPS, which is the most I could get out of it in FP16. Adding more layers beyond that didn't help.
INT8 is presumably where Nvidia's advertised TOPS figure comes from, but Nvidia says INT8 is supported as a quantization format while computation remains in FP16. Pure INT8 compute isn't supported on this platform, so it's unclear how this 55 TOPS figure is actually reached. With that said, the hardware will actually run INT8 if you work around TensorRT, but I'll come back to that after the FP16 results, because what it does with it is the strangest aspect of the entire NPU.
Next, I wanted to test some real models, so I tried both MobileNetV2 and ResNet-50 from the ONNX Model Zoo. Neither compiled for the DLA without modification. I had to fold the BatchNorm layers into their preceding convolutions, avoiding a GPU "weights engine" that's disabled on Windows on Arm, and replace the final classifier layer with a mathematically equivalent 1*1 convolution.

With those changes, MobileNetV2 ran in 1.52 ms and ResNet-50 in 11.8 ms, compared with 4.49 ms and 42.4 ms on the 20-core CPU through ONNX Runtime. It's roughly three to three-and-a-half times faster, and the top-five predictions matched the CPU's on every test. However, the comparison isn't perfectly like for like, as the CPU used FP32 while the DLA used FP16.
ResNet-50 also shows how far a real-world use case is from a synthetic benchmark; the effective throughput was just 0.65 TFLOPS, well below the 5.2 TFLOPS benchmark. Unlike a stack of identical 3*3 convolutions, the model's 1*1 and strided convolutions can't keep the accelerator fully occupied, so its peak performance is much lower.
I also built a dozen small networks containing a single operation each to see what the DLA would accept. Convolutions, ReLU, sigmoid, tanh, both tested GELU variants, layer norm, instance norm, softmax, nearest-neighbour resizing, and mean reductions all compiled and matched NumPy.
Support for layer norm, softmax, and GELU is particularly interesting, as these operations are common in transformer architectures, suggesting that the DLA is intended for more than just computer vision. TopK, INT8 weights, and INT4 weights failed to compile, though, despite references to them in the compiler, which might be caused by this still being in beta. After all, Nvidia's official supported-layer list currently covers just ten layer types.
I went back later with a much broader sweep of around 65 operations, and TopK did eventually work, but only along a tensor's last axis, where it runs on the RISC-V vector unit rather than the DLA's main hardware. Cosine, logarithm, and square root ran on the vector unit as well. More importantly for transformers, TensorRT's ONNX parser turns matrix multiplications into operations the DLA’s own hardware can run, even though TensorRT's network API rejects them outright. Matrix multiplications compiled and matched NumPy at every size I tried up to 2048768768, and so did a complete attention block, with the query, key, and value projections, the softmax, and the final multiplication, plus rotary position embeddings on top.
There's a catch, though. Even at their best, using chains of 32 1*1 convolutions (which is mathematically the same thing as a matrix multiplication), those multiplications only reached around 4 TFLOPS, roughly 18 times slower than cuBLAS on the GPU.
To compare efficiency, I ran the equivalent calculations on both accelerators, using cuBLAS matrix multiplications on the GPU instead of TensorRT, because TensorRT can't build GPU engines on Windows on Arm. I then recorded power using nvidia-smi's per-rail readings. Aside from when I tested the GPU, these tests were conducted with the GPU at idle. While these values aren't affected, during later testing I also had a local LLM loaded, which is why my GPU power can climb higher than the figures below.
|
Workload |
Throughput |
Measured power |
TOPS/W |
|
GPU (cuBLAS, FP16) |
71.5 TOPS |
45 W |
1.59 |
|
NPU rail only (FP16) |
5.23 TOPS |
2.82 W |
1.85 |
Switching to INT8 in a separate run improved the GPU's efficiency by around 55%, but did almost nothing for the NPU, which drew the same power in INT8 as in FP16 for the same throughput.
On its own rail, the NPU is about 16% more efficient than the GPU, though it's almost 14 times slower. This is thanks to hybrid mode, which keeps the GPU awake even when it isn't performing any computations. Its rail drew another 3.35 W, compared with 1.3 W at idle, reducing combined efficiency to 0.85 TFLOPS/W. Even counting only the roughly 2 W increase over idle, the NPU manages around 1.07 TFLOPS/W, still below the GPU's 1.59.
ResNet-50 tells a similar story, consuming 36 mJ per inference on the NPU rail alone and 87 mJ when the GPU rail is included.
There are some important caveats, though, namely around INT8. INT8 can offer twice the throughput of FP16 on DLA architectures, with structured sparsity potentially doubling that again, but neither advantage materialised when I tested it. I later ran the same convolutions in INT8 on both accelerators, and the gap only got wider: the GPU managed 2.32 TOPS/W through cuBLAS's INT8 path, while the NPU managed 1.10 on its own rail and 0.82 once the GPU's extra draw is counted. In other words, the GPU is roughly twice as efficient as the NPU in INT8, which is the precision NPUs are supposed to be best at. As well, comparing the GPU and the NPU in this way excludes the cost of converting convolutions into matrix multiplications, and that favors GPU, especially given that the GPU was also running at full clocks. On the other hand, cuDLA's unsupported standalone mode could eliminate much of the GPU power overhead.
In other words, these results are indicative rather than something that determines the actual efficiency of the silicon here. There's too much we currently don't know, and it's far too early to make broad conclusions of the hardware and its efficiency based on specific workloads. Instead, treat this as an assessment of the NPU's current FP16 implementation and the system's software limitations. From what I could tell, the NPU doesn't throttle, either. I left it running INT8 work for ten minutes straight, and the DLA clock held at 1,561 MHz while the NPU peaked at 65°C and drew around 5.7 W. Throughput dropped by about 8% over that time, but that came from the GPU clocking itself down rather than the NPU, as hybrid mode relies on the GPU to pass it work. INT8 works, as long as you go around TensorRT.
INT8 works, as long as you go around TensorRT
It just isn't any faster

Nvidia's TensorRT documentation for Windows on Arm explicitly says that INT8 quantized models are accepted as a storage format, but computation remains in FP16, and pure INT8 compute isn't supported. Every INT8 network I tried building through TensorRT failed with a DLA compile error, consistent with that limitation. What I couldn't establish was whether the restriction came from the hardware or the software.
To find out, I built a proxy for nvdla_compiler.dll that forwarded all 655 exported functions to the original library while logging TensorRT's calls. During FP16 builds, TensorRT targets "t254" and requests half-precision computation. INT8 builds use the same half-precision setting, never requesting INT8 compute, before failing during compilation.
I tried overriding that setting to INT8 in my proxy, but the compiler ignored the change because the network's tensors were still FP16.
To get it working, I cut TensorRT out entirely. The DLA compiler exposes a C interface, and by capturing the arguments TensorRT passed through my proxy DLL, I reverse-engineered enough of it to build a network directly from Python. I created an input, several convolution layers, and a compiler profile configured for INT8.
The compiler produced a loadable that the DLA accepted and executed without complaint. That was further than I'd managed to get through TensorRT. Actually getting the right results took longer than expected, though, primarily because I'd accidentally registered the same buffer for the network's input and output, making it look as though the NPU was reading from the wrong memory. Once I corrected the buffer registration, INT8 worked.
A single convolution on random input matched my reference INT8 implementation to within one quantization step on every output. Deeper networks of up to 64 layers remained within a few steps, and the NPU's output was actually slightly closer to the full-precision reference than my ideal INT8 implementation at every depth I tested.

Synthetic layers only prove so much, though, so I built a complete ResNet-50 model through the same C interface. That required disassembling the compiler to reverse-engineer its pooling and addition functions, as well as working around its refusal to compile INT8 max pooling, aided by DeepSeek V4.1 Flash 1017 running locally in order to speed up the process. I recreated max pooling using nine depthwise convolutions, each selecting a different position in the pooling window, followed by a chain of element-wise maximum operations. It's a clunky workaround, but mathematically equivalent to the original operation.
On all three test images from the ONNX Model Zoo, the INT8 model produced the same top prediction and top five classes as the CPU, with closely matching output scores. However, I calibrated the INT8 ranges using those same three images, so this establishes that the model runs correctly rather than demonstrating its accuracy across a larger dataset.
Unfortunately, it doesn't run any faster. ResNet-50 took 13.6 ms per image in INT8, slightly slower than its 11.8 ms FP16 result. Synthetic benchmarks carried the same result, with INT8 peaking at roughly 6.0 TOPS, compared with 6.05 TFLOPS in FP16 for the same workload, and no difference in NPU power consumption.
Even larger 5*5 and 7*7 convolution kernels, which perform more computation relative to memory traffic, gave INT8 an advantage of just 3 to 4%. Structured 2:4 sparsity provided no speedup either, even when I stayed within Nvidia's documented restrictions.
This is where things get really strange, though: I dumped the register writes generated by the compiler and found that the INT8 loadable actually configures all four convolution units for INT8, with the hardware set to process twice as many channels per step as FP16. Even still, each of those steps execute at the same rate, which leaves the effective throughput basically unchanged.
I tried running multiple tasks in parallel, splitting computation across independent branches, using every compiler profile the hardware accepts, and even patching register values directly. Nothing pushed throughput beyond roughly 6 TOPS. Nvidia's statement that computation remains in FP16 turns out to describe the performance surprisingly well: the data is INT8, but the throughput is effectively the same as FP16.
That still leaves Nvidia's advertised 50 to 55 TOPS unexplained. The compiler contains support for a compressed sparse INT8 weight format that it never uses when targeting this chip, suggesting there may be capabilities the current software doesn't expose. I couldn't get beyond roughly 6 TOPS, barely a tenth of what you'd expect.
Only Nvidia knows if the performance can be unlocked through a future driver or compiler, or if those peak TOPS rates shared with other outlets are even reachable on this hardware. The company declined to comment on the NPU's architecture at this time, aside from the existence of a technical paper that will hopefully be published soon.
It looks like the RISC-V DLA Nvidia described in 2024
Nvidia hasn’t confirmed it, though

Let's take a look at the Jetson Orin for a moment: on this machine, cuDLA reports hardware version 2, while the compiler contains numerous "DLA2" classes and Orin-specific code paths. Jetson AGX Orin has two DLA 2.0 engines, each rated at 52.5 sparse INT8 TOPS at 1.6 GHz. Nvidia's newer Jetson Thor doesn't have a DLA at all, with the company's Orin-to-Thor migration guide listing it as "not applicable."
Orin's rating also offers a clue as to where 55 TOPS comes from. The company hasn't specified whether that's dense or sparse INT8 performance, and a report from Windows Central claims that it's capable of 50 TOPS, not 55. Whether that's a dense or sparse figure is particularly important as sparse INT8 performance can be twice the dense figure. Scaling Orin's per-DLA rating to this chip's 1,562 MHz maximum clock gives approximately 51 sparse INT8 TOPS, which is close to both of those numbers. That would suggest Nvidia is quoting sparse performance, the same way Nvidia does for Orin. I can run INT8 on this NPU now, but at around 6 TOPS it doesn't come close to either number, sparse or not. When I asked Nvidia, they told me it will answer the TOPS question in an upcoming white paper.
Having said all of that, this appears to be more than a conventional Orin DLA. At the RISC-V Summit in 2024, Nvidia's Frans Sijstermans described a DLA containing two RISC-V processors: a simple 32-bit control processor and NVRVV, a 1,024-bit vector processor for operations outside the main convolution engine. The design also included a dedicated convolution core and Rubik, a data-transformation engine.
All of this work is part of Nvidia's broader move away from its older Falcon microcontrollers to RISC-V cores across its chips. The architecture Sijstermans talked about hasn't been seen in a consumer product so far, though, and I wanted to see if it had finally made its first appearance.
As it turns out, nearly every part of that architecture appears in its driver. Its performance counters reference four convolution MAC units (CMAC0 to CMAC3), four CSDP units, four OPRDMA units, an input DMA engine, two Rubik units, and one RVV unit. The driver also contains messages such as "Wait RVV to finish booting..." and "Failed to boot RVV from iova," alongside separate handlers for RVV stall and no-stall interrupts. That suggests the vector processor has its own boot process and interrupt handling.
The DLA firmware embedded in the driver provides stronger evidence. It was built for "firmware-t35x" and roughly 1 MB of code before its strings looks unlike the surrounding driver. I found between 92 and 126 compressed RISC-V return instructions per 64 KB, compared with an average of just 1.8 elsewhere in the driver, and no Arm64 return instructions in that firmware region. Disassembling it produced coherent 32-bit RISC-V code, complete with ordinary function prologues and loops polling hardware registers, which matches the simple 32-bit control processor Nvidia described in 2024.
I also managed to get evidence of RISC-V execution on the device itself, using a network containing a sine function compiled into a loadable with RVV code inside. TensorRT also reports 2.5 MiB of SRAM for this single DLA, compared with 2 MB shared between Orin's two DLAs. The driver also contains display classes labelled T254 and T256, with the GB10 identified as T254. The hardware is in the same general family, which aligns with the similarities we've seen between the RTX Spark and the GB10.
The compiler includes a vector operation called NvrvvMhaRmsnormRope, combining multi-head attention, RMSNorm, and rotary position embeddings. These operations are important to LLMs, not so much your typical NPU tasks, which suggests Nvidia designed the vector processor with transformer workloads in mind rather than computer vision alone. I couldn't get the compiler to use it from any graph I built, even the full attention block with rotary embeddings, which ran entirely on the DLA's regular hardware instead. Reaching it likely requires the unreleased transformation library I'll get to later. Finally, something interesting I spotted was that while there's only one DLA core on this laptop, the ONNX Runtime tests are written for two or more.
All of this evidence strongly points to the design Nvidia described in 2024, but it's far from definitive. That presentation didn't name a specific product it would ship in, and the compiler targets several SoCs, including Orin's T234 alongside T254 and T256. Not every code path necessarily applies to this laptop, and I couldn't confirm that its Rubik units were active.
GB10's boot configuration explicitly marks DLA as disabled
Whether it can be enabled remains unanswered

Nvidia's own documentation offers several clues as to what's going on here. For starters, Nvidia's official DGX Spark porting guide contains a "Chip Features" table that lists DLA but marks it "NO." The same table includes features more commonly associated with laptops, including eDP for an internal display, CSI for cameras, SoundWire audio, a sensor hub, and an ISP. However, it's unclear whether "NO" means a feature is physically absent from the chip or simply unsupported on DGX Spark.
Other entries make it hard to establish the distinction: the audio DSP entry specifies "No external Codec," even though GB10 has audio hardware, while "dGPU attach" is marked "No" despite the chip having PCIe and USB4 controllers. On my DGX Spark, every PCIe root port exposed to Linux is already assigned to the ConnectX-7 networking, SSD, Ethernet, Wi-Fi, or GPU, and there are no exposed USB4 domains capable of tunnelling PCIe to an external GPU. I initially read the porting guide as a description of what the actual DGX Spark platform supports, rather than the capability of the silicon. Under this interpretation, the GB10 could support DLA, though it could equally indicate that the GB10 simply lacks the hardware.
The DGX Spark fits that picture perfectly, as its firmware doesn’t define a DLA0 device, so Linux never sees one. Unlike on Windows, nvidia-smi lists only the GPU, and the Linux driver and its GSP firmware don’t contain any of the DLA or RVV code that the Windows driver does. What's interesting, though, is that the firmware knows about a DLA. Its ACPI tables include DLA power domains, power telemetry entries for the DLA's input and output, a DLA thermal zone, and a power management table that references a DLA0 device even though no such device is ever defined.
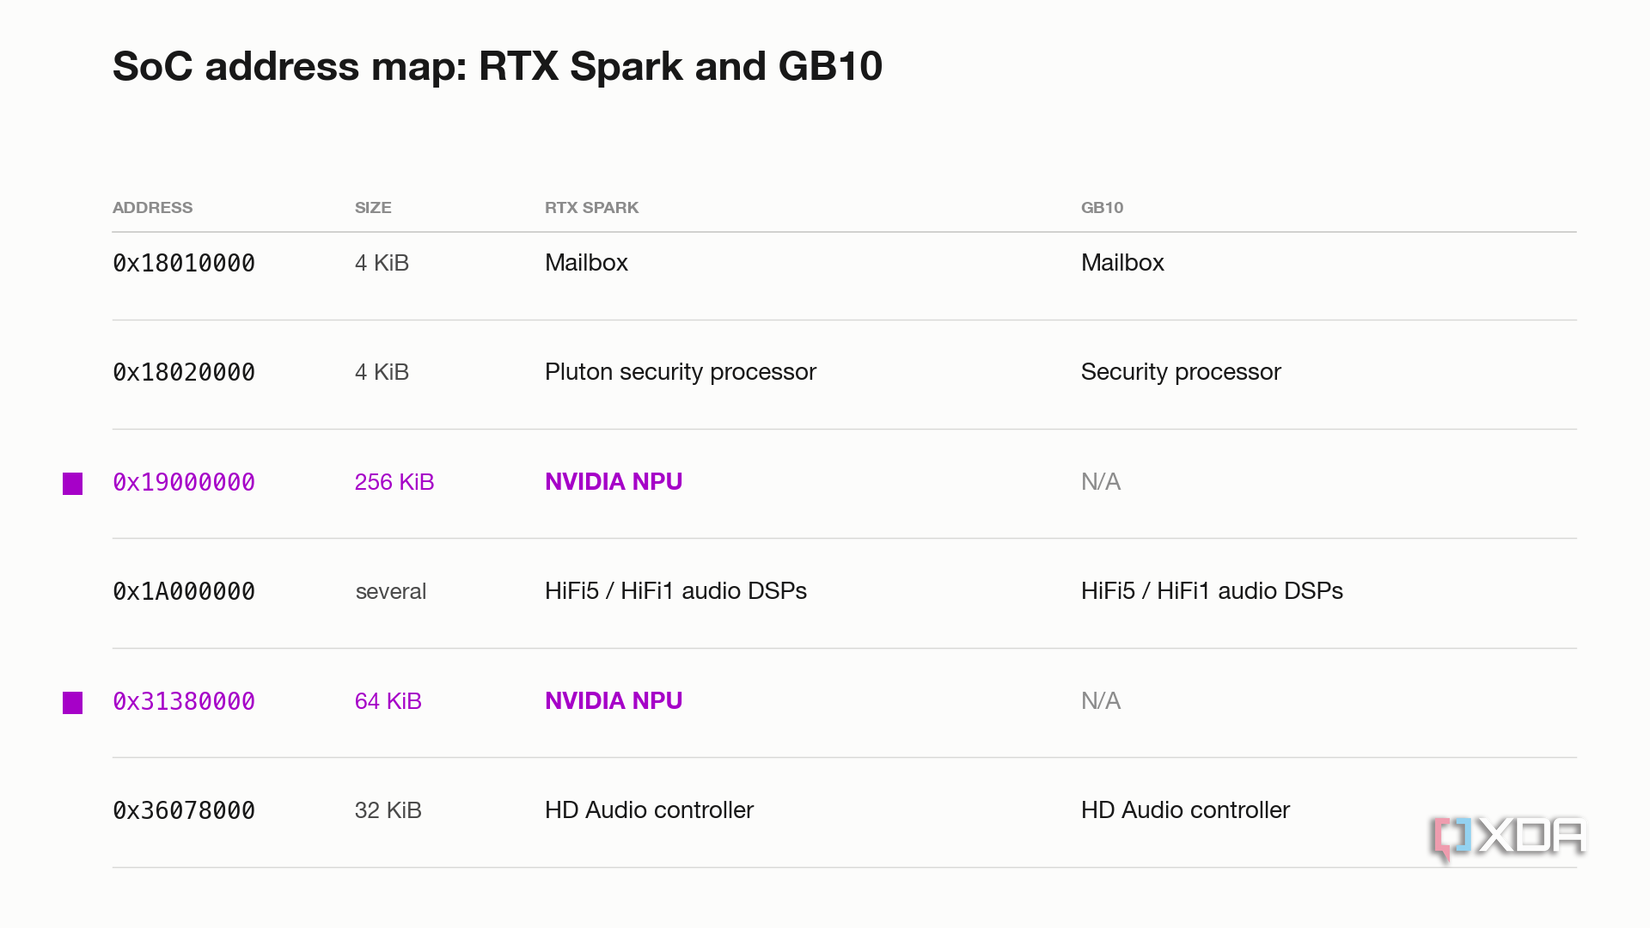
The memory map reveals another similarity. DGX Spark's mailbox, security processor, audio DSPs, and HD Audio controller all sit in exactly the same addresses as they do on the OmniBook. However, the two register windows used by the OmniBook's NPU, 0x19000000 and 0x31380000, are unclaimed on GB10.
In August 2025, Nvidia presented a GB10 block diagram which also lacks a DLA, but it also omits the audio DSPs, which are present at the same addresses on both chips, meaning that it's not an exhaustive mapping of the silicon. Taken together, these findings could be considered consistent with a disabled or inaccessible DLA that's still physically present, but they could also be explained by firmware shared between two chips with different hardware configurations.
Having said that, the firmware isn't identical: both chips have power-diagnostics tables with the same layout, but the RTX Spark is labelled "Tumaz" while GB10's is labelled "Rikulau." These appear to be internal codenames, potentially for the chips or their power-management firmware, and the RTX Spark version is a slightly newer revision.
Taking things a step further, I tried to read the NPU's register windows directly. The main 256 KiB window returned zeroes throughout, just like the empty address space surrounding it, while the HD Audio controller responded as expected. That doesn't necessarily mean the NPU's address space is empty, though as the GB10 also returns zeroes for its own power controller, which is clearly operational but inaccessible to the operating system. The smaller 64 KiB window did return data, but it's inside of a larger block of SoC registers that reports the same value across a bunch of unrelated slots. In other words, it doesn't really tell me anything about the existence of a DLA.
GB10's power manager yields some more clues, though still has a number of gaps. The telemetry table contains entries for DLA temperature and power alongside the GPU and SoC sensors, but they remain fixed at 0 °C. Its input power never changed, and its output power stayed at zero.
I eventually recovered the DGX Spark's early-boot firmware log, with Secure Boot still enabled. It records the boot configuration loaded on my machine, including this entry:
DLA_DIS = 0x1 (default is 0x0)The firmware explicitly describes 1 as "off," which is the value reported on my DGX Spark. That gives us something considerably more concrete than an unused device name or a temperature sensor that never changes: an explicit DLA disable setting recorded before Linux starts. The reported default of zero belongs to the firmware's description of the setting; it doesn't establish how the hardware is fused or what every shipping machine uses.

I then went a step further, investigating 43 publicly available GB10 SoC firmware releases covering Nvidia, Lenovo, ASUS, Acer, Dell, MSI, Gigabyte, and HP's ZGX systems. Across each one, I discovered that they all contain a "DLA Support" setting that defaults to Disabled, with the question hidden behind an unconditional suppression expression. There were eight distinct main ACPI tables across all of those images, and none defined a DLA compute device for the operating system to discover.
Both my DGX Spark and the OmniBook report the same Arm SoC identifier, which Nvidia's driver identifies the GPU of internally as GB20B. Along with the matching peripheral addresses, there's a lot of evidence that points towards a common SoC design, even if we can't establish the fuse settings or what hardware is usable.
I still haven't been able to demonstrate a working DLA on GB10, nor have I figured out where the final initialization code that consumes the disable setting is located. There could be additional hardware restrictions, and changing the configuration might not be sufficient to expose it in the first place. However, what I can establish is that the DGX's early-boot firmware records DLA as explicitly disabled, while every GB10 firmware release I examined also hides the setting and defaults it to Disabled.
Windows still has no proper way to use the NPU
Nvidia's official software support is barely there

Despite everything I've managed to run on the NPU, there's still no straightforward way for Windows applications to use it. Microsoft's DirectML can't access it, and creating a Direct3D 12 device on the NPU fails with DXGI_ERROR_UNSUPPORTED at every feature level, using both the built-in runtime and the latest Agility SDK. I tested Nvidia's drivers 617.21 and 617.42, with identical results.
In the hopes of getting it working, I looked to Windows ML which uses execution providers supplied by hardware vendors rather than relying exclusively on DirectML. However, Microsoft's list of supported execution providers, updated on October 7, only includes NPU providers for Qualcomm, Intel, and AMD. Nvidia's sole entry is TensorRT for RTX, which runs on the GPU.
Support is in the works, at least, and a pull request merged into the onnxruntime-ep-tensorrt repository on October 7 added DLA inference support for Windows Arm64, advertising the DLA as a separate NPU device. However, it requires cudla.dll from a matching DTK execution-provider package that isn't publicly available, and the pull requests also notes that the Arm64 inference tests haven't been run on DLA hardware.
Interestingly enough, Microsoft is involved in the process as well, according to the repository. In a separate, still-open pull request, a packaged static library DLA graph transformation is added "per MSFT request."
That library seems to be less secret than it sounds. Microsoft's model optimization toolkit, Olive, has had a public set of 21 "DLA transforms" since July 2025, and two of the steps named in Nvidia's pull request, RemoveQDQ and MatMulToTransposeConvTranspose, match functions in Olive. The first strips the quantize and dequantize nodes out of a model, and another Olive transform converts INT8 weights back into floating point. Nvidia's test case uses 16-bit activations and 8-bit weights, with values copied from a real model called PSH_ver_2.0.9.quant.onnx, and once those transforms have run, there's no INT8 left in it at all. TensorRT then compiles what's left in FP16.
In other words, the publicly documented Windows ML integration takes quantized models and converts them to FP16 before executing them on the NPU. I've already demonstrated that the hardware can run INT8 directly, but Nvidia and Microsoft's software still doesn't expose that capability.
Out of the box, Copilot+ isn't even ready. The RTX Spark is certified for Copilot+ but right now, doesn't support any of its features. Microsoft is still working to bring Recall, Click to Do, and on-device semantic search to the platform in the coming months, meaning that the NPU's most obvious intended workloads aren't available yet, either.
There are some rough edges to the beta software as well; for example, registering a cuDLA buffer while a copy into it was still being made caused 17% of my test runs to return all-zero outputs without actually returning an error. I was able to get around this by synchronizing the copy before registering the buffer, but it's an example of how early this software is currently.
The NPU looks like it's there for Microsoft rather than Nvidia
Copilot+ needs one, after all

The timing of all this is strange. Nvidia outlined this DLA design at the RISC-V Summit in October 2024, then said nothing more about it for two years. Around the same time, rumours suggested Nvidia's Arm PC chip would debut at CES 2025, but the company only revealed the GB10-powered Project DIGITS, which eventually became the DGX Spark. The Windows chip seemingly slipped repeatedly amid reports of Windows on Arm delays, weak demand, and a silicon revision, with one report even claiming Nvidia cancelled a planned CES announcement at the last minute. When the RTX Spark finally launched, it included an NPU that Nvidia barely acknowledges publicly.
Public code shows work on this DLA going back much further than the launch. In April 2025, a Microsoft engineer working on ONNX Runtime's TensorRT support added a pass to Olive that converts matrix multiplications into convolutions, describing it as "needed by TensorRT EP to meet certain hardware requirement." In May 2025, Nvidia's TensorRT 10.11 added a DLA-only option for the kind of uint8 quantization Windows models use, and Nvidia's header says that engines using it must target "DLA version >= 3.16." The compiler on the RTX Spark reports version 3.16, and I couldn't find any Jetson or Drive release that documents a DLA at that version. In July 2025, Nvidia upstreamed Linux support for the on-chip fabric of a chip it calls Tegra254, covering its C2C, GPU, and display fabrics, and Olive gained its full set of DLA transforms that same month.
The DLA firmware in the driver I tested carries a build tag from November 2025, and the first public build of cuDLA for Windows on Arm only appeared in Nvidia's CUDA downloads in September 2026, a month before launch. The code doesn't name a product or release date, so we can't figure out when Nvidia planned to ship it. However, what it does show is that Microsoft and Nvidia were both writing software for this exact DLA around 18 months before it was even available to consumers.
It's important to know that, over the past few years, Nvidia hasn't exactly been a fan of NPUs in PCs. In a leaked presentation from May 2024, it classed NPU-based PCs at 10 to 45 TOPS as "Basic AI" and RTX GPUs at 100 to 1,300 TOPS as "Premium AI," seemingly in response to Microsoft making a 40+ TOPS NPU a requirement for Copilot+. A GPU can't satisfy that requirement no matter how fast it is, so if the RTX Spark was going to be a Copilot+ PC, it needed an NPU, and the DLA is a design Nvidia already had.
The software tells a similar story. Nvidia has identified Copilot+ as the only purpose for the NPU, and Microsoft is directly involved in bringing support to Windows. Git commits relating to the ONNX Runtime even reference a DLA transformation library supplied "per MSFT request." Despite that, the integration is about as minimal as it could be: hybrid mode only, no DirectML, and a beta SDK. Even the published route for running quantized models on it converts them to FP16, so none of it uses the INT8 hardware that a TOPS figure would likely be measured on. Meanwhile, the GB10 doesn't expose a DLA to Linux, and the DGX Spark's early-boot log explicitly records it as disabled, although whether the hardware can be enabled remains unanswered. Unlike the RTX Spark, the DGX Spark's GB10 has no need to meet Microsoft's Copilot+ requirements.
It's impossible to know exactly what Nvidia's motives were, but the evidence points to an NPU that's there primarily because Microsoft requires one, rather than because Nvidia sees it as an important part of its AI strategy. The NPU is based on an architecture Nvidia already had and ships with barely enough software to make it usable, while Nvidia has published very little about its hardware architecture. Given how much Nvidia usually has to say about its AI hardware, that silence is particularly telling.