Insider Brief
- Google Quantum AI researchers developed a method that uses saved error-correction records to reduce distortion in quantum results after a calculation, achieving more than 1,000-fold suppression in simulations.
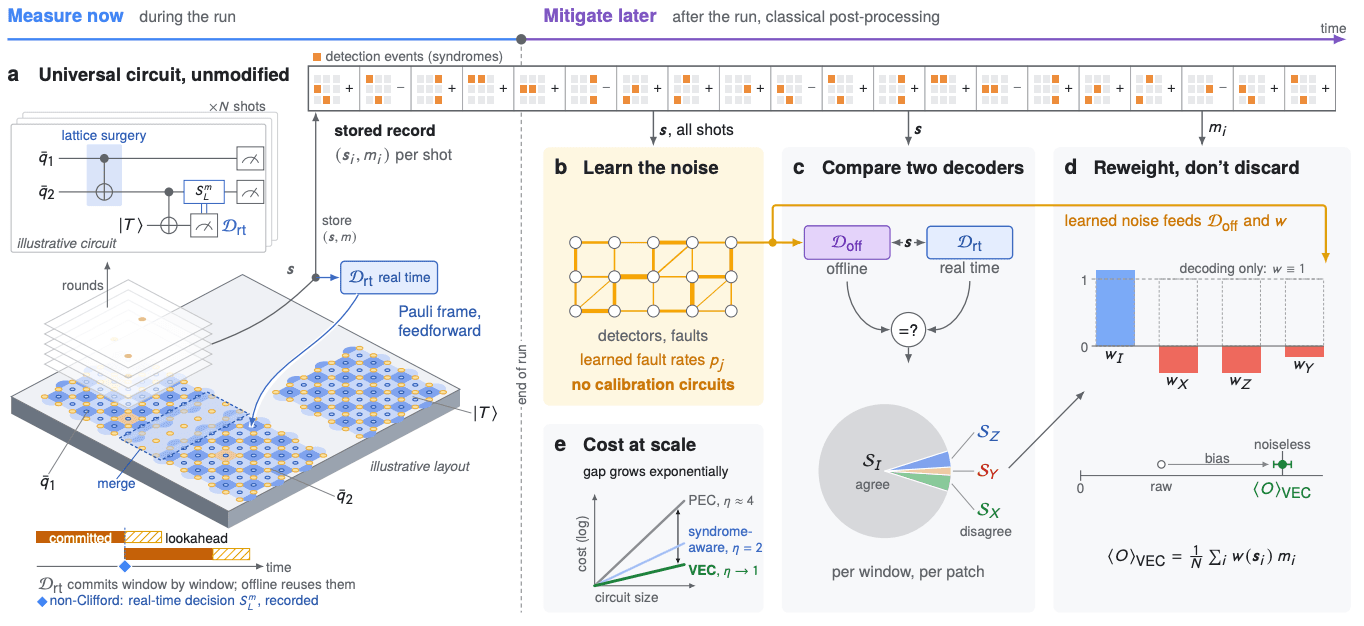
- The method compares a fast decoder with a more accurate offline decoder and adjusts how much each measurement counts toward the answer, avoiding separate calibration experiments or changes to quantum circuits.
- The results rely on simplified noise simulations, and the method requires additional measurements and further testing under realistic conditions and on quantum hardware.
Errors can survive even a quantum computer’s built-in correction system, leaving researchers with results that look reliable but remain slightly off.
Now, Google Quantum AI researchers report on a “measure now, mitigate later” approach in a preprint study on arXiv that uses error records saved during the calculation as a way to reduce that remaining distortion by more than 1,000-fold in simulations.
Their method, called virtual error cancellation, moves part of the work to a conventional computer after the quantum calculation ends. It uses information the quantum system already collects to adjust how individual measurement results contribute to the final answer.
According to the study, the approach avoids separate experiments to measure noise and does not require changes to the quantum circuits running the calculation. It still carries a cost, however. Researchers must repeat measurements to produce a precise answer, and the gains have yet to be demonstrated on quantum hardware.
The findings point to a possible way to get more accurate estimates from early fault-tolerant quantum computers. These machines are designed to keep operating despite errors, but their protection will remain imperfect, especially while the number of available qubits is limited.
Double Check
Quantum computers are unusually sensitive to disturbances, or “noise,” as those disturbances are sometimes called. Their basic units of information, called qubits, can lose information or behave incorrectly during a calculation.
Error correction addresses this problem by spreading information across several physical qubits. Together, those qubits form a protected unit called a logical qubit. The computer repeatedly checks for signs that something has gone wrong.
Those checks generate error records, known as syndromes. A conventional computing program called a decoder reads the records and decides which correction is most likely to work.
The process can miss errors and, sometimes, the available evidence is ambiguous, or the decoder chooses the wrong correction. An error can then reach the protected information and affect the calculation.
One response is to build larger groups of qubits that provide stronger protection. That can reduce errors, but it also increases the hardware needed to perform useful work.
The Google team examined another option. Rather than trying to prevent every remaining error during the calculation, researchers could use the saved records to reduce its effect on the answer afterward.
Quantum calculations often involve repeating an experiment many times and combining the measurement results into an estimate. Virtual error cancellation changes how much each result contributes to that estimate.
Some results receive slightly more weight. Others receive negative weight, meaning their contribution is subtracted. With the right weights, the remaining errors cancel on average, according to the study.
The method improves the estimate produced from many runs. It does not make every individual run correct or repair a quantum state after the calculation has finished.
A Fast Decision, Then a Closer Review
The proposal relies on two decoders with different jobs, according to the study.
The first works while the quantum computer is running. This decoder must make quick decisions because some steps in a quantum calculation depend on the outcome of an earlier measurement.
The second examines the saved records afterward and — without the same deadline — can spend more computing effort assessing what most likely happened.
Comparing their decisions helps identify runs that deserve closer attention.
For a single logical qubit, the researchers divided the runs into four groups with one containing cases in which the decoders agreed. The other three contained different kinds of disagreement.
Most runs fell into the agreement group. The disagreement groups contained useful evidence about errors that the fast decoder was more likely to have missed.
The researchers then calculated weights — or, numbers that determine how much each result counts toward the answer — for each group. Results from the agreement group received a small increase in weight, while results from the disagreement groups received negative weights.
This goes beyond simply throwing out questionable results. Discarding runs when the decoders disagree can improve an estimate, but it leaves a problem. Both decoders can agree and still be wrong.
According to the study, virtual error cancellation uses the disagreement results to offset errors that remain even among the agreement results.
The team also developed a way to estimate fault rates from the saved error records. That removes the need for separate calibration experiments, although researchers still need a model of how faults produce the recorded warning signs.
What the Simulations Showed
The team tested its approach using a surface code, a widely studied way of arranging qubits for error correction.
The simulations included three levels of protection, known as code distances 3, 5 and 7. Larger distances generally provide stronger protection at the cost of more qubits. The distance-7 model contained 49 data qubits.
The researchers compared ordinary decoding, rejecting runs when the two decoders disagreed, and applying virtual error cancellation.
In their largest end-to-end test, the new method reduced residual logical error bias by more than 1,000-fold compared with ordinary decoding under favorable conditions. It also achieved more than 100-fold suppression compared with rejecting disagreement runs.
Here, bias means a systematic distortion in the estimate, rather than the random variation that comes from taking a limited number of measurements.
The strongest results used a large collection of error records to learn the noise. The largest learning budget had a baseline of 10 million samples, with the actual budget increasing as the simulated physical error rate decreased.
The reported 1,000-fold suppression occurred when the average physical error rate was at or below 2.2%. The improvement weakened at the highest error rates tested.
More samples helped the researchers estimate fault rates more accurately, reducing the distortion caused by imperfect knowledge of the noise.
The approach also showed promise in reducing the extra measurement burden associated with error mitigation.
Giving results positive and negative weights makes the final estimate more sensitive to random variation. Researchers therefore need additional runs to reach a chosen level of precision.
The study found that virtual error cancellation could require less additional sampling than existing methods that also use error records. Under favorable conditions involving larger codes and a useful advantage from the second decoder, the excess sampling burden approaches roughly half a single-decoder benchmark.
That does not mean every calculation would need half as many runs. The benefit depends on the noise, the code and how well the two decoders perform.
Longer calculations can still become expensive because their accumulated errors increase the sampling requirement. The proposed method eases that cost under suitable conditions but does not remove it.
The Next Test Is More Realistic Noise
The study suggests the main limitation is that the numerical tests used a simplified picture of a quantum computer. The simulations placed errors on the data qubits while assuming the error checks themselves worked perfectly. Real machines also suffer faults during gates, measurements and repeated rounds of correction.
The researchers identify tests with realistic circuit noise as a next step. Those tests would need to follow errors across both the qubit layout and the sequence of operations.
The study also focuses mainly on a model of discrete errors. Some real disturbances act more like a small, unwanted rotation of a qubit’s state and those effects fall outside the team’s current detailed analysis.
The researchers suggest possible ways to address them, including averaging across groups of error records and using established techniques to make the noise easier to model. Those approaches would likely need further testing within this framework.
Other problems may need to be addressed separately. For example, a qubit can leave the states intended for computation, a failure known as leakage. The paper proposes using existing error-control tools alongside virtual error cancellation to address that situation.
The team also outlines how the method could fit into more general quantum calculations. Its proposed design breaks a circuit into local blocks and reviews overlapping sections of the error record so that faults crossing a boundary are not overlooked.
That provides a route toward larger applications, but the study does not demonstrate a complete useful algorithm on hardware.
A further step would be to include the method in quantum compilers, the software that turns an algorithm into instructions a machine can execute. Designers could then compare the costs of stronger hardware protection, more accurate analysis after the run and additional measurements.
The research team included Oles Shtanko, Saswata Roy, Shashwat Kumar and Zlatko Minev, all of Google Quantum AI. Roy also lists an affiliation with Cornell University.
For a deeper, more technical dive, please review the paper on arXiv. It’s important to note that arXiv is a pre-print server, which allows researchers to receive quick feedback on their work. However, it is not — nor is this article, itself — official peer-review publications. Peer-review is an important step in the scientific process to verify results.