Product teams are usually good at defining what they want to improve: paid conversion, engagement, churn, search success, or transaction completion. The harder question is not what to optimize. It is: what behavior must change elsewhere in the system for this metric to improve?
Product metrics do not move on their own. They move because user behavior changes. And when a team changes incentives, friction, defaults, timing, visibility, or access, it rarely changes only one behavior. Move the paywall earlier and conversion may rise, but the composition of paying users may change. Send more notifications and weekly activity may increase, but so may fatigue. Change search ranking and CTR may improve while discovery quality declines.
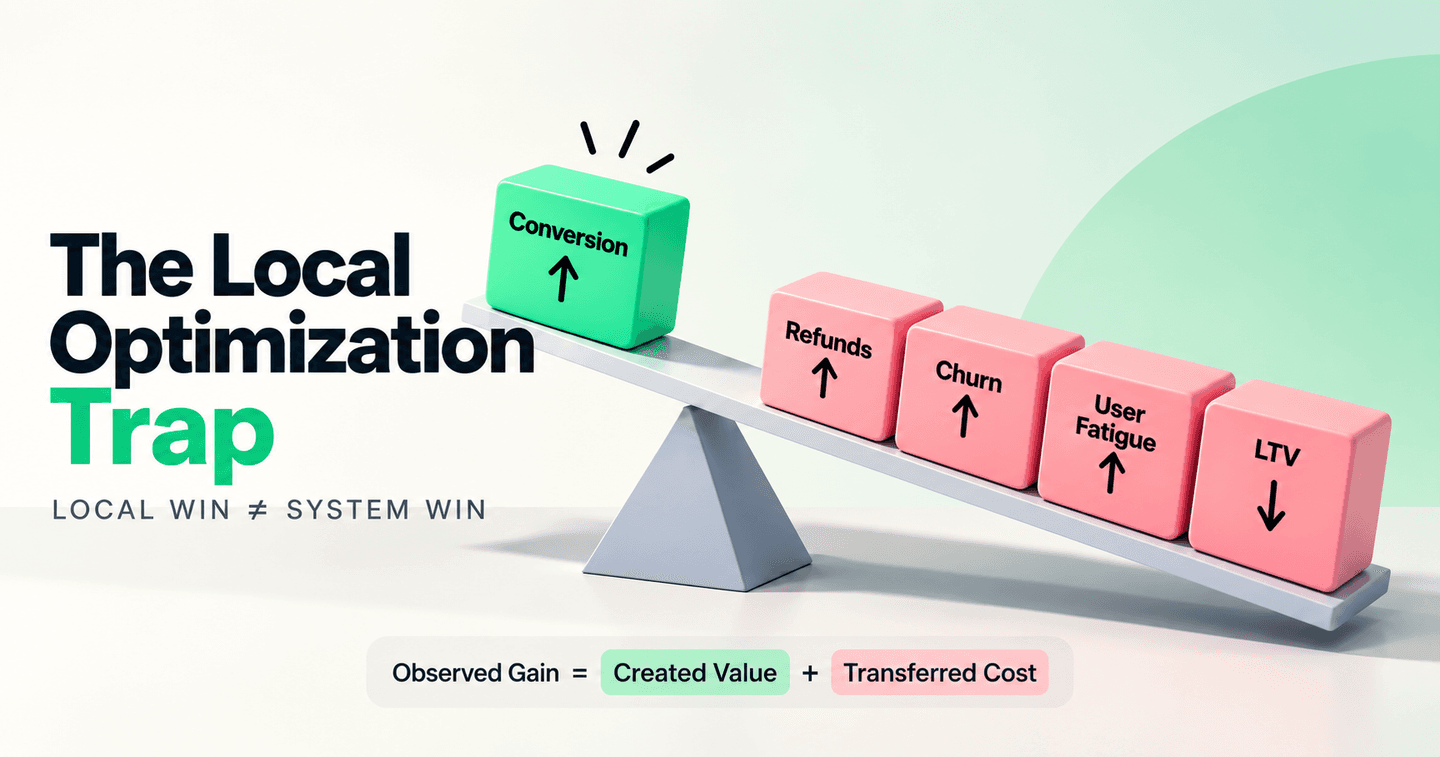
The metric improves, but the mechanism that produced that improvement may create damage elsewhere. I call this the Local Optimization Trap: a team improves a local metric while transferring part of the cost into another part of the product system.
To evaluate that more rigorously, I use the Optimization Integrity Framework:

The Primary Metric shows the local behavior we want to improve. The Causal Trade-Off describes how that improvement could create damage elsewhere. The Counter-Metric is the signal that would reveal that damage. The System Outcome tells us whether the broader product actually improved.
The key principle is simple: do not choose the Counter-Metric first. Derive it from the mechanism by which success could become harmful.
The Hidden Transfer Function of Optimization
Most product optimizations do not create value in isolation. They redistribute something: friction, attention, time, choice, risk, trust, user quality, or economics. I think of this as the transfer function of an optimization.
There are four common forms of transfer.

1. Transfer Across Time
The gain appears now, while the cost arrives later. More notifications may increase engagement this week while increasing fatigue next month. An aggressive discount may improve conversion today while weakening willingness to pay later. A retention tactic may postpone cancellation without changing the reason a user wanted to leave.
2. Transfer Across Segments
The aggregate metric improves because one segment benefits while another gets worse. A simplified flow may help new users while frustrating experienced ones. A pricing change may raise average revenue while pushing away customers with higher lifetime value. An algorithm optimized for the majority may improve total CTR while degrading results for a smaller strategic segment.
3. Transfer Across Behaviors
One behavior improves by displacing another. Users click more but explore less. They complete onboarding faster but understand less. They open the app more frequently but perform fewer meaningful actions. They purchase earlier but evaluate the product less carefully.
4. Transfer Across Economics
A local product gain creates a financial cost elsewhere. Conversion rises while refunds rise faster. Retention improves only because expensive incentives are introduced. Transaction volume grows alongside fraud and support costs.
This is why a local metric and a system-level outcome can move in opposite directions. The optimization may look successful because the Primary Metric sees the gain but not the transferred cost.
From Primary Metric to Causal Trade-Off
The first element of the framework is the Primary Metric: the behavior the experiment is designed to change. But the framework does not move directly from Primary Metric to Counter-Metric. The missing layer is the Causal Trade-Off.
This is the explicit hypothesis about how improving the Primary Metric could make the product worse. If we move the paywall earlier, more users may subscribe because they have less opportunity to evaluate the product before paying. If we increase notifications, engagement may rise because we interrupt users more often rather than because the product became more useful. If we rank popular results more aggressively, CTR may rise because users are exposed to fewer alternatives rather than because relevance improved.
Only after this causal statement is clear should the Counter-Metric be chosen.
Counter-Metrics as Falsification Tests
A useful Counter-Metric should be derived from the Causal Trade-Off. Its job is to answer: if our interpretation of success is wrong, what signal should move?
For an earlier paywall, the predicted failure mode may be lower-quality conversion. Refund rate or 30-day paid churn can test that. For more notifications, the predicted failure mode may be attention fatigue. Notification opt-outs, uninstall rate, or delayed churn can test that. For a search-ranking change, the predicted failure mode may be weaker result quality. Reformulation rate or return-to-results behavior can test that.
This gives Counter-Metrics a stricter role: a Counter-Metric is not a secondary KPI. It is a falsification test for the causal story behind the Primary Metric.
Example 1: The Paywall That Converts Too Well
Suppose a subscription product moves the paywall earlier and reduces the amount of functionality available before payment. Free-to-paid conversion rises from 6% to 9%. At first glance, this is a clear win.
But the Primary Metric does not tell us why conversion increased. One explanation is positive: users understand the value proposition faster. Another is less attractive: users pay before they have enough information to evaluate the product.
The Primary Metric is free-to-paid conversion. The Causal Trade-Off is reduced informed evaluation before purchase. The Counter-Metrics are refund rate and 30-day paid churn. The System Outcome is durable paying customers.
If conversion rises while refunds and paid churn remain stable, the evidence supports a genuine monetization improvement. If conversion rises while refunds double and early churn increases sharply, the interpretation changes. The product became better at generating transactions, but not necessarily at generating durable customers.
The cost was transferred from pre-purchase evaluation to post-purchase regret. That is a false win.
Example 2: Engagement Bought With Attention
Now imagine a product trying to increase weekly engagement by sending more push notifications and email reminders. Weekly active users rise.
The Primary Metric is weekly active users. The Causal Trade-Off is that engagement may be purchased with greater pressure on user attention. The Counter-Metrics are notification opt-out rate, uninstall rate, and delayed churn. The System Outcome is voluntary, durable return behavior.
If engagement rises while opt-outs and later churn also rise, the product may have moved engagement forward in time rather than created more of it. The gain is real, but it is borrowed from future tolerance.
Example 3: Search That Produces More Clicks and Worse Discovery
Imagine a marketplace that changes ranking to place popular items more aggressively at the top. Search-result CTR rises. The obvious interpretation is that search improved.
But another mechanism is possible: users are clicking the first acceptable option because the system exposes fewer meaningful alternatives. The Primary Metric is search-result CTR. The Causal Trade-Off is that higher click concentration may come at the cost of discovery quality. The Counter-Metrics are reformulation rate, return-to-results rate, and perhaps downstream purchase satisfaction. The System Outcome is successful discovery with less effort.
If CTR rises while reformulation falls, the experiment likely improved search efficiency. If CTR rises while reformulation and return-to-results behavior also rise, the system may simply have become better at generating premature clicks.
The local behavior improved. The search task did not.
Why Guardrails Are Not Enough
Guardrail metrics protect against broad classes of harm: crashes, latency, revenue loss, support volume, or other critical outcomes. Counter-Metrics answer a narrower question: did the mechanism that made this experiment successful also create the damage we predicted?
This matters because many false wins never trigger a generic guardrail. A paywall experiment may leave latency and top-line revenue healthy while degrading customer quality. A search experiment may improve CTR without affecting system performance while making discovery less effective.
The harm is experiment-specific, so the Counter-Metric should be too.
The Optimization Integrity Test
Before running a meaningful experiment, I use four questions.
1. What behavior are we trying to change? Define the Primary Metric.
2. What mechanism could make this result look positive while damaging the product? This is the Causal Trade-Off.
3. What observable signal would falsify our interpretation of success? This becomes the Counter-Metric.
4. What broader outcome must improve for the trade-off to be worth accepting? This is the System Outcome.
Together, these questions form the Optimization Integrity Test. The second question is the most important. If a team cannot describe how the experiment could succeed for the wrong reason, the experiment is not yet defined rigorously enough.
Four Experiment Outcomes
Once the framework is defined, experiment results become more informative than simple win or loss.
If the Primary Metric rises, the Counter-Metric remains stable, and the System Outcome improves, this is the cleanest result. The local behavior improves, the expected downside does not appear, and the broader outcome moves in the right direction.
If the Primary Metric rises but the Counter-Metric gets worse, this is a transferred win. The experiment produced the intended local effect, but part of the gain was funded by a cost elsewhere. That does not automatically make the experiment a failure. Some trade-offs are acceptable. But the result should be treated as an exchange, not a pure improvement.
If the Primary Metric stays flat while the System Outcome improves, the Primary Metric may have been a weak proxy for the outcome that actually mattered.
If the Primary Metric rises while the System Outcome remains flat, this is an empty optimization. The team successfully changed local behavior without improving the broader outcome. The experiment worked as designed. The product did not meaningfully improve.
Optimization Integrity Is About Where the Cost Goes
The important question is not whether an experiment has a downside. Almost every meaningful product change does. The important question is: where does the cost go?
Does it appear later? Does it fall on another segment? Does it displace a more valuable behavior? Does it show up in economics rather than product usage?
A useful mental model is:
Observed Gain = Created Value + Transferred Cost
This is not literal mathematics. It is a diagnostic model. If most of the observed gain comes from created value, the optimization is strong. If much of it comes from transferring cost somewhere the Primary Metric cannot see, the win is fragile.
The Most Dangerous Experiments Are Plausible Wins
The easiest experiments to reject are the ones where the Primary Metric gets worse. The dangerous ones are those where it improves for a plausible but incomplete reason.
The metric moves. The feature ships. The experiment is recorded as a win. Then the cost appears later: refunds begin rising, a high-value segment becomes less active, search reformulation increases, or notification opt-outs accelerate.
By then, the original experiment may already be institutionalized as a success.
That is why the Causal Trade-Off should be defined before the experiment starts. If the failure mechanism is predicted in advance, the result becomes falsifiable rather than merely interpretable after the fact.
Conclusion
Product experiments do not improve metrics. They change behavior, and metrics are the observable traces of those changes.
That is why I use the Optimization Integrity Framework:
Primary Metric → Causal Trade-Off → Counter-Metric → System Outcome
First define the behavior you want to change. Then describe how that change could create a false win. Derive a Counter-Metric from that failure mechanism. Finally, judge the experiment against the broader outcome that actually matters.
The core question is no longer:
Did the metric improve?
It is:
Did we create new value, or did we simply move the cost somewhere our Primary Metric could not see?
That is the difference between optimizing a number and improving a product.