
João has been covering the tech world for over 7 years, with a heavy focus on laptops and the Windows ecosystem. I also love all things tech and videogames, especially Nintendo, which he's always happy to talk about.
Prior to joining XDA in 2021, he worked at Neowin: https://www.neowin.net/news/poster/jo%C3%A3o-carrasqueira/
We live in an age where getting any kind of information can be done in a few minutes with a simple internet search. But that's just the thing — all that information lives on the internet, so you're always dependent on a connection to get the answers you need, even if you have a locally hosted LLM to ask questions.
I wanted an answer system that could work even if my internet was down, so I built it. I downloaded Wikipedia and self-hosted it using Kiwix, and now I have all the information I could want right inside my house.
Hosting Wikipedia isn't as hard as I thought
It can be a big download, but still

With how massive of a resource Wikipedia can be, you'd be forgiven for thinking you can't fit it on your own computer. But it turns out you can, and all it takes is the right self-hosted service: Kiwix.
I deployed Kiwix in my Proxmox home lab using the respective community script, only increasing the disk size to 10GB from the default 4GB to accommodate the size of the Wikipedia database I was planning to download. You can download a wide range of variants of the Wikipedia database, even if you're strictly looking to keep every article in English.
The full list of databases is here, if you're curious, and you can download your choice by going into the container's terminal and navigating to its data folder, then use wget to pull the file you want from that list.
To fit the relatively small container, I downloaded the Simple English version of Wikipedia, and I specifically went for the nopic variant, which doesn't include any images from articles, either. This database comes to a little over 1GB, so it can easily fit on any computer. I was tempted to go for the standard English database that would have been around 50GB, but I decided against it, mostly for time reasons.
What Kiwix actually looks like
It's exactly what you'd expect
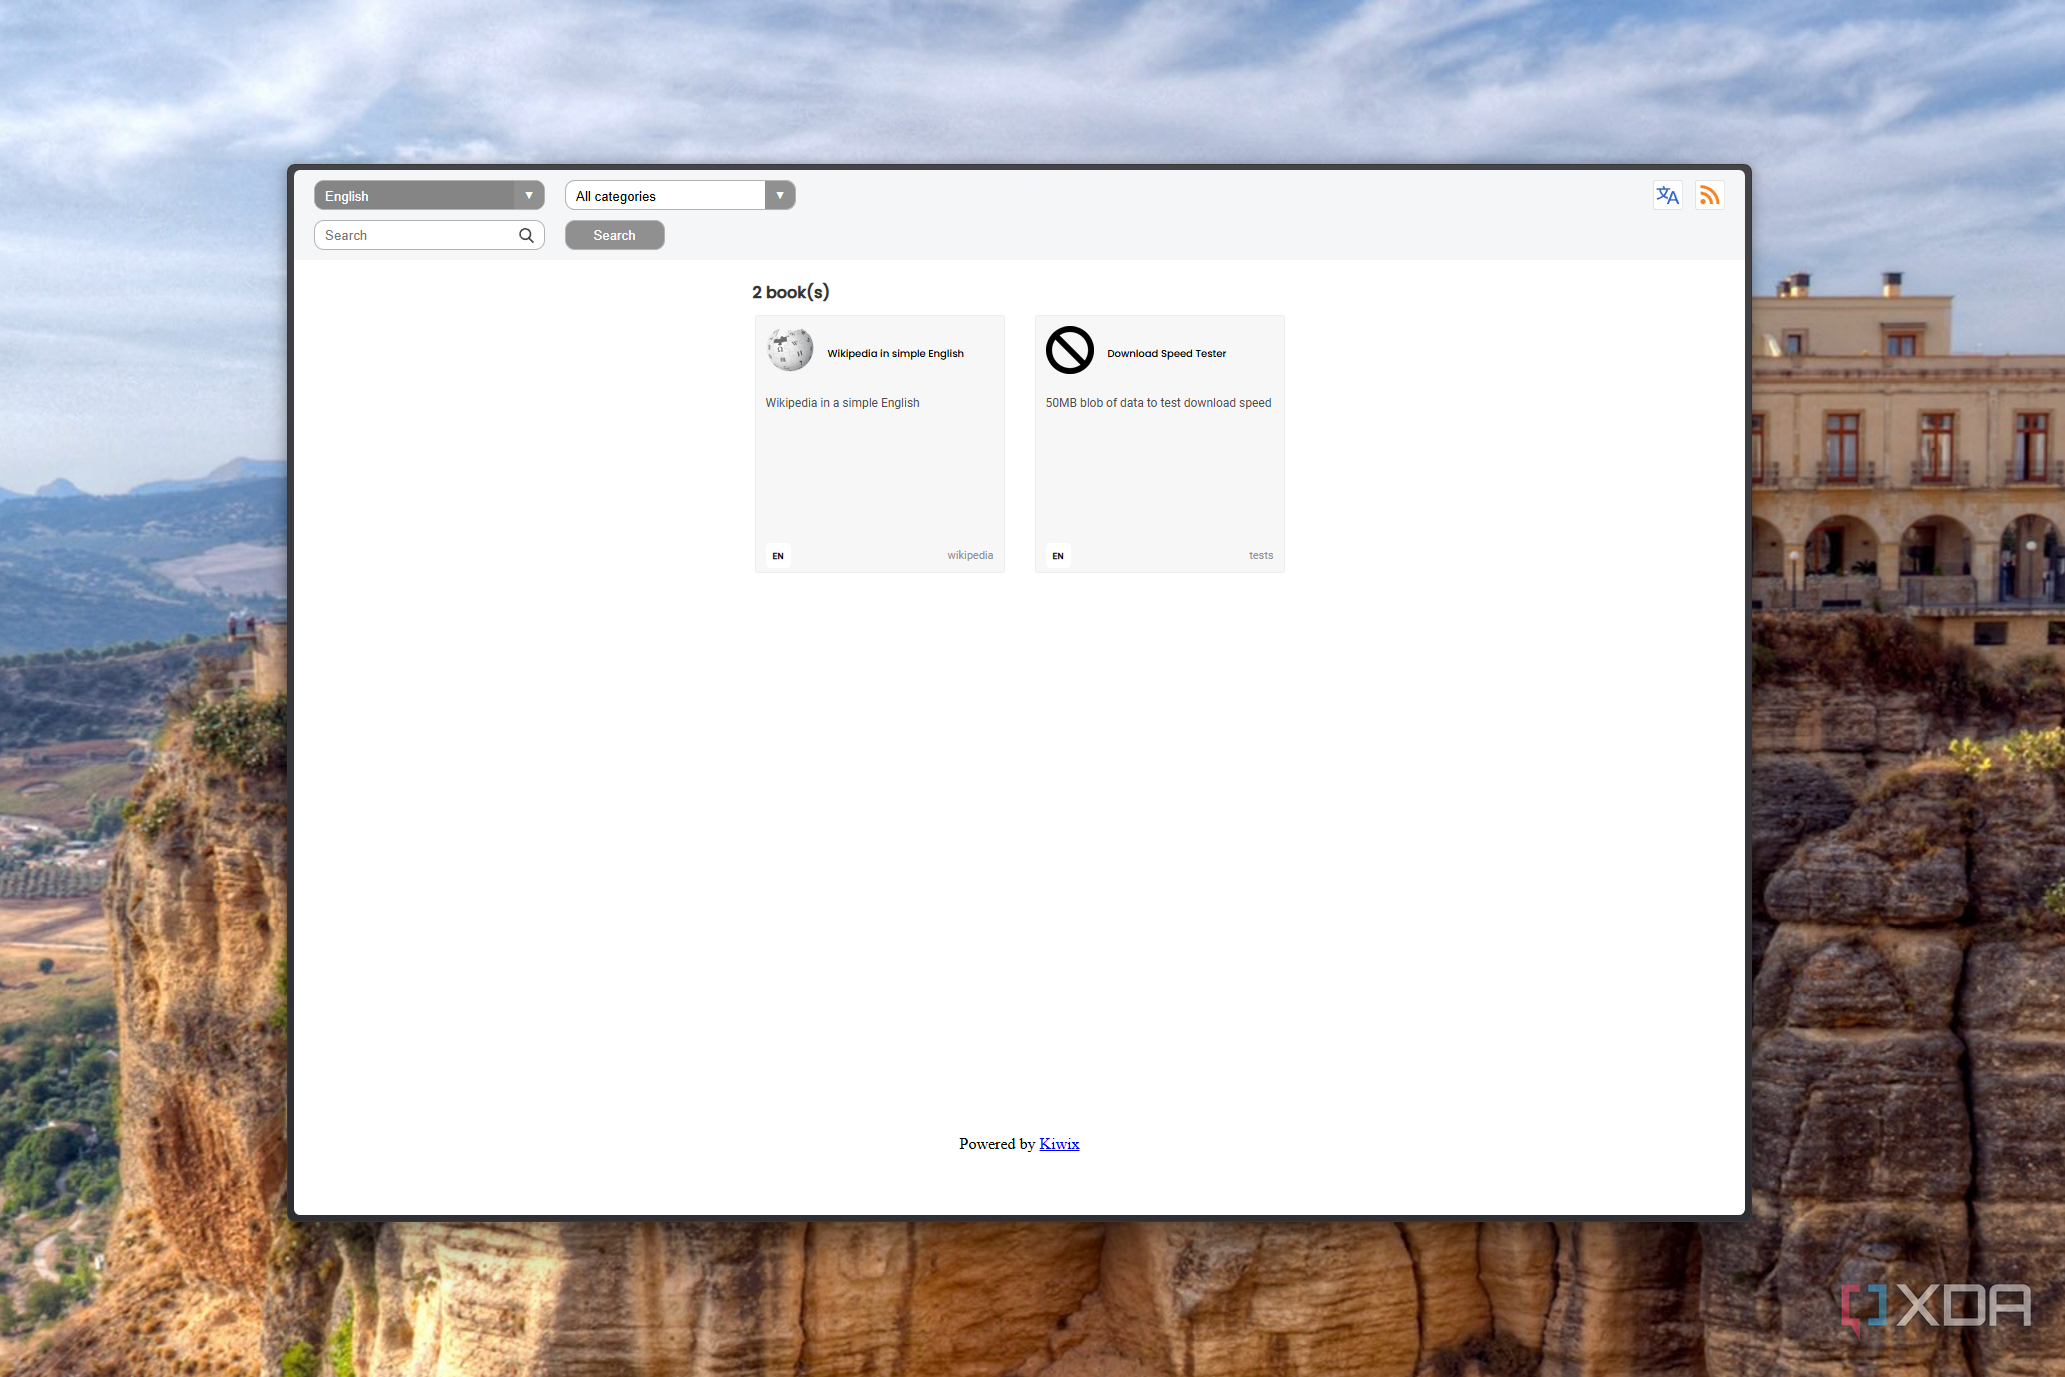
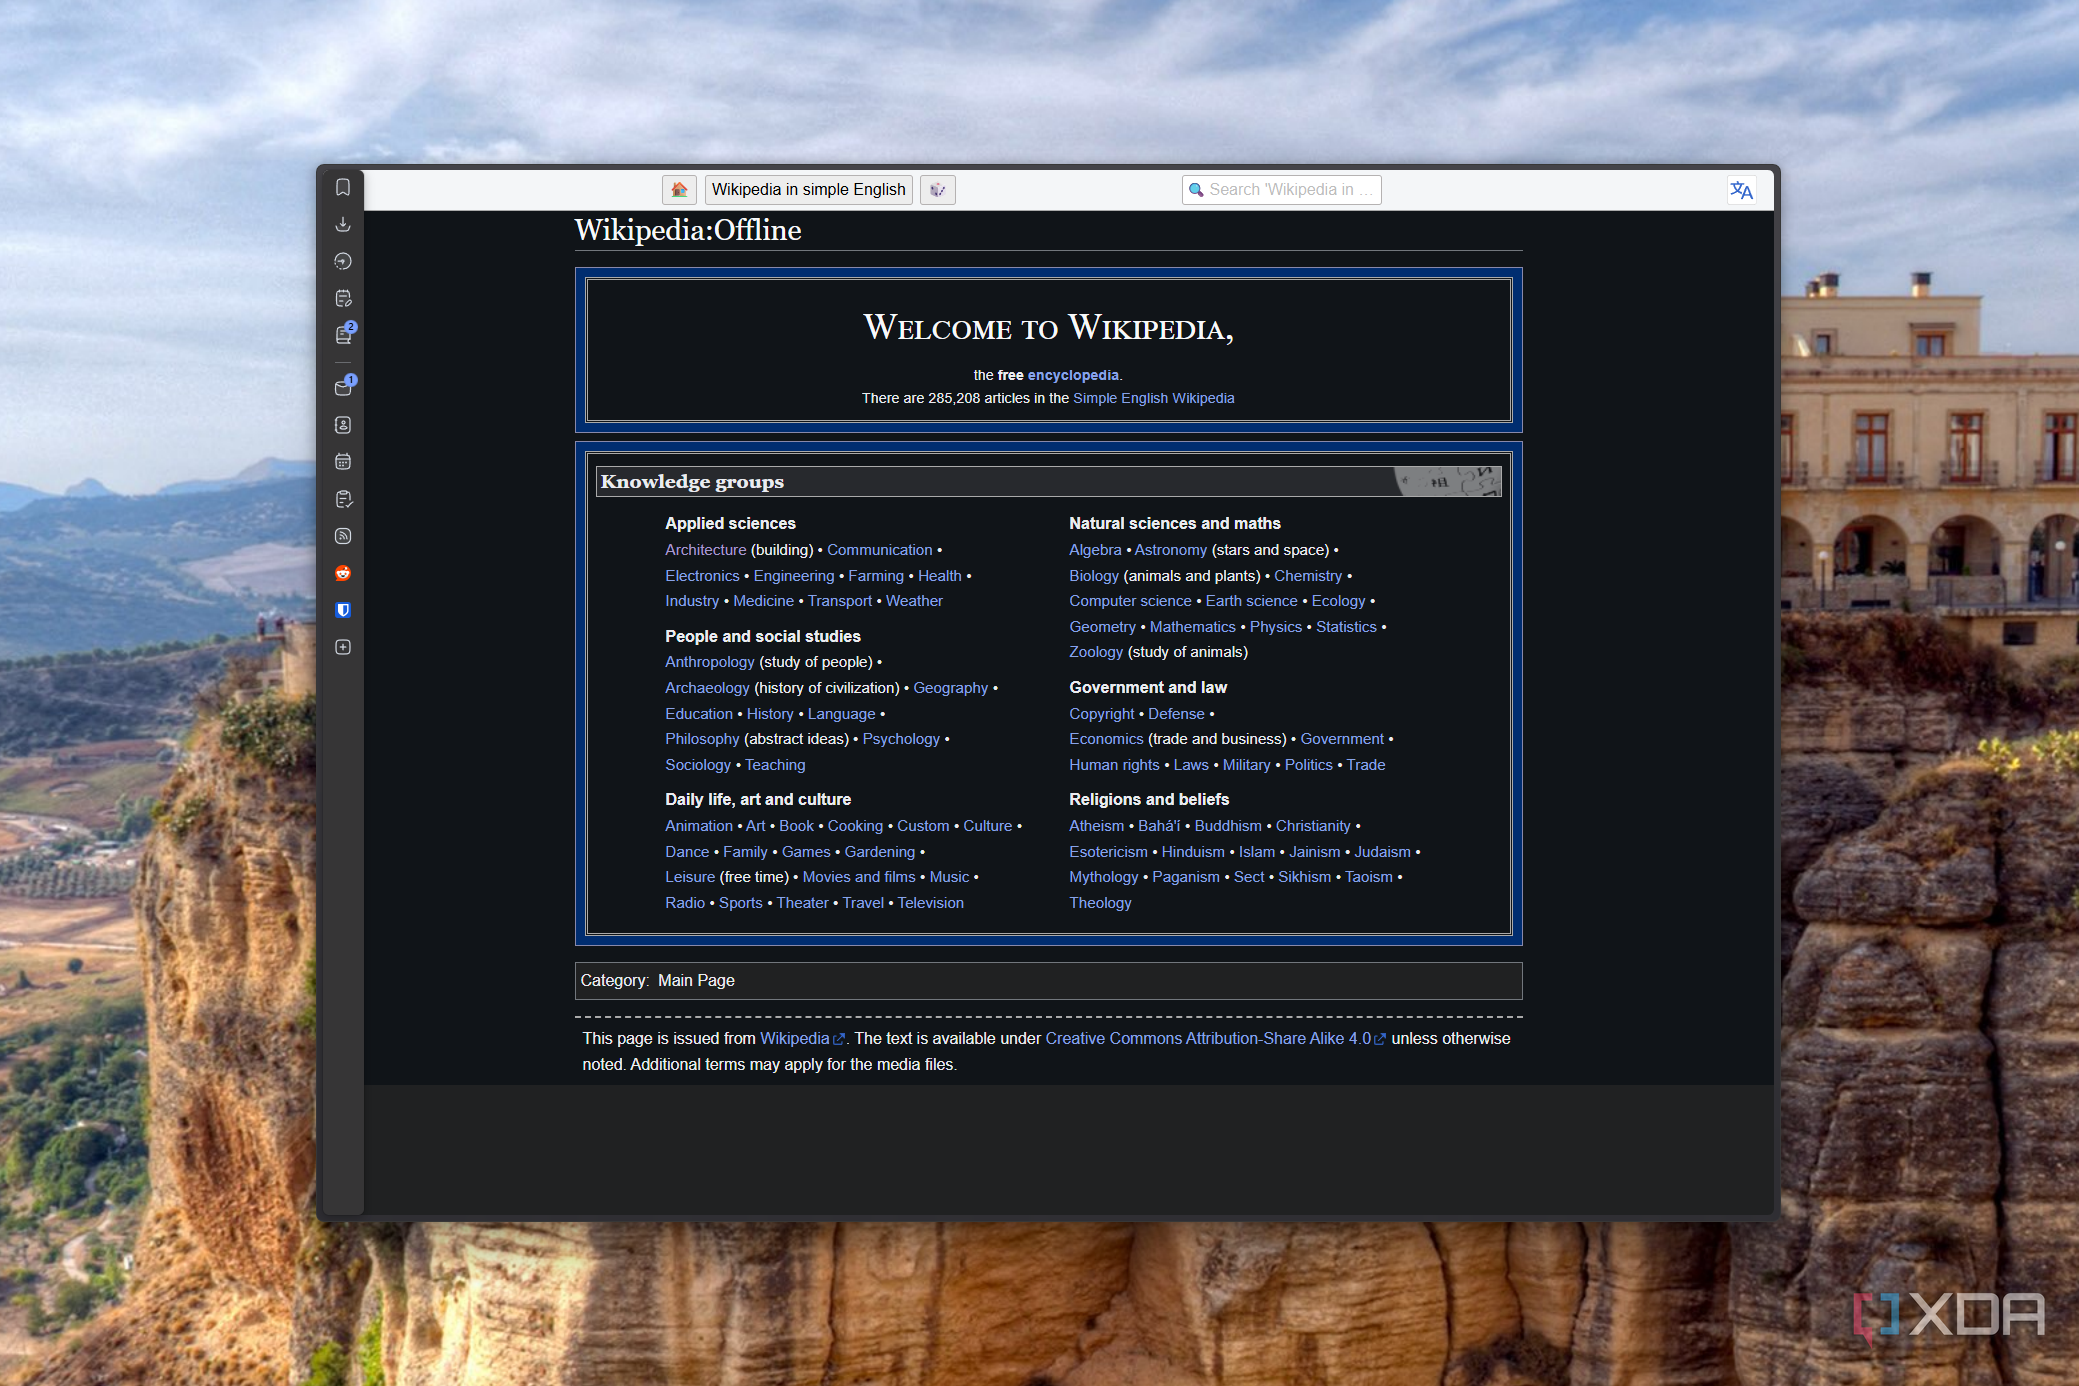
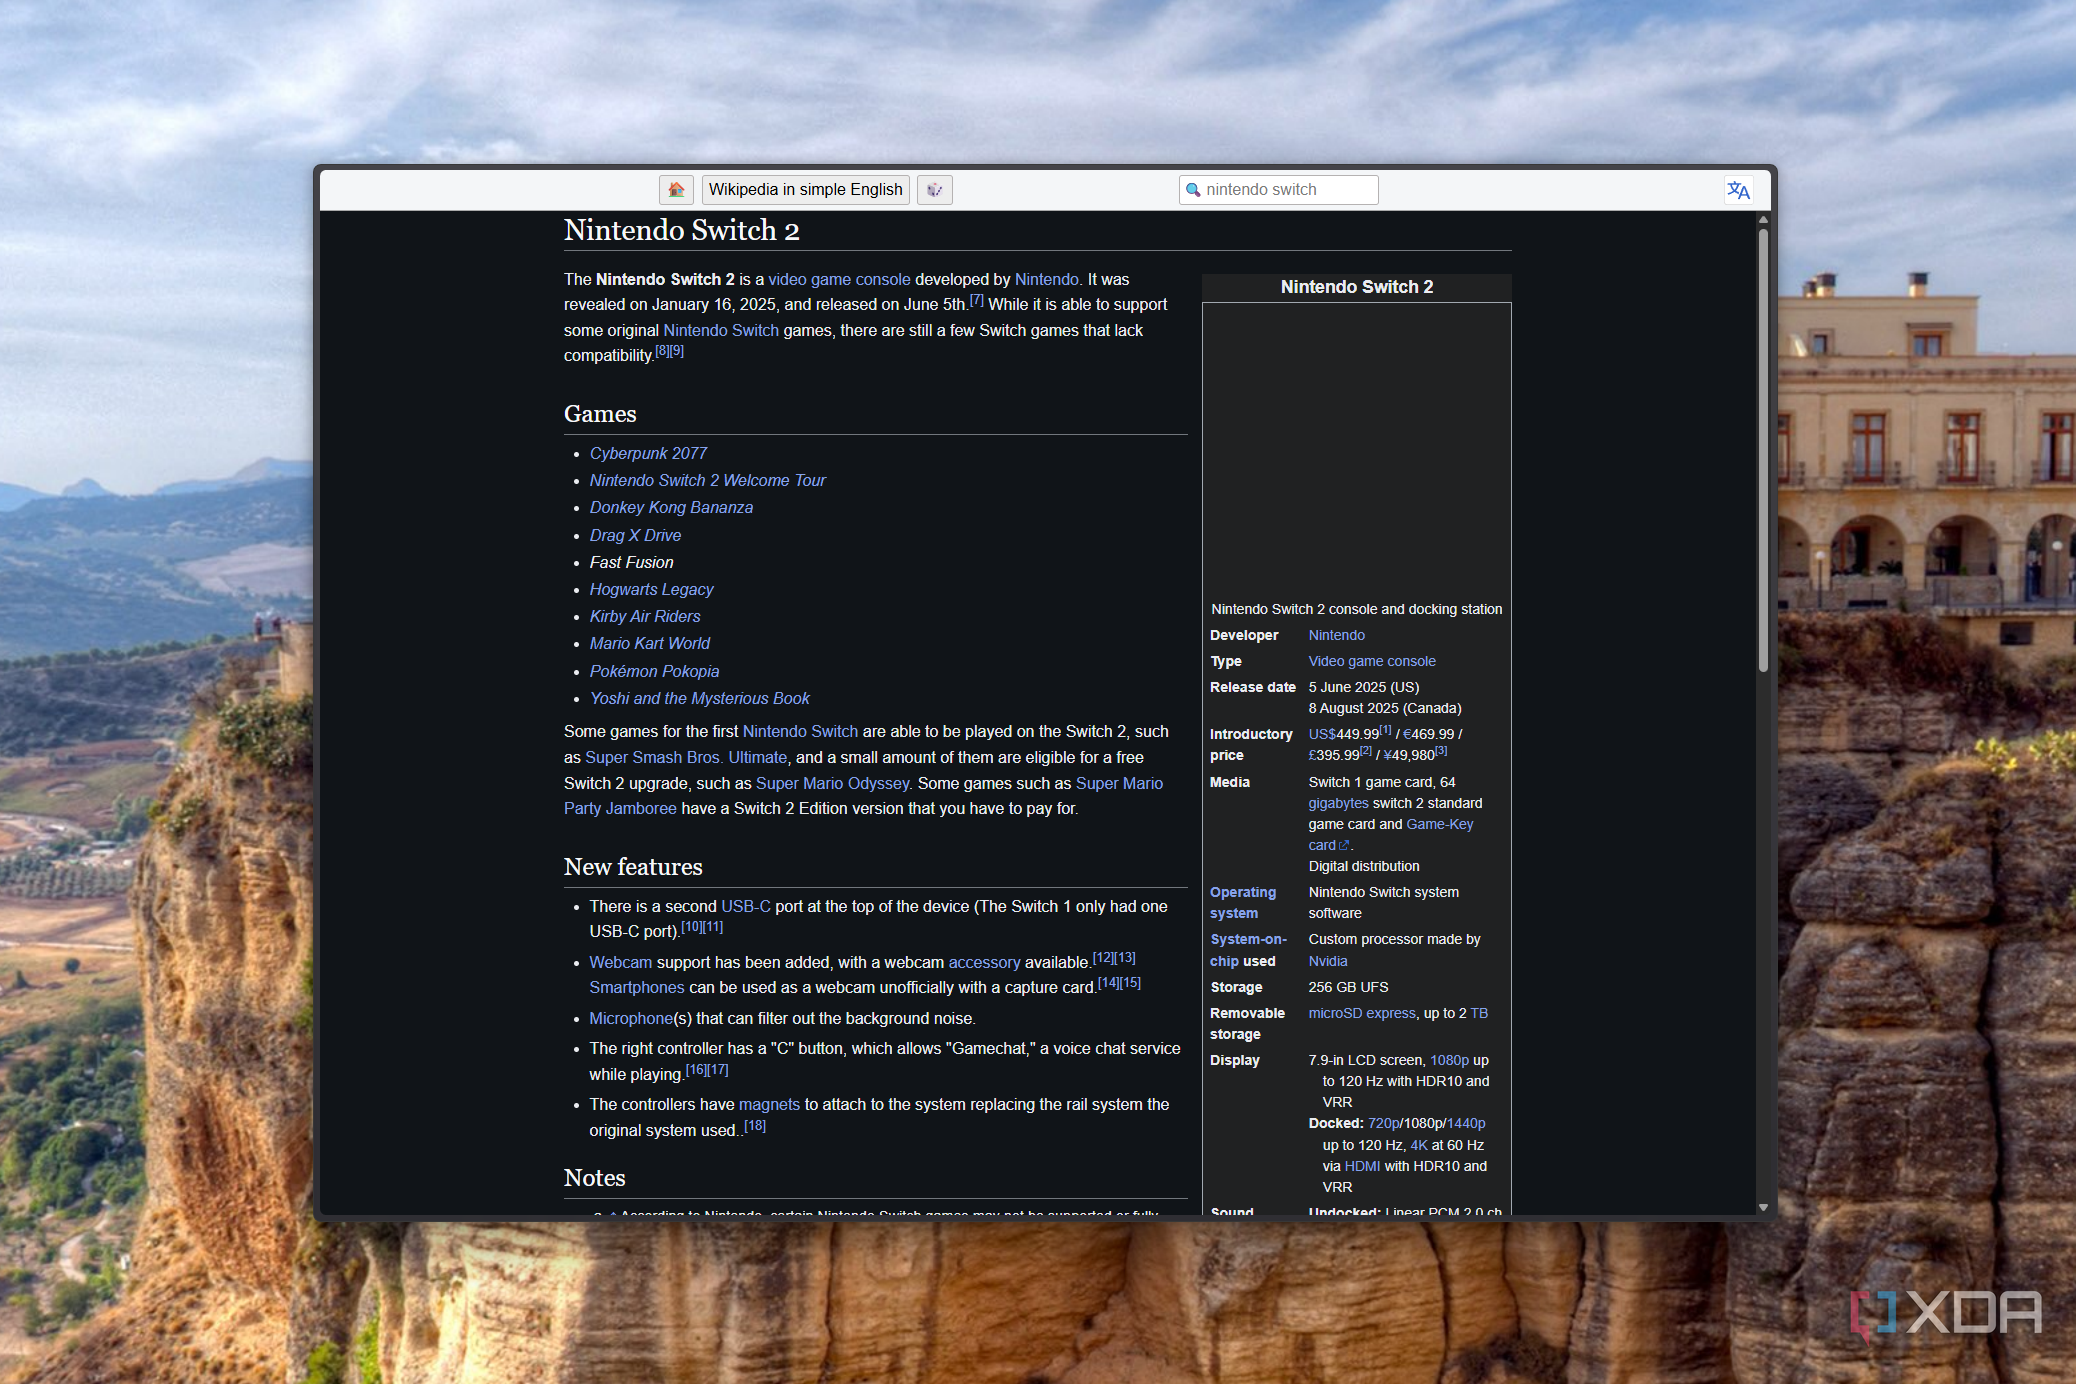
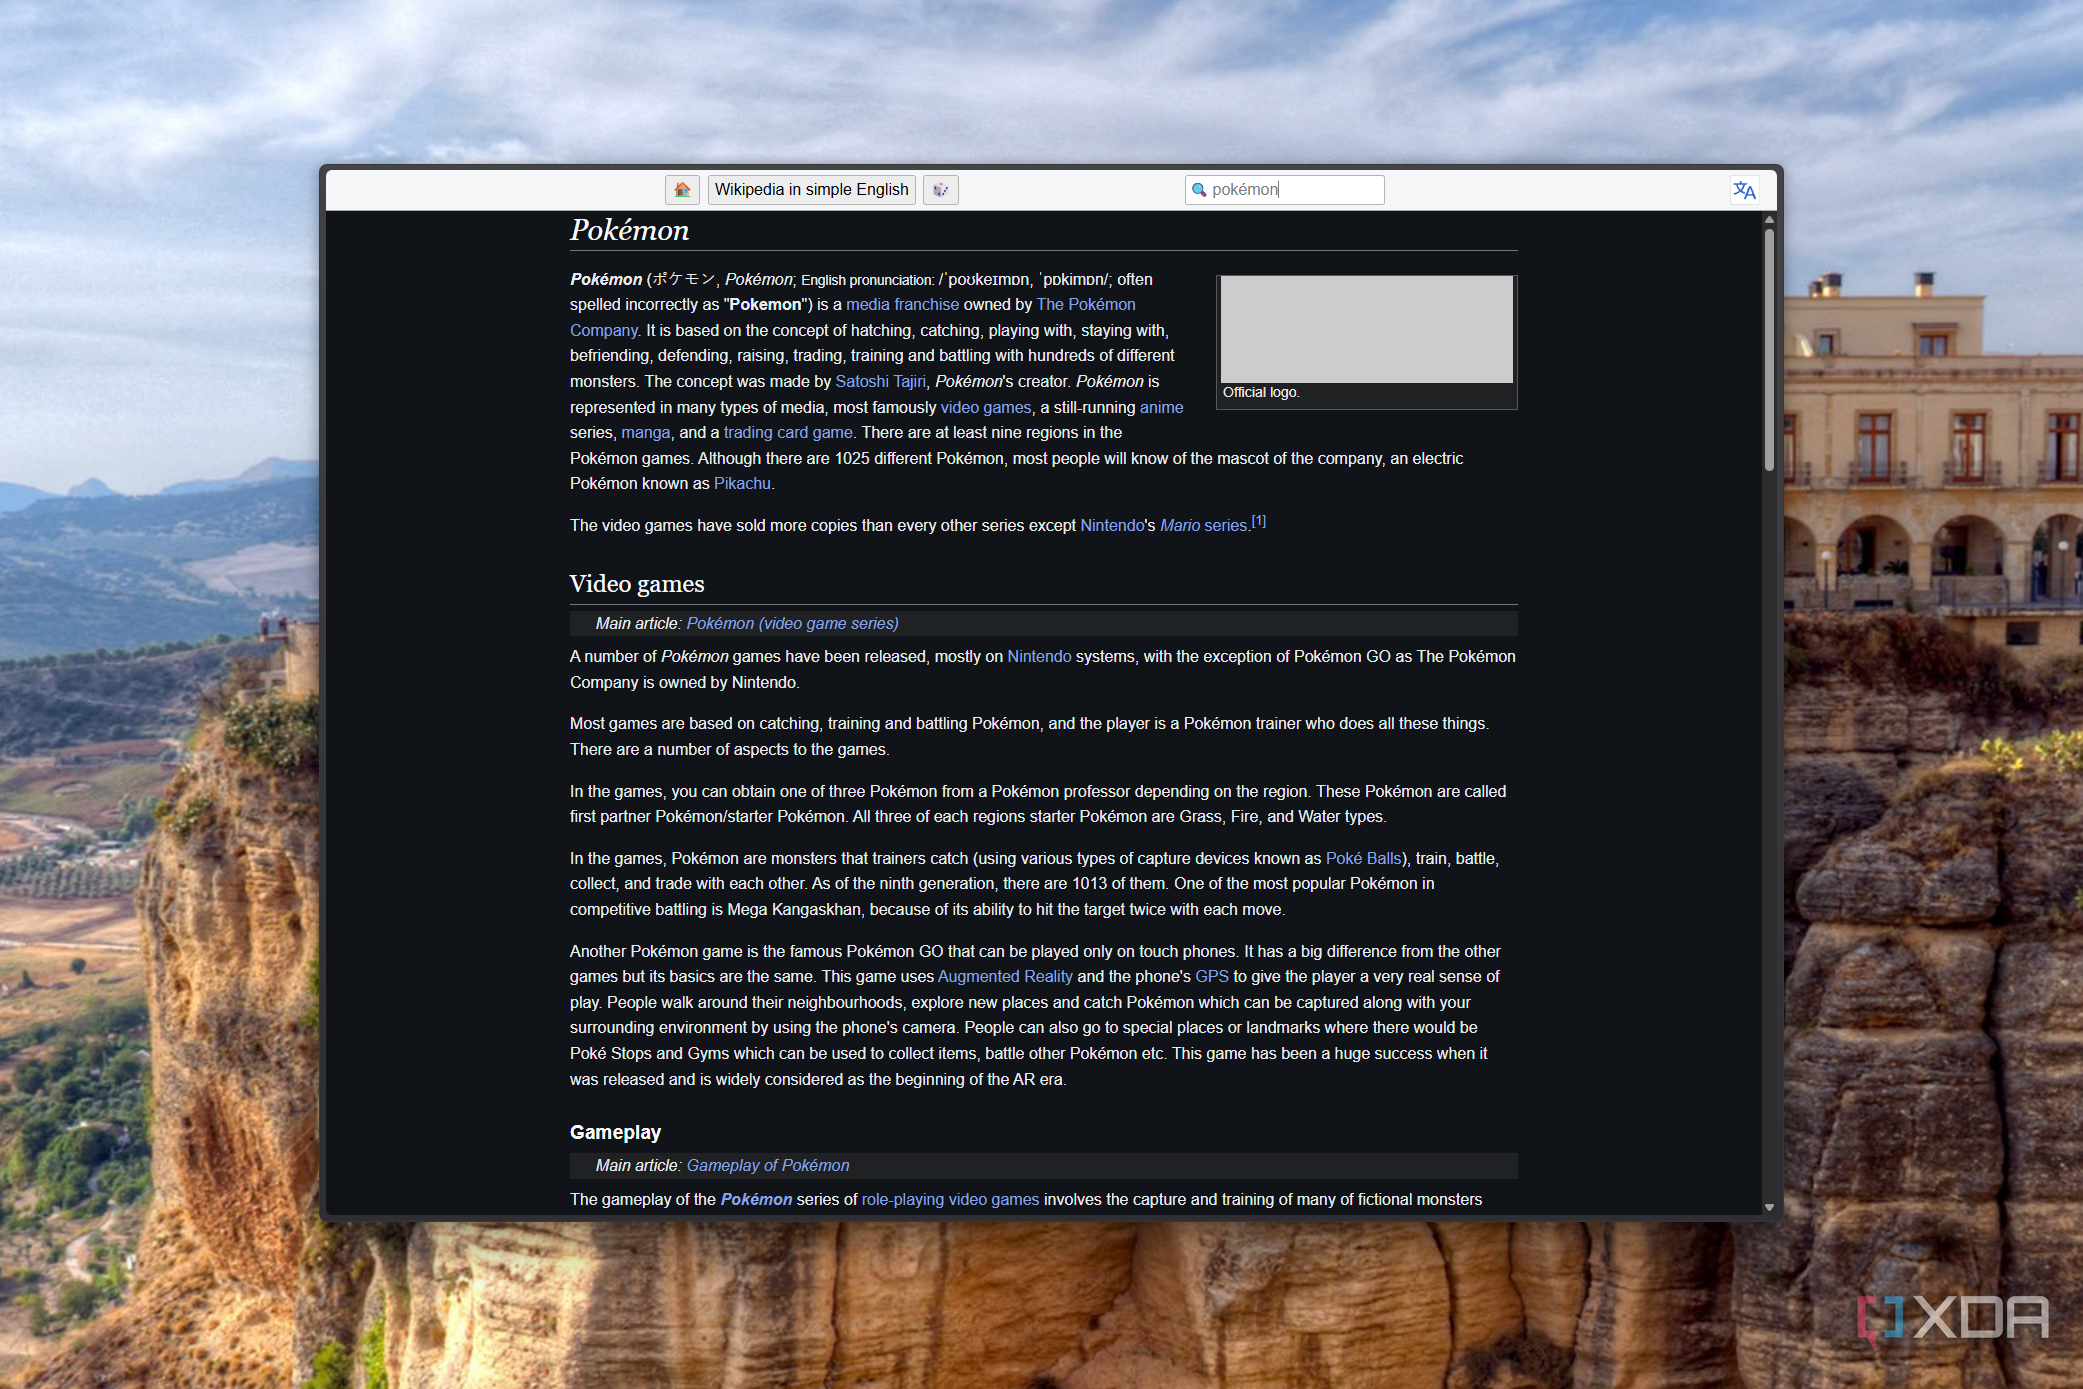
With the database downloaded and Kiwix rebooted to load it, I now have a tons of information available at my fingertips. Any database I choose to download is shown as a separate "book", so I could reasonably have multiple variants here, whether I want to focus on specific areas of study or to have different language variants of Wikipedia.
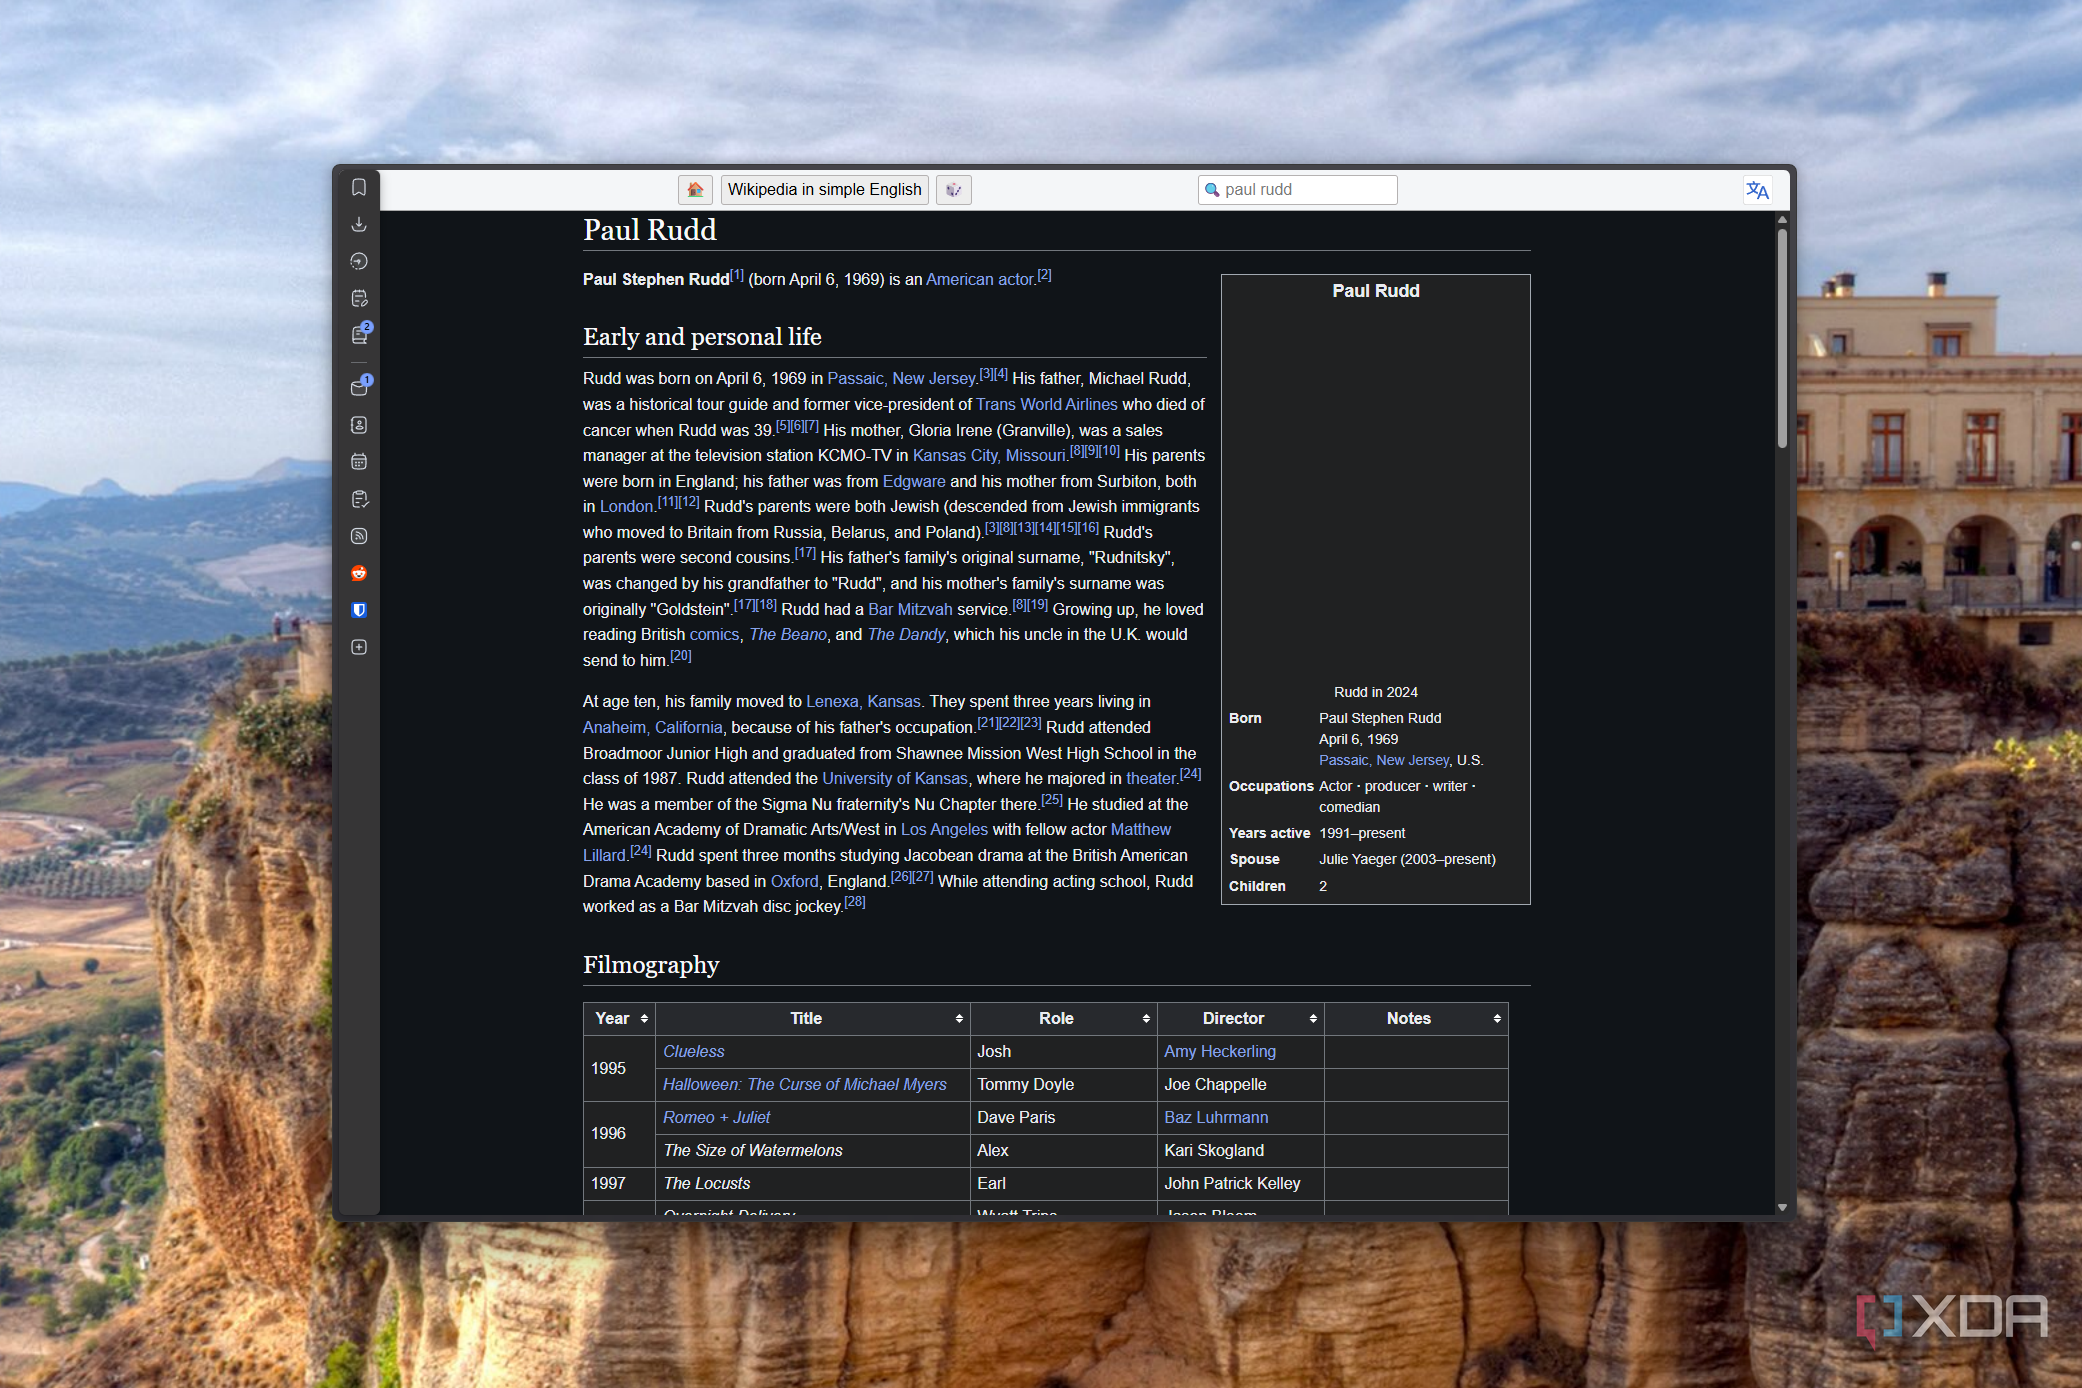
The Simple English version of Wikipedia may not have quite as much information, but I can look up Paul Rudd and see a list of the movies he's worked on, and that's already very cool. In fact, I can look up almost anything and get a relatively basic overview of that topic or person. Pages look basically just like they would on the internet version of Wikipedia, and links are preserved, too.
While the Wikipedia pages are viewable without internet, the included links naturally require an online connection, but it's still great to have them here. I can see the most important information offline, and if I need to check sources, I can still do it easily if I do have an internet connection.
Getting it to answer my questions
That's another challenge entirely

Now that I had my personal Wikipedia up and running, I wanted to see if I could ask it questions using natural language. This took a bit of work. First, I had to set up an MCP server that can query Kiwix, and I went with this one. There are others that can interact with the ZIM archives Kiwix relies on, though. I actually had to fix the main build file for this one, as it declares a "capabilities" parameter that doesn't seem to exist. After removing that specific portion from the main.ts file, I was able to use npm to build the MCP server and start running it.
Then, I had to use llama.cpp to download an LLM to use offline. I went with Qwen3.8-27B. I initially tried a distilled 4B version of this model, but I was getting a lot of incorrect information, so I had to step up to a more powerful model and hardware. I decided to run this part of the setup on a Minisforum AI X1 Pro review unit I had lying around, which has an AMD Ryzen AI 9 HX 370 processor and 64GB of DDR5 RAM.
Finally, I needed an agent harness to connect the MCP and the LLM so I could ask natural language questions. I installed Pi, added the MCP server to the configuration, and then connected it to the llama.cpp model I had on the machine. One particular setting I had to change within Pi was to change the MCP server exposure from the default codemode to direct. Otherwise, Pi seemed to bypass the MCP server when I asked any questions.
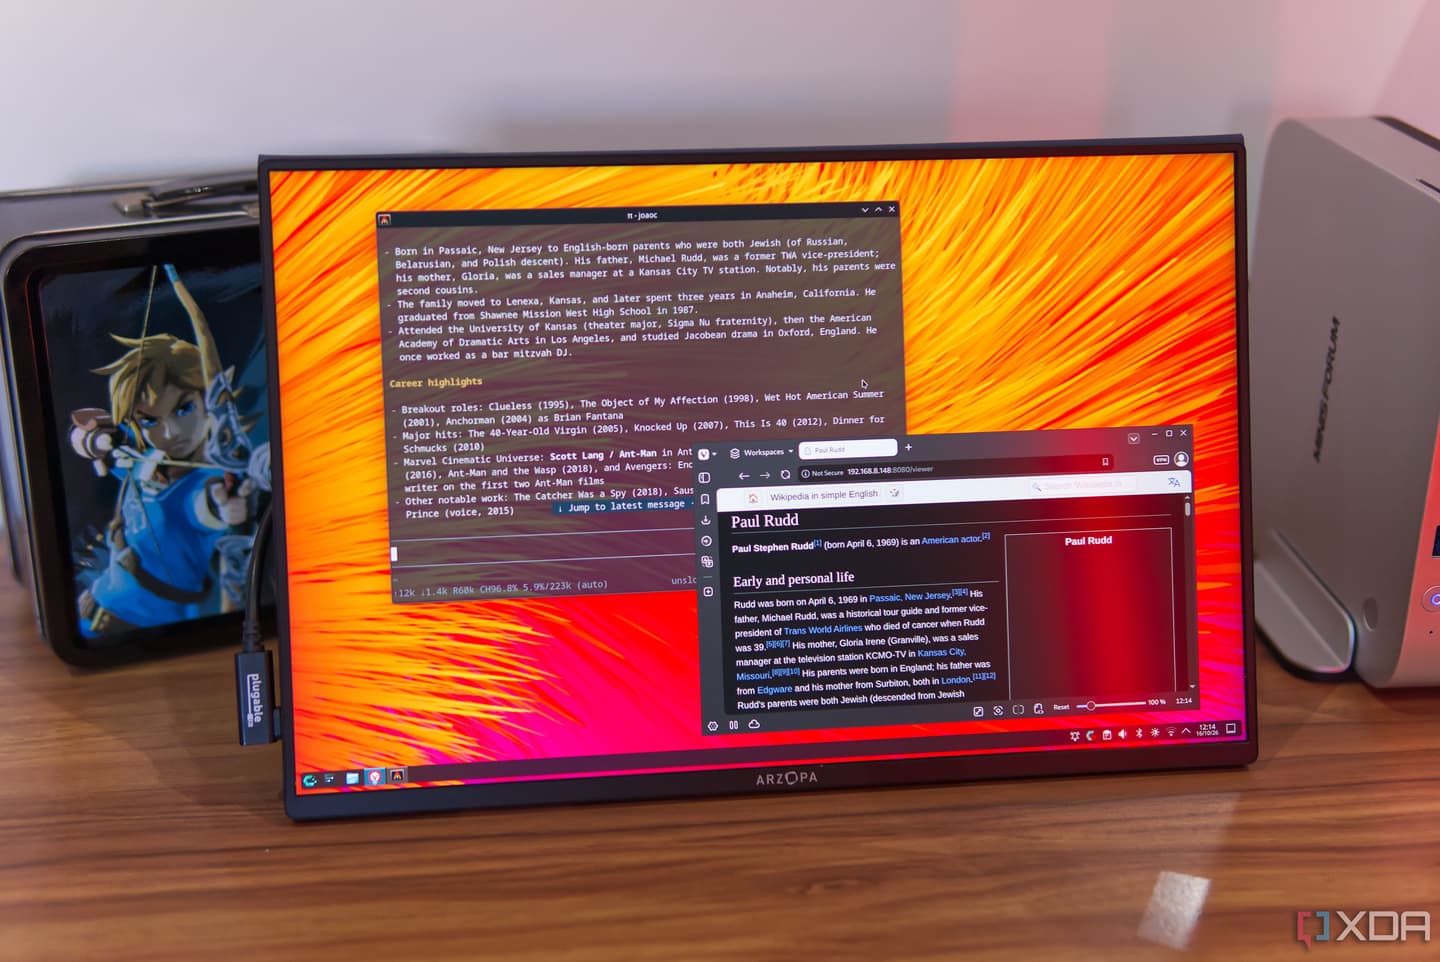
With all this finally done, I was able to ask Pi questions about these articles, and it was actually querying my Kiwix server to get answers without connecting to the internet. It does take a few minutes to get me answers, though.
It's (mostly) accurate
Results can be hit or miss for longer pages
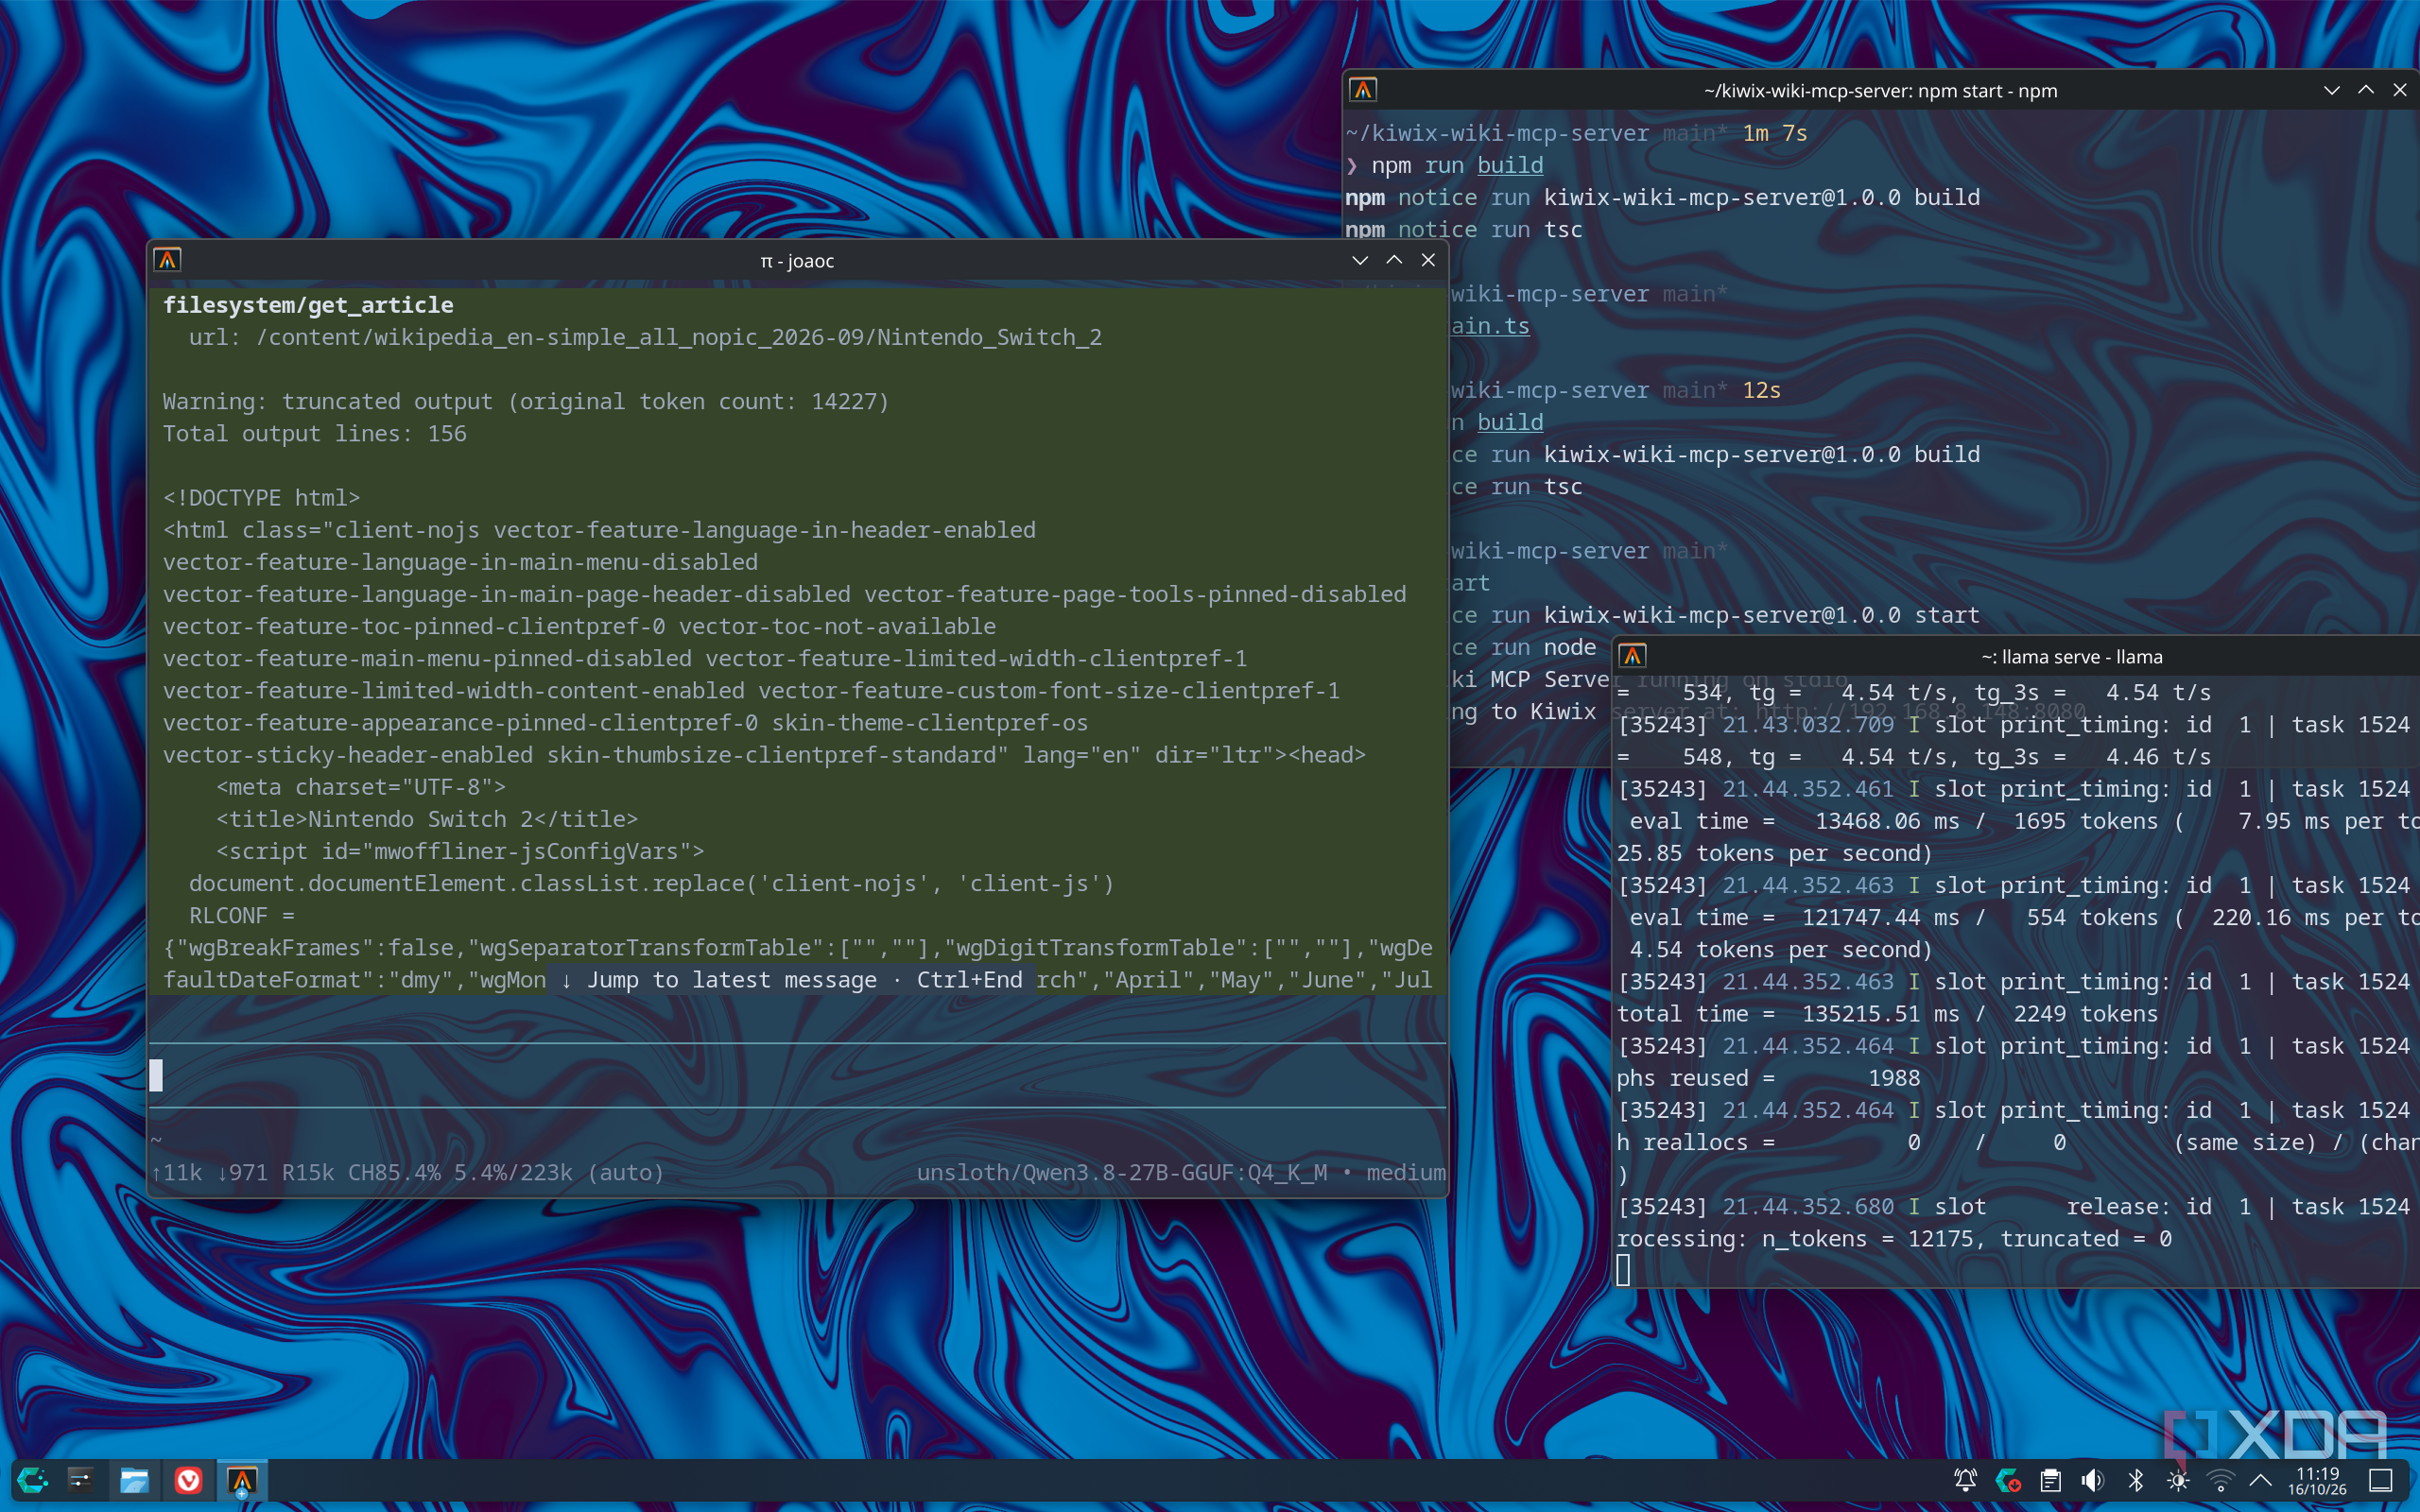
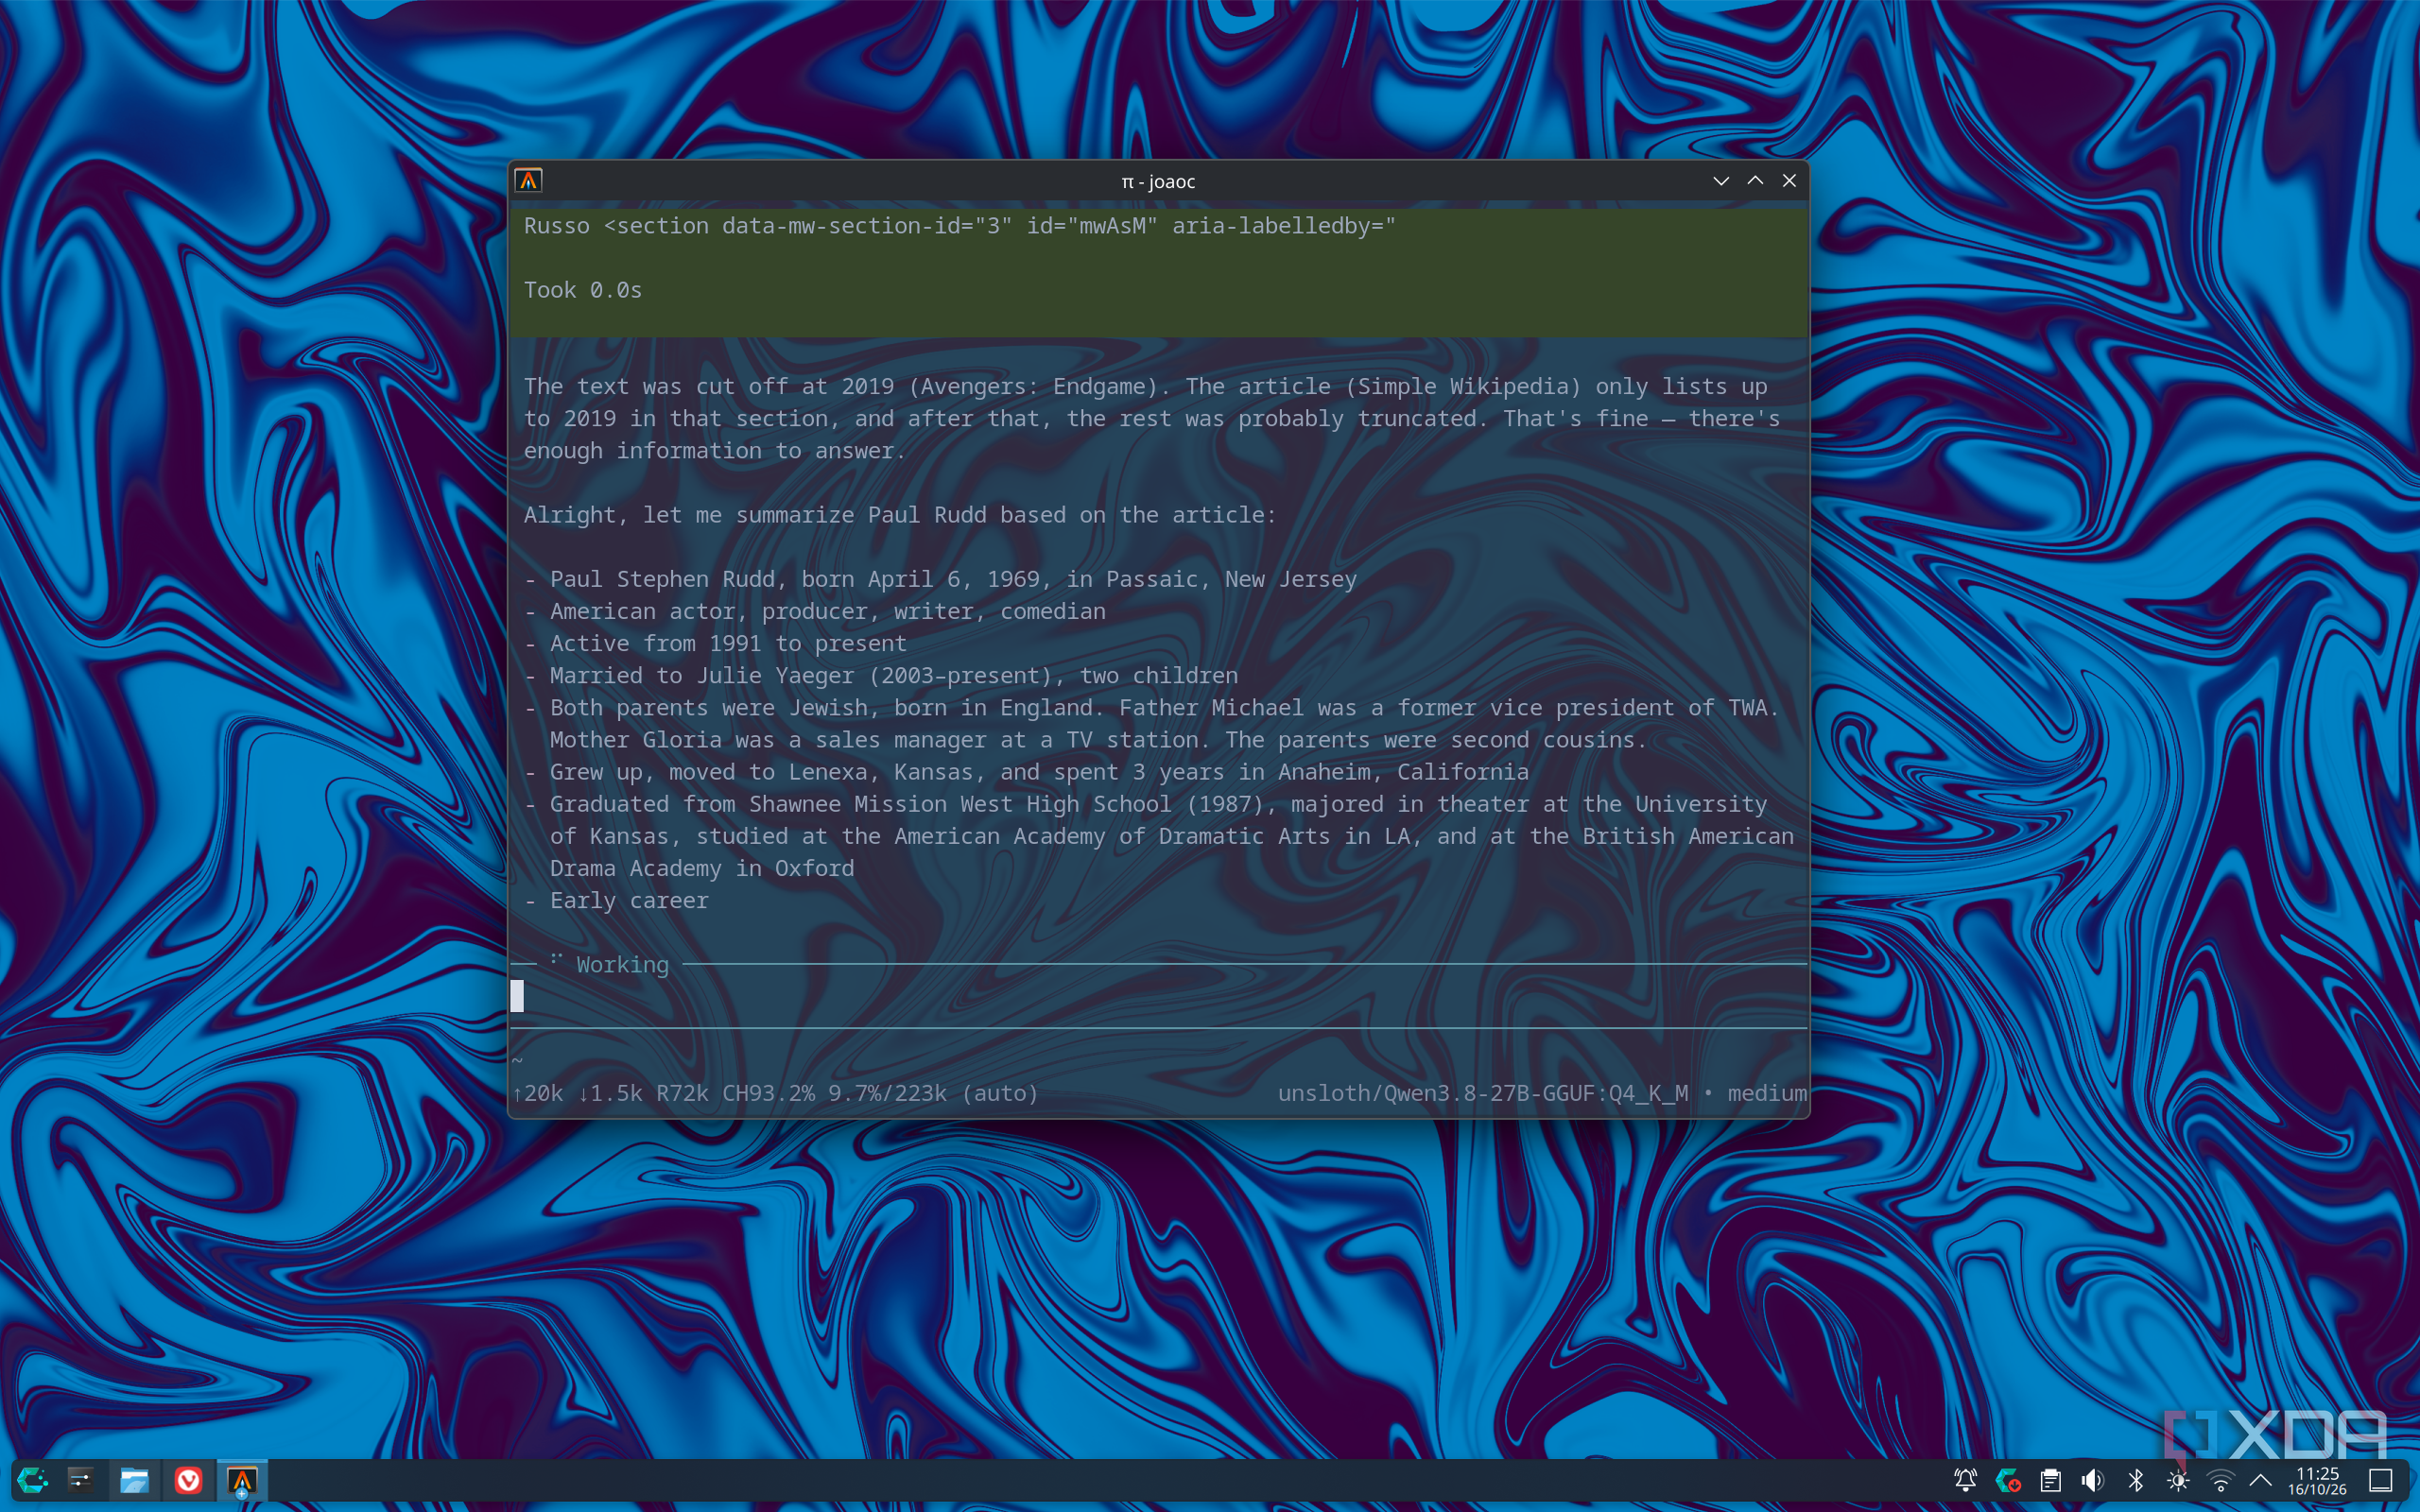
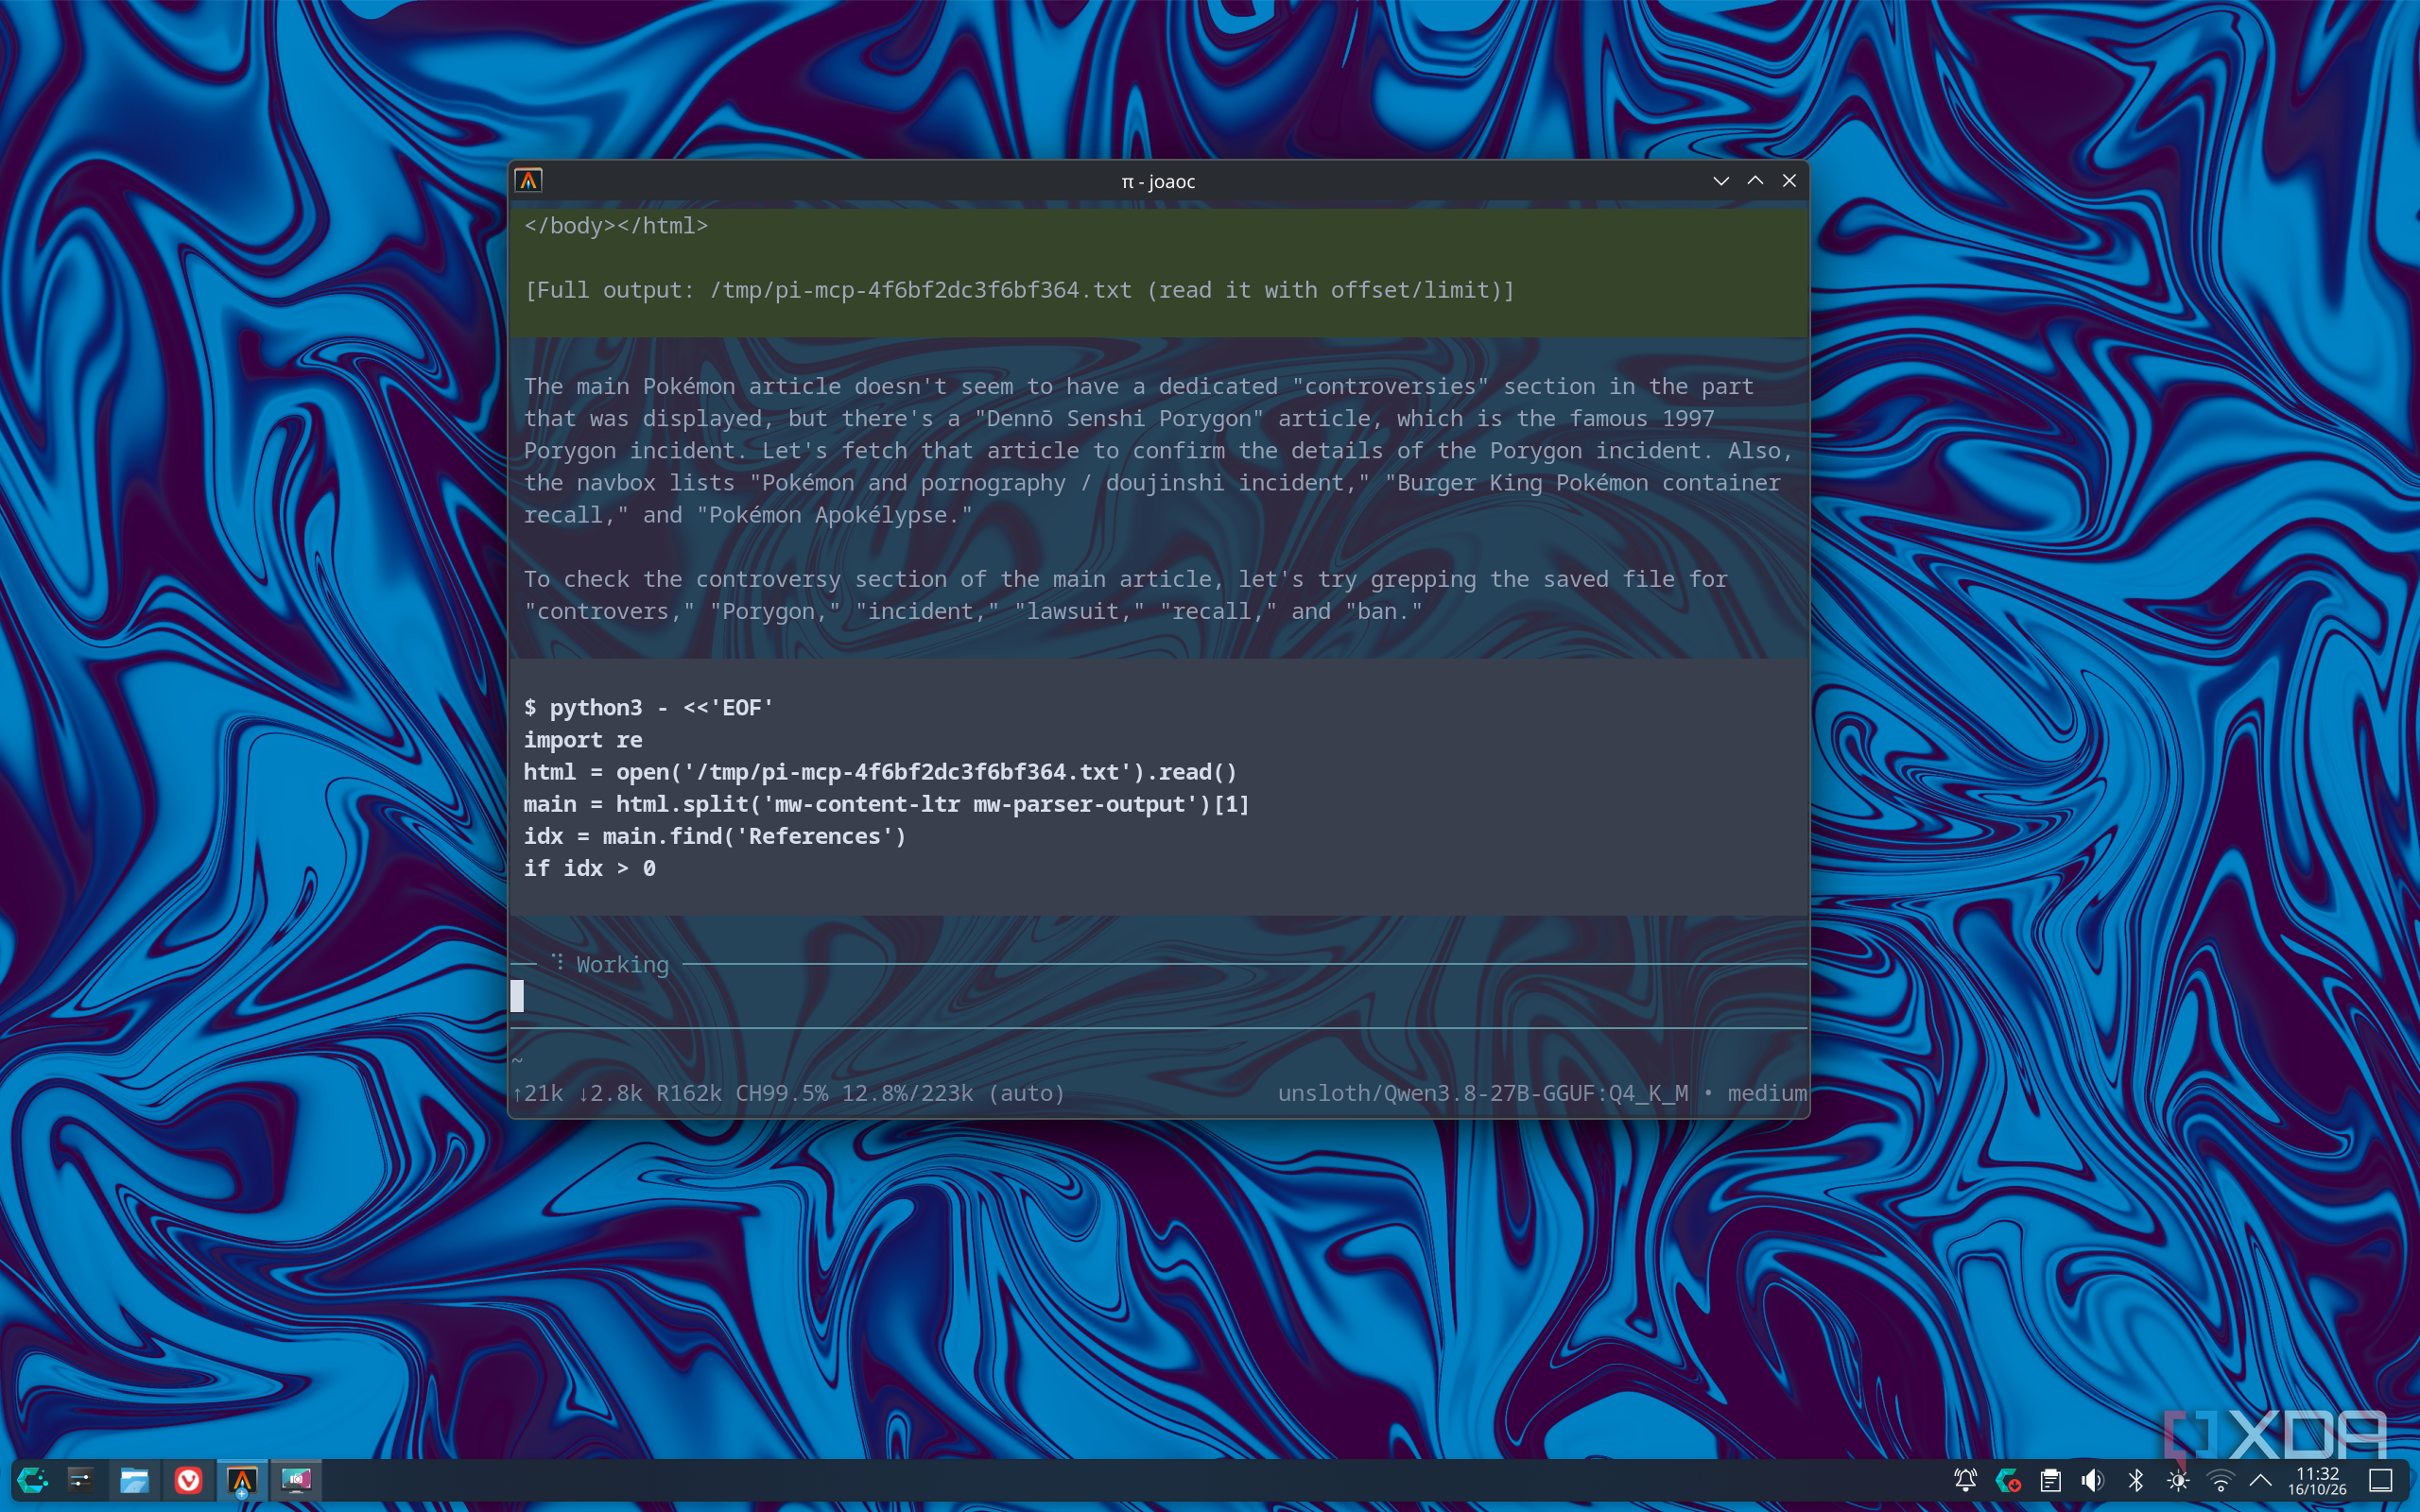
While I was able to get this to work, I did notice some issues when trying to set this up, which may have contributed to why I needed a 27-billion-parameter model to get usable answers in the first place. When calling the tools enabled by the MCP server, I noticed the target content was parsed as plain text with all the HTML tags, which were then crudely stripped in the following step, potentially wasting tokens and resulting in a worse job extracting information.
That may be why using a 4-billion-parameter model resulted in gibberish answers. When I asked "Who is Paul Rudd?", while it got basic details like his name and birthday right, the filmography was completely made up.
Upgrading to a 27-billion-parameter model, I was able to get much closer to reality, but still not perfect. It got most of the details about Paul Rudd's filmography right, except it claimed his character's name in the Marvel Cinematic Universe is Pete Peterson (it should be Scott Lang) and made up a movie called Down and Out with the Ducks. Interestingly, these errors weren't repeated on a second run of the query.
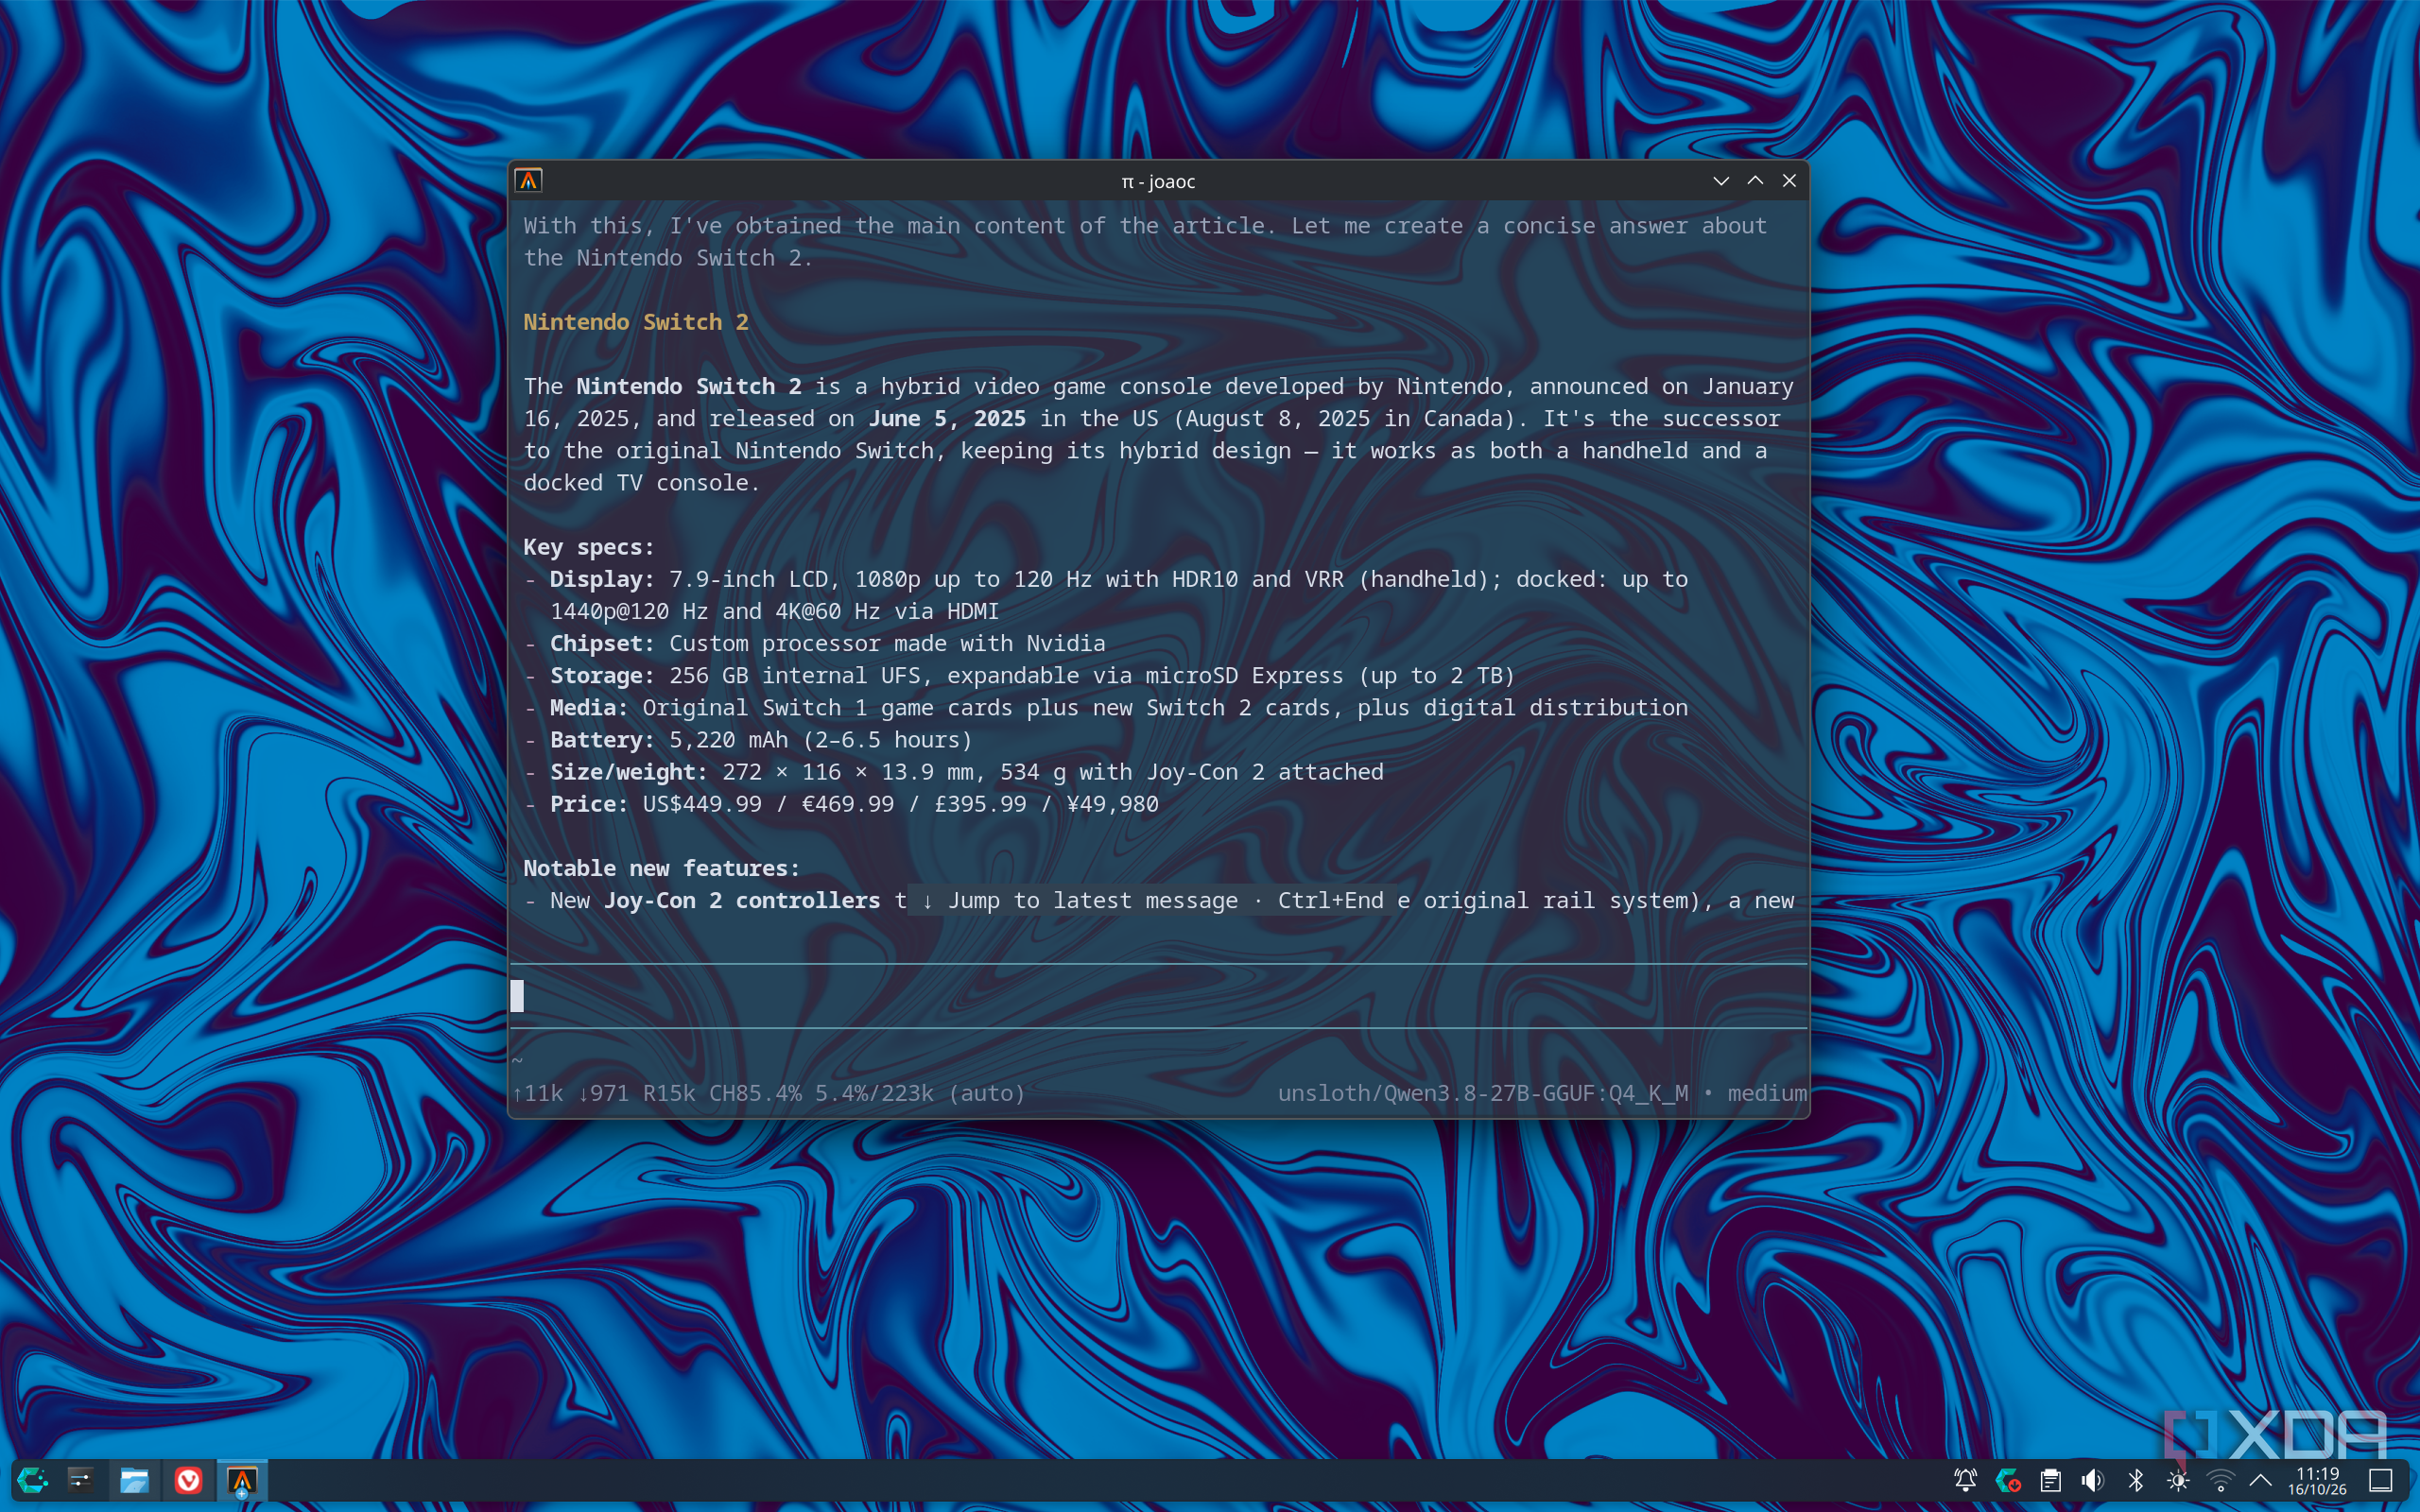
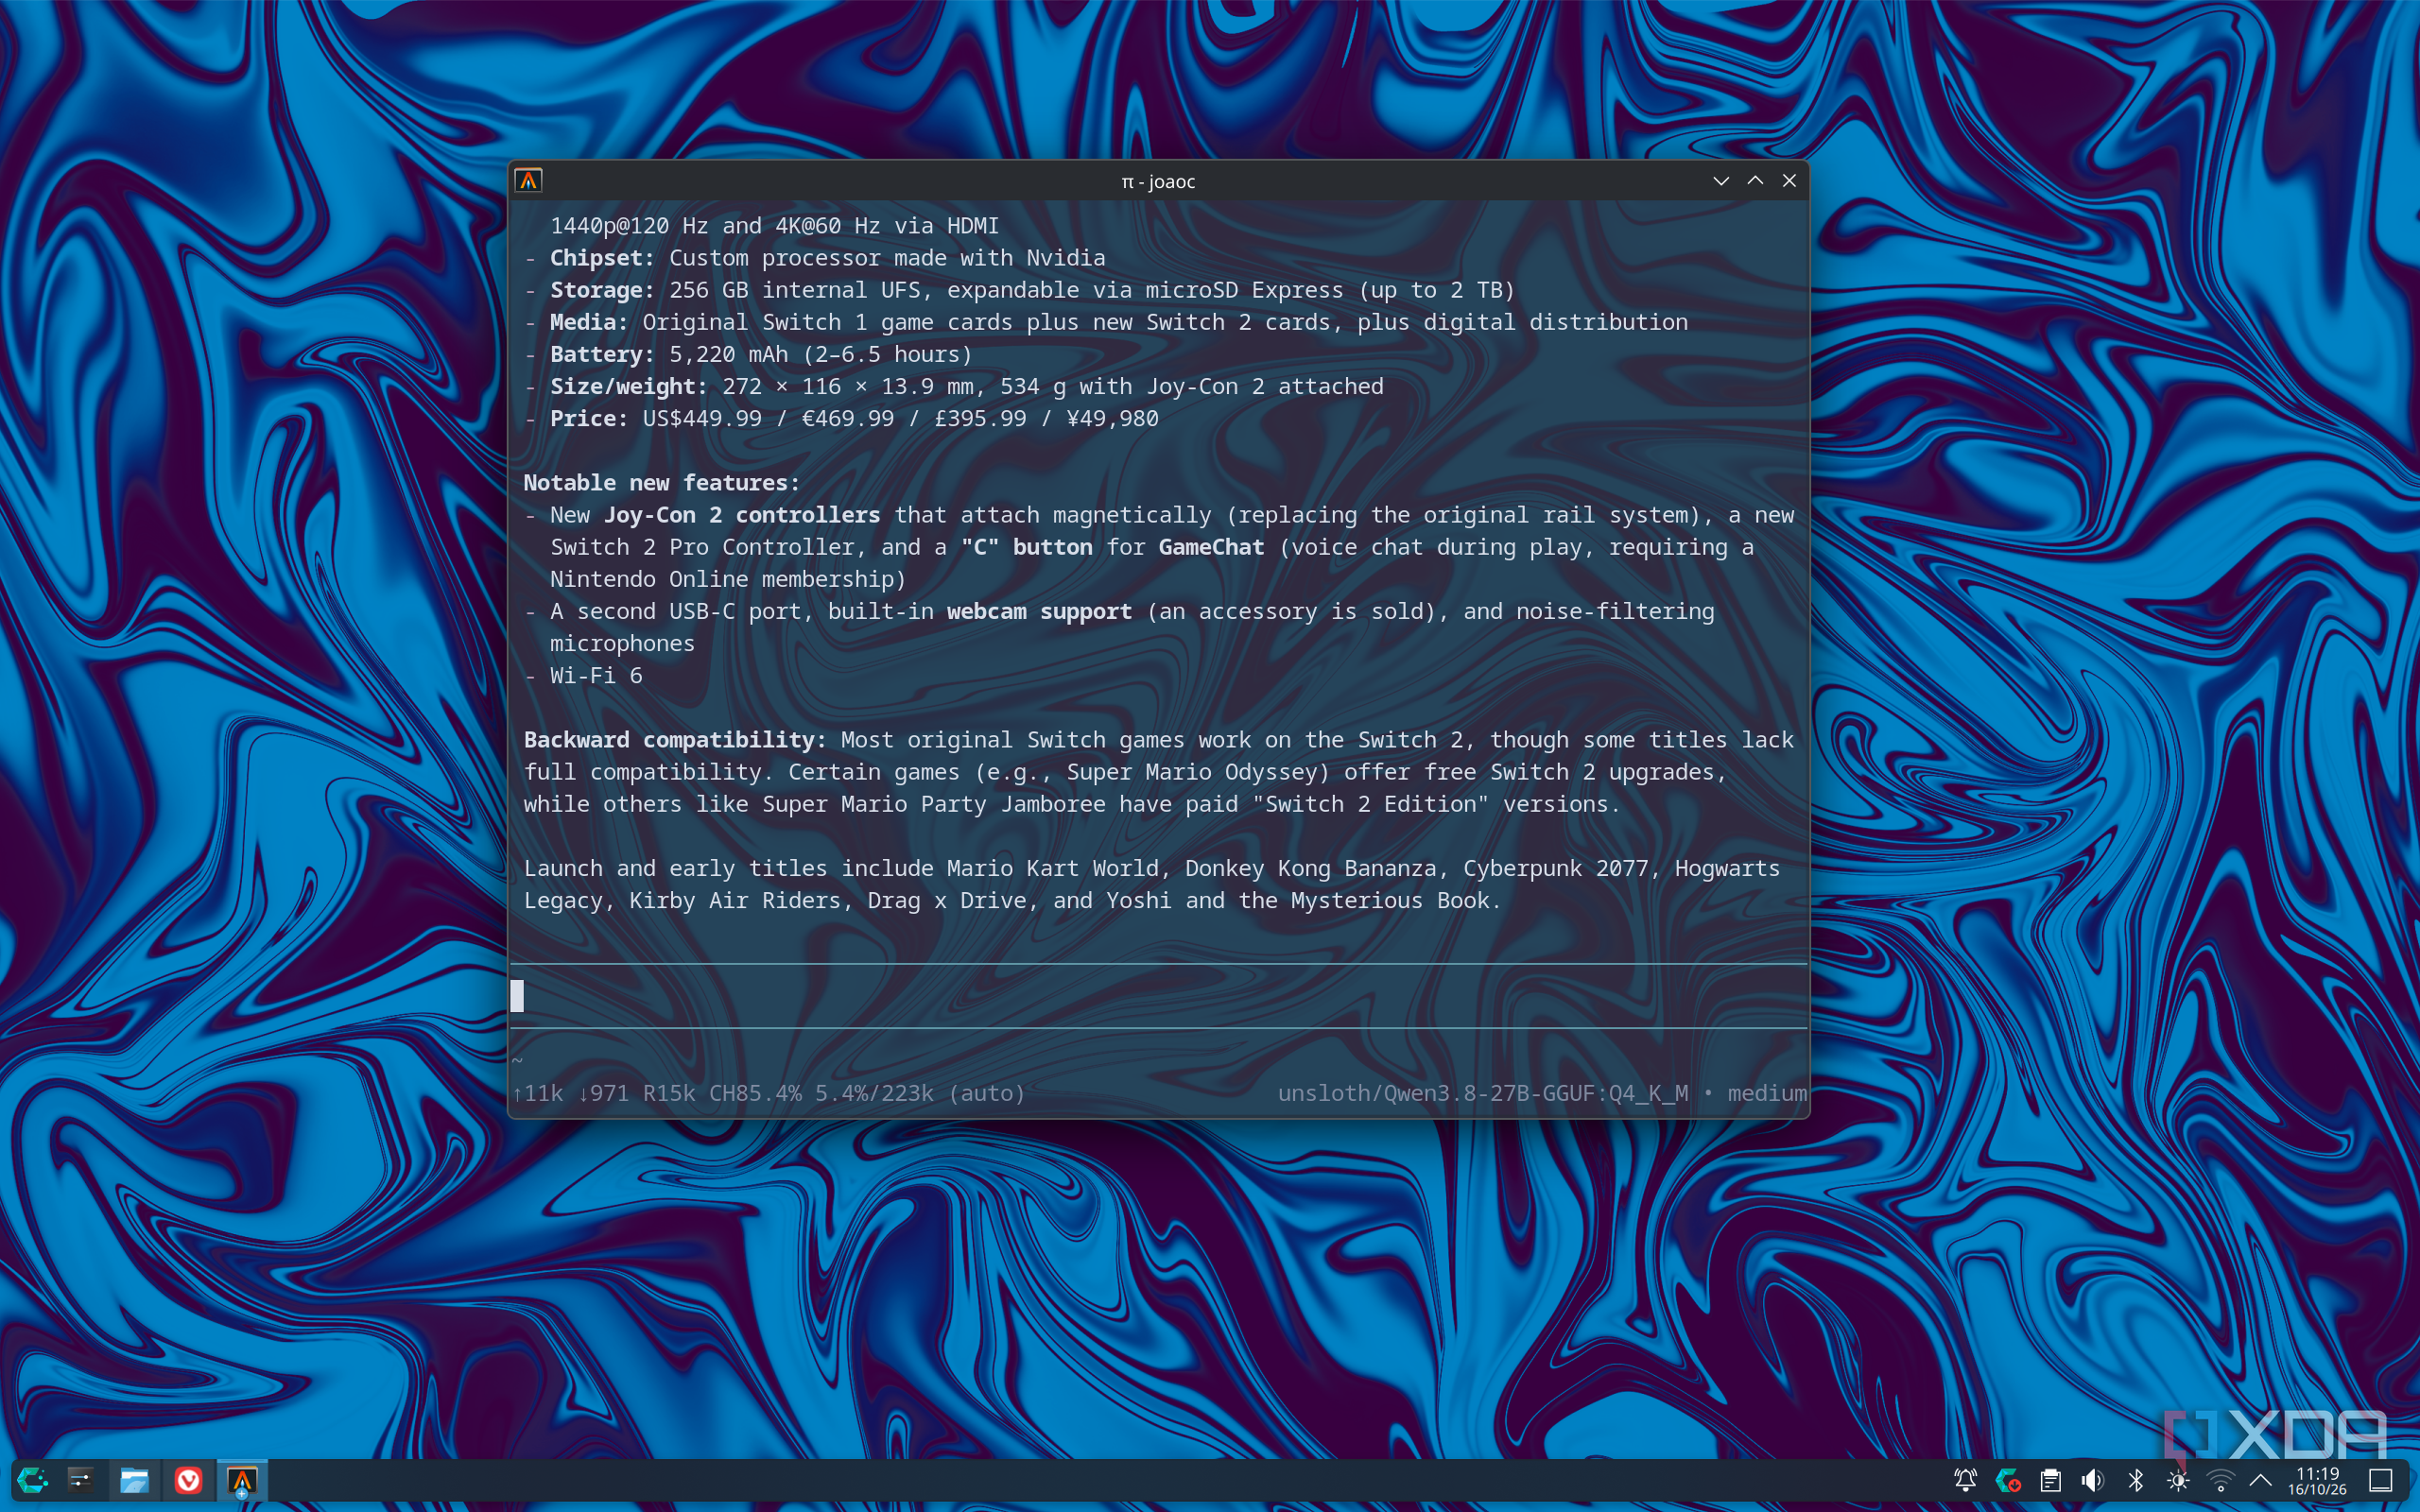
I also asked it "What is the Nintendo Switch 2?", and in this case, the response pretty much completely accurate. It told me the exact reveal and launch date in the US, it highlighted all they key specs accurately, and even included some information about early titles on the platform, all of which were accurate. It mentioned that the console launched on August 8 in Canada, but after checking Kiwix, it seems like that information was wrong in the Wikipedia database, too, so it's not a problem with the model.
The big difference between the two is the size of the page, and the fact that Paul Rudd's page on the Simple English Wikipedia has a fairly long table. The HTML tags for it may have taken a significant chunk of tokens while processing the request and hurt the quality of the output as it scanned further down the page.
It's still amazing
Even if the responses I get from my LLM aren't 100% accurate to the information on Kiwix, this entire process is kind of amazing. Simply having my own Wikipedia that I can use offline is already very cool, but it's made even better when I can set up a local LLM to query that database and answer questions for me, all without going to the internet. It may have some gaps, but it still works pretty well.