


I’m Adam Conway, an Irish technology fanatic with a BSc in Computer Science and I'm XDA’s Lead Technical Editor. My Bachelor’s thesis was conducted on the viability of benchmarking the non-functional elements of Android apps and smartphones such as performance, and I’ve been working in the tech industry in some way or another since 2017.
In my spare time, you’ll probably find me playing Counter-Strike or VALORANT, and you can reach out to me at adam@xda-developers.com, on Twitter as @AdamConwayIE, on Instagram as AdamConwayIE, or u/AdamConwayIE on Reddit.
Sign in to your XDA account
When talking about laptops with 128GB of unified memory, conversations naturally gravitate towards local LLMs. It's the pretty obvious pitch when it comes to Nvidia's RTX Spark, after all, given its close relation to the DGX Spark's GB10. What's more, being able to run Qwen3.8 Flash Next in a device that you can carry around is pretty incredible. I did exactly that with the HP OmniBook Ultra 16, but I also wanted to see what you can do with all that memory if you aren't running local AI.
As a result, I decided to give Blender a go. In a way, large 3D scenes aren't too dissimilar from LLMs when talking about memory limitations. If you do a lot of heavy Blender work with scenes that outgrow a conventional gaming GPU, the usual solution is an incredibly expensive workstation card. I combined the two: I had a local LLM build a procedural city in Blender with an adjustable detail setting, then increased the complexity until a single Cycles render was using roughly 49GB of GPU memory.
That 49GB of GPU memory that the Blender render used in this test was considerably more than an RTX 5090 has, and even exceeds the 48GB RTX PRO 5000 workstation card. Rendering each of my 1080p frames took around 12 minutes, with the laptop's fans going flat out, but it worked, which is more than you could say for a machine with less VRAM.
The RTX Spark gives its GPU a slice of system memory
You can decide how much it gets

HP sent me the top configuration of the OmniBook Ultra 16 for performance evaluation and testing, and it comes with Nvidia's 20-core Grace CPU, a 6,144-core Blackwell GPU, and 128GB of LPDDR5X-9400. It costs $6,229.99 on HP's store, which is a lot of money a laptop, though less than some of the workstation GPUs I'll compare it against later. The CPU and GPU share that memory over a 256-bit bus with 300GB/s of bandwidth.
Windows doesn't treat that memory as one big pool, though. The RTX Spark reserves a portion of it for the GPU, which Windows reports as dedicated GPU memory, in the same way that it sees VRAM on a discrete graphics card. Nvidia refers to this VRAM pool as a "carveout," allowing users to adjust it up to 96GB through the Nvidia app. I left mine at the default 64GB throughout testing, with the remaining memory split between shared CPU/GPU memory and CPU-only memory. The model actually overflowed the default 64GB carveout, yet I didn't realize until after.
For CUDA allocations, these end up using the dedicated carveout first, then overflow into shared memory when it's full. For a typical desktop graphics card workload, that means falling back to system RAM over PCIe, but on the RTX Spark, both regions use the same physical LPDDR5X chips, so overflow cross a slower PCIe connection. Nvidia says the dedicated region benefits from larger memory pages and other driver optimisations, meaning allocations in shared memory can still be slower, even if they're faster than a PCIe fallback.
Until recently, Blender couldn't use RTX Spark's GPU for CUDA or OptiX rendering on Windows on Arm. Support was added in September, with those changes arriving in the beta version Blender 5.3. It's specifically built with the RTX Spark in mind, while also packing unified memory optimizations. All of the previous Blender results I've seen for the RTX Spark used CPU rendering, so I installed the 5.3 beta to test GPU rendering for myself.
A local LLM designed the entire city
Qwen 3.8 Flash Next handled it all

I'm not much of a Blender guy; I've used tools like Solidworks and Onshape for CAD projects, but designing an environment that would tax a GPU isn't something I'm particularly skilled at. Instead, I asked Qwen3.8 Flash Next running locally using llama.cpp paired with a 262K context window to build it, made easy thanks to Nvidia publishing an RTX Spark recipe that uses Unsloth's IQ4_XS quantization of the model. The model has 125 billion parameters, but its mixture-of-experts architecture activates only six billion per token, allowing for up to 45 tokens per second. I connected it to Pi, Mario Zechner's minimal coding agent, and gave it a prompt to build an abandoned futuristic city with roads, industrial structures, vehicles, vegetation, and dusk lighting.
As well, I told the model that it shared memory with Blender, so it needed to develop and test the scene at lower detail levels before producing a standalone PowerShell script for the final renders that I could run with the inference server shut down. From the initial prompt to the first full-size Cycles render took around 81 minutes, without any intervention from me. During that time, the model found Blender in my Downloads folder, verified that OptiX worked, wrote the scene generator, and refined it by rendering and inspecting previews.
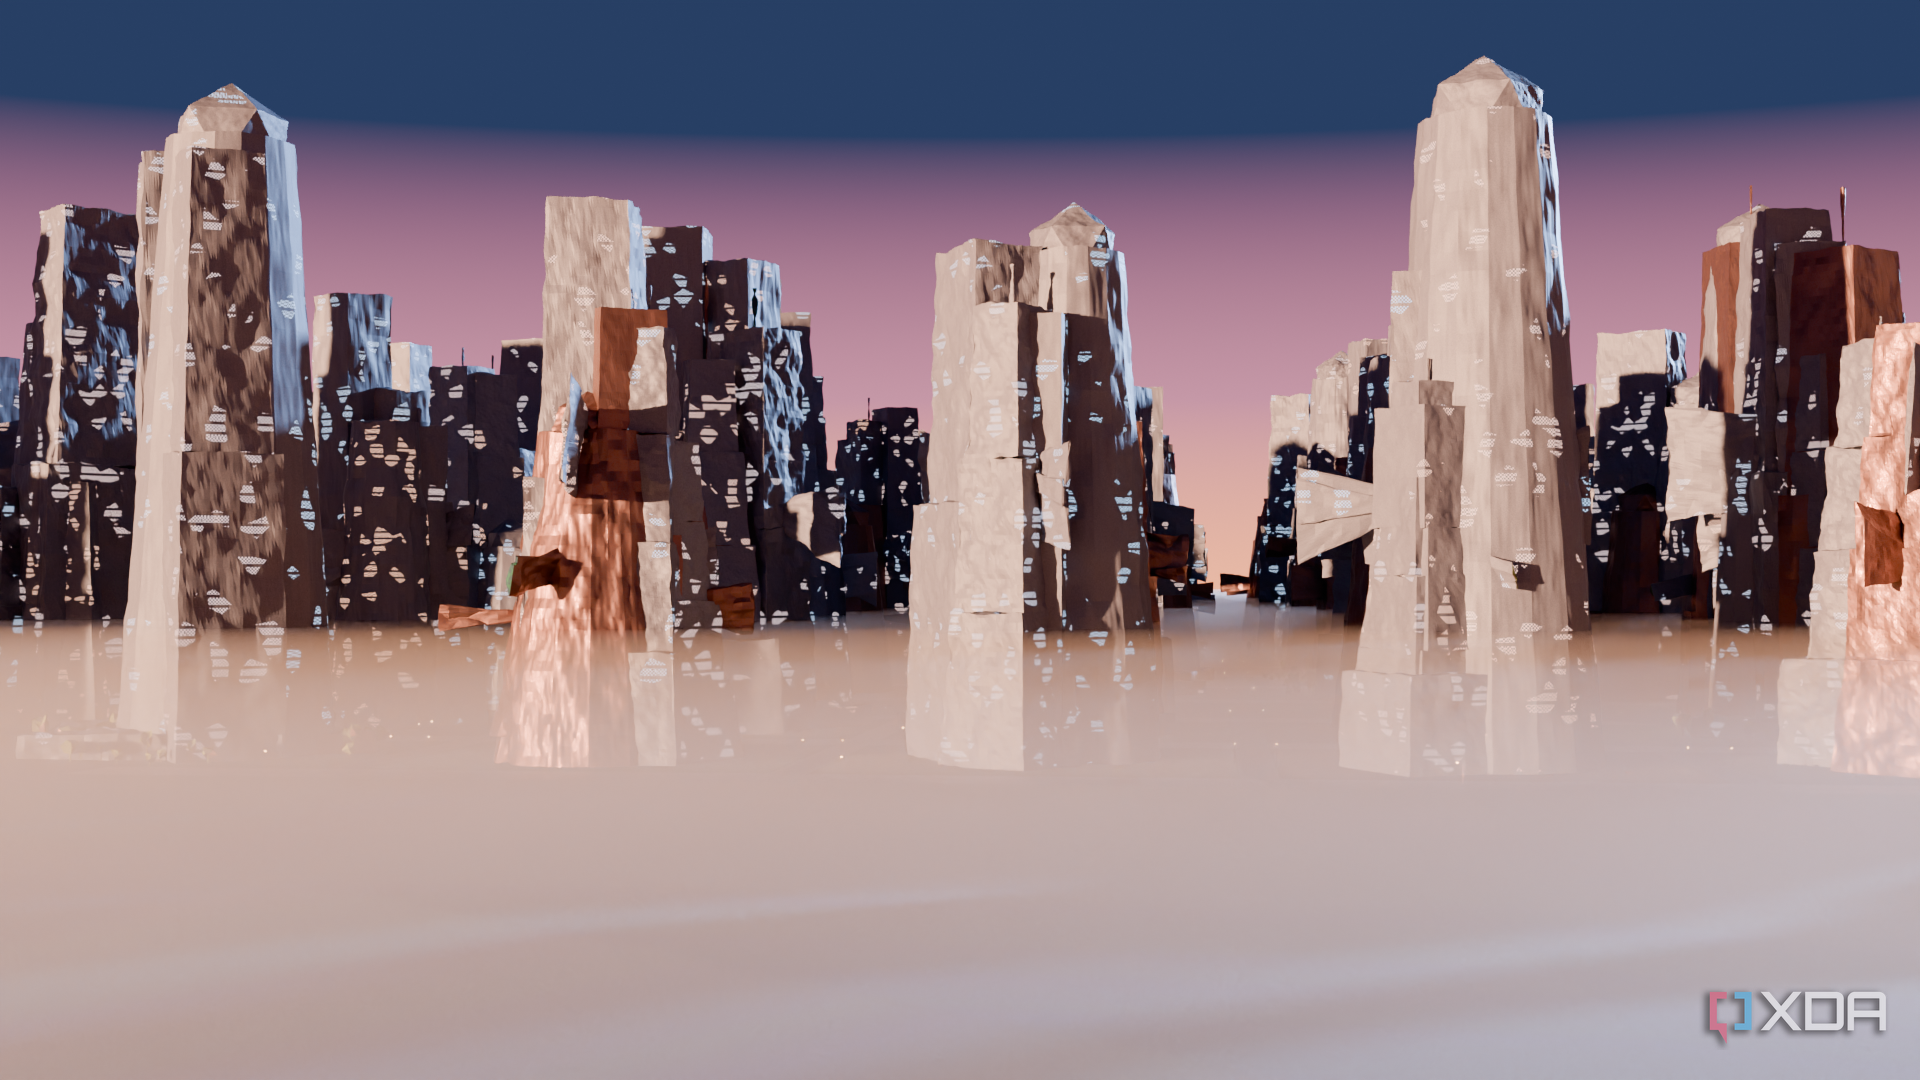
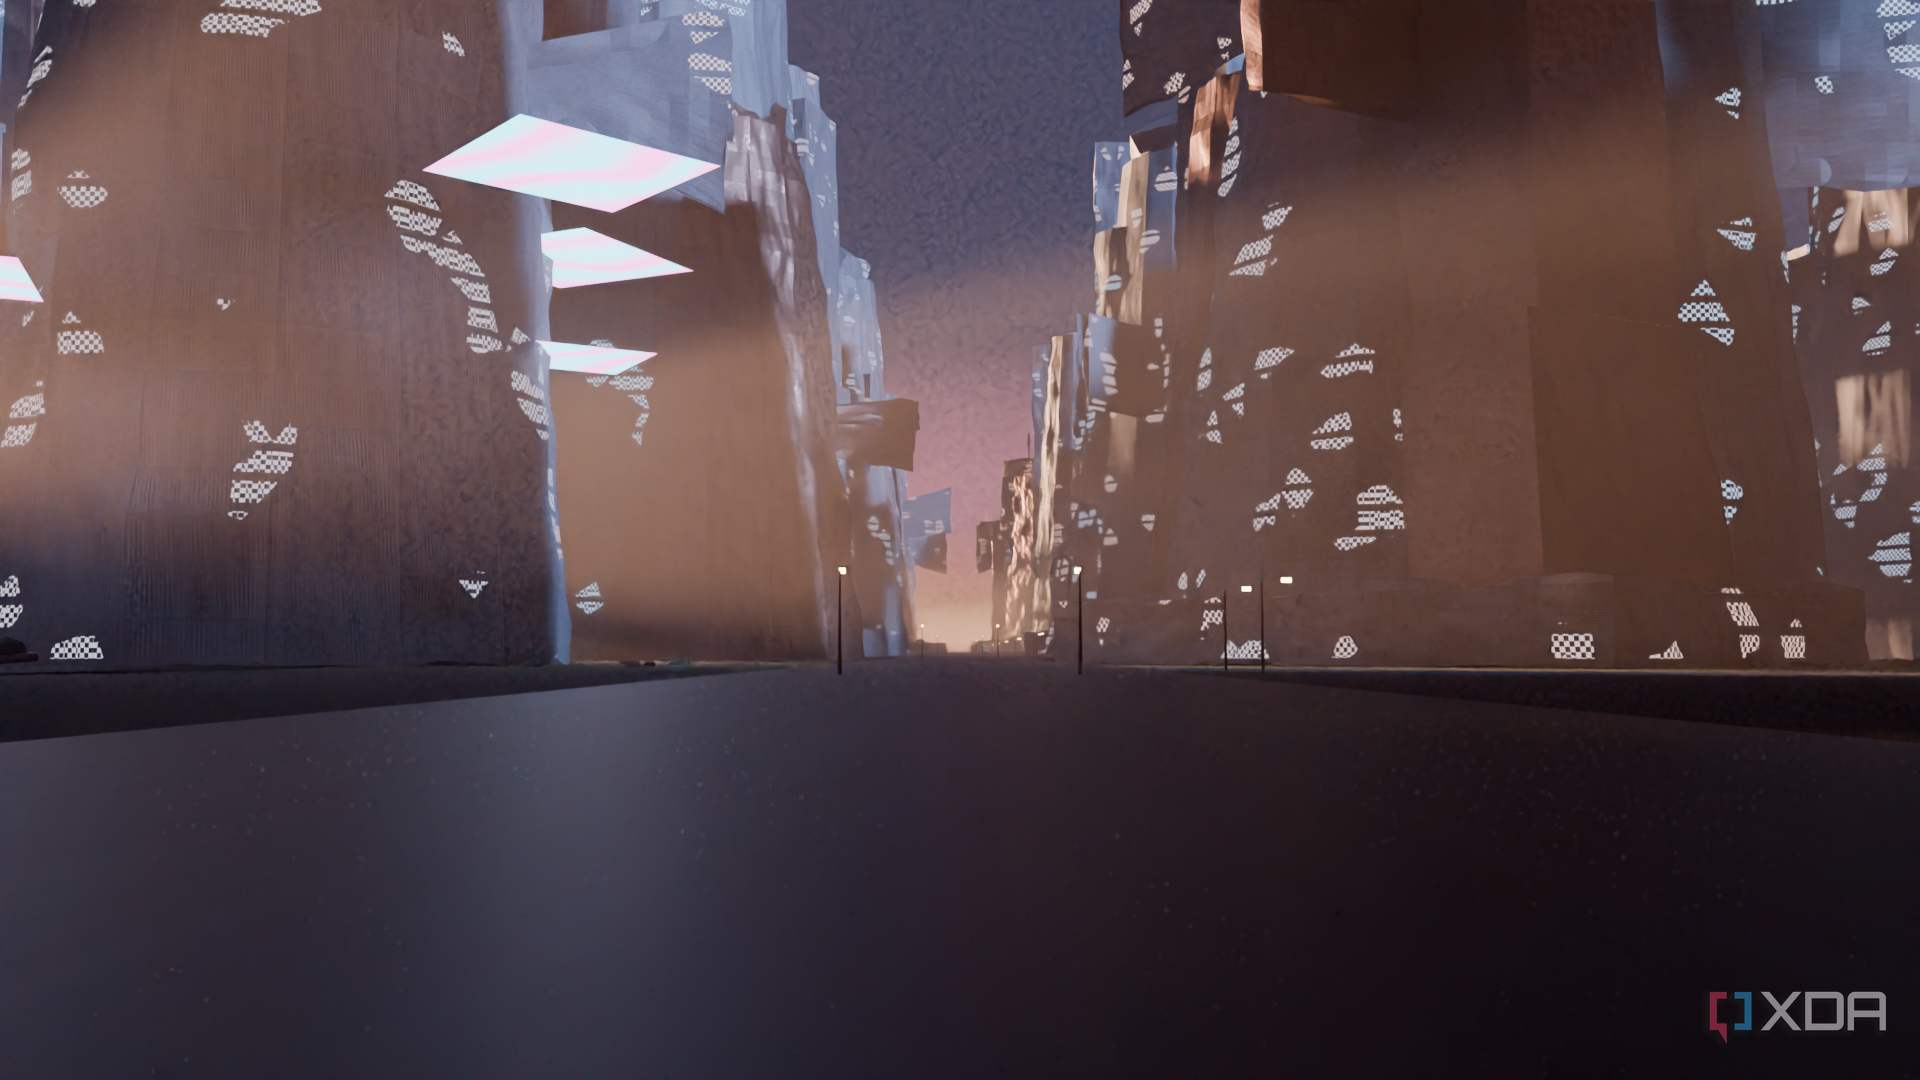
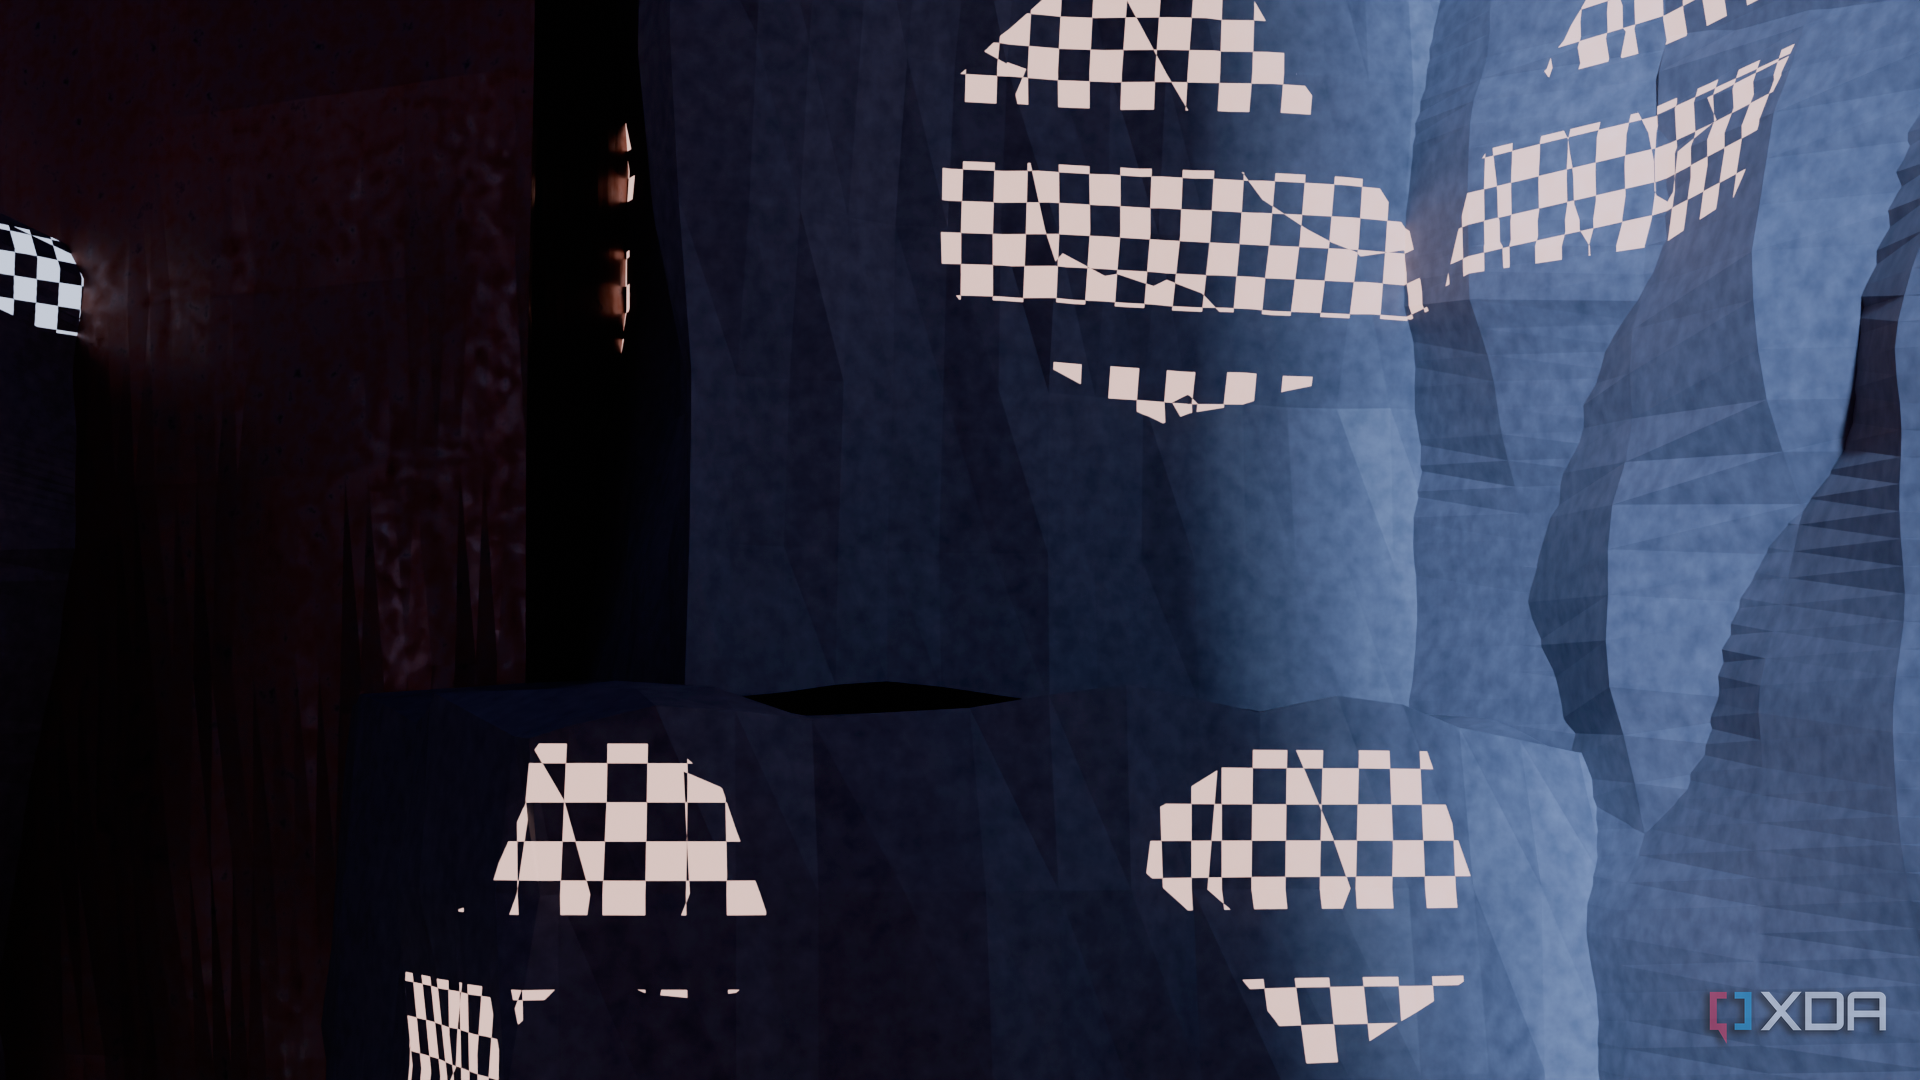
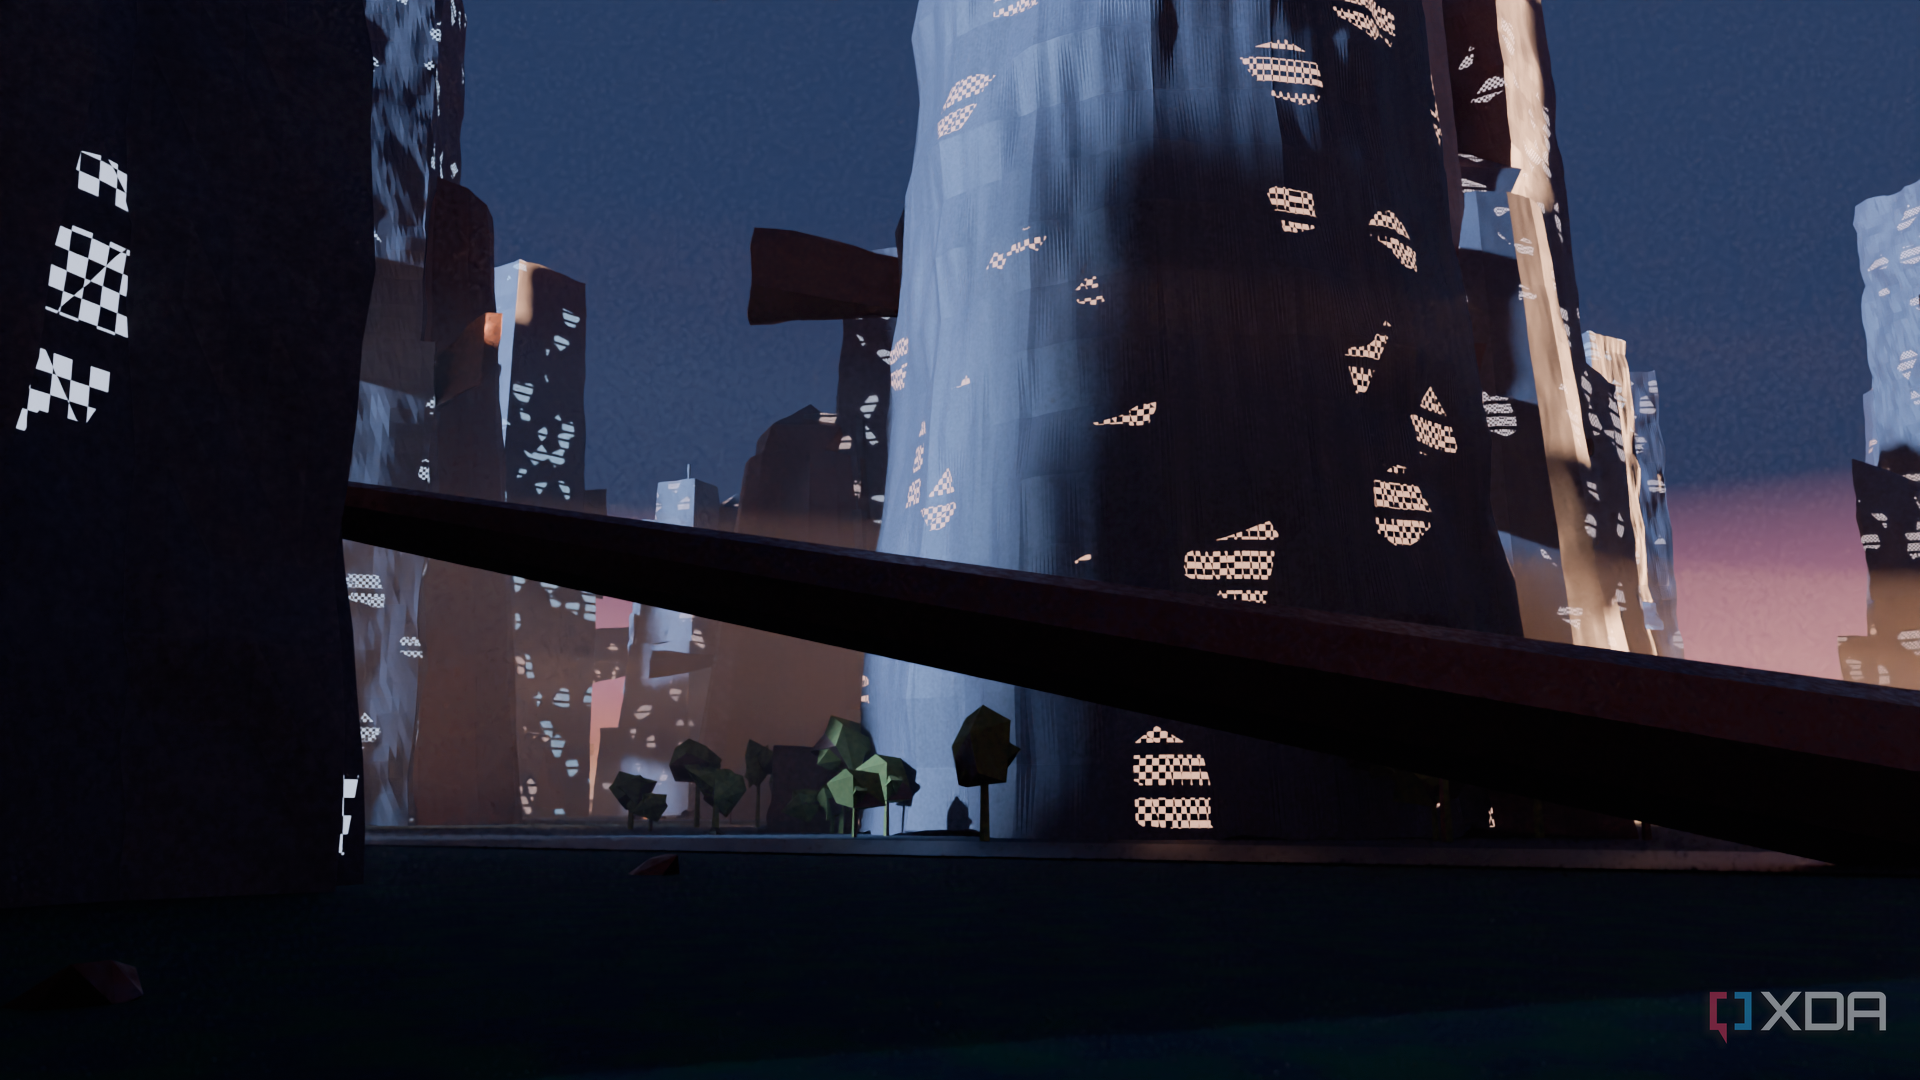
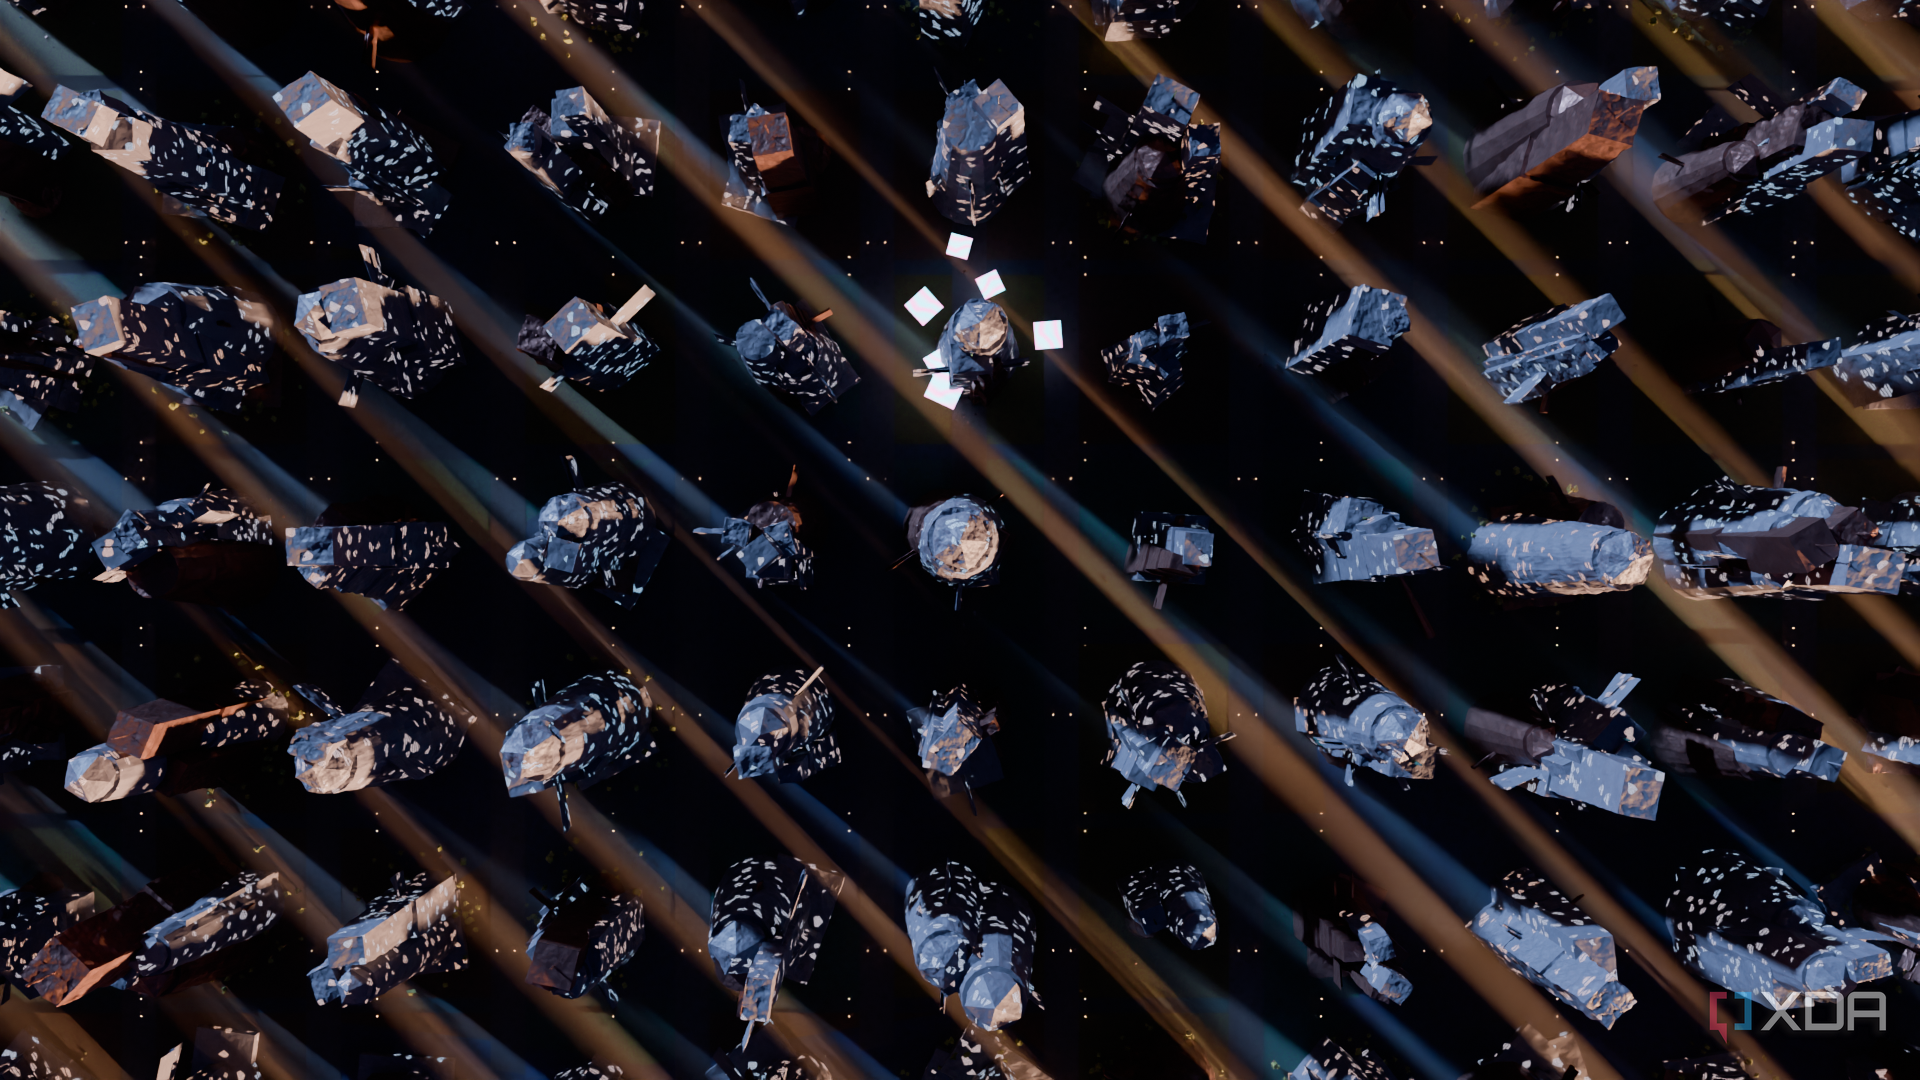
In the end, I had a Python script of just over 700 lines using Blender's bpy API to generate an entire city from scratch. At full scale, it creates a 15-by-15 grid of blocks spaced 170 metres apart, containing around 13,600 objects. There are 24 tower designs, industrial buildings, skybridges, 60 vehicles (including 15 overturned wrecks), 380 trees, rubble, streetlights, holographic billboards, and even a fallen 110-metre communications tower. All the materials are procedural, too, with individual building colours and window grids that randomly illuminate in warm orange or cold cyan.
The model even generated 18 camera positions automatically, built by analyzing the scene to find landmarks such as the tallest tower, the fallen communications tower, and the densest cluster of trees, then framing a shot around each one. Everything you see in these renders, from the buildings to the materials and lighting, was generated by code written by a local LLM running on the same laptop. That model, without offloading strategies, also needs more memory than a typical gaming GPU provides.
Everything about the city is perfect for testing
Configurable detail levels

Qwen 3.8 Flash Next wrote all of the scripts for this project, including a detail setting that can control the city's complexity. Every building has a subdivision modifier that splits its faces into smaller ones, followed by a displacement modifier that uses noise to give the structures a weathered appearance. Each subdivision level roughly quadruples the number of faces, while the displacement gives buildings different surface geometry. As a result, Blender ends up needing to evaluate significantly more geometry as detail increases.
Interestingly, the .blend file stays under 2MB regardless of the detail level. As it turns out, that's because storing the base meshes and modifier settings is cheap, and the additional geometry is generated when Blender evaluates the scene for rendering. In the end, it's the geometry and OptiX's ray-tracing acceleration structures that make up most of the GPU memory use.
To measure memory use, the render script, also written by Qwen 3.8 Flash Next, polls nvidia-smi every half-second and records both the baseline and peak GPU memory allocation for each render. On the RTX Spark, those figures reflect usage within the dedicated GPU memory carveout, making them broadly comparable to VRAM allocations on a discrete graphics card. With the LLM shut down, the laptop reported around 1.3GB in use before rendering.

|
Detail level |
Evaluated vertices |
Peak scene memory |
1080p render time |
|
Level 4 |
6.65 million |
6.7 GB |
10-17 seconds (48 samples) |
|
Level 6 |
106.3 million |
38.4 GB |
6.5 minutes (16 samples) |
|
Level 6 + 11% of buildings at level 7 |
139.3 million |
49.3 GB |
12 minutes (64 samples) |
At the highest tested detail level, Blender evaluated 139.3 million vertices and used an additional 49.3GB of GPU memory, bringing total reported usage to 50.6GB. I rendered five different shots at 1080p and 64 samples, and peak memory use varied by less than 70MB between them.
Each frame took around 12 minutes at the highest level of detail, but rendering itself didn't appear to account for most of that time. A 16-sample render still took over 11 minutes, which suggests that the bulk of the work really came down to preparing geometry and building acceleration structures rather than tracing additional samples. Throughout the test, the laptop's fans were running at full speed, though that's not really a surprise given the sustained workload.
An RTX 5090 doesn't have the VRAM for this scene
But it's not automatically worse because of it
Nvidia's most powerful consumer-focused card, the RTX 5090, has a mere 32GB of GDDR7 VRAM compared to the 128GB of the RTX Spark here. The laptop version has even left, just 24GB, meaning that neither could accommodate the full 49GB of allocations needed by this Blender scene. In fact, even the 48GB RTX PRO 5000 Blackwell falls slightly short. There is a 72GB version of that GPU that you can purchase, but it costs $9,999, and the 96GB RTX PRO 6000 Blackwell can set you back as much as twice that. That's more than the entire HP OmniBook Ultra 16 costs, and more than most people's entire desktops.
That doesn't mean an RTX 5090 couldn't render the scene at all. Blender's Cycles renderer can fall back to system RAM when GPU memory fills up, so a desktop with enough RAM may still complete scenes that exceed its VRAM capacity. However, not every type of data can be moved out of GPU memory, and Cycles will fail if the remaining allocations don't fit.
In situations where Cycles has to fall back to system RAM on a desktop GPU, it has to access that data over PCIe, where PCIe 5.0 x16 peaks at approximately 64GB/s in each direction. That's in contrast to the RTX Spark's 300GB/s of unified memory bandwidth, which makes for a pretty big difference.
To be clear, none of this makes the RTX Spark faster at rendering than an RTX 5090. The RTX 5090 has 1,792GB/s of memory bandwidth, almost six times higher than the RTX Spark, not to mention it's a significantly more powerful card as well. For the scenes that can squeeze into its 32GB of VRAM, it's going to be both a faster and better option. However, the RTX Spark's advantage is its memory capacity, which can go a long way in some specific workloads.
Nvidia's RTX Spark isn't the only option for this kind of workload, either. For example, AMD's Strix Halo also supports up to 128GB of unified memory and can accelerate Blender through HIP, though it doesn't support CUDA or OptiX, which lets Cycles use Nvidia's own ray-tracing. Apple's M5 Max also has a considerably higher memory bandwidth and can come with the same or more VRAM, too.
What once required a workstation can run on a laptop
Don't expect it to be as fast, though

What I find most interesting about this setup isn't that the RTX Spark could quickly render a city, but that it could accommodate the entire, huge scene in the first place. These workloads are where memory capacity can matter significantly more than the raw GPU performance, and my 49GB test doesn't even exhaust the laptop's default 64GB VRAM carveout.
What's more, I was able to use the same laptop to run the local LLM that created the scene, before switching roles and rendering it. Neither workload would fit entirely within an RTX 5090's VRAM, yet both ran on the same portable machine. It's a good example of what large unified memory pools make possible, even when they aren't paired with the fastest GPU.