Most companies have a data platform, a model platform and a pile of AI pilots. Fewer have the thing that decides which of those pilots should be allowed near a customer.

The chatbot that worked a little too well
Picture a mid-sized insurer that ships an internal claims assistant in six weeks. Adjusters love it. Then someone pastes a policyholder's medical notes into the prompt box to get a quick summary, and a month later a compliance analyst asks a perfectly reasonable question: where did that text go, who could see it, and which model version produced the answer we sent to the customer?
Nobody can say. The logs exist, technically, but they live in three systems and none of them record the model version. The "approval" for the project was a slide deck and a nod in a meeting.
I have seen versions of this story enough times that I no longer think of it as a failure of any particular team. It is what happens when a company builds the data layer, the model layer and the application layer, and quietly assumes the fourth thing will appear on its own. Governance does not appear on its own. Somebody has to design it.
Why the usual answer does not hold up
The default response is a policy document and a review board. I understand the instinct. A policy feels like progress, and a board feels like accountability.
The trouble is timing. A board that meets monthly cannot review a system that changes weekly, and a PDF cannot stop a prompt from leaking a phone number at 2 a.m. Policy written in prose is a statement of intent. It only becomes a control when something in the system enforces it, records that it did, and can show the record to a stranger a year later.
There is a fair counterargument, though. Heavy governance can strangle the experimentation that makes AI worth doing. A team that needs six sign-offs to try a summarisation prompt will simply stop asking, and then you have shadow AI, which is worse. So the goal is not more process. It is the right amount, attached to the right places and automated wherever that is realistic.
Governance as a layer, not a committee
The shift that helped me most was to stop picturing governance as a gate at the end and start picturing it as a layer that runs alongside everything else, like identity or networking. You would not let each team invent its own login system. The same logic applies here.
Frameworks already point this way. The NIST AI Risk Management Framework talks about governing, mapping, measuring and managing risk as continuous activities. The EU AI Act ties obligations to risk tiers, which in practice means you need to know what you have and how risky it is before you can comply with anything. Banks have lived with something similar for years under supervisory guidance on model risk, such as SR 11-7 in the United States. None of these tell you what to build, which is both their strength and their limit. That gap is what an architecture fills.
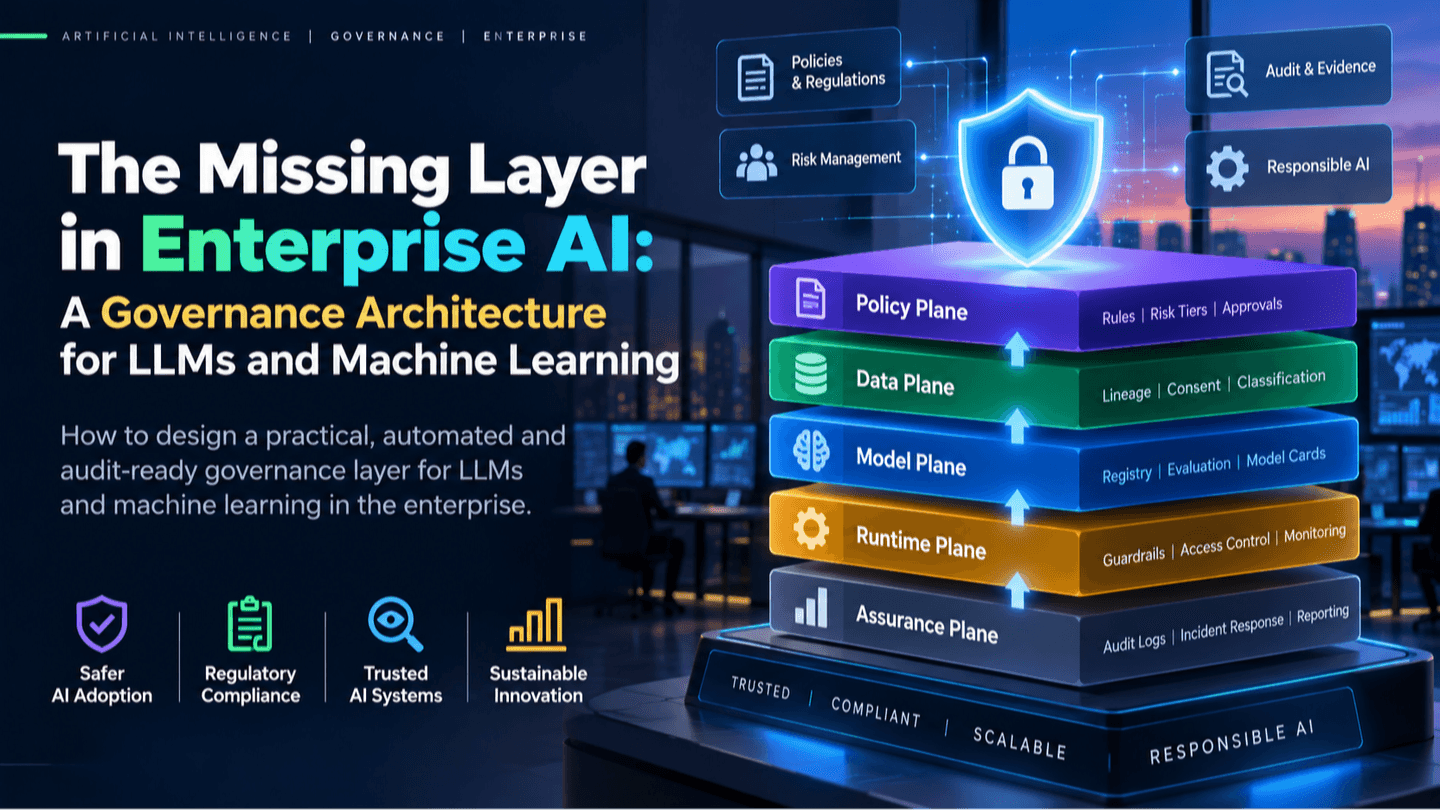
Five planes and one evidence trail
Here is the structure I keep coming back to. It is not the only way to slice the problem, and I would not be shocked if your version has six planes or four. What matters is that each concern has a home and an owner.

The policy plane holds the rules in a form machines can read. Risk tiers, acceptable use, who may approve what, and which regulation maps to which control. A customer-facing credit model and an internal meeting summariser should not face the same hurdles, and the policy plane is where that difference is written down.
The data plane answers where the inputs came from. Lineage, consent, classification and retention all live here. For LLM work this includes the documents behind a retrieval index, which is the part teams most often forget. If the index can read a file, the model can repeat it.
The model plane is the registry and the testing ground. Every model, prompt template and fine-tune gets a version, an owner, an evaluation record and a short model card. Evaluation here means more than accuracy. It covers bias checks for scoring models and, for LLMs, things like grounding, refusal behaviour and resistance to prompt injection.
The runtime plane is where controls actually bite. Input and output guardrails, rate limits, human escalation and a kill switch sit here. The assurance plane watches everything afterwards. Drift monitoring, incident response, reporting to risk teams and the board.
Running through all five is the evidence trail: immutable logs that record decisions, owners and timestamps. This is the unglamorous part, and I would argue it is the whole point. Governance you cannot prove is just a story you tell.
What this looks like for an LLM
Take the insurer's claims assistant and run it through the runtime plane.

A request arrives. An input guard checks for personal data and obvious injection attempts, and applies policy for that user's role. Retrieval then runs with access control, so the system only fetches documents the person is already allowed to read. This step matters more than most prompt-level defences, because it stops the model from ever seeing what it should not repeat. The model generates an answer. An output guard checks whether the answer is grounded in the retrieved sources and whether it leaks anything sensitive. Low-confidence or high-stakes cases route to a human.
Every stage writes to the audit log: the prompt, the sources, the model version, the guard verdicts, the latency, the user's role. When the compliance analyst asks her question, the answer takes a few minutes instead of a few weeks.
I should be honest about the limits. Guardrails are probabilistic, and the OWASP list of risks for LLM applications exists precisely because injection and data leakage are not solved problems. No filter catches everything. The architecture does not promise safety. It promises that failures are contained, visible and traceable, which is a more modest and more truthful claim.
What this looks like for classical machine learning
Traditional models need the same bones with a different rhythm. A fraud model or demand forecast moves through a lifecycle, and governance shows up as gates between the stages.

Data intake requires a lineage and consent check. Training must be reproducible, so someone else can rerun it and get the same result. Validation covers performance, bias and robustness. Approval requires a named human owner, with the depth of review set by the risk tier. Deployment comes with a canary release and a rollback plan. After that, monitoring watches for drift, and the loop closes: when a threshold is crossed, the model is retrained or rolled back.
Retirement is the underrated stage. Old models linger because nobody owns the decision to switch them off.
Who owns what
Architecture without ownership is a diagram on a wall. The model I find most workable borrows from the three lines familiar in financial services, scaled down so a smaller company can use it.

Build teams own their models and use cases, run the tests and respond to alerts. A small governance office sets risk tiers, reviews only the high-tier approvals and maintains the shared tooling, so everyone else gets the controls for free. Internal audit and risk sample the logs and test whether the controls work in practice, then report upwards.
Policy flows one way, evidence flows the other. If a team has to fill in a form to get a control, it will be skipped. If the control ships with the platform, it will mostly be used.
Where this can go wrong
Two failure patterns are worth naming. One is governance theatre: beautiful policies, no enforcement, no logs. The other is the opposite, a control regime so heavy that teams route around it.
I am also not sure the five-plane split suits every organisation. A ten-person data team probably does not need a governance office. It might need one engineer who owns the registry and a habit of writing down who approved what.
A sensible first ninety days
I would not begin with tooling. I would begin with an inventory, because you cannot govern what you cannot list. Find every model and LLM-powered feature, including the quiet ones in spreadsheets and vendor products, and give each a risk tier and a named owner.
Next, pick the highest-risk system and wire up logging end to end, so a decision can be traced back to a model version and data source. Then add one automated gate to the deployment pipeline, such as refusing to promote a model with no evaluation record. Small, boring and enforceable beats ambitious and optional.
The layer worth building
Enterprise AI does not usually fail because the models are weak. It fails in the seams: between the team that built the thing and the team that has to answer for it, between what the policy says and what the system does. Governance is the layer that closes those seams, and it is far easier to design before the first incident than after it.
The insurer in my opening example eventually fixed things. Retrieval got access control, the logs gained a model version, and the approval became a record instead of a nod. None of it was glamorous. All of it was the part that let them keep the chatbot.
What does your organisation's version of this layer look like, and who owns it? I would genuinely like to hear where this framing breaks down.