
Abhinav pivoted from a career in banking to pursue his first love in writing. Even while working full-time, he continued contributing as an editor-at-large, a role he has held for more than 7 years. A lifelong tech enthusiast who has built three gaming and productivity powerhouse PCs since 2018, his passion for technology keeps him closely following the semiconductor industry, from NVIDIA and AMD to ARM. His MSc dissertation explored how artificial intelligence will reshape the future of work, reflecting his curiosity about the wider social impact of emerging technologies.
For almost the entirety of 2026, I've run countless experiments with several dozen local LLMs week after week, and yet it feels as though I've barely scratched the surface of how capable local AI has become in such little time.
I've been a staunch proponent of a local-first approach when it comes to AI inference for both data privacy and fiscal prudence, but I must concede that one of the key limitations of this approach is that no single model is the best at deep research, coding, and image generation, and that makes it hard for local models to compete with their cloud counterparts.
What I've realized, though, is the fact that there doesn't really have to be a single model. On my PC with a 16GB RTX 4070 Ti Super coupled with a Ryzen 5 7600X, I keep three "experts" in rotation for a task that's best suited for them. Here are the models I'm using for writing code, deep research, and generating and editing images, while paying $0 for cloud subscriptions.
BigBang-v1 turns a search engine into a research assistant
Five searches later, it found everything I was looking for
BigBang-v1 is a fine-tuned variant of the ever-reliable Qwen3.6-35B-A3B, released under the Apache 2.0 license. On the surface it's a general-purpose model like Qwen3.6, but one of the most interesting aspects about it is that its model card reports a 76.5 on BrowseComp, which is a benchmark that tests how well a model can dig up hard-to-find information on the web. Since it's based on Qwen3.6-35B-A3B, which only activates 3 billion of its 35 billion params for each token, it is faster than the reading speed on my RTX 4070 Ti Super.
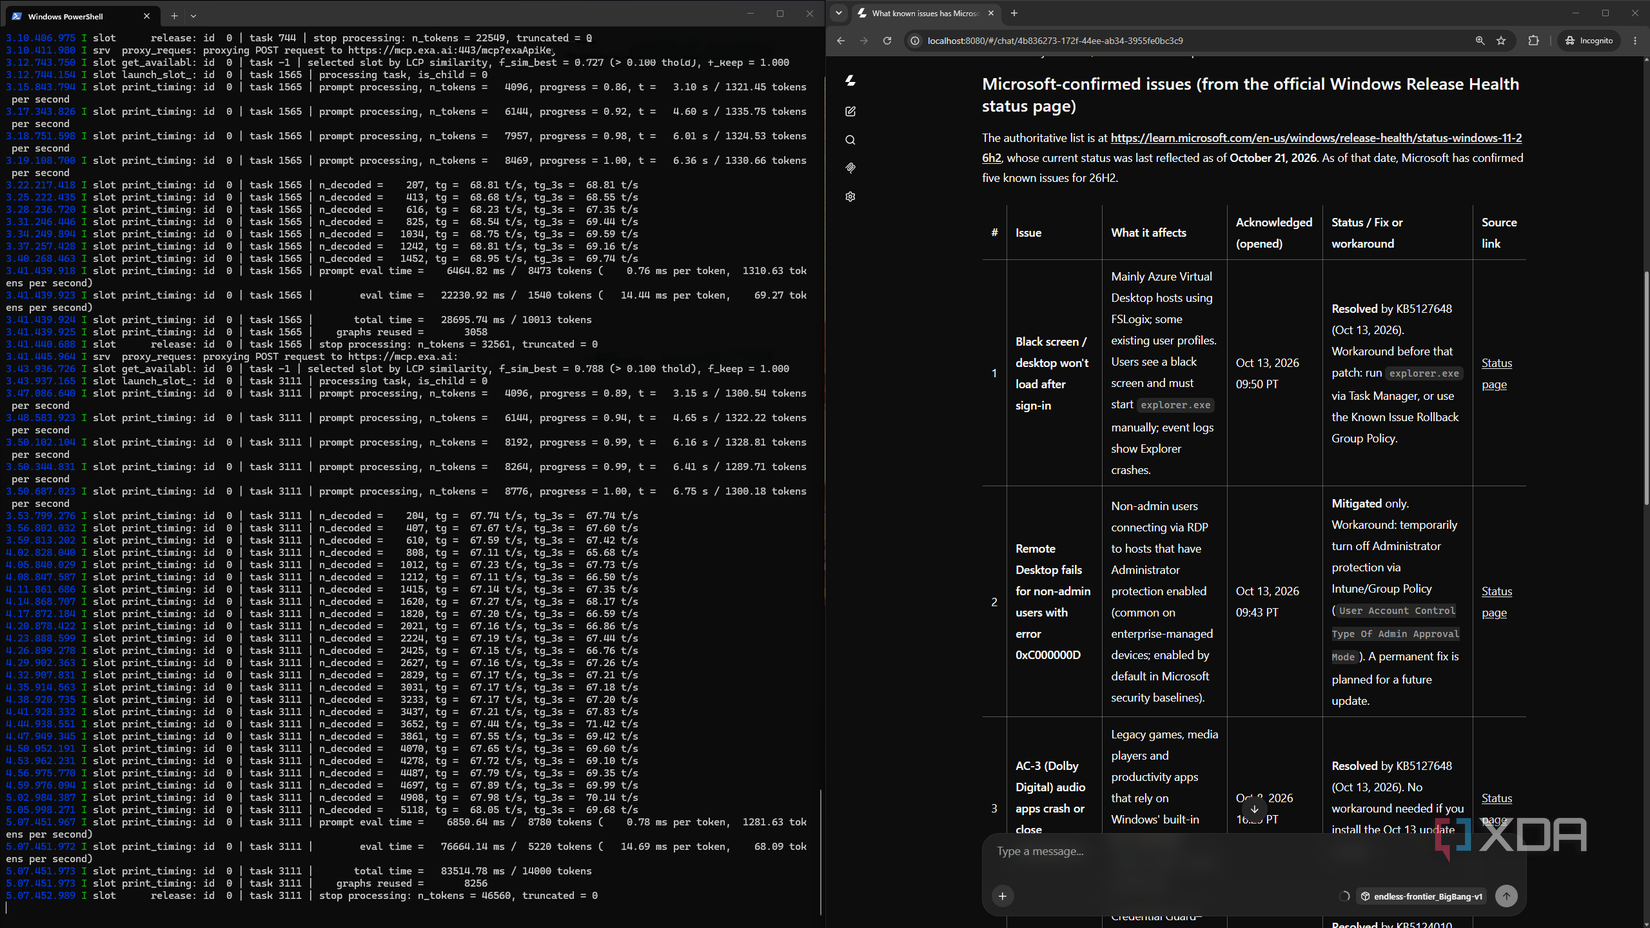
The IQ4_XS quant from bartowski is 19.3GB in weights, which is evidently more than my VRAM capacity. To make it fit, I use the --n-cpu-moe flag to move about 7GB of the model into system RAM, which holds the model's experts, only a handful of which it uses for each token. Even with a 128K context window, it can write 68 to 78 tokens per second.
To test its search capabilities, I connected llama.cpp's web UI to Exa's search engine over MCP using a free API key. Then, I asked a standard question that was recent enough to be well past its training cutoff date, relating to the latest known issues in Windows 11 26H2.
Impressively enough, with just five searches, it caught every issue Microsoft had confirmed at the time of writing, complete with the right dates and KB numbers. It did add a KB number and a fix for one issue that I couldn't trace back to Microsoft, which is why I still check its sources, although that should be standard practice when using any LLM.
FLUX 3 Image Klein turns a prompt into a finished image
Who wants to deal with Nano Banana's usage limits anyway?
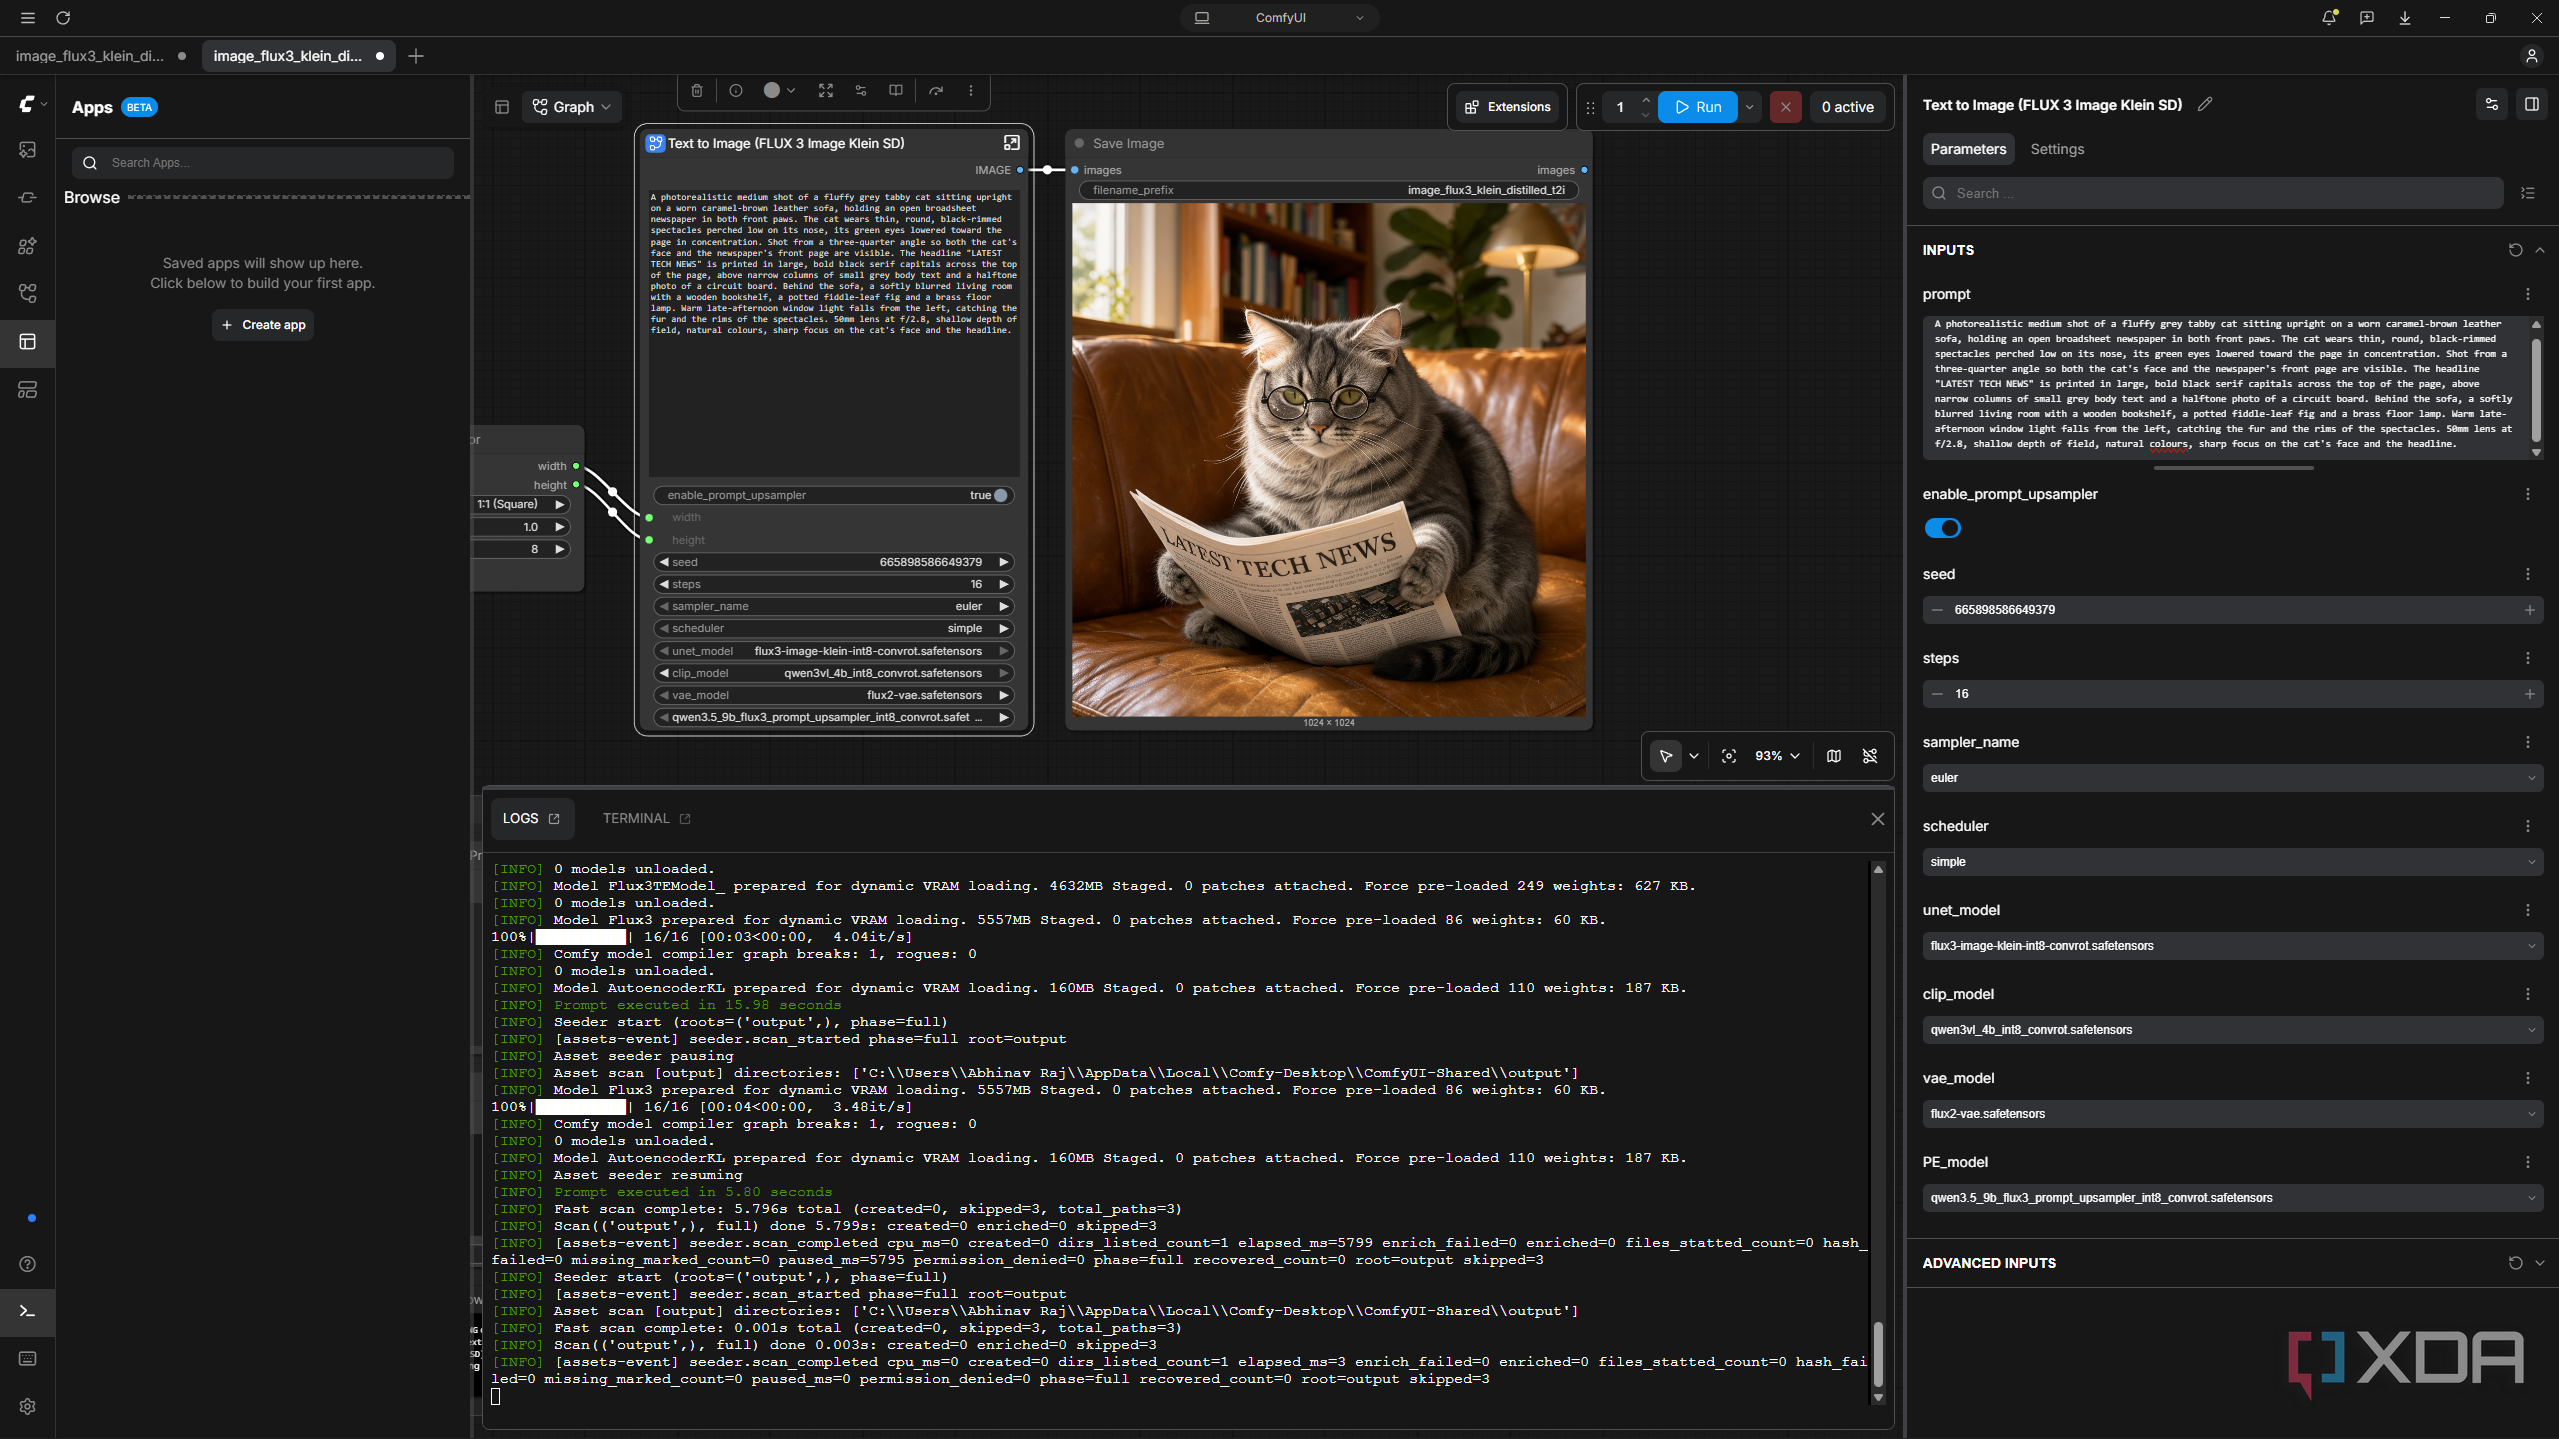
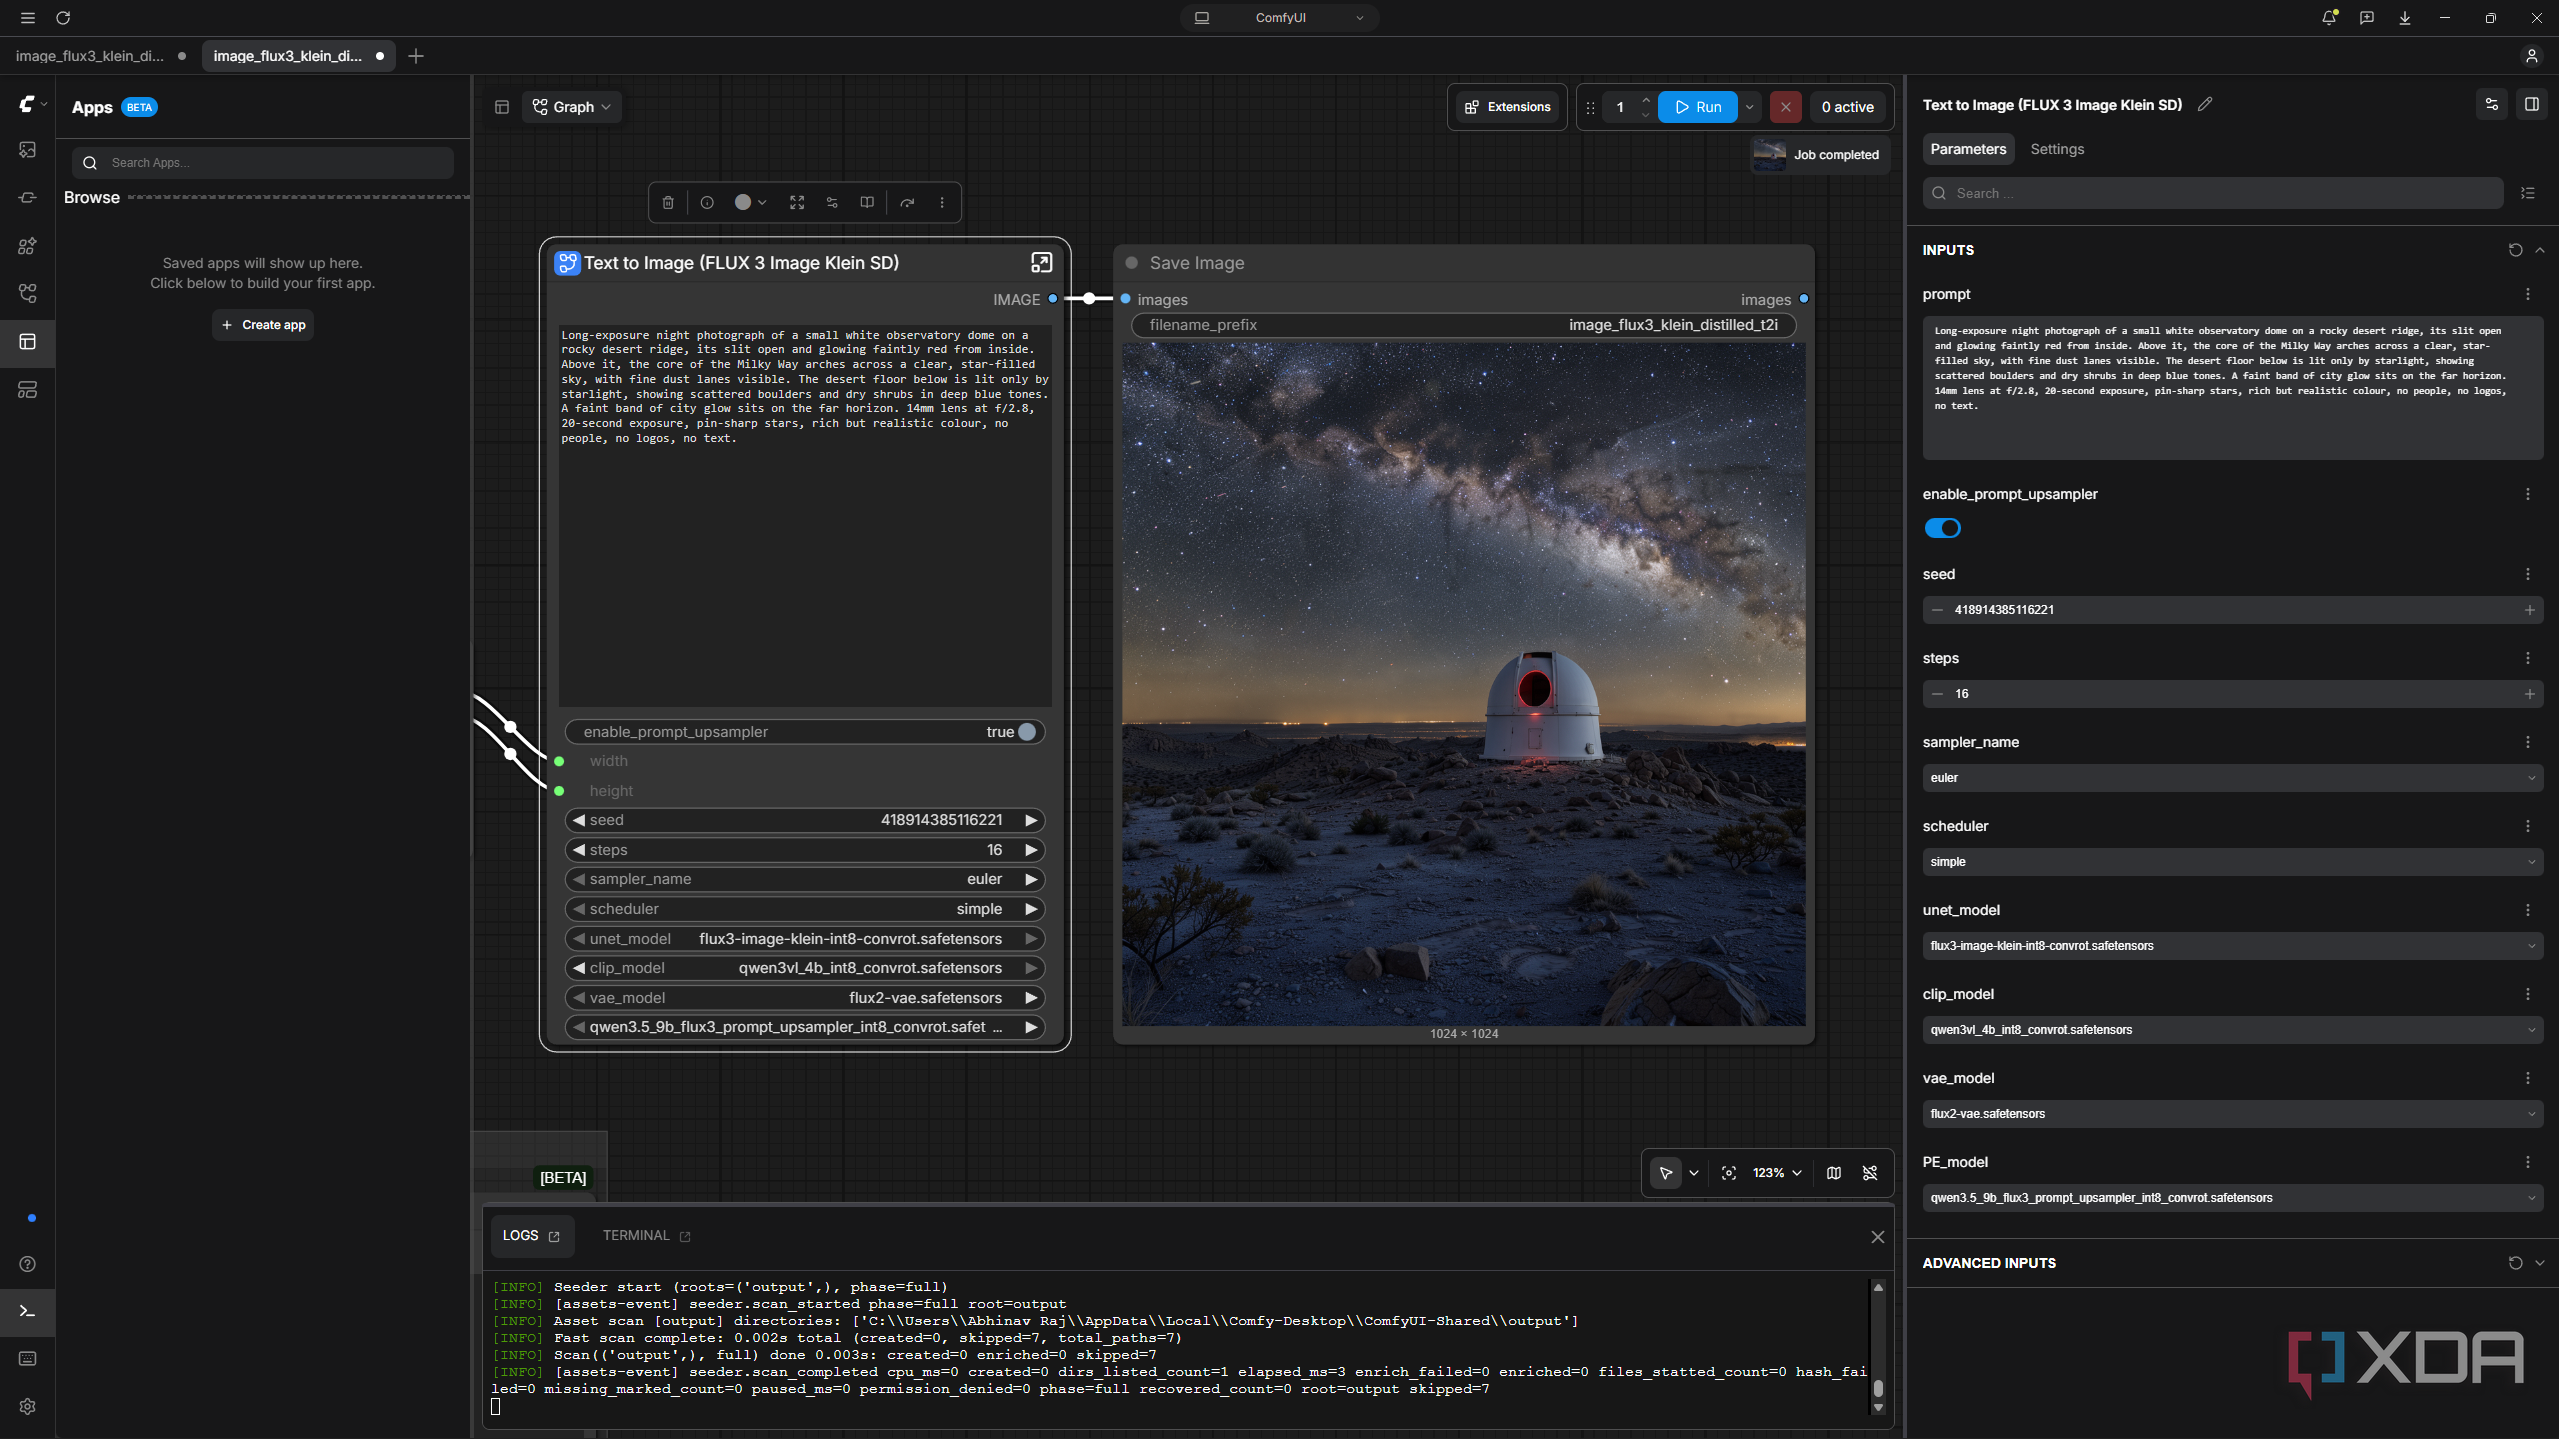
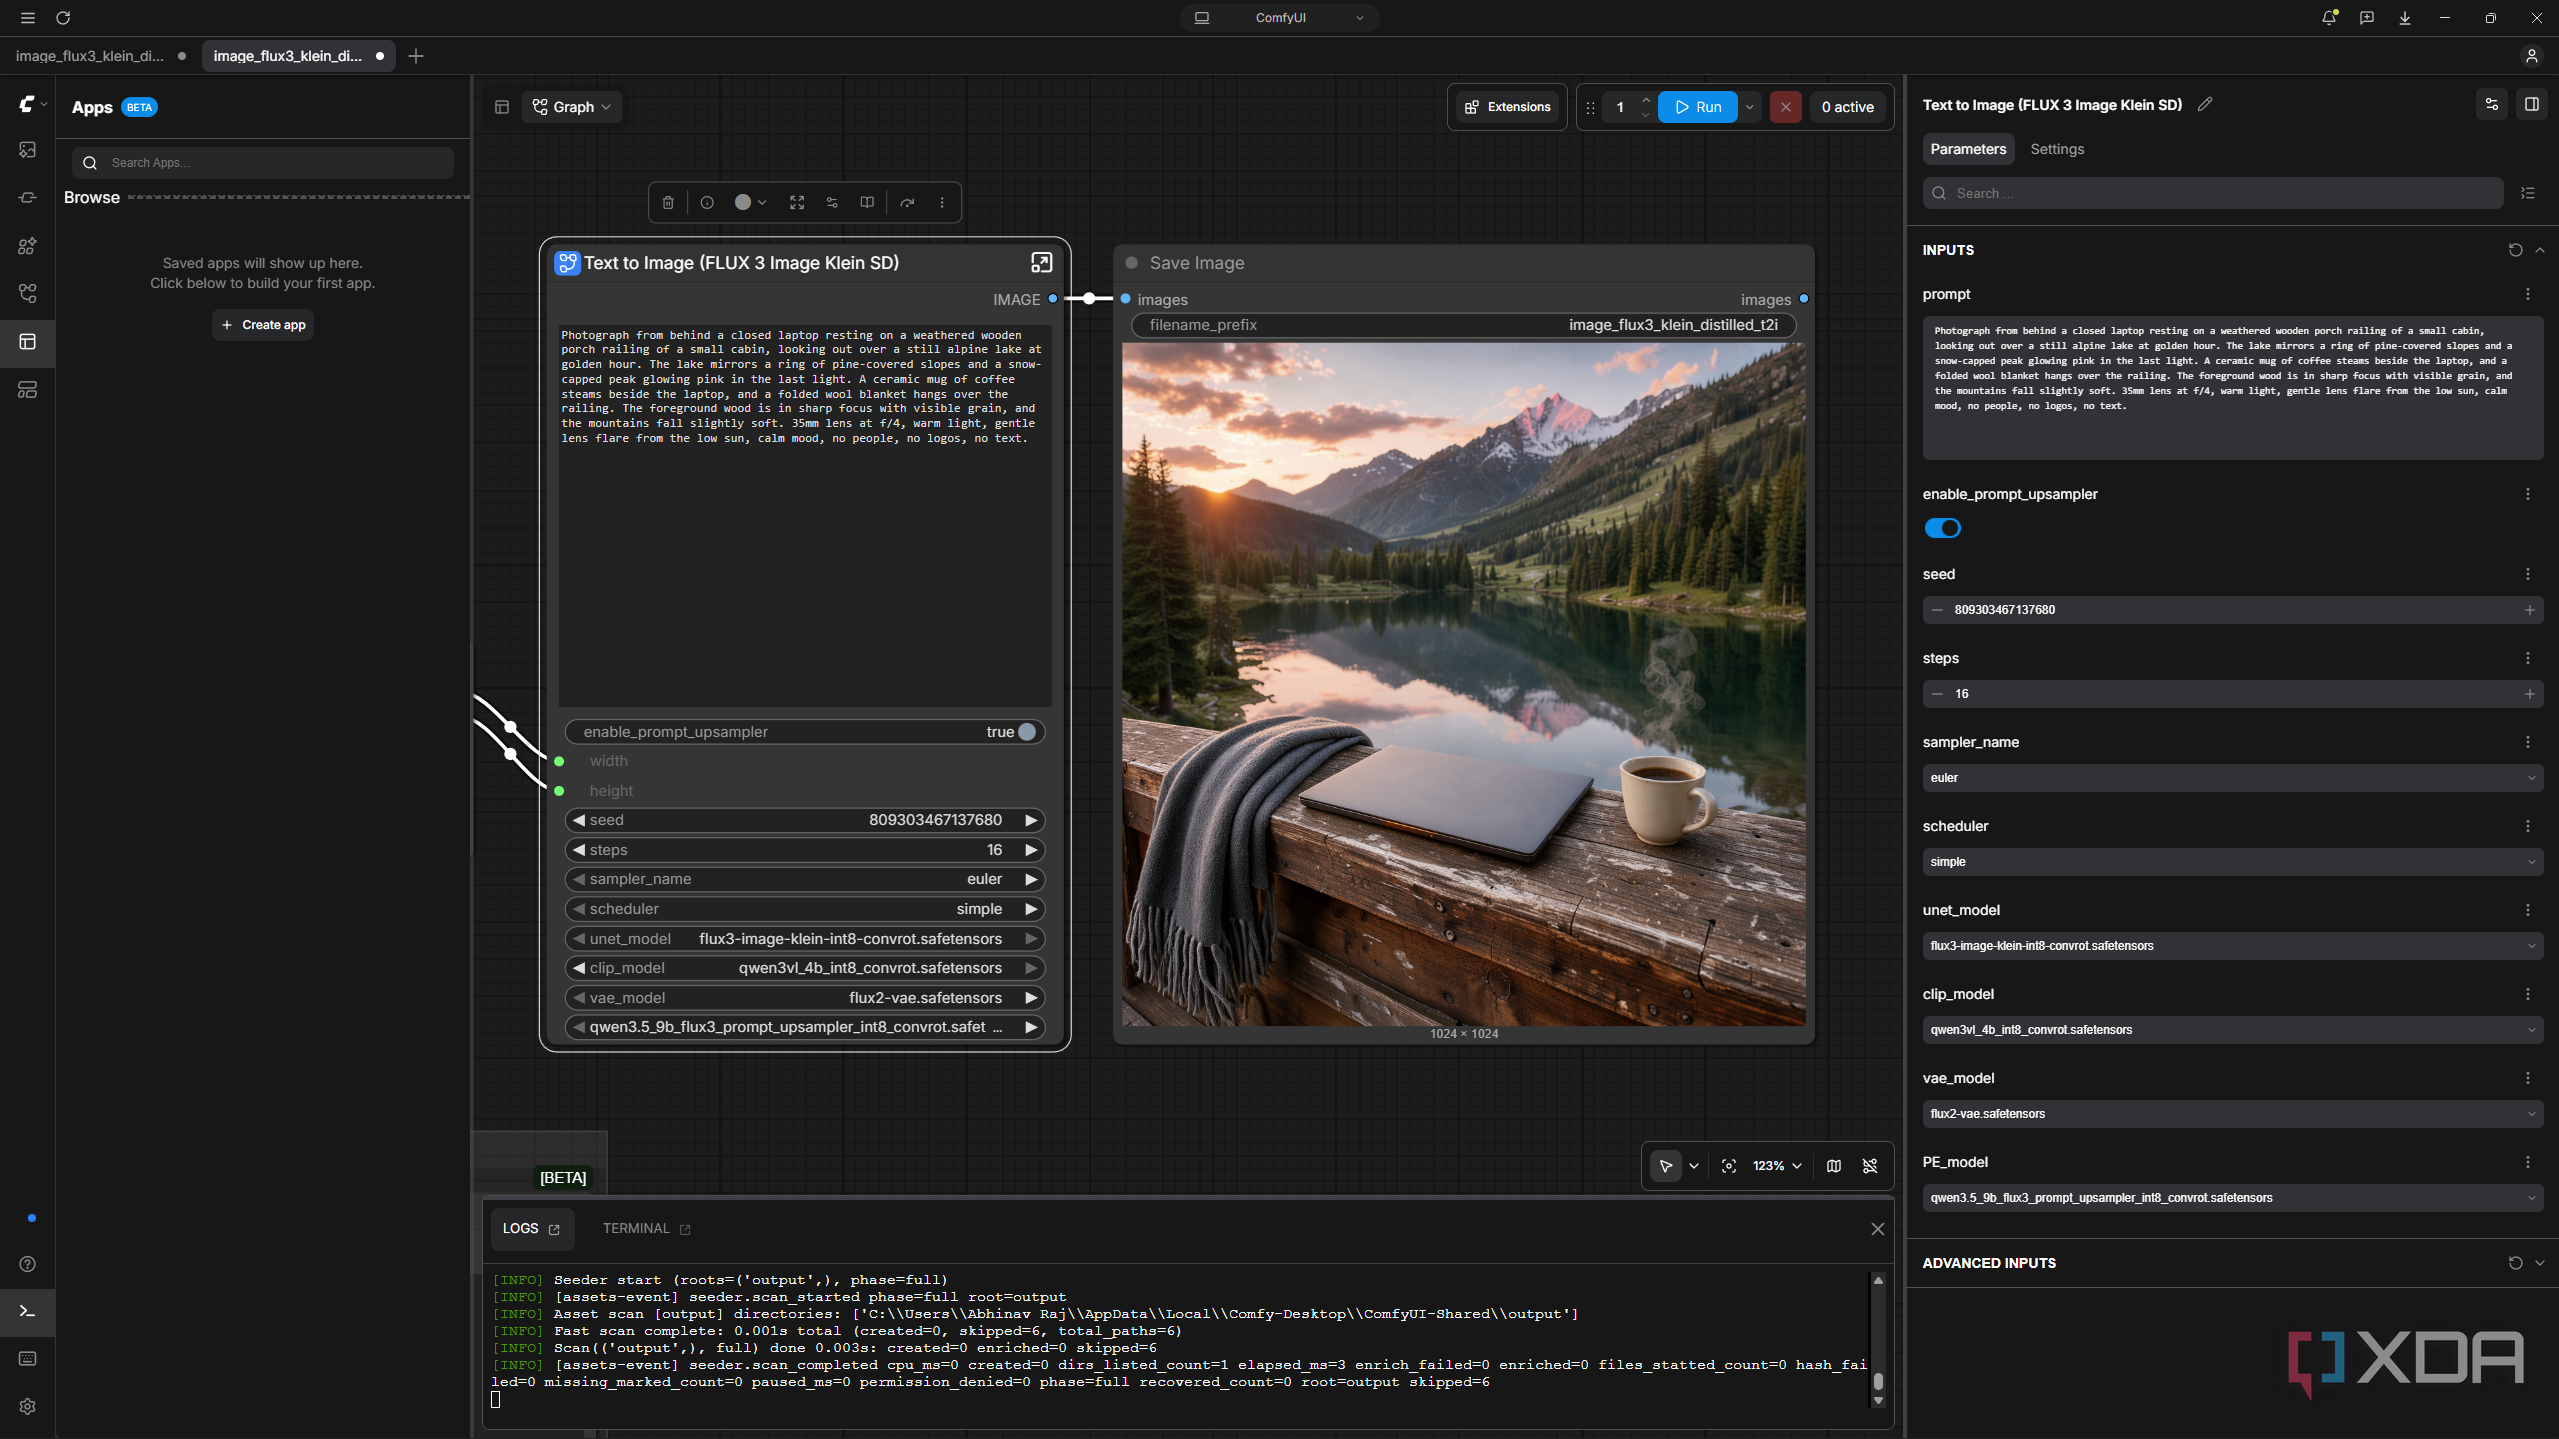
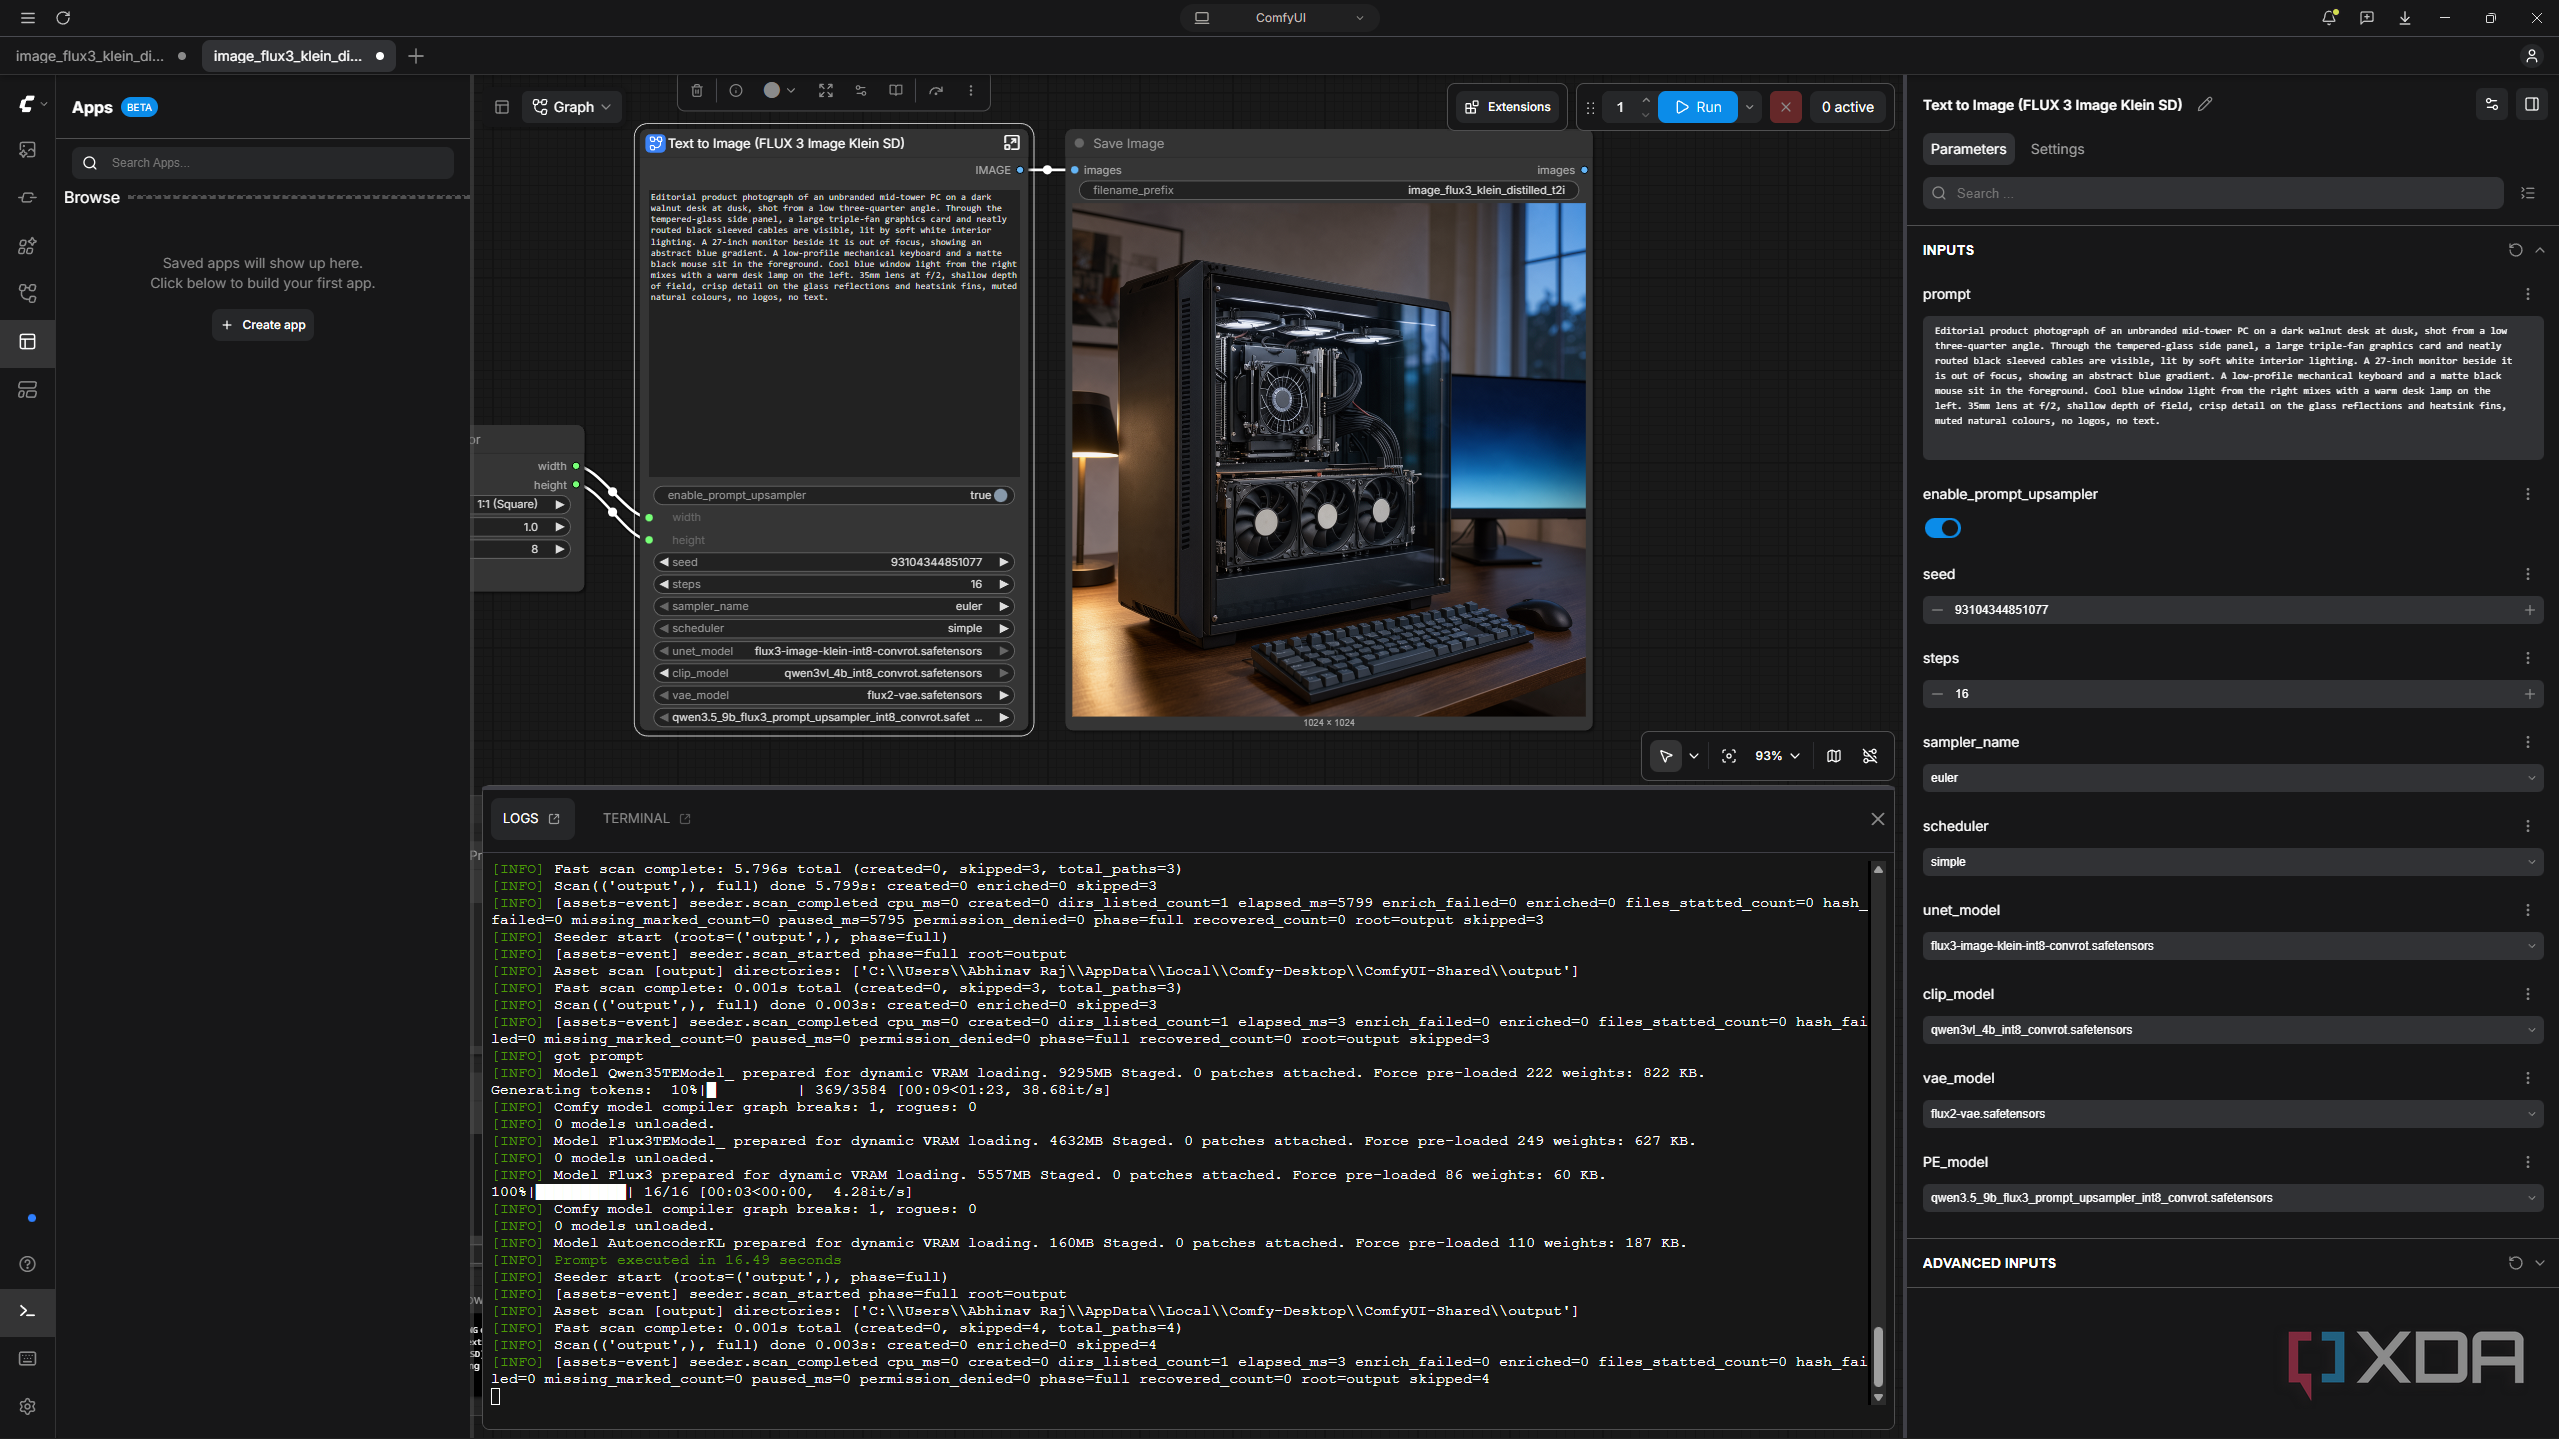
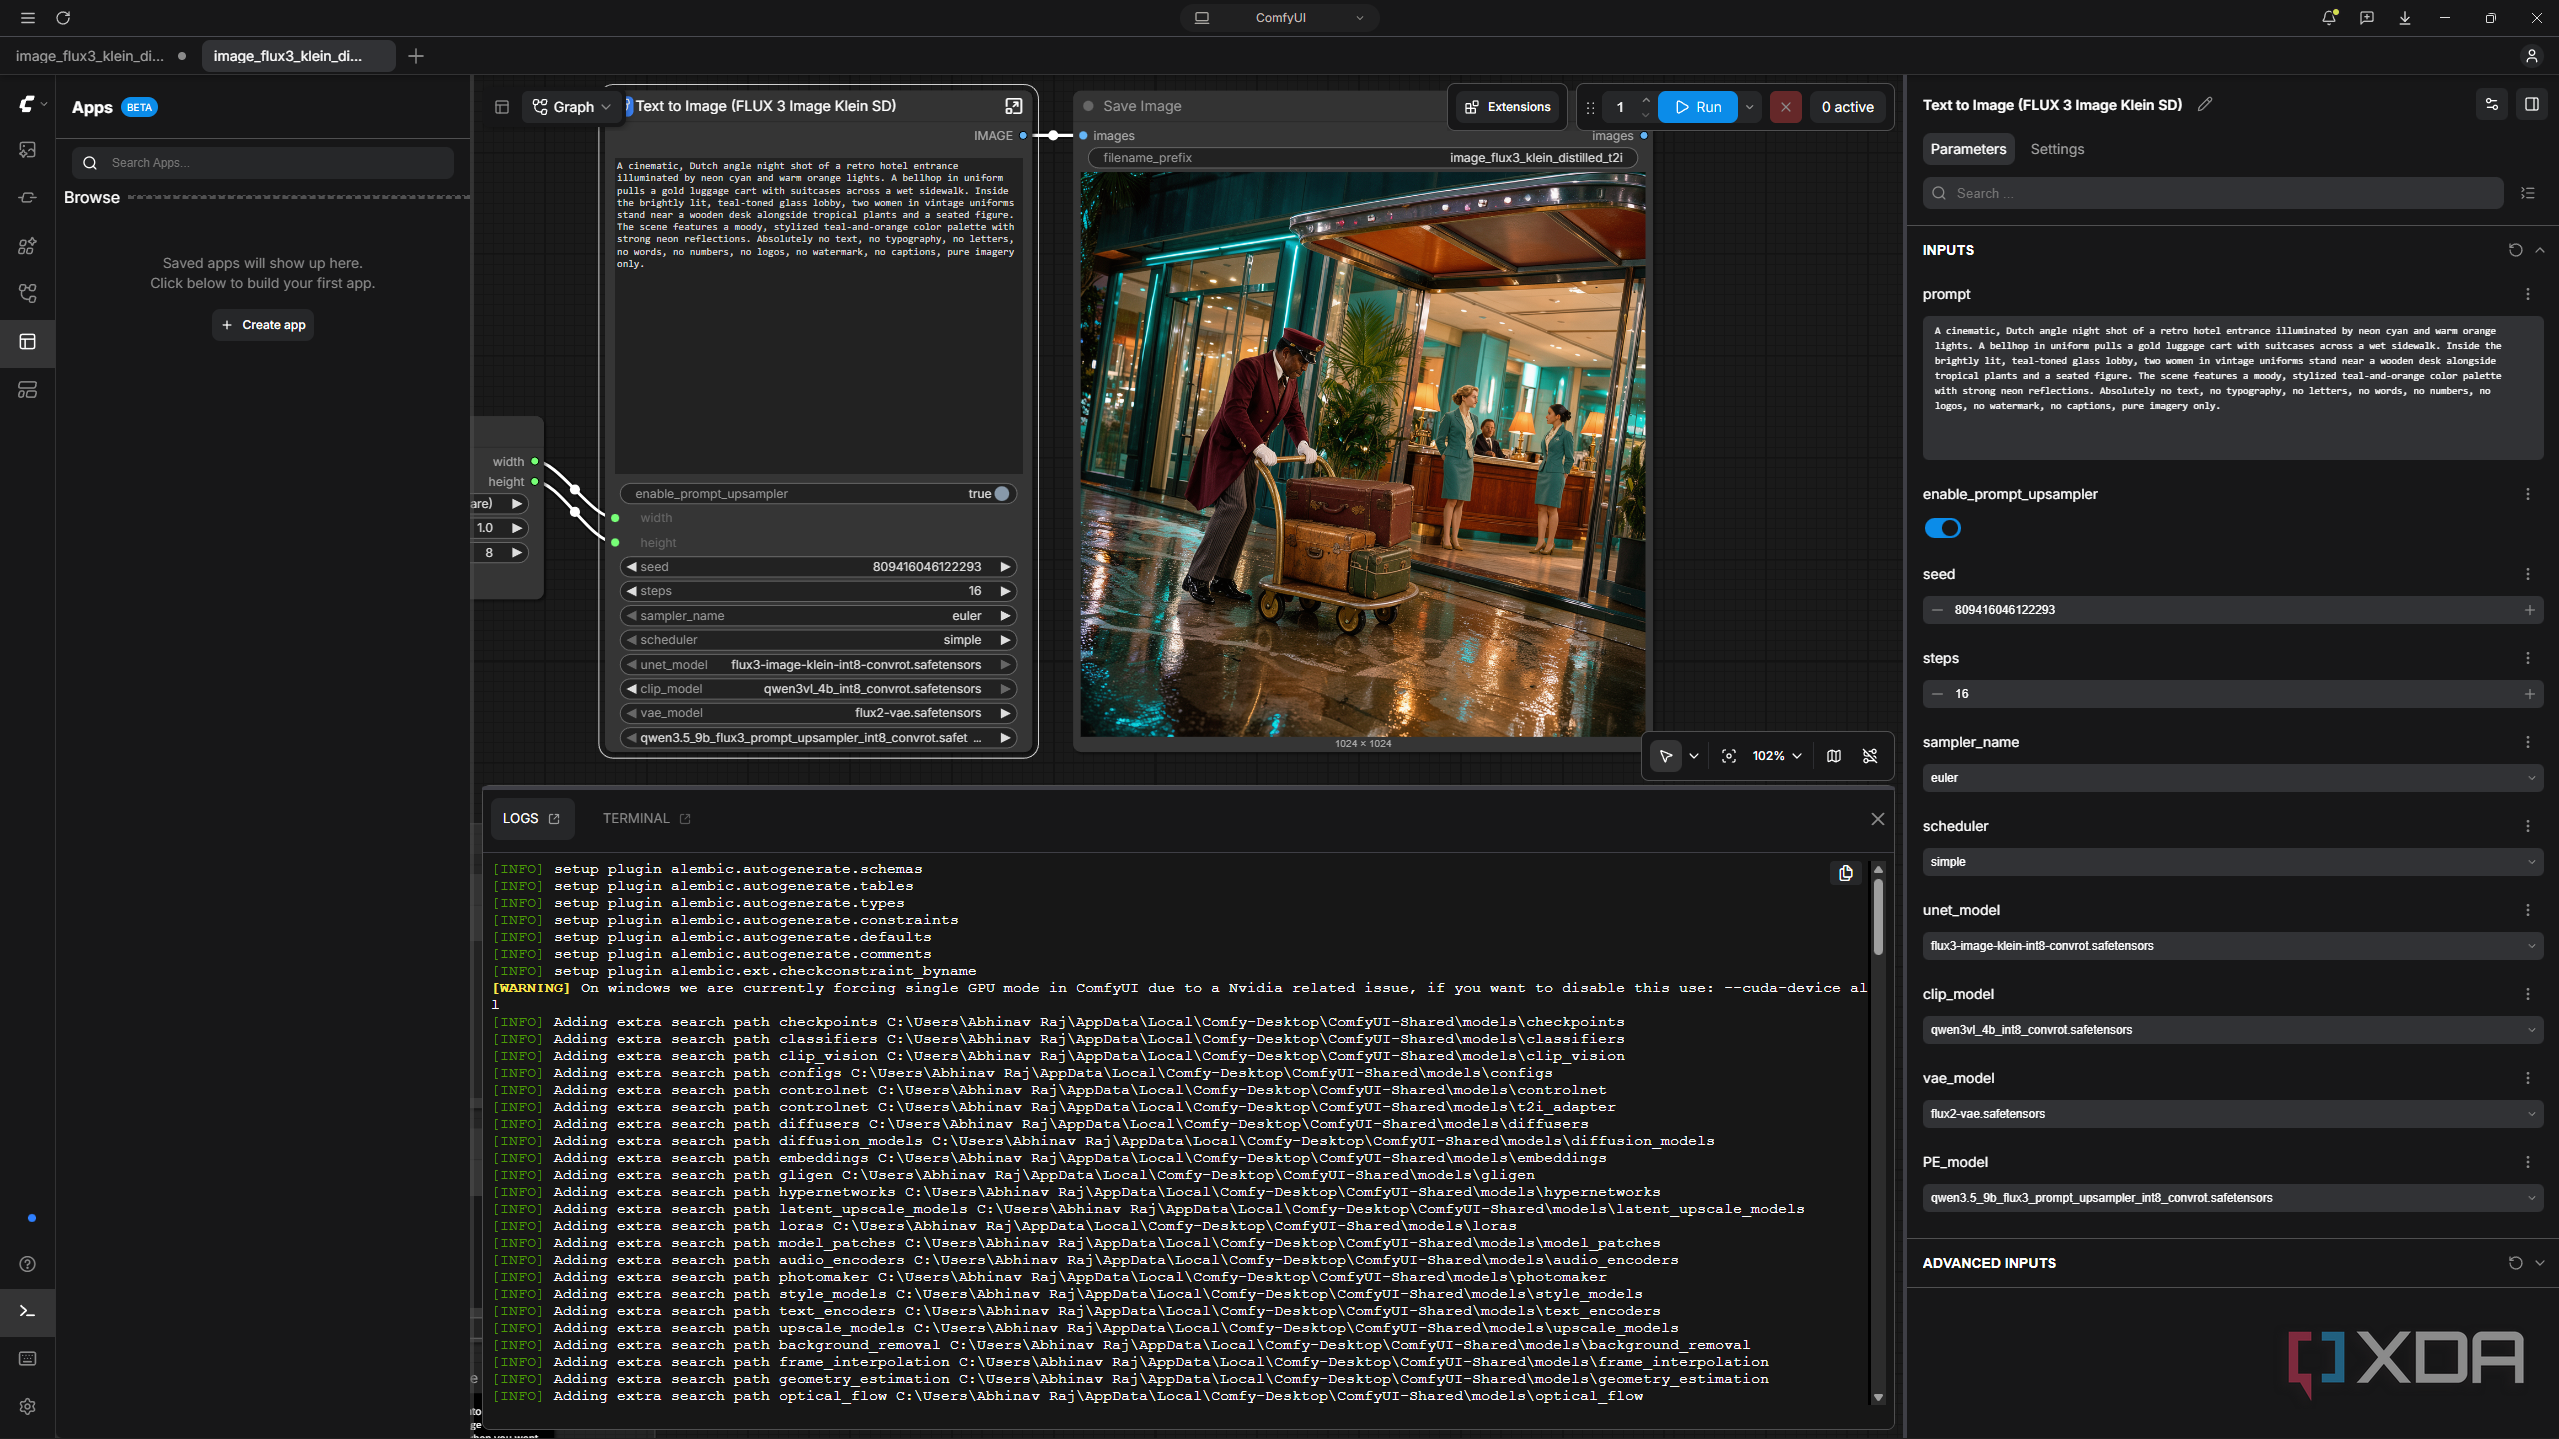
With 5.6 billion parameters, FLUX 3 Image Klein is the smallest model in my local AI stack, but it puts everything to use by generating and editing images from the same weights. I run the distilled version, which needs only 16 steps per image in ComfyUI. It's also only one of the three models that isn't Apache 2.0. What's nice is that its FLUX Kommunity License allows for non-commercial use, plus commercial use for anyone earning less than $5 million a year with some conditions.
The model doesn't work all by itself, though. It needs a 9B Qwen3.5 model acting as the prompt upsampler, to rewrite the provided prompt in better detail, and a 4B Qwen3-VL model, acting as the text encoder, to turn that prompt into embeddings Klein can work with. I use INT8 builds of all three, and ComfyUI loads each into the VRAM when their respective stage runs.
In terms of speed, there's barely any wait time to speak of on my hardware to generate a 1024x1024 image. During my tests, it took an average of about 16 seconds across five runs. Sampling itself takes about 4 seconds, and most of the rest goes to the upsampler to generate its own expanded prompt. Since it's all running locally on my hardware, there are no usage limits or watermarks to fret over, and that sense of ownership over the generation makes the setup worth it. Although I must admit, navigating ComfyUI in its current state is a bit of a pain for first-timers.
Qwen3.8-27B is my model of choice for coding
It trades speed for better code, which is a fine bargain

At this point, you might be debating the benefits of having a separate dense coding model on an NVMe SSD when a fine-tuned Qwen3.6-35B-A3B already occupies space on the same drive. That would be a reasonable question. It's true that BigBang-v1 can write code too, however, Qwen reports a 61.7 on SWE-bench Pro against the 54.2 on BigBang-v1's model card. It's worth mentioning that both scores are self-reported, but I generally have a better coding experience with Qwen3.8-27B.
The only trade-off that I can confidently report is the speed. Qwen3.8-27B is a dense model, so all 27 billion of its params work for every token compared with just 3 billion for BigBang-v1. Because the former is not an MoE model, my usual trick of utilizing --n-cpu-moe flag to offload experts doesn't apply.
The only reasonable workaround with my limited VRAM is, therefore, opting for Unsloth's UD-IQ4_XS quant, which is 14.3GB, so unlike BigBang-v1, the weights can be fully resident in the VRAM. The 32K context window, however, is another story. Its cache needs about 2GB on top of the 14.3GB of weights, so llama.cpp runtime automatically moves 6 of the model's 64 layers back into system RAM, and the generation speed often comes to about 15 to 17 tokens per second. For most of the Pygame projects that I let it write for entertainment, though, that hardly becomes an issue, and the quality of the code justifies the slower generation speed.
All the models are free, and getting better with time
Each of the models I picked helps me with a part of my daily workflow, and together they have made my RTX 4070 Ti Super more useful than I would've ever imagined that a component that I purchased exclusively for gaming at 1440p would be. Given how quickly the local AI scene is moving month after month, I wouldn't be surprised if I were to replace these models with better ones in a matter of the next couple of weeks, and the same GPU would do more for my workflow without asking for any subscription fees in return.