
Shivansh began his tech journey as an avid reader of tech publications, which inspired him to launch his career in video media at Sillycorns.
He has led content across multiple tech YouTube channels and Instagram accounts, crafted go-to-market (GTM) strategies for Vivo, and consulted on digital growth. Coming full circle to his roots in written media, he now delivers deep-dive tech journalism.
Outside of his professional work, Shivansh loves watching movies, riding bikes, and playing cricket.
Ask Claude Opus 5.5 something that brushes against security, and the reply can come back from a different model. A notice appears, the answer gets tagged Opus 4.8, and Anthropic's newest flagship stays switched to the older model for the rest of the chat.
It's one of the safeguards Anthropic added so a model this strong at cybersecurity doesn't turn Claude into a security risk. A classifier flags the request, and Opus 4.8 takes over. The catch is in Anthropic's own system cards. In its prompt-injection tests, most of the attacks that got through came through that fallback model, not the flagship.
Why Claude Opus 5.5 hands security work to Opus 4.8
The handoff is automatic, and you don't get a vote
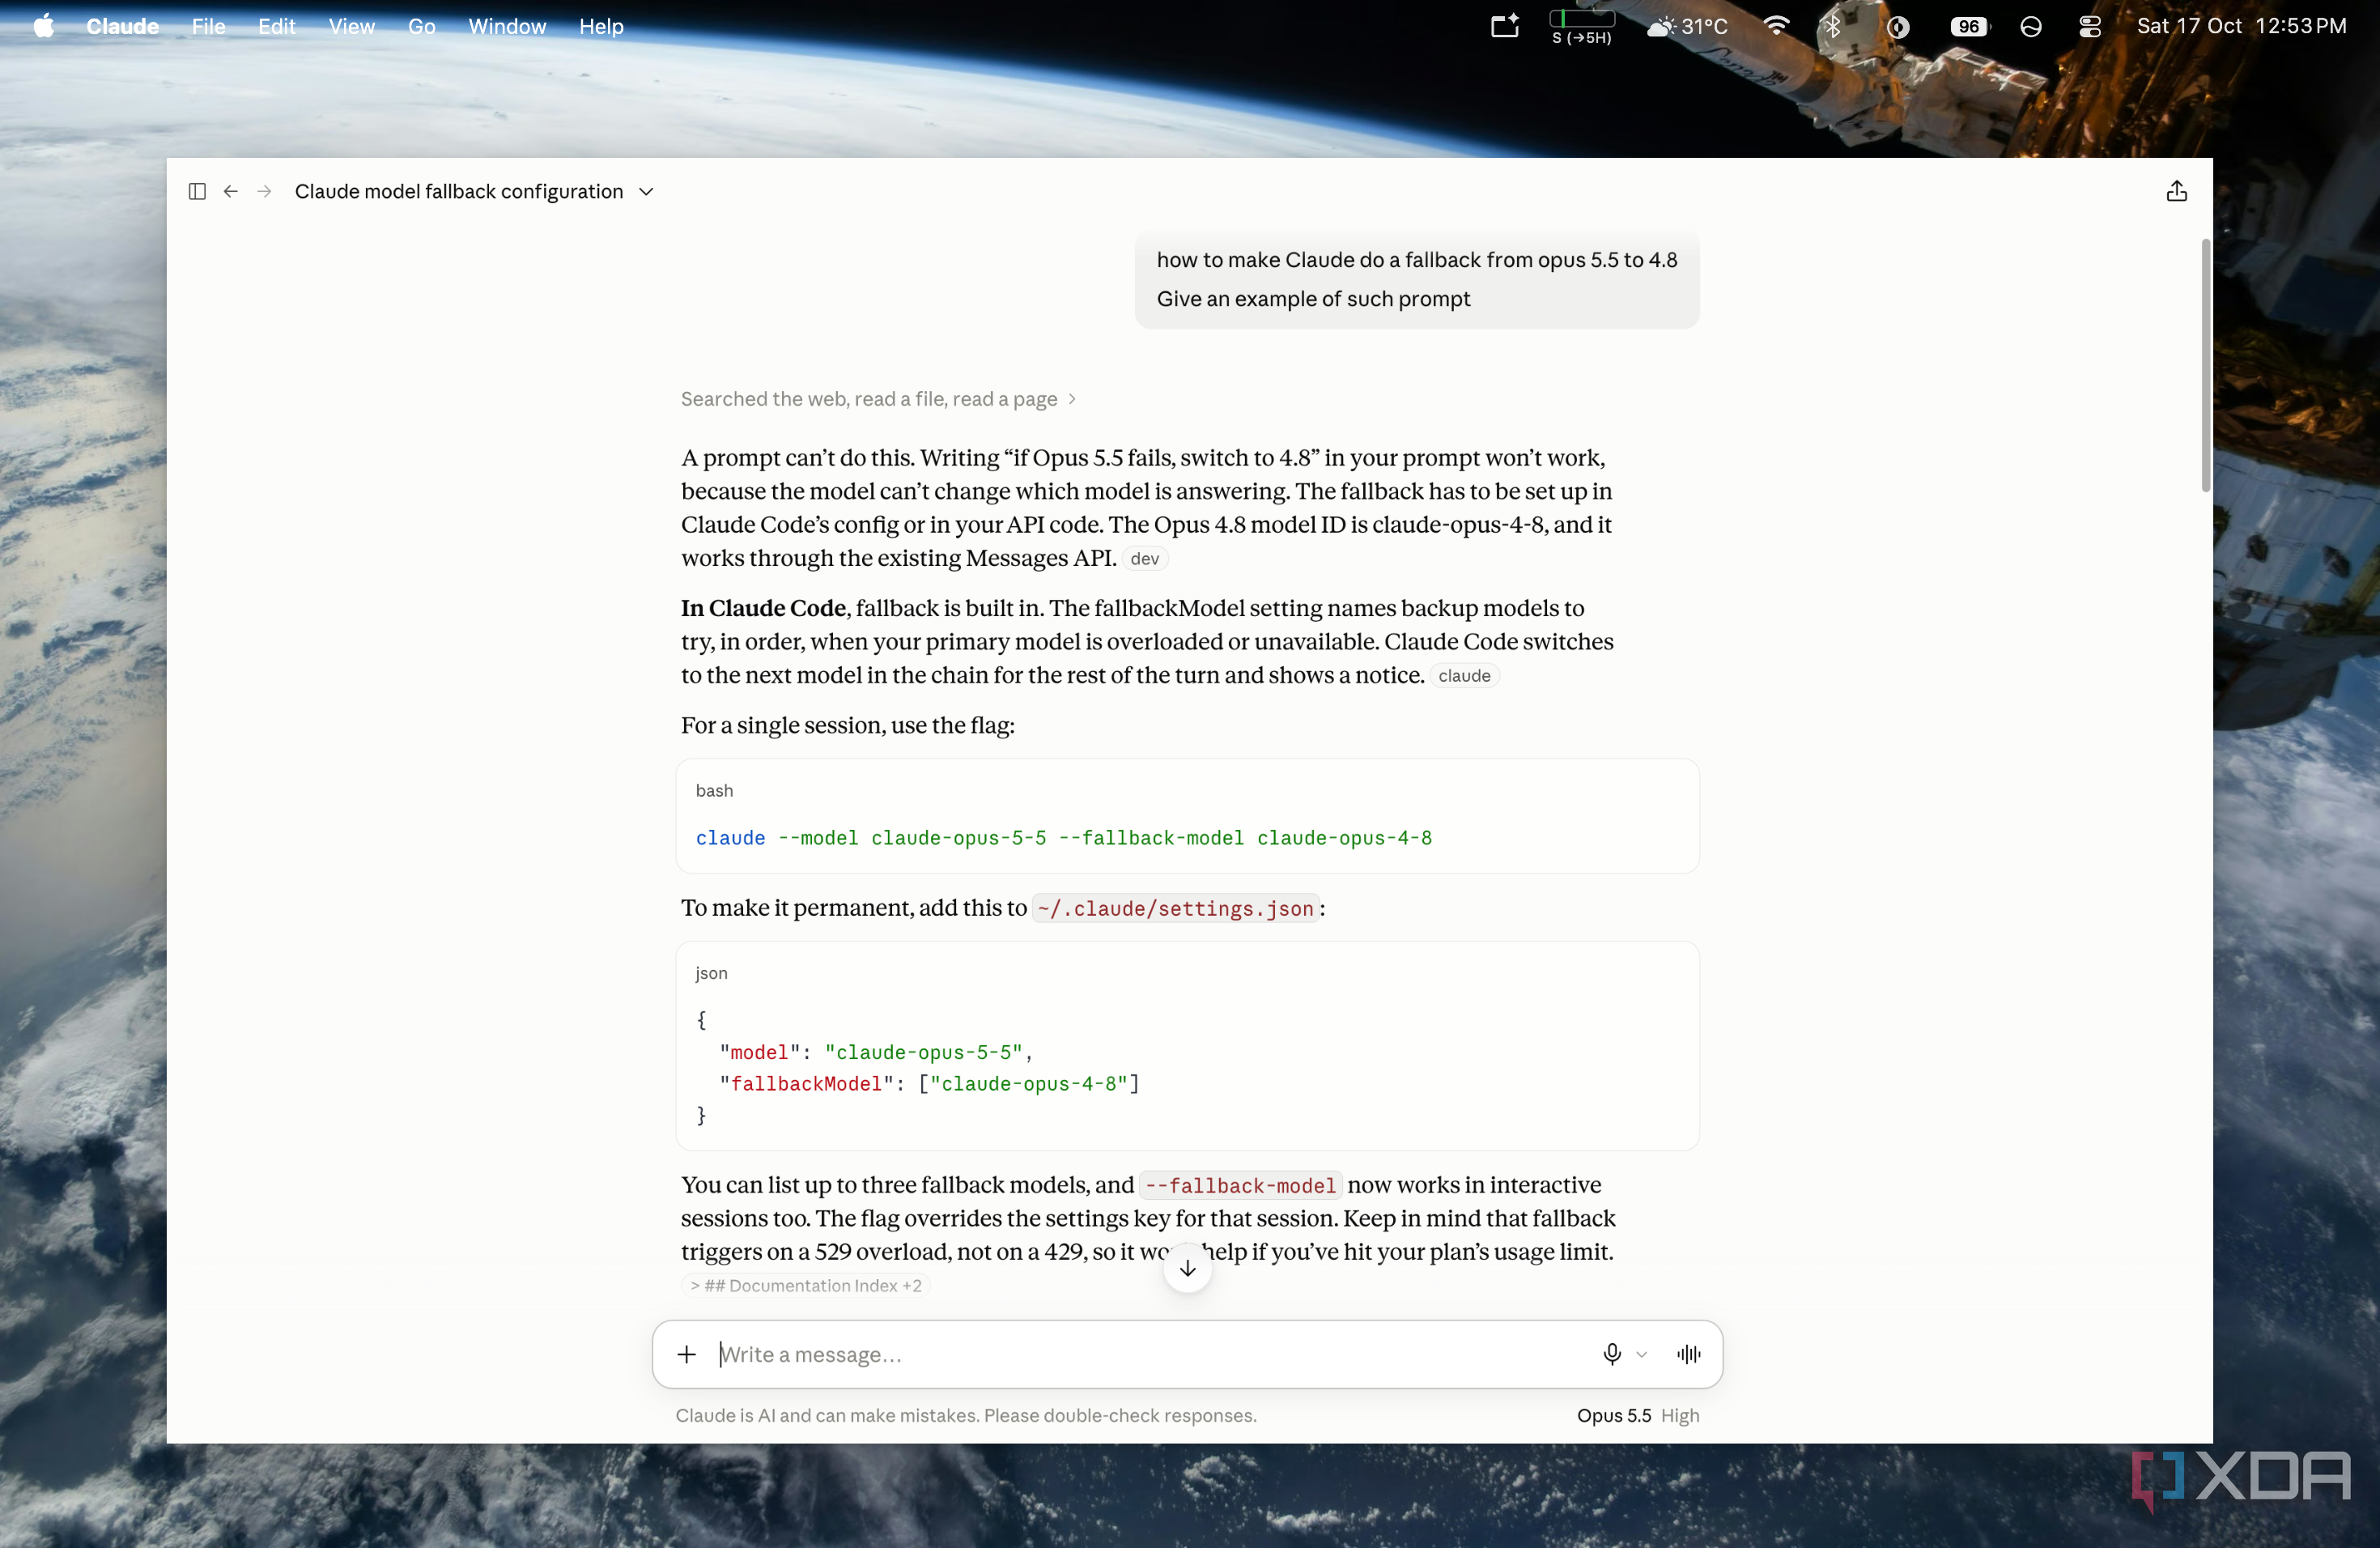
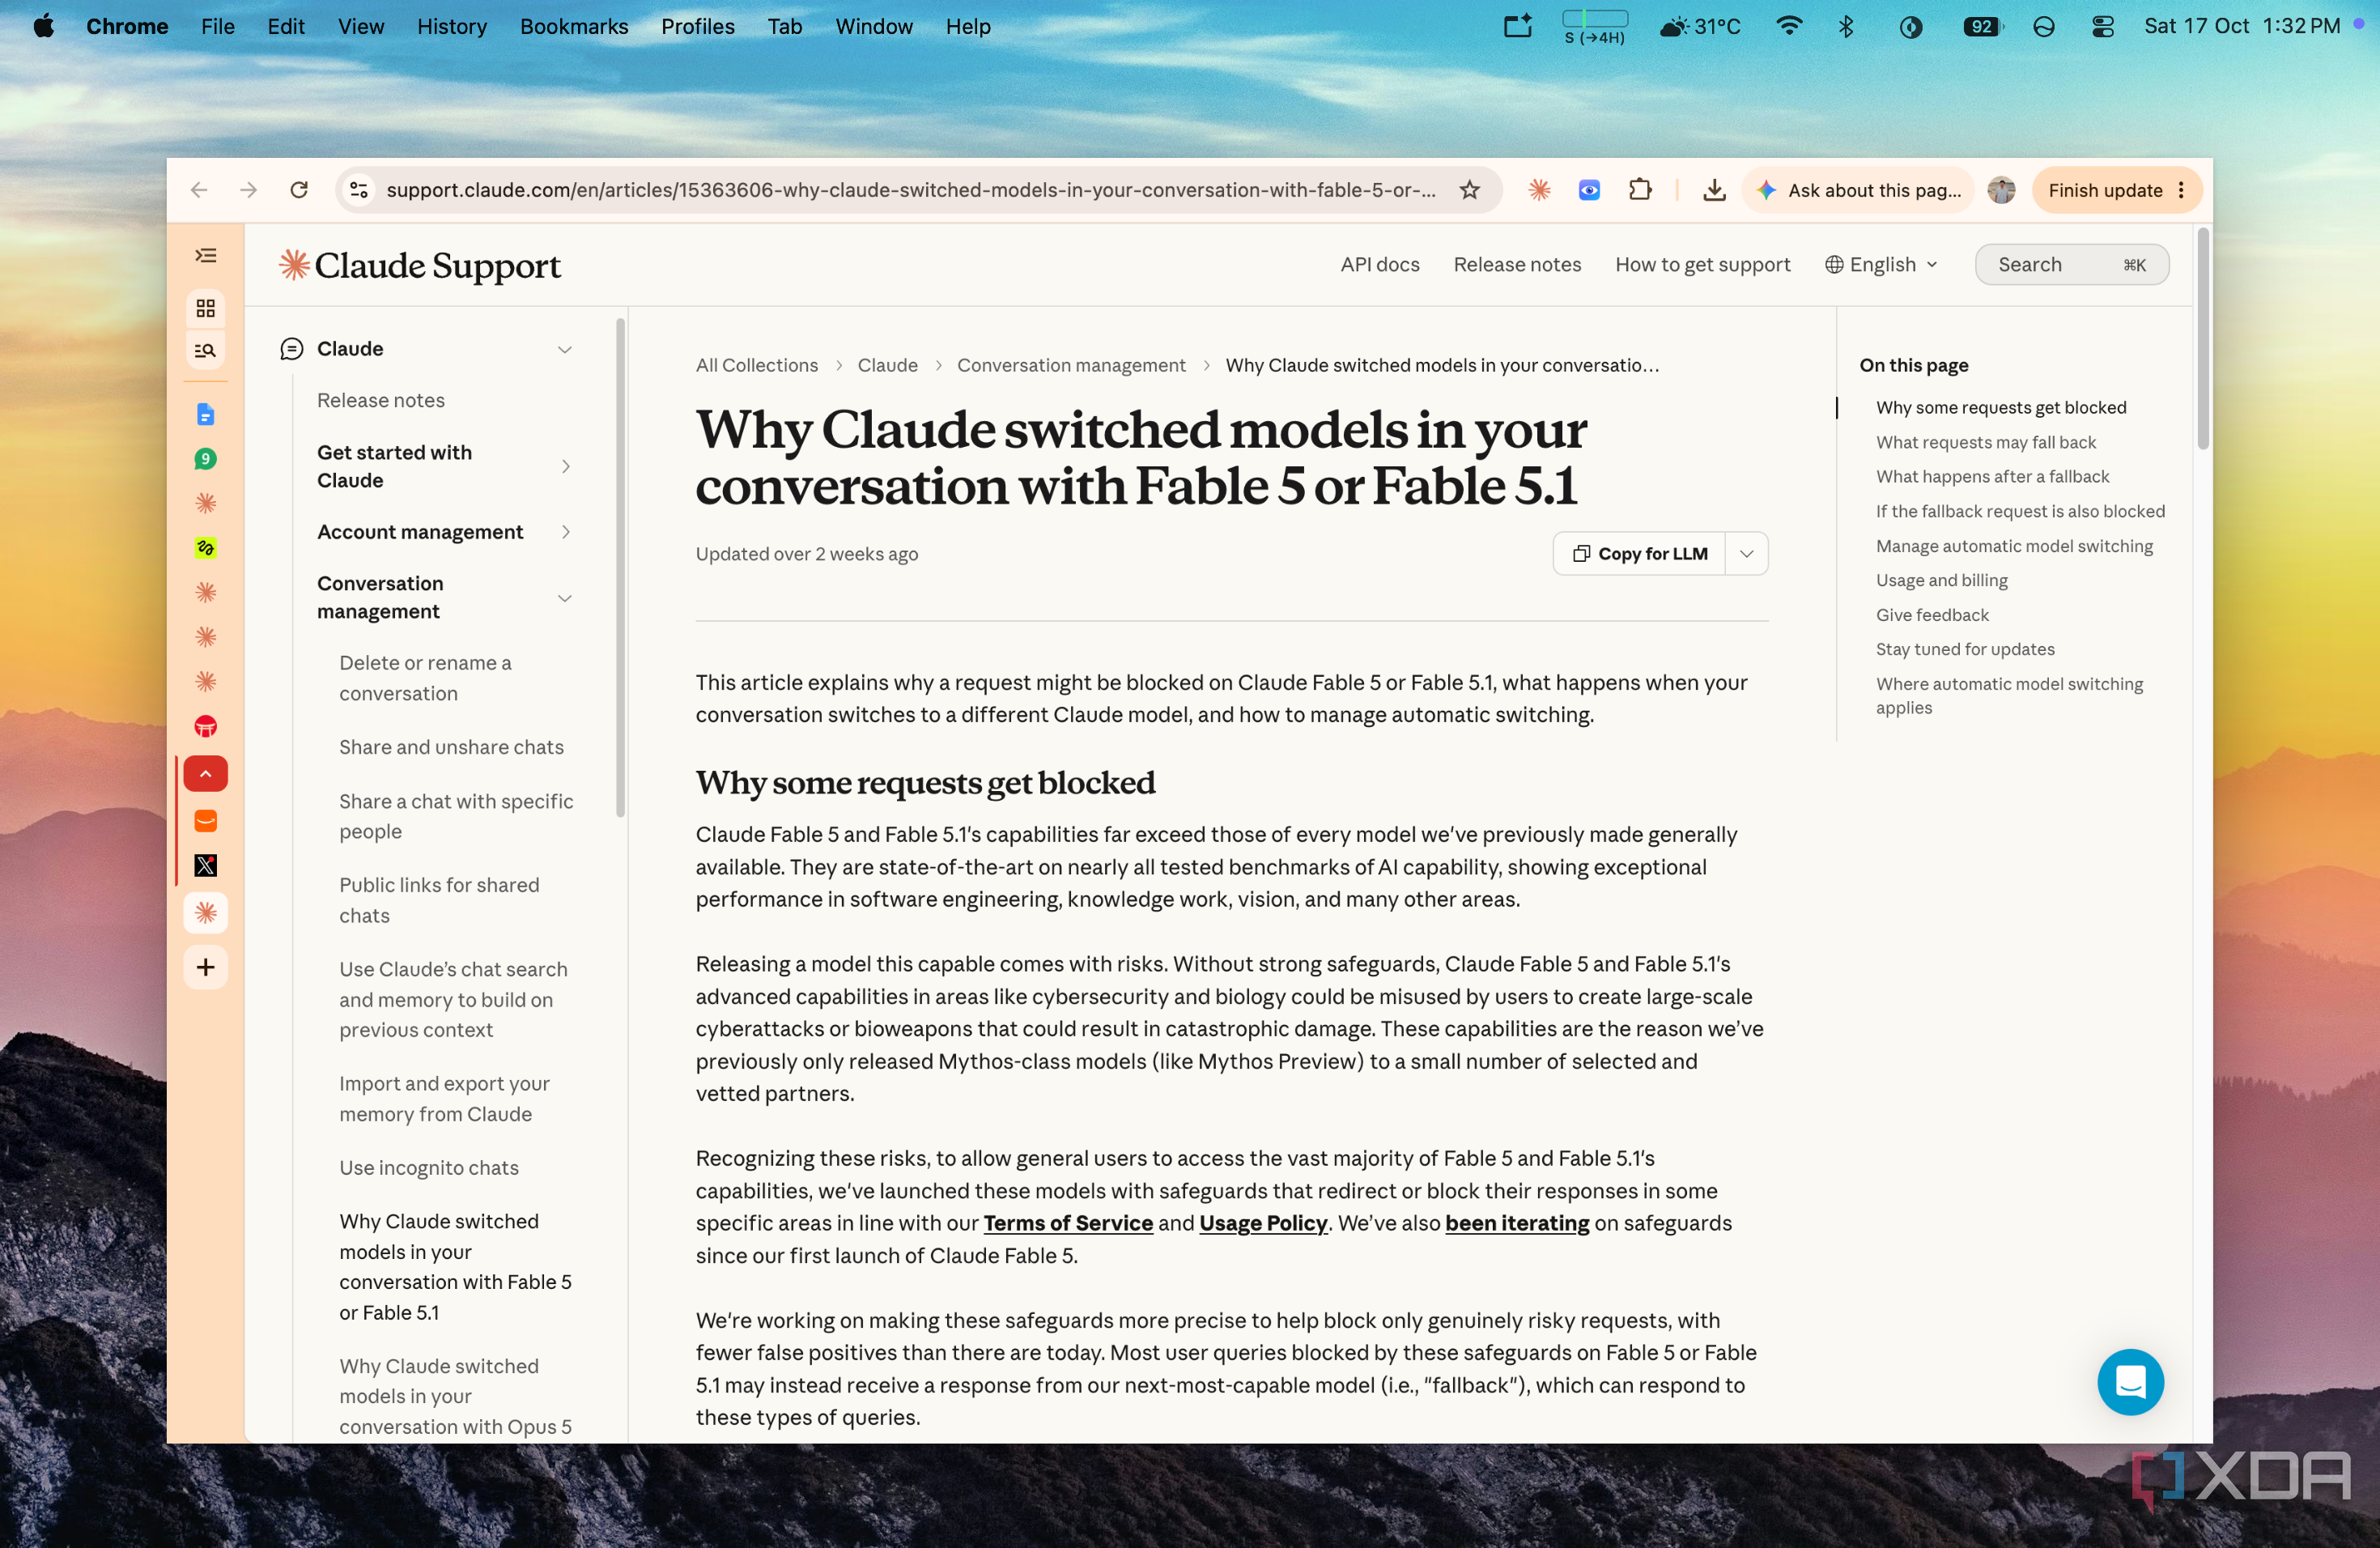
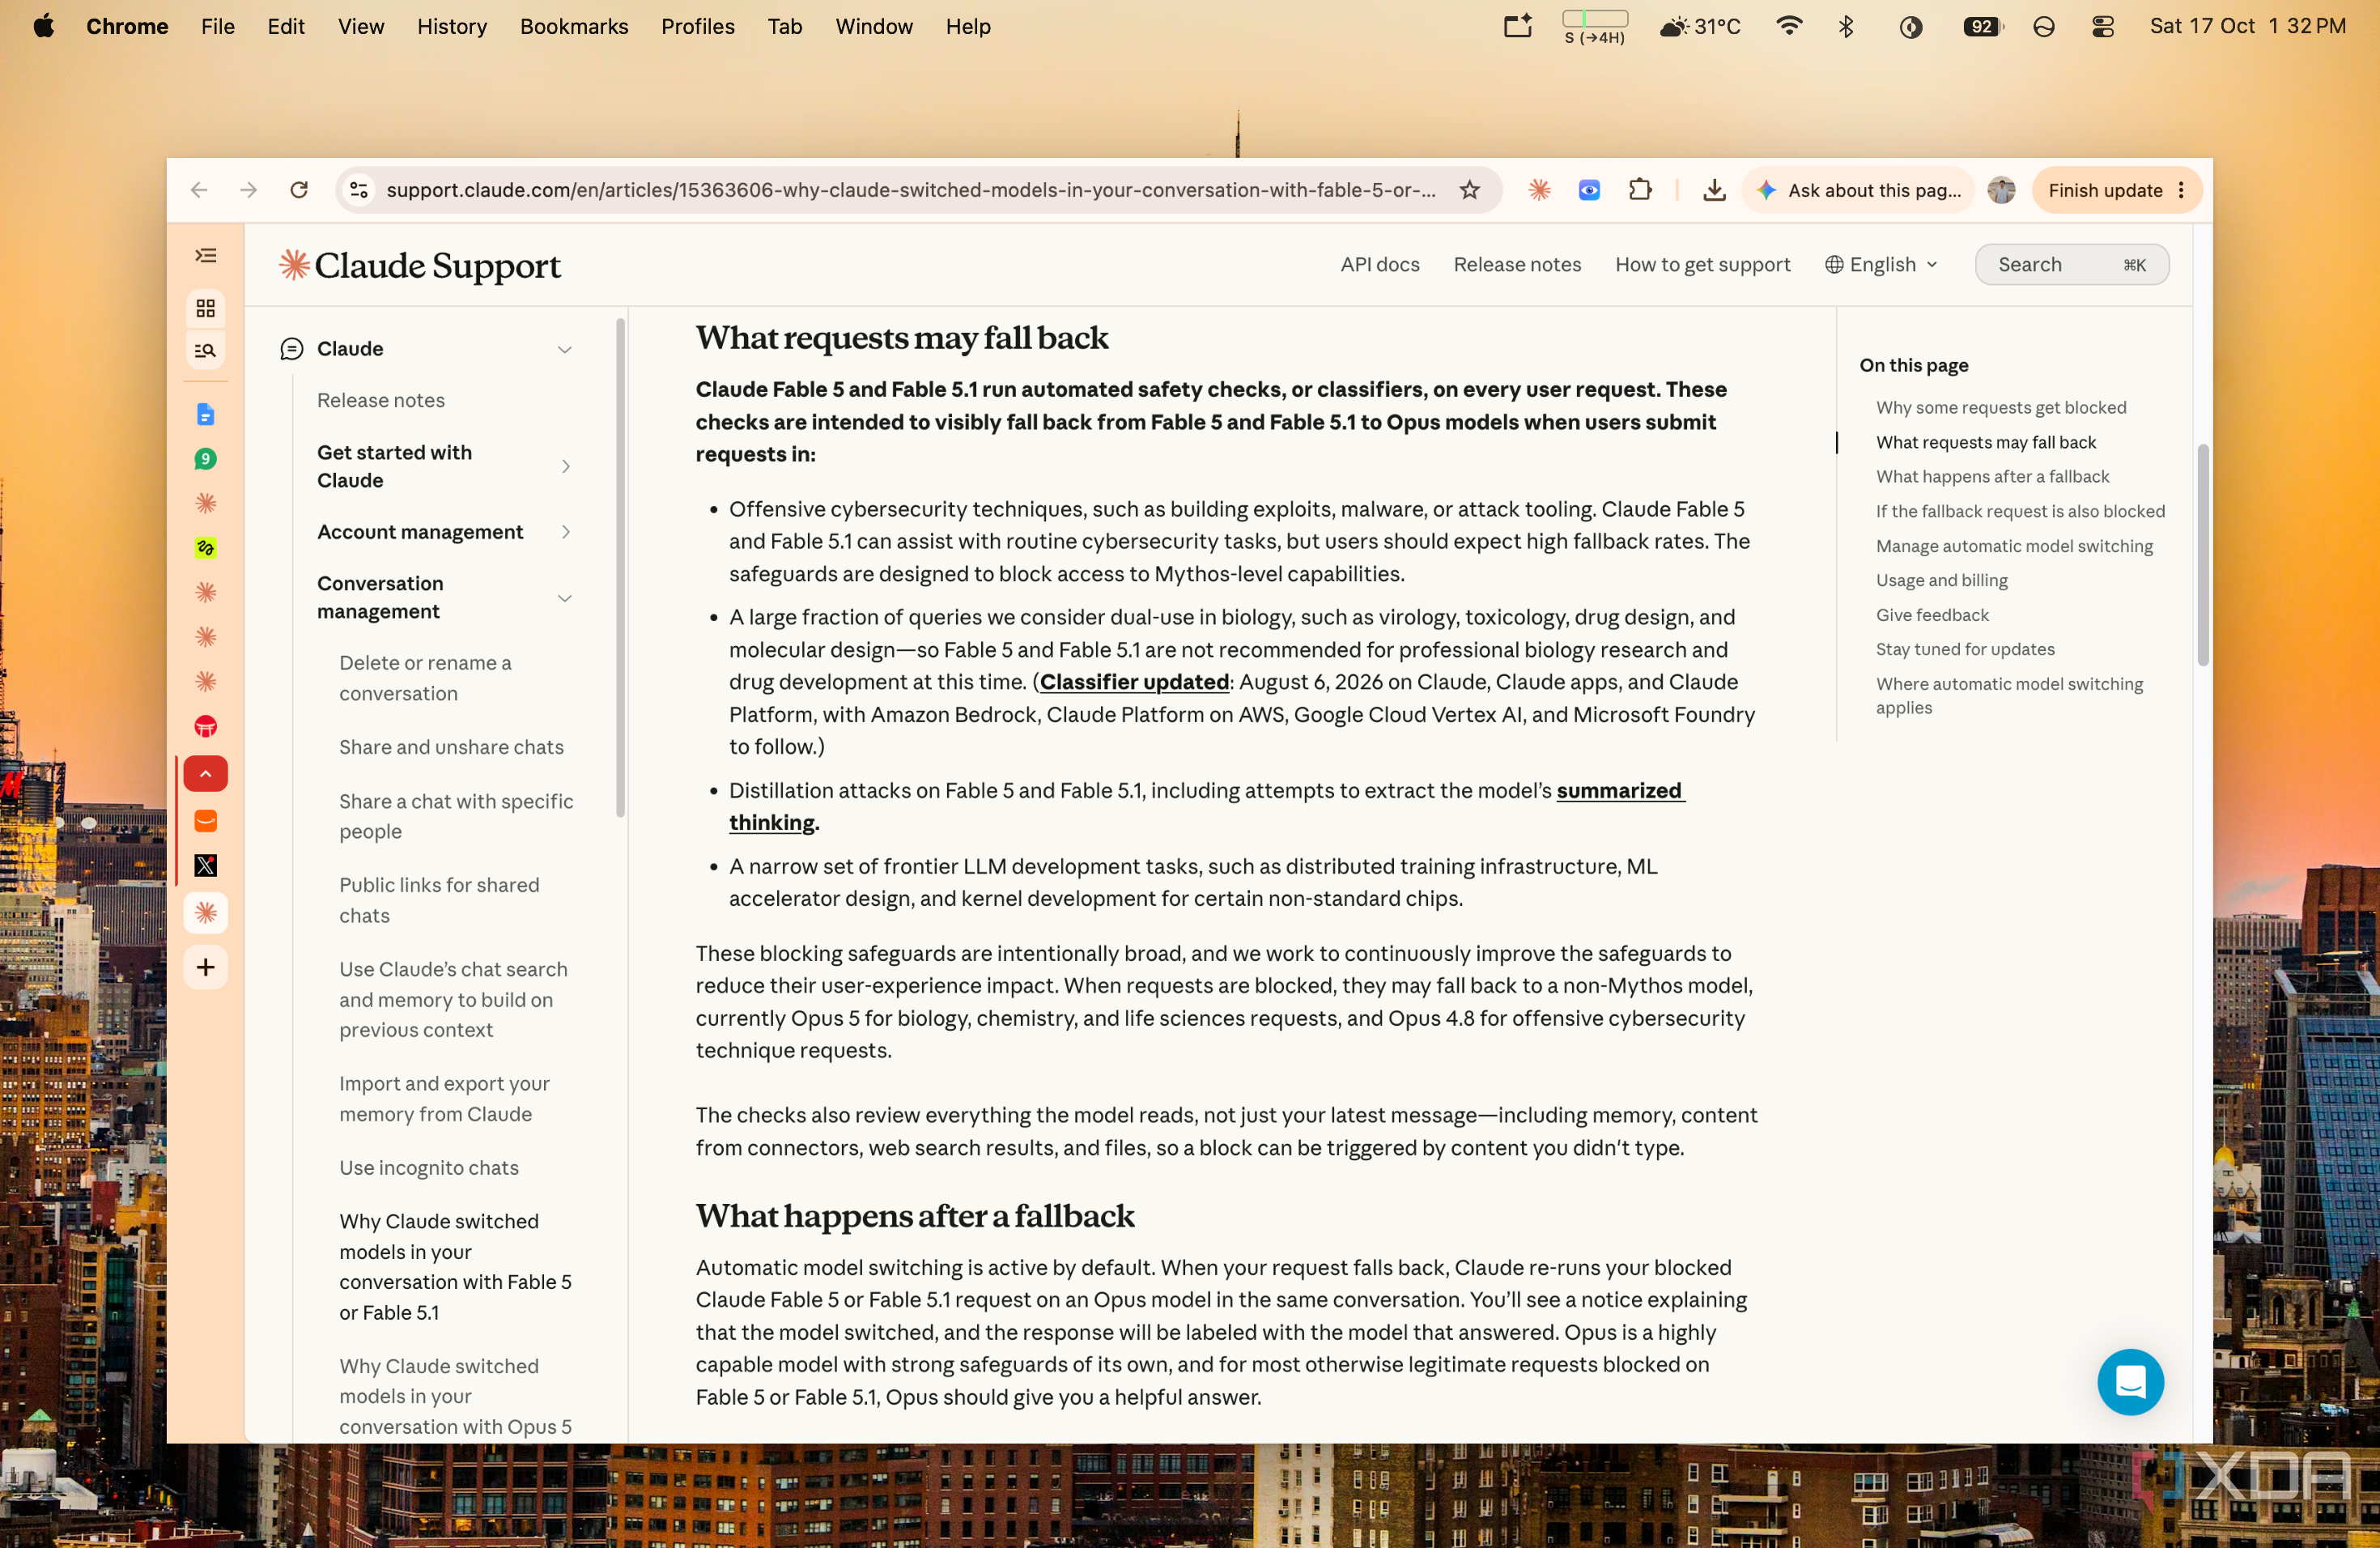
Claude Opus 5.5 launched on September 22, and Anthropic rates its cyber skills close to Claude Mythos 5.1, the model it keeps behind trusted-access programs. So every request passes a screen. A probe reads the model's internal activations, a lighter classifier double-checks anything suspicious, and a trained classifier makes the final call. If it decides you've asked for offensive cyber work, Opus 5.5 is blocked, and across Anthropic's own apps, claude.ai and Claude Code included, Opus 4.8 answers instead.
Anthropic says most cybersecurity tasks get rerouted this way, and its system card draws the line in plain words. Finding vulnerabilities in your own source code is fine, while digging them out of compiled binaries isn't. Secure code review, threat modeling, patching known issues, and triaging alerts stay on the flagship too. Malware analysis and exploit validation are the kind of work that can trip the wire.
The switch also sticks. Once it fires, the model picker stays on Opus 4.8 for the rest of the conversation, so every reply after that comes from the older model until you switch back yourself. On the API, fallback is an opt-in, and the tell is the model name in the response. That's the quiet part, and it matters more than it sounds.
Anthropic's own testing found the fallback was the weak point
The safety net had the biggest hole in it

The clearest numbers sit in the system card for Claude Sonnet 5.5, which drops to Sonnet 5 the same way Opus 5.5 drops to Opus 4.8. Anthropic ran Shade, an adaptive attack tool from Gray Swan, across 40 coding scenarios with 200 attempts each. The attacker hides instructions in an agent's workspace and tries to make it wipe a disk or delete files.
Those destructive instructions are exactly what the cyber classifier hunts for, so they trip it. That's the twist. The attack itself pulls the request off the newer model and onto the older one, which is far easier to push around.
A quarter of the requests ended up on Sonnet 5 after a cyber block, and 12.01% of those were compromised. Sonnet 5.5, answering for itself, was compromised in 4 of 5,901 requests. Anthropic's own verdict is blunt: most of the model's attack success came from the fallback.
|
Anthropic's coding prompt-injection test (Sonnet 5.5 system card) |
Result |
|---|---|
|
Requests rerouted to the fallback after a cyber block |
25% |
|
Rerouted requests that were compromised |
12.01% |
|
Requests the newer model answered itself that were compromised |
0.07% (4 of 5,901) |
If that sounds like a Sonnet problem, the system card for Claude Haiku 5.5, published on October 7, says otherwise. Haiku 5.5 has no fallback at all, so a blocked request simply stops. In Anthropic's coding injection test, it was much harder to hijack than Sonnet 5.5, Opus 5.5, and Fable 5.1, and Anthropic says fallback mechanisms explain the gap. Most of those models' successful attacks came from requests a fallback model answered. In that test, the cheap model with no backup plan beat the flagship with one.
You don't have to type anything risky to trigger it
Your files and web searches get a vote too

The classifiers don't just read your prompt, either. Anthropic says they also check what the model reads for you, including memory, attached files, connectors, and web search results. A security advisory pulled in by search, or a hostile instruction buried in a repo, can flip the switch on a question that looked boring when you typed it. If you run Claude as an agent across real code, remember that part, because it's exactly how the Shade attacks got in.
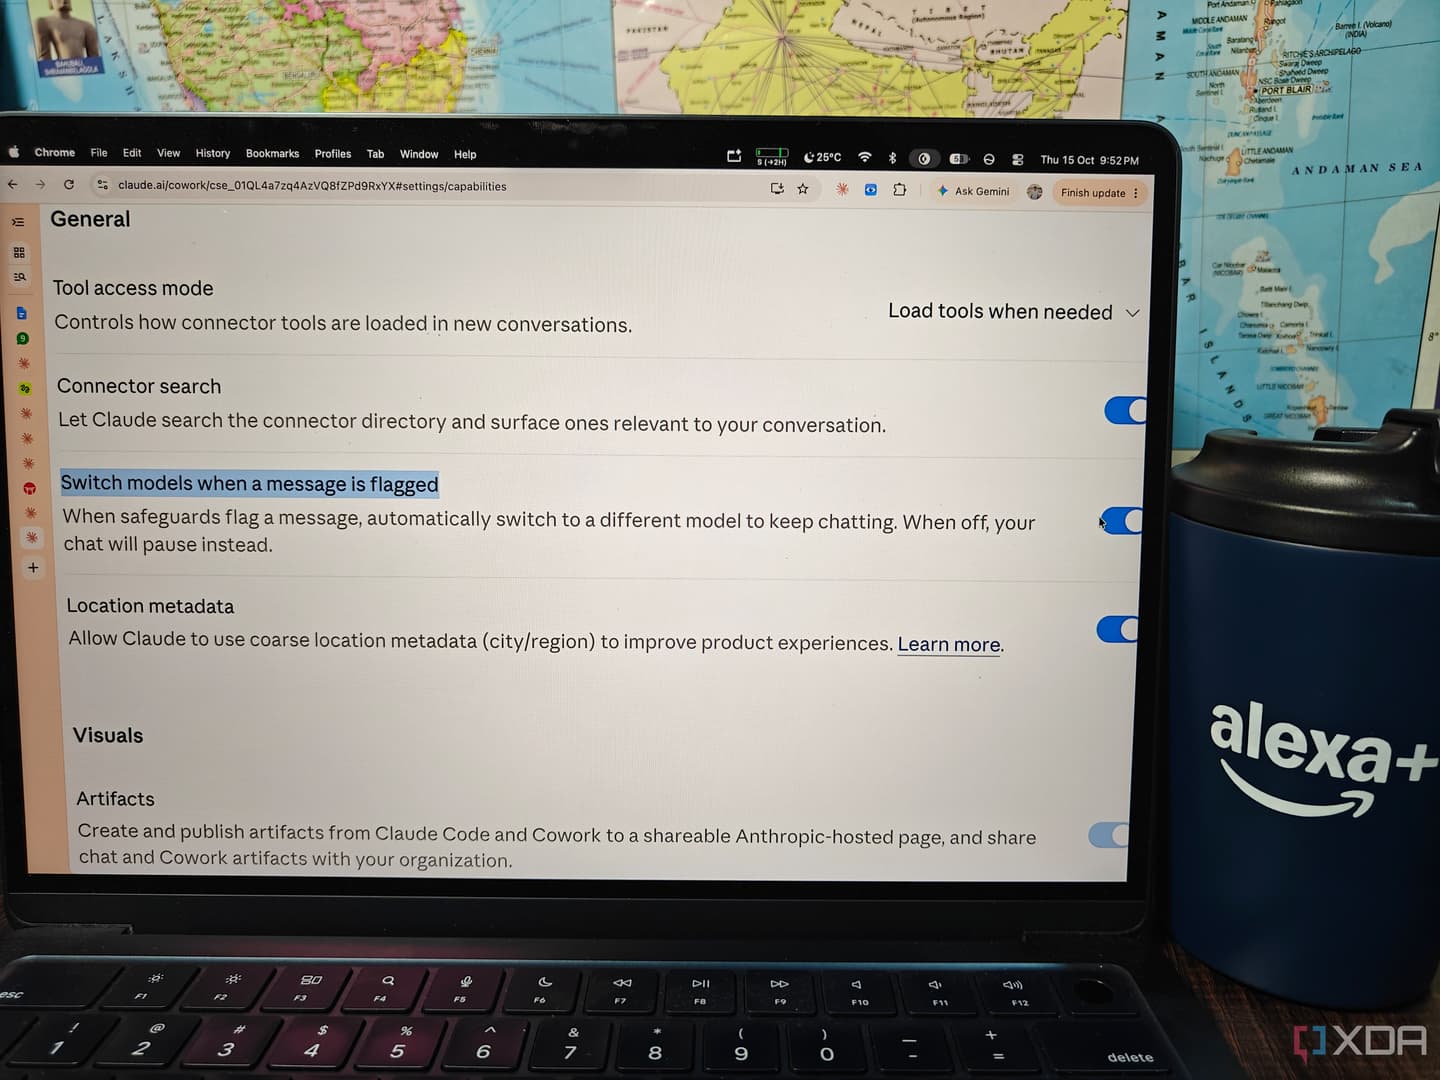
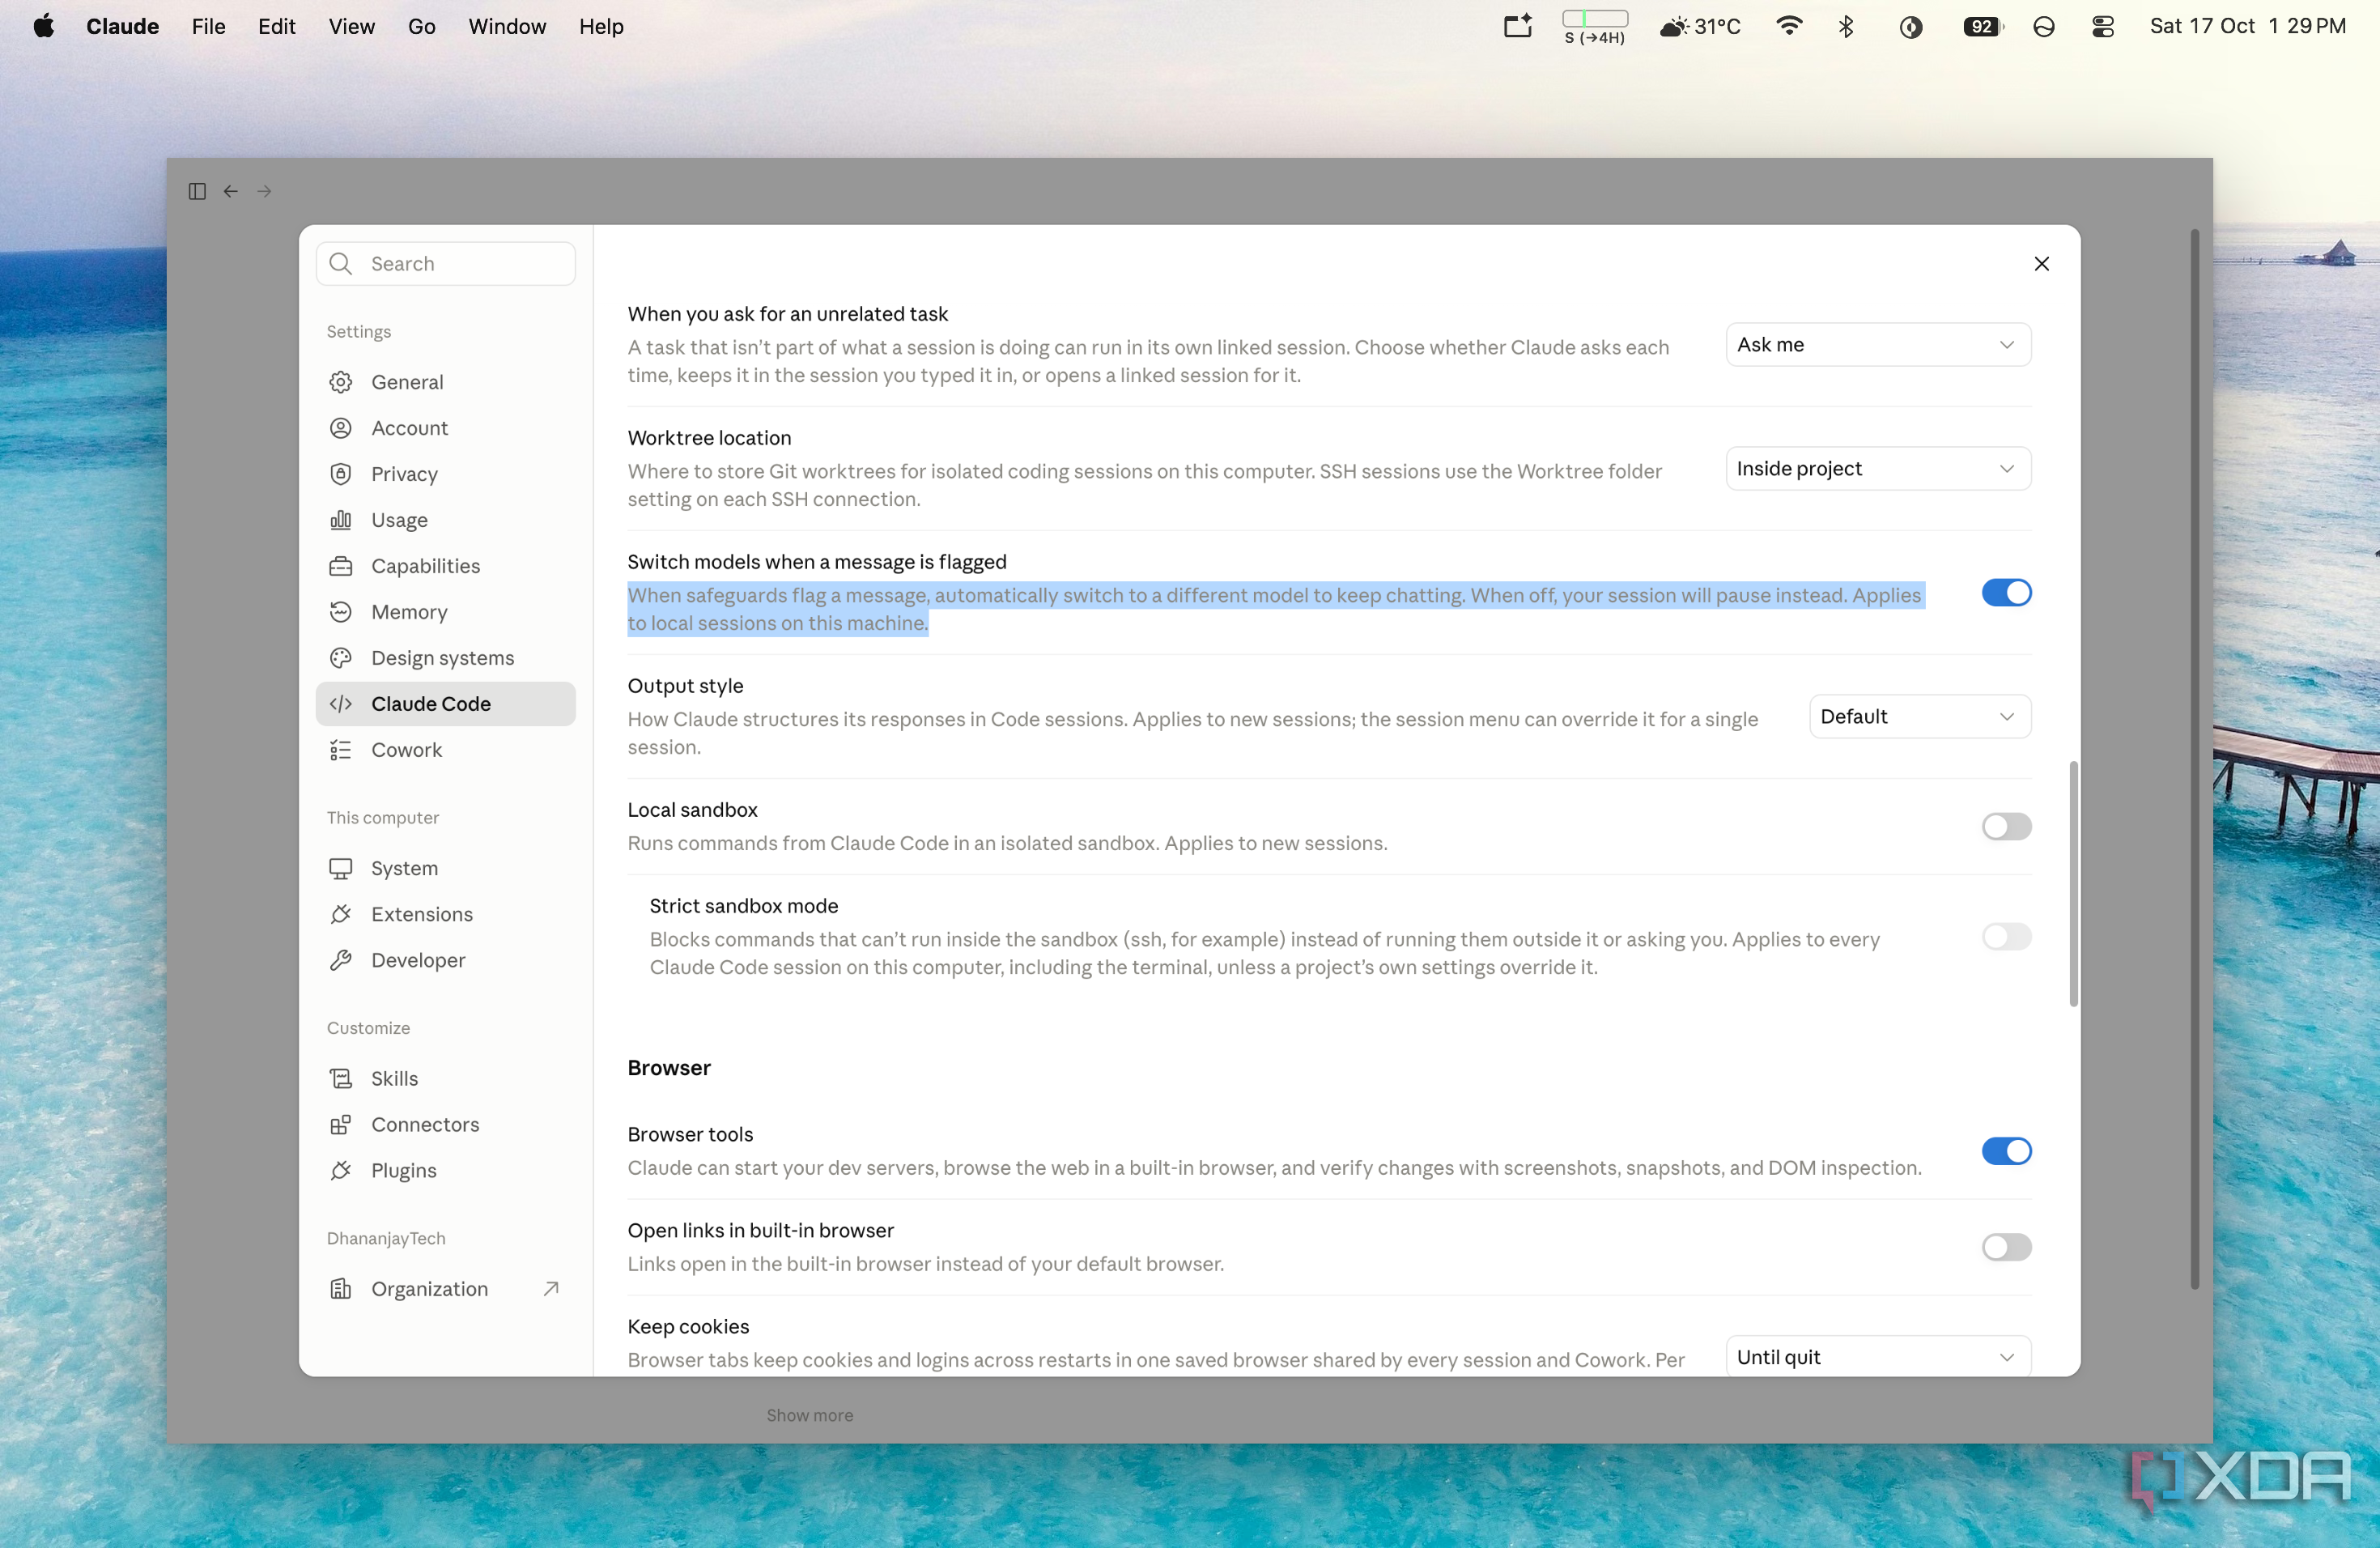
You get one real lever. In the Claude app, Settings -> Capabilities there's a toggle called Switch models when a message is flagged, and Claude Code keeps the same switch under Config -> MODEL & OUTPUT. Turn it off, and a flagged request pauses instead of landing on Opus 4.8. You can then rephrase it, retry it, or pick a model yourself.
If your security work is defensive, Anthropic's Cyber Verification Program is the other door. It expanded on October 6 into three tiers for defenders, red teams, and a small set of critical-infrastructure teams, and verified users get lighter classifiers on Opus 5.5. Individuals can only apply for the first tier, and only on a paid plan.
How often the Claude fallback actually gets hijacked
It blocks far more than it lets slip

The other side deserves a fair hearing. The 25% and 12.01% in that table come from Sonnet 5.5's card, where the fallback is Sonnet 5, so treat them as the clearest published example rather than an Opus 4.8 measurement. On a second, external benchmark that Gray Swan built with the UK's AI Security Institute, the fallback barely registered. One of 777 fallback-served runs was compromised, and Anthropic says fallbacks don't degrade robustness there.
The switch also does the job it was built for. In Anthropic's own cyber-scenario test, Opus 5.5 without verified access was blocked in all 50 trials, and the company describes what falls back as a narrow set of higher-risk requests. Routine coding isn't on that list. The weak spot isn't that the switch exists. It's that an attacker who trips it on purpose gets moved to the model that's easier to fool.
When I'd turn Claude's model switch off
I'd leave the switch on for everyday chats, where the worst case is a weaker answer from Opus 4.8. But if you point Claude at content you didn't write, like repos, inboxes, or web pages, turn it off. A flagged request should stop and wait for you, not quietly slide onto the model Anthropic's own tests found easier to hijack. The safety net is real. It just isn't the place you want an attacker to land.