

Beginning his professional journey in the tech industry in 2018, Yash spent over three years as a Software Engineer. After that, he shifted his focus to empowering readers through informative and engaging content on his tech blog – DiGiTAL BiRYANi. He has also published tech articles for MakeTechEasier. He loves to explore new tech gadgets and platforms. When he is not writing, you’ll find him exploring food. He is known as Digital Chef Yash among his readers because of his love for Technology and Food.
Running AI locally gives me more privacy and control, but choosing the right software matters more than I initially expected. Ollama is one of the easiest ways to get started with local language models, letting me download models and run them without much setup. But once I started exploring more advanced use cases, I began questioning whether Ollama was the best option for the long run. I wanted to understand what happens under the hood and whether running models directly through an inference engine like llama.cpp would give me more flexibility.
Ollama is the easiest way to start with local AI
It fits naturally into my daily workflow
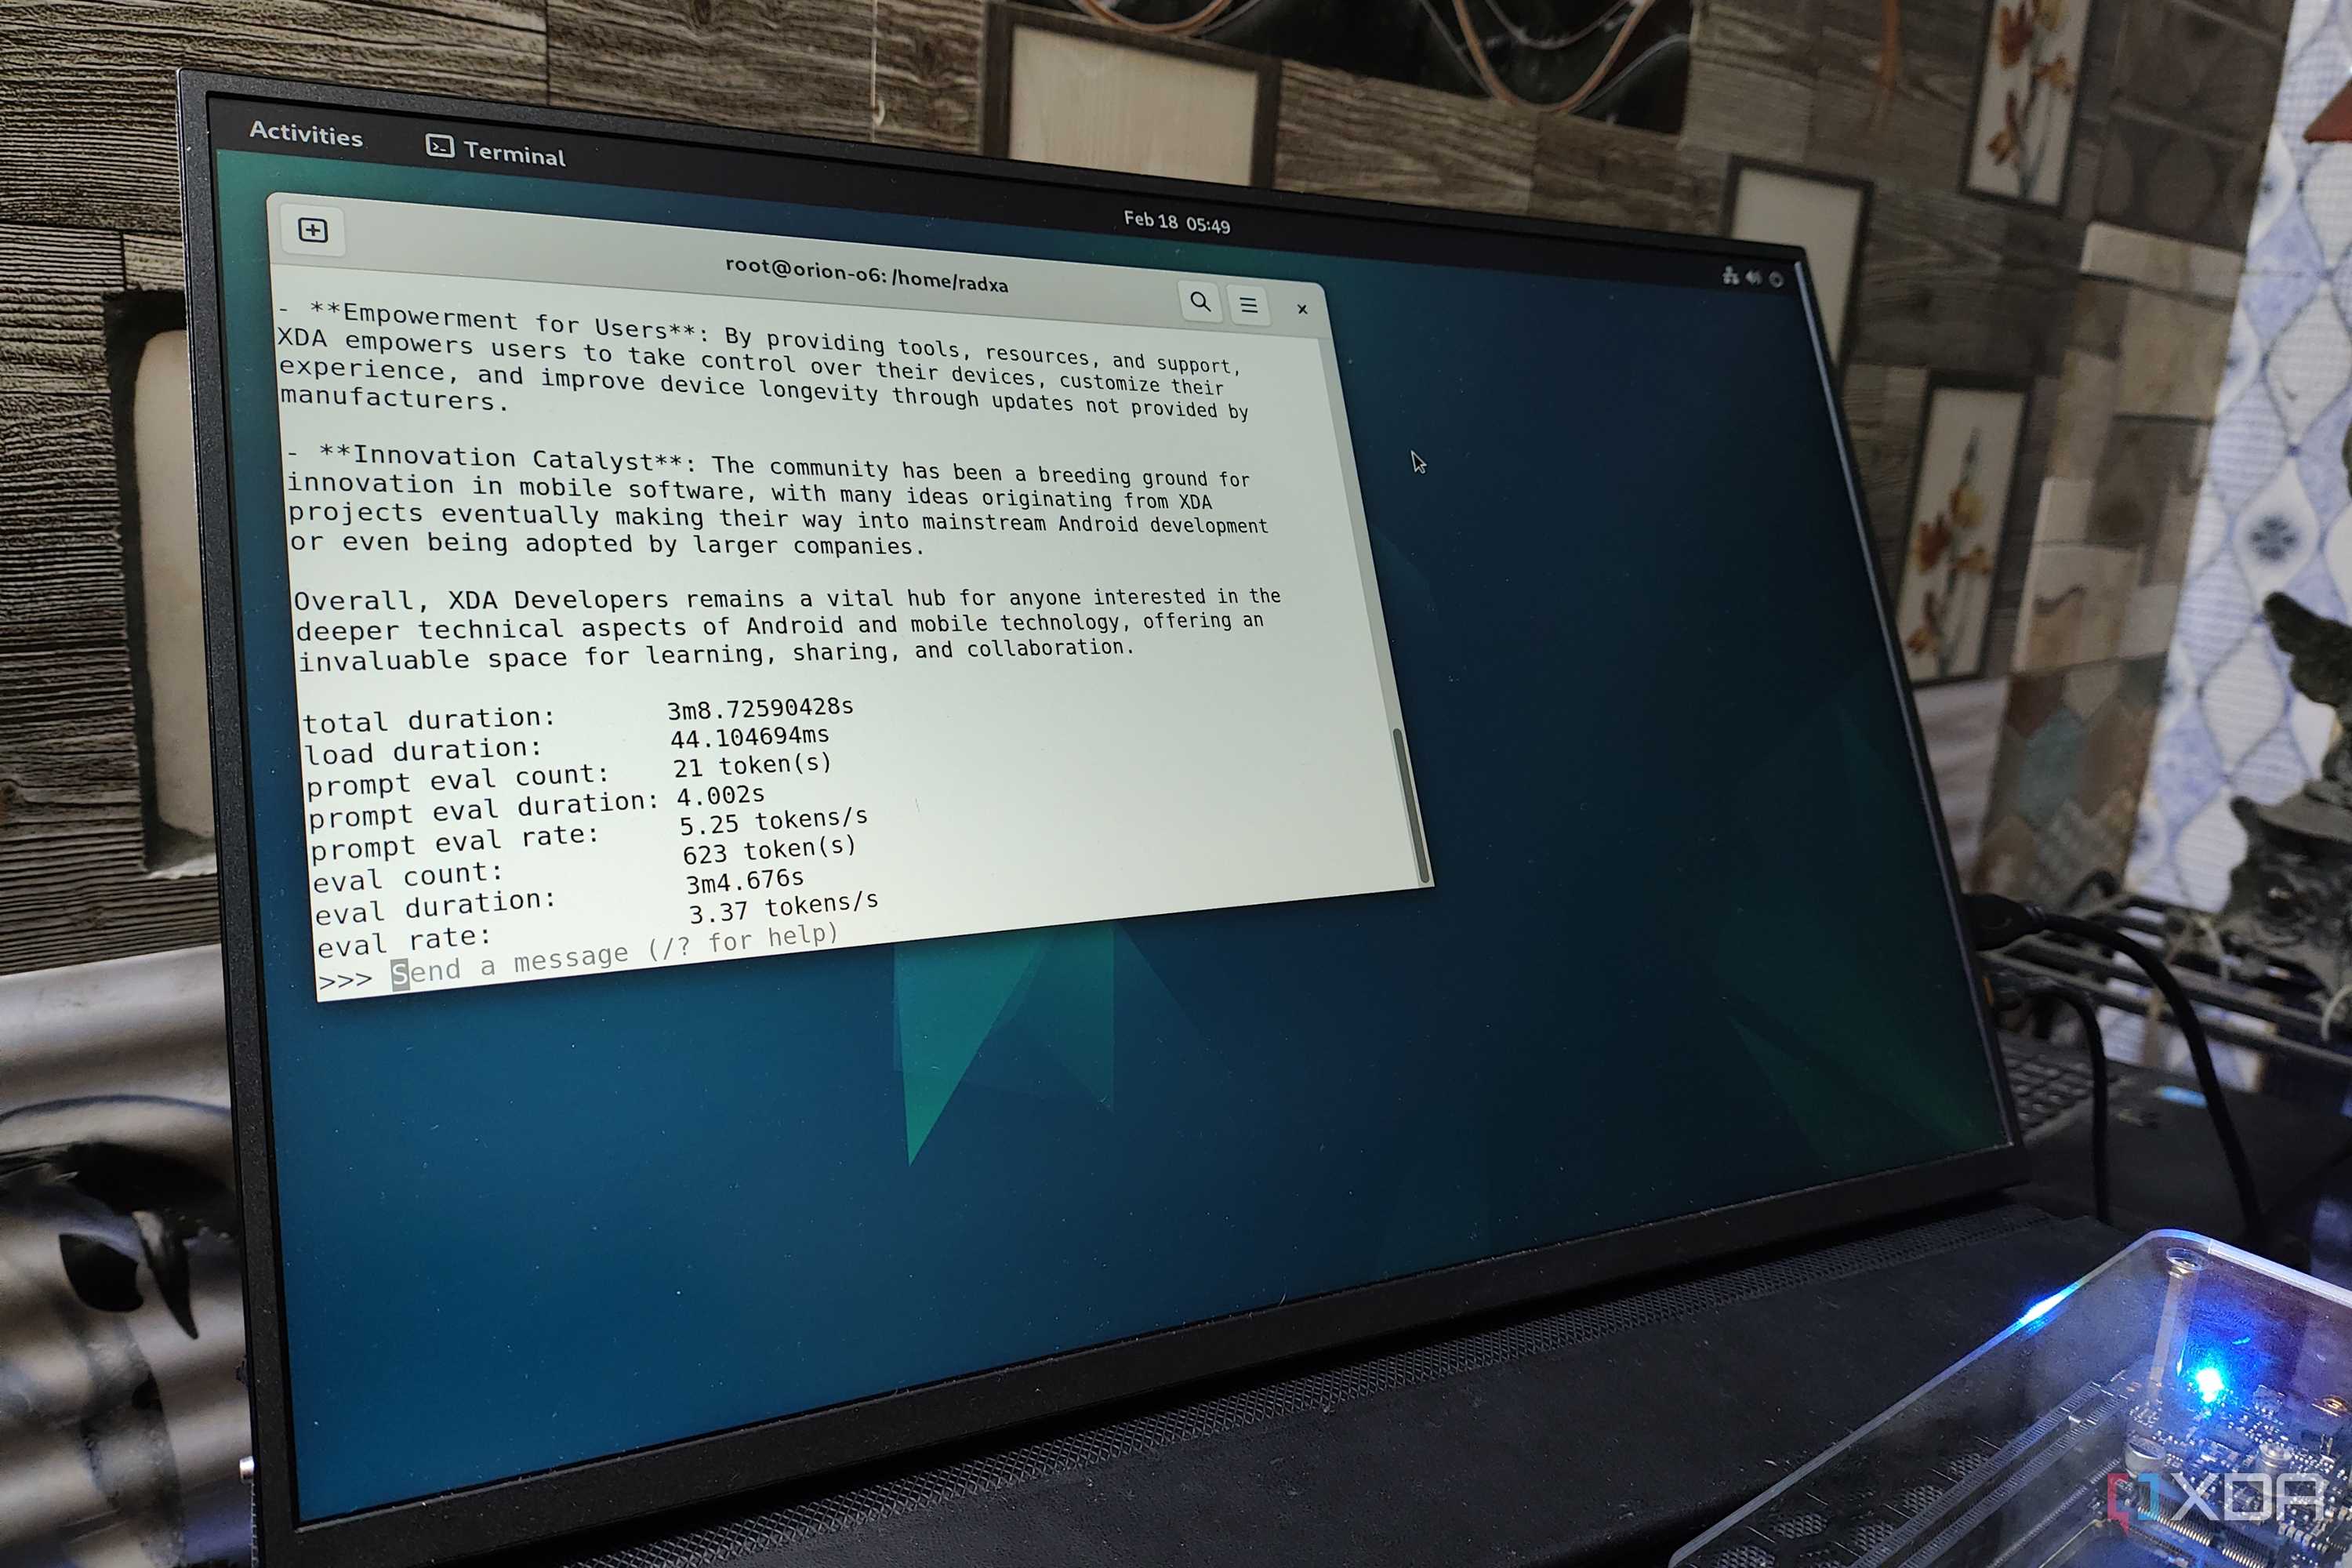
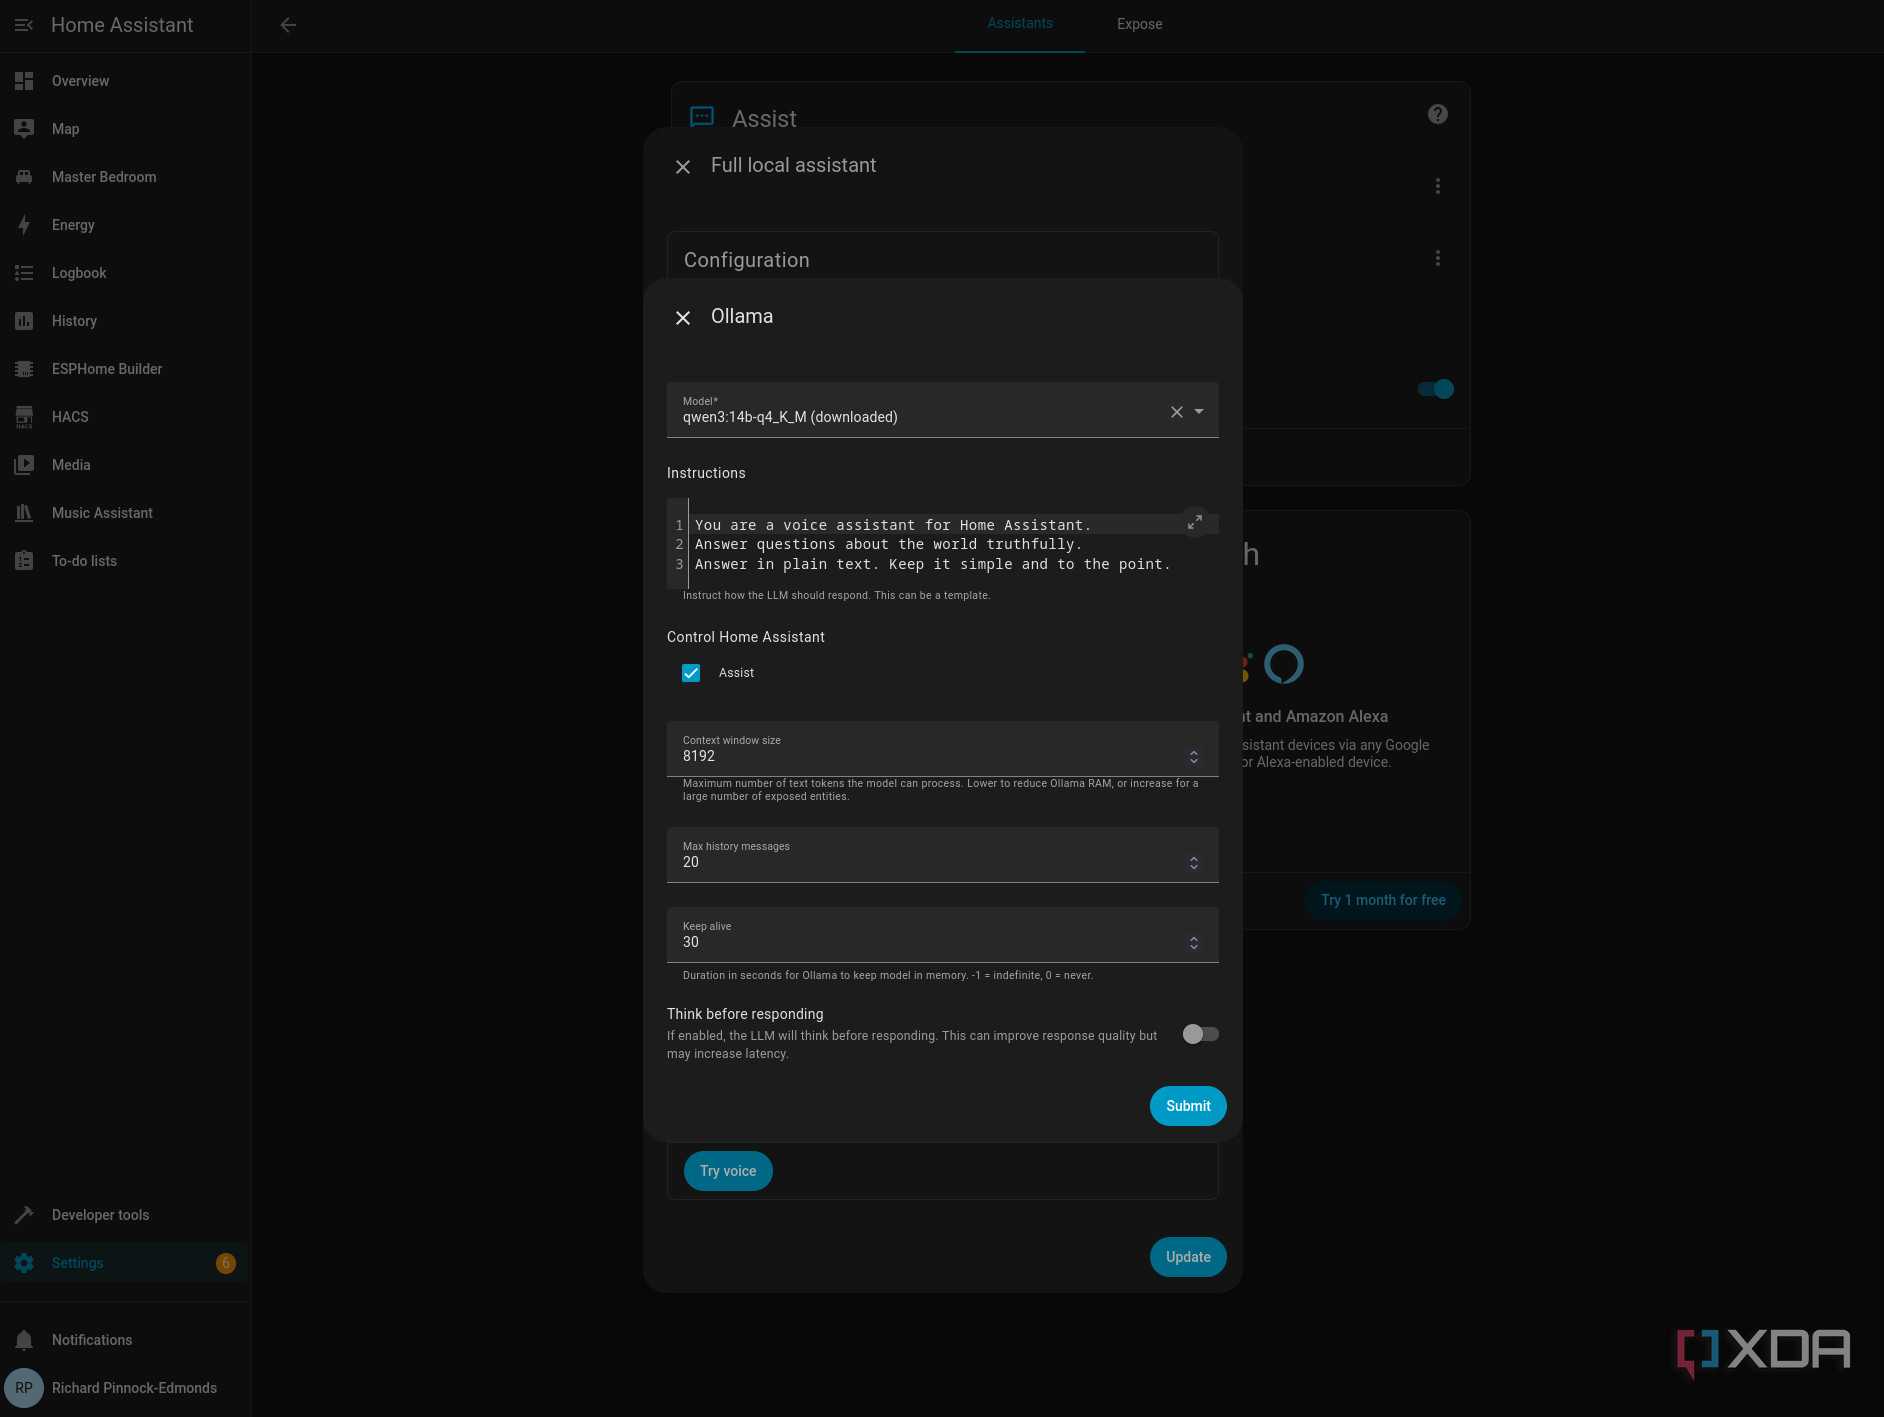
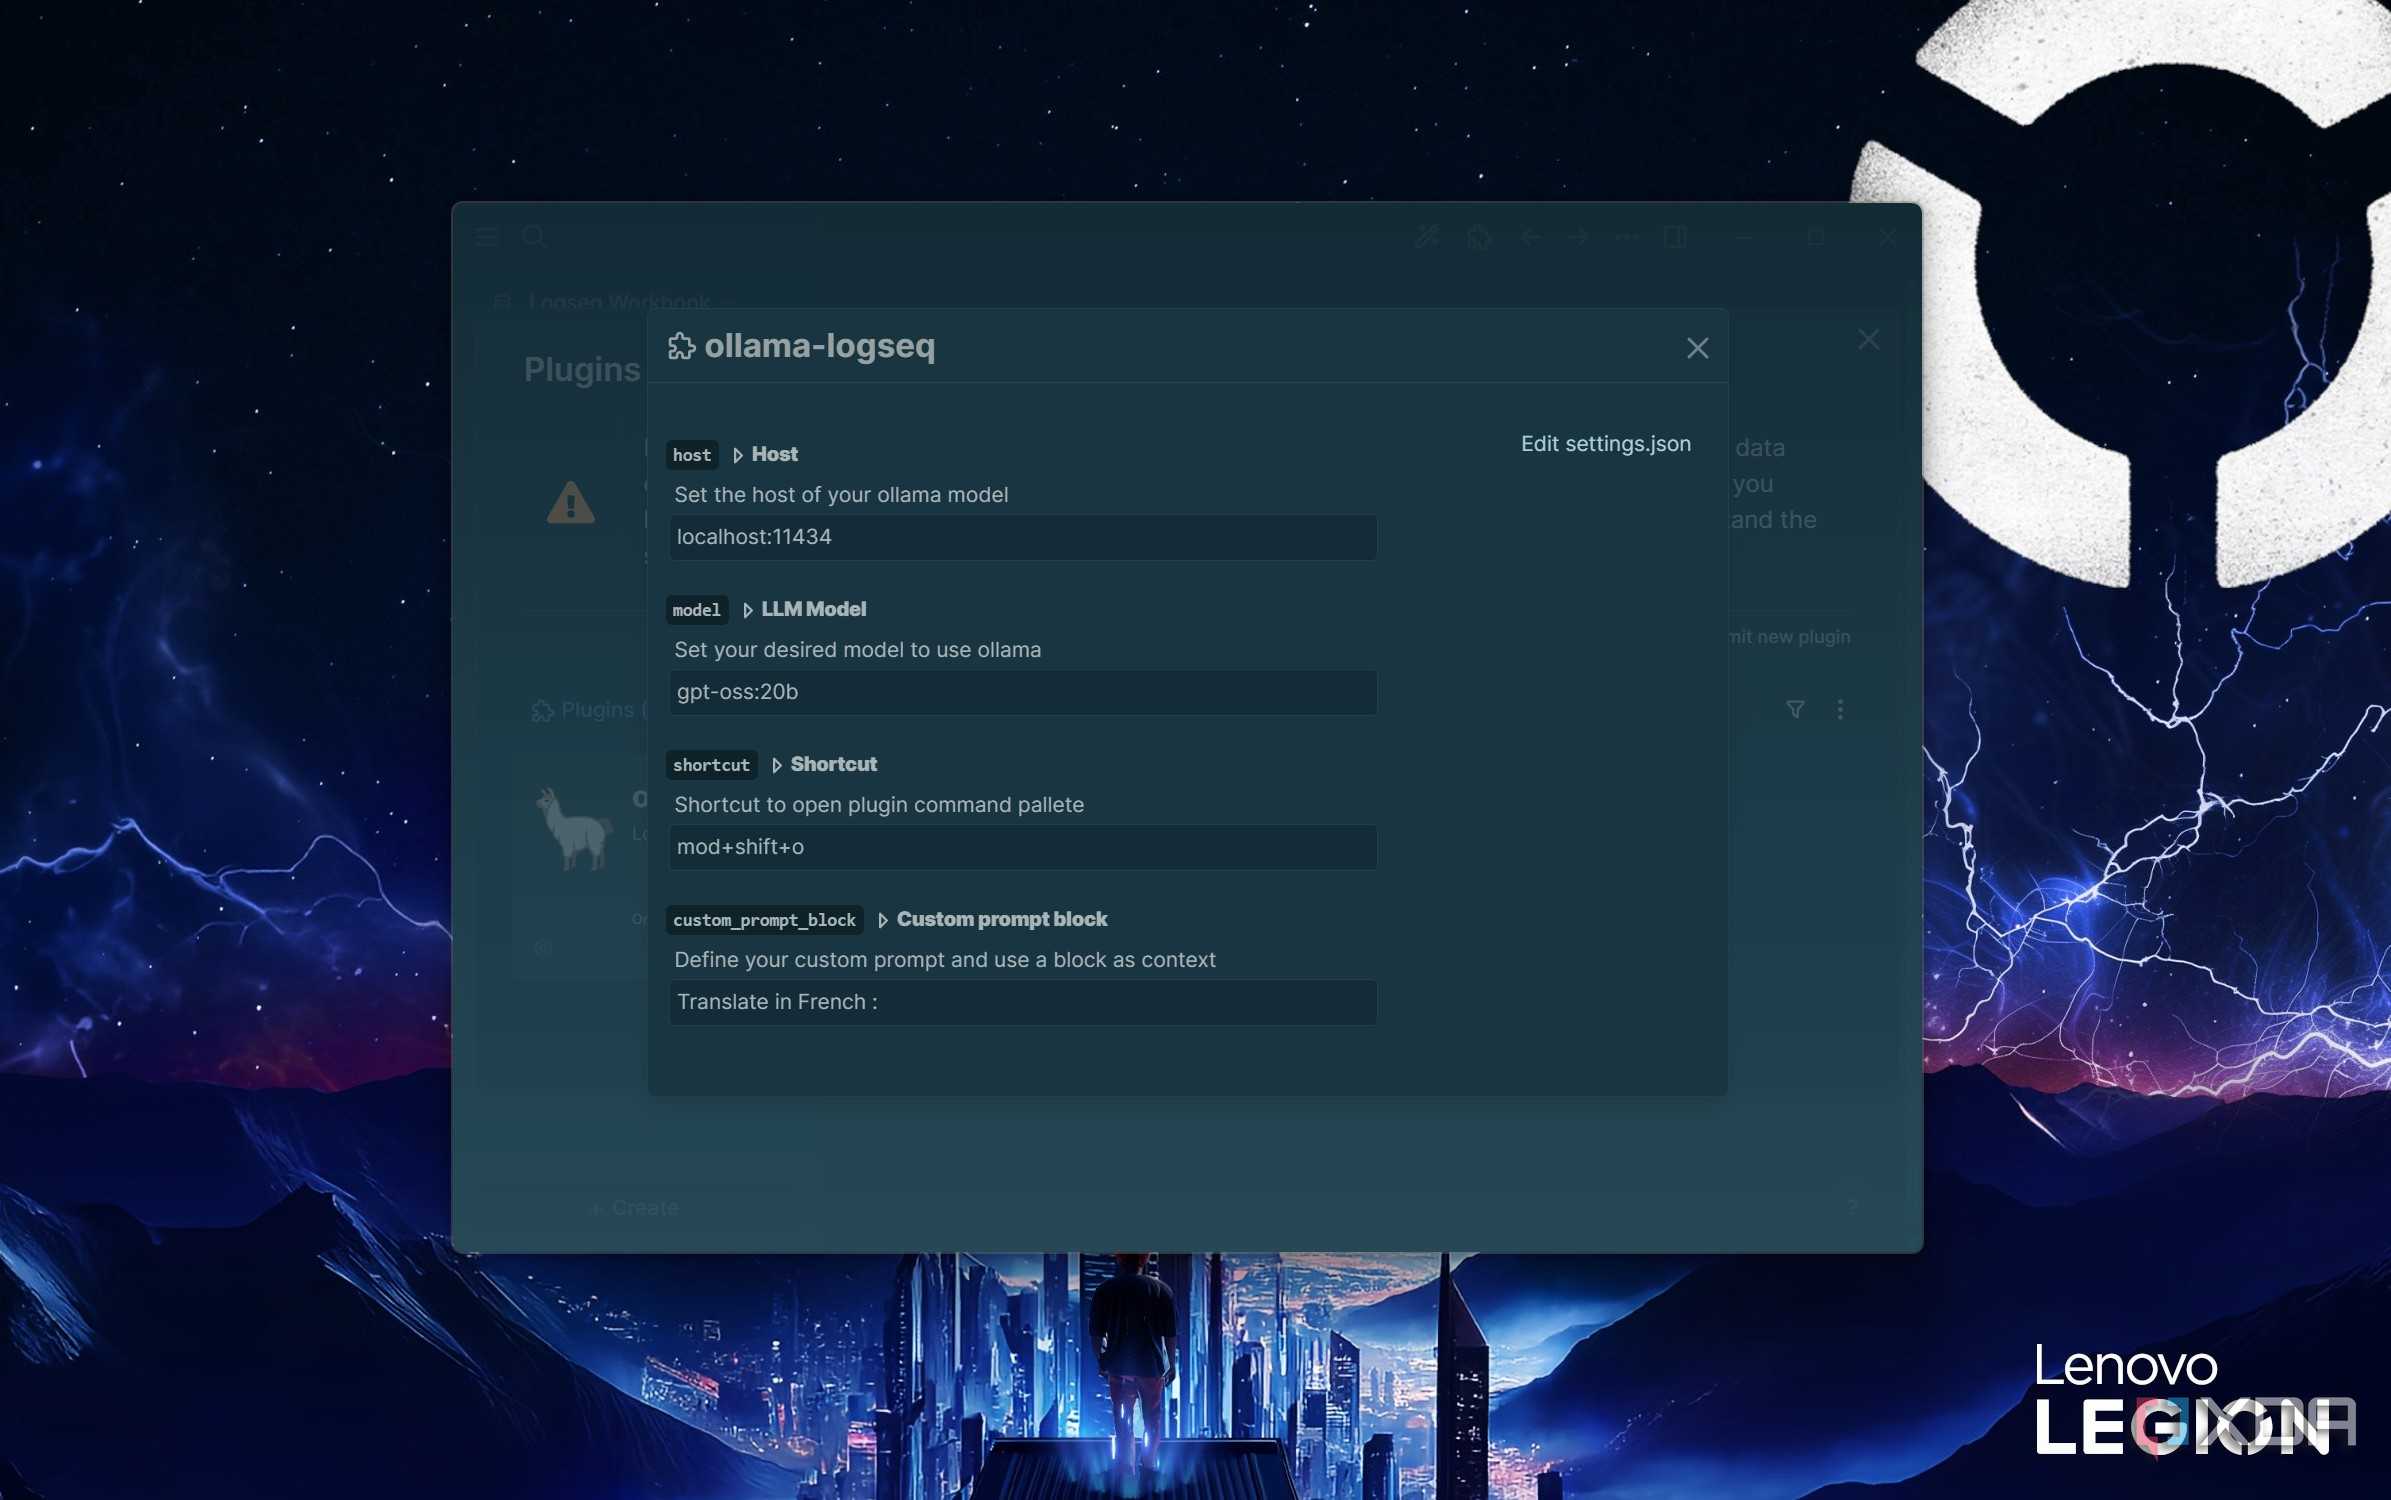
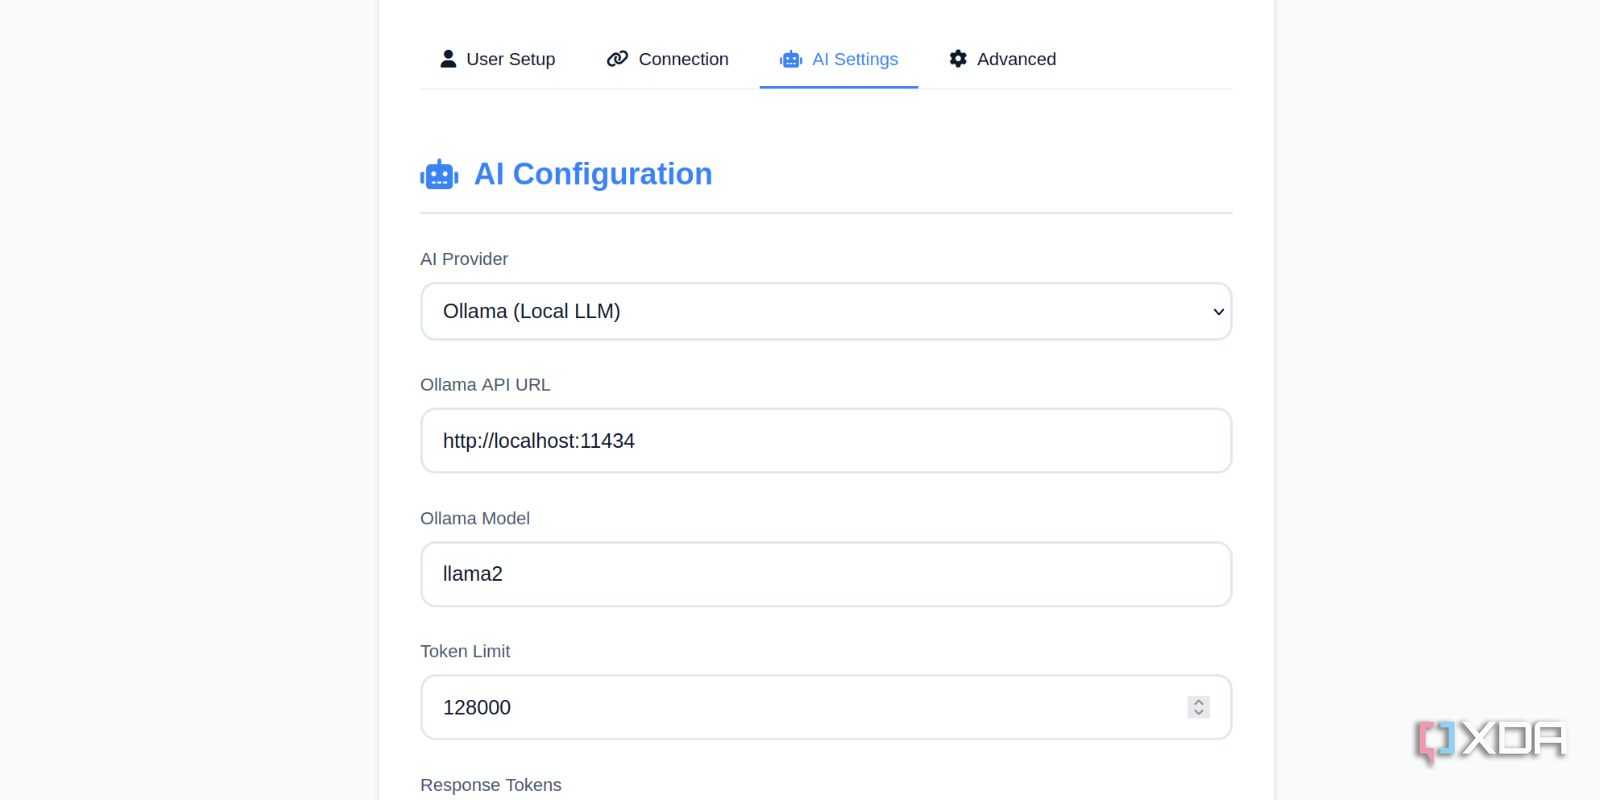
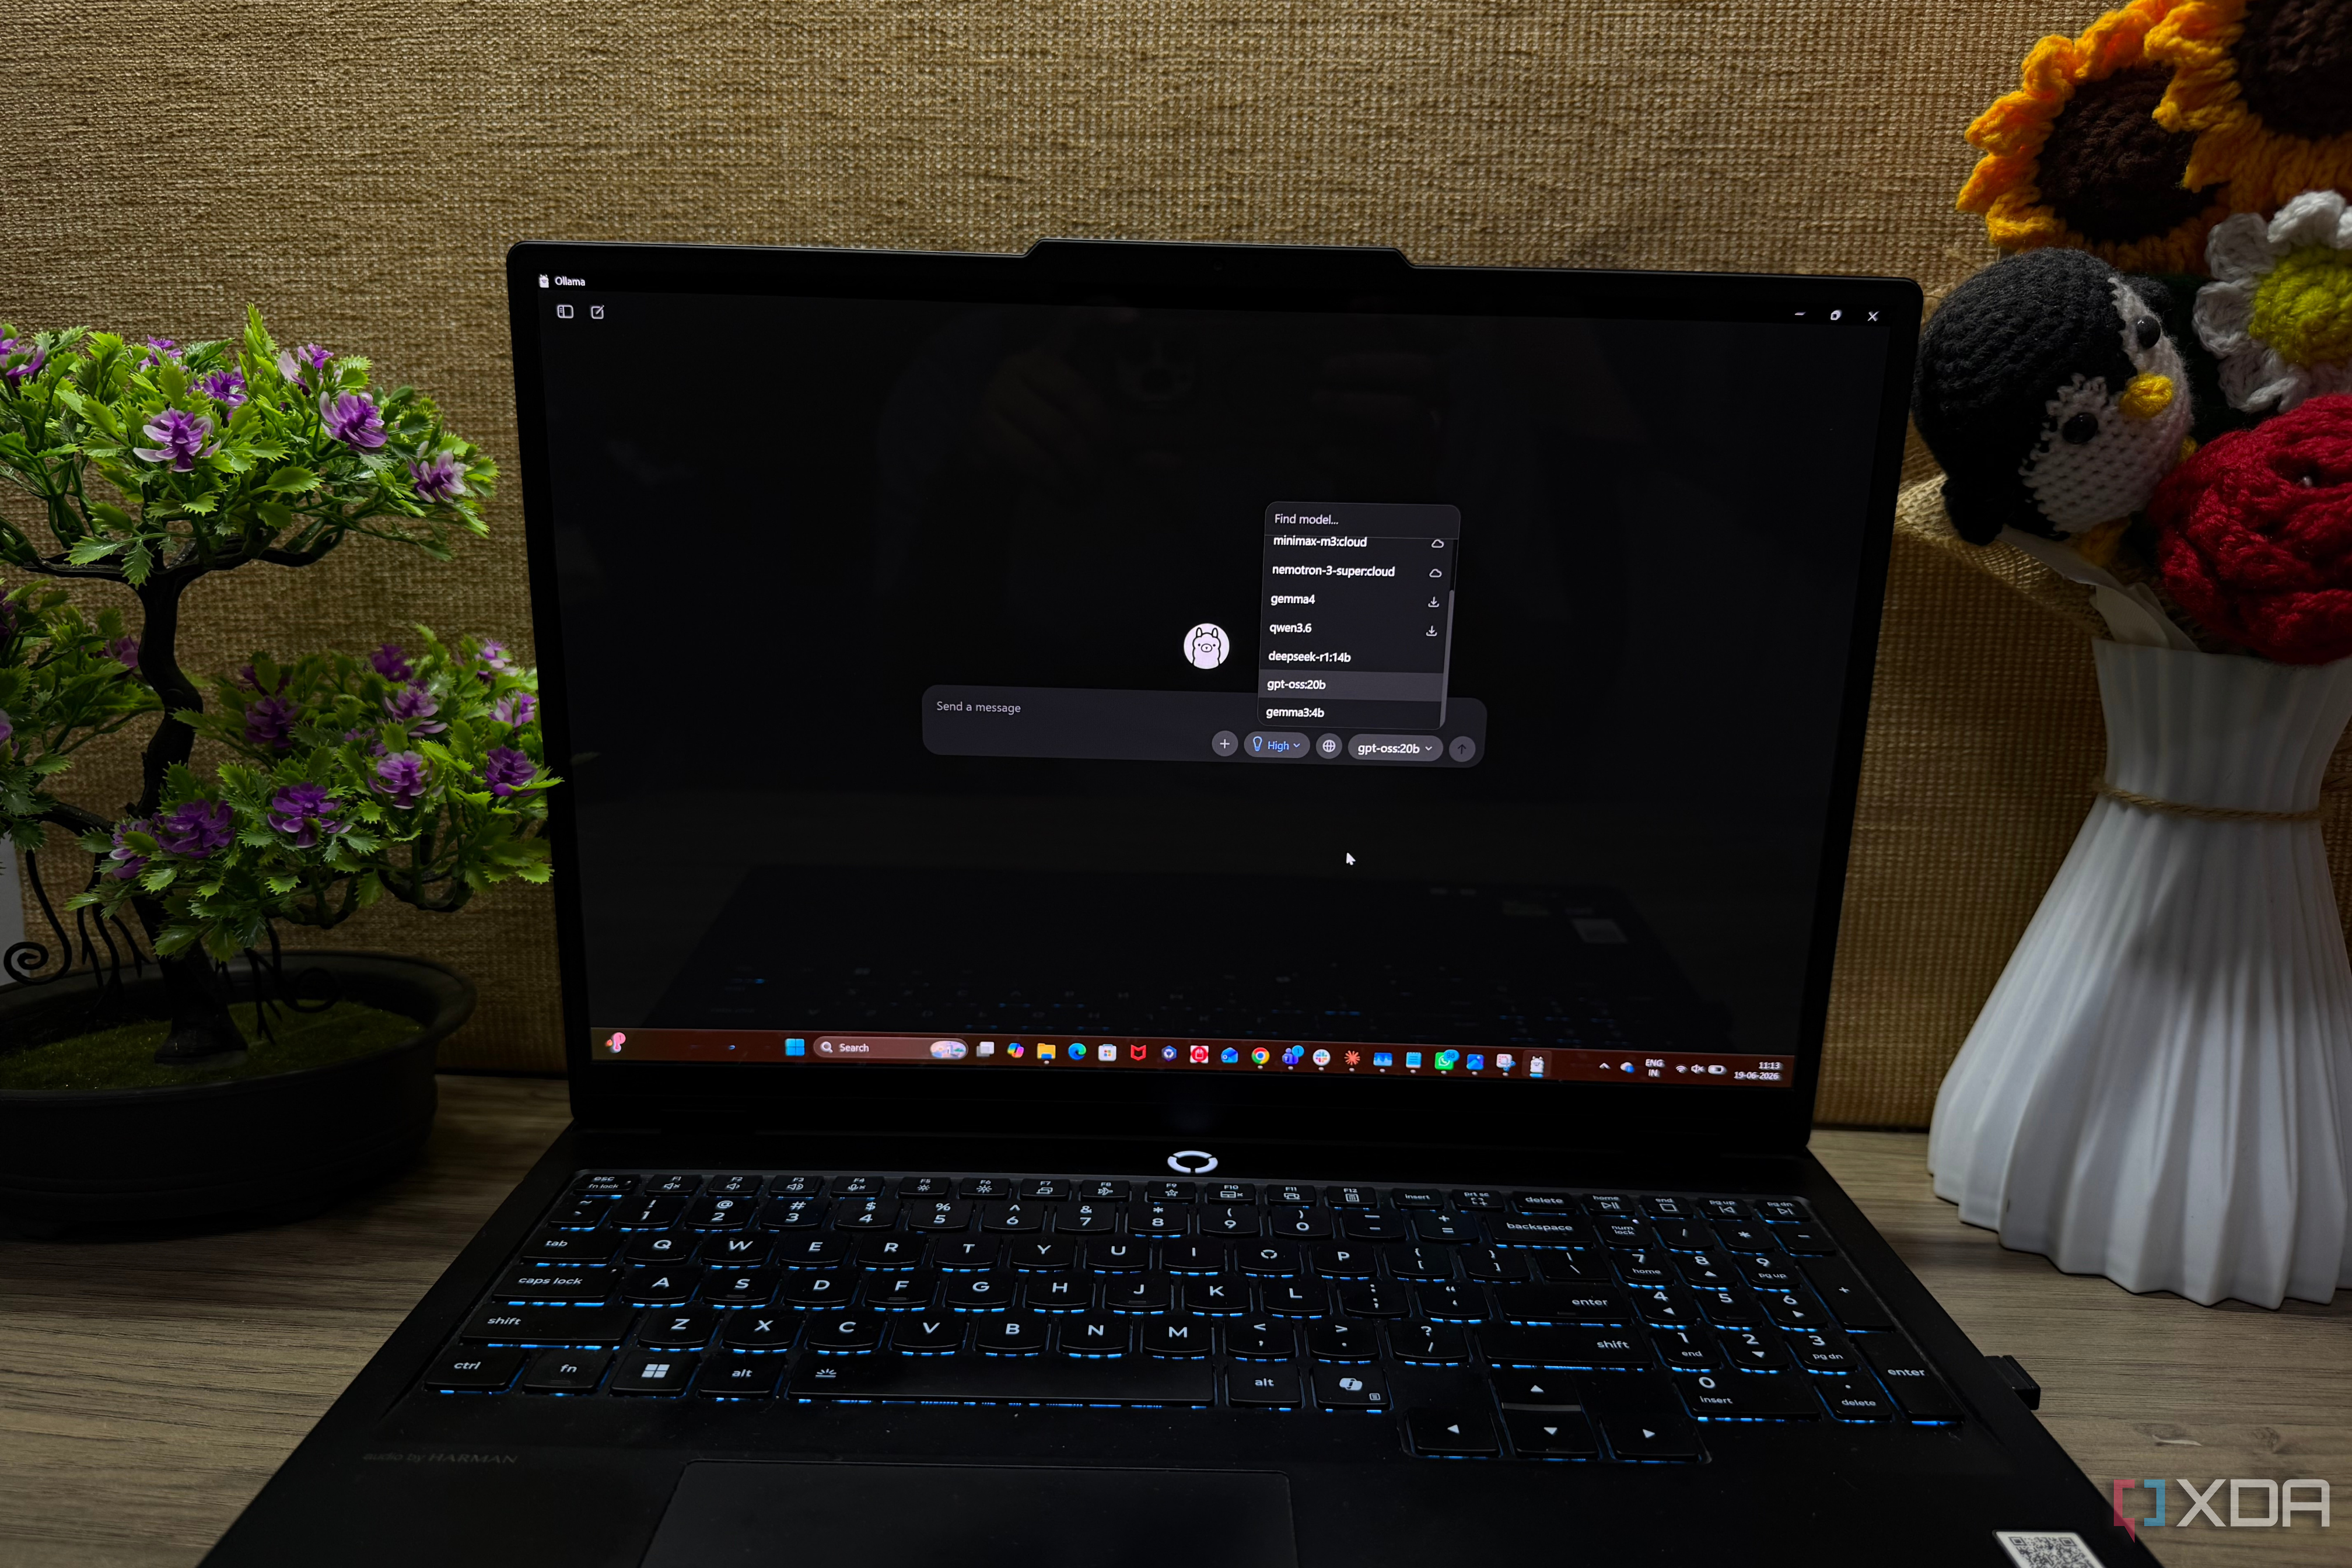
When I first started experimenting with local AI, Ollama made the whole process feel surprisingly simple. I didn't need to spend hours configuring an inference engine or figuring out how different components worked together. I installed Ollama, downloaded a model, and started chatting with it through the terminal. That's pretty much all it took to get my first local LLM running.
What I appreciate most about Ollama is how little I need to think about the setup. If I want to try another model, I can download it with a simple command and start using it almost immediately. There's no need to manually manage every part of the process before I can see what a model can do.
Ollama isn't limited to chatting through the terminal, either. It runs as a background service and exposes an API that other applications can use. This makes it easy to connect local models to different tools without building an entire AI setup from scratch.
I can experiment with different models, compare their responses, and find out which ones work best for my needs. Whether I'm testing a lightweight model for quick responses or trying something larger for more demanding tasks, Ollama gives me a straightforward way to get started.
That's why I still consider it an excellent entry point for anyone curious about running AI locally. It removes much of the initial complexity and lets me focus on exploring the possibilities instead of wrestling with configuration. For someone who simply wants to download a model and see what local AI can do, it's hard to beat that level of convenience.
After a certain period, Ollama started getting in my way
The hidden costs of keeping things simple

Ollama made running local AI easy, but I eventually started wondering whether I was getting the best performance from my hardware. Running the same model through different inference engines can produce different results, and Ollama's abstraction layer can add overhead compared with running llama.cpp directly. I didn't want to assume that switching would automatically make everything faster, but it made me curious about what I was missing.
The default context window was another issue. Ollama commonly uses a context length of 4,096 tokens unless configured otherwise. That's fine for basic conversations, but it can become restrictive when I'm analyzing lengthy documents or working with tools that need more context. The frustrating part is that this limit isn't always obvious when Ollama sits behind the front end. I had to pay closer attention to the server's configuration instead of assuming the model was using its full context capacity.
I also found that Ollama's model storage made switching inference engines less convenient than I expected. It stores model data in its own registry structure, using hashed filenames, rather than presenting every download as a standalone GGUF file. If I want to use a particular model with another runtime, I may need to locate or download the corresponding GGUF separately.
I replaced Ollama with llama.cpp
Fewer layers in between
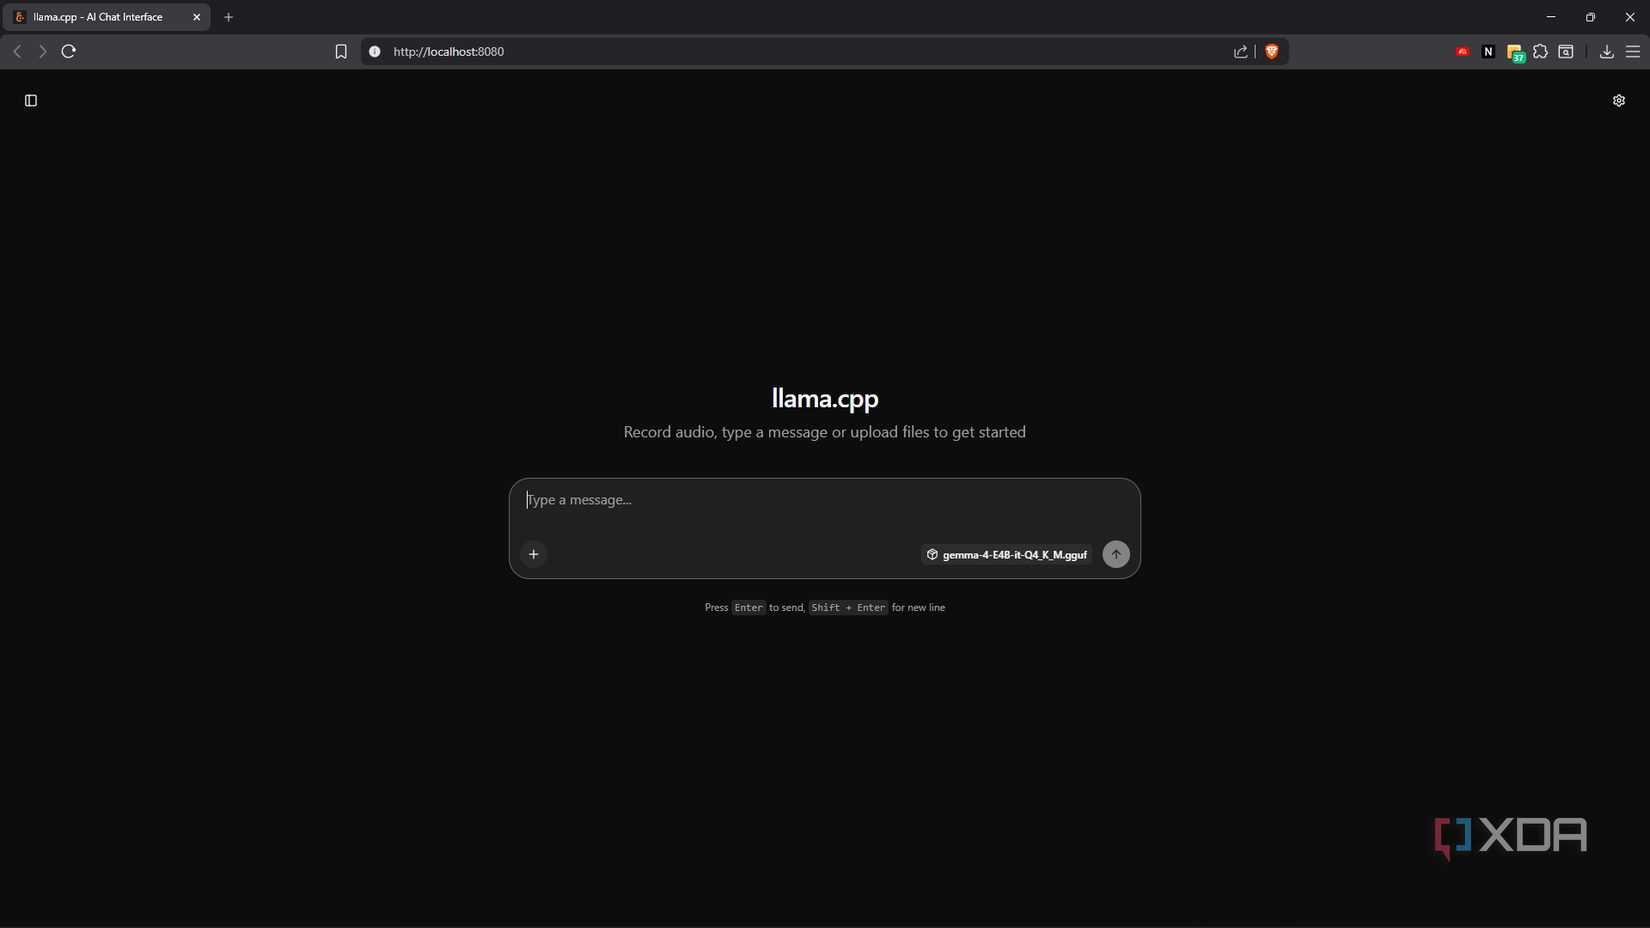
Switching to llama.cpp felt like the next step once I wanted more control over my local AI setup. The biggest difference is that I'm working closer to the inference engine instead of relying on a tool that manages most of the process for me.
I started using llama.cpp to run GGUF models directly, and its flexibility quickly stood out. I can adjust settings such as context size, GPU offloading, and sampling parameters to better suit each model and my hardware. It takes more effort to get everything configured, but I also have a clearer understanding of what's happening behind the scenes.
Another advantage is its built-in server, which provides an OpenAI-compatible API. That means I can connect compatible frontends and applications without rebuilding my entire workflow. I don't have to give up the convenience of using local AI tools just because I've changed the backend. llama.cpp isn't as beginner-friendly as Ollama, but the extra control makes it a better fit for how I use local AI today.
Start simple, switch when you're ready
Ollama still makes sense for anyone taking their first steps into local AI, and I wouldn't tell beginners to avoid it. But as my needs grow, I want tools that give me more control over how everything runs. That's why llama.cpp is my choice now. You don't have to start with the most advanced setup. Start with what works, learn along the way, and switch when your current tool starts holding you back.