
Abhinav pivoted from a career in banking to pursue his first love in writing. Even while working full-time, he continued contributing as an editor-at-large, a role he has held for more than 7 years. A lifelong tech enthusiast who has built three gaming and productivity powerhouse PCs since 2018, his passion for technology keeps him closely following the semiconductor industry, from NVIDIA and AMD to ARM. His MSc dissertation explored how artificial intelligence will reshape the future of work, reflecting his curiosity about the wider social impact of emerging technologies.
Ever since I started hosting local AI models, Ollama has been my default way to run them. For the longest time, it gave me absolutely no room to complain, and I'd wager for most beginners that would be the case. It's not lost on me that local AI inference does seem to have a pressing friction problem, and that a clean GUI like Ollama's doesn't make you work too hard and is therefore less likely to push you back to cloud alternatives by taking care of the problems for you.
So why else would the average user, much like myself, even bother to move to llama.cpp? Most would expect that my reason to leave Ollama would be the inference speed, but ever since Ollama started running models through llama.cpp in May, the gap has become nonexistent for the models I run. But when it comes to local AI, convenience itself is an important consideration. Here's why I decided to move to llama.cpp anyway.
The fastest model I run has larger weights than my VRAM
And yet, llama.cpp lets me run it at lightning-fast speed

Qwen3.6-35B-A3B is a 17.7GB model, which, by all standards of measure, is too big to fit neatly on the 16GB of GDDR6X on my RTX 4070 Ti Super. However, thanks to llama.cpp, it's still the fastest model I run on both runners. Since it's a mixture-of-experts model, out of the 35 billion parameters, only about 3 billion do any work for a given token. That means that some of its expert layers can be offloaded to system RAM without wrecking my generation speed, as long as the parts that run on every token stay resident on the GPU.
On the defaults, both runtimes did a decent job of placing it, but Ollama came out slightly ahead at 77.02 tokens per second and llama.cpp close behind at 74.75 at 32K context. However, because of my runtime, I had access to a neat little truck through llama.cpp's --n-cpu-moe flag, which allows me to set how many layers keep their experts in system RAM. I was also able to limit the server to one chat slot instead of the default four to hand the full context budget to a single slot, freeing up VRAM for more of the model to sit on the GPU.
With eight layers' experts in RAM, the same model on the same GPU hit 81.43 tokens per second. It's worth noting that Ollama has no equivalent to this. The feature request for this has been open since August 2025, though.
|
Qwen3.6-35B-A3B, 32K context |
Generation speed |
|---|---|
|
Ollama (default) |
77.02 t/s |
|
Llama.cpp (default) |
74.75 t/s |
|
llama.cpp (tuned --n-cpu-moe 8) |
81.43 t/s |
Llama.cpp makes it easier to know my models better
llama-bench makes it easier to find the right settings

One of the key challenges in nailing your local AI stack's configuration is finding what settings work best for your bench. Users have a fair share of variance when it comes to their unique setup, so the settings you find online that offer you the "maximum tokens per second" and the highest quality of generation may not agree with your setup as well as they do with the reviewer's. The most reliable way to really know is to measure your own numbers.
An issue that I frequently run into is the cache warm-up problem. In a recent test wherein I was testing Gemma 4 12B, Ollama printed 44.98 tokens per second, and I almost logged it. In the next run, however, with the same prompt, the speed hit 61.76 tokens per second.
A 37% swing with the same settings is what I observed, and that was because the first run was still loading weights into VRAM. An average user with a bigger model would conclude the model runs abysmally and drag the model file straight into the recycle bin on the basis of this wrong assumption. Llama.cpp has a built-in fix to this problem, which is llama-bench. It measures prompt processing and generation separately, repeats each test five times, and reports the average for you.
I keep my models wherever I want them with llama.cpp
Fewer imports, workarounds, and of course, fewer headaches
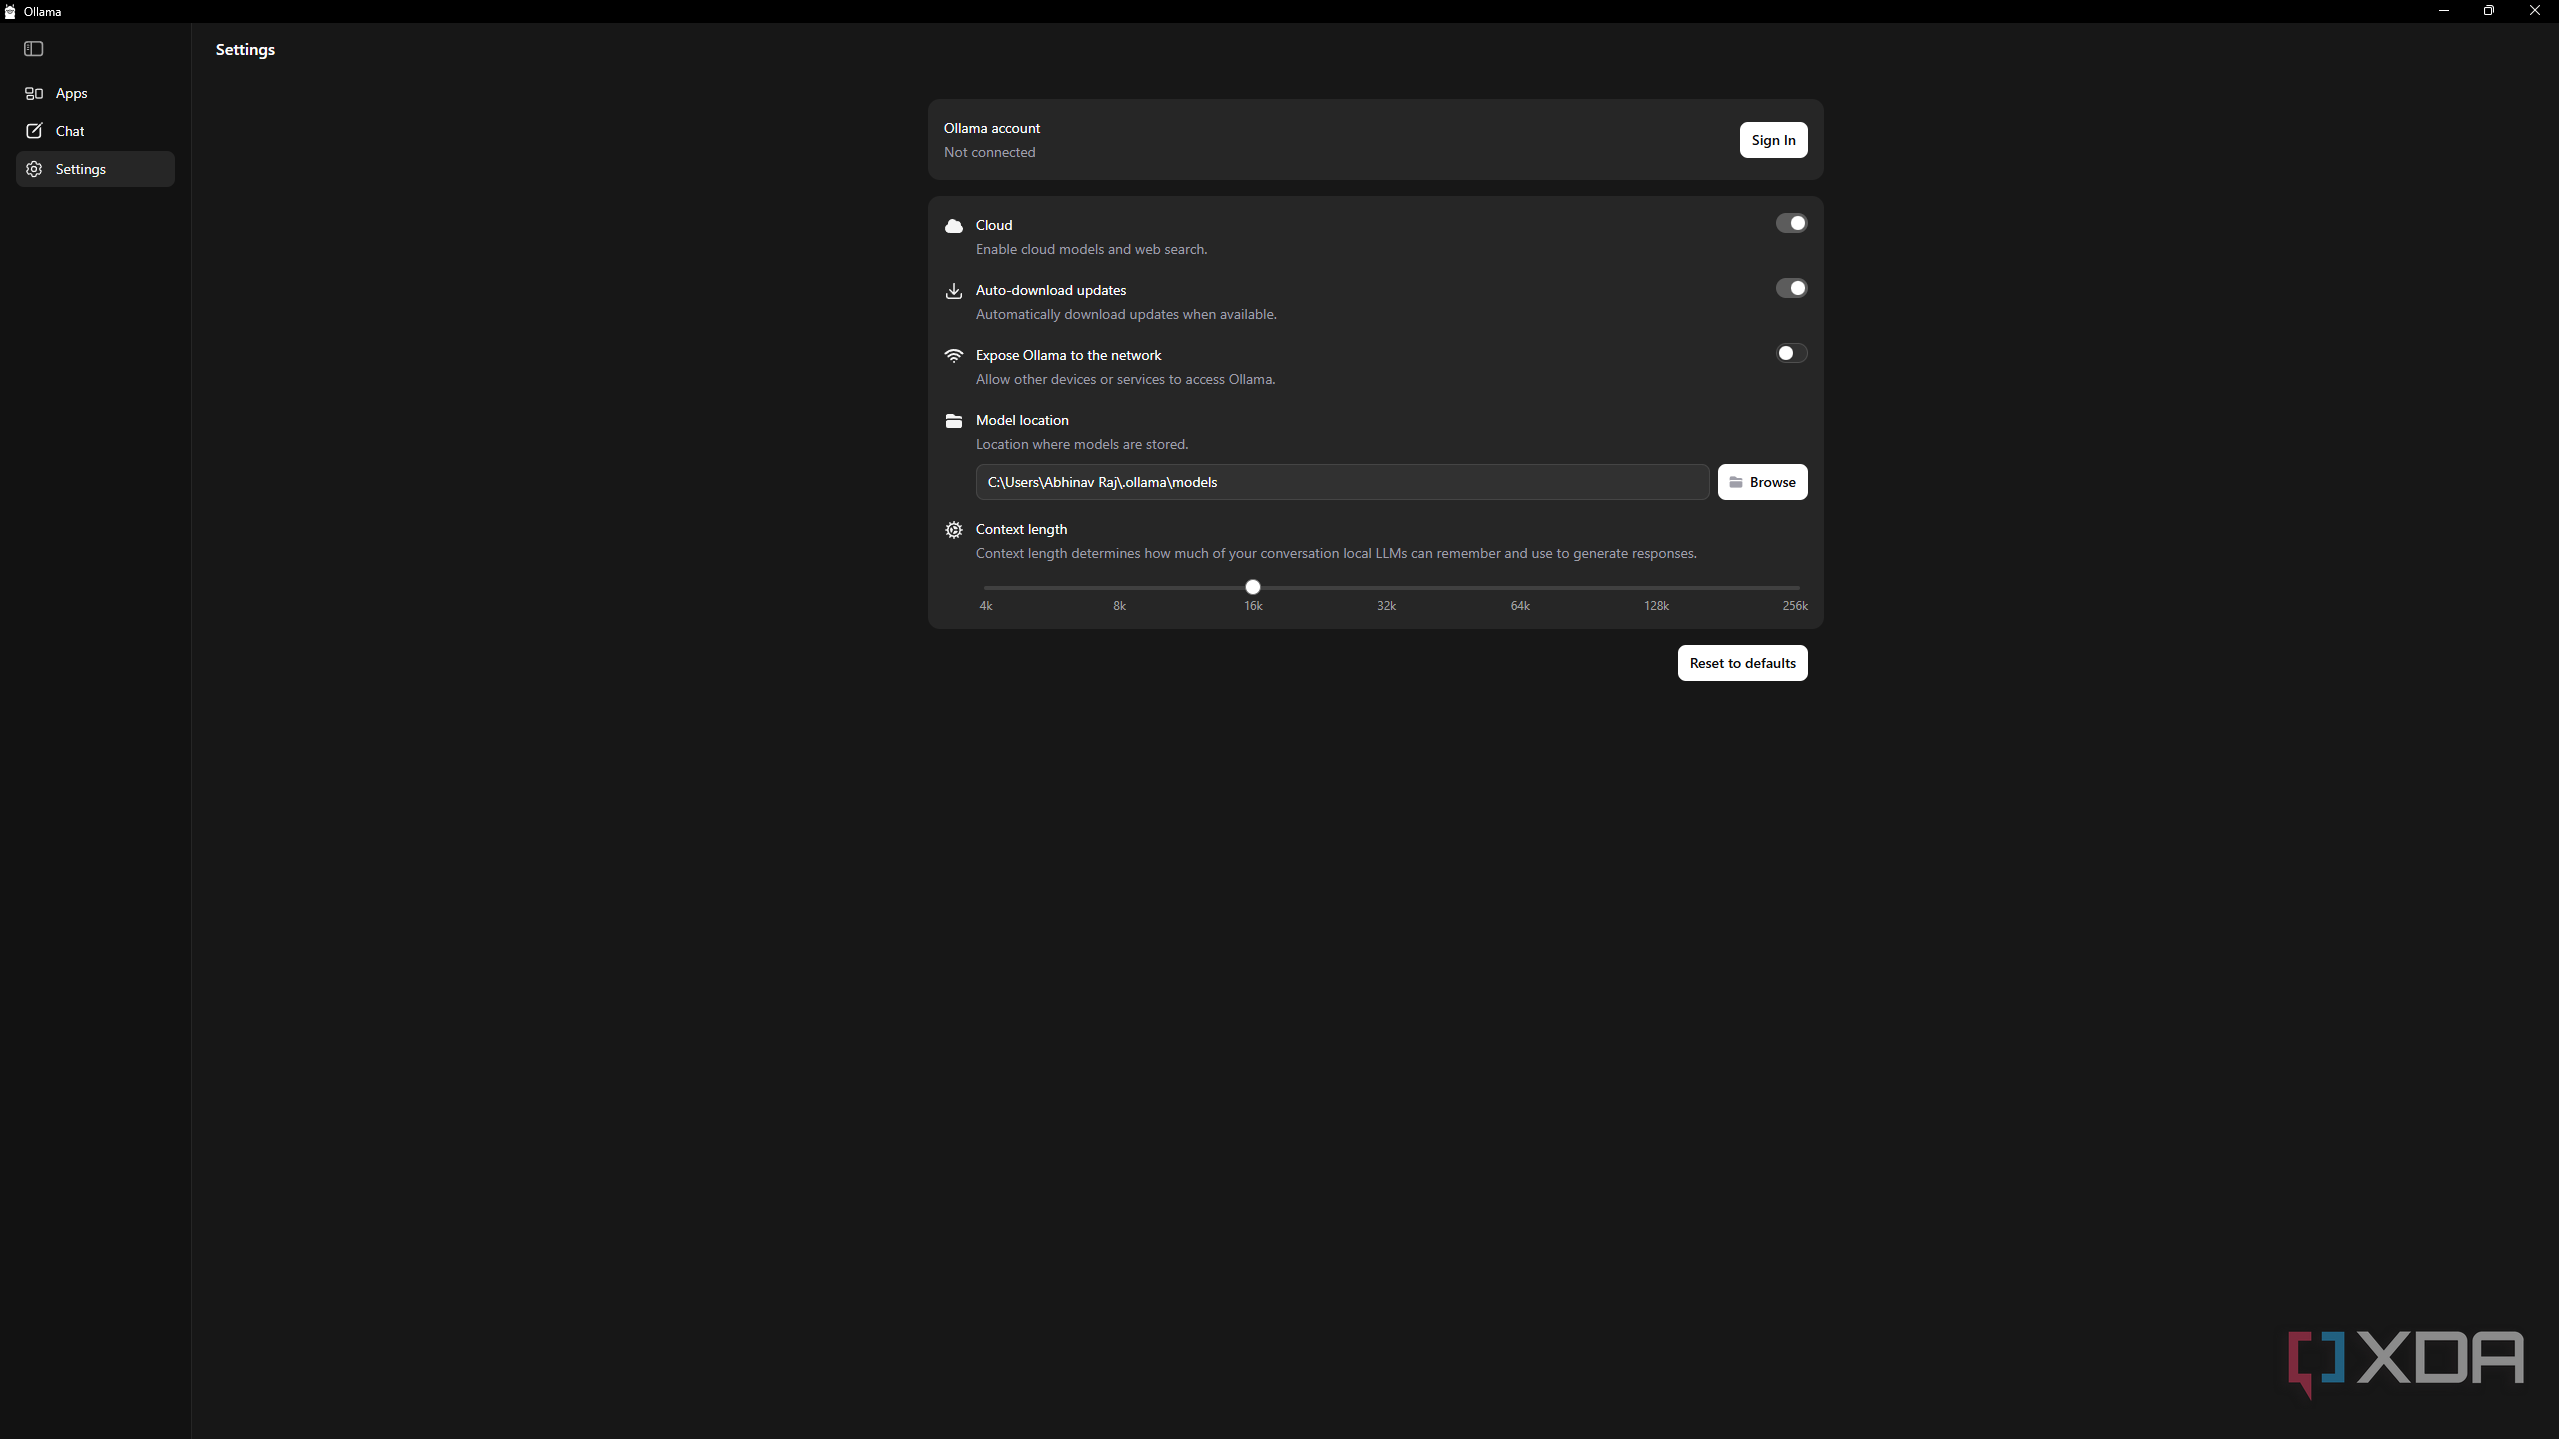
A beautiful aspect of llama.cpp is the fact that the runtime does not care about where a model is on my drive. I can point llama-server at a GGUF that can be anywhere on my PC, and it takes just as many clicks to get to the chat interface. On the other hand, Ollama needs a Modelfile and an ollama create step, which copies the whole model into its own folder.
This is going to read like a minor gripe to many, but when you're frequently shuffling models and downloading multiple at a time, you can have tens of gigabytes worth of duplicates that, after the testing concludes, I have to clean by hand. For context, for about 3 models, that leaves about 41GB of duplicates on the drive.
The import process also tends to trip new users up. Personally, I ran into an "invalid model name" error and an "unexpected EOF" error because an old Modelfile picked up files I didn't ask it to. Not that any of it was particularly impossible to work around, but every workaround is a step the other open-source alternative doesn't ask for.
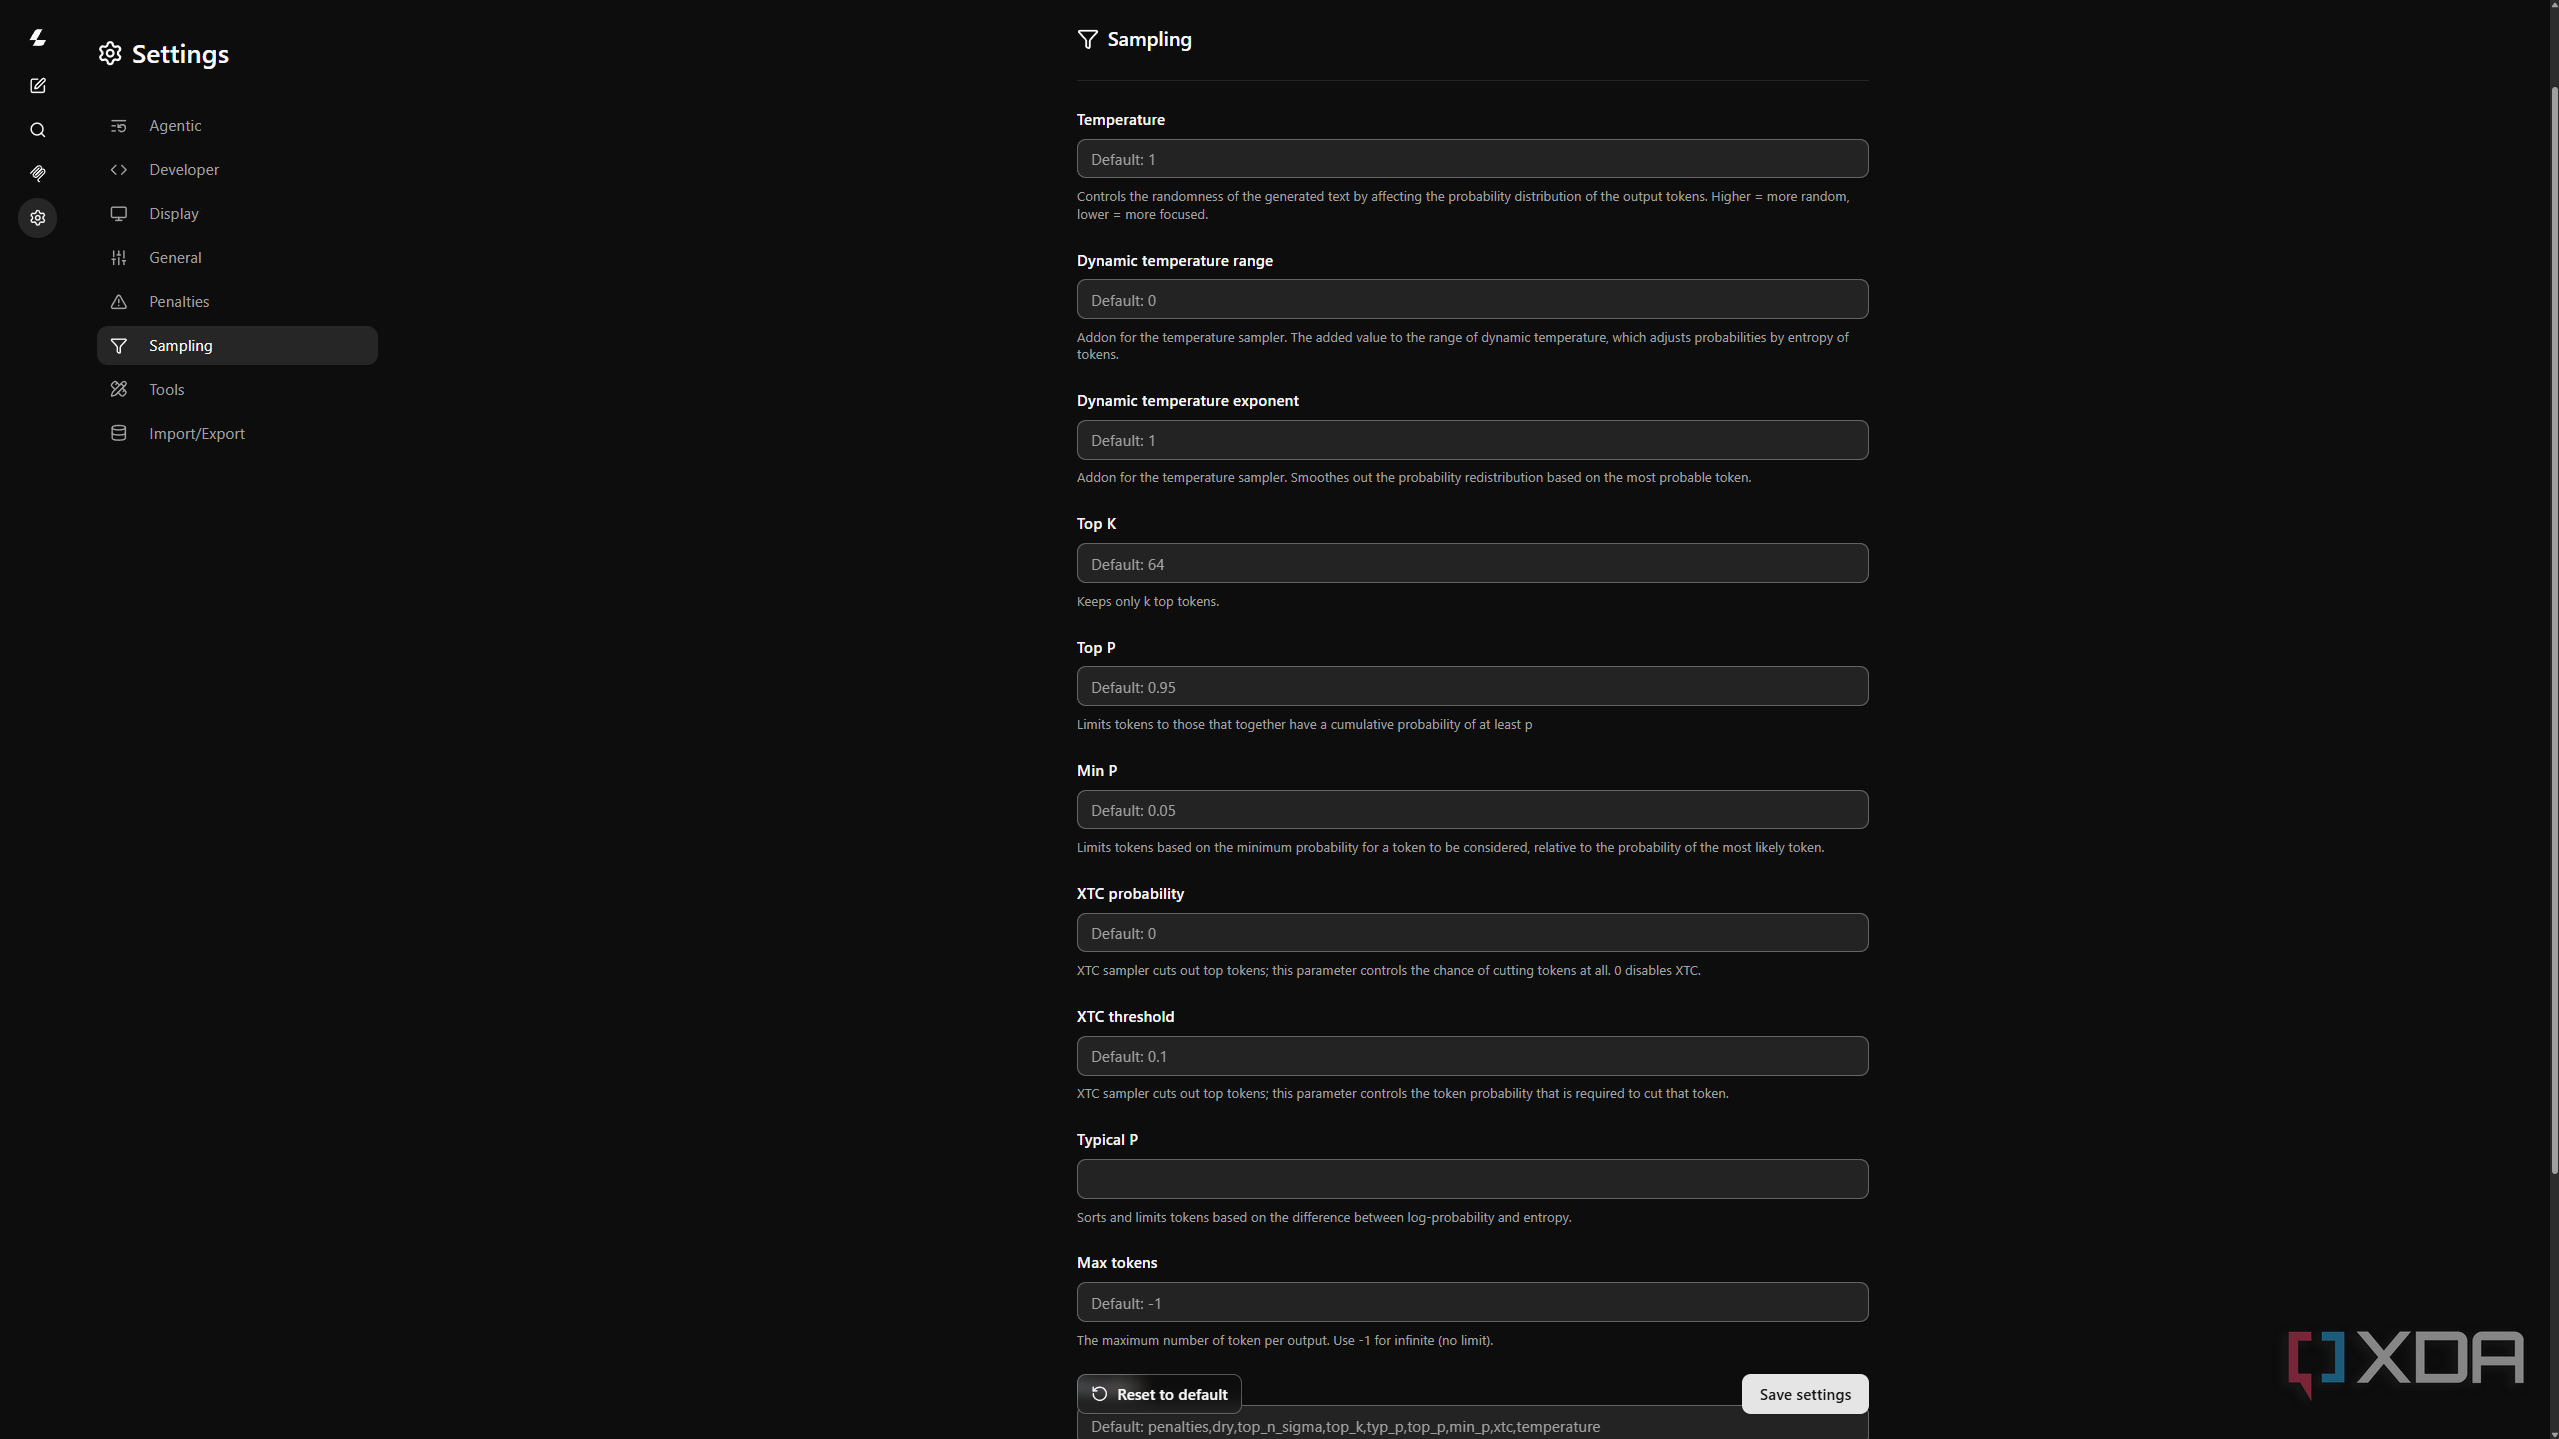
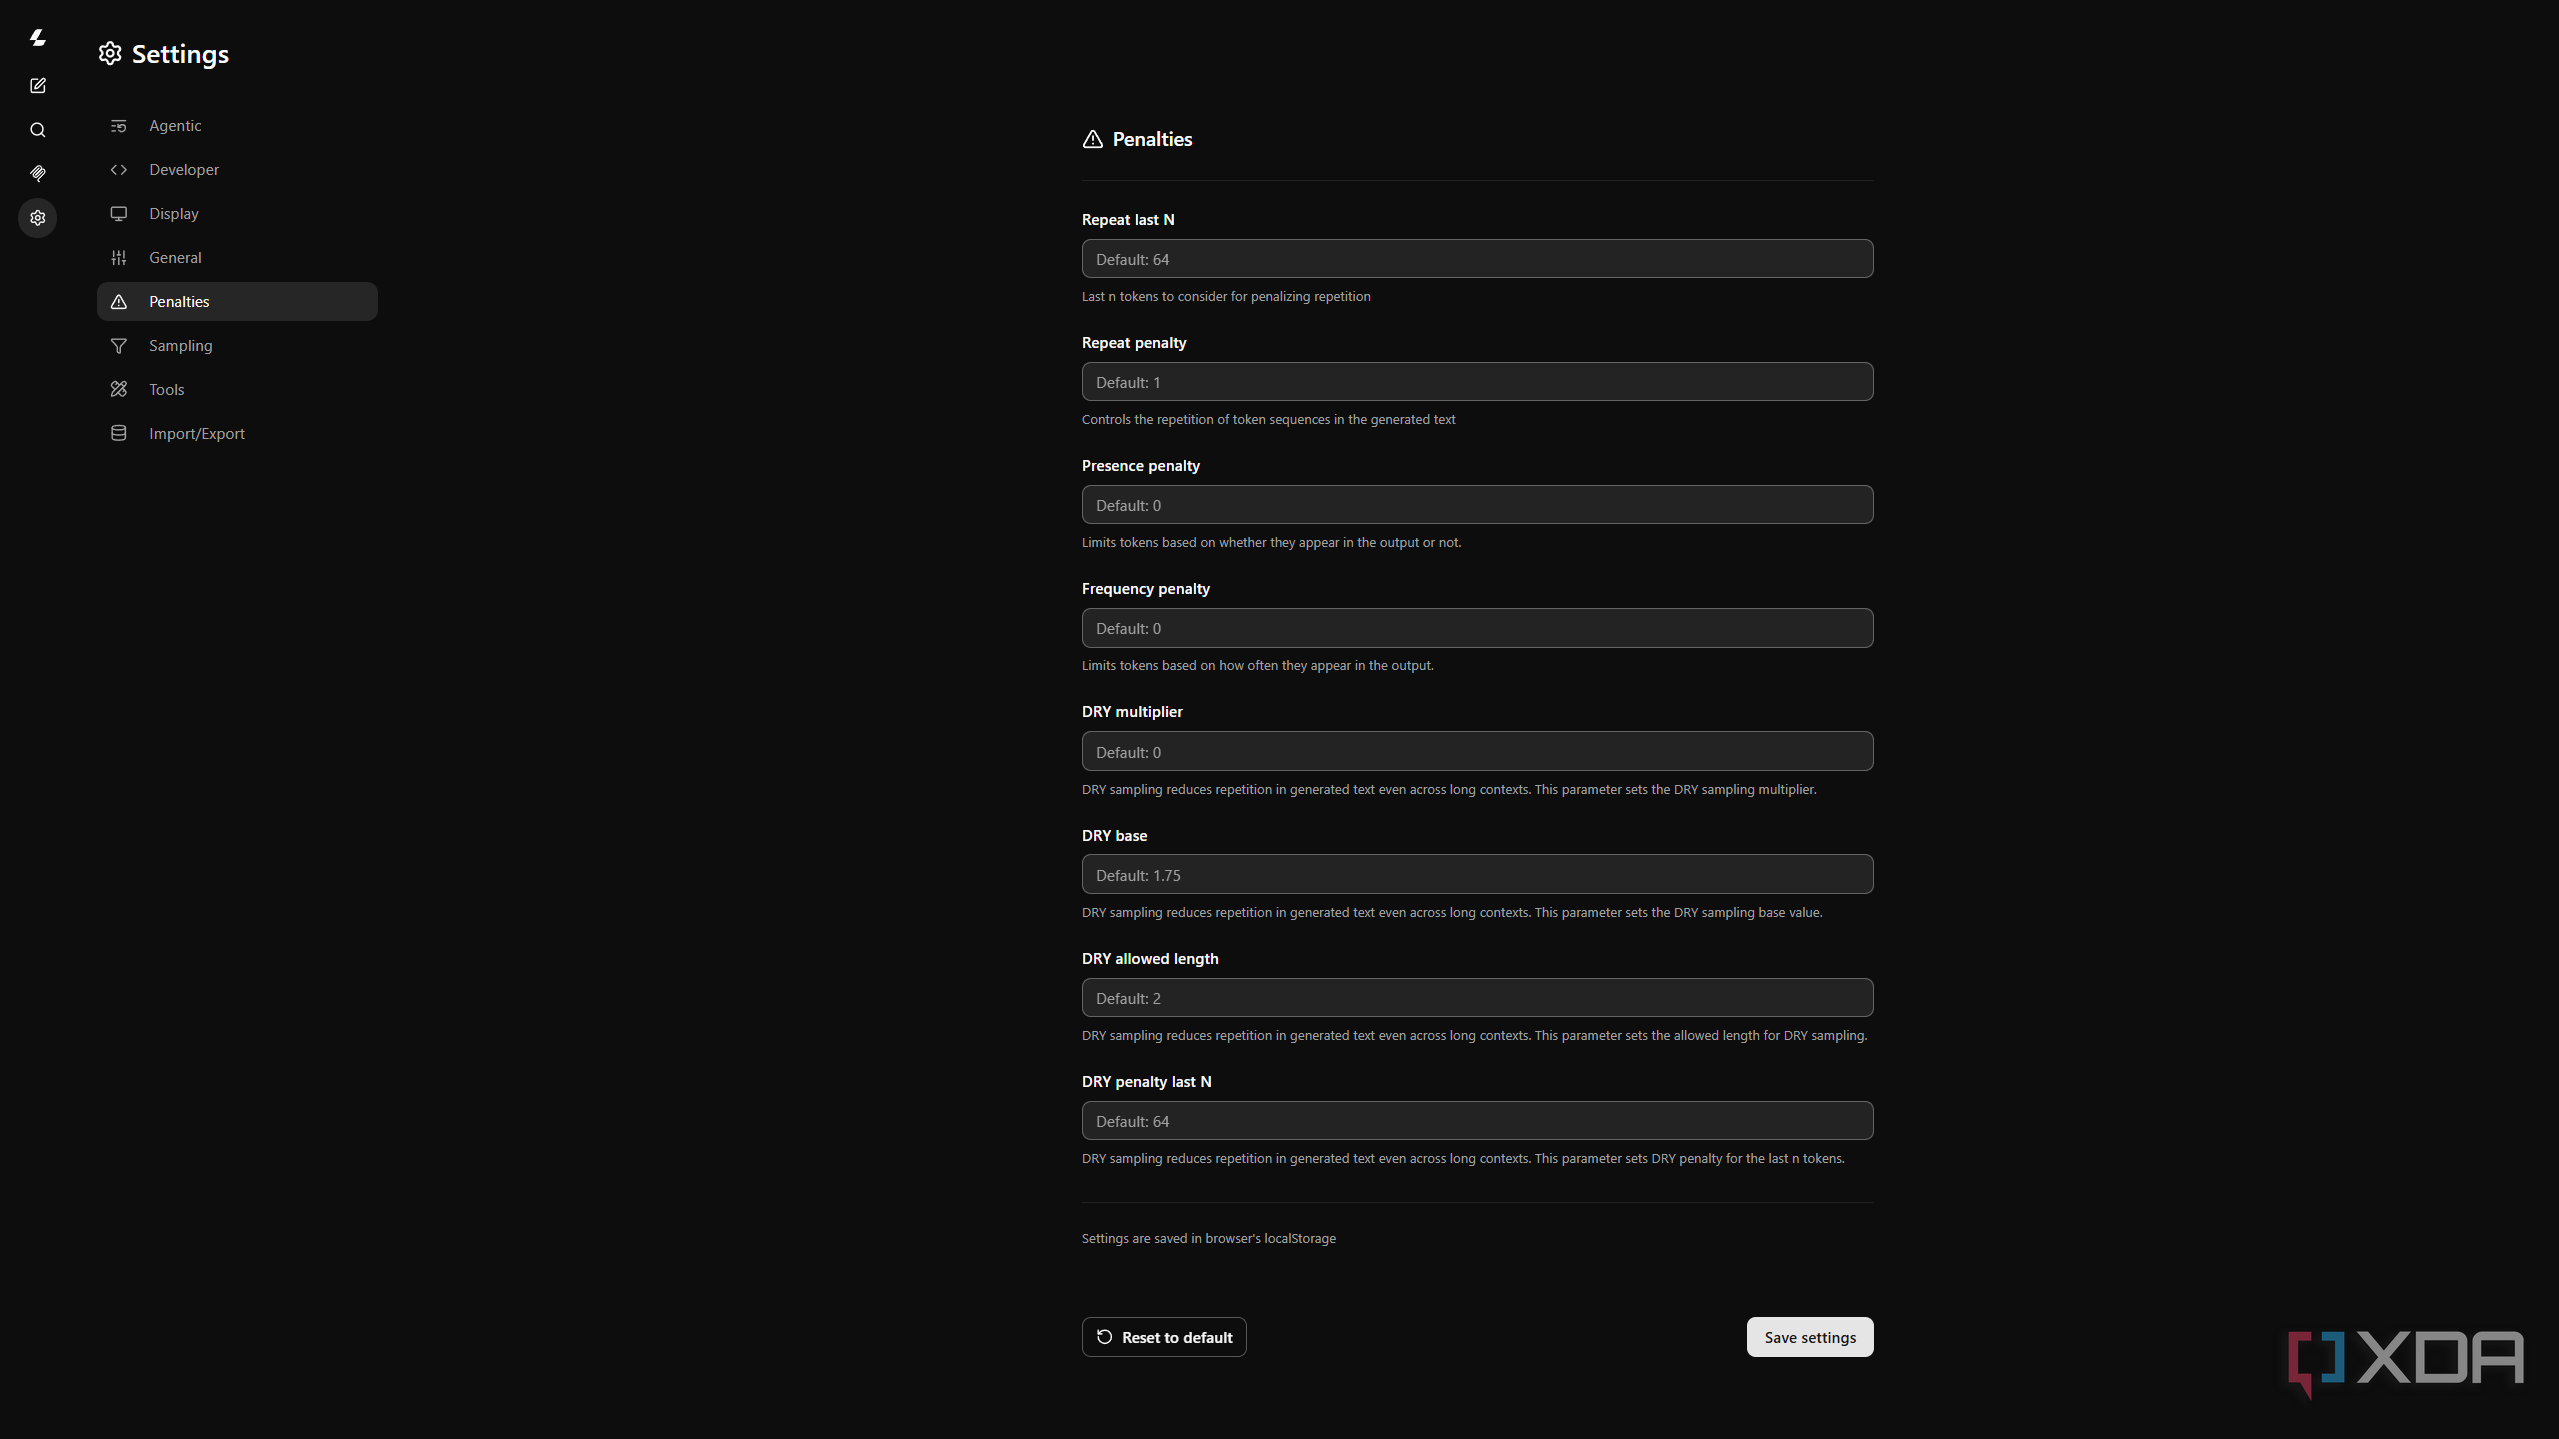
Then, there's some small stuff. Changing values like top_k or top_p in Ollama requires a Modelfile edit, an interactive CLI command or an API request, depending on how you're running the model. Llama.cpp's WebUI puts it one click away in the settings menu, which is mighty convenient for someone whose workflow revolves around changing those values a dozen times a day.
A better runtime than Ollama has been in town for a long time now
I understand the appeal of Ollama entirely. It's essentially a download-and-chat experience that many first-time users and those trying to save up on cloud subscriptions are looking for, and for those users, it's excellent. I'd even argue that it has made local AI inference accessible to those who would otherwise never venture into this territory. At the same time, once those very users get accustomed to llama.cpp and start tinkering with more models on Hugging Face, I'm willing to bet a small fortune that they'd not want to go back.
llama.cpp
Llama.cpp is an open-source framework that runs large language models locally on your computer.