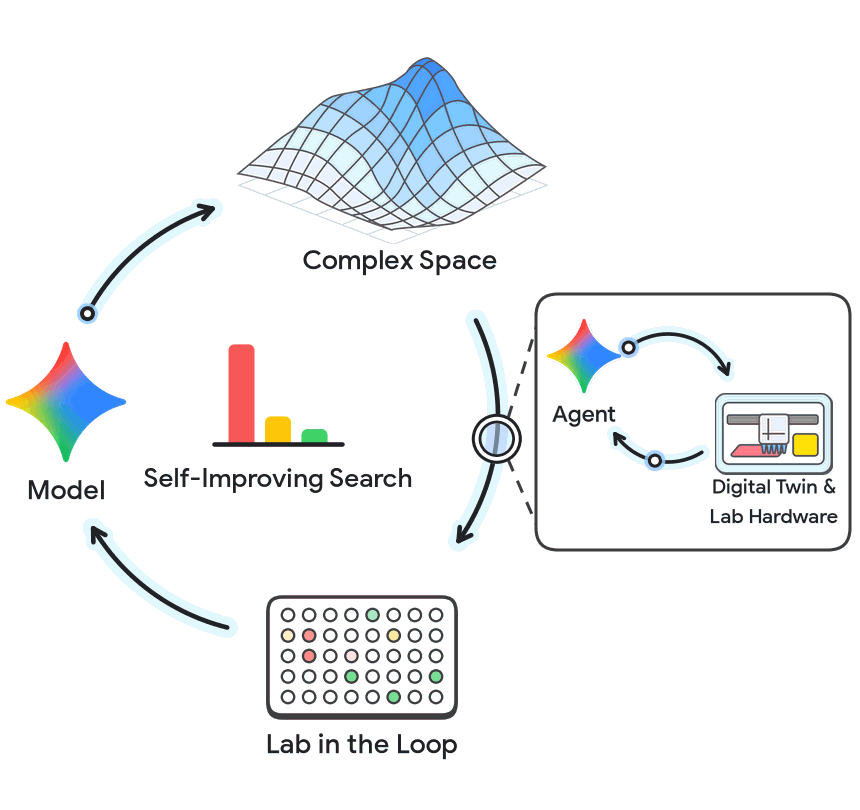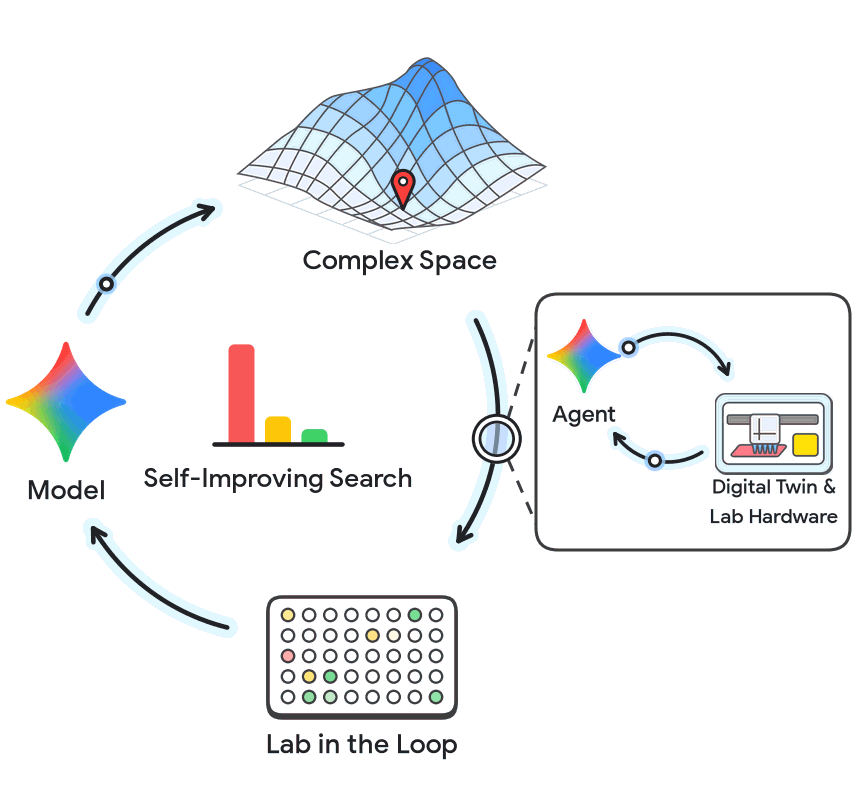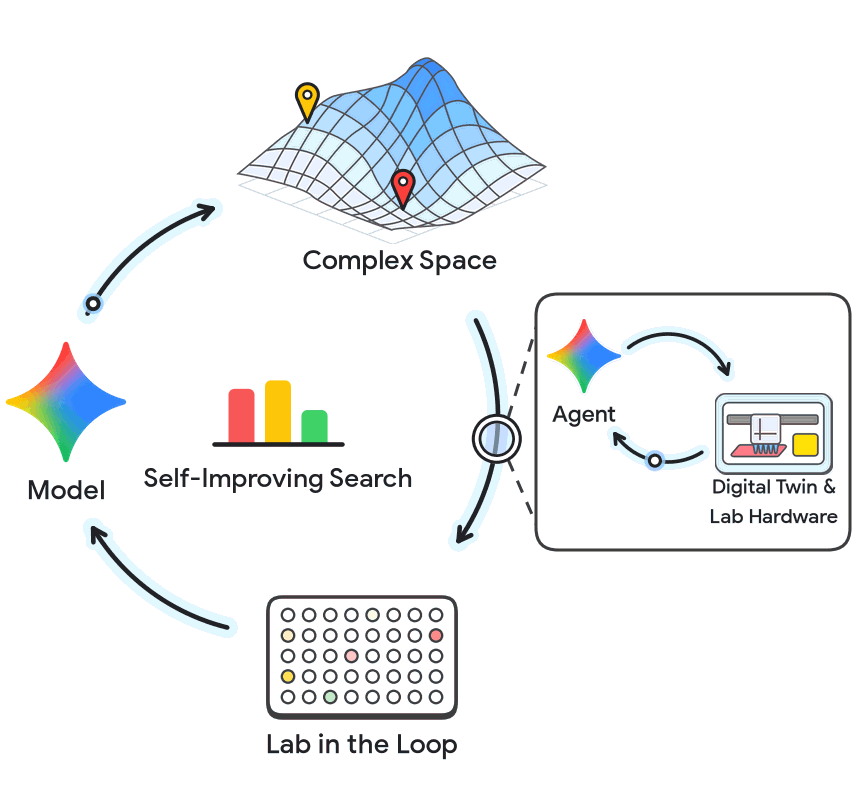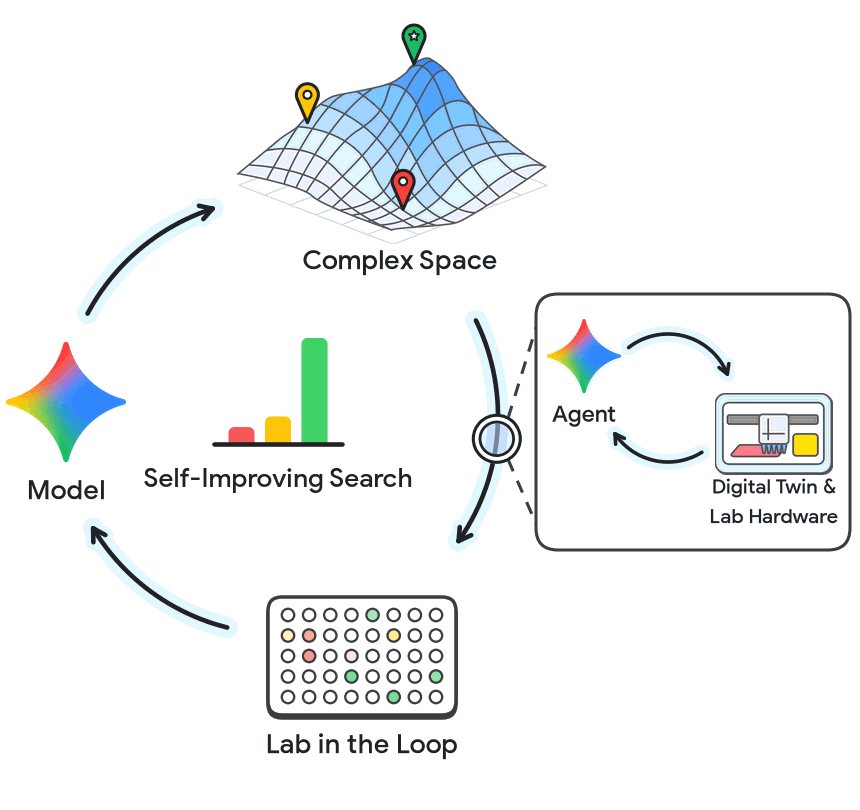
Frontier AI systems have the potential to transform biology research and drug discovery by intelligently navigating vast combinatorial search spaces (e.g., a single 100-amino-acid protein spans at least 20100 possible sequences) calling for dynamic multi-candidate exploration. Our long-term research vision is that AI agents will not only ideate and analyze, but also run lab experiments to test their hypotheses, learn from the results, and self-improve to solve complex problems — all driven by human scientific agency.
Realizing this vision requires solving two intertwined challenges: First, frontier models still do not reason reliably about 3-dimensional geometry and physical state — which poses a problem in the automation of the specialized liquid-handling robots that move reagents, track volumes, and execute molecular biology protocols in a wet lab. Second, while agentic hypothesis generation and in-silico design are advancing rapidly, needing repeated cycles of real-world feedback to validate the proposals and navigate vast search spaces, real-world wet-lab experiments have not kept pace, making experimental readouts more of a bottleneck than ever.
In this post we share three research projects highlighting our progress on bridging the gap between in-silico AI exploration and real-world wet-lab experimentation:
- Enabling AI agents to perform safe, resource efficient experimentation grounded in physical measurements by using the VERID framework.
- Demonstrating closed-loop agentic scientific discoveries on our prototypes for aptamer and de-novo protein design.
Grounding agents in physical reality
First, we present the VERified Infrastructure for Discovery Laboratories (VERID) framework to bridge the gap between the high-level reasoning of AI agents and the complex, error-prone physical reality of a wet lab. It is a semantic digital twin of the laboratory workcell, i.e., a live, stateful 3D volumetric entity tree that tracks everything from robotic arm geometry to individual well volumes, reagent identities, and pipette tip inventory.
The safety of a command depends on the live physical context as well as the code. An agent can generate syntactically valid code that is physically impossible (e.g., lowering an 8-channel pipette into a narrow trough that is too short), logistically invalid (e.g., aspirating from a depleted well), or scientifically compromised by unmodeled fluidic effects.
Built on top of the open-source PyLabRobot framework, VERID provides four core capabilities:
- Live 3D state tracking: Allow agents to check deck layout, well volumes, and available tips before acting.
- Fast virtual dry runs: Simulate protocols in seconds to catch collisions or empty wells before touching reagents.
- Hardware safety checks: Block invalid commands before they reach the robot.
- Synchronized video and action logs: Capture a complete record of every run for research rigor, reproducibility, and debugging.
In our report, we show these capabilities in action through case studies. First, synchronized video and execution traces caught uneven dye stratification caused by dispensing too close to the well floor, allowing the agent to refine its mixing strategy. In the same campaign, the persistent digital twin state allowed the agent to recover mid-run from a plate-reader failure without re-pipetting. Second, when the simulator rejected an 8-channel aspiration that physically wouldn't fit in a narrow trough, the agent replanned on the fly and designed a targeted factorial diagnostic isolating a subtle bias caused by residual tip-wall carryover that replication alone would have missed. Finally, in a closed-loop self-play campaign, an agent iteratively designed and ran robot experiments to reconstruct blinded dye mixtures from overhead camera images, identifying its own optical and fluidic artifacts across runs to improve accuracy more than fivefold.
Reproducible execution and full trace logs — capturing procedural variables like dwell times, evaporation, and plate layout — lay the groundwork for agents to eventually be able to separate biological signals from experimental noise as they explore and refine many candidates in parallel across rounds.
Learning to learn with aptamers
Agents need real experimental readouts to refine their hypotheses as computational models do not capture the full picture of what happens in a wet-lab reaction and cannot replace empirical validation. In “Aptamers as a sandbox for lab-in-the-loop agentic molecular discovery”, we use protein-binding DNA aptamers to prototype the lab in a closed loop with AI agents over 3 design-test-iteration cycles. Aptamer discovery is a type of experiment common in research efforts for clinical biomarker discovery. A complete aptamer design-test-analyze cycle takes just 7–10 days, as DNA can be chemically synthesized in pooled libraries and read out directly by sequencing. In each round, agents design candidate sequences, which are screened against target proteins on magnetic beads to isolate functional binders, and then sequenced to return rich quantitative data for the next cycle.
Across three rounds on two protein targets with varying difficulty levels (myoglobin and α-thrombin), AI-driven rational and de novo design raised confirmed on-target hit rates as can be seen in the image below (to 33.5% and 42.1% for myoglobin and α-thrombin, respectively), though each target required identifying and overcoming a different wet-lab failure mode.
On α-thrombin, Round 1 yielded 0% binders because fixed primer overhangs disrupted folding in 48% of sequences; once the agents introduced clamped flanking stems in Round 2 and diversified in Round 3, hit rates climbed to 26.0% and then 42.1% at 98.5% specificity.
On myoglobin, as agents prioritized raw binding affinity in Round 2, they heavily enriched G-quadruplex motifs (63% of designs). While raw pull-down increased, the wet-lab data showed that most of these G-quadruplexes were non-specific "sticky" binders adhering to off-target proteins and bare magnetic beads, causing both target specificity (from 75.0% to 19.1%) and true, bead-corrected hit rate (from 10.2% to 3.7%) to plunge. Recognizing this artifact from the Round 2 readout, the agents autonomously revised their design rules for Round 3, capping promiscuous motifs, subtracting bead binders, and pivoting to non-G4 structural scaffolds to recover specificity (72.4%) and surge ninefold in on-target hit rate (33.5%).
In the paper, we also examine how agents reason like scientists, analyzing data and suggesting tweaks to wet-lab protocols, but also sometimes think atypically, exploring sequence spaces that structural biologists might not.
Accelerating de novo protein binder design
Closing the loop for proteins is more complex. Unlike aptamers, which are chemically synthesized, proteins must be expressed biologically, so each loop adds cellular or cell-free selection, expression, and folding steps. Together with a larger sequence space, this creates bottlenecks on both the computational and wet-lab sides.
In “Agent-guided epitope excision enables economical de novo binder design”, we applied our workflow to fibroblast activation protein alpha (FAP), a large, challenging receptor overexpressed in solid tumors. In just a few experimental runs, the top designs yielded binders with single-digit nanomolar affinity, a level of tight, drug-like binding typically achieved only after extensive rounds of laboratory optimization.
Computationally, de novo binder design requires generating candidate backbones, designing sequences to fit them, and re-folding the resulting complexes to predict binding. That final re-folding step consumes the vast majority of GPU compute, as it scales quadratically with target length. By surgically excising just the local binding pocket during folding, our pipeline accelerated each cycle more than eightfold without losing structural accuracy. This turns decisions about where to bind and how much surrounding structure to include into tactical levers that LLM agents are well-suited to optimize.
In a head-to-head comparison at equal compute, human–agent collaboration, where a scientist sets the high-level strategy and an agent drives tactical execution, nearly doubled the in-silico hit rate of a scientist working alone while uncovering hits across a much broader range of target sites. To scale wet-lab screening alongside our computational pipeline, we operationalized yeast surface display with fluorescence-activated cell sorting (FACS), a workflow that allows us to screen large libraries of engineered protein variants in parallel by fluorescence.
Our next step is to weave these threads together, combining VERID’s fully traceable automation with closed-loop learning for protein discovery to enable agents to directly navigate complex, rugged biological search spaces in the wet lab.
Safety
In line with Google’s Frontier Safety Framework and our approach to bioresilience, we build safeguards across both the computational and wet-lab sides of our workflows:
- Safe testbeds and screening: We deliberately selected well-controlled, non-infectious biological systems without gain-of-function risk, as testbeds to evaluate agent behavior and catch drift early. Every designed sequence goes through biosecurity screening.
- Simulation before execution: Through VERID, agents never send unverified code directly to the liquid handling robots. Every protocol is dry-run in simulation and validated against the digital twin before touching reagents.
- Human oversight: Humans directly authorize and review designed sequences, verify wet-lab protocols, and supervise robot runs.
As AI agents take on more of the design-test cycle, new safety and reliability challenges emerge. Moving toward an autonomous wet lab requires solving these open problems with opportunities for human agency and oversight: ensuring agents optimize for true target binding rather than unintended experimental shortcuts, verifying multi-step wet-lab protocols, and continuously monitoring agent reasoning and execution traces.
From grounding agents in physical lab robotics, to running fast closed-loop aptamer cycles where agents learn to explore sequence space, to discovering single-digit nanomolar protein binders, these efforts form the building blocks for human-directed autonomous discovery in the life sciences. We're excited by this progress and look forward to sharing what comes next.
Acknowledgements
This research is led by Annalisa Pawlosky, alongside Pooja Rao and Petar Sirkovic. We would like to thank our co-authors and collaborators across the foundational papers supporting this work: Zach Cutts, John Coller, Rachel Chen, Mathias Bellaiche, Hua Tang, Ryder Easterlin, and Dina Zverinski (aptamer discovery); Jun Kim, Artiom Myaskovsky, Oscar Donosa, Jamie Rogers, and Lawrence Chan (protein design); and Yves Delley, John Coller, Zach Cutts, Alexander Daryin, Mathias Bellaiche, Jun Kim, Oscar Donosa, Srinidhi Seshadri, Tanner Clary, and Sandy Klemm, with additional technical and experimental contributions from Xinyi Deng, Sanath Ramachandran and Jiawu Bi (VERID automation).
We are deeply grateful to Reuven Sayag, Avinatan Hassidim, Ronit Levavi Morad, Yossi Matias, and James Manyika for their leadership guidance and to Matthias Heiler, Burak Gokturk, Bill Jia and Pushmeet Kohli for their support throughout this research. We also thank Shekoofeh Azizi, Andrew Carroll, Philip Q. Nelson, Yishay Mansour, Dan Popovici, and Riccardo Pisoni for their reviews and insightful feedback, Amanie Brik for overall contributions to the effort, and Udi Graff for visual design and graphics for this post.