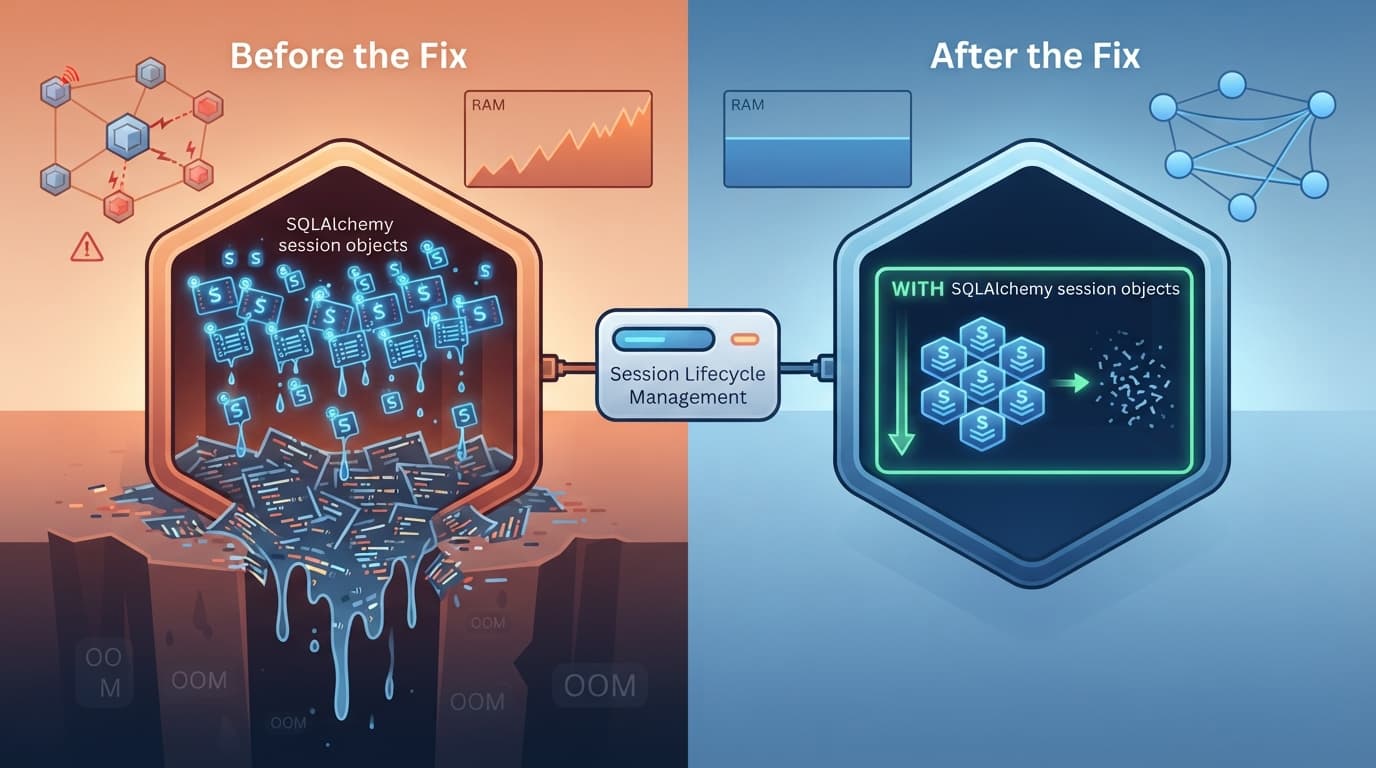
For months, our secondary telemetry and notification microservice lived on a clock. Every 48 hours, like clockwork, Kubernetes would mercilessly terminate the pod with an OOMKilled (Out Of Memory) exit code.
At first, we treated it as a background tax of running high-throughput asynchronous Python applications. We simply scaled up the container memory limit from 512MB to 1GB, then to 2GB. Predictably, the crash cycle just stretched from 48 hours to 96 hours. The memory wasn't fluctuating based on load; it was climbing in a slow, relentless, linear line straight off a cliff.
If you’ve ever chased a phantom memory leak in a microservice architecture, you know how frustrating it is. Here is how we tracked down the culprit, hidden deep inside our ORM session lifecycle, how we diagnosed it, and the exact architectural fix that flattened our memory usage permanently.
1. The Symptoms: Ghost Connections and Rising RAM
The service in question was built on FastAPI, leveraging SQLAlchemy as the ORM to talk to a shared PostgreSQL database cluster. It handled high-frequency webhook events, processing background jobs asynchronously using task queues.
When we looked at our monitoring dashboards before a crash, two things stood out:
- RAM Usage: A jagged saw-tooth pattern of garbage collection that slowly trended upward until hitting the container ceiling.
- Database Metrics: Active connection counts on PostgreSQL were maxing out, even during periods of low incoming traffic. The database was choking on thousands of
IDLE in transactionor unclosed client connections.
Clearly, connections and memory objects were being created, but they were never being cleaned up.
2. Under the Hood: What the ORM Was Doing
To understand the leak, we had to look at how our background tasks interacted with SQLAlchemy sessions.
In our asynchronous event loop, background task functions were instantiating global or long-lived database sessions haphazardly. Because the tasks threw exceptions or returned early under certain timeout conditions, the session object and all the identity map cache objects it tracked went out of scope without explicit closure.
Python
# The Anti-Pattern: Unmanaged sessions in background workers
from sqlalchemy.orm import Session
from database import SessionLocal

# Global or module-level session misuse in async tasks
db = SessionLocal()

async def process_webhook_event(payload: dict):# If an exception occurs halfway through, db.close() is never reached!
    user = db.query(User).filter_by(id=payload["user_id"]).first()
    user.last_seen = datetime.utcnow()

    # Missing explicit commit/close handling under failure paths
    db.commit()
    db.close()
Why this leaks memory:
- The Identity Map: An ORM session maintains an internal cache (the identity map) of every Python object it loads during its lifecycle. It keeps references to these objects so it doesn't query the database twice for the same row.
- Orphaned Sockets: When an async task abandoned a session without calling
.close(), the underlying socket connection to PostgreSQL stayed open. Worse, the Python garbage collector couldn't clear the session object because references were trapped inside dangling transaction scopes or event loop closures.
Over thousands of background iterations, this accumulated megabyte by megabyte until Kubernetes pulled the plug.
3. The Diagnosis: Profiling Memory and Connections
To catch the leak in action, we ran memory profiling tools locally against a staging replica under simulated load. Using mprof (Memory Profiler) and inspecting active SQLAlchemy connection states via PostgreSQL, we saw a stark reality:
SQL
SELECT pid, usename, client_addr, state, query
FROM pg_stat_activity
WHERE datname = 'our_database';
Dozens of connections were sitting in an idle state, tied to process IDs from our microservice container that should have released them minutes ago.
Next, we added instrumentation logs tracking active session creation and disposal counts. The delta between session_opened and session_closed grew wider with every single background webhook invocation.
4. The Fix: Enforcing Strict Context Managers
To solve the issue, we completely removed any manual, global session handling. We enforced strict context managers (with statements) to guarantee that sessions are always torn down, transaction states are rolled back on error, and network sockets are immediately returned to the pool.
We refactored our database dependency and task execution handlers to use generator-based context managers:
Python
from contextlib import contextmanager
from database import SessionLocal

@contextmanager
def get_safe_db_session():"""Ensure session is always closed, even if exceptions occur."""
    db = SessionLocal()
    try:
        yield db
        db.commit()
    except Exception:
        db.rollback()
        raisefinally:
        db.close()  # Guarantees socket and memory release!

# Usage in background tasks:
async def process_webhook_event(payload: dict):with get_safe_db_session() as db:
        user = db.query(User).filter_by(id=payload["user_id"]).first()
        user.last_seen = datetime.utcnow()
        # Session automatically closes and cleans identity map upon exiting 'with' block
Additionally, we configured explicit pool recycling and overflow limits in our SQLAlchemy engine configuration to prevent stale socket accumulation:
Python
from sqlalchemy import create_engine

engine = create_engine(
    DATABASE_URL,
    pool_size=10,
    max_overflow=20,
    pool_recycle=300,  # Recycle connections every 5 minutes
    pool_pre_ping=True  # Drop dead connections automatically
)
5. The Measurable Impact
Deploying this fix to production immediately transformed the behavior of our cluster:
- Memory Stability: The jagged, upward-clamping RAM graph flattened instantly. Memory utilization locked in at a predictable 350MB and stayed there indefinitely, regardless of uptime.
- OOM Exits: Dropped from multiple occurrences every 48 hours to zero. The service has been running continuously for months without a single automated restart.
- Database Health: PostgreSQL active connection counts dropped by 70%, completely eliminating connection pool exhaustion errors during peak traffic hours.
So, Respect the Lifecycle
When building microservices, it’s easy to treat ORMs and database drivers as black boxes. But when working with asynchronous code and background workers, state management becomes your most critical responsibility.
If your containers are slowly eating more memory over time, don't just throw more RAM at the problem. Look under the hood at your connection lifecycles, enforce strict context managers, and make sure your sessions are closing the door behind them.