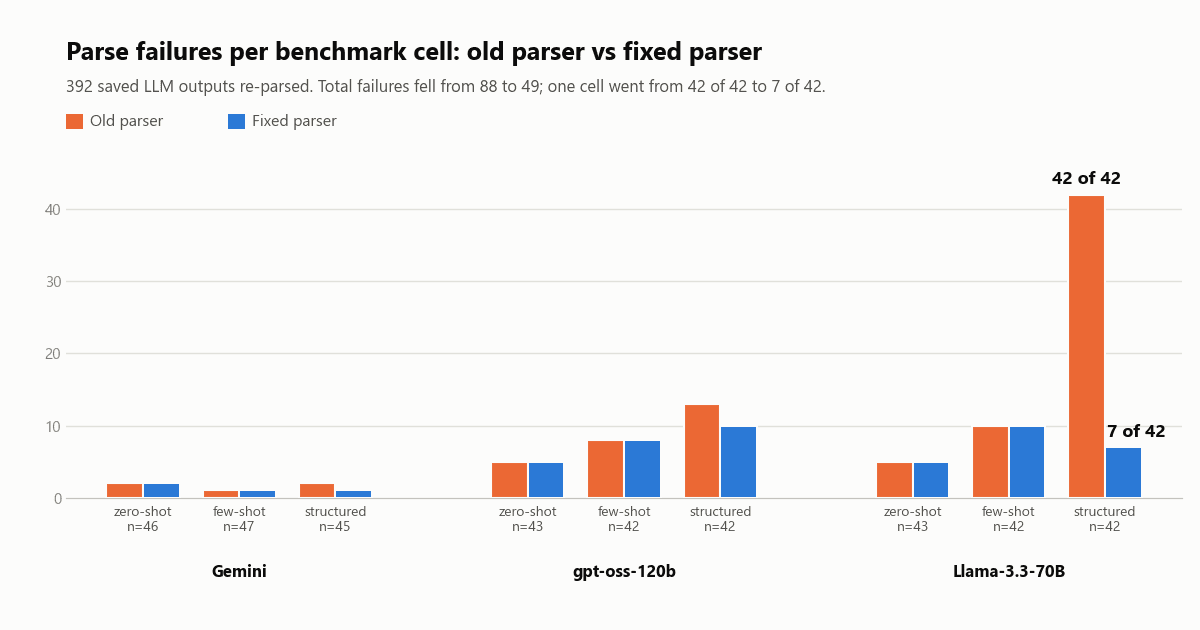
Summarily:
- One cell of our LLM benchmark showed a 100% failure rate (42 of 42 runs, recall 0.0). It looked like a model collapse. It was our parser.
- Of the 42 failures, 30 happened because the model did not repeat a field our code already knew. Only 5 were the JSON-formatting problem we expected.
- Fixing your scorer after you have seen the results is dangerous. We fixed only format problems, kept every content failure, never touched the raw outputs, and wrote tests that lock those rules in.
- A second, unrelated problem, hidden "reasoning" tokens eating the output budget on free-tier APIs, produced truncated answers that look like a model-quality difference. Both problems are easy to make and easy to miss.
What we were measuring
We built a benchmark to test whether large language models can write a project risk register from a project's planning documents. The ground truth is real: 21 World Bank and UK government projects that each publish a human-written risk register. We cut those registers out of the model's input, asked three models to generate their own, and matched the two sets by semantic similarity.
The grid was three models (Gemini, gpt-oss-120b and Llama-3.3-70B-Instruct), three prompting strategies (zero-shot, few-shot, and a "structured" prompt that asks for step-by-step reasoning followed by a FINAL JSON: marker), and two runs per project per cell. That came to 392 real generations, all on free-tier APIs, for about US$0.18 of paid fallback calls in total. We hit the problem in late July 2026, while the results were still coming in.
Every model output had to be valid JSON matching a fixed schema before it could be scored. A run that did not parse counted as recall = 0.
The number that should not exist
When we first scored the grid, one cell looked like this:
| Model | Prompt | Runs | Failed to parse |
|---|---|---|---|
| Llama-3.3-70B | zero-shot | 43 | 5 |
| Llama-3.3-70B | few-shot | 42 | 10 |
| Llama-3.3-70B | structured | 42 | 42 |
Same model, same 21 projects, and it worked most of the time on two prompts and never on the third. A model that fails on every one of 42 attempts is possible, but we did not believe this one. A perfect 100% or 0% in a real experiment usually means the harness, not the model.
So we did the boring thing: we stopped reading the results table and started reading the raw failures.
Reading the failures instead of the score
We broke down all 88 parse failures across the whole grid by root cause. For the 42 failures in that one cell, the old parser's own error messages told the story:
| Runs | What the old parser said | What was actually happening |
|---|---|---|
| 30 | 'project_id' is a required property | The model did not restate the project ID. Our code already knew which project each call was for. |
| 5 | Extra data: line 9 column 2 | The model listed risks as separate JSON objects with no enclosing array. The parser kept the first one and threw away the rest. |
| 7 | no FINAL JSON: marker | The model never reached its answer. This one is a genuine failure. |
The parser was strict in two ways that had nothing to do with whether the model could identify risks:
- Our schema required the model to repeat a field we could fill in ourselves.
- The extraction regex demanded exactly one
{...}object anchored to the end of the response:
_FINAL_JSON_RE = re.compile(r"FINAL JSON:\s*(\{.*\})\s*\Z", re.DOTALL)
A bare array, a list of comma-separated objects, or a friendly "Let me know if you need anything else!" after the JSON all broke it. Across the grid, the same family of format problems showed up for other models too, in smaller numbers. Llama on the structured prompt just happened to hit the worst of them.
The part that is easy to get wrong
At this point we had a scorer we wanted to change after seeing the results. That is exactly what researchers are warned against. If we loosened the parser until our numbers looked good, we would no longer be measuring the models.
So we wrote the rules down before changing any code:
1. Never regenerate. Never edit raw outputs. Every call's raw response was already saved to disk. We only re-derived the parsed result from that saved text, and we diffed every changed file to confirm the raw text was untouched.
2. Fix format, never content. We allowed a fix only if the model had clearly produced the right content in the wrong wrapper:
- Fill in
project_idfrom the run metadata instead of requiring the model to repeat it. - Collect all sequential JSON values instead of just the first one, using Python's
json.JSONDecoder.raw_decodein a loop instead of a regex (condensed below). - Accept a bare array, or trailing prose after a complete JSON value.
- Treat
risk_registeras a synonym forrisks. - Accept
"External"for"external", but only when the lowercased value is one of the eight real categories.
decoder = json.JSONDecoder()
values = []
i = first_json_start(text)      # index of the first '{' or '['
while i < len(text):
    while i < len(text) and (text[i].isspace() or text[i] == ","):
        i += 1                      # skip separators between objectstry:
        val, i = decoder.raw_decode(text, i)
    except json.JSONDecodeError:
        break                       # whatever is left is trailing prose
    values.append(val)
3. Leave the schema alone. A risk category outside our eight-category taxonomy ("legal", "market", "social", "procurement") is a model error, not a formatting quirk. Those still fail, and we added a regression test named test_invalid_category_still_rejected_not_papered_over so a future change cannot quietly start accepting them.
4. Check what is left. After the fix, we read the remaining failures one by one instead of assuming they were all genuine.
5. Disclose it. The bug, the fix, and the before/after numbers are in the paper.
What changed
Re-running the parser on the same saved outputs:
- Total parse failures across the grid: 88 → 49. That is 39 recovered.
- Llama on the structured prompt: 42 of 42 failed → 7 of 42, and its recall went from 0.0 to about 0.43, in line with its other two prompts.
- The 49 that remain are real: 25 invalid categories outside the taxonomy, plus field-length violations, missing required fields, and truncated responses.
If we had not looked, the results table would have said that structured prompting makes Llama-3.3-70B collapse completely. Someone might have cited it.
The second bug: reasoning tokens you never asked for
While debugging that, we found a different class of problem hiding in the same experiment.
Several current models spend part of their output-token budget on hidden reasoning before they write a visible answer. The providers say so themselves. Google's Gemini docs state that the output limit includes thought tokens and that a model which hits the limit while reasoning "stops generating with status incomplete and returns truncated or empty output" (Gemini API: thinking). OpenAI's docs warn that this "might occur before any visible output tokens are produced" (OpenAI: reasoning models).
If you set max_tokens the way you would for an older model, the budget runs out in the middle of the response. The API returns a truncated answer with finish_reason="length", and it looks like the model just wrote something bad.
What we saw on the free tiers, from our own dated build notes at the time (we did not log finish_reason or completion-token counts for the main grid, so these specific figures are our contemporaneous record of a one-off smoke test, not something we can re-derive from saved data today):
- Gemini at
max_tokens=4096: in an early 9-call smoke test, all three Gemini cells came back cut off around 650 to 700 characters, mid-string. Six of nine cells overall failed to parse. - The structured prompt on Gemini at
max_tokens=8192: still failing, at only 325 completion tokens. At 24,000 it succeeded cleanly (4,061 completion tokens). We do not fully understand why the failing case used fewer tokens than the 4096 case. We wrote that down as an open question instead of inventing an explanation.
One number here we can stand behind independently: gpt-oss-120b at max_tokens=1024 returned an empty response with finish_reason="length", the visible answer never started, and it needed max_tokens=4096 to clear the reasoning spend and return real content. That one is recorded twice in our own project docs, from a real logged call, not just a comment we wrote once and moved on from.
We raised the ceiling to 24,576 for every model. It costs nothing for models that stop early anyway.
The same root cause hit us a third time in the LLM-as-judge pilot. A judge budget of 512 tokens meant 3 of 5 judge calls came back truncated or empty. That is a 60% failure rate that has nothing to do with judging quality.
A checklist you can steal
- Treat 0% and 100% as bugs until proven otherwise. Read the raw failures before you interpret the score.
- Save every raw response, and never overwrite it. Keep generation separate from parsing and scoring so you can re-score without re-calling the API.
- Do not make the model restate what your code already knows. IDs, project names and run metadata belong in your code.
- Log
finish_reasonand completion-token counts on every call.lengthis a harness event, not a model answer. Count it separately. - Split failures into format and content. Only format failures are yours to fix. Write the rule down before you touch the code.
- Break failures down by root cause, per cell. An overall failure rate hides the one cell that is on fire.
- Put the rule in a test. If a fix must not loosen something, write the test that fails when it does.
- Report the bug. A disclosed, corrected harness bug makes your numbers more credible, not less.
The code
The corpus manifest, prompts, parser, raw outputs and the regression tests are public: github.com/smadhu6364-beep/public-reproducible-benchmark. The parser fix is commit 4608c8e.
We are a student researcher at NYU and a student researcher at DCU, building this alongside our degrees, and we would rather show the mistake than only the polished result. If you run LLM evals, we would like to hear what your version of this bug looked like.