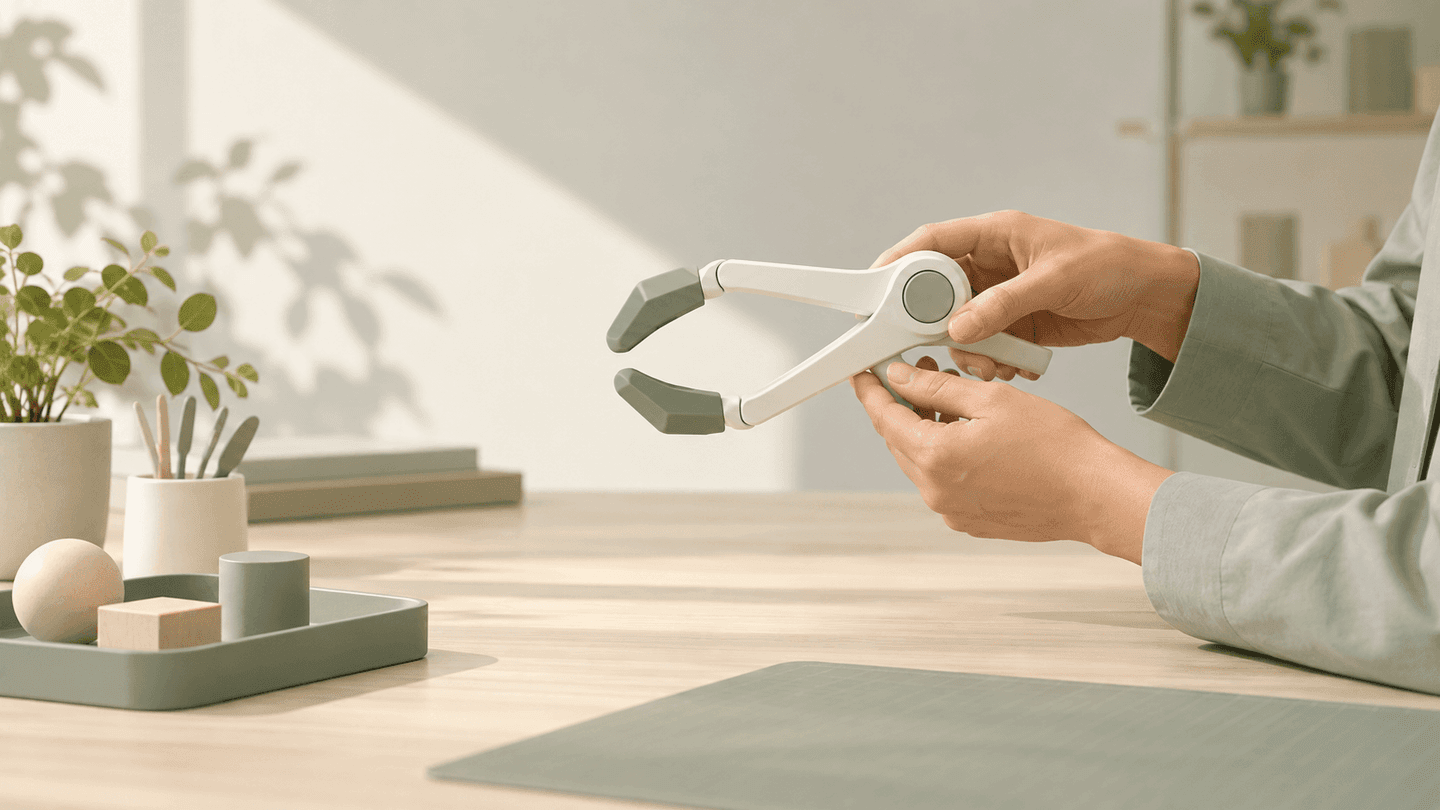
A team led by Hao Dong at Peking University, working with Shanghai personal-robot maker PrimeBot, has introduced HIL-UMI, a method for post-training vision-language-action models that collects correction data with a handheld gripper instead of a physical robot arm. The paper is on arXiv; a project page is live at hil-umi.github.io. PrimeBot is the English brand of Qiyuan Robot, where Dong serves as chief scientist.
Post-training for robot manipulation usually needs real-world interaction. Classic human-gated DAgger, or HG-DAgger, has an operator watch a robot execute a task and take over when it is about to fail, then reset the scene. That loop is accurate but slow: most of the time goes to clumsy robot motion and manual resets rather than useful correction frames.
HIL-UMI keeps the human-in-the-loop idea but drops the robot from the collection step. An operator performs a task with a Universal Manipulation Interface handheld gripper while cameras record the same view the policy would see. In the background, the current policy predicts future actions on that stream without controlling any arm. When an Energy Score shows the policy's action distribution diverging from the human trajectory, the system prompts the operator to record extra demonstration for that segment.
A second loop trains a progress-based advantage estimator, then uses advantage-conditioned behavioral cloning so the model learns actions that actually advance the task, not idle motion. After each round of targeted collection, the policy is updated, so later sessions fire alerts on harder edge cases instead of repeating easy ones.
On four real robot tasks — folding a towel, cleaning up a table, stacking blocks and stamping — the team reports that, under the same frame budget, plain supervised fine-tuning raised average task progress score from 44.3 to 58.0, while HIL-UMI reached 94.8, with perfect scores on the two precision tasks. On the long-horizon clean-up-table task, they quote 73.40 milliseconds per useful frame for HIL-UMI versus 412.99 milliseconds for HG-DAgger, about 5.63 times higher collection efficiency. Those figures are the authors' own results and have not been independently verified.
The paper argues this separates iterative, policy-aware correction from robot deployment, so post-training data could be gathered by more operators in more places without parking a robot farm in the lab.
SEE ALSO: SenseTime Open-Sources SenseNova-RoboRSI · PrimeBot Begins First Deliveries of Q1 and T1 · Infinigence AI Open-Sources APXInf