
Abhinav pivoted from a career in banking to pursue his first love in writing. Even while working full-time, he continued contributing as an editor-at-large, a role he has held for more than 7 years. A lifelong tech enthusiast who has built three gaming and productivity powerhouse PCs since 2018, his passion for technology keeps him closely following the semiconductor industry, from NVIDIA and AMD to ARM. His MSc dissertation explored how artificial intelligence will reshape the future of work, reflecting his curiosity about the wider social impact of emerging technologies.
A lot of what you can do with your PC seems to be limited by the VRAM its GPU has. It decides what resolution your games run at, how large a video project you can edit without the timeline stuttering intermittently, and most recently, which local AI models you can self-host. A lot of these examples feel like hard limits, but there are workarounds for almost all of them.
Perhaps the simplest of those workarounds relate to local AI inference. I had already mentally disqualified my Lenovo Legion 5 with an 8GB RTX 3070 Mobile GPU from running some of the models that I run on my RTX 4070 Ti Super with 16GB of GDDR6X. However, in the past couple weeks of testing, I stumbled upon a workaround that helps it to run massive models itself at reasonable speeds.
One llama.cpp flag had my curiosity
Were the best models truly reserved for bigger GPUs, or was there a workaround?
Last week, I talked about moving my local AI stack from Ollama to llama.cpp, and while testing the runtime and its various features, it struck me that one of those features can help optimize a smaller system with a lower VRAM budget to run models that have absolutely no business running on it. On my desktop's RTX 4070 Ti Super, Qwen3.6-35B-A3B was the fastest model I tested at IQ4_XS quantization and 32K context, despite being a whopping 17.7GB file sitting on top of 16GB of GDDR6X.
The math says the model shouldn't fit the VRAM, of course, but Mixture-of-Experts (MoE) models already changed the math a while back. Out of the model's 35 billion parameters, roughly only 3 billion are activated for inference and the rest sit idle. Much of the trick is moving the dormant expert layers to the system RAM while the always-on parts of the network stay comfortably resident on the GPU.
The flag that makes this possible is --n-cpu-moe N. You can pair it with -ngl 99 to instruct llama.cpp to load every layer to the GPU, and --n-cpu-moe then peels expert tensors of the first N layers back off and keeps them in system RAM. As a result, attention layers, embeddings, shared weights and most importantly the KV cache all stay in VRAM, which are all integral to token generation speeds. The expert layers, on the other hand, are only touched when the router picks them, are resident in the system memory, and get copied over as needed.
This naturally got me curious about my Lenovo laptop. If a 17.7GB model can run on a system with 16GB of VRAM, exactly how far can the same trick stretch a system with 8GB of VRAM? That was precisely the question driving the experiment I've detailed.
Llama-bench had all the information I needed to fine-tune the model
It took one command to see if my laptop's 8GB GPU could hold up
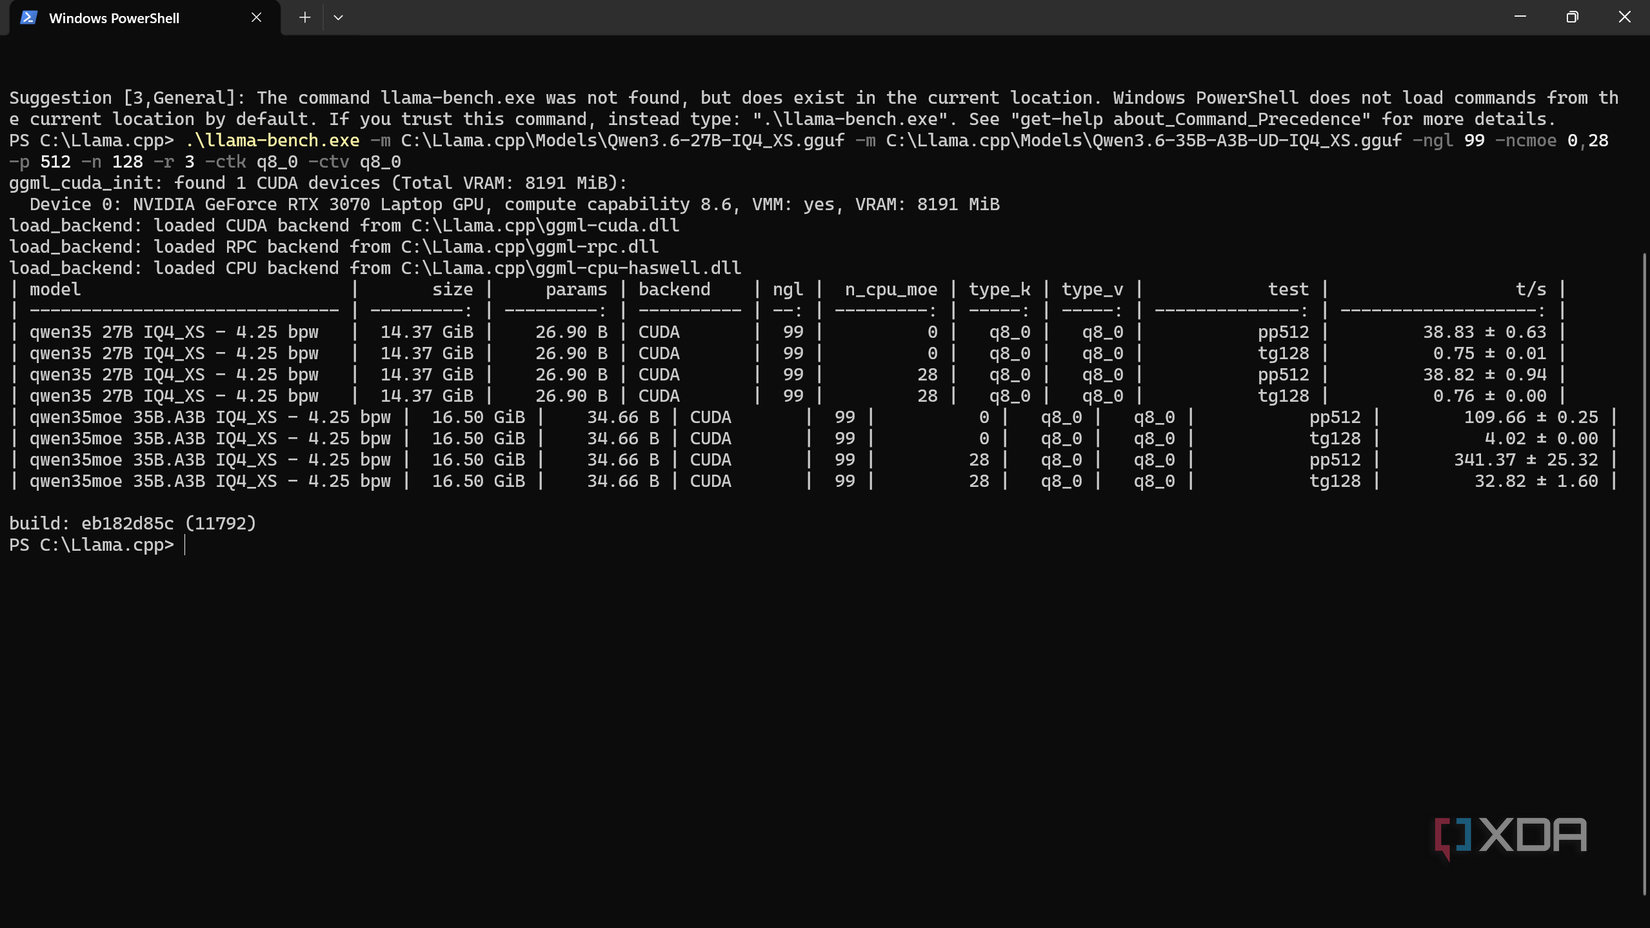
Prior to using any flags, I wanted an honest and reproducible answer to check if my 8GB RTX 3070 laptop GPU could actually sustain inference on something larger than the models it was built for. I would argue that there's no better way to check it than llama.cpp's utility known as llama-bench.
For this test, I ran both the models I have on my laptop, including Qwen3.6-27B at IQ4_XS quantization and Qwen3.6-35B-A3B at UD-IQ4_XS quantization. If you're wondering why I used a dense model that can't have expert layers offloaded to the RAM, it's because it is used as a reference to benchmark against. To start the test, I used the following command:
.\llama-bench.exe -m Qwen3.6-27B-IQ4_XS.gguf -m Qwen3.6-35B-A3B-UD-IQ4_XS.gguf -ngl 99 -ncmoe 0,28 -p 512 -n 128 -r 3 -ctk q8_0 -ctv q8_0This benchmarks four configurations on both models, each at --n-cpu-moe 0 (no offload), and 28 (28 layers' worth of expert weights moved to system RAM). It's worth taking a moment to understand what each flag means here.
The -ngl 99 instructs llama.cpp to attempt loading every layer onto the GPU. The -p 512 -n 128 sets a 512-token prefill followed by 128 tokens of generation per run, which are llama-bench's defaults, which are enough to produce stable numbers. Next, the -r 3 repeats each configuration three times so that singular lucky runs don't muddy up the dataset. Lastly, -ctk q8_0 - ctv q8_0 quantizes the KV cache down to 8-bit.
The following are the results llama-bench produced after the run.
|
Model |
MoE layers in RAM |
Prompt processing (tokens/sec) |
Generation speed (tokens/second) |
|
Qwen3.6-27B (Dense, IQ4_XS, 14.37GiB) |
Not applicable (Dense model) |
38.83 |
0.75 |
|
Qwen3.6-35B-A3B (MoE, UD-IQ4_XS, 16.50GiB) |
109.66 |
4.02 |
|
|
Qwen3.6-35B-A3B (MoE, UD-IQ4_XS, 16.50GiB) |
28 |
341.37 |
32.82 |
One llama.cpp flag turned my 8GB laptop into a 35B inference machine
A desktop optimization unlocked an entirely different tier on my laptop
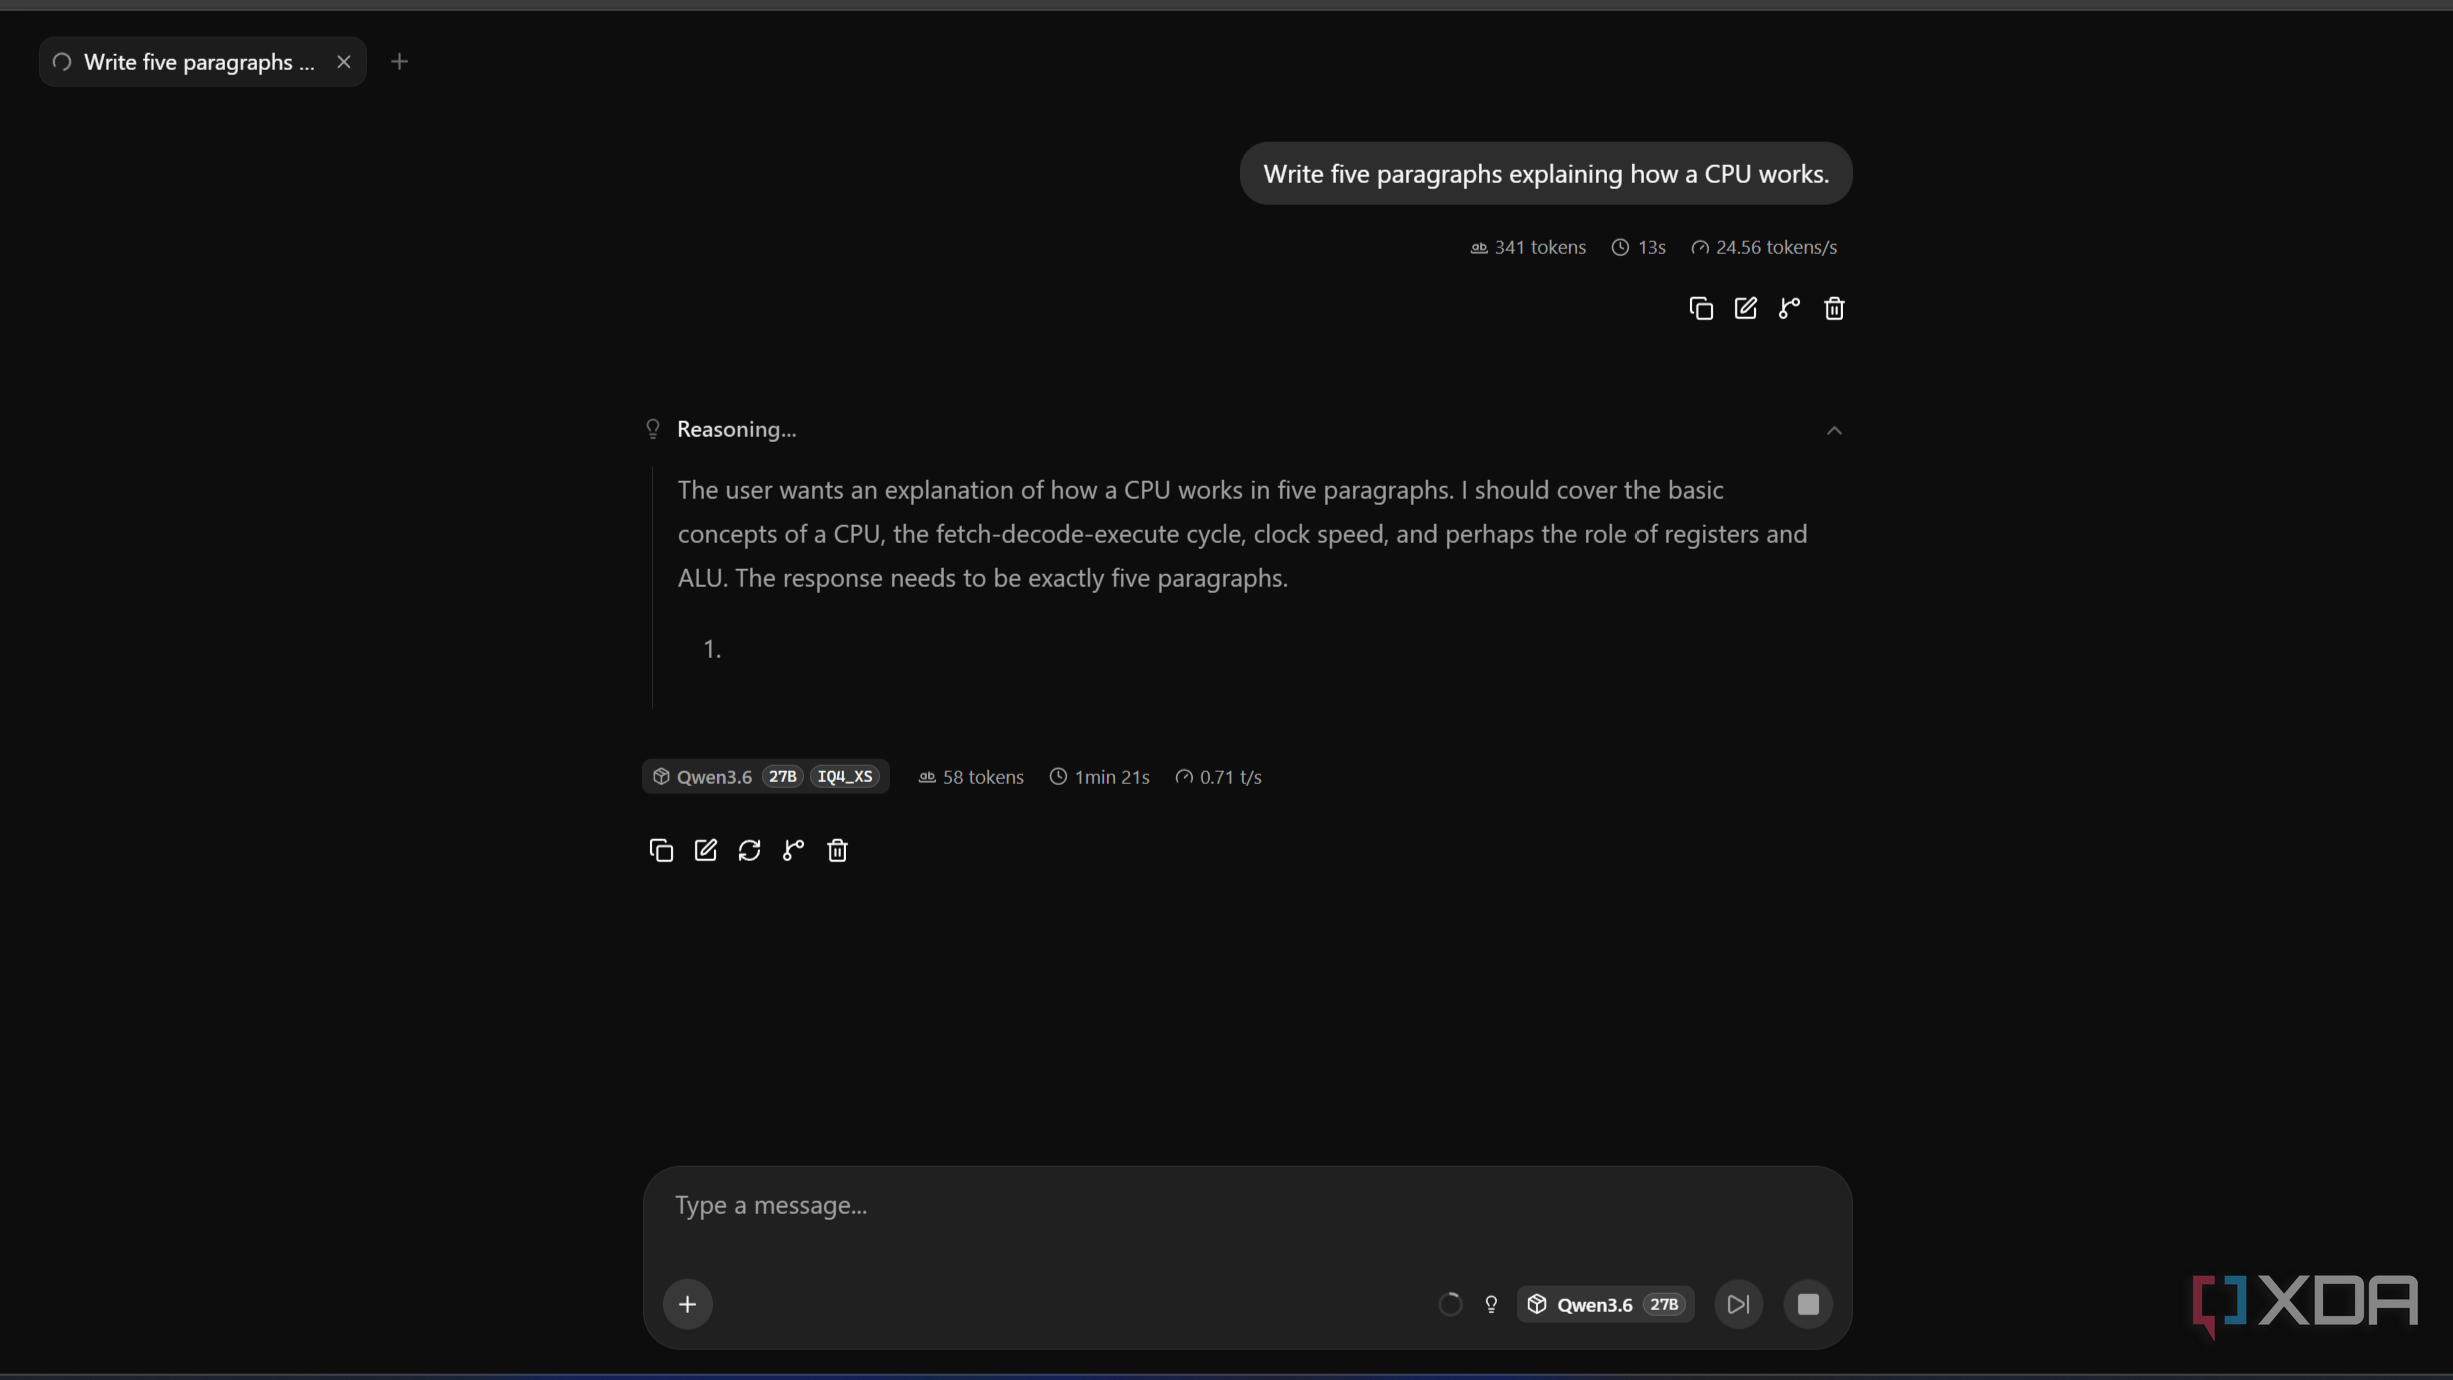
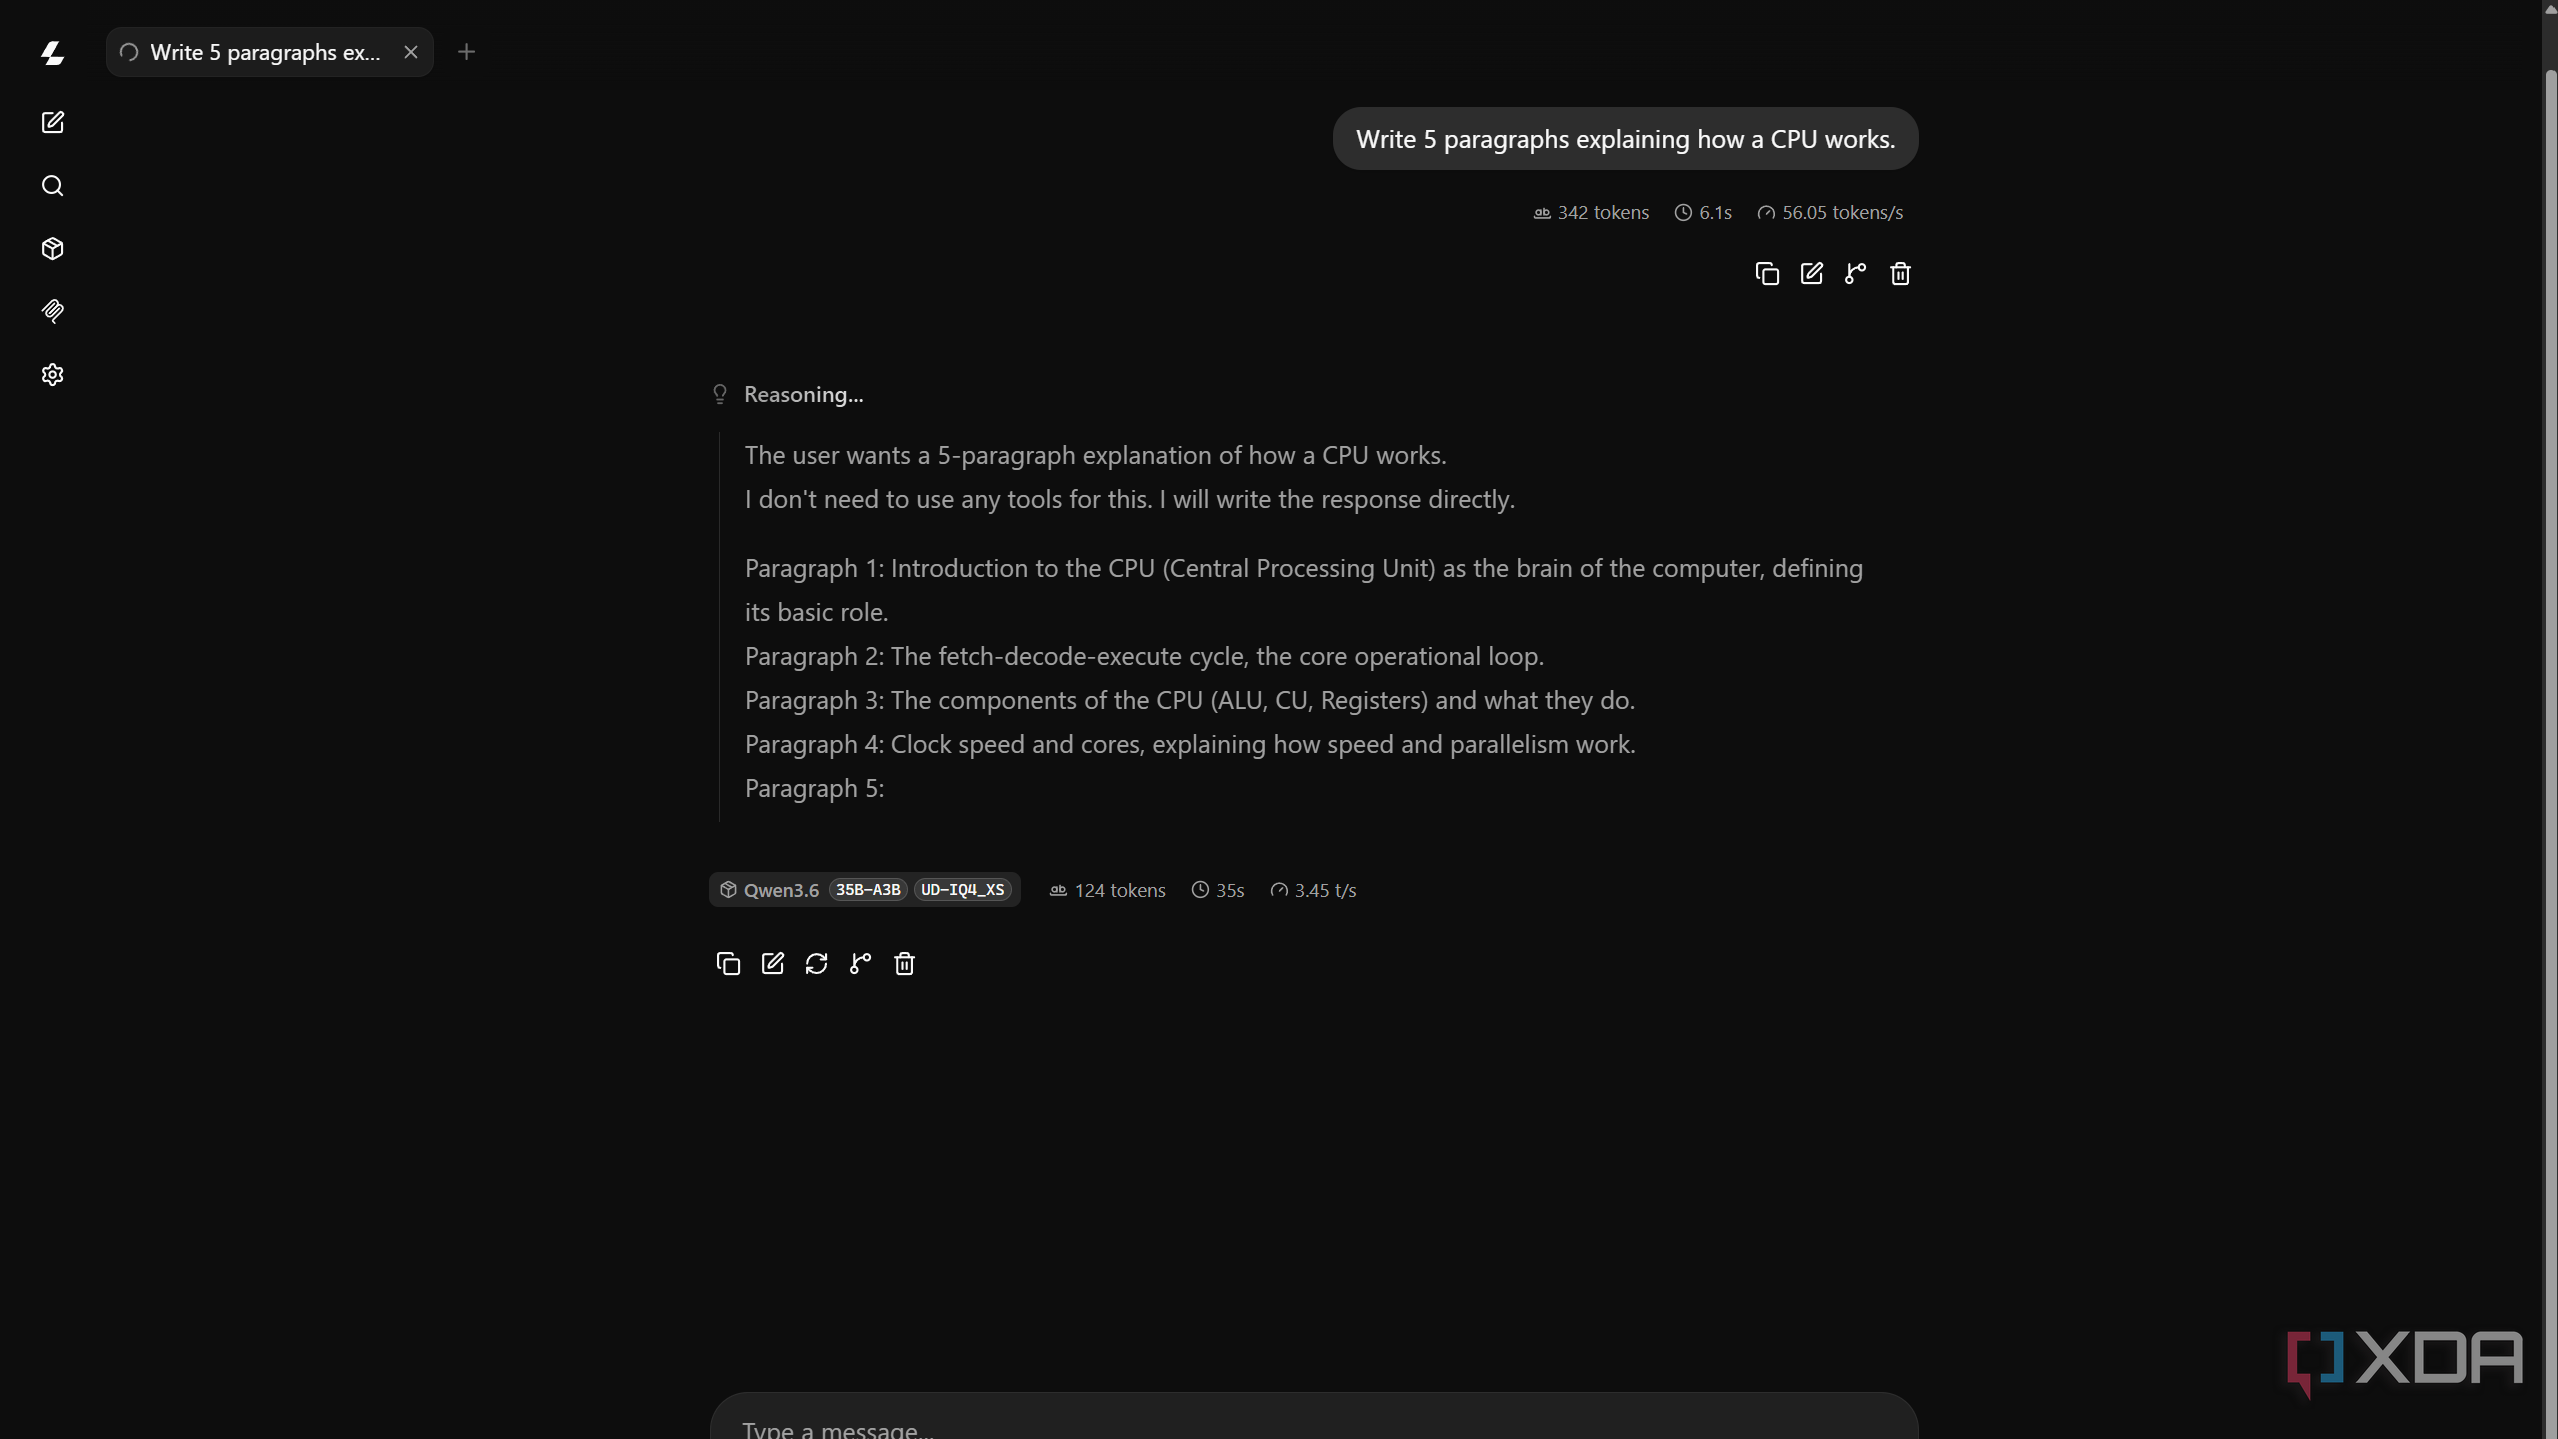
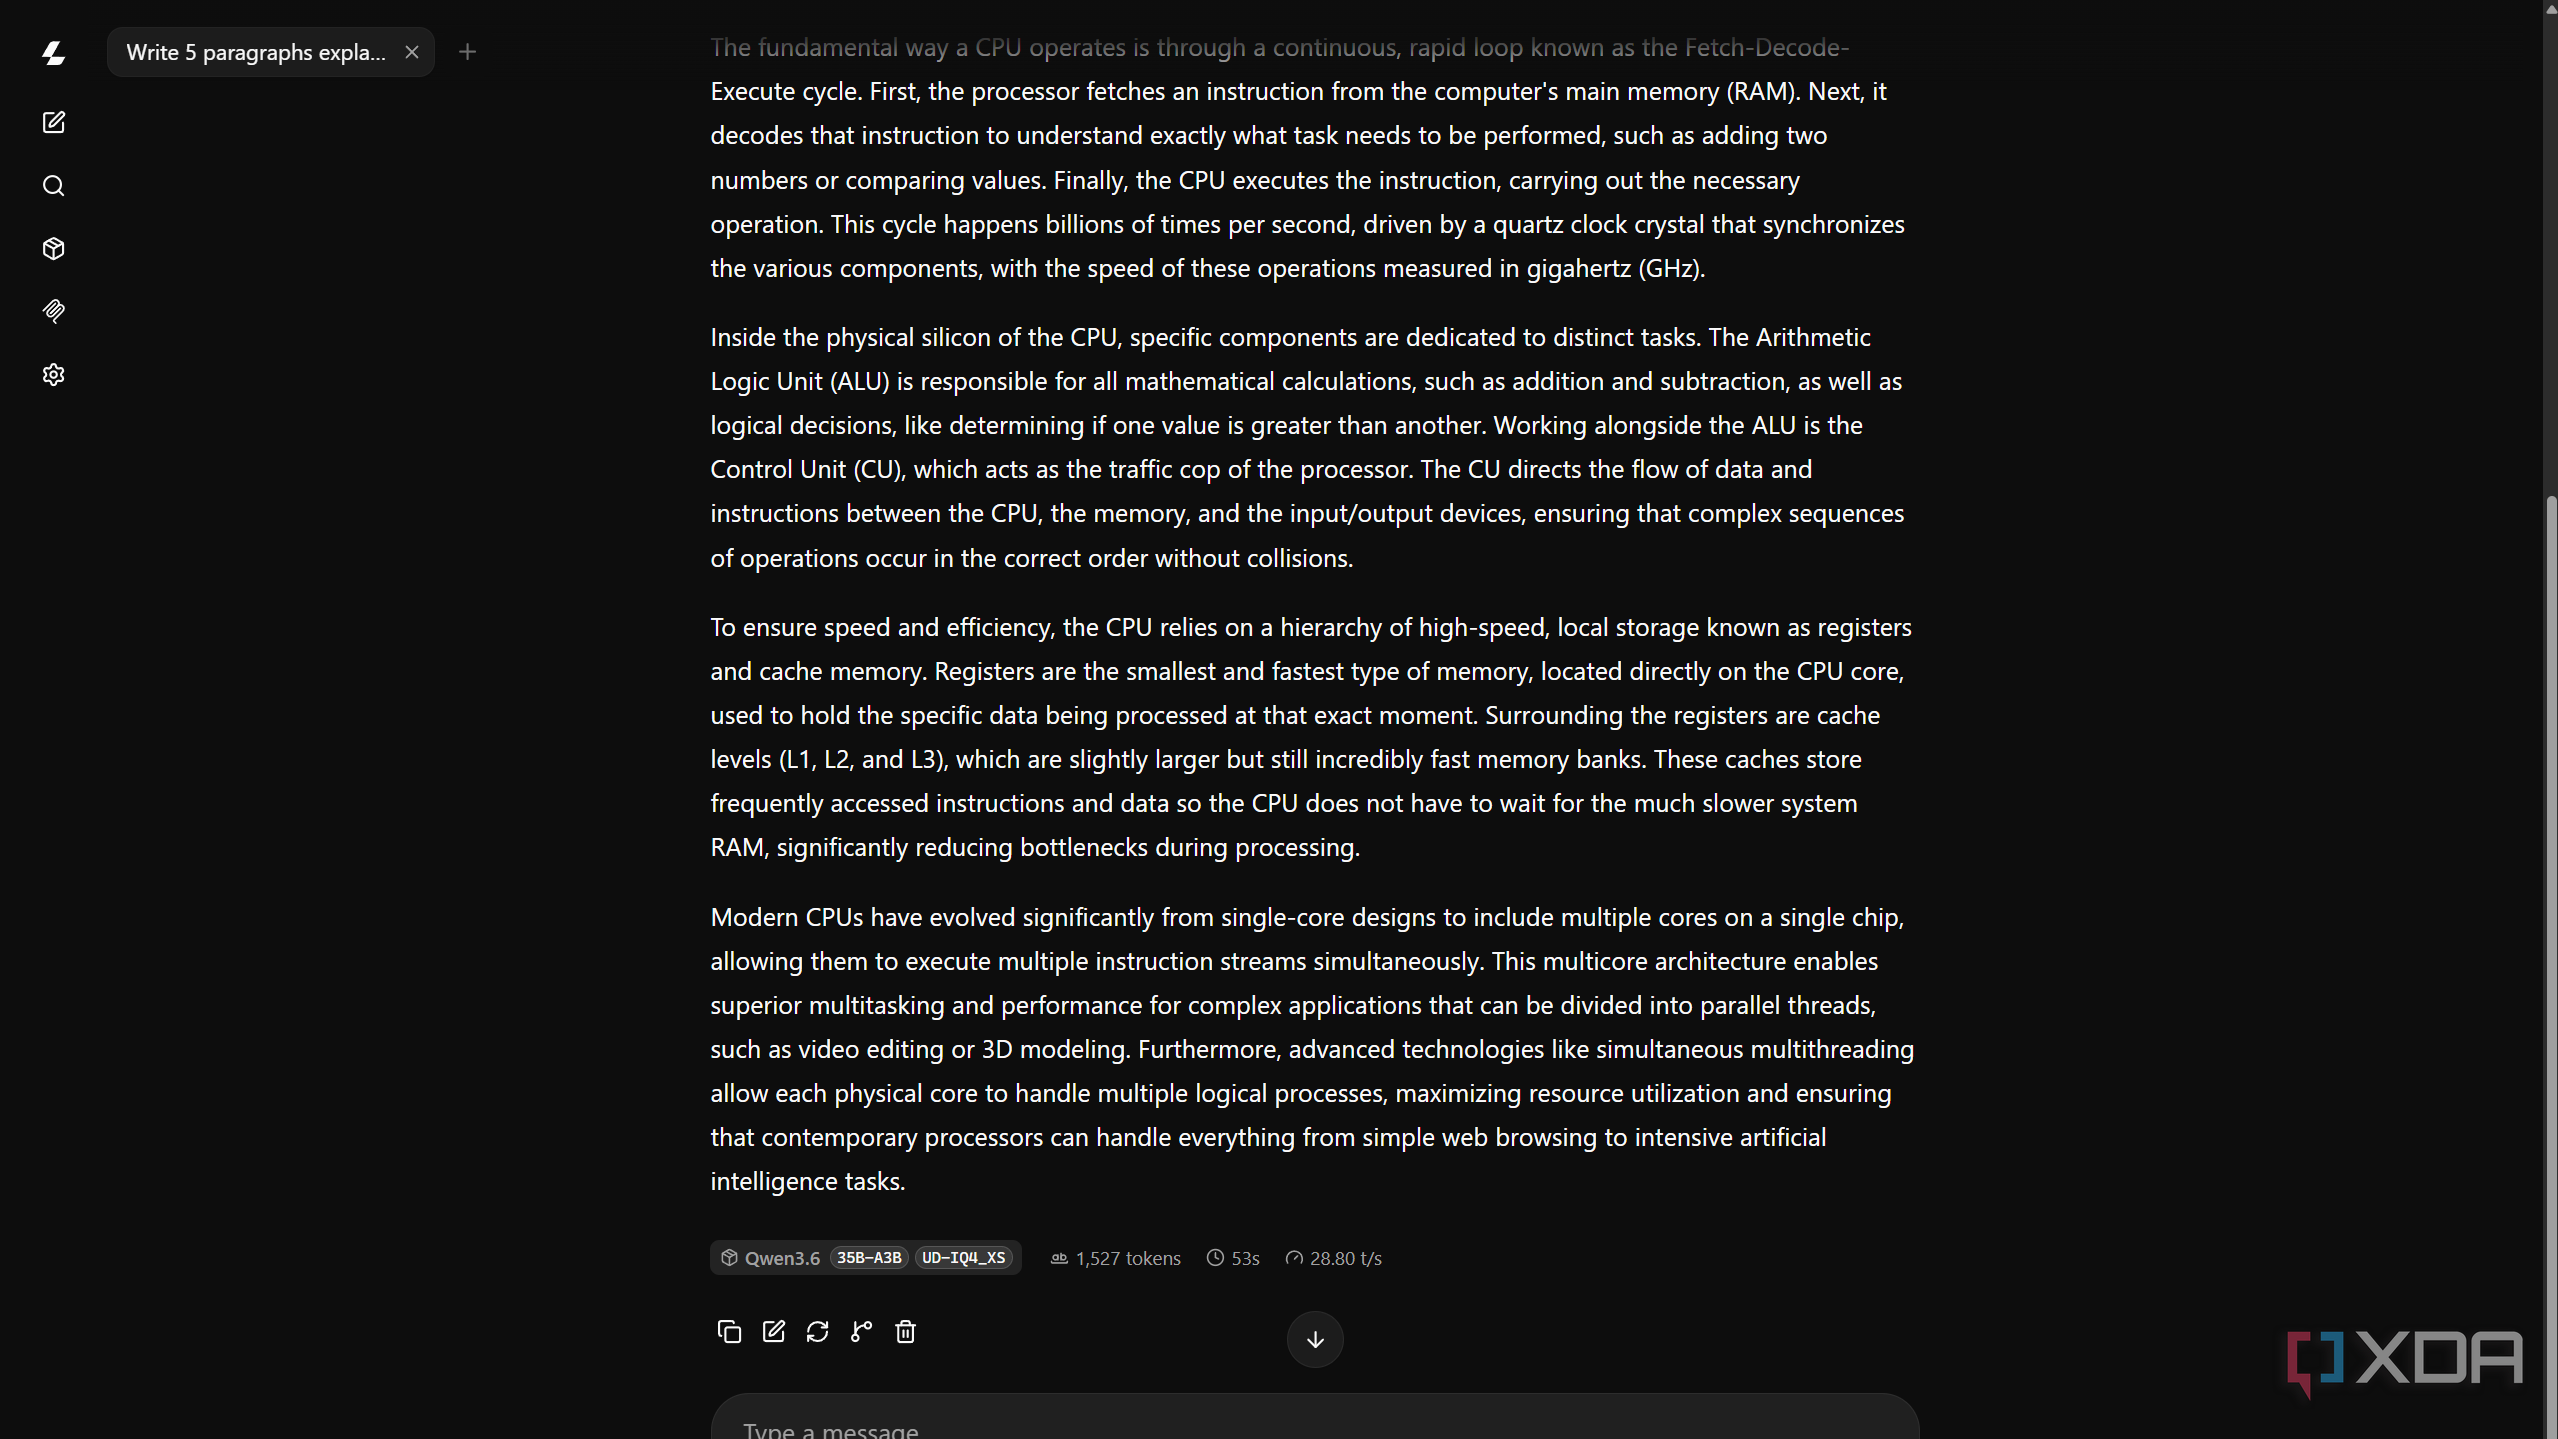
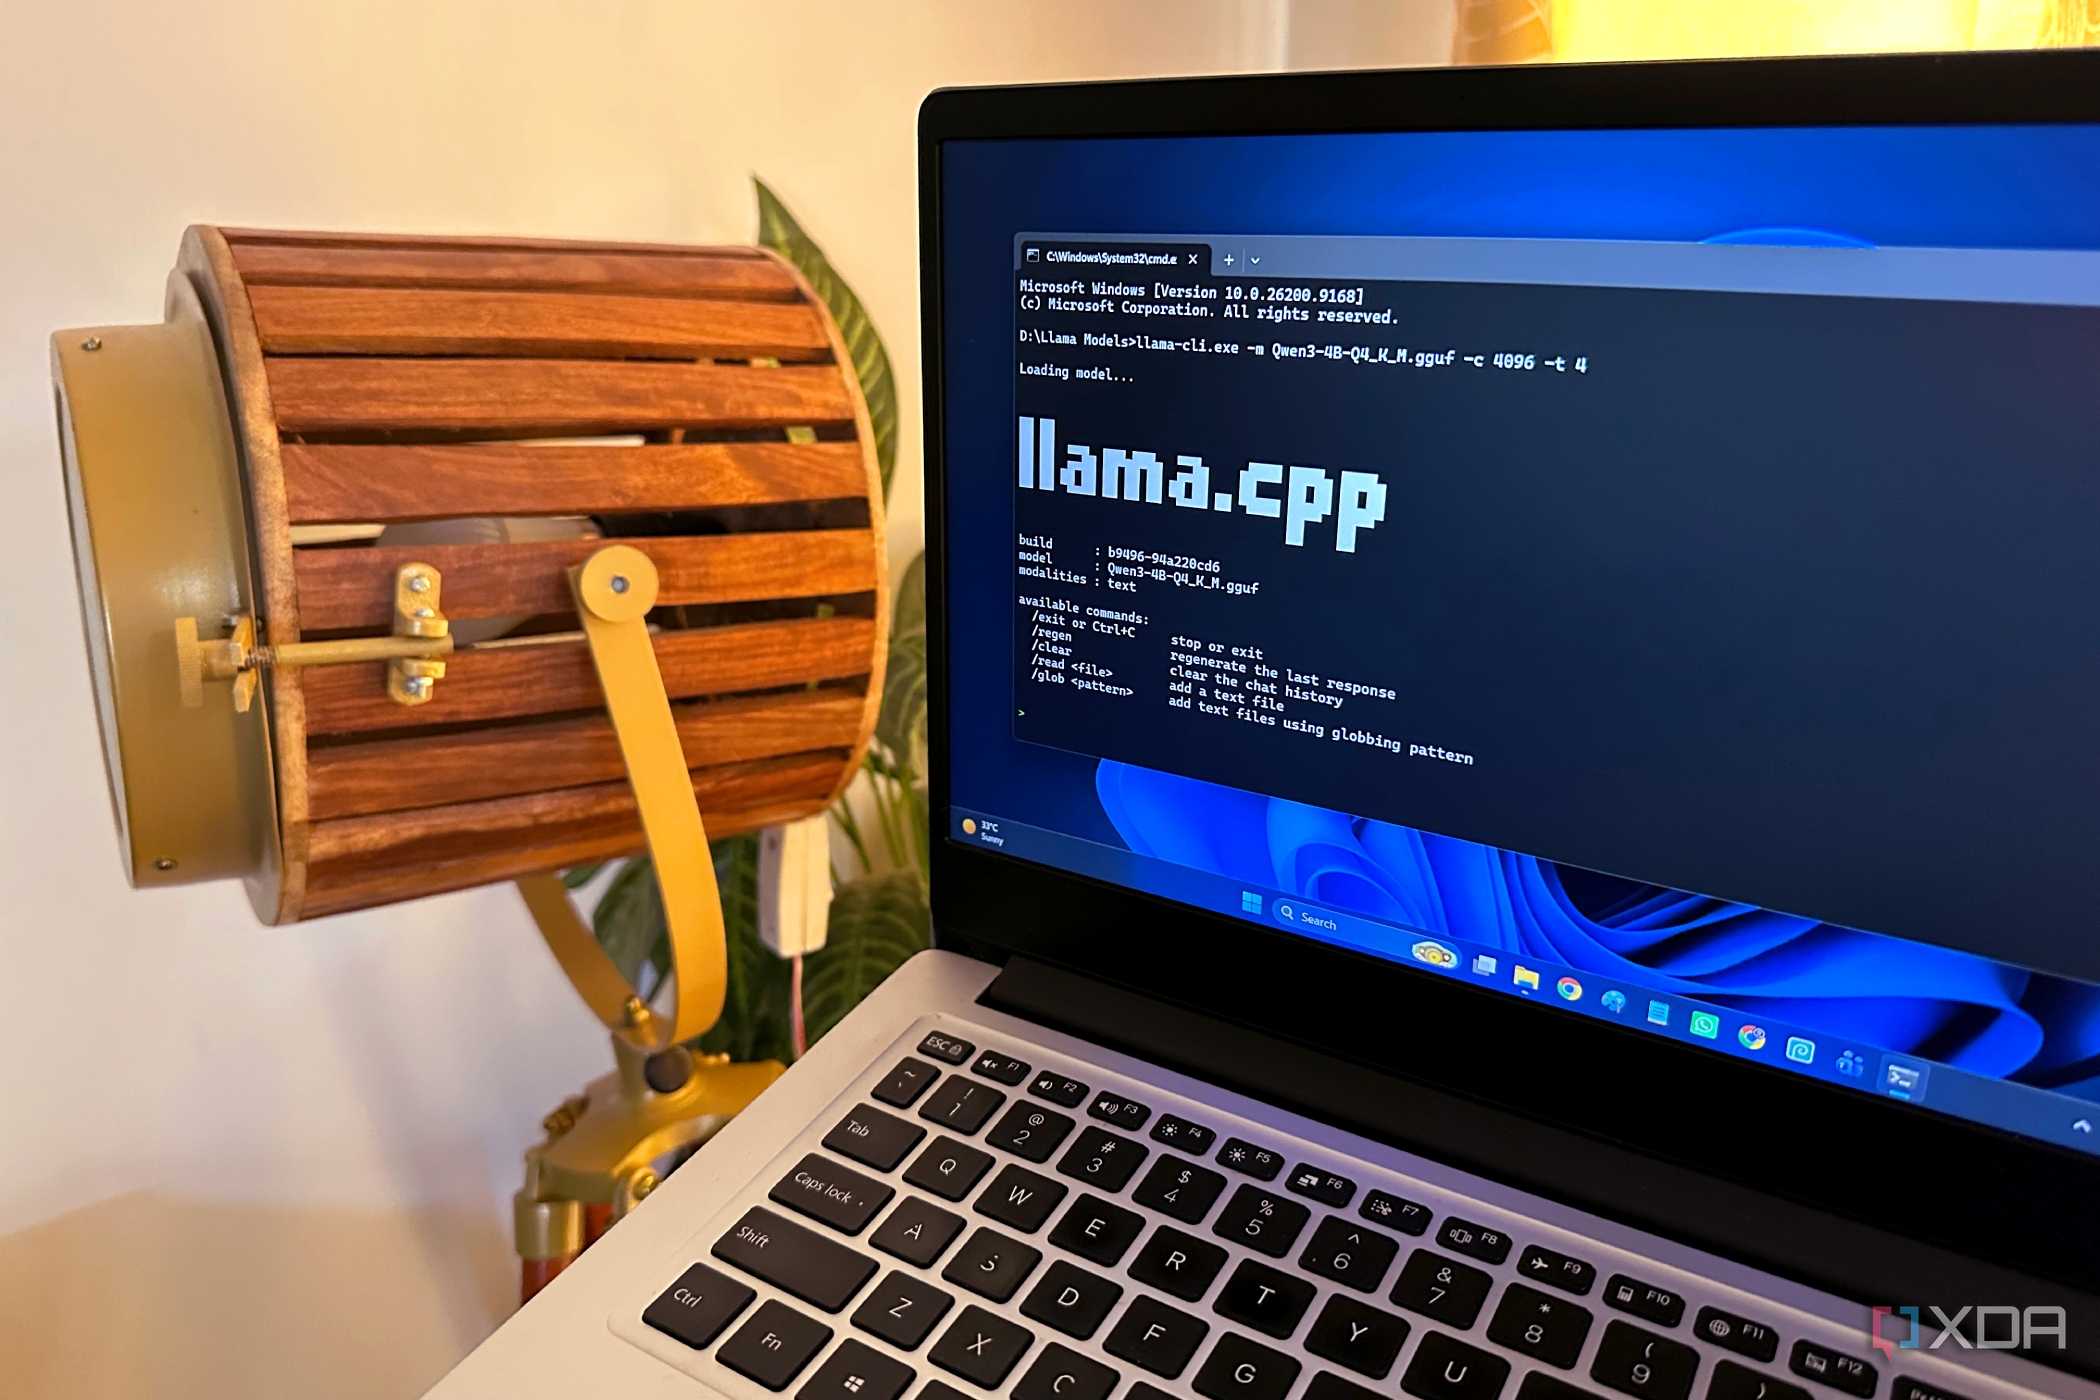
For the longest time, just like most other users, my mental model of local AI was simple, yet deceptive. I thought that only my desktop could run the serious models, and the laptop would have to stick with whatever small Gemma 4 variants could fit in the VRAM. This experiment has completely subverted that expectation in perhaps the best way possible.
It is, indeed, possible to optimize a 35B mixture-of-experts model that barely crosses 4 tokens/second to do 33 tokens per second on the very same hardware with the use of flags. Roughly 33 tokens per second is much faster than I read, which means the model responds at a speed that I am comfortable working with.
The best models aren't reserved for my desktop anymore
Perhaps the one thing that this optimization changes in a way that it matters to me, and I'd wager would matter to most users like myself, is the level of access it enables. Most users would think loading up a 35B MoE model would mean sitting at home at their desks right next to their workstations, but with the right flags and right optimizations, it's possible to carry a 35B model on the go, no matter whether it's on a flight, in a hotel, or a place with no network. That is something significant that llama.cpp enables for me.
llama.cpp
Llama.cpp is an open-source framework that runs large language models locally on your computer.