

Abhinav pivoted from a career in banking to pursue his first love in writing. Even while working full-time, he continued contributing as an editor-at-large, a role he has held for more than 7 years. A lifelong tech enthusiast who has built three gaming and productivity powerhouse PCs since 2018, his passion for technology keeps him closely following the semiconductor industry, from NVIDIA and AMD to ARM. His MSc dissertation explored how artificial intelligence will reshape the future of work, reflecting his curiosity about the wider social impact of emerging technologies.
Over the past couple of months, I've experimented with the idea of reducing my dependence on cloud-based AI services for various reasons. For one, they can be expensive. For another, my personal and professional workflows involve a lot of information that I couldn't reasonably trust a cloud service with.
My experiments have, indeed, seen relative success in terms of cost savings. I've talked about how using a hybrid approach involving switching between capable local coding models in developer workflows can cut cloud AI spending by up to 50%, and I have pocketed the savings from utilizing this method.
And yet, I still wouldn't vouch for a total local-only approach because of the obvious trade-offs associated with capability. That's why I've taken to reserving my cloud models for the work that needs them, while anything more sensitive for a cloud server can stay with my local LLM.
My local LLM offers zero data retention by default
I can do my taxes, look at health records, and dump my bank statements
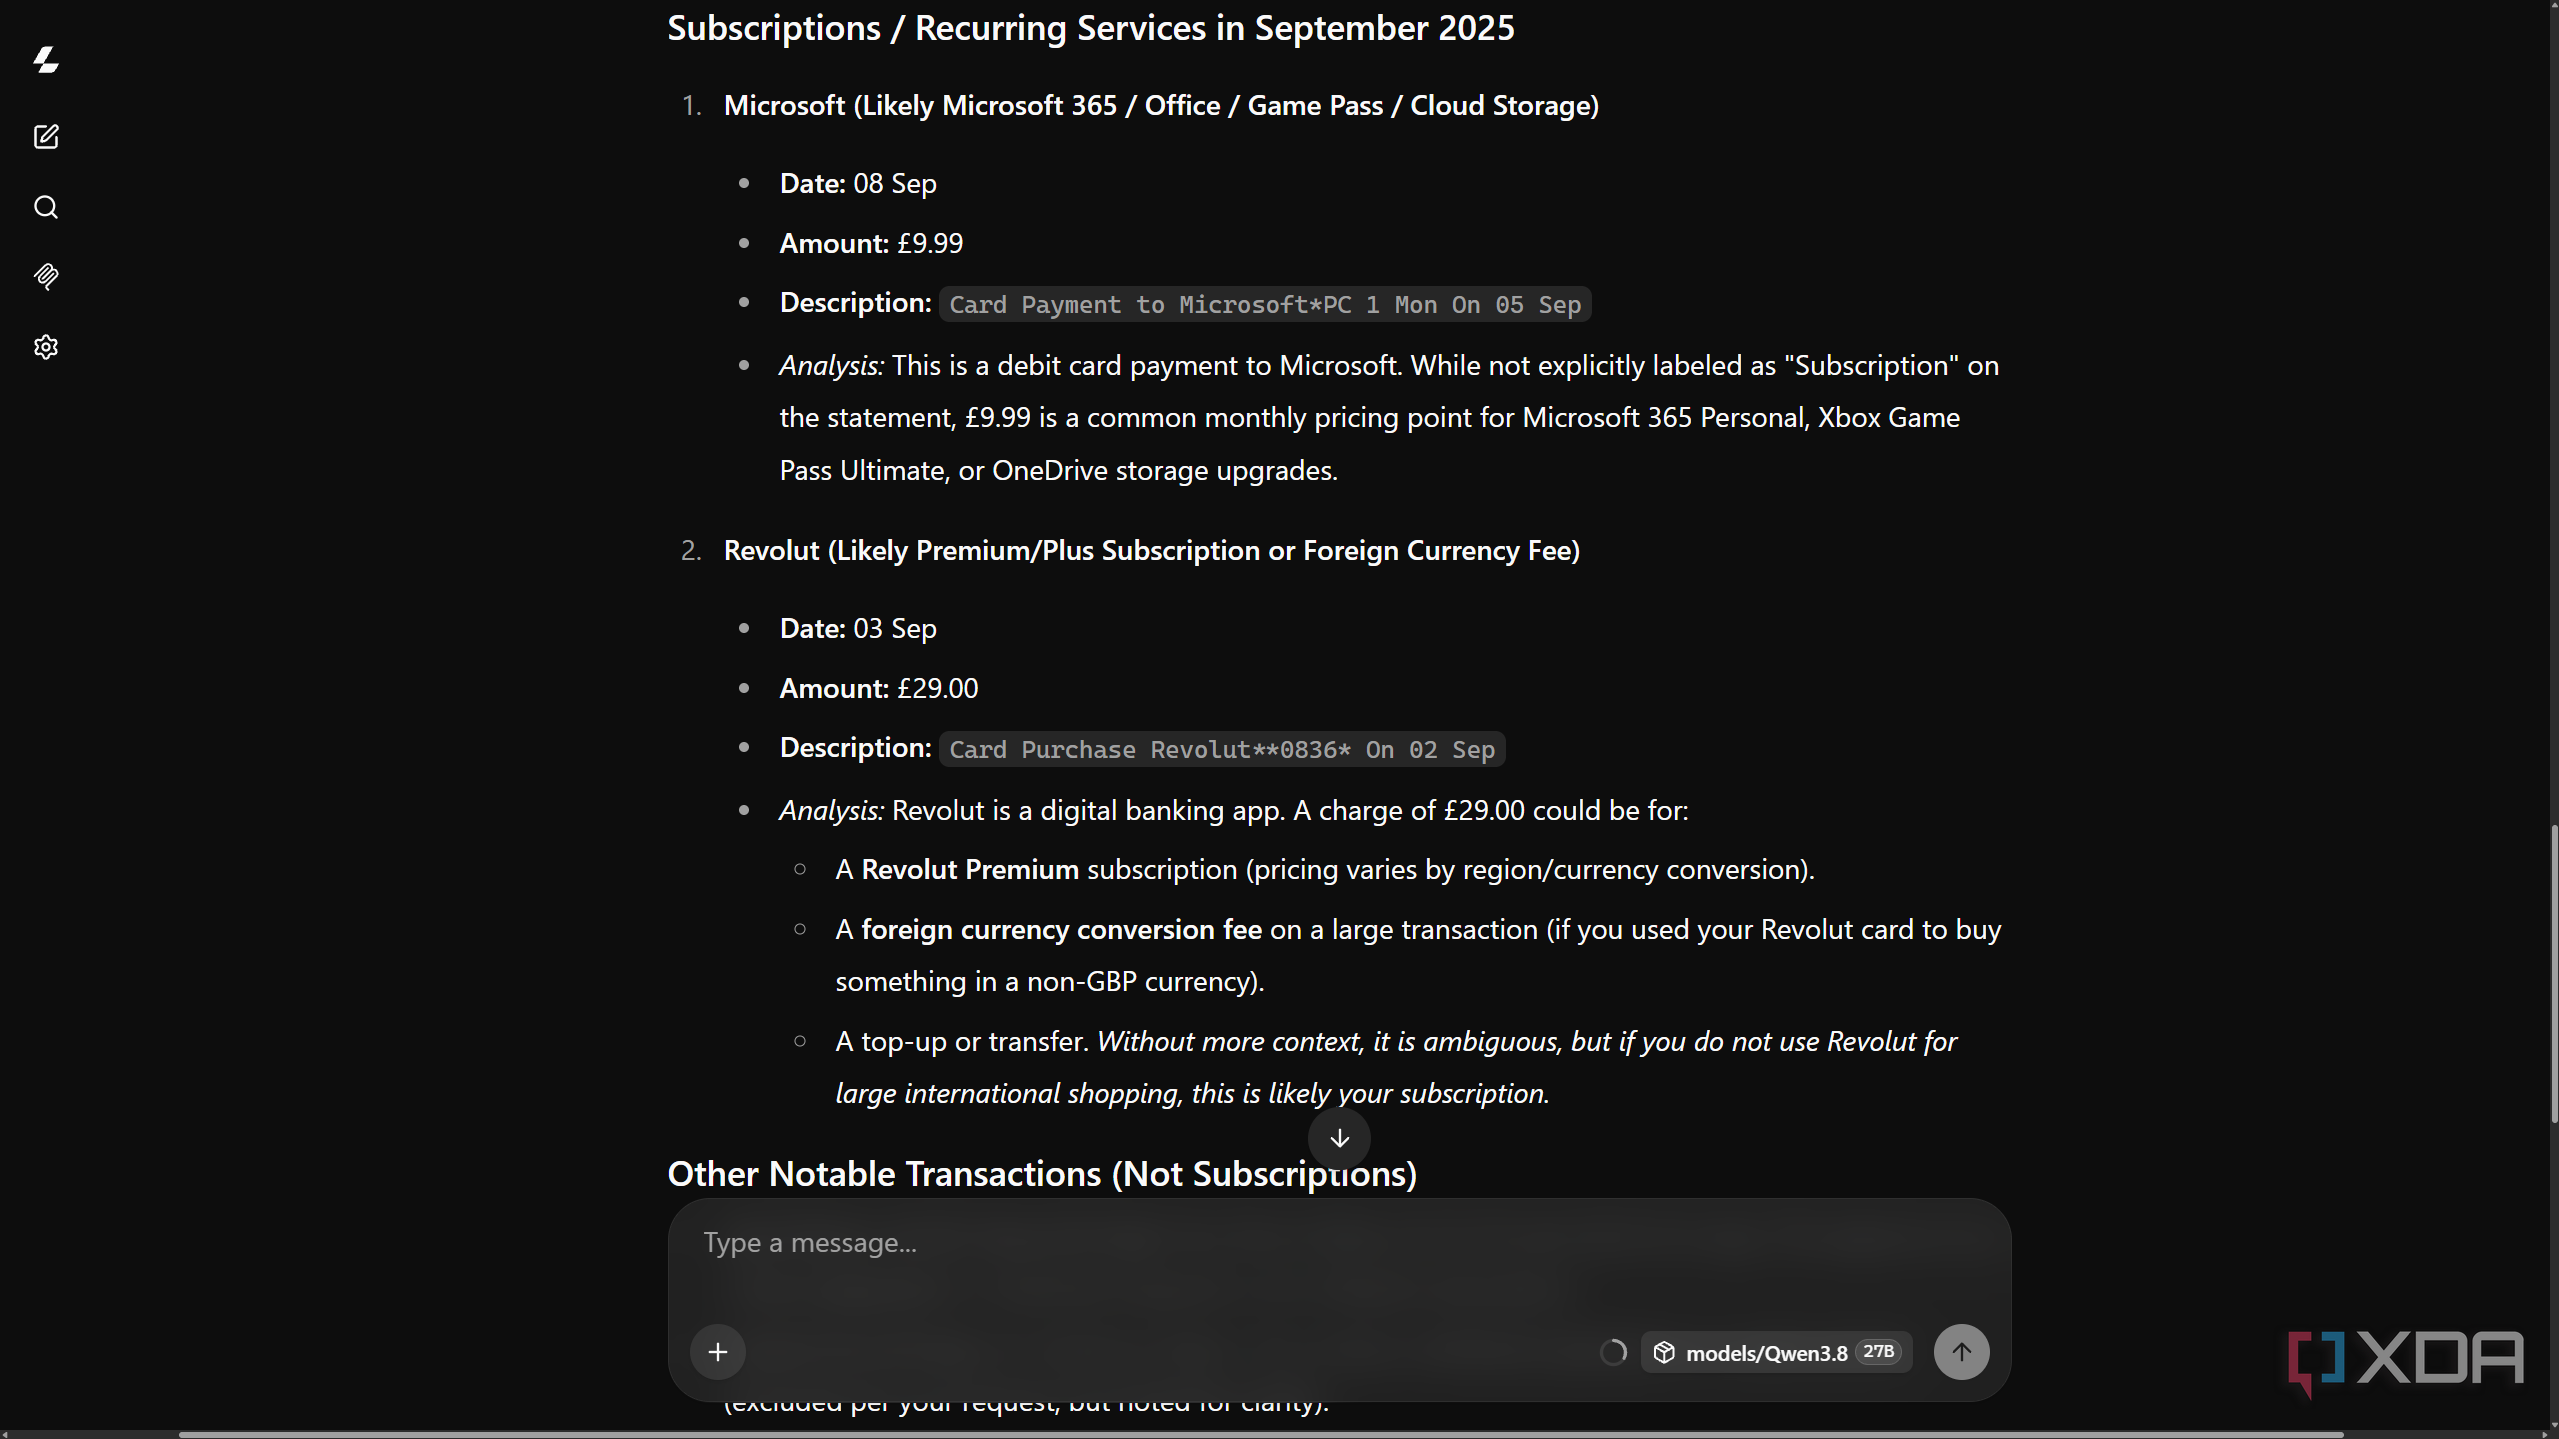
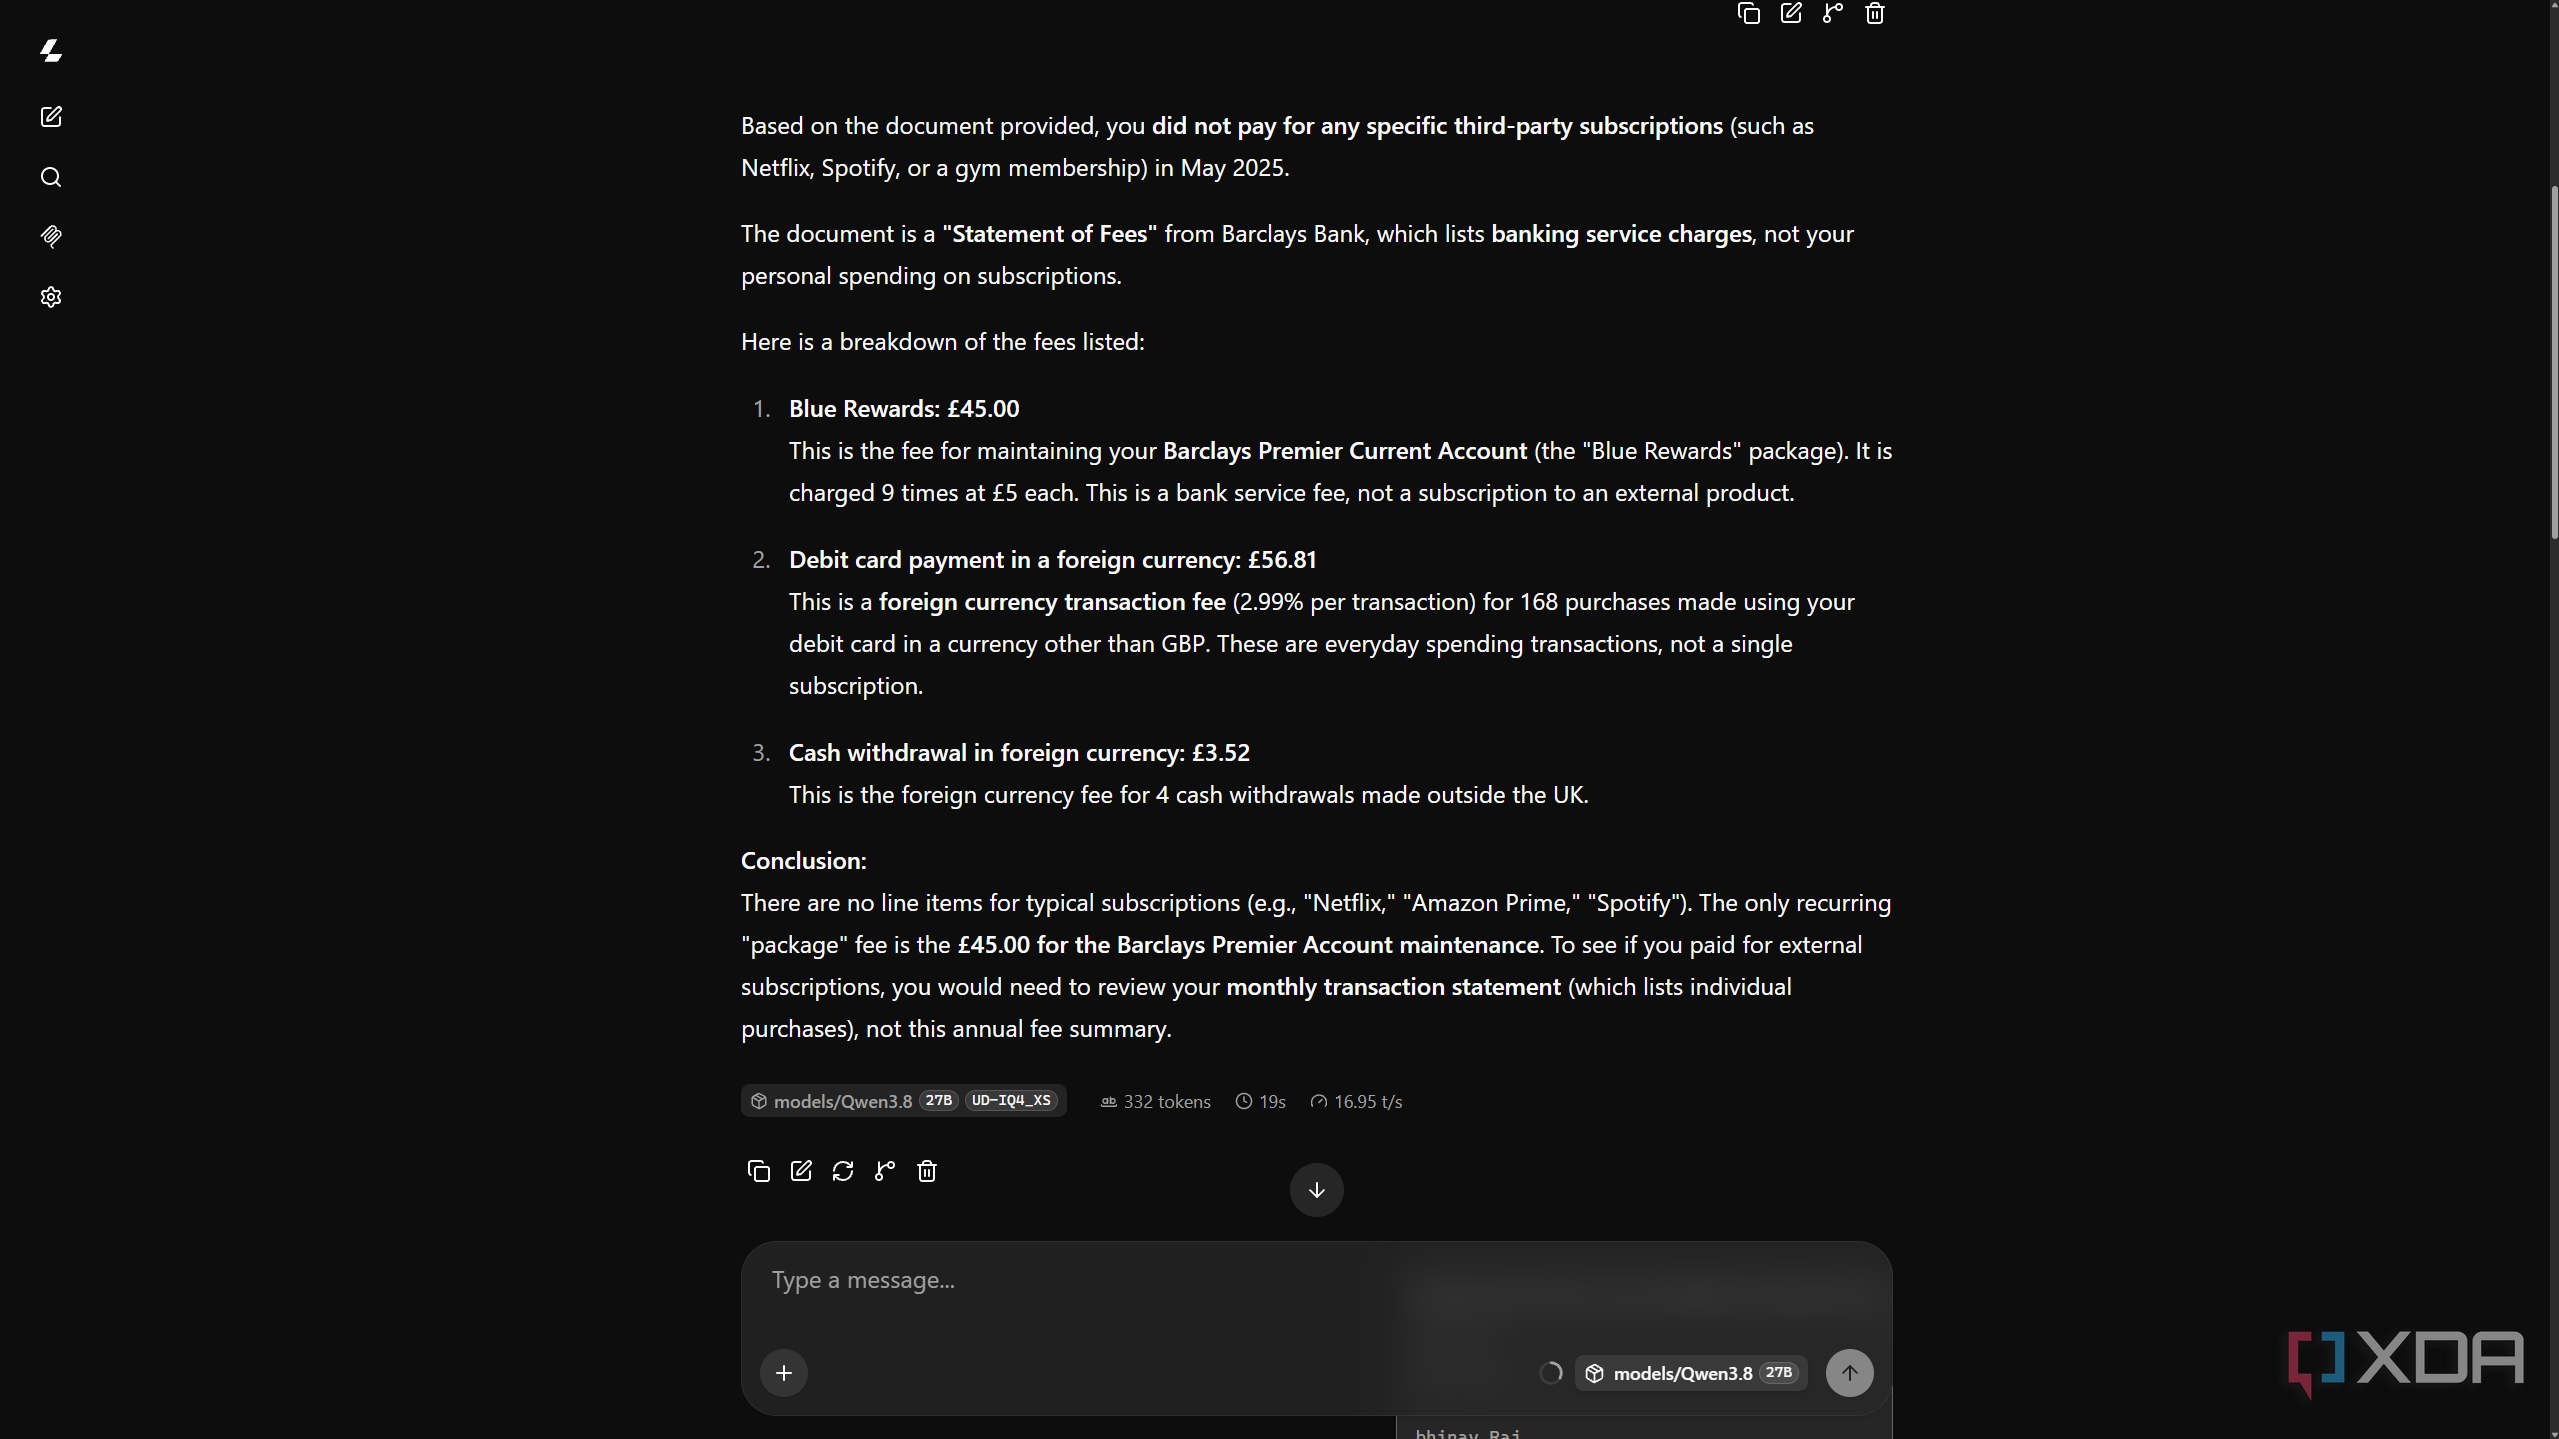
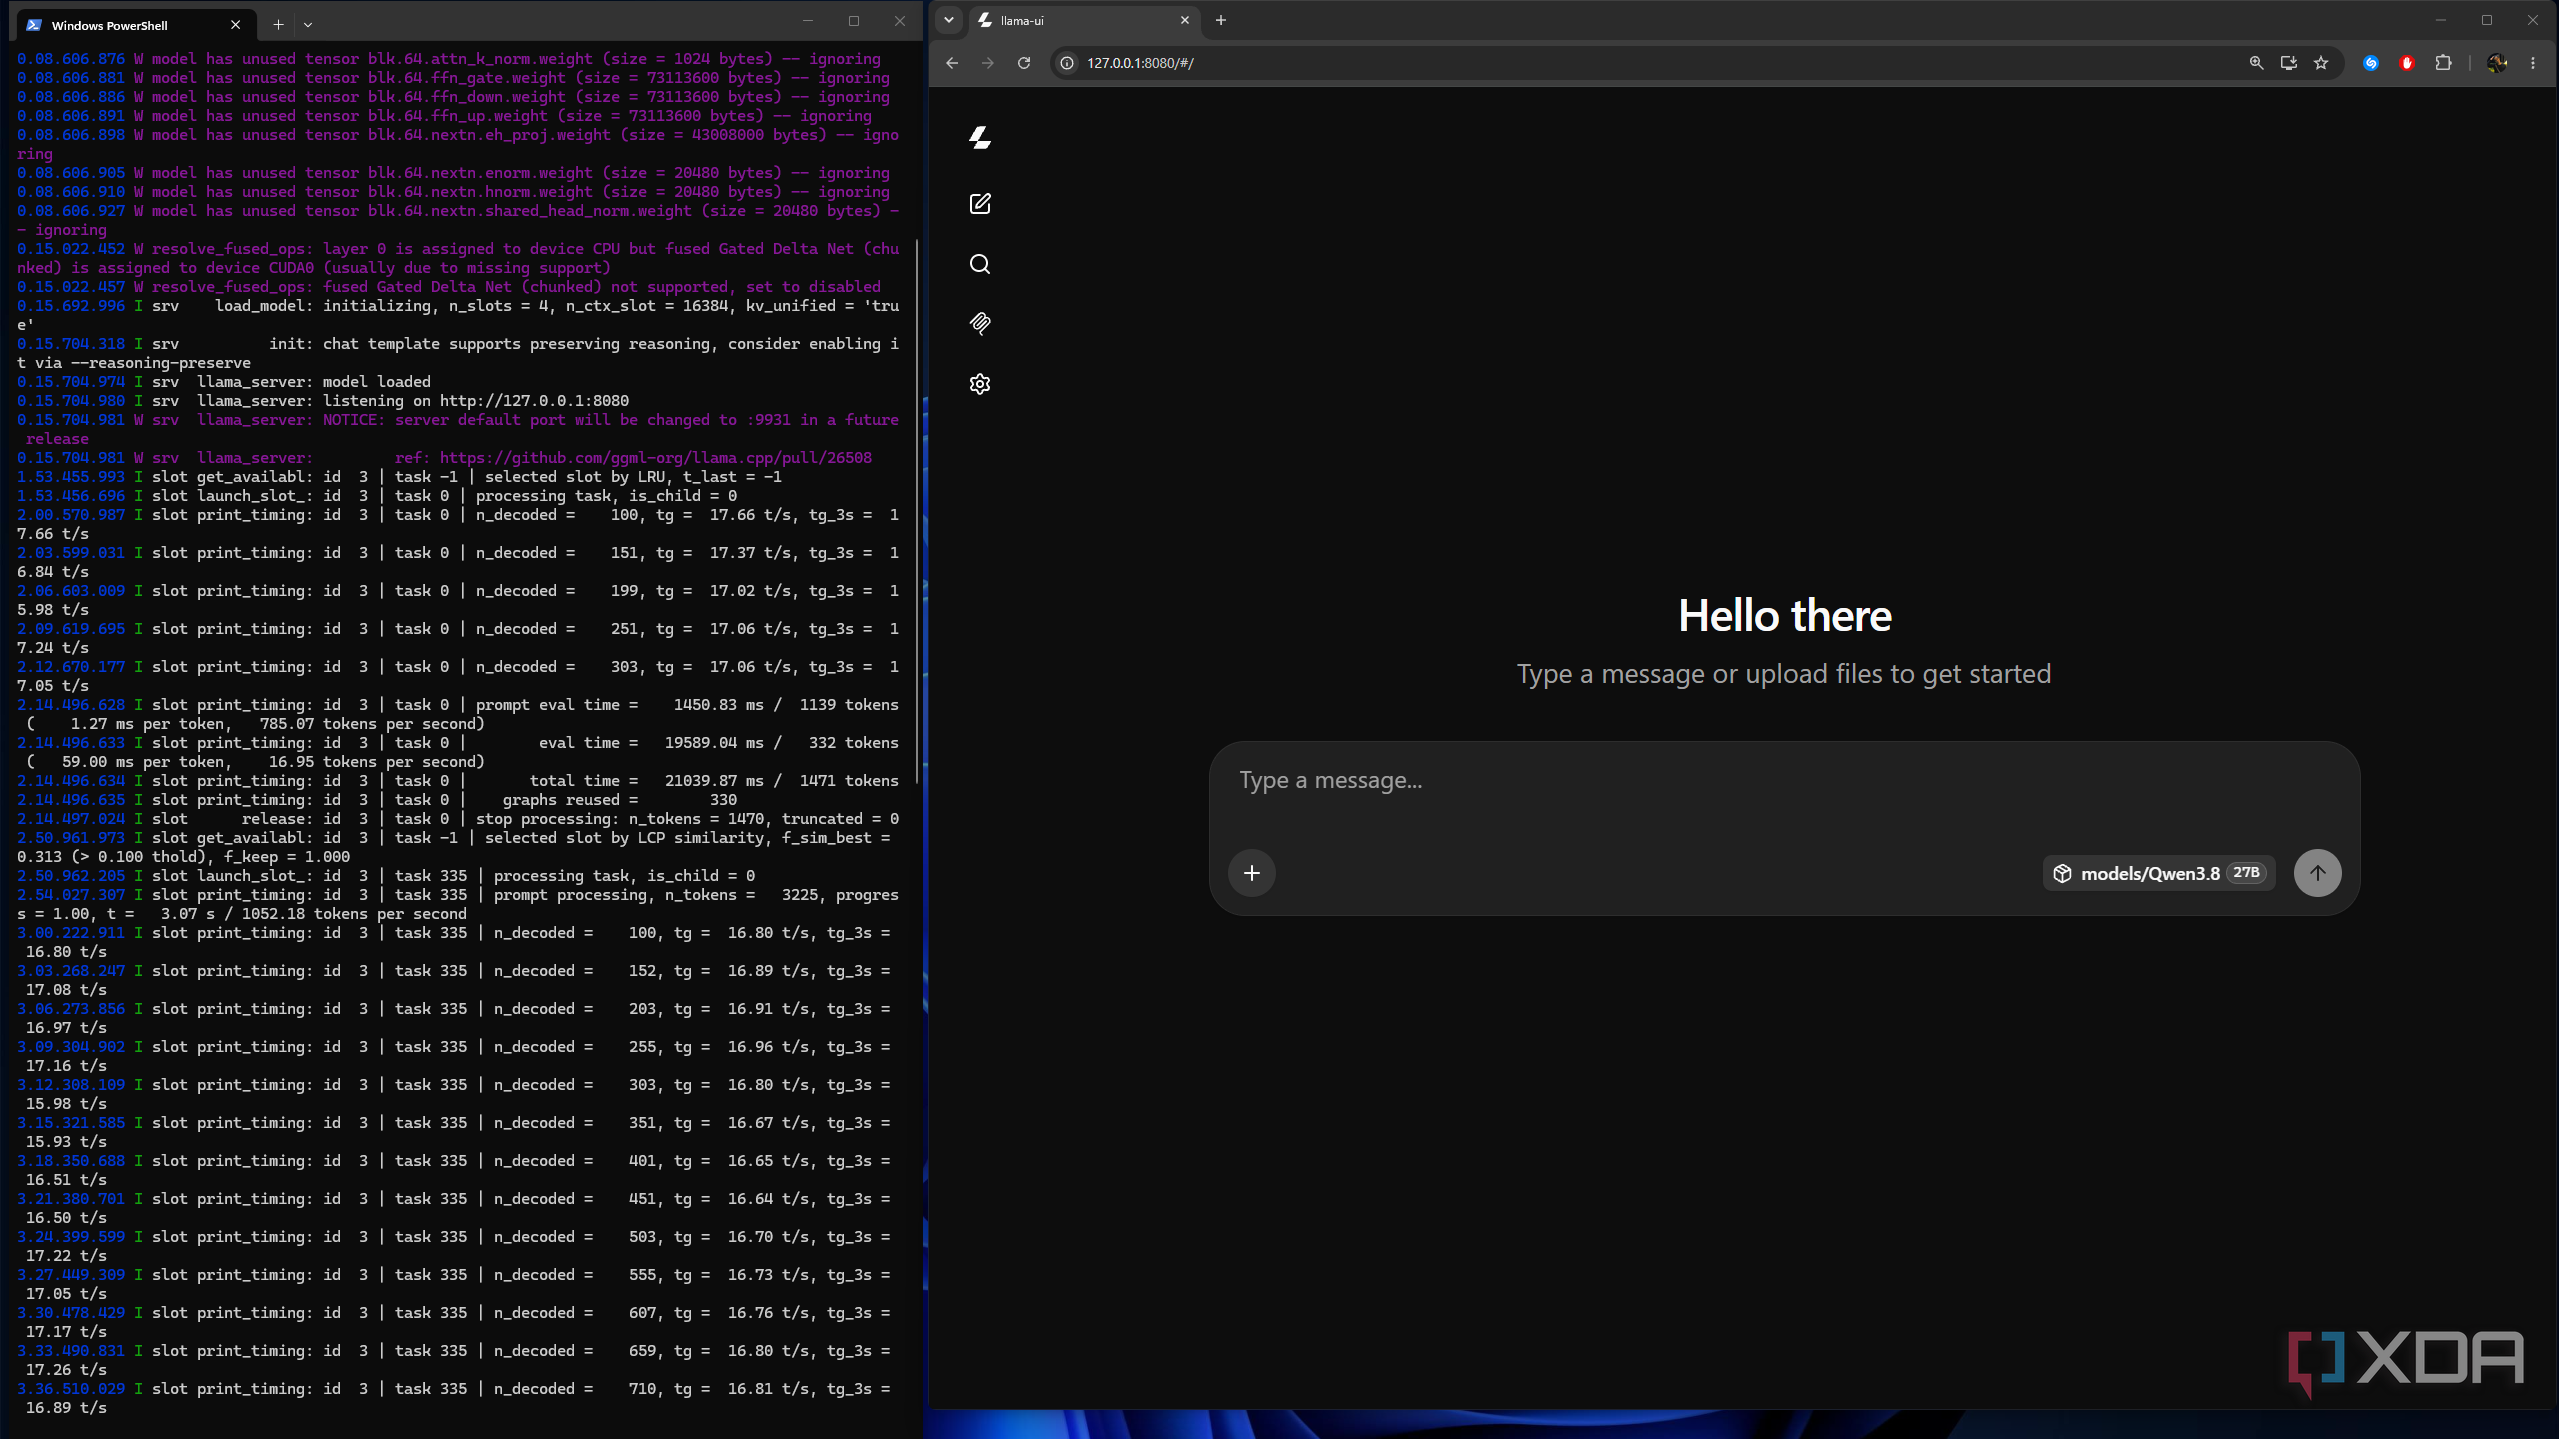
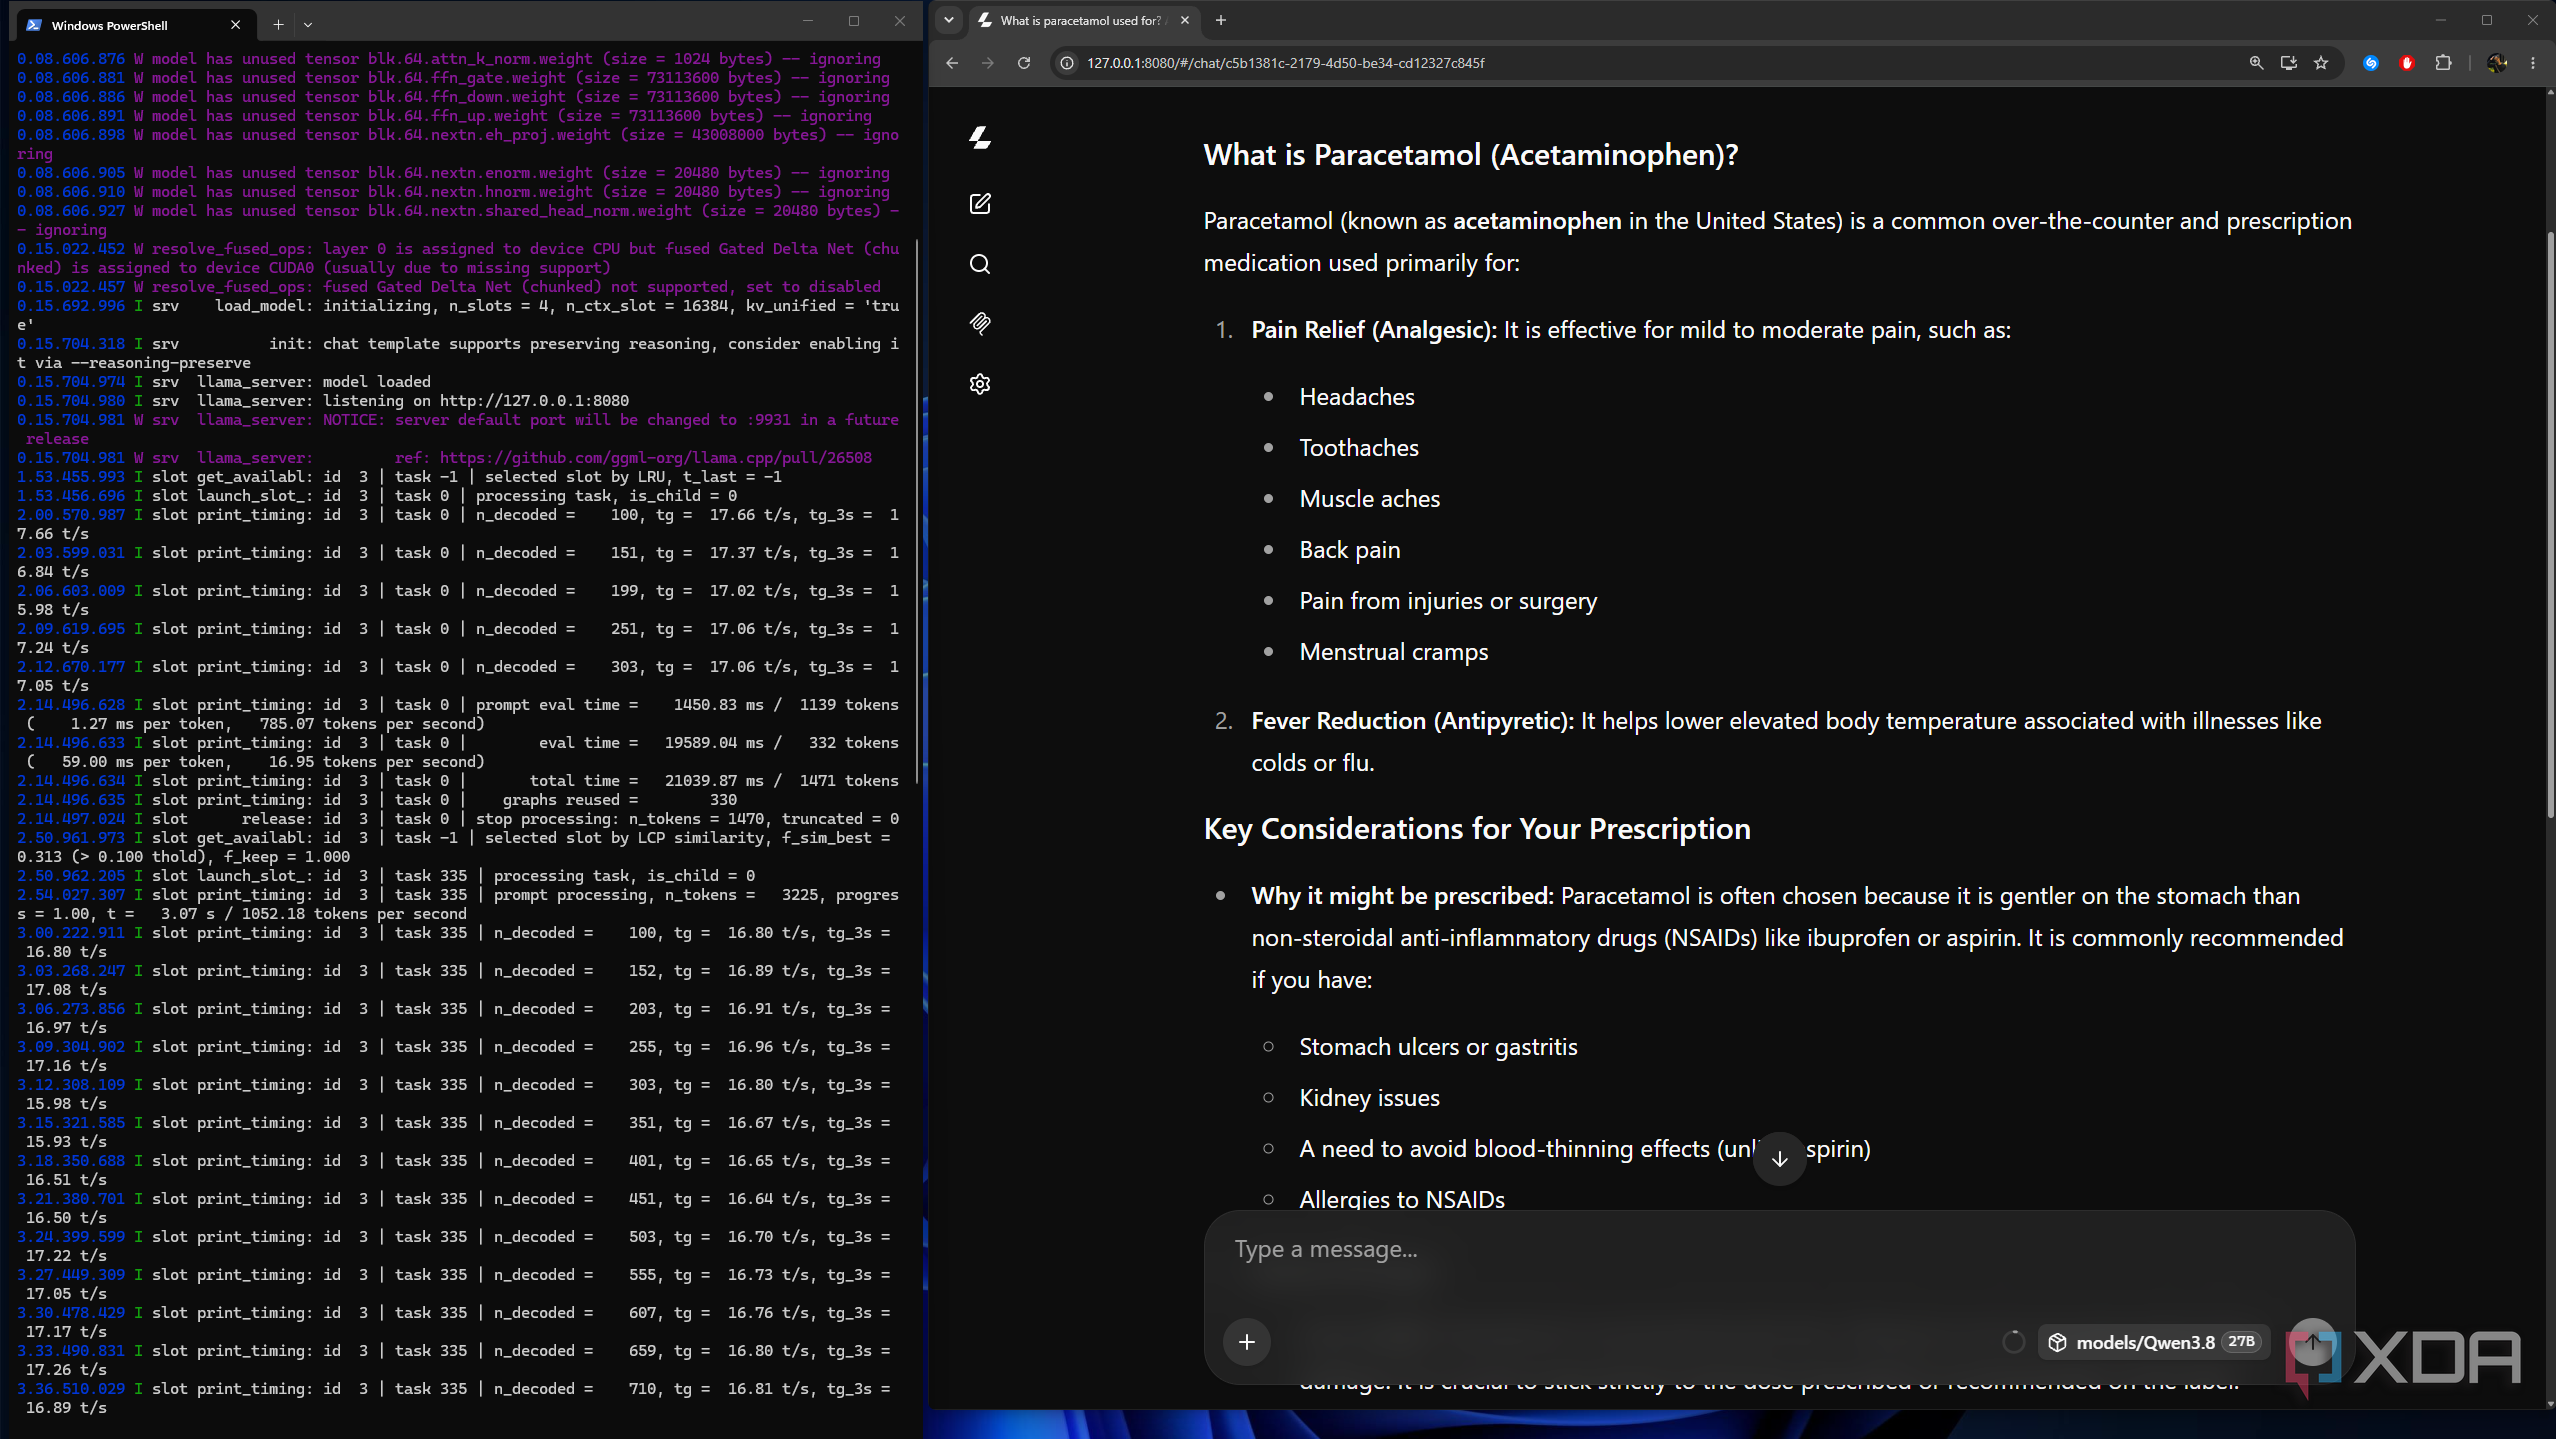
The most liberating aspect about running my local model on my own machine isn't the full control that I have over the model's reasoning, size, or capability (although I've come to appreciate all three), but it's the fact that I can go to bed every night knowing that my data has never left my PC. My prompts go into llama.cpp's web interface, the response comes back, and there's no trail, no monitoring, and no flags that give license to a third party to audit my conversations.
Without that anxiety, there's a surprising lot of things that I can put in front of my model. I can hand it a year of bank statements and ask it to tag every subscription service I've forgotten about, I can paste a lab report and query what the acronyms mean before I see a doctor, or dump my tax spreadsheet and have it flag the deductions that I missed. A growing number of users have found such use cases for local LLMs, and a growing number have come to appreciate the liberty.
With local AI, my prompts go into llama.cpp's web interface, the response comes back, and there's no trail, no monitoring, and no flags that give license to a third party to audit my conversations.
No major cloud AI provider offers ZDR to everyday customers
Which meant my chats and my data sat on their servers, by default
Out of the three major cloud AI service providers, including Anthropic, Google, and OpenAI, none offer zero data retention by default, and consumer plans don't offer it at all.
On Anthropic, ZDR is an opt-in arrangement for enterprise, Claude Platform, and API customers who negotiate it with the sales team on a per-organization basis. Even then, inputs and outputs can be retained for up to two years if Claude's automated trust and safety systems flag a session. For consumers like myself paying $20 for Claude Pro, there simply isn't an option for this at all.
Google, on the other hand, saves Gemini chats to Gemini Apps Activity for 18 months as default, and human reviewers can read anonymized snippets through this. And if you're thinking that simply turning activity off would solve the problem, then you're just as wrong as I initially was. Google still holds conversations for 72 hours for monitoring before dropping them. On the Gemini developer API, prompts persist in the abuse logs for a default of 55 days.
On OpenAI's platform, ChatGPT Free, Plus, and Pro, save chats indefinitely until you manually delete them, and conversations may feed training unless you turn it off. Though ZDR exists on the API, it only exists for approved customers, and it never applies to ChatGPT itself.
Cloud models have developed a tier problem lately
You can use them for free, but the best models start at $20

A question any reasonable user would ask going through all of this is, "Why not just use the free tiers of cloud models?", and that is a question that I've asked myself time and again. The most recent problem is the fact that capability is being gatekept behind a paywall, and lately it seems that the gates have been closing fast this year, which has become a pattern amongst cloud AI service providers.
On Claude's free plan, you don't get access to any Opus or Fable models at all. These are the models a user reaches for to handle hard reasoning, complex app development, or long-document work. Free users only get access to Sonnet or Haiku, which, while capable, aren't at the top of the stack.
Google recently made this argument for me. On October 9, it revoked free users' access to Gemini 3.6 Flash and Gemini 3.1 Pro, leaving the free tier with Gemini 3.5 Flash-lite, which is the smallest model in the family. Even the users paying $4.99 a month lost access to Pro, which now costs $19.99 through the AI Pro plan. This trend has led to the rise of a serious capability divide between users, which means that paying users get access to a different standard of service entirely, which wasn't the case a few months ago.
Unlike cloud services where the best models are kept away until you pay, you get the full capability of a local model right when it's loaded into your VRAM. That gives me more of a reason to always keep a 27B model file on my desktop.
Unlike cloud services where the best models are kept away until you pay, you get the full capability of a local model right when it's loaded into your VRAM.
I'm not done with cloud AI, but I have a safer way to use AI after all
One of the most concerning aspects of opening up my sensitive data to cloud models is guessing what it's being used for, what it's training, and where it can show up following an adverse event. I've previously talked about how a normal user over years shares and dumps far more information on the AI platform of their choice than they ever would on a search engine or an online forum, which makes them more vulnerable as their dependence rises.
It also has to be taken into account that AI isn't profitable yet, and it makes one wonder how major providers will get there. OpenAI recently rolled out ads to users on Free and Go tiers, and keeping personal information away from advertisers becomes an act of trusting a corporation and that its policy won't change with time. A local model running on my own PC is the only option right now where that level of trust isn't necessary.