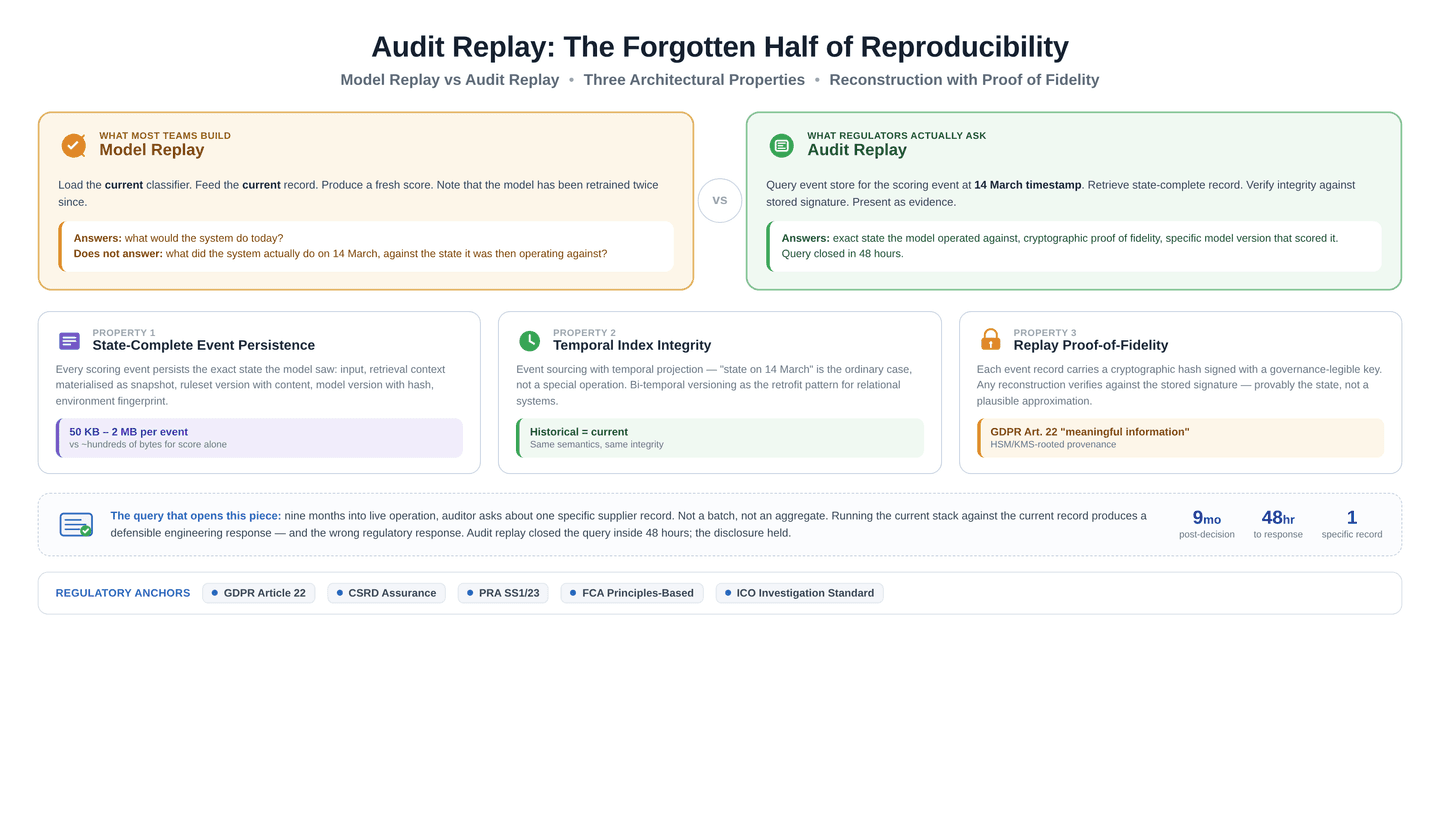
Reproducibility isn't rerunning the model. It's reconstructing a specific past decision — as it was made, against the state that produced it — without invoking the model at all. Most enterprise AI systems can do the first. Almost none can do the second. And the second is the one regulators are asking about.
This is article 10 in a series on the engineering economics of regulated AI. Prior pieces have covered provenance graphs, multimodal validation for climate risk, runtime enforcement, the reproducibility crisis, attribution stability, deterministic orchestration, the cost model for auditable AI, and the escalation layer that produces the persisted state audit replay operates against. The next piece will address model version pinning as a regulatory primitive — why "we upgraded to a newer model" is the wrong answer to a compliance query, and what the right architectural pattern looks like.
Nine months into the live operation of the climate-risk pipeline I designed for the DCarbon client engagement through SustainGRC, an auditor sent through a query on a single supplier record. Not a batch. Not an aggregate. One specific supplier, one specific quarter, one specific classification decision that had flowed through to a client's disclosure filing. The question was narrow and precise: "On the date this record was scored, what was the exact state the system was operating against, and what evidence supported the classification you filed?"
The engineering team's first instinct — the instinct almost every AI team's first instinct will be — was to re-run the model against the record. Load the current version of the classifier, feed it the record, produce the score, present it as the answer. This is what most reproducibility discourse in enterprise AI means when it uses the word: "we can regenerate the output."
But that is not what the auditor asked. The auditor asked what the state was at the moment of scoring, which had happened seven months earlier. The classifier had been retrained twice since then. The retrieval corpus had been updated. The escalation-rules module had gone through three versioned iterations. The supplier's own record had been touched by four intervening events, only one of which was material to the classification in question. Running the current stack against the current record produces a fresh answer that is genuinely defensible as today's answer. It does not answer the question the auditor asked. And under the disclosure integrity requirements the client was operating under, a fresh answer produced retrospectively is not admissible as evidence of what was known at the time the disclosure was filed.
The response the pipeline was capable of producing — because the escalation layer had been designed with complete state persistence, as the previous piece in this series discussed — was different. It reconstructed the exact feature vector the classifier had seen, the exact retrieval context that had been assembled, the version of the ruleset that was active, the version of the model that scored it, the fingerprint of the runtime environment, and the specific evidence bundle that had been persisted alongside the scoring event. It presented these as the answer, together with a deterministic proof that these were the artefacts the model had actually operated against, not a reconstruction from partial logs. The auditor accepted the response inside forty-eight hours. The disclosure held.
The difference between these two responses is the difference between model replay and audit replay, and it is one of the most consequential architectural distinctions in regulated AI that almost no enterprise deployment is currently designed to make. This piece is about why that distinction matters, what audit replay actually requires as an engineering discipline, and what happens to organisations that discover the gap only when the auditor's letter arrives.
Why model replay is not enough
The dominant framing of reproducibility in production AI treats the question as one of output regeneration. Given the same inputs, the model produces the same outputs. Bit-for-bit determinism is the gold standard. Statistical determinism (same distribution over many runs) is the acceptable fallback. Both are meaningful engineering achievements. Neither is what audit-defensibility requires.
The regulatory question is not can you produce the same output now — it is can you produce, as evidence, the exact state that produced a specific past output, and can you prove that state is the state the model actually operated against. These are different specifications. The first is a property of the model and its execution environment. The second is a property of the persistence architecture surrounding the model. The first is solved by good MLOps discipline. The second requires a specific architectural commitment that most enterprise AI systems have not made.
The gap between these two commitments becomes visible under three specific pressures.
The first pressure is temporal separation. Regulatory queries typically arrive months to years after the decision they are asking about. The model that produced the decision may have been retired. The retrieval corpus may have been re-indexed. The ruleset may have been superseded. The infrastructure may have been migrated. Model replay against the current stack answers what would the system do today with the same inputs, which is a different question from what did the system actually do on the date in question against the state it was operating against. Under GDPR Article 22, which grants data subjects the right to obtain "meaningful information about the logic involved" in a specific past decision, the answer must reference the state the decision was made against, not the state the system is in now.
The second pressure is state entanglement. Enterprise AI systems rarely operate as pure functions. Their outputs depend on retrieval context that was assembled from a corpus that changes, on ruleset versions that evolve, on upstream feature pipelines that themselves depend on data sources that update. Bit-for-bit output regeneration would require pinning every one of these upstream dependencies to the exact state they were in at the moment of scoring — which is what audit replay requires but model replay typically does not. Most production systems can pin the model. Fewer can pin the retrieval corpus. Even fewer can pin the ruleset. Almost none can pin all three simultaneously against a specific historical timestamp.
The third pressure is evidentiary standing. When an auditor accepts a reconstructed answer as evidence of what was known at the time, the reconstruction must itself carry proof that it is faithful — that the state presented as the answer is the state the model actually saw, not a plausible approximation. This proof is not incidental. Under CSRD assurance requirements and the audit-trail obligations increasingly attached to AI-assisted disclosure preparation, a reconstruction whose fidelity cannot be independently verified is a reconstruction whose evidentiary standing is contested. Model replay produces outputs. Audit replay produces outputs with proof of state-fidelity, and the proof is often more difficult to engineer than the reconstruction itself.
These three pressures compound. Temporal separation makes model replay progressively less answerable to the actual question. State entanglement makes bit-for-bit regeneration progressively harder to achieve. Evidentiary standing means that even where regeneration is achievable, it does not satisfy the underlying regulatory ask. An organisation that has invested in model reproducibility but not in audit replay has bought the wrong insurance for the risk it is actually exposed to.
What audit replay actually requires as an engineering discipline
The pattern I'll describe here was developed through my independent research and refined during the DCarbon client engagement delivered via SustainGRC, and has been carried into the PinkMate R&D work on how regulated-AI patterns port down to smaller organisations. It treats audit replay as an engineering commitment with three specific properties: state-complete event persistence, temporal index integrity, and replay proof-of-fidelity. Each addresses one of the three pressures named above. Each has engineering cost that is meaningful but bounded. And each is load-bearing — an audit-replay architecture that has two of the three properties is an architecture that will fail the specific class of regulatory query it is designed to answer.
State-complete event persistence
The first property is that every decision-producing event in the system persists, at the moment of decision, the complete state the decision was made against. Not a reference to state. Not a pointer that resolves against the current version of upstream systems. The state itself, materialised and stored, as an immutable event record.
This is a stronger claim than "we log everything," and it is a stronger claim than the state persistence that the escalation layer in the previous piece required. Escalation-layer persistence captures the state a reviewer would need to exercise substantive oversight — meaningful, but not necessarily complete. Audit-replay persistence must capture everything the model saw at the moment of scoring, in a form that can be presented as evidence months later without further reconstruction.
Concretely, this means: the input record as it existed at scoring time (not the current version); the retrieval context materialised as a snapshot rather than a query-and-reconstruct pattern; the active ruleset version with its content, not just its identifier; the model version with a cryptographic hash of the deployed weights; the runtime environment fingerprint including library versions, hardware class, and any determinism-relevant configuration; and the scoring event itself as a signed, timestamped record whose integrity can be independently verified.
The storage implications are meaningful. In the DCarbon engagement pipeline I built, state-complete event persistence for each scoring event typically ran between fifty kilobytes and two megabytes depending on the size of the retrieval context, versus a few hundred bytes for the score itself. Aggregate storage cost was measurable but not prohibitive — on the order of a few percent of the total infrastructure cost of the pipeline — and materially cheaper than the cost of failing to answer a specific regulatory query.
The design principle to hold is that audit-replay persistence is a write-once commitment. The event record must be immutable, cryptographically signed if the regulatory context requires it, and stored in a system whose access controls and retention policies are governance-legible. Persistence in a mutable database is persistence that a sceptical auditor can rightfully question; persistence in a write-once event store with clear provenance is persistence that carries evidentiary standing.
Temporal index integrity
The second property addresses the state-entanglement pressure. Audit replay must be able to answer "what was the system state on date D, at time T, for entity E" with the same integrity for D six months ago as for D yesterday. This requires temporal indexing to be a first-class property of the persistence architecture, not an operational afterthought.
Most production databases treat "time" as a column. Rows are updated in place; historical values are lost unless explicitly captured. This design pattern is fine for operational systems whose questions are always about the present state. It is architecturally incompatible with audit replay, which asks questions about past states that no longer exist in the current row.
The architectural pattern that answers this is event sourcing with temporal projection — an approach where the source of truth is a stream of events, and current state is a projection computed from events up to a given timestamp. Under this pattern, asking "what was the state on 14 March" is not a special operation; it is the ordinary case, computed by replaying events up to that timestamp. Asking "what is the state now" is the same operation with the timestamp set to now. Both queries have the same semantics, the same integrity properties, and the same cost profile.
For teams operating on relational databases without event-sourcing infrastructure, the practical pattern is bi-temporal versioning — storing every row with two temporal dimensions: the transaction time (when the row was written) and the valid time (the time the row's content applies to). This makes historical queries expressible in ordinary SQL and preserves the ability to reconstruct past states without a full architectural rewrite. It is not as clean as event sourcing, but it is materially achievable in a system that was not originally designed with audit replay in mind.
The engineering discipline here is that temporal integrity is a property of the schema and the write path, not a property of the query path. A system whose writes discard historical values cannot recover them through cleverer queries. A system whose writes preserve every version with bi-temporal metadata can support audit-replay queries with no additional infrastructure. The commitment must be made at the write path, and it must be made early enough that the discipline is retrofitted only against a bounded fraction of the system's data.
Replay proof-of-fidelity
The third property addresses the evidentiary-standing pressure. When the system produces a reconstruction as evidence for an audit query, the reconstruction must carry proof that it is faithful to the original state, not a plausible reconstruction from partial data.
The mechanism is straightforward in principle and demanding in practice: at the moment of decision, the state-complete event record is written together with a cryptographic hash of its content. The hash is signed with a key whose provenance is independently verifiable. Any subsequent reconstruction can be checked against the stored hash — if the reconstruction matches the hash, it is provably the state that was recorded; if it does not, the reconstruction is either incomplete or has been tampered with.
The demanding part is that the signing key must itself be governance-legible. A key held only in the same infrastructure that hosts the events is a key whose integrity a sceptical auditor can rightfully question. Standard practice is to use a hardware security module or a key management service whose provenance the organisation's governance function has independently validated. This is not free, but the cost is modest compared to the evidentiary value it produces.
There is a secondary property worth naming. Under the increasingly literal reading of GDPR Article 22 that European regulators are applying, the "meaningful information about the logic involved" obligation is being interpreted to require not just an explanation of the decision, but evidence that the explanation is faithful to the actual computation. A signed state-complete event record, together with a deterministic reconstruction that hashes to the stored signature, is arguably the most defensible pattern currently available for satisfying this requirement in production AI systems. Organisations that have implemented this pattern have a precise, mechanical answer to Article 22 subject requests. Organisations that have not are answering with best-effort reconstructions whose fidelity is contested every time a subject challenges them.
Where model replay and audit replay diverge in practice
The pattern's clearest expression is in how the two forms of replay behave under a specific regulatory query. Consider the earlier scenario — the auditor asking about a single supplier record scored seven months prior.
Under model replay, the engineering response is: Load the current classifier version. Retrieve the current supplier record. Assemble a retrieval context from the current corpus. Score. Present the output. Note in the response that the model has been retrained twice since the original decision and that the retrieval corpus has been updated, but that the current output is consistent with what a fresh evaluation would produce.
This is a defensible engineering response. It is not a defensible regulatory response.
Under audit replay, the engineering response is: Query the event store for the scoring event corresponding to the supplier record and date. Retrieve the persisted state-complete event record. Verify its integrity against the stored signature. Present the persisted state as the evidence base the model operated against, together with the score the model produced and the model version that produced it. Note that the current model version differs, but that the response is answering the question as asked — what was the state on the date of the original decision.
The regulatory value of these two responses is materially different. Under CSRD assurance, under GDPR Article 22, under the retrospective defensibility expectations of PRA SS1/23, and under the FCA's principles-based approach to demonstrable AI governance, the second response is the one that closes the query. The first response opens further questions.
The engineering cost of being able to produce the second response — rather than the first — is the cost of the three properties above. That cost is bounded, quantifiable, and materially smaller than the cost of failing a single high-stakes audit query.
The mid-market pattern
The pattern is: persist state-complete event records as PostgreSQL JSON blobs in an append-only table with a bi-temporal index; sign hashes using a cloud KMS whose key access is separated from the application service account; produce audit replay responses by querying the event store and verifying the returned record's hash matches the stored signature. This can be built with a small engineering team on standard infrastructure. It carries a fraction of the operational complexity of a full event-sourced architecture. And it produces responses to audit queries with the same evidentiary properties that the more elaborate implementation produces.
The engineering discipline is not in the sophistication of the pattern. It is in the commitment to build the pattern before the auditor's query arrives. Retrofitting audit replay after the fact — reconstructing historical state from application logs, database backups, and pipeline code — is possible in principle but its fidelity is unverifiable in practice, which means its evidentiary standing is contested every time it is invoked. An organisation that adds audit replay in the third year of its AI deployment has evidence-quality reconstructions from year three onwards and best-effort reconstructions from years one and two. The regulator does not care which regime a specific query falls into; the regulator cares that the query is answered with fidelity.
What this pattern does not do
Audit replay reconstructs the state a decision was made against. It does not reconstruct the reasoning the model applied to that state, if the model is a stochastic-decoding LLM or a system whose reasoning is not itself deterministic given the state. This is a real limit. Under GDPR Article 22's meaningful-information requirement, the state is a substantial part of the answer, but for genuinely stochastic systems, the answer to "why this decision specifically" involves a probabilistic element that cannot be reduced to state alone.
The pattern that partially closes this gap is decision-trace persistence — capturing not just the state the model saw but the intermediate reasoning artefacts the model produced, where those artefacts are inspectable. For structured-output LLM patterns that emit reasoning traces before final outputs (a pattern I've discussed elsewhere in this series), the reasoning trace itself can be persisted as part of the state-complete event record. This is not the same as reproducing the model's internal computation, but it produces an artefact that satisfies the meaningful-information requirement more directly than the state alone.
For fully stochastic systems where the reasoning is not inspectable — the majority of embedding models, closed-weights LLMs used through opaque APIs, and any system whose decoding process is not itself producing capturable intermediate artefacts — audit replay produces the state but not the trace. This is a genuine limit and should be named in the deployment's governance documentation, not obscured in the audit response.
Where this is heading
The regulatory trajectory across Europe and the UK is toward more literal reading of retrospective defensibility requirements, not less. The gap between organisations that can produce audit-replay responses to specific queries and those that can only produce model-replay responses to general questions is going to become one of the most consequential dividing lines in regulated AI deployment over the next three years. On one side of that line are organisations whose AI systems are audit-defensible in a form that would satisfy an ICO investigation, an FCA principles-based review, a CSRD assurance engagement, or a PRA model risk examination. On the other side are organisations whose AI systems can regenerate outputs but cannot produce evidence of past specific decisions with verifiable fidelity.
The engineering commitment that puts an organisation on the right side of that line is not a technology purchase. It is an architectural discipline — state-complete event persistence, temporal index integrity, and replay proof-of-fidelity — that must be adopted at the write path and maintained consistently over the deployment's lifetime. The commitment can be adopted at meaningful engineering cost early or at prohibitive engineering cost late. The commitment cannot, in practice, be avoided.
The auditor's query that opened this piece is now the routine case, not the edge case. Regulatory bodies across sectors are increasingly capable of framing queries with the specificity that model replay cannot answer. The organisations that respond to those queries inside forty-eight hours with signed, state-complete reconstructions are the organisations whose disclosures hold. The organisations that produce fresh evaluations from current stacks and note that the model has since been retrained are the organisations whose disclosures do not.
The engineering discipline this piece is arguing for is not exotic. It is the specific architectural commitment that separates AI systems designed to answer what did we do from AI systems designed only to answer what would we do now. The distinction sounds semantic. It is architectural. And it is the distinction the next generation of regulatory queries will be built to expose.