
Ayush Pande is a PC hardware and gaming writer. When he's not working on a new article, you can find him with his head stuck inside a PC or tinkering with a server operating system. Besides computing, his interests include spending hours in long RPGs, yelling at his friends in co-op games, and practicing guitar.
When you think about locally-deployed AI models, bulky servers armed with cutting-edge graphics cards are probably the first things that come to mind. And considering how much computational power bulky LLMs need, you wouldn’t be far off the mark. But having tinkered with all sorts of wacky experiments over the past year, I’ve realized that heavy LLMs with dozens of billions of parameters aren’t the only AI models that can meet my productivity needs.
Heck, depending on your specific AI tasks, you don’t even need powerful hardware. Toss in a couple of edge models, and even a mere Raspberry Pi can drive useful AI tools with ease.
The Raspberry Pi 5 is fully capable of driving Gemma 4 E2B
And even its E4B sibling, albeit at lower performance
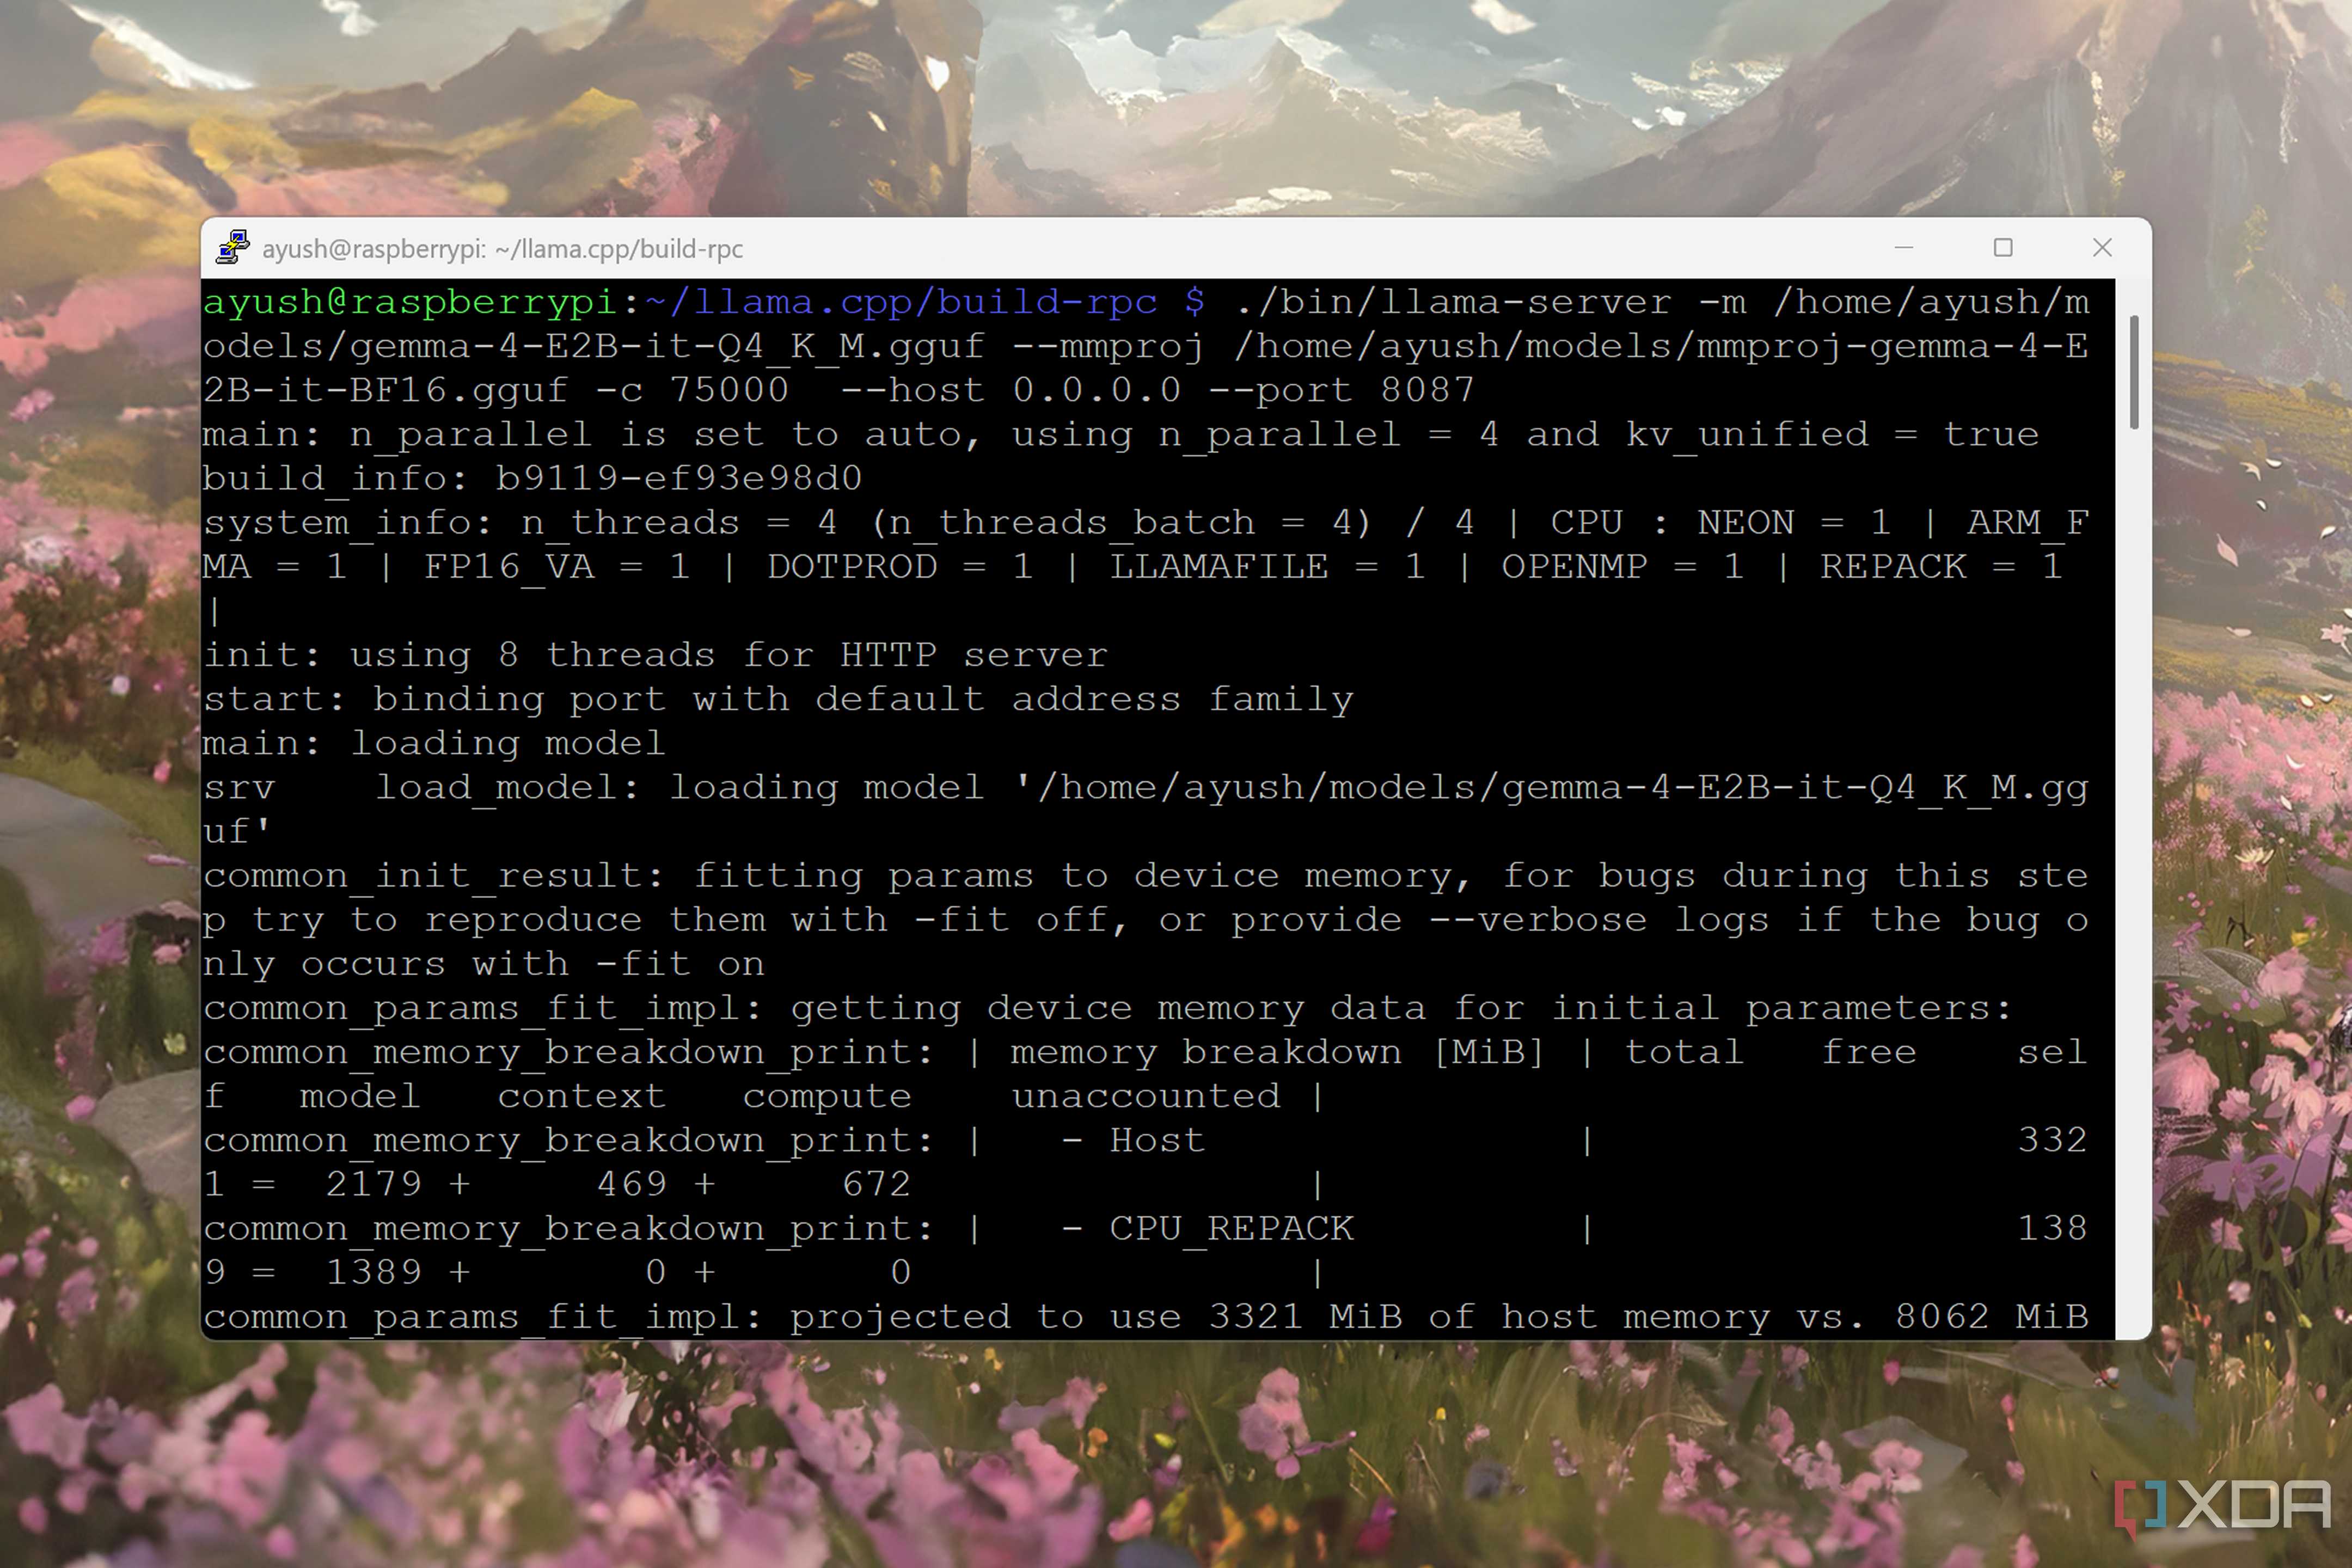
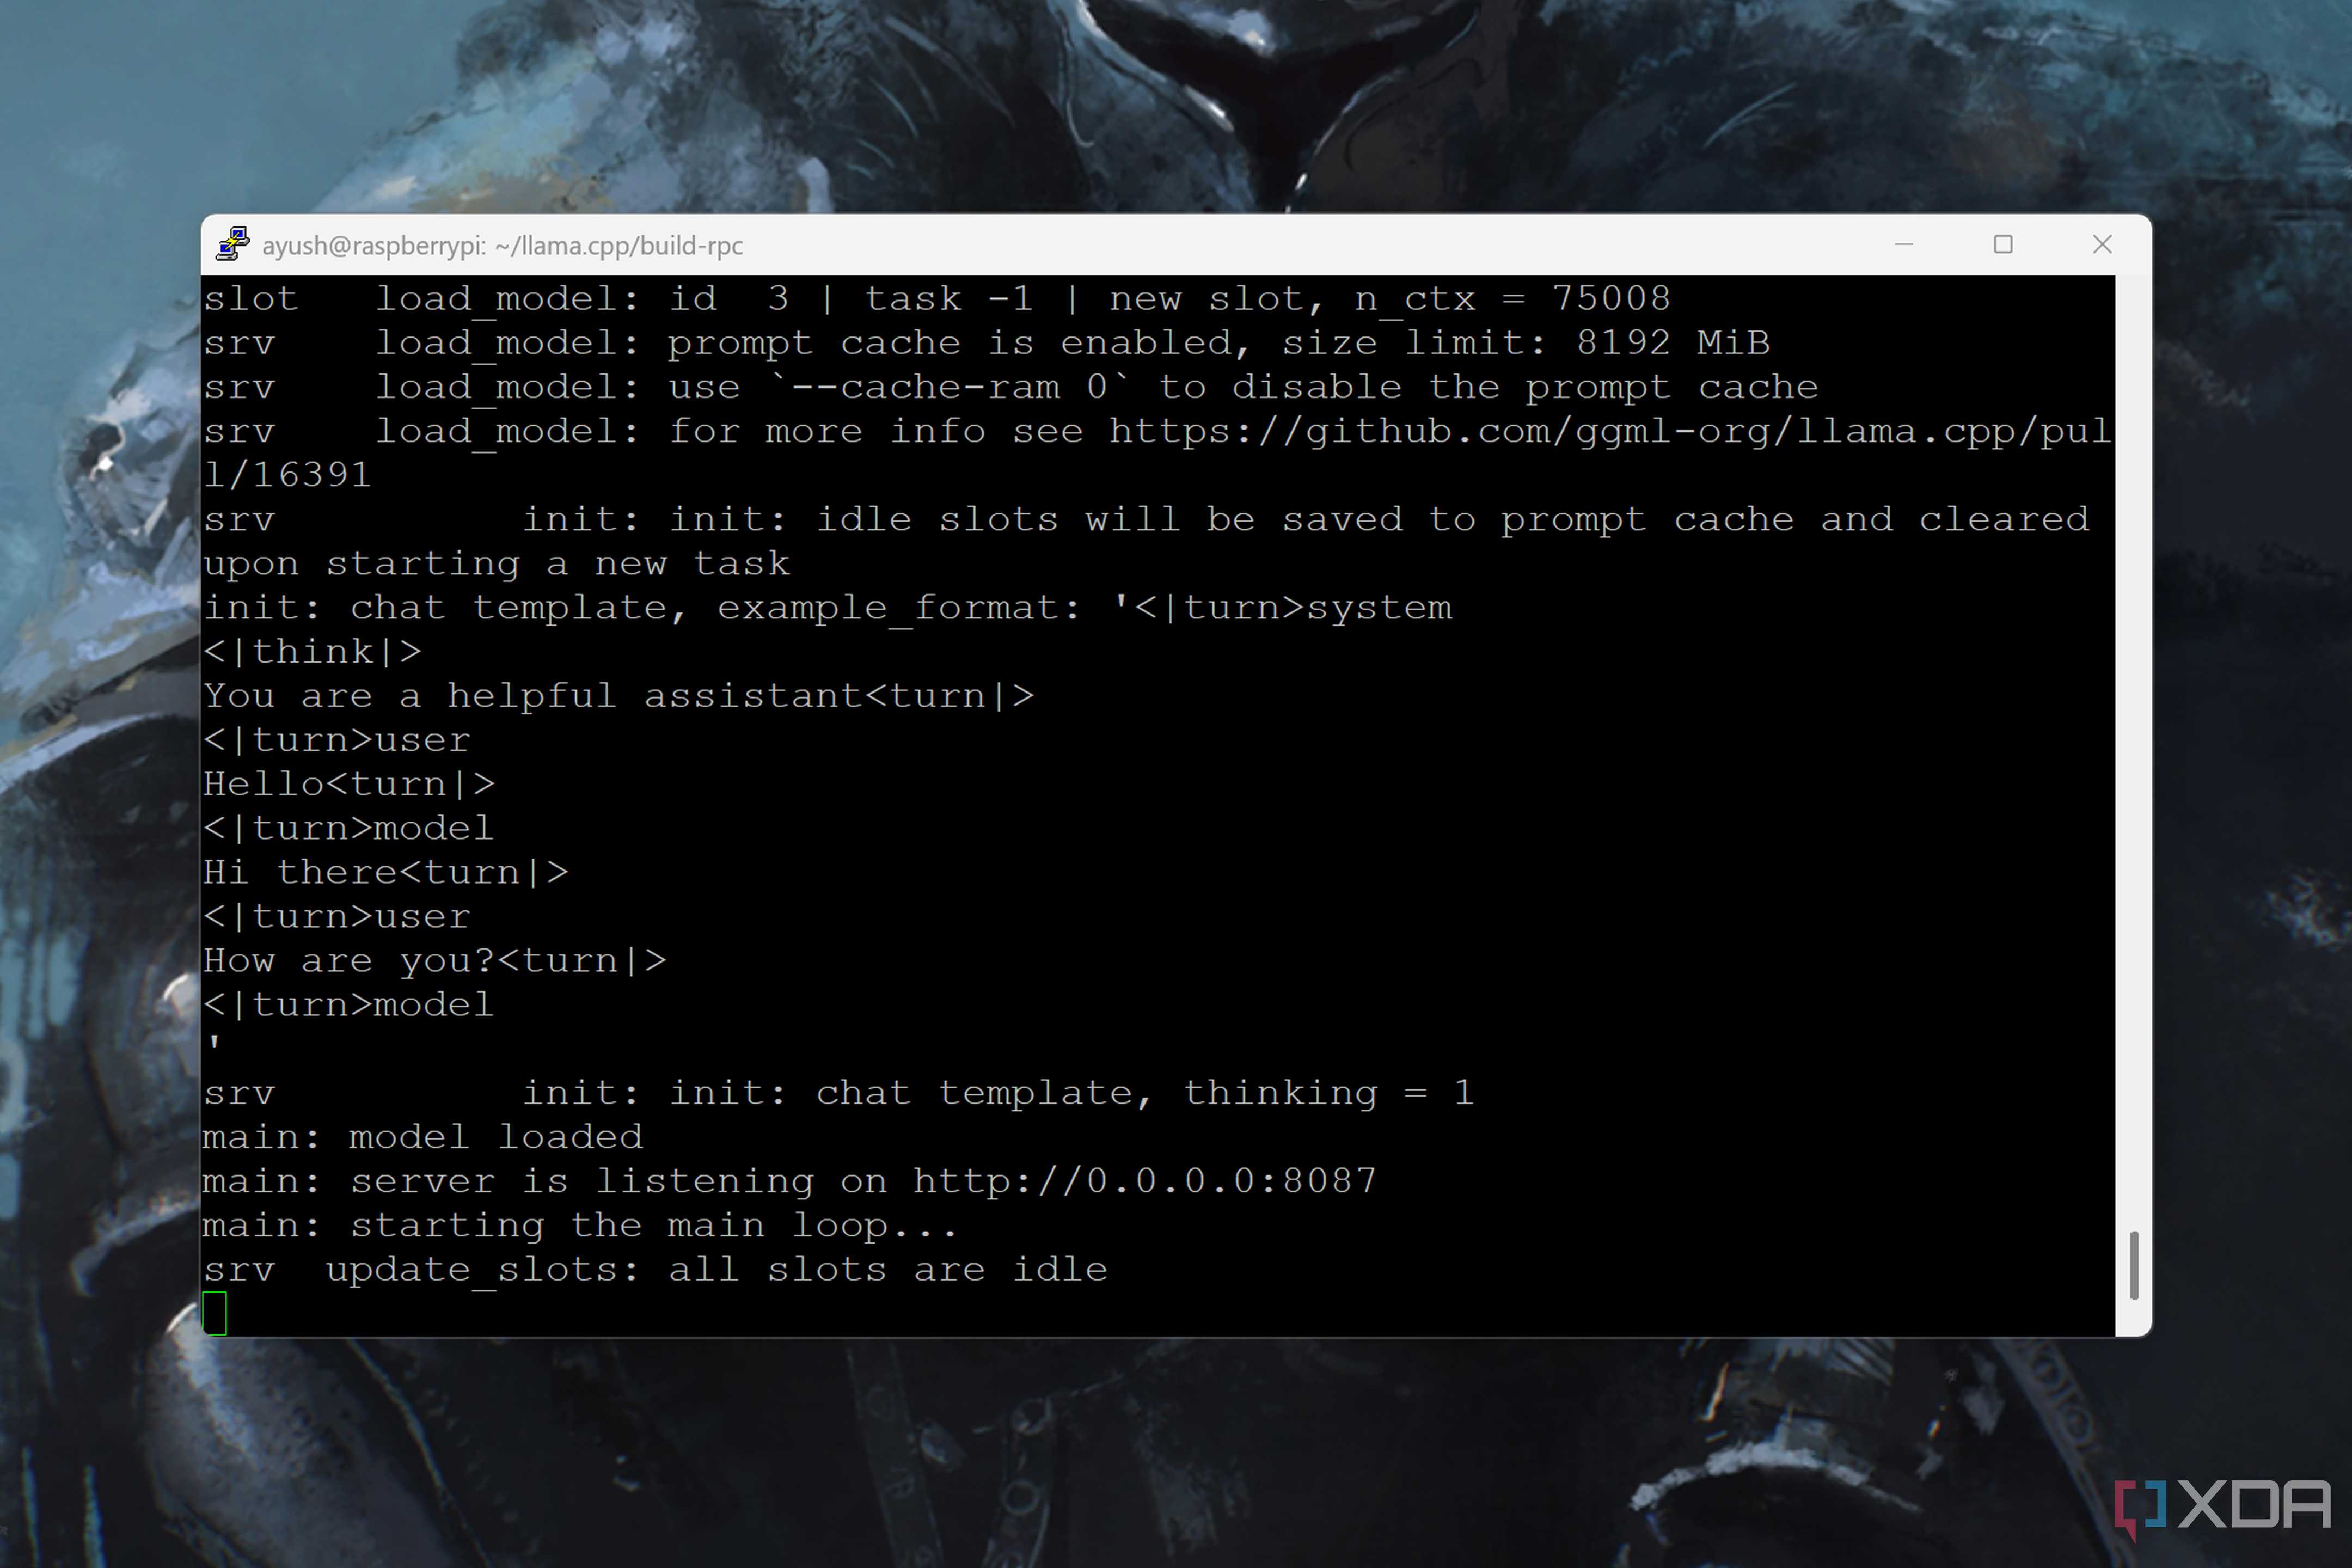
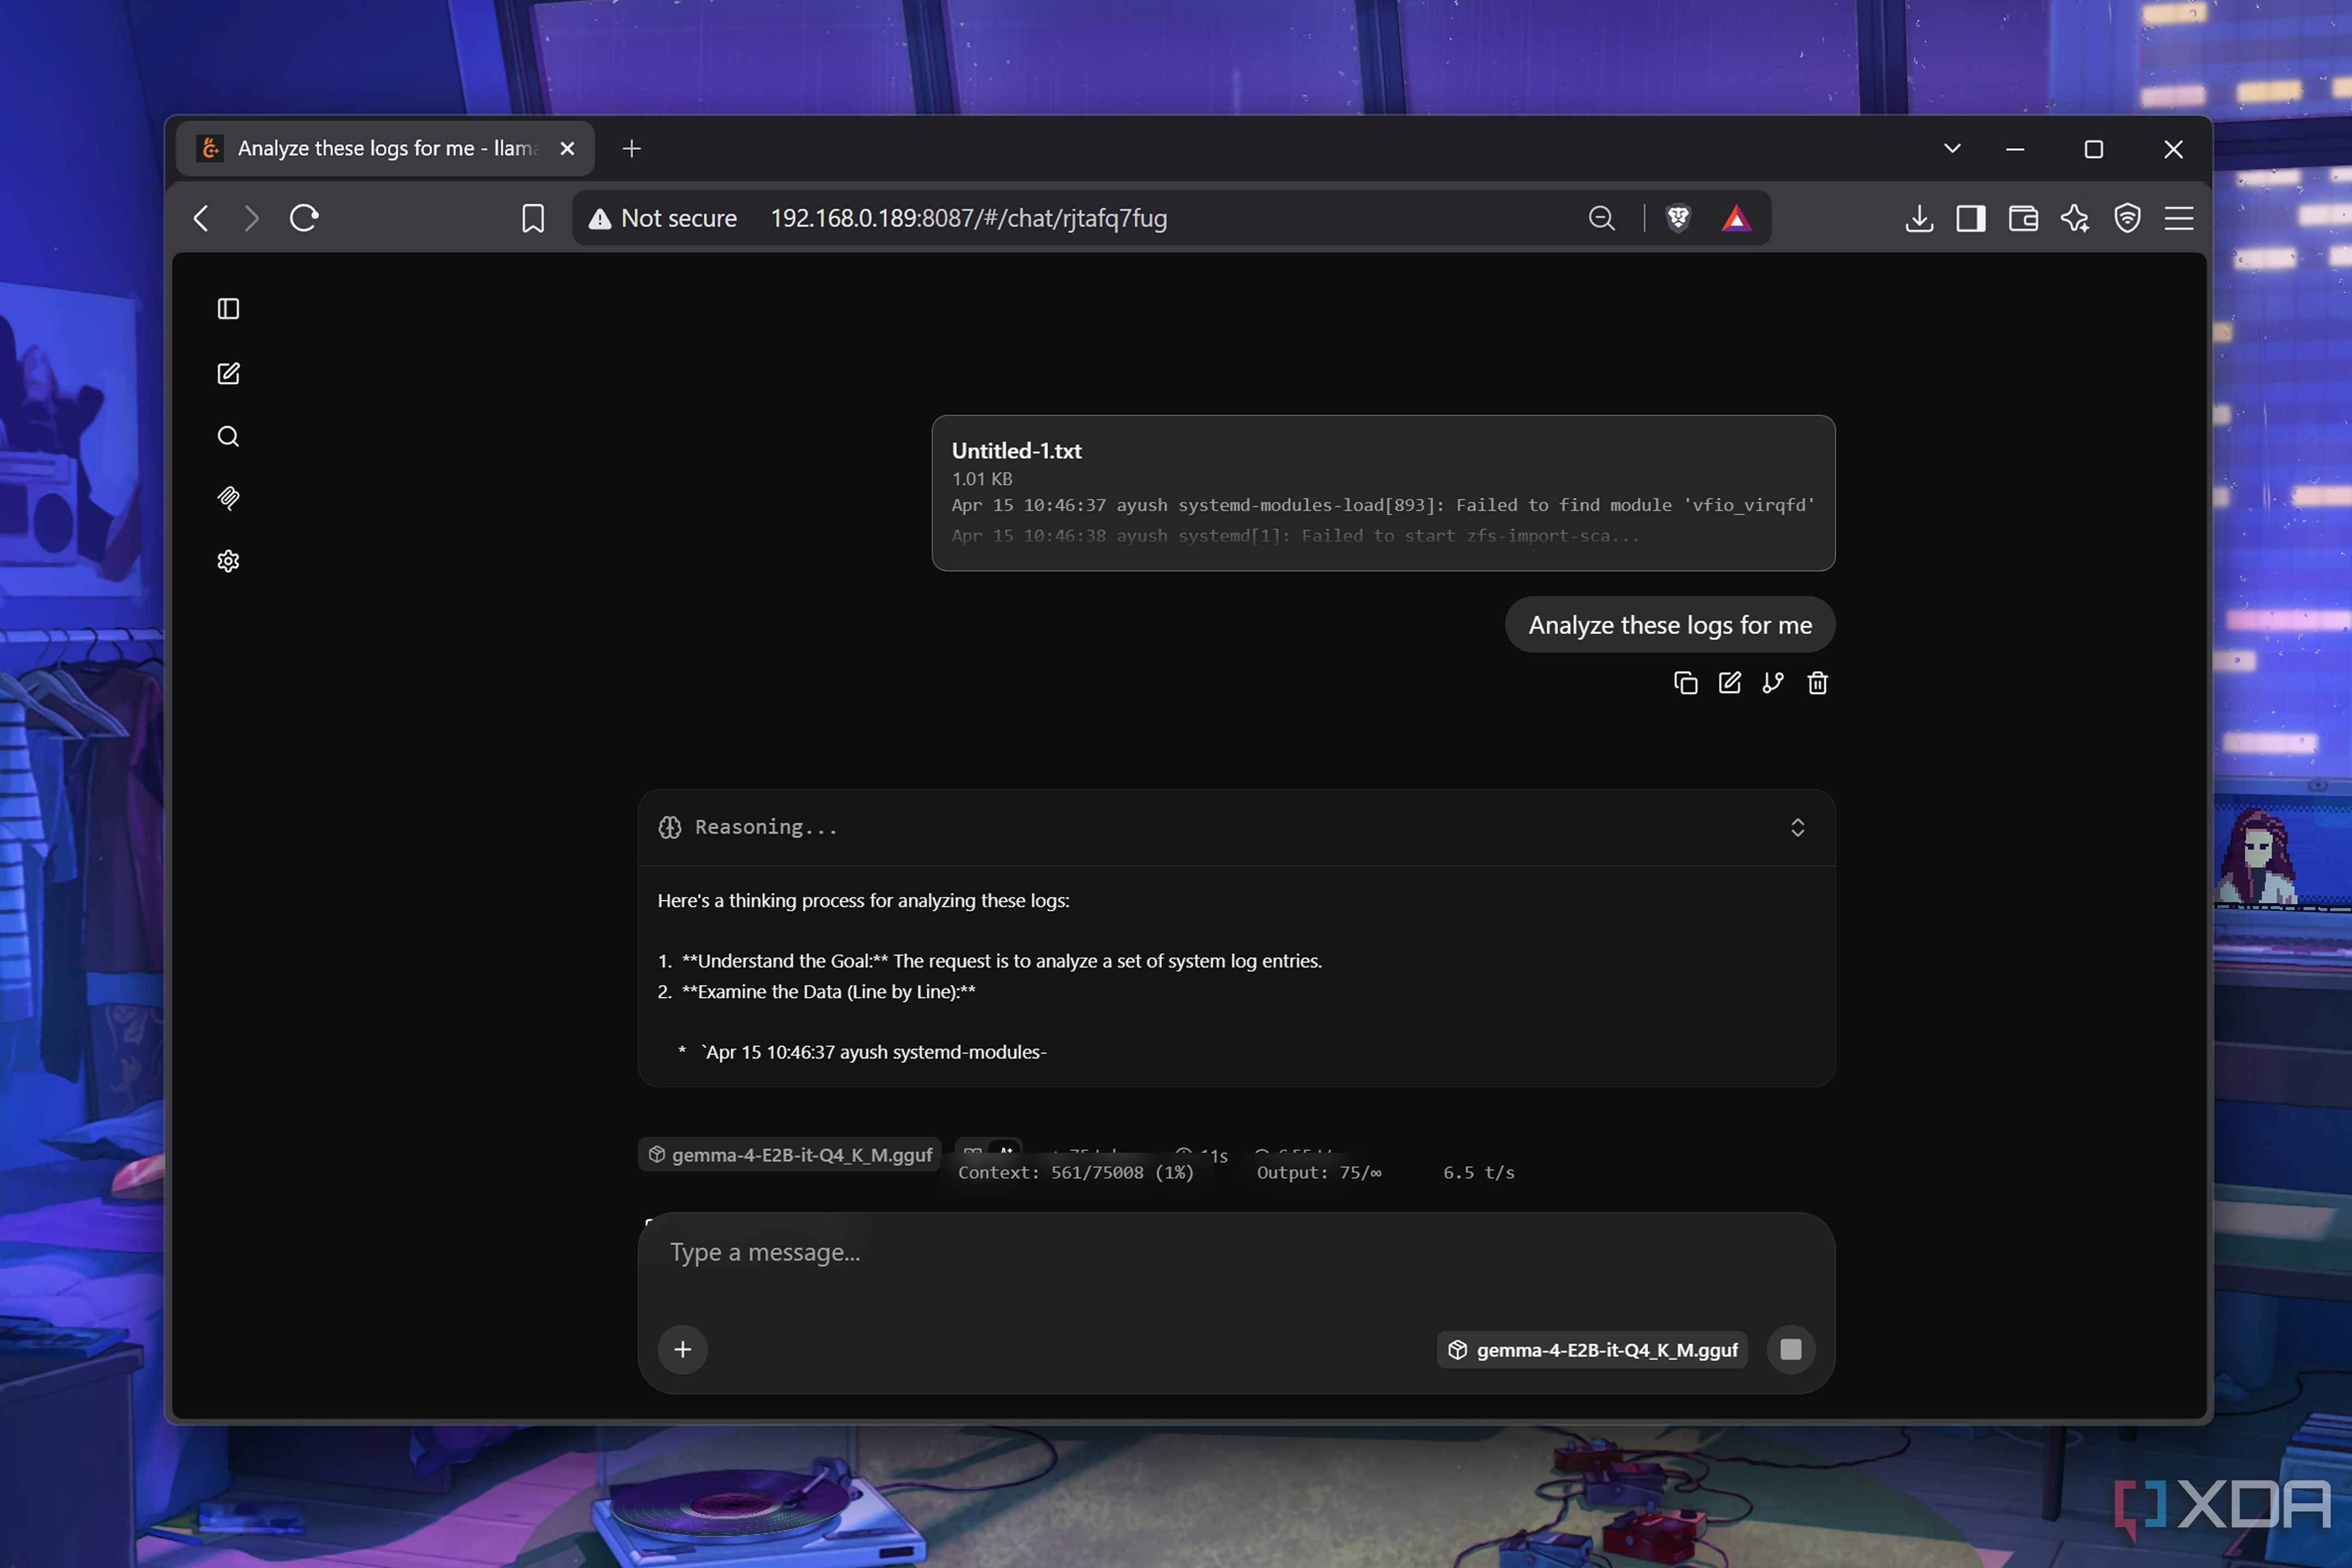
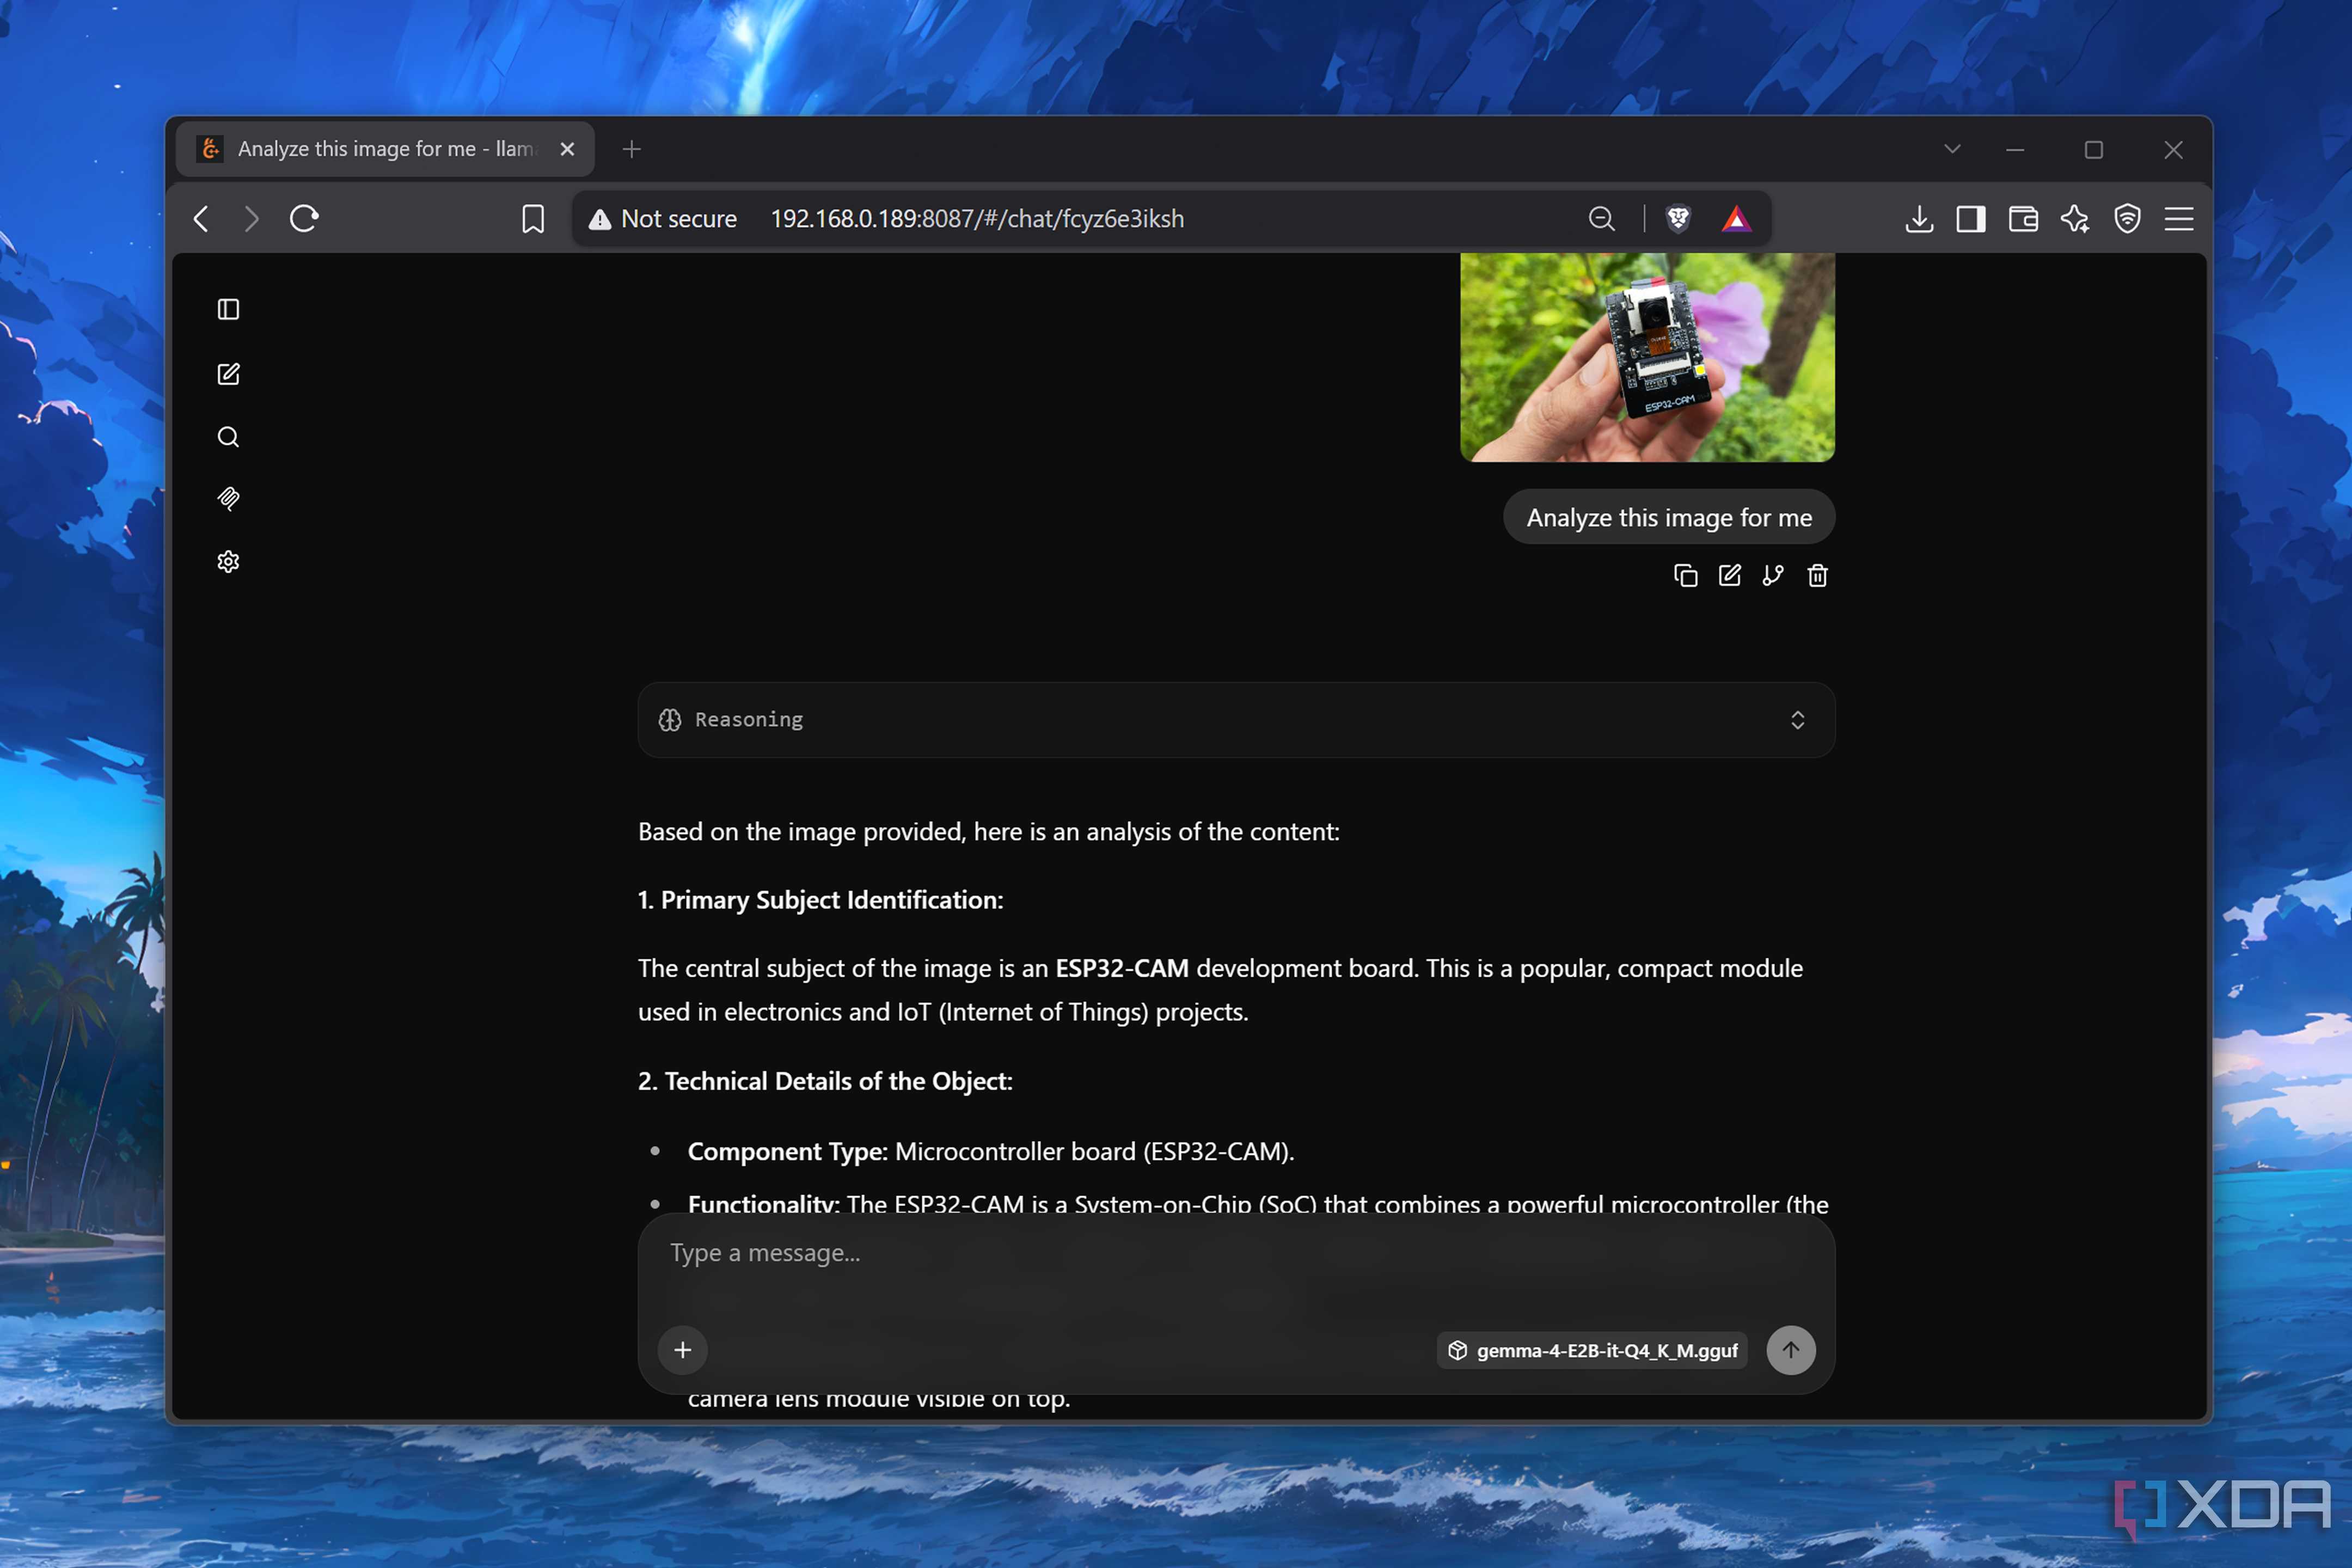
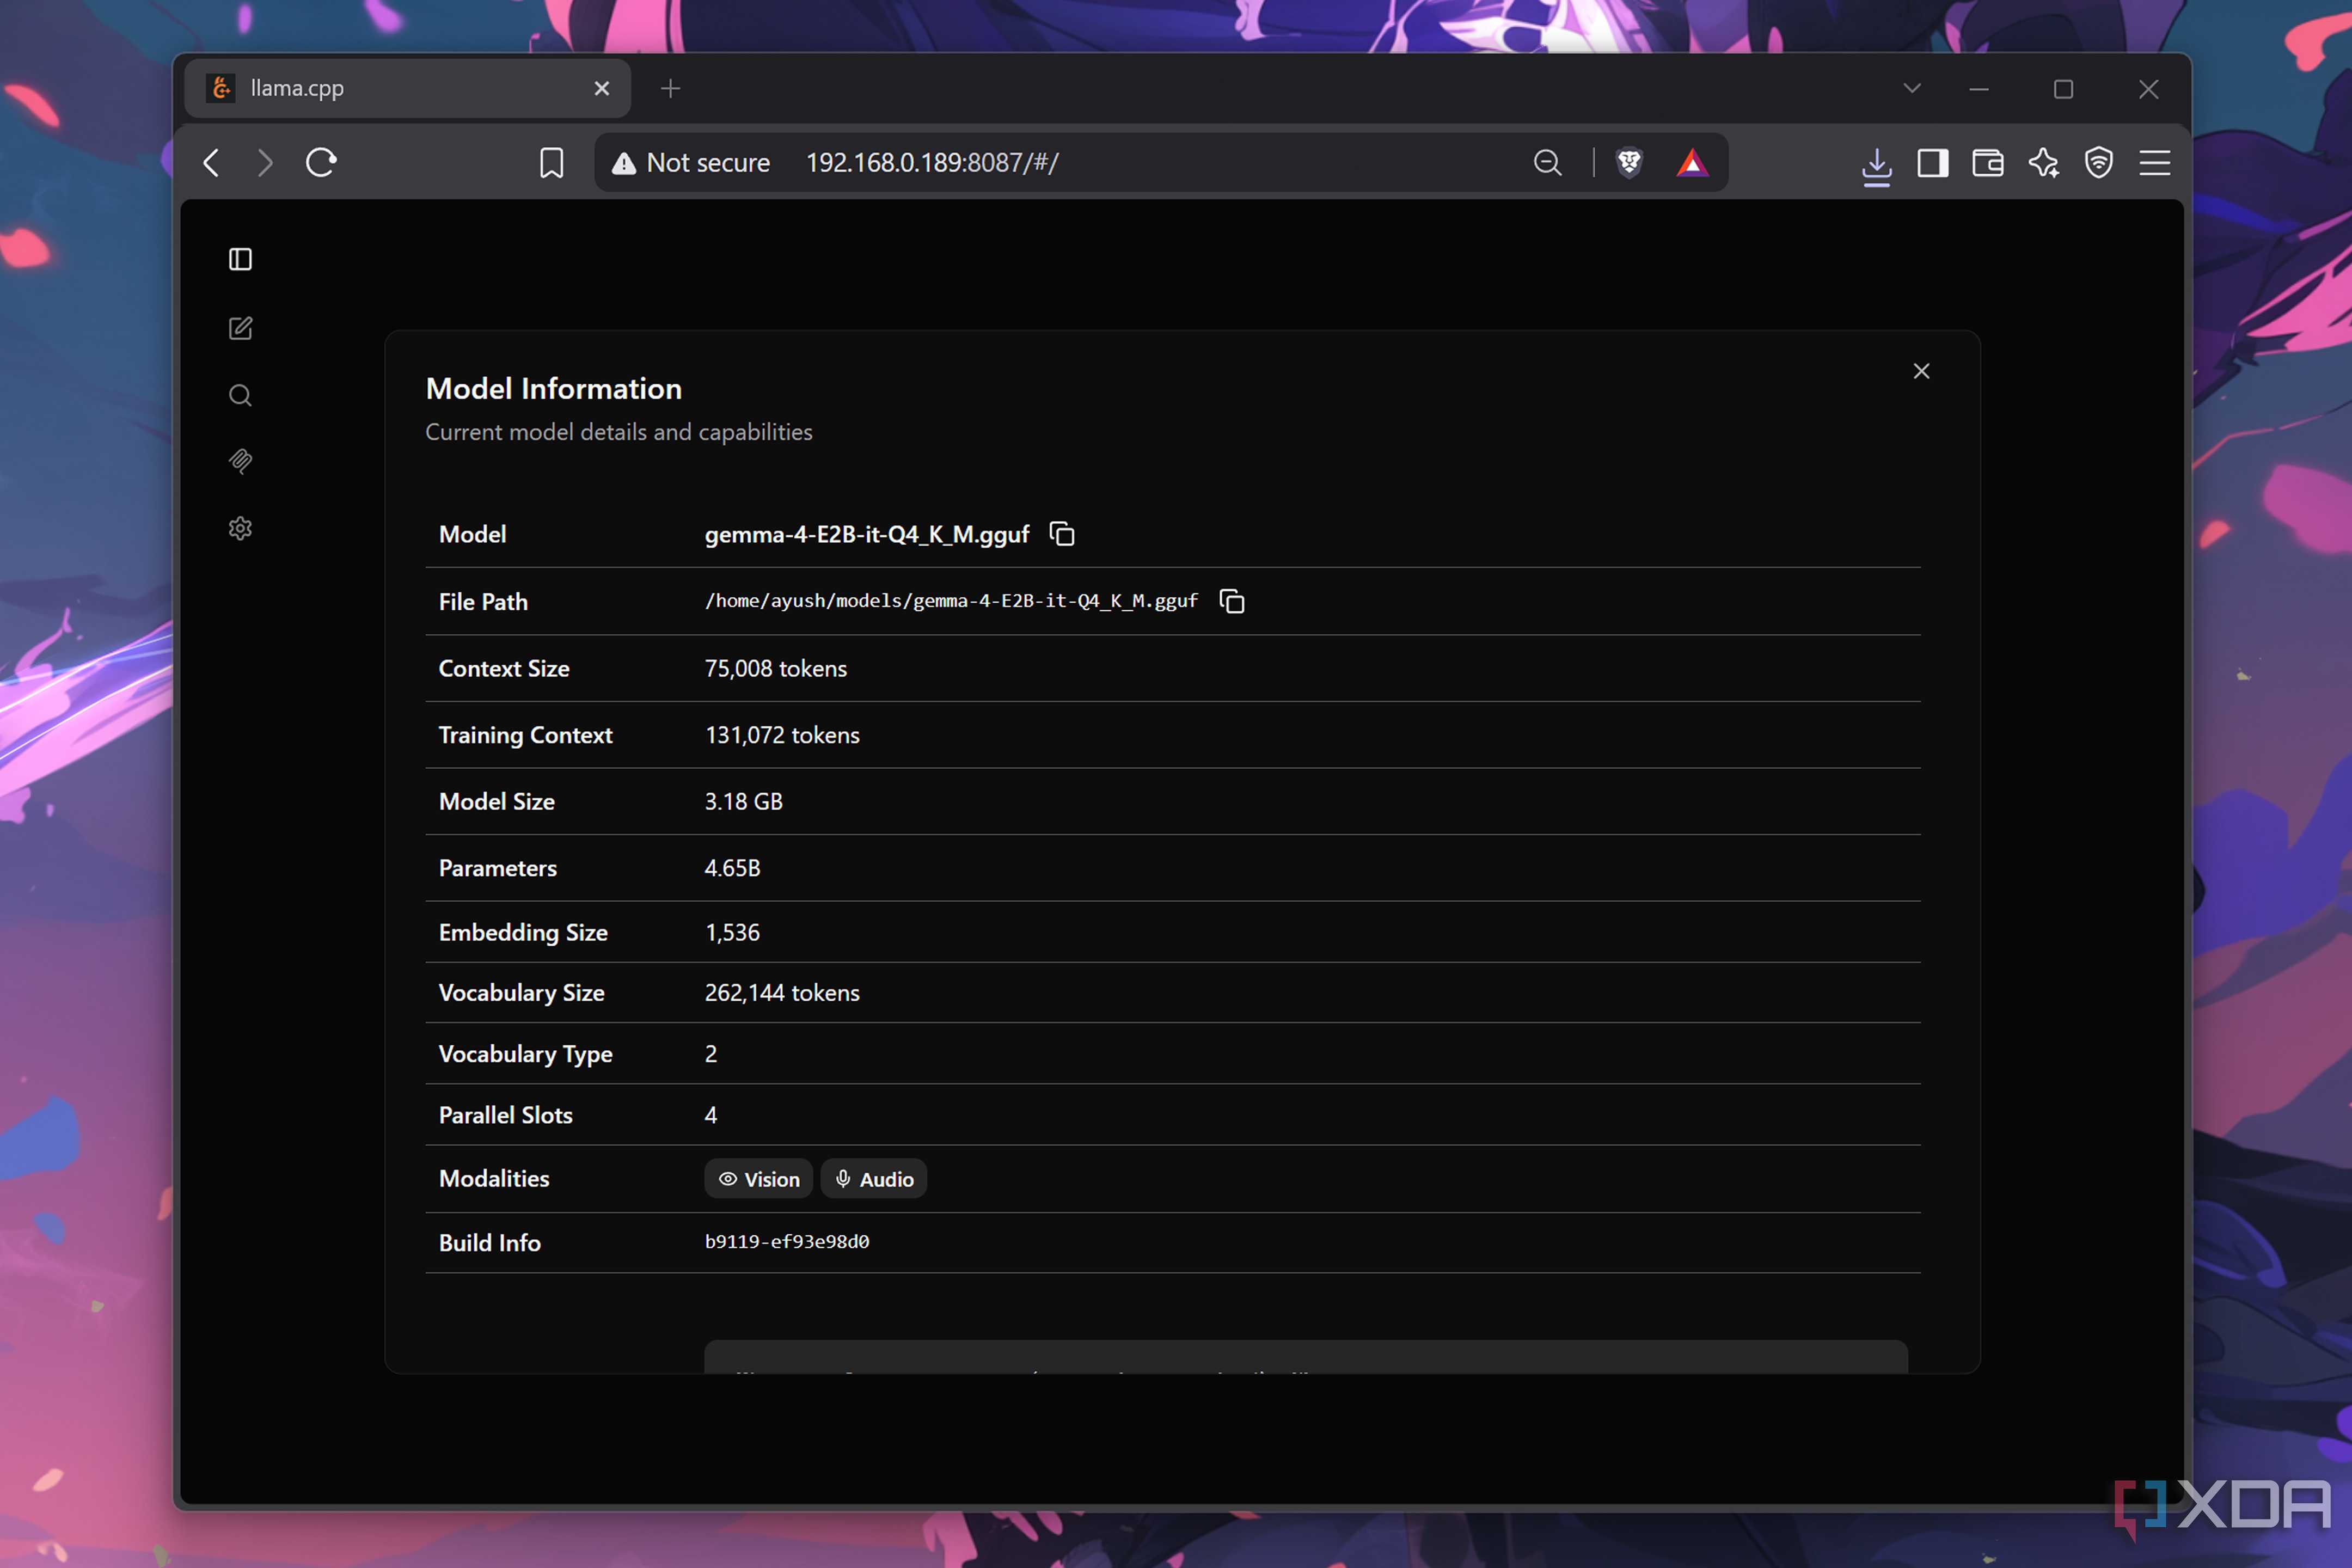
Low-parameter LLMs may work on weak systems, but they’re infamous for their limited reasoning skills and tendency to enter hallucination-riddled infinite loops for even the most basic prompts. And having attempted to run a bunch of lightweight LLMs on my Raspberry Pi 5 during a Pi (as in, the agent harness) project, I’d say their infamy is well-deserved. That said, the Gemma 4 family is an exception to this rule, as the E2B and E4B models in this lineup can hold their own against typical productivity apps.
You see, both Gemma models have this unique architecture where every decoding layer gets its own Per-Layer Embedding table, thereby letting it perform quick lookups instead of performing complex computations for each query. E2B, for example, only has 2.3B active (effective) compute parameters, even though its total parameter count is 5.1B. Similarly, E4B behaves like a 4.5B parameter model during active inference, despite possessing 8B total parameters.
Thanks to their lightweight design, my Raspberry Pi 5 can run these models without buckling under the extra computation load. As long as I use llama.cpp as the inference engine, my 8GB RPi 5 can handle Gemma 4 E2B at 5.8–6.5 tokens/second, and that’s with the Multi-Modal Projector file enabled for image recognition capabilities. As you’d expect, Gemma 4 E4B is slower on the RPi 5, as the SBC can only generate 2.5–3 tokens per second.
On paper, that’s too slow for normal conversations, and I would never use it for complex coding tasks. But when it comes to summarizing my Karakeep bookmarks, performing OCR scans on Paperless-GPT, or auto-tagging my Blinko notes, a Gemma 4 E4B (or even E2B) instance running on my Raspberry Pi 5 is more than enough to replace ChatGPT and other cloud platforms.
Edge models like the Cactus Compute Needle 3 are even more efficient for simple tasks
It ain’t quite an LLM, but it gets the job done when you configure it right
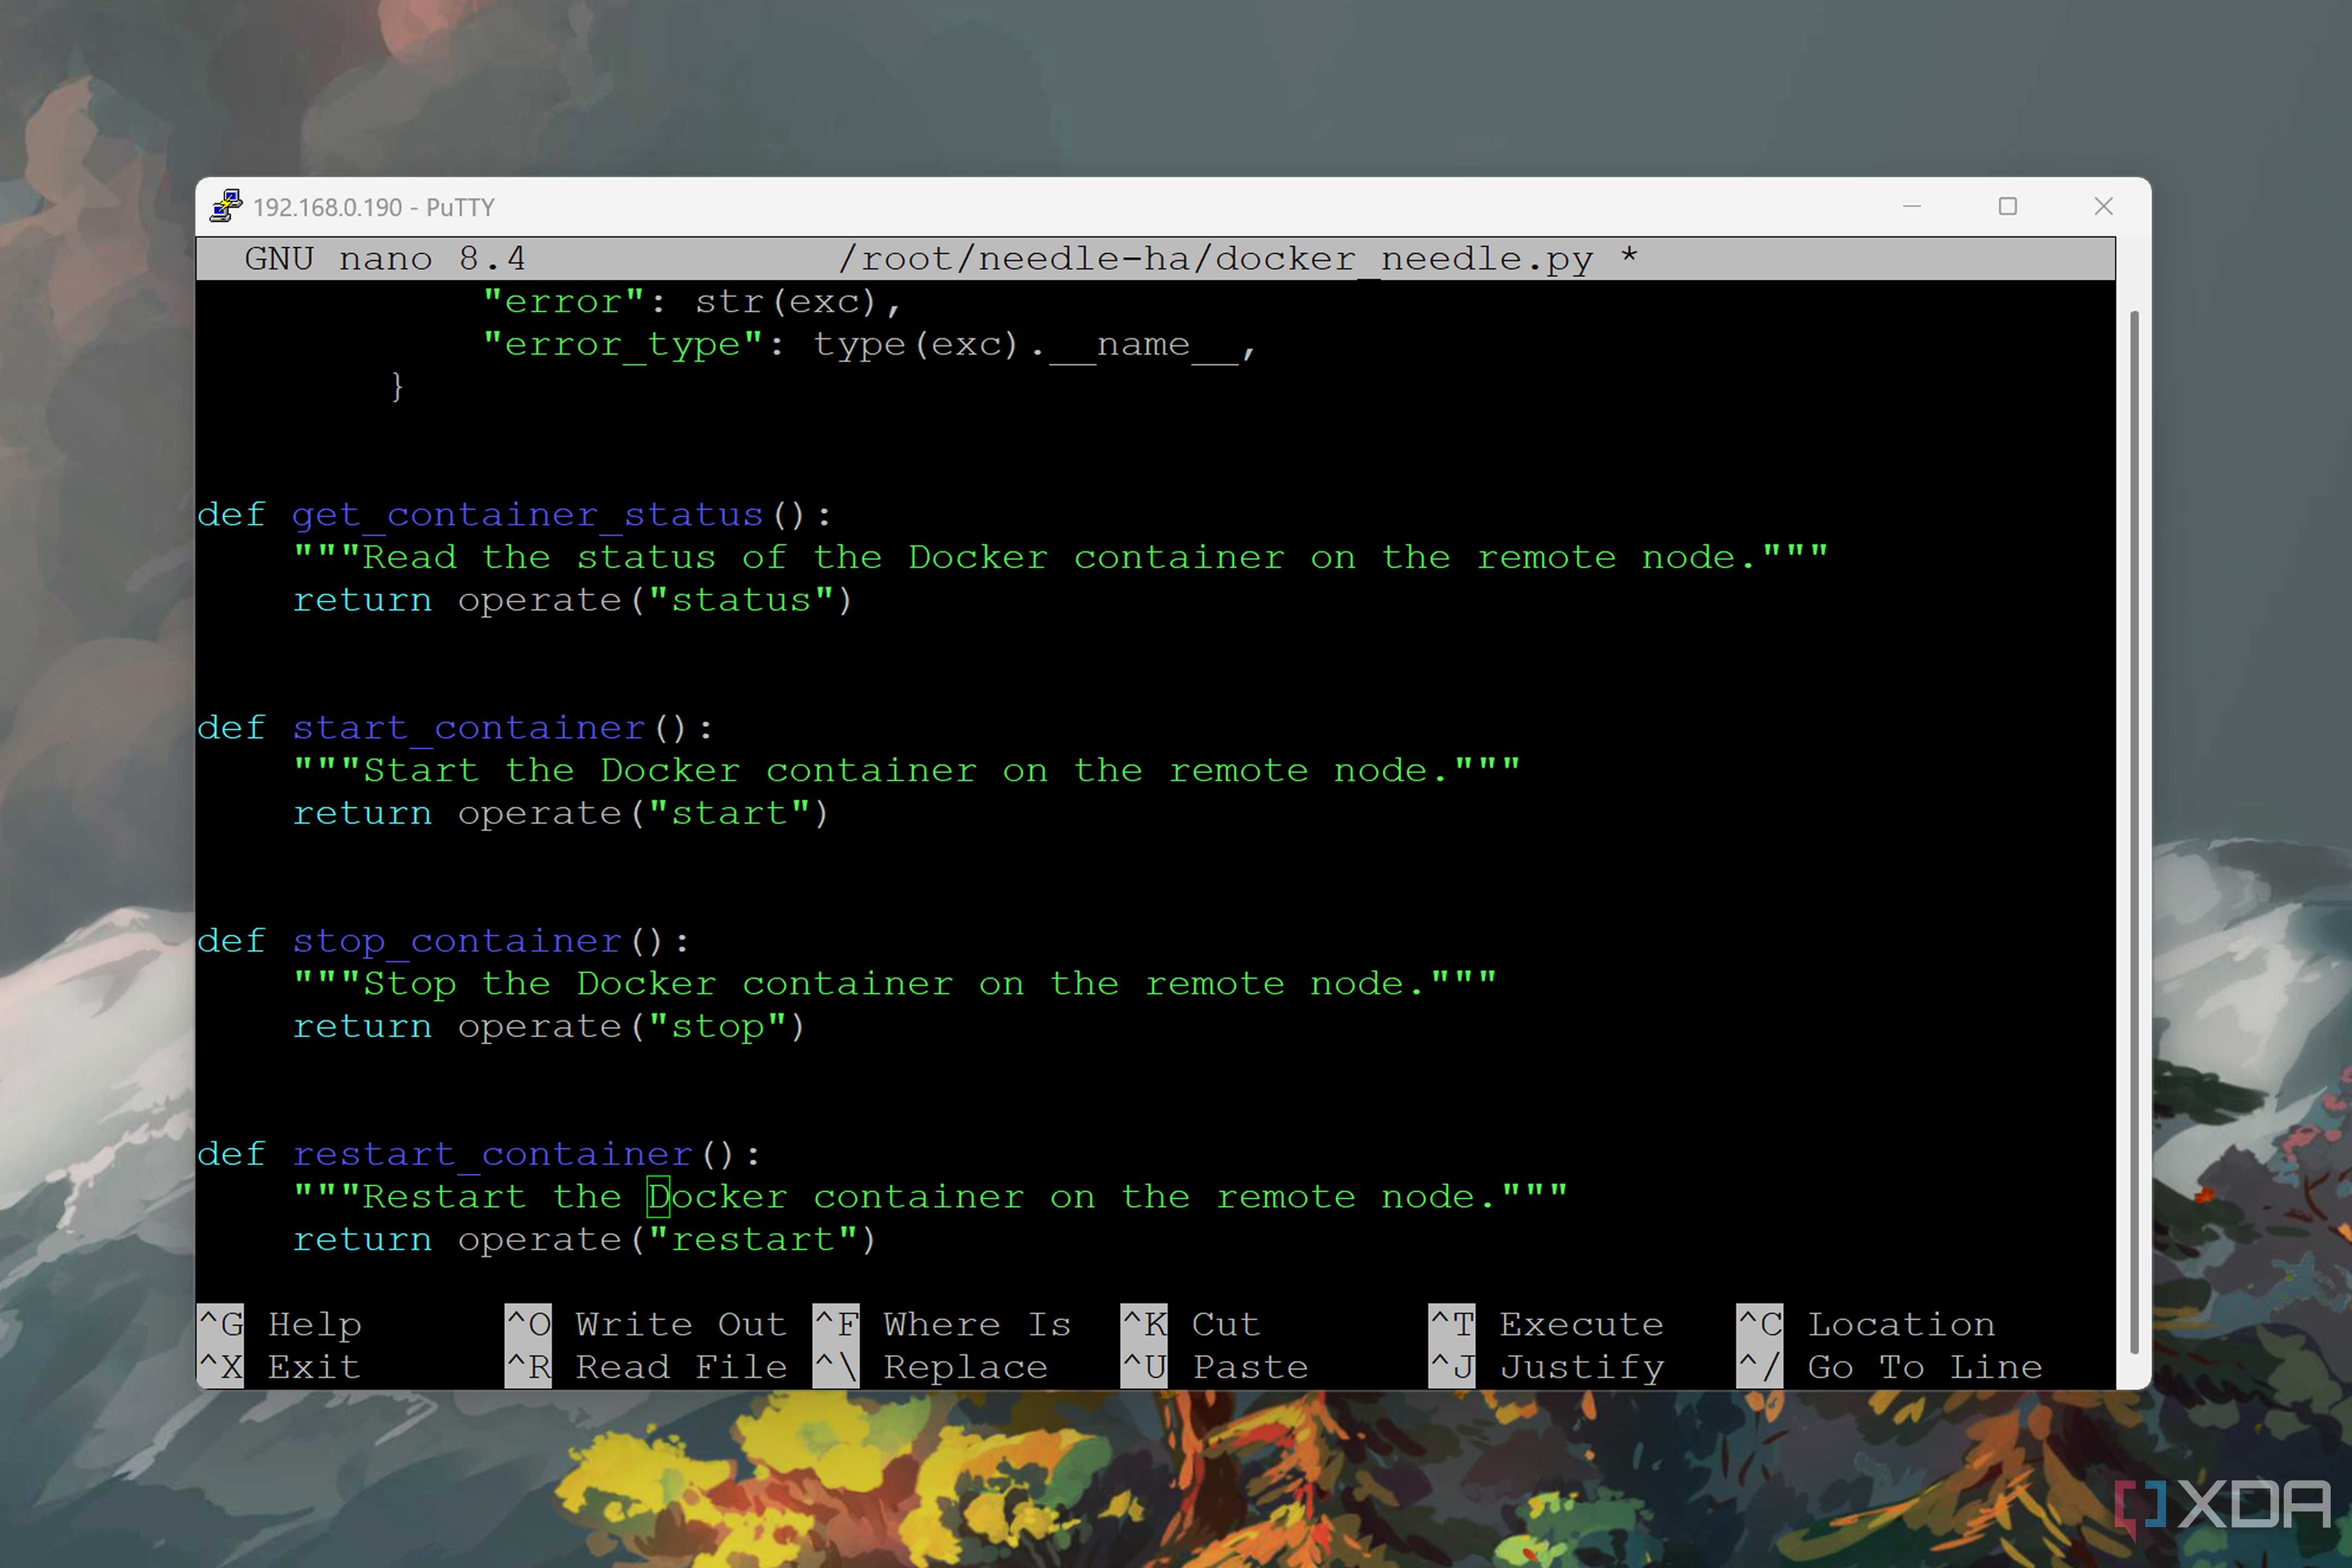
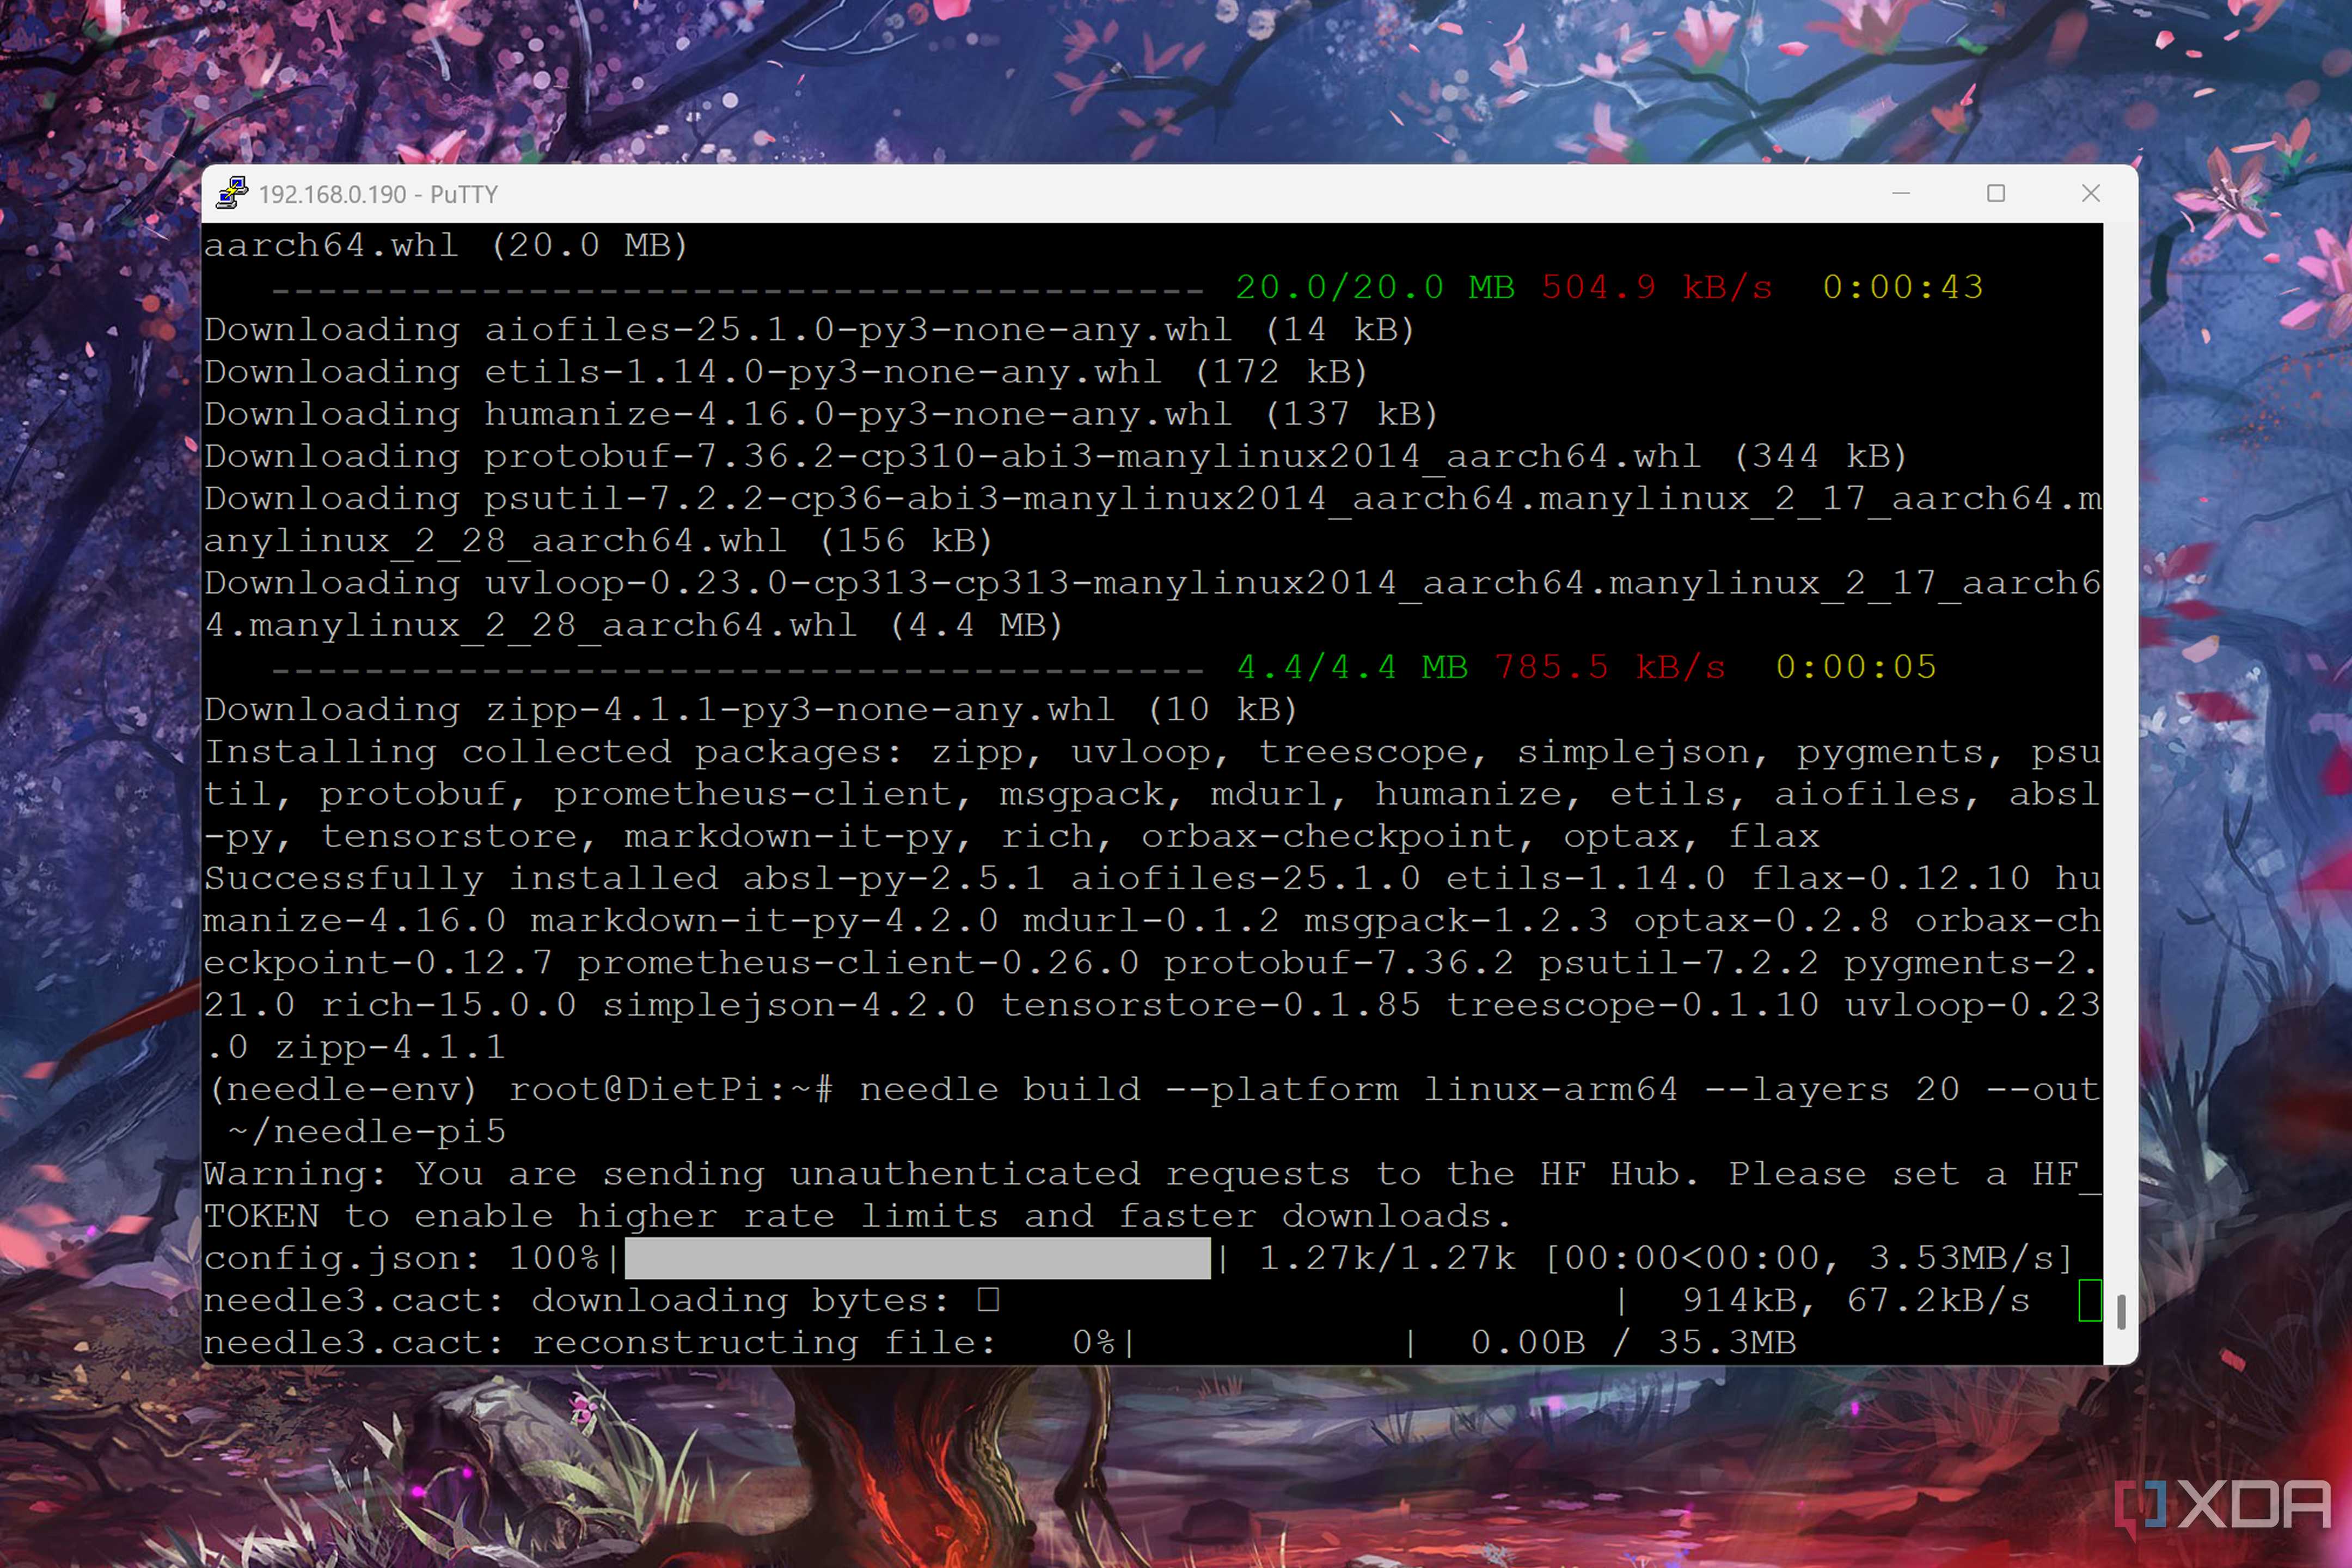
Cactus Compute Needle 3 is one of the more recent models I’ve tinkered with on my RPi 5, and it has quickly become my favorite way to run AI tasks on my SBC. For one, it’s not really a general-purpose LLM like the Gemma 4 models I highlighted earlier.
Needle 3 discards the conversational and open-ended text generation capabilities you’d find in typical LLMs, and instead works as a specialized model whose only purpose is to call tools, extract data fields, and create text embeddings. As such, it only has a maximum of 121M parameters, and thanks to its layer-based design, it’s possible to deploy sub-networks of reduced depth to save performance on ultra-low RAM devices – including the likes of microcontrollers.
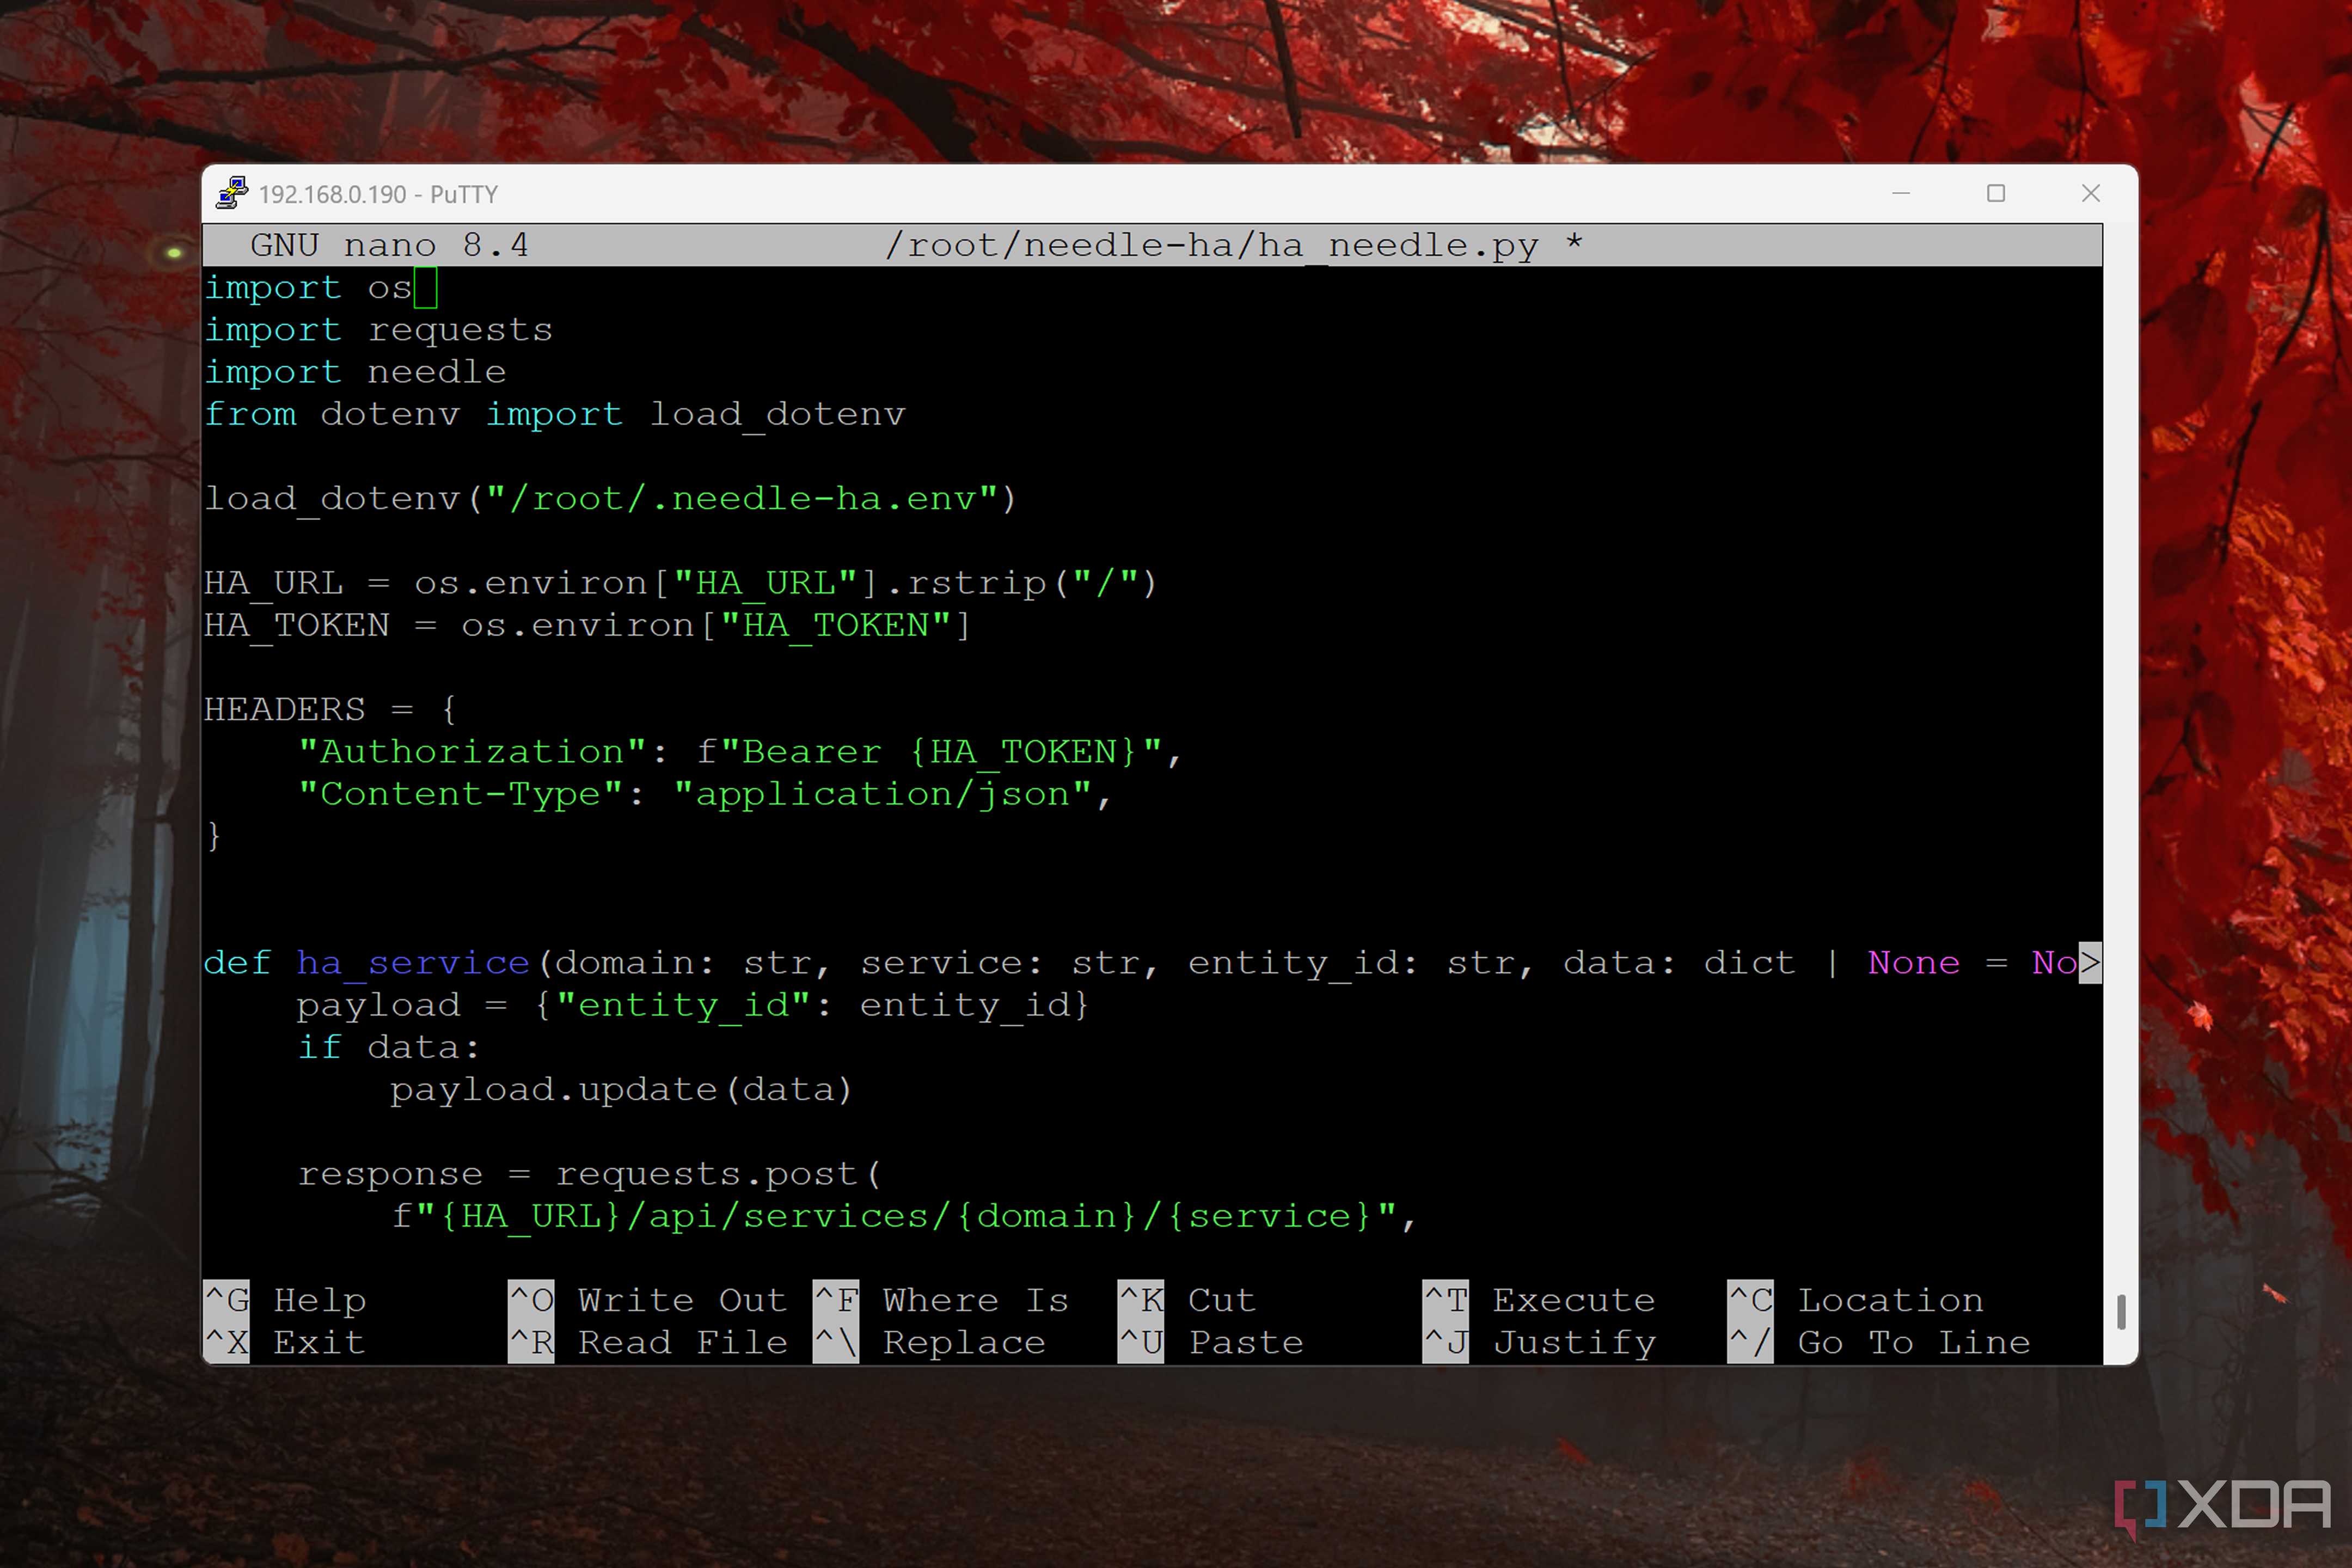
While Needle 3 didn’t work on my first-gen RPi Zero due to the latter’s dinosaur CPU architecture, it works really well on my Raspberry Pi 5. When I tried experimenting with this edge AI mode, I created a simple Python file that connects my Needle 3 instance to Home Assistant and controls my smart plug.
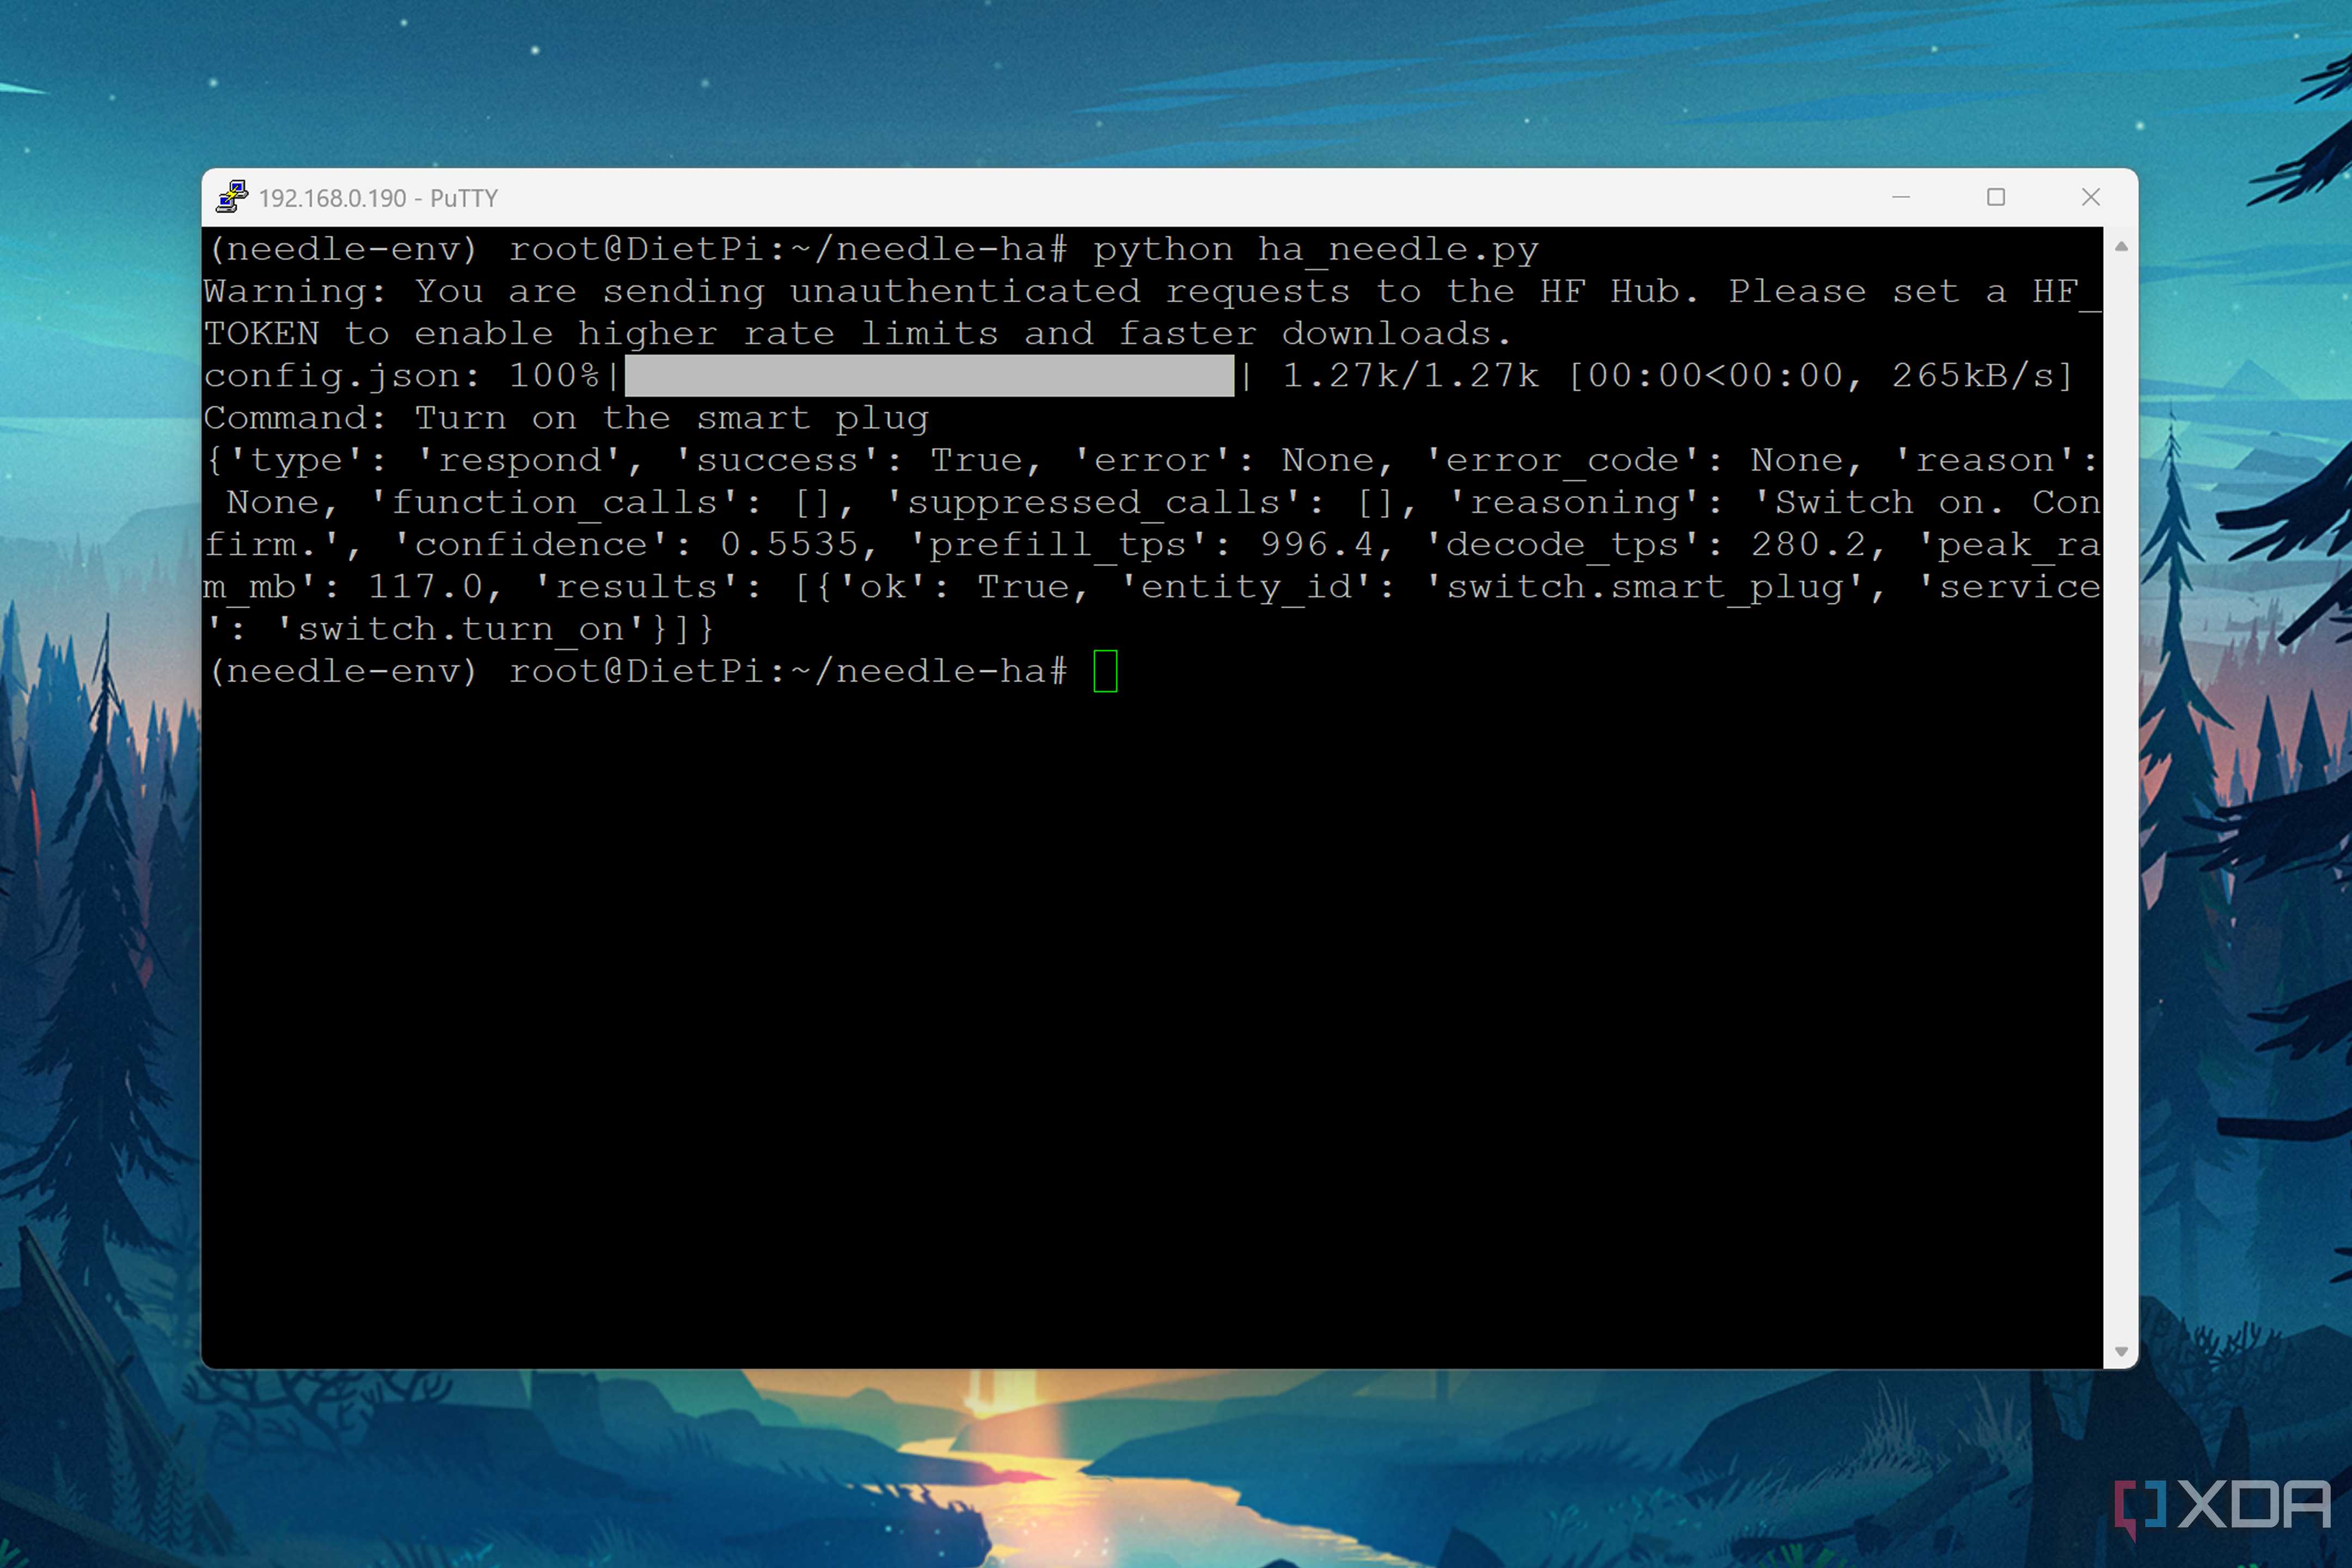
Then, once I fed this script to the Needle 3 instance (with all 20 layers) and ran a simple conversational query to turn my smart plug on, the AI model fired the right automation immediately, with a decode rate of 280.2 tokens/s and a prefill value of 996.4 tokens/s. I’ve experimented with Docker management commands and other Home Assistant tool calls, and this edge model worked perfectly well as long as I didn’t mess up the Python configs. Again, it’s nowhere near as easy to use as LLMs, but for folks willing to create custom Python code, the Raspberry Pi + Needle 3 form a killer combo for AI-aided automations.
This tiny board is just as capable of running embedding models
Which, in turn, can complement bulky LLMs running on dedicated servers

Let’s say you’re using your Raspberry Pi as a secondary home server node – one that only runs lightweight apps and companion services for your bulky FOSS toolkit. Well, you can extend this repertoire of tools to include AI modes. Specifically, embedding models that convert regular ol’ text and image inputs into numerical vectors and place them in a multi-dimensional space, with similar vectors getting grouped together.
Then, apps that support Retrieval-Augmented Generation capabilities can use these vector mappings to inject extra context for the LLMs every time you query them, thereby making the responses more precise and preventing your locally-deployed clankers from hallucinating. In my home lab, Paperless-ngx, Open Notebook, and Blinko rely on embedding models to ensure my LLMs get all the information from my own documents and notes. I’ve migrated to an old PC for embedding models now, but I’d often use nomic-embed-1.5 with my Raspberry Pi 5 to generate these vector mappings for my self-hosted tools.
Then there’s the YOLO models for the Raspberry Pi AI Kit
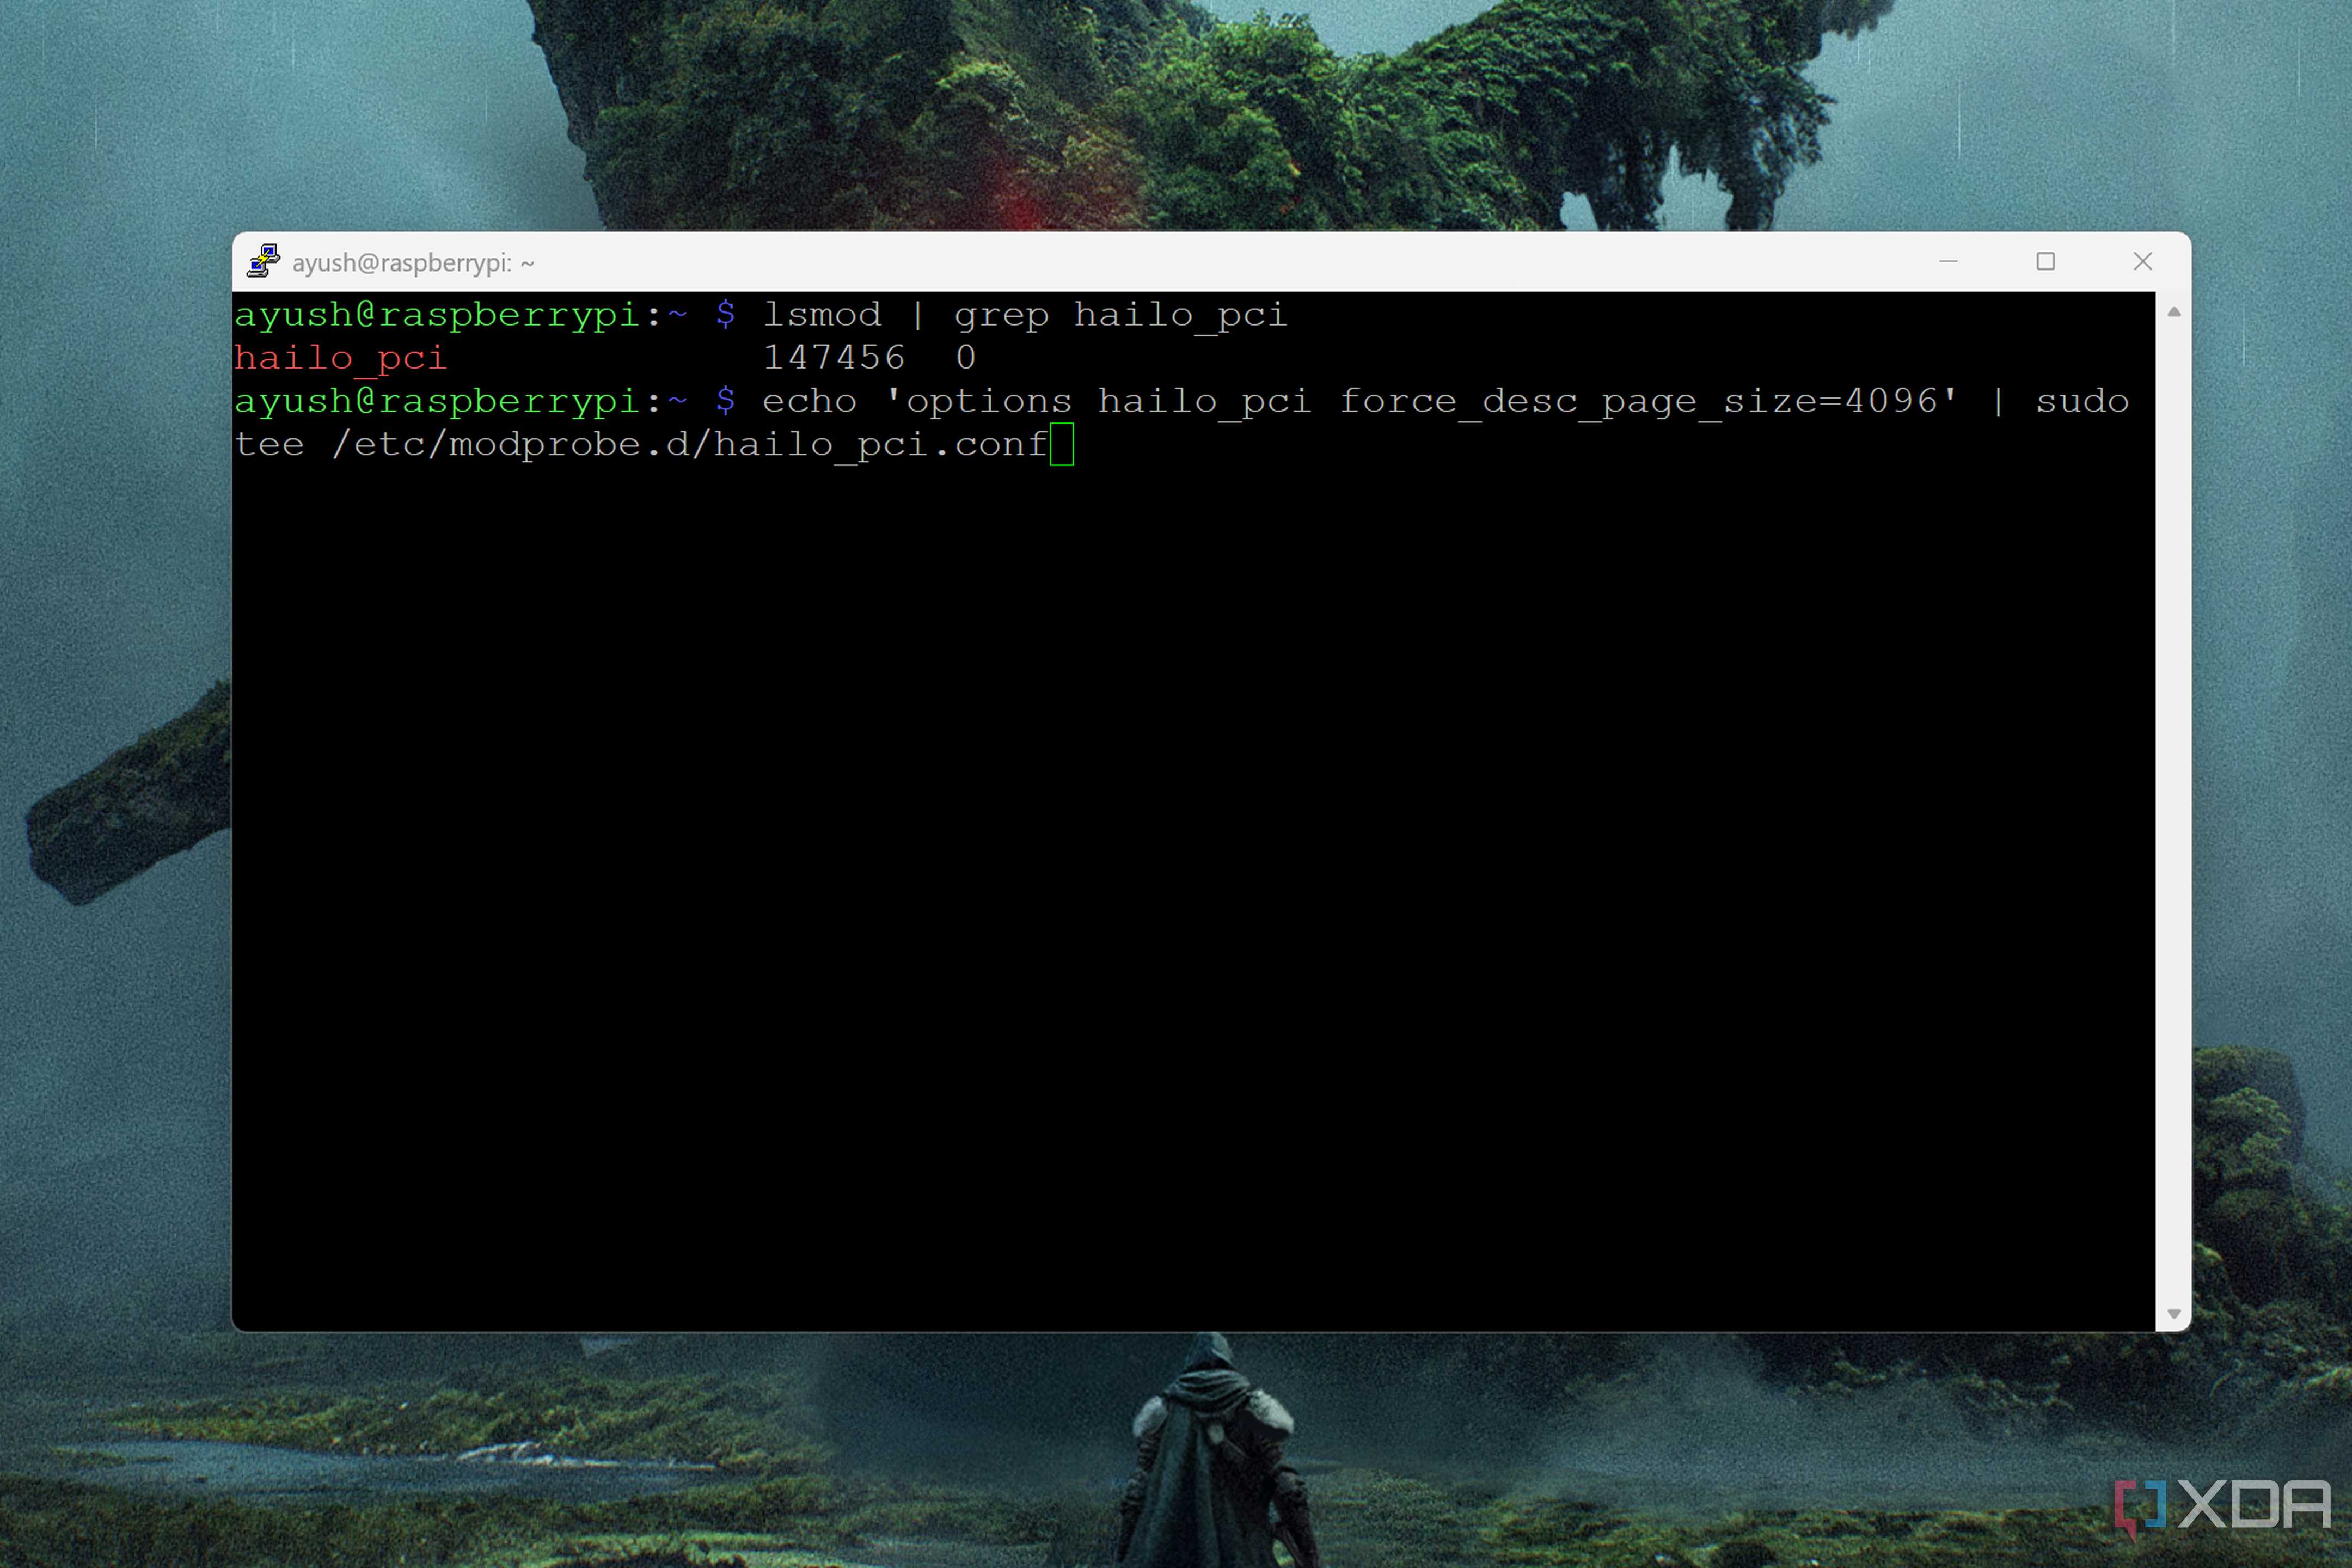
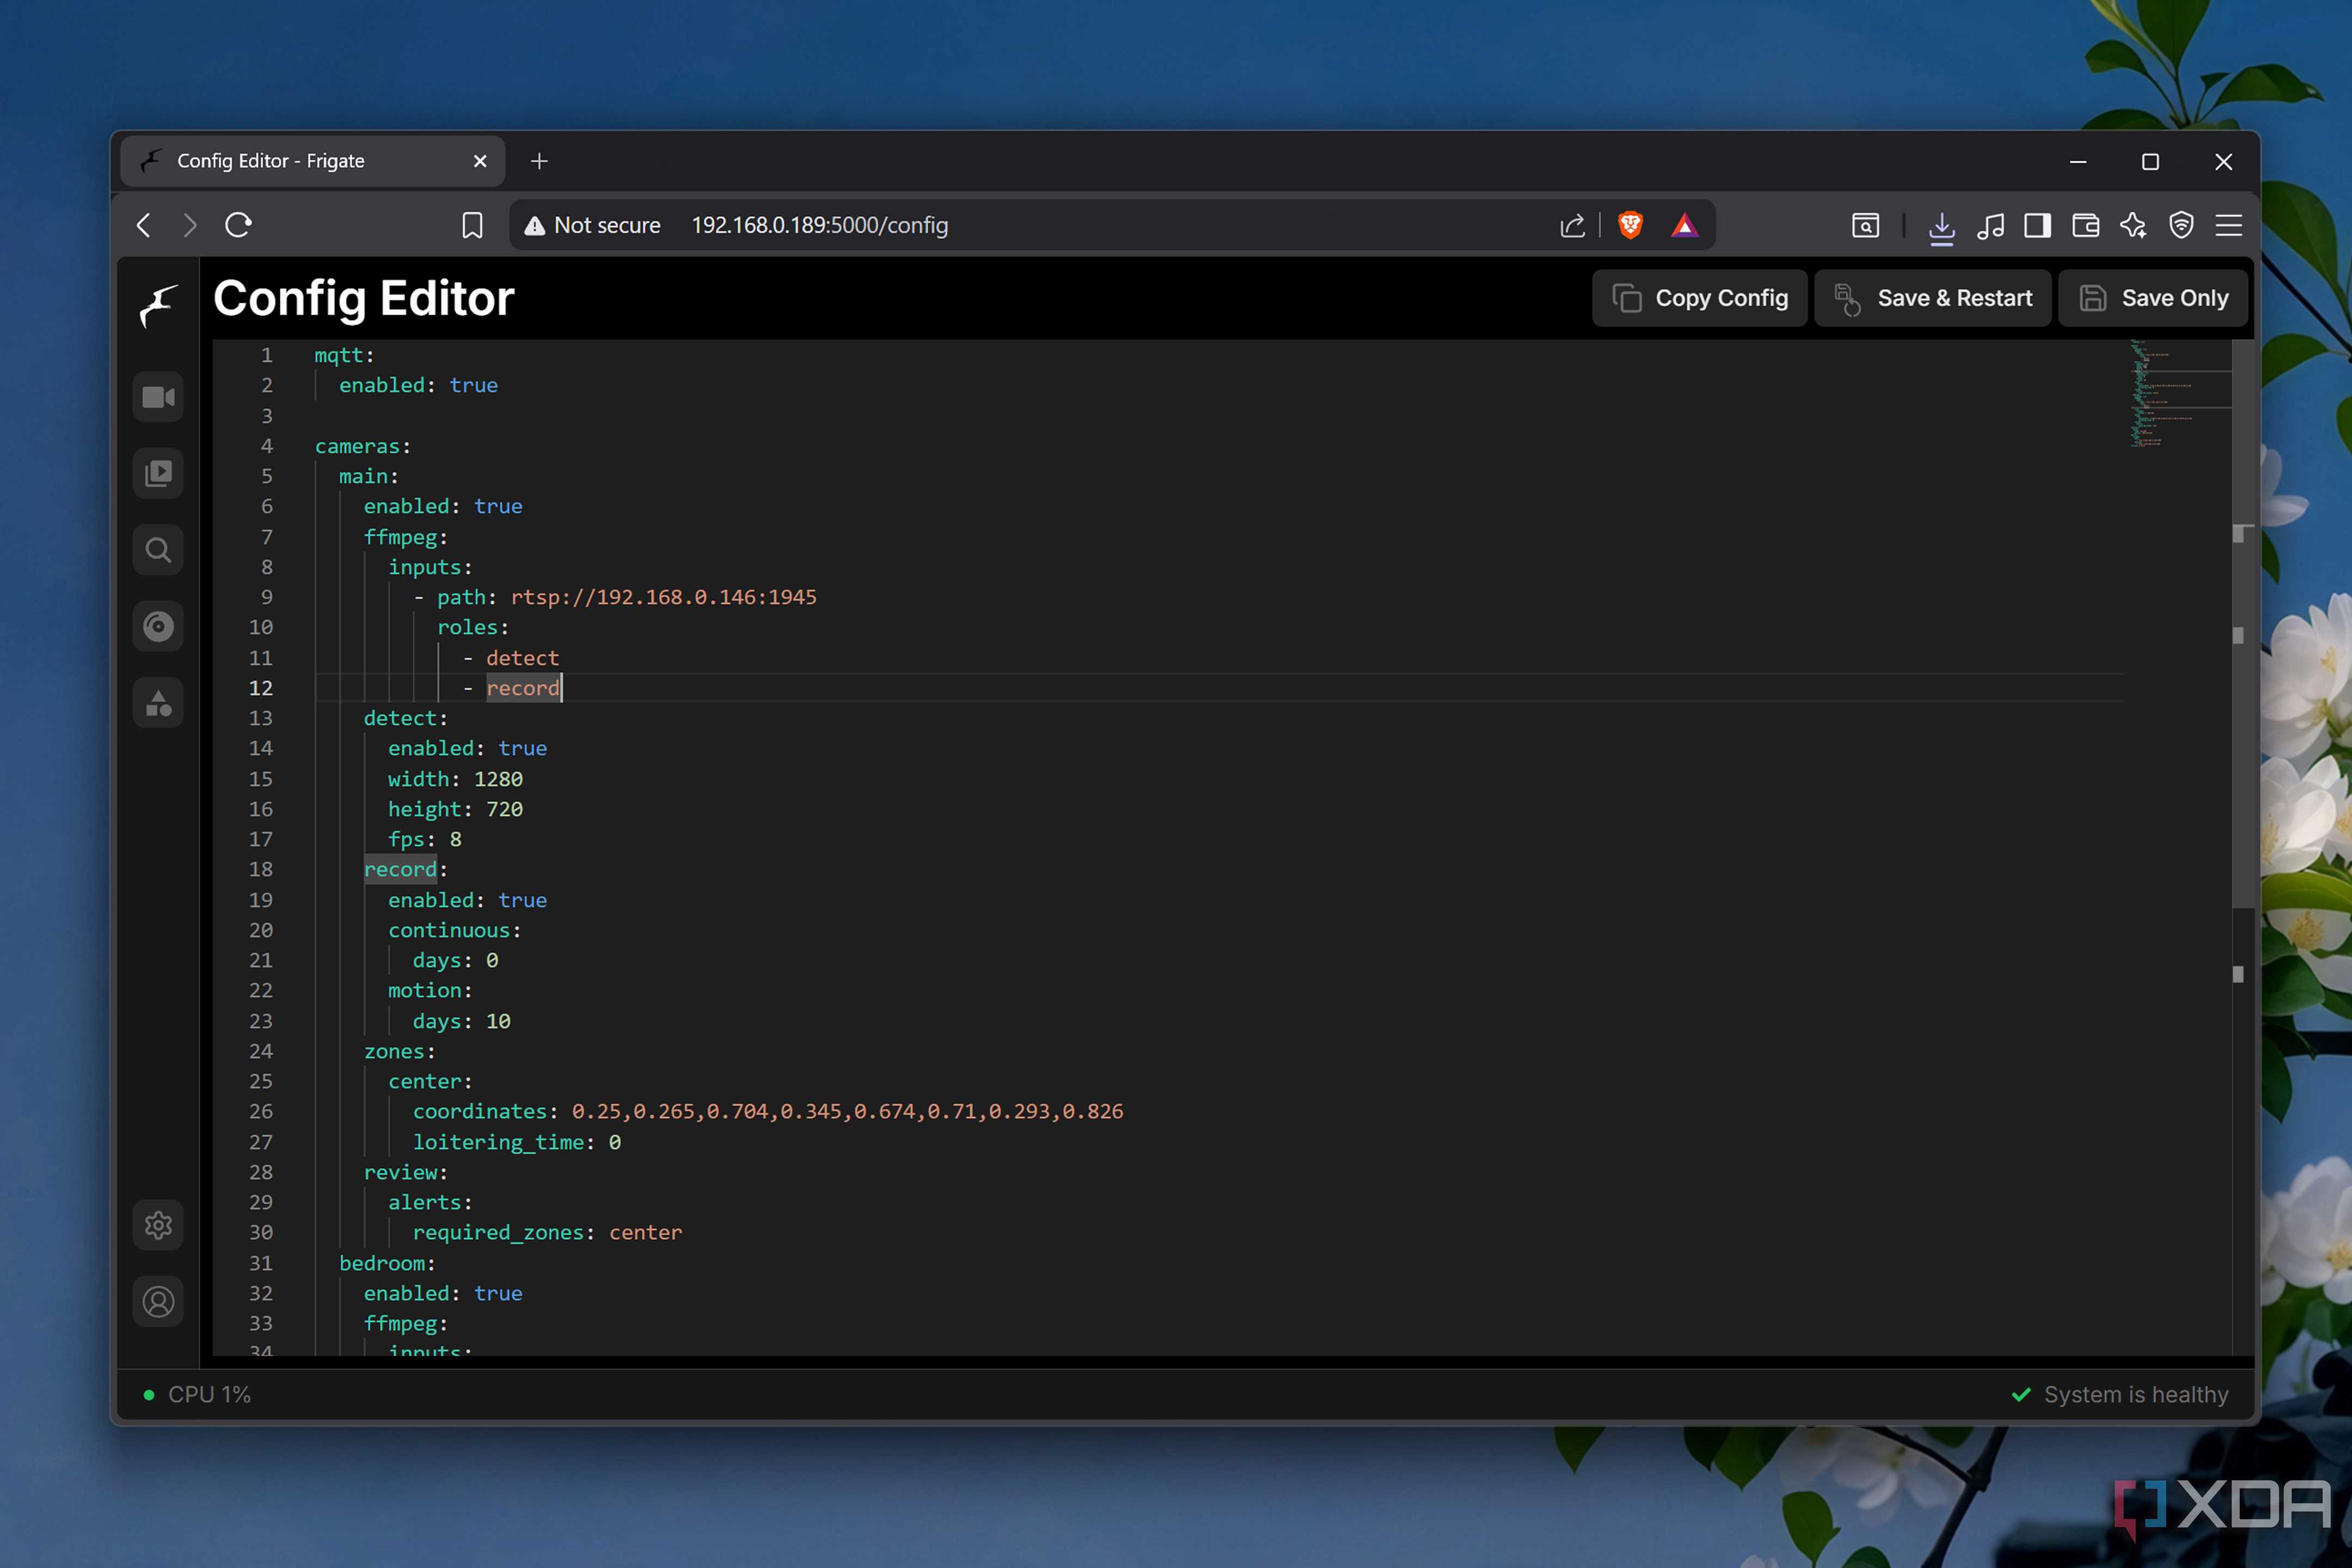
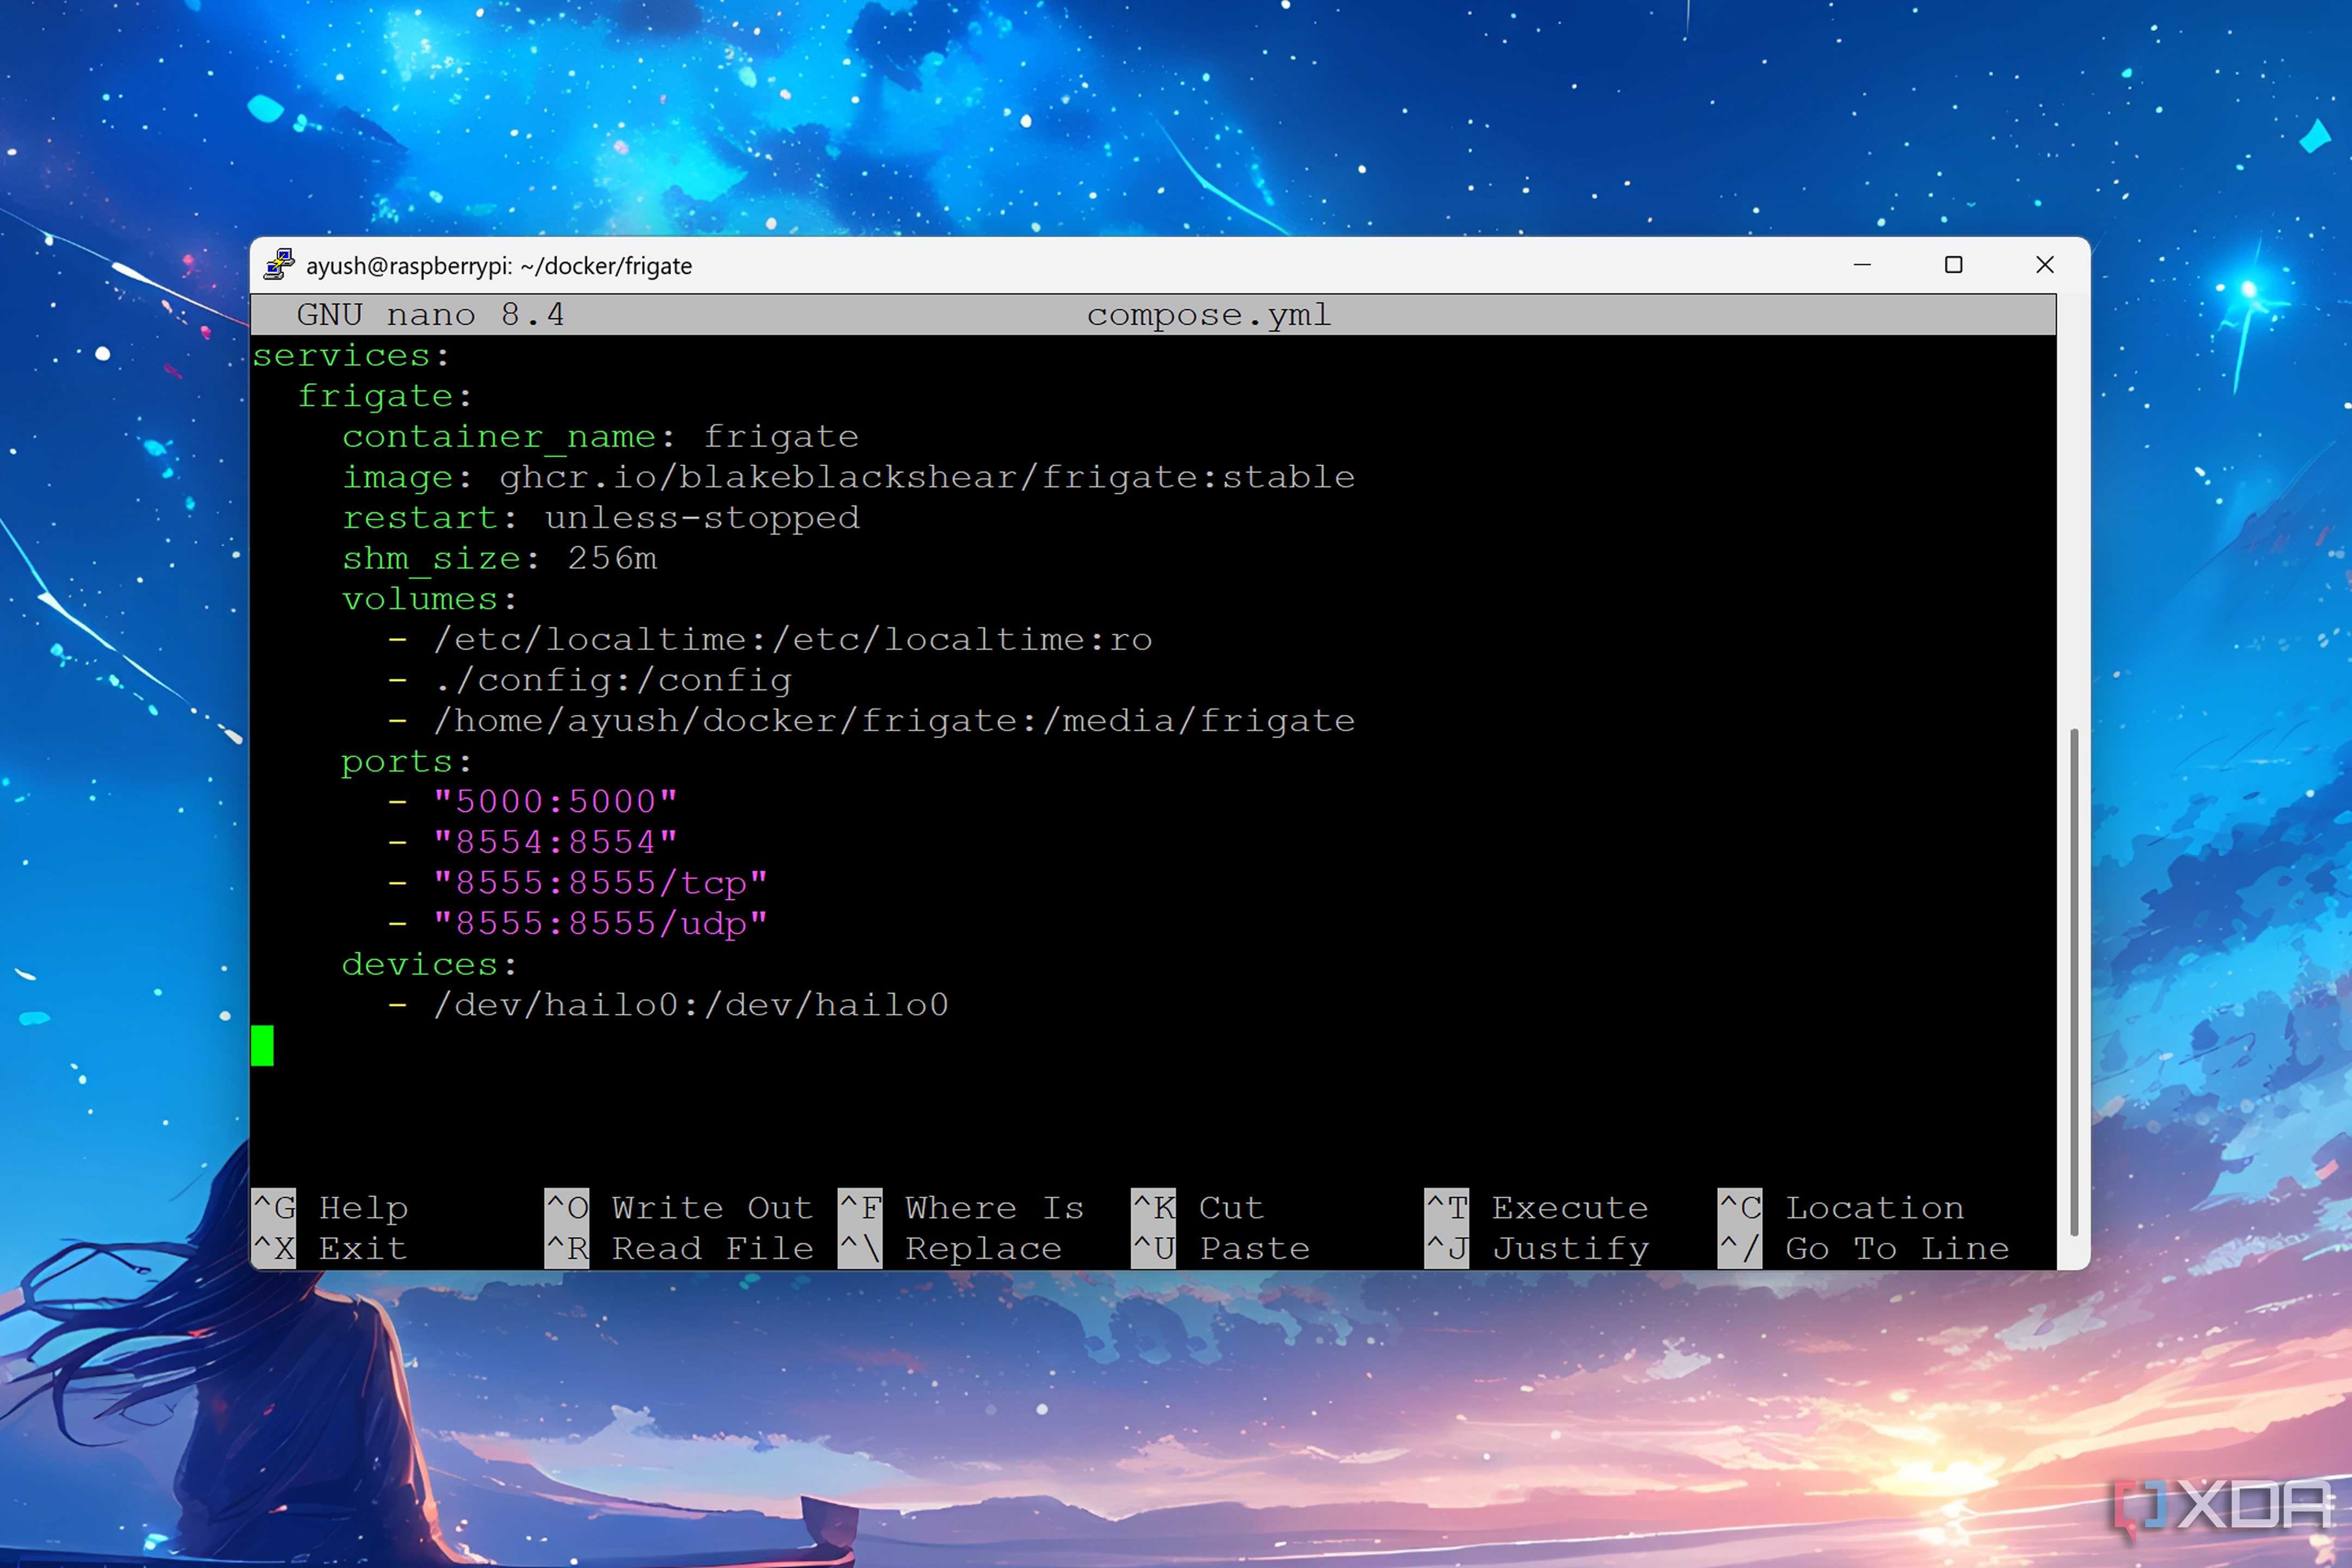
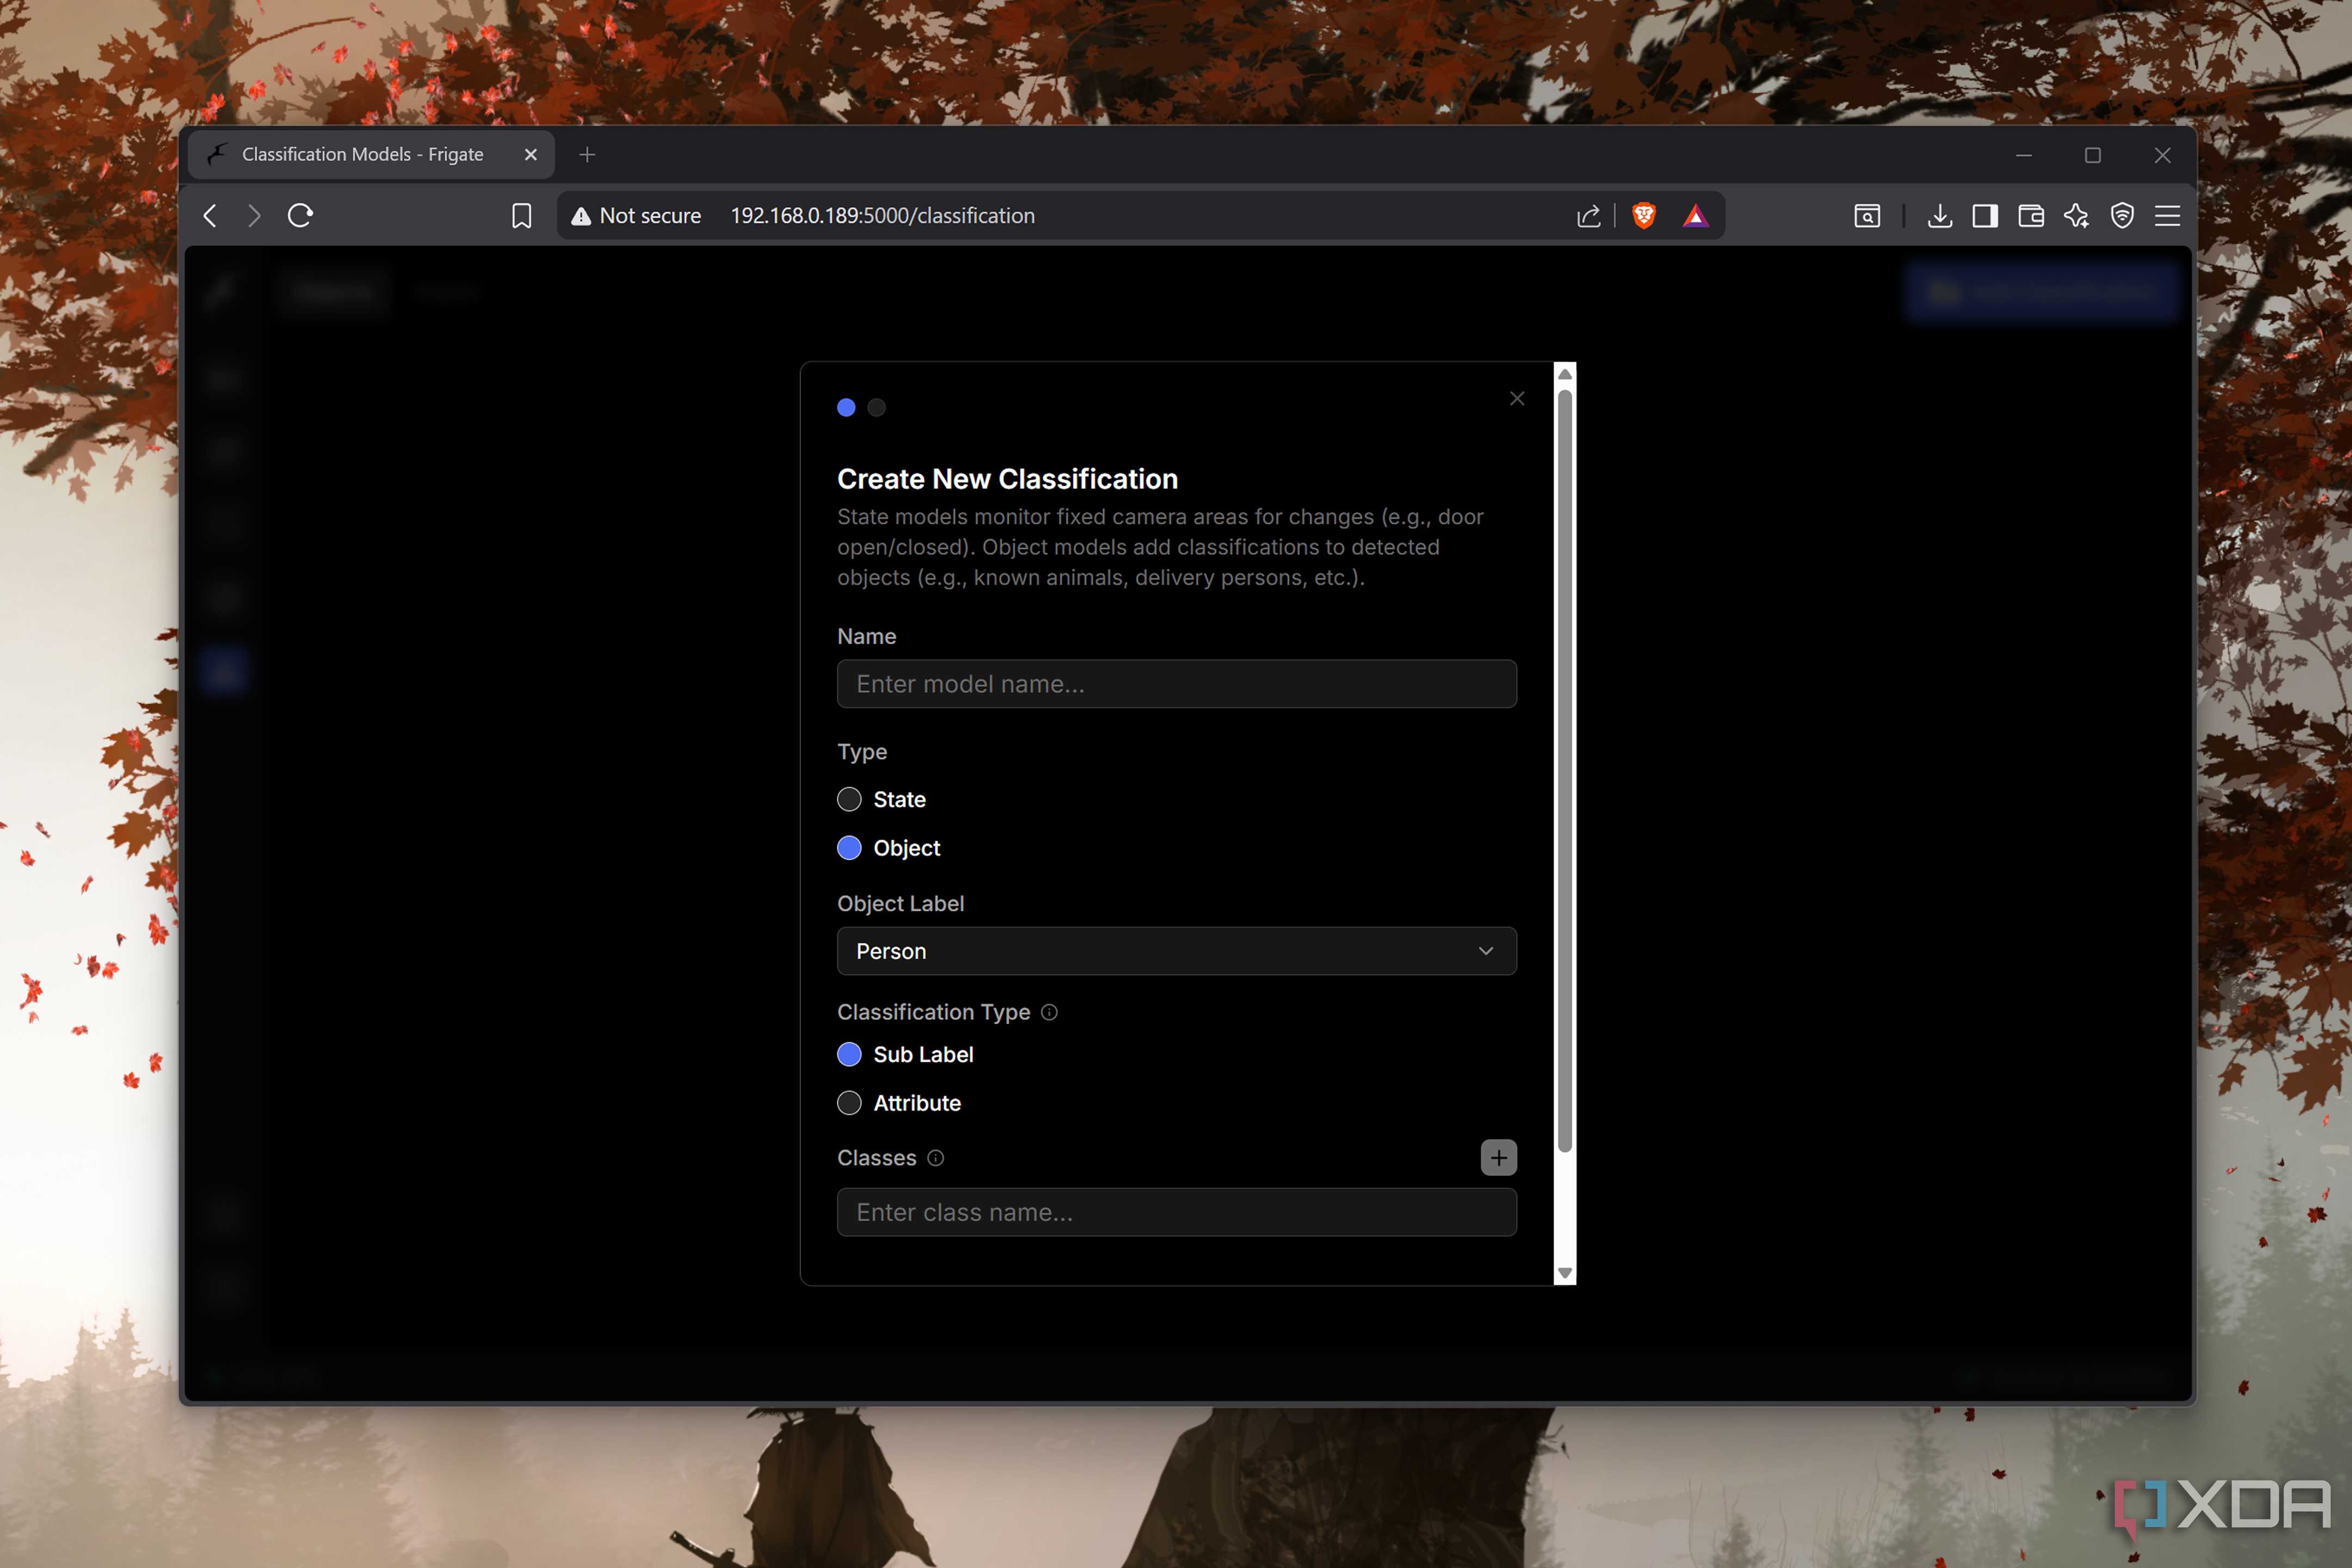
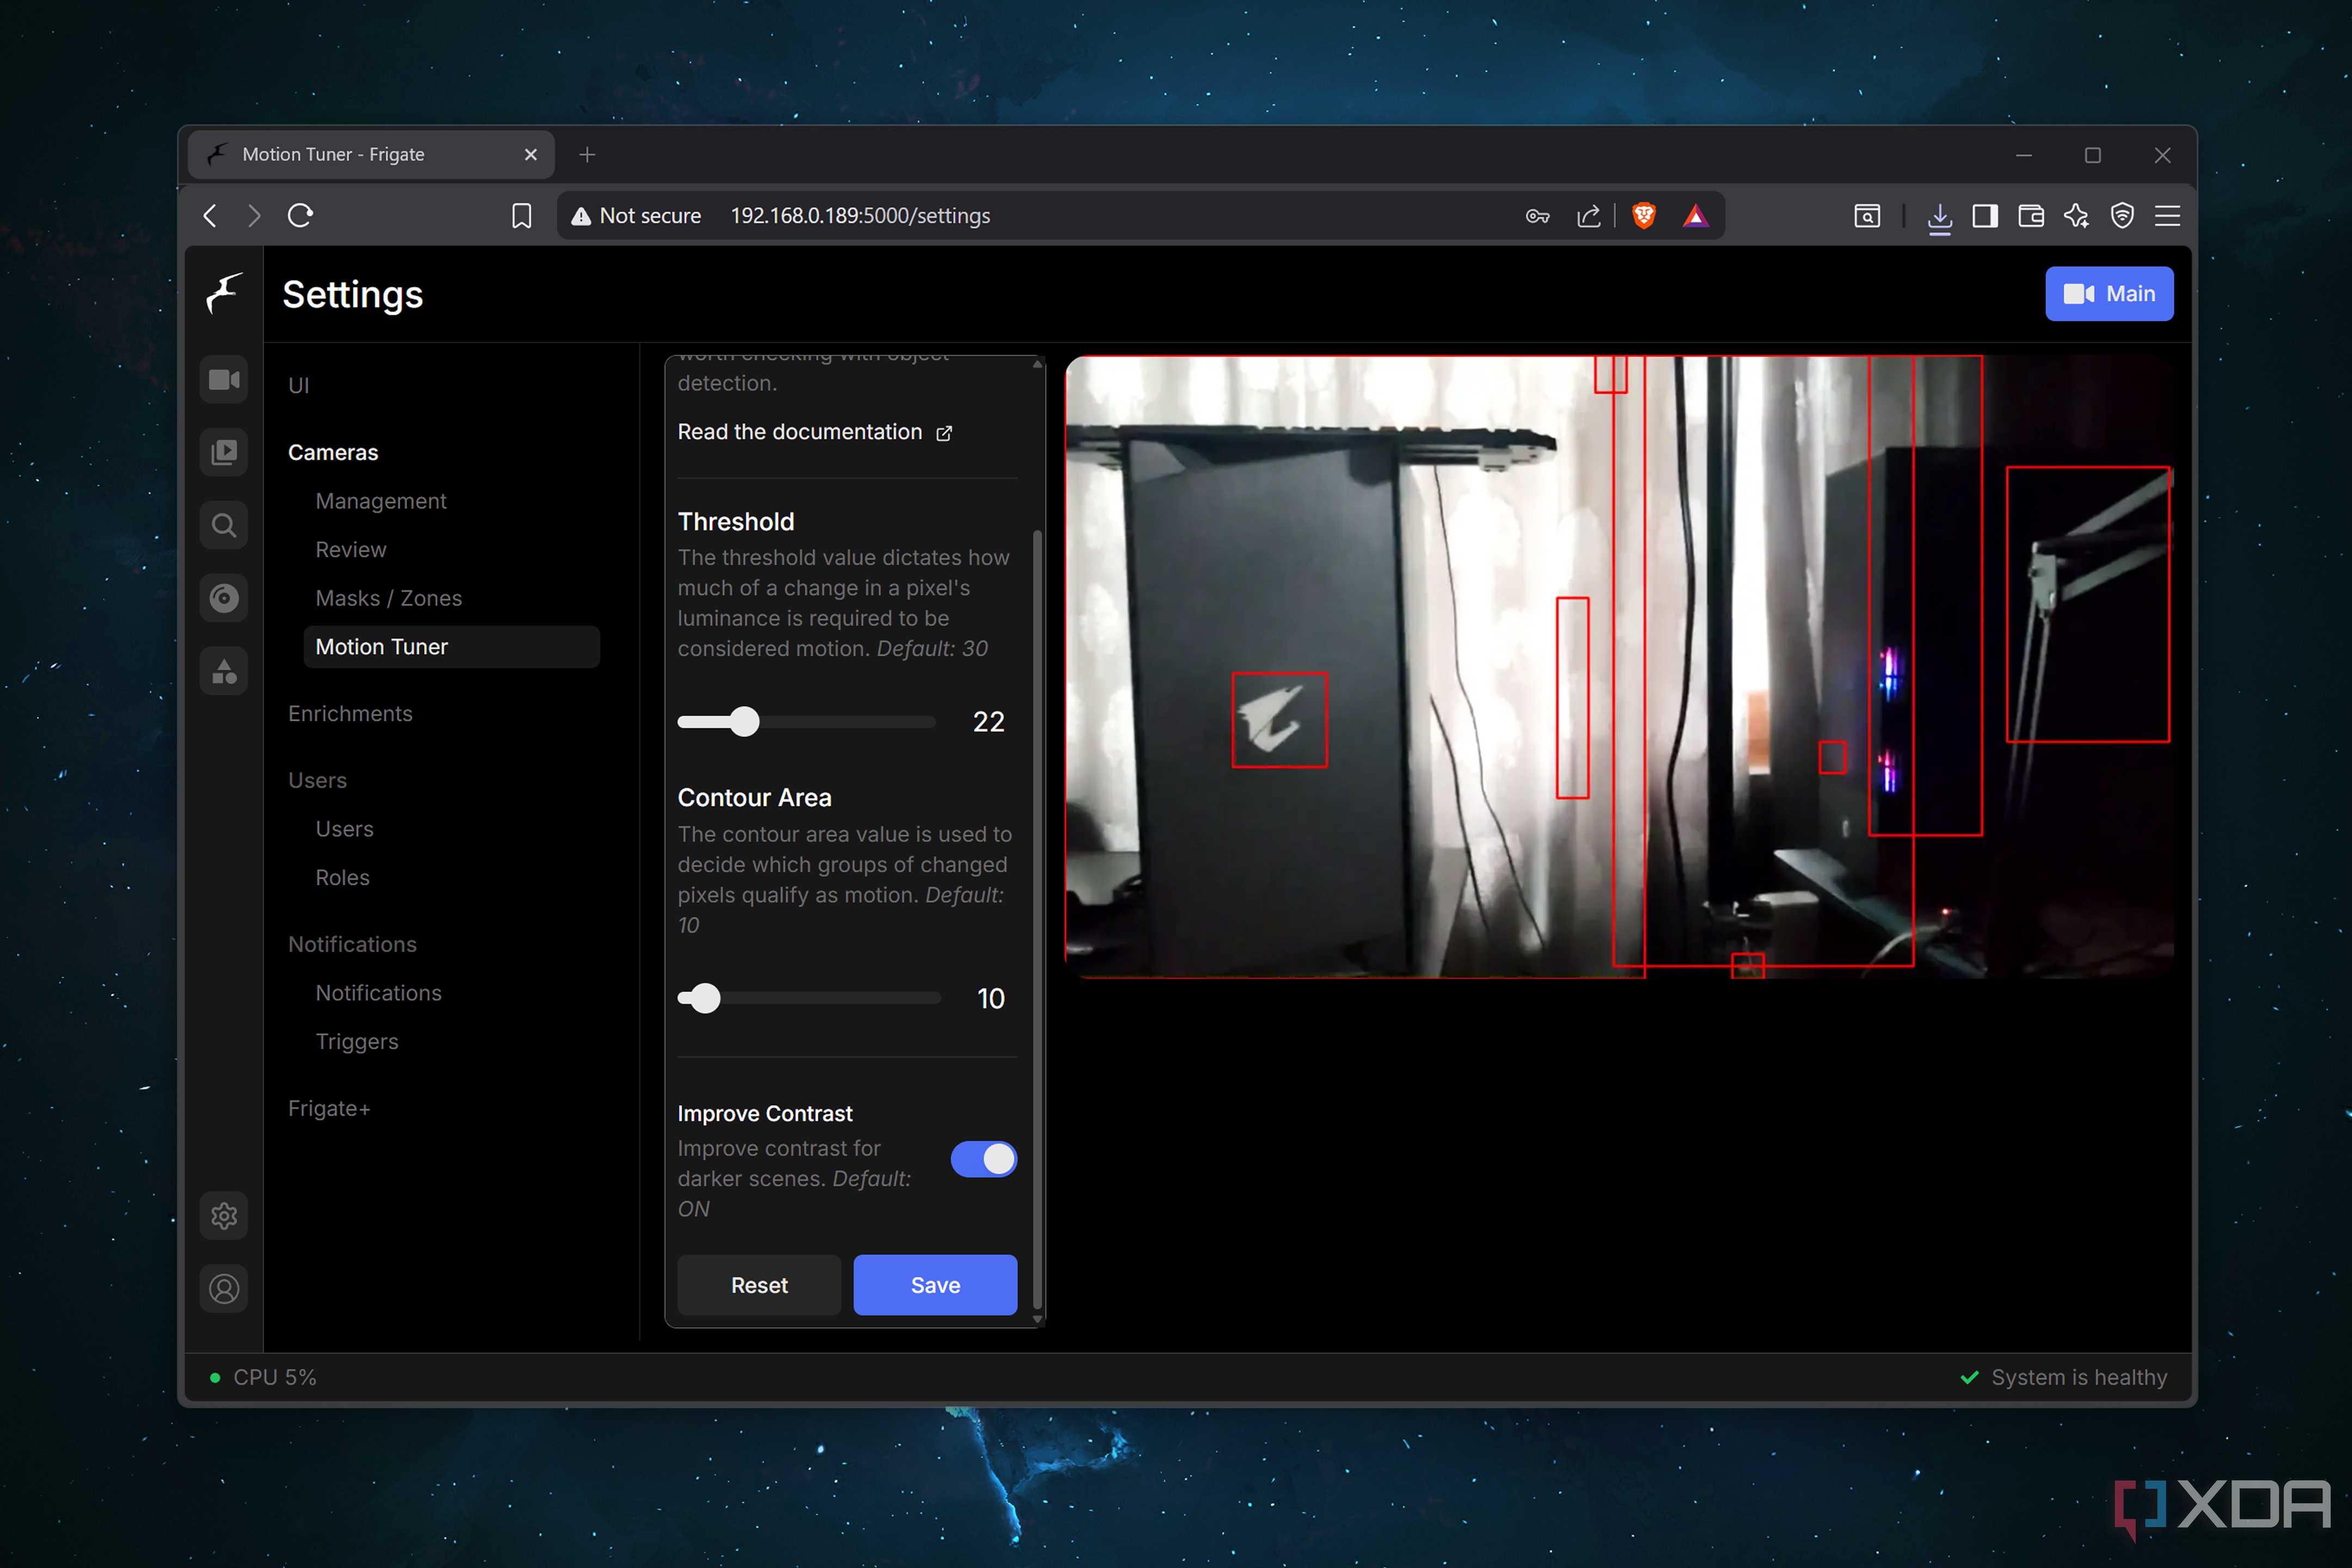
So far, I’ve only discussed models that I can run on my standalone Raspberry Pi 5. However, I can’t end this article without mentioning the object detection models running on my Frigate server. The Raspberry Pi Foundation released the AI Kit a while ago, and although it doesn’t support typical LLMs, it can drive YOLOv8 to detect simple objects on the security footage that my surveillance cameras pull into Frigate.
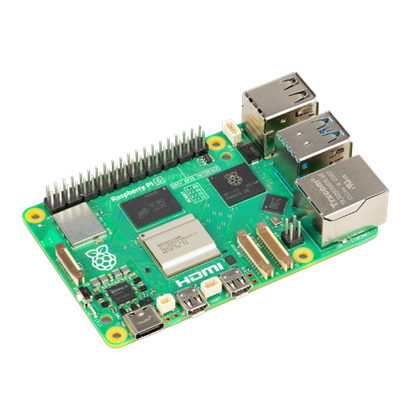
Raspberry Pi 5
- Arm Cortex-A76 (quad-core, 2.4GHz)
- Up to 8GB LPDDR4X SDRAM
- Raspberry Pi OS (official)
- 2× USB 3.0, 2× USB 2.0, Ethernet, 2x micro HDMI, 2× 4-lane MIPI transceivers, PCIe Gen 2.0 interface, USB-C, 40-pin GPIO header
- VideoCore VII
- $60