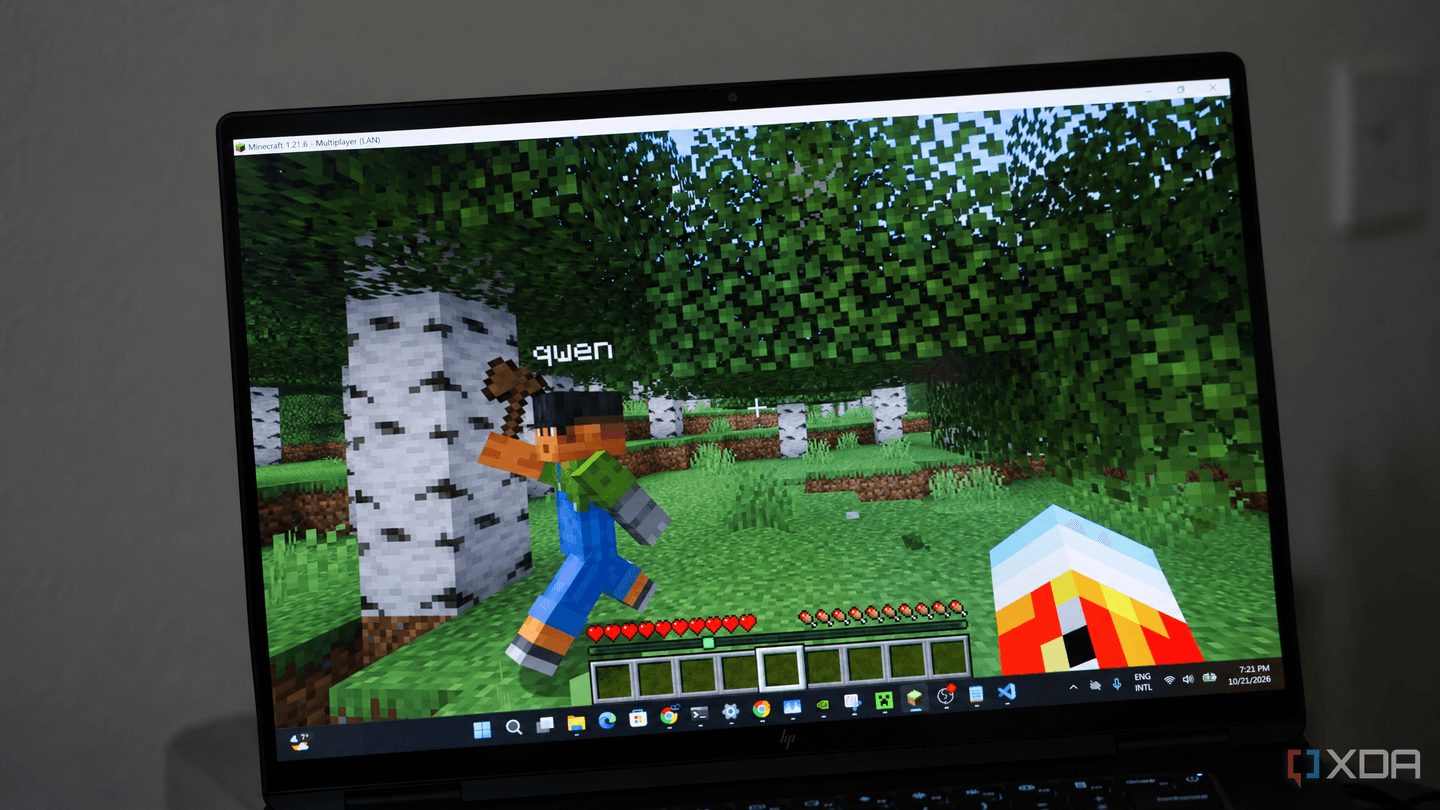
Running a local LLM and a game on the same PC usually means one of them will have a bad time. A typical gaming GPU with 16GB of VRAM might have enough memory for a decent model or a game, but running both at the same time? That's a pretty tall order, and it'll likely cause data to spill over into your slower system RAM.
Using the HP OmniBook Ultra 16, packing Nvidia's RTX Spark, combines a 20-core Arm CPU and a 6,144-core Blackwell GPU with 128GB of unified memory. Using Qwen 3.8 Flash Next, a 125-billion-parameter mixture-of-experts model, I was able to invite a bot to a Minecraft world over LAN. And thanks to the 128GB of VRAM, I was able to play Minecraft and have the model control the bot at the same time.
Is it perfect? Absolutely not; the bot takes a while to respond, occasionally promises items it doesn't have, and at one stage, jumped into a hole in the ground before disconnecting from the server. With that said, it works, and Minecraft was running at around 120 FPS for much of the session, even with the model running alongside it.
Mindcraft turns a language model into a Minecraft player
Not a very good one, mind you

The bot uses Mindcraft, an open-source project built on Mineflayer, a Node.js library for creating Minecraft bots. Mindcraft connects the bot to your world like any other player, and you interact with it through the in-game chat. When you ask it to do something, the model has tools available to it that come through in the form of commands. For example, I asked it to bring me 10 birch longs, and it sent "!collectBlocks("birch_log", 10)" into the chat before going ahead to do just that. Mindcraft handles the actual movement, mining, and inventory management, while the model decides what to do and narrates its actions.
Setting it up is straightforward. I opened my Minecraft world to LAN on a fixed port, connected Mindcraft to it, and ran node main.js. That also launches a web dashboard showing the bot's health, position, and inventory. Mindcraft doesn't have a dedicated llama.cpp option, but its LM Studio integration uses an OpenAI-compatible API with a configurable address, so I pointed it at my local llama.cpp server.
You can also set up vision, and commands such as !lookAtPlayer capture an image from the bot's perspective and send it to the model, allowing it to see what's happening around it. Mindcraft also includes premade tasks, ranging from collecting four logs to building a church from a blueprint, which are useful for testing the bot immediately and ensuring that it works.
You can also have the model run JavaScript on your computer, through a !newAction command. I left this switched off, but it means you can ask it to do things outside of the game with the outputs piped back into the game chat.
But one doesn't affect the other

Nvidia provides llama.cpp recipes for running models on RTX Spark, and I used the Qwen3.8-Flash-Next recipe to get things up and running. This includes vision support and an MTP draft model for speculative decoding, with llama.cpp serving the model through an OpenAI-compatible API on port 9931. Before launching Minecraft, I measured roughly 46 tokens per second at a short context, dropping to just under 42 at 32,000 tokens.
Qwen 3.8 Flash Next is a mixture-of-experts model with 125 billion parameters, but only around 6 billion are active per token, and its 51-billion-parameter n-gram embedding is streamed from storage rather than kept entirely in memory. It uses a huge amount of memory for a local LLM, but the laptop's 128GB unified memory pool means that there's more than enough room to run Minecraft alongside it.
Better yet, Minecraft runs natively on Windows on Arm, with Arm64 builds of Java and the required graphics libraries, so there's no need for Microsoft's PRISM x86 emulation. I was getting around 120 FPS for much of the session, even with the model running alongside it.
There also doesn't need to be any special arrangements made when it comes to GPU scheduling in order for this to work. Nvidia has its NVIGI SDK which supports optimizations for running AI workloads alongside games, but its CUDA in Graphics feature isn't currently supported on RTX Spark. In other words, the llama.cpp server and Minecraft are both sharing GPU resources without those optimizations, but thankfully, Minecraft isn't a particularly demanding game. I've previously run Cyberpunk 2077 at 1440p on a ThinkStation PGX using the same GB10 silicon, and I'd expect a game of that calibre to suffer a whole lot more if a 125B model were running alongside it.
It handles simple jobs well enough
Birch logs, saplings, and dirt
Once Qwen joined my world, it proceeded to act like an eager but slightly confused friend. It greeted me, narrated everything it was doing, and asked for instructions when it was idle. When I told it to collect birch logs, it sent a message that said !collectBlocks("birch_log", 10), walked to the nearest trees, and started chopping. There's a noticeable delay between asking it to do something and seeing it act, as the model needs to process the conversation and generate its next command.
Gathering materials is arguably where it works best; after it collected all of those birch logs, I asked it to hand over the saplings it had picked up as well from the decaying trees. It replied "Sure, here are your saplings," walked over, and dropped eight of them at my feet. It's pretty cool to see, so I upped the ante a bit. I asked it to collect roughly 30 blocks of dirt, and it replied "On it" before digging straight into the ground. That didn't go quite as smoothly.
The respones aren't canned, which is nice. When it joins the server (or rejoins), it'll give a unique greeting generated by the language model itself. It's a pretty small detail, but it adds to the experience of feeling like you're playing with another person than a script that's just executing commands.

The bot makes plenty of mistakes, too. When I first asked it to hand over the birch logs it had collected, it replied "Sure, here you go" and tried to give me ten. There was just one problem: it didn't have any, because I had put it in Creative mode at first by mistake. Mindcraft's logs, though, said that it never got the items, and the model quickly corrected itself: "I don't have any birch_logs in my inventory right now. Let me gather them again for you." It's a pretty human way to handle being caught out, at least.
On several occasions, the bot tried to call the !newAction command despite it being disabled. For example, it would generate a plan to do a task I had asked it, like "Collect 5 more birch logs using the wooden axe," only to discover that code writing wasn't allowed. It would acknowledge the restriction in chat and offer to use Mindcraft's standard commands instead, which it should have done from the beginning.
On its quest to collect more birch logs when I asked, the bot took a running jump straight into a hole, before immediately leaving the game as soon as it fell. A few seconds later, it came back, announced that it was "Picking up item!", and carried on as though nothing had happened. It then dropped me the birch logs I'd asked for. Pretty neat.

Collecting dirt was a bit peculiar, too. The bot dug itself into a pit, sat there for a while, before announcing "I'm stuck!" followed by "Exiting." before disconnecting again. These errors come from Mindcraft's built-in unstuck system, which can detect when the bot hasn't moved for 20 seconds while carrying out a task. It first tries to move five blocks away, but if that fails after another ten seconds, it terminates the agent before trying again. Once it had rejoined, it announced "Got stuck there for a sec. Retrying now." and resumed digging. About a minute later, it moved over to me and dropped me half a stack of dirt blocks.
These navigation problems aren't caused by the model, nor do they have anything to do with performance. Mineflayer's pathfinding has some issues, and the model depends on Mindcraft to execute its instructions. It can decide to collect ten logs, but actually reaching the trees and collecting them is another matter. For the most part, the model understood what I wanted, even when the bot struggled to carry it out.
I wasn't really impressed by how intelligent the bot was (in fact, several amusing instances kind of swung the other way), but I was impressed that I could run the entire experiment on the same machine. Minecraft ran at basically 120 FPS the entire time, while a 125-billion-parameter model generated responses and decided what to do next in the background. All of the inference happened on the same machine, without a cloud API, and thanks to the 128 GB of VRAM on board, I didn't need to compromise on the size of the model just to make room for the game.
Mostly, though, it's just fun to play around with.