
Anurag is an experienced journalist and author who’s been covering tech for the past 5 years, with a focus on Windows, Android, and Apple. He’s written for sites like Android Police, Neowin, Dexerto, and MakeTechEasier. Anurag’s always pumped about tech and loves getting his hands on the latest gadgets. When he's not procrastinating, you’ll probably find him catching the newest movies in theaters or scrolling through Twitter from his bed.
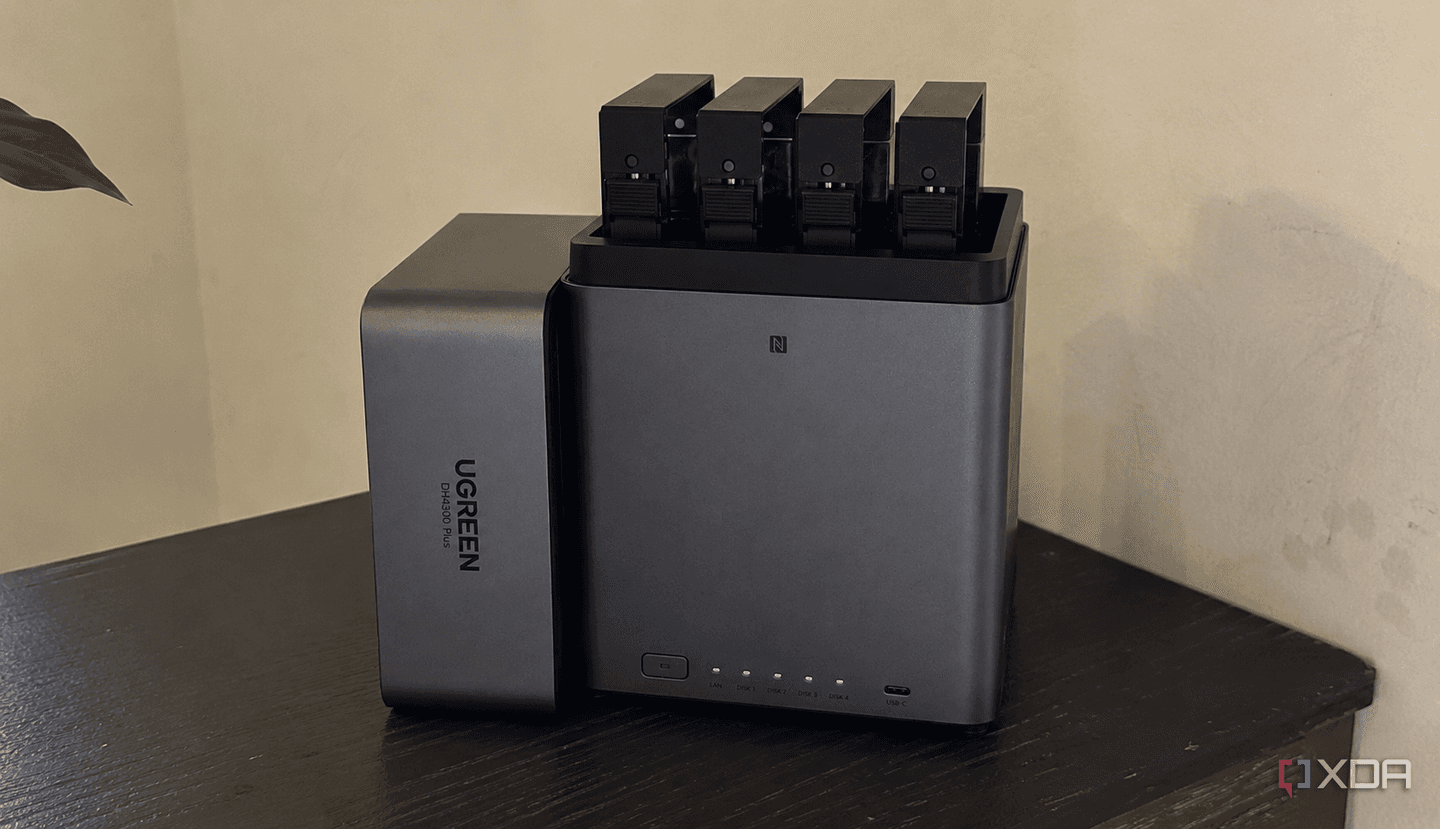
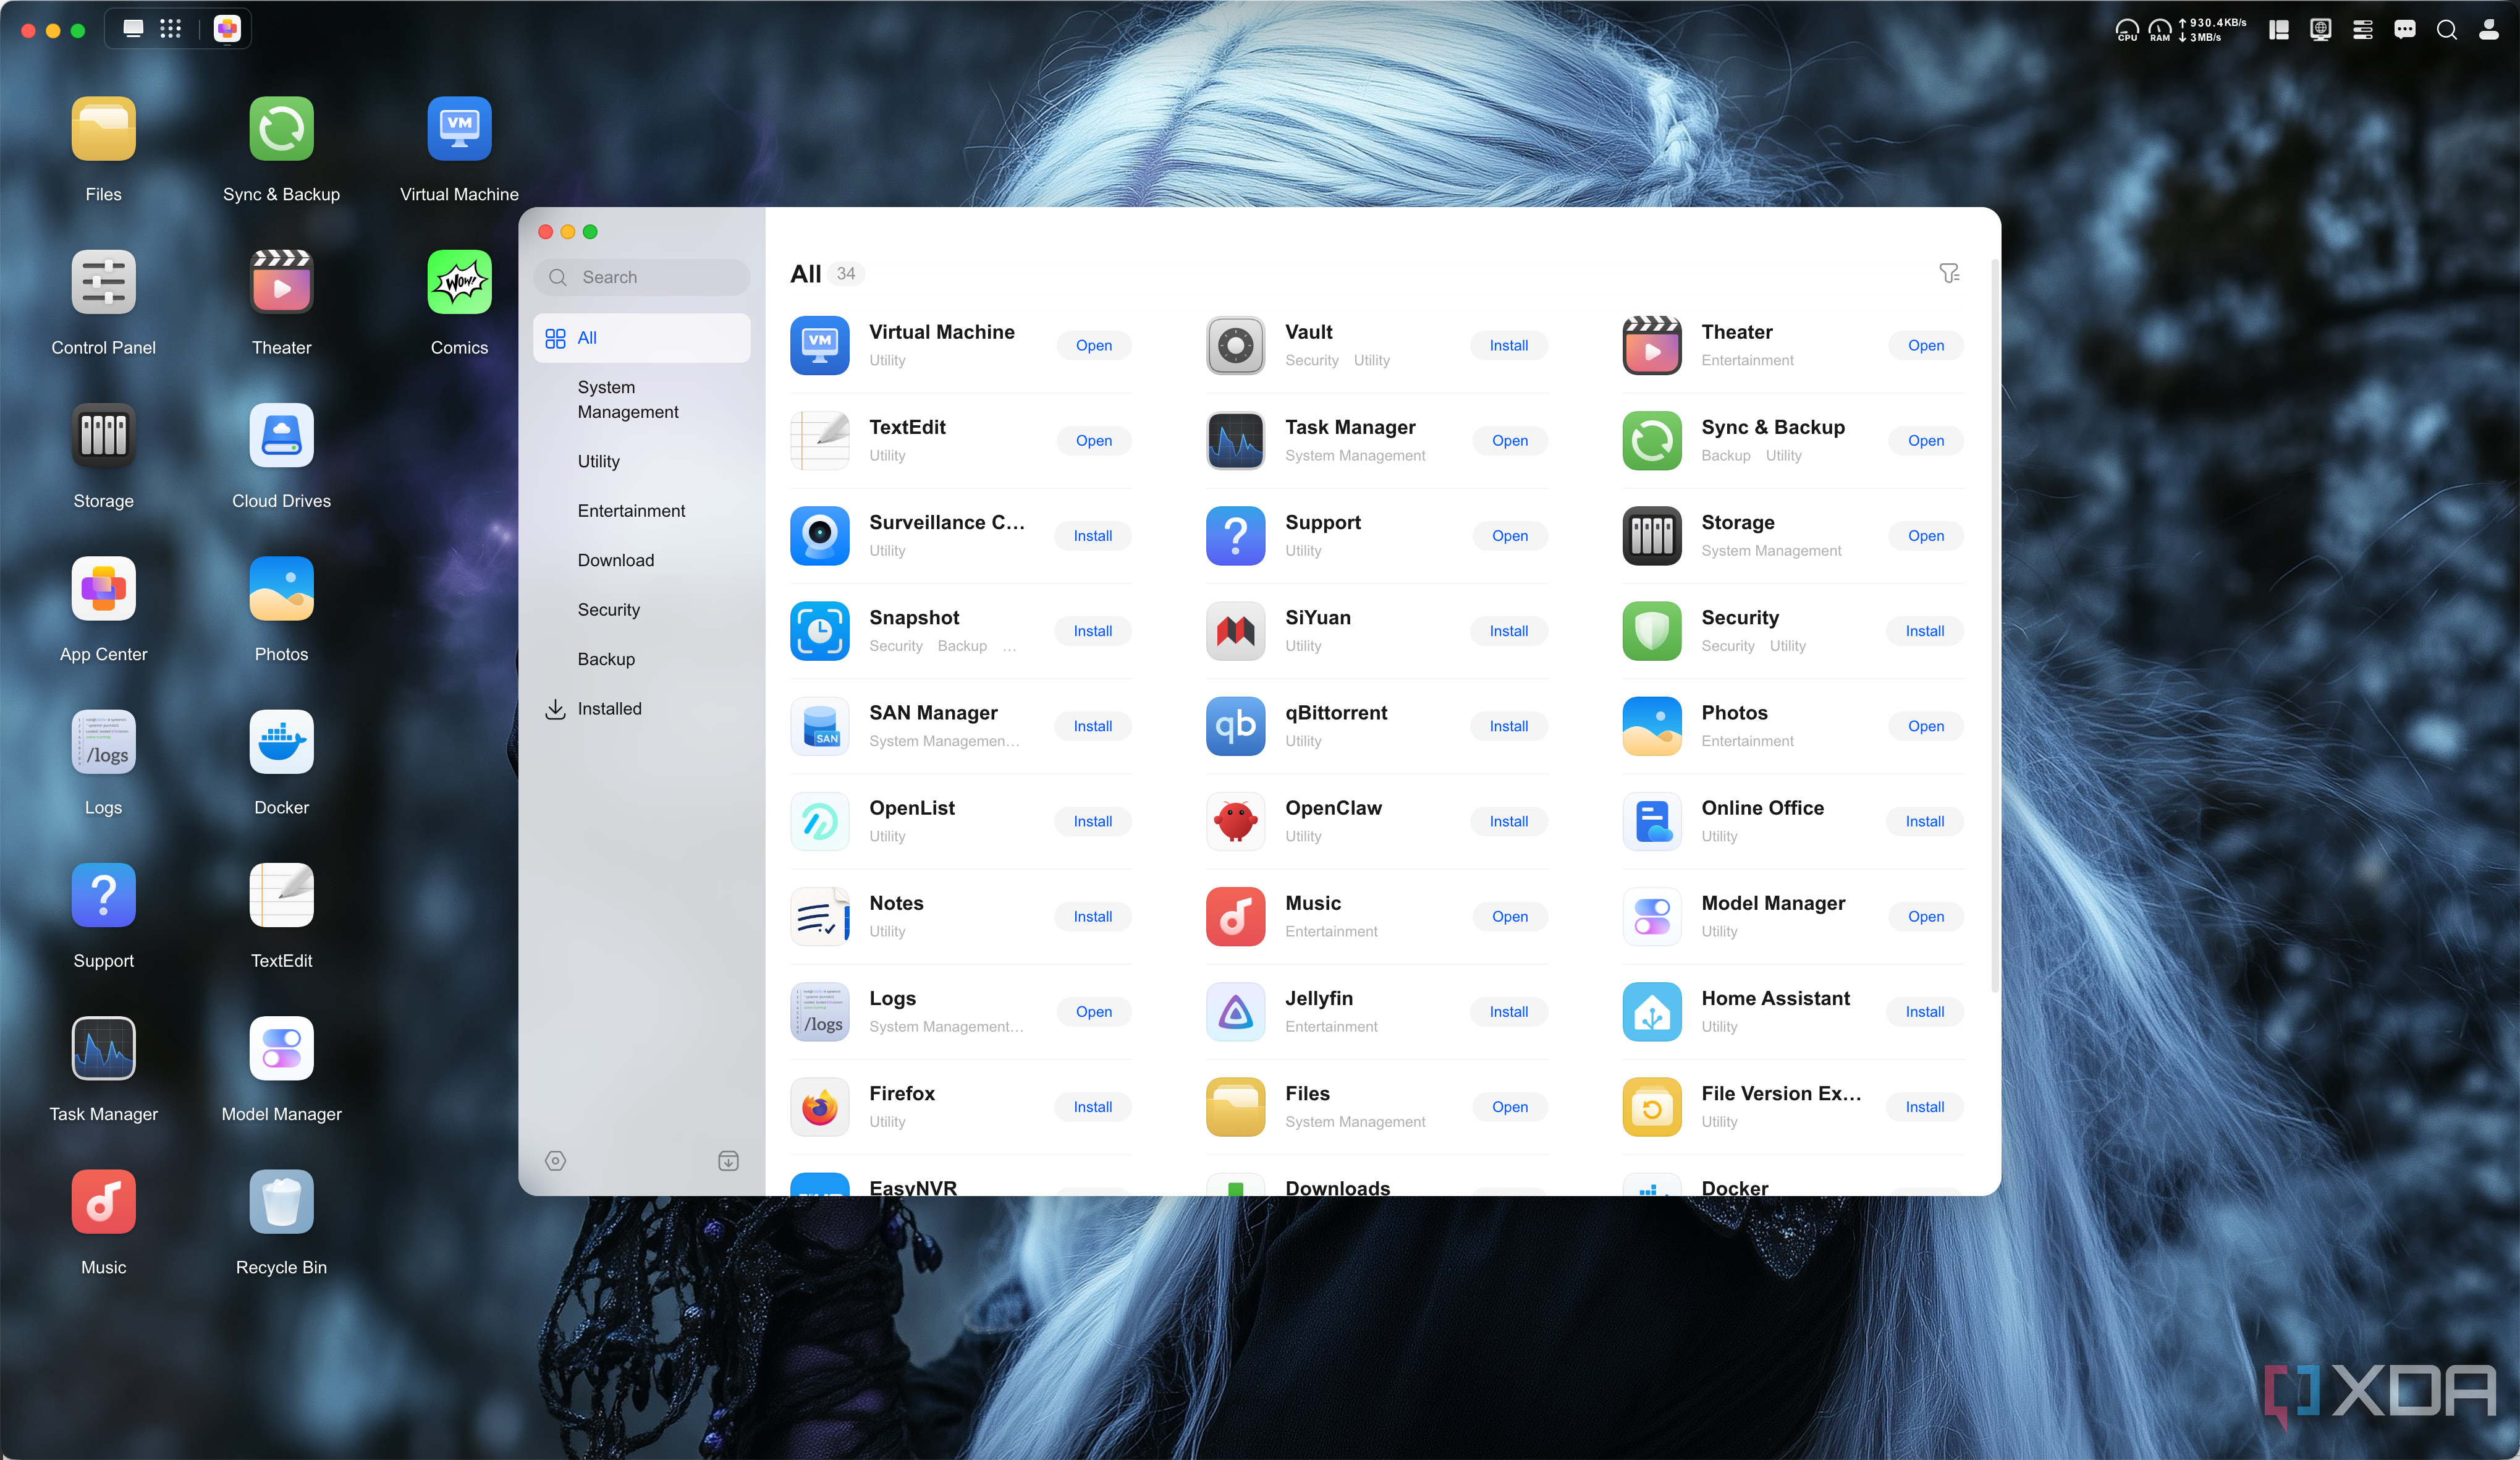
I use my NAS for storing documents, keeping backups, and running my Jellyfin library. Once everything is set up, there’s very little reason to open the dashboard every day. I can access my files from my computer and watch movies on the TV without checking what the NAS is doing in the background. I have to remember to check whether last night’s backup actually finished.
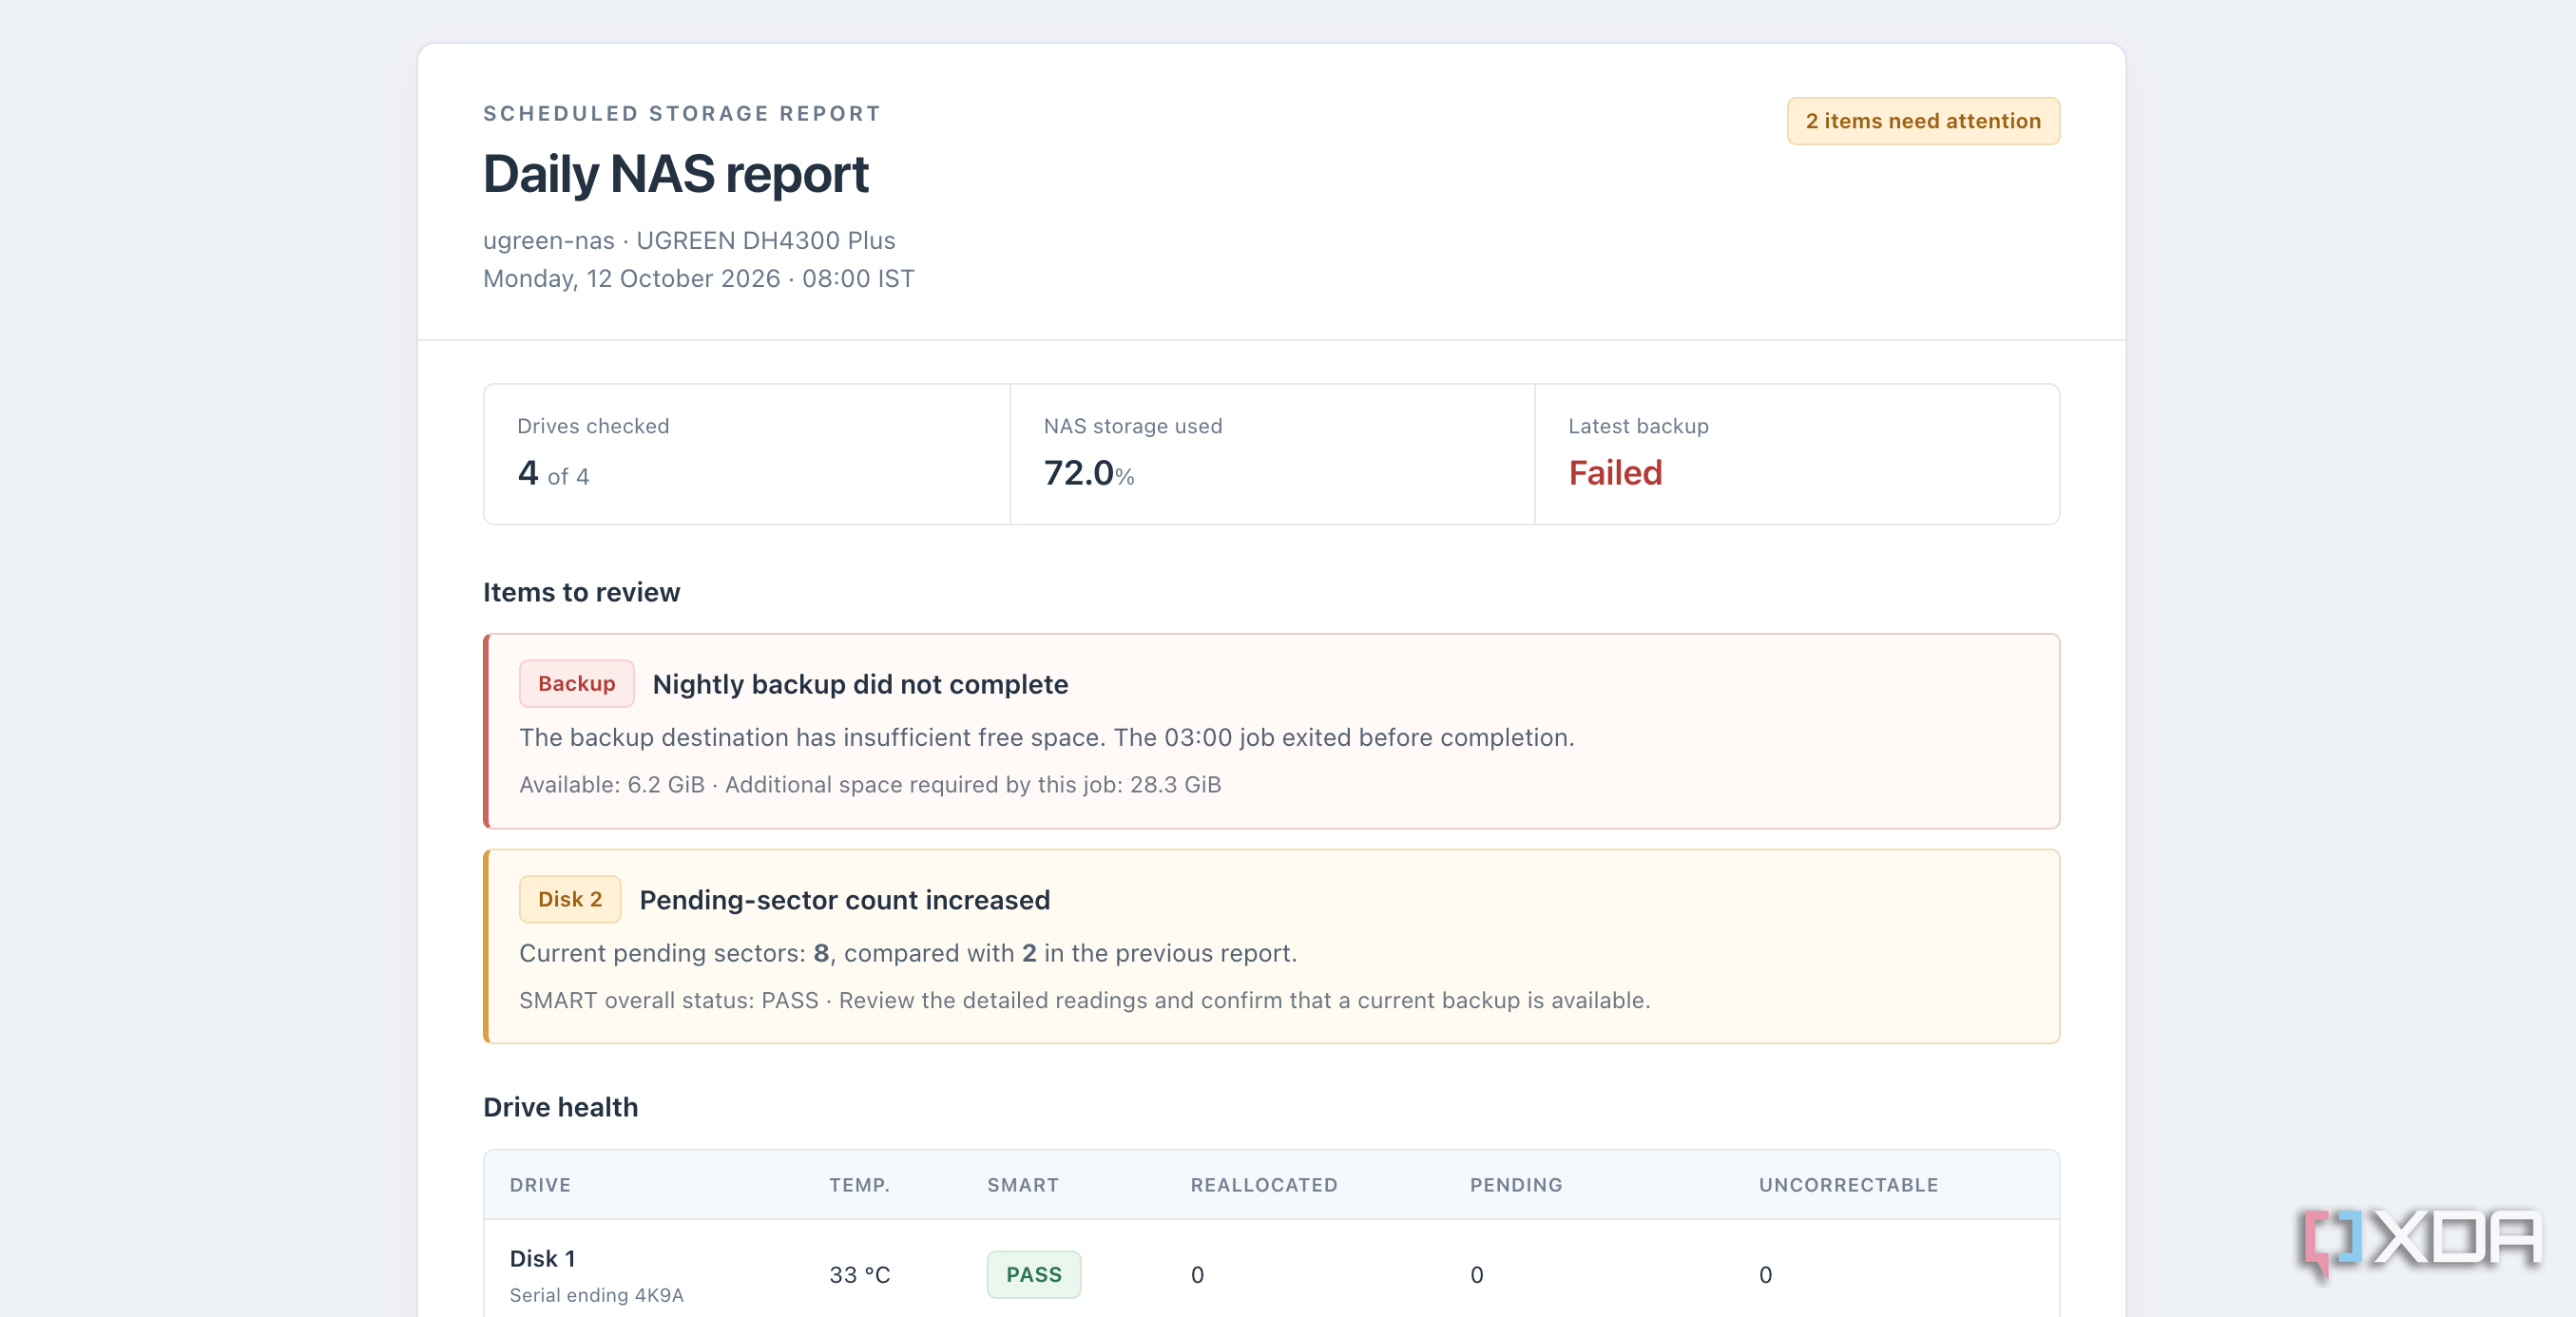
So I’ve set up a small Python script that checks the NAS and sends me a report every morning. I already check my email, so adding the report there makes more sense than giving myself another dashboard to visit. It has so far caught a backup that stopped completing and a concerning change in one drive’s health readings, both when I could still access my files normally.
I put the checks I kept forgetting into one morning email
And it's been a lifesaver

The script runs as a scheduled task on the NAS and puts the results into a short HTML email. It collects drive-health information through smartctl, checks available storage, and reads the backup logs. These are checks I can do myself through the dashboard and the backup application, so there’s no complicated monitoring setup involved.
For drive health, you want to see the temperature and unusual changes in the SMART readings. My script keeps the previous readings so I can compare them. If a drive starts reporting pending sectors, having yesterday’s value alongside the current one helps me see whether the count has increased. The report also identifies the affected drive, which saves me from having to work out which disk the warning refers to.
I've also added a backup section that shows the latest job result and when a backup last completed successfully. I also include available space on the NAS and the backup destination, since either one running out of room can wreck the whole backup strategy. I also include the collection time in the email. Also, if the script cannot read a drive or retrieve a backup result, that entry says the information is unavailable. Otherwise, an incomplete check could leave you with a reassuring report that hasn’t actually checked everything.
You realize how easy it is to miss failed backups
The report helps me catch those

One of the problems the report caught in my setup was an overnight backup that had stopped completing. The email showed a failed job and the timestamp of the last successful run. I could still open my documents and stream movies through Jellyfin, so I hadn’t noticed anything wrong during normal use.
The backup destination had run out of space. I found that in the job’s log after seeing the warning in the report. The files on the NAS were fine, and the older backups were still there. The problem was with anything I’d added or changed since the last successful backup. Those files weren’t getting the separate copies I expected them to have. I adjusted the backup retention settings to free up space on the destination and ran the job again, and that fixed things for me.
If you are wondering, I back up my NAS to a cheap cloud service called Backblaze, and it’s a lot easier for me to manage than backing up everything to another drive. It’s also much safer because a backup drive kept in the same location is still at risk of physical damage, and keeping it somewhere else is more work.
Discover issues before you actually lose your data
I have actually saved stuff before it got lost
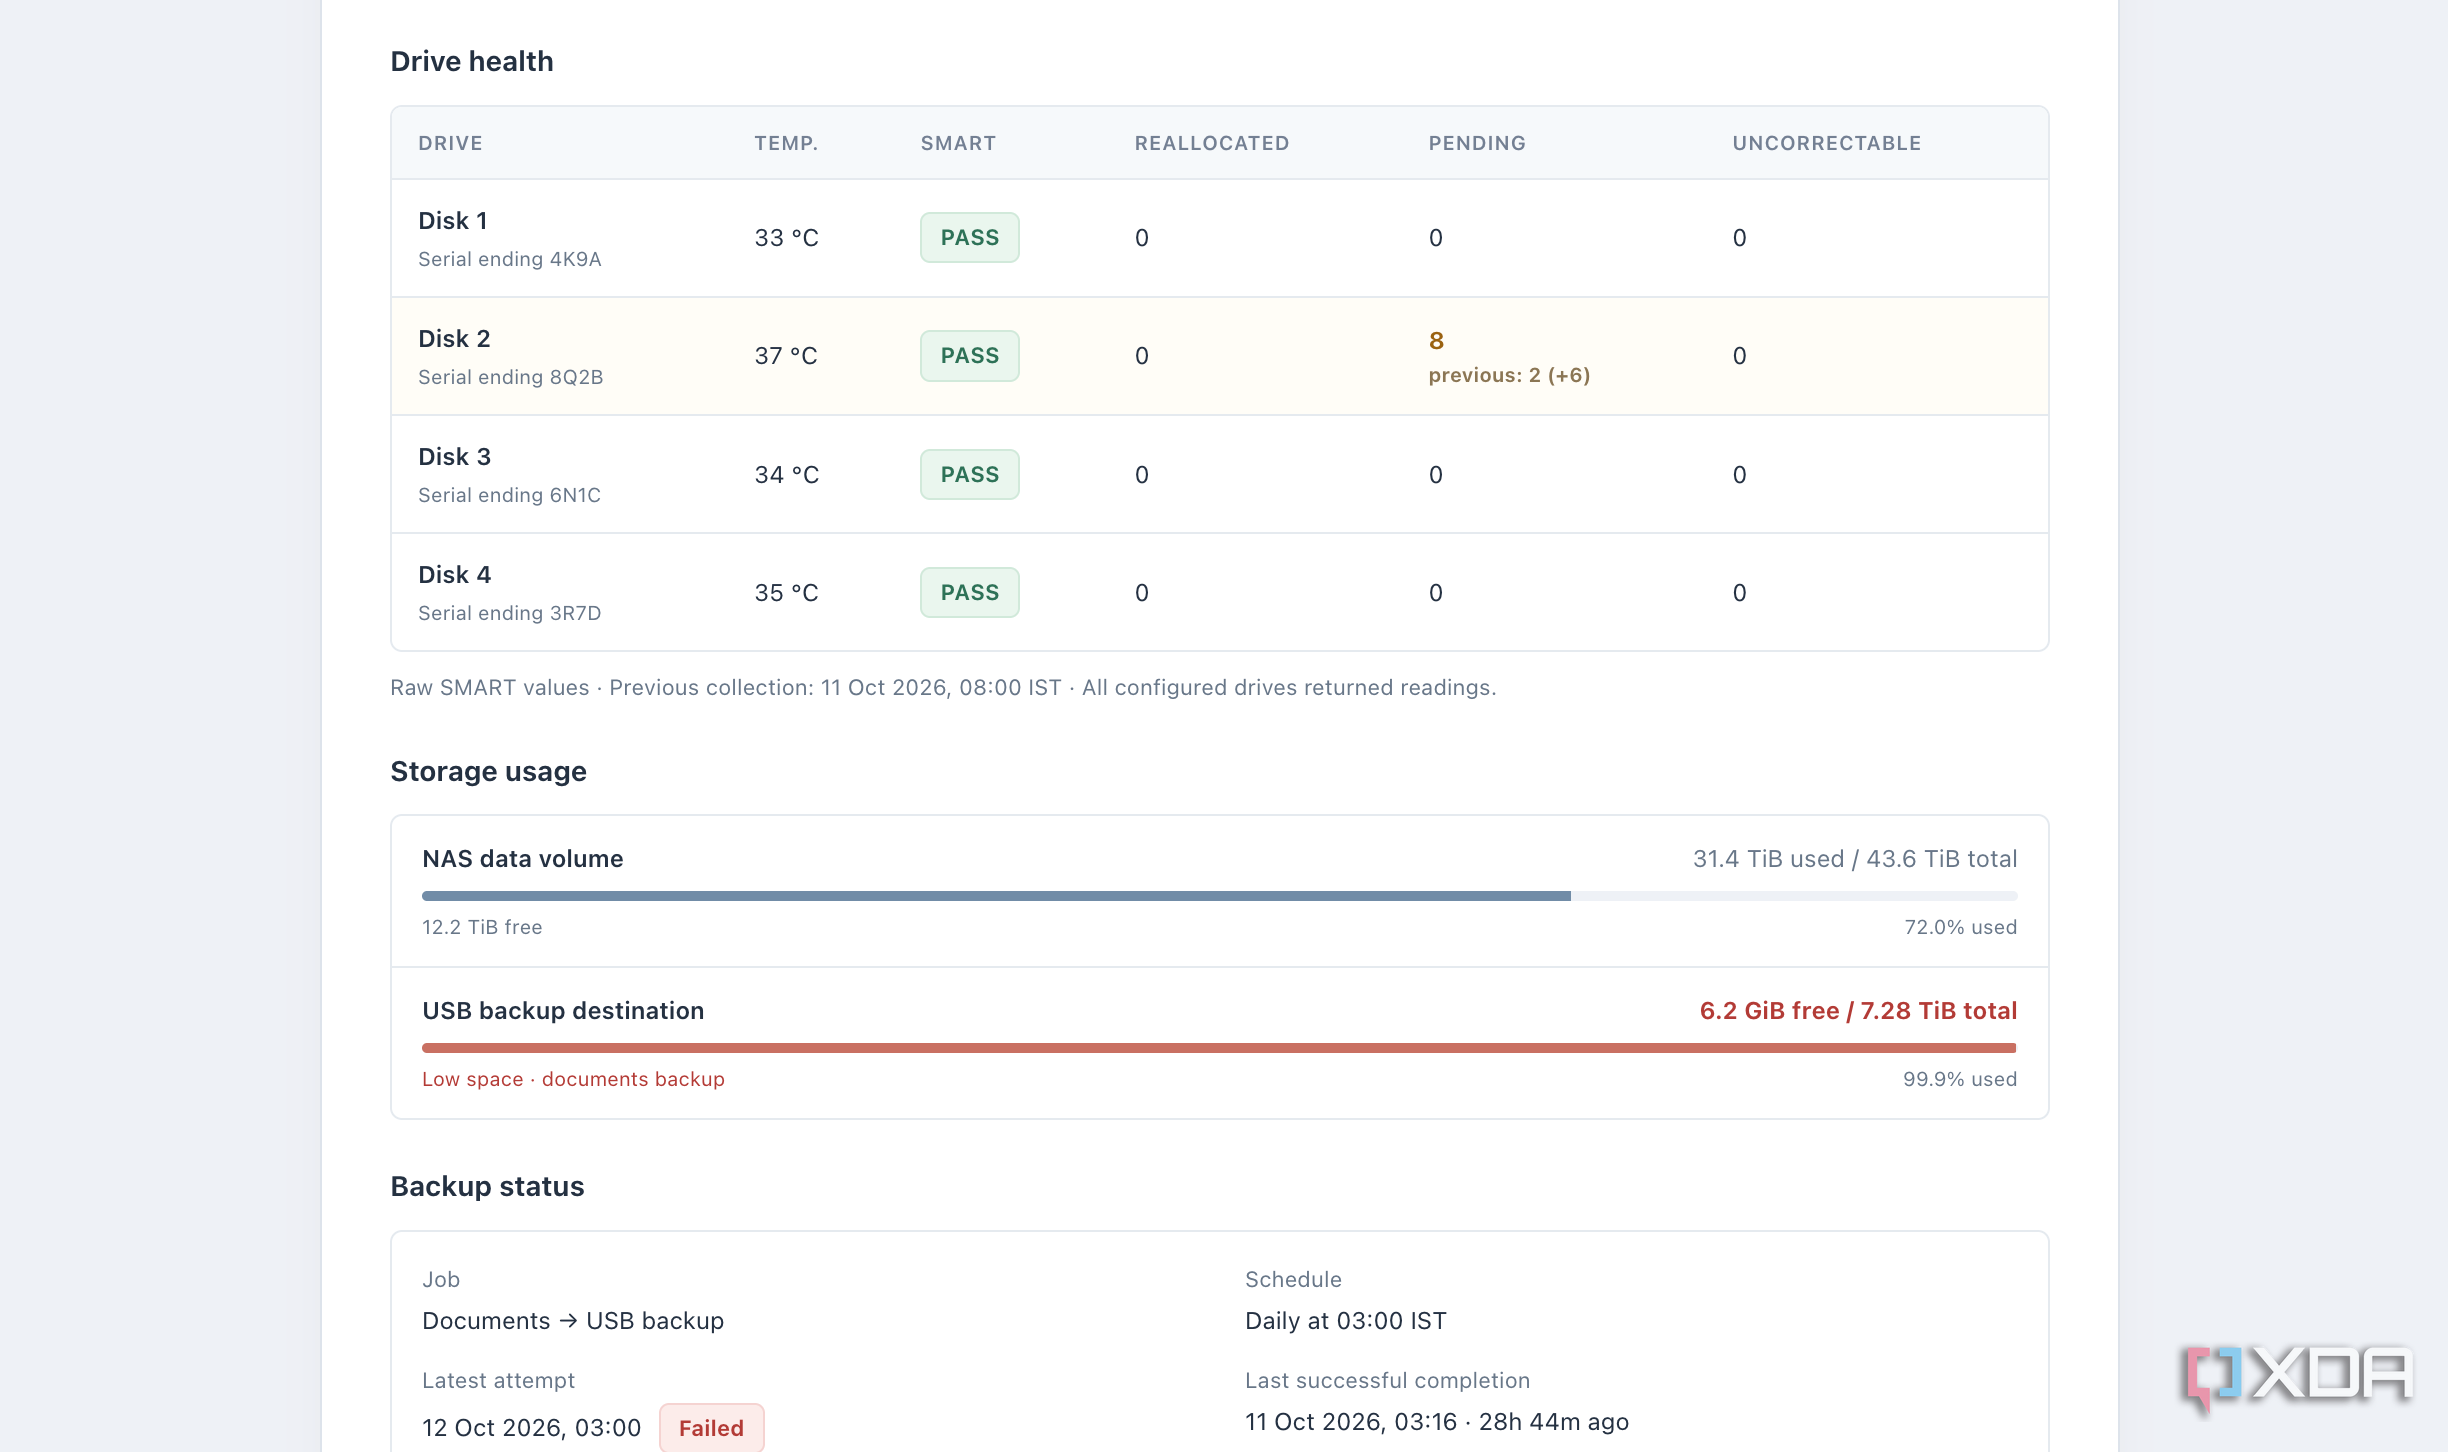
Another report flagged an increase in the pending-sector count on one of my hard drives. The NAS was still accessible, and I hadn’t encountered a problem opening files. I checked the drive’s SMART readings after seeing the change in the email.
Pending sectors are sectors the drive couldn’t reliably read and needs to reassess. The count gives you something to investigate, although it doesn’t tell you when a drive will fail. The previous reading in the report helped here, since I could see the value had increased. I keep the detailed readings in the report even when the overall SMART status says a drive has passed. That status doesn’t mean every reading deserves to be ignored, and an increasing sector count is worth checking.
The morning email also sits alongside the NAS’s immediate storage notifications. You don't want to miss out on urgent fault notifications while you wait for a schedule report, and there are instances when a drive fails without advance SMART warnings.
I’m keeping the morning report
I’ve put enough work into setting up my NAS and its backups that I want to know when something stops working, especially because it holds all my important data, and I’m trying to avoid the cloud wherever I can. Just make sure that the email you send to yourself is short because the whole point of this is to get a snapshot of everything you need to know. If you turn it into a whole report with multiple things, the email itself will become something you avoid.