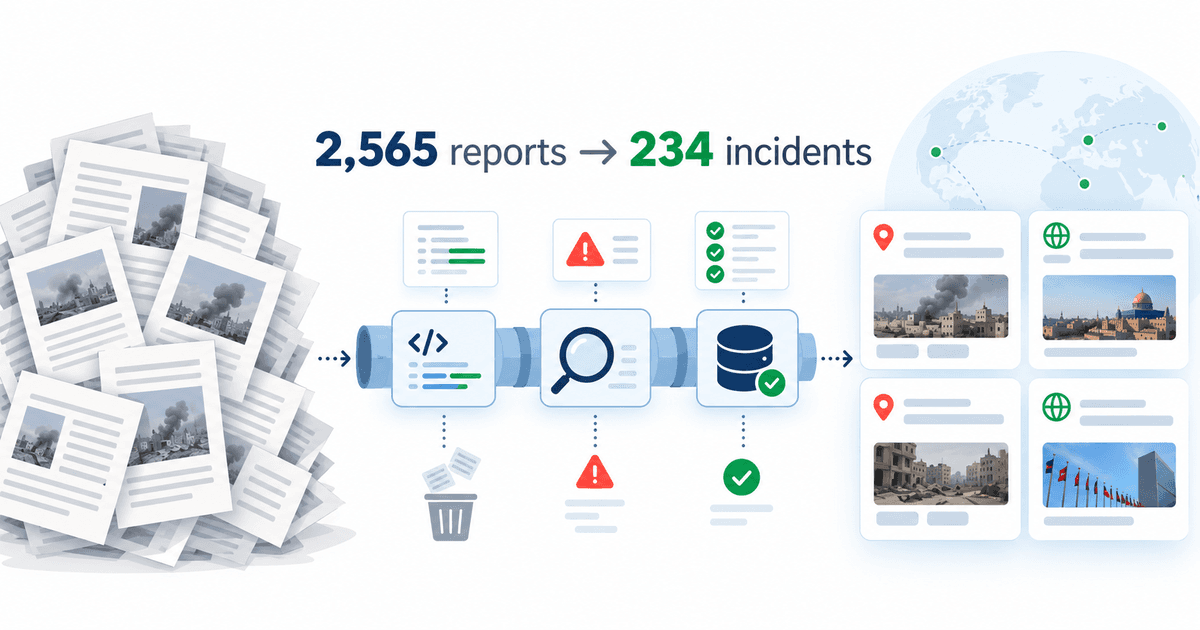
I began this project with what sounded like a simple question: when a fatal strike was reported in a small Lebanese town, did that specific event appear in international news coverage? I expected the difficult part to be finding the coverage. Instead, it was reconstructing what had happened accurately enough to search for it at all.
Media Cloud and Lebanon’s National News Agency (NNA) were never designed to communicate with each other. Media Cloud contained English-language news stories using inconsistent transliterations of Lebanese place names. NNA published Arabic reports in bursts: an initial casualty count, a later update, and sometimes a final Ministry of Public Health figure. Neither provided a shared incident identifier. Before I could compare them, I had to build that missing connection myself.
I conducted the project independently, with AI assistance for structured extraction, classification, exploratory analysis, and editorial organization. I personally reviewed the classified reports, exclusions, incident merges and splits, date corrections, and coverage matches against the underlying source material.
That distinction became important very quickly. Scraping 2,565 Arabic reports took a weekend. Making the resulting dataset trustworthy took a week. My code silently merged separate strikes that occurred in the same town on the same day. An early aggregation step interpreted an unspecified death toll as zero. An overlapping regional bulletin could have entered the registry as a separate incident total. None of these problems caused the pipeline to crash. They simply produced outputs that looked clean while being wrong.
These were not abstract rows in a test dataset; the numbers represented people who had actually died. That made auditing more than a final quality-control exercise. It became part of the methodology itself. Every merge, split, date correction, query, and validation decision needed to remain traceable and open to review.
The resulting study identified 229 fatal location-days, 83.4% of them in South Lebanon and Nabatieh. Among resolved cases, qualifying international English-language coverage was 44.9% there versus 72.7% elsewhere, a gap that persisted after adjusting for reported deaths and calendar week. I examine what that geographic coverage gap means for international news attention in a separate analysis for Eurasia Review.
This article is the story of how I built that system: the scraper, the data model, the incident-reconstruction logic, the mistakes I found, and the search pipeline that connected Arabic reporting to international coverage. It focuses on the engineering behind the research rather than the substantive coverage findings.
1. The Engineering Problem: Two Datasets With No Shared Identifier
Connecting NNA’s Arabic incident reports with Media Cloud’s international English-language coverage meant designing a pipeline that could turn a pile of news bulletins into a clean, traceable chain:
NNA report → incident → location-day → Media Cloud query → verified coverage
Every one of those arrows is a place where an automated process can quietly get something wrong — merge two different strikes into one, split one strike into two, misdate an event, or accept an irrelevant search result as a match. The rest of this article follows that chain stage by stage, with a focus on how I kept checking it. If you want to reproduce any of it, Section 11 has the exact steps.
2. Pipeline Architecture and Data Model
Before writing a line of scraping code, I sketched the shape of the pipeline as a series of transformations, each one materialized as its own CSV so I could inspect, re-run, or roll back any single stage without touching the others:

The pipeline splits into two halves with a hard boundary between them. Everything up through location_day.csv — call it Stage 1 — is about building the reference registry from NNA's reporting. Everything from location_day.csv onward — Stage 2 — is about searching for and verifying international coverage. The location-day (a place plus a calendar day) is the deliberate seam between them: it's coarse enough that two separate strikes on the same town on the same day don't need to be told apart before I can search for coverage of "an attack on that town that day," but specific enough to search for.
The stack is deliberately conventional: Python 3, requests, BeautifulSoup, the official mediacloud Python client, python-dotenv, and pandas / numpy / statsmodels for the final regression script.
Every intermediate artifact is a plain CSV with a UTF-8-with-BOM encoding (so it opens cleanly in Excel, which mattered for manual review passes) — no database, no ORM, nothing that would make a reviewer's life harder if they wanted to check my work in a spreadsheet. The repository is laid out as 25 numbered scripts, run in order, reading and writing into a shared data/ directory:
scripts/
  01_download_sitemaps.py   ...   25_uncovered_audit.py
data/
  raw/            # immutable scraped JSON — not in the public release
  processed/      # every derived CSV described below
3. Scraping the NNA Security Archive
I picked NNA specifically because it's Lebanon's state wire service and it publishes a structured, dated security-news category — the closest thing to a systematic, chronological record of individual attacks that I could find, as opposed to retrospective summaries or aggregated casualty counts published after the fact.
I scraped NNA in two steps. First, I pulled NNA's daily security sitemaps from March 2 through April 2, 2026, covering the March 2–31 study period plus two additional days for follow-up reports and casualty updates. Those extra two days matter: NNA sometimes files a follow-up report on April 1st or 2nd that finalizes or corrects a casualty count from a strike that happened on March 30th or 31st, and if I stopped scraping on March 31st I'd miss it. Each sitemap gave me a list of article URLs and IDs; from there I queried NNA's article API endpoint for each ID and saved the full response — title, body text, publication timestamp, and URL — as a raw JSON file, one per article.
That gave me 2,565 articles before I applied a single substantive filter. I saved every one of them, including those unrelated to fatal attacks, and never modified the raw JSON cache again — downstream scripts only read from it. That immutability mattered because every classification, merge, or date decision could be traced back to the original text. When I later found bugs in the classification logic, I could re-derive everything from the untouched source instead of reconstructing the article from memory or from a lossy intermediate.
4. Filtering, Classifying, and Normalizing Reports
Keyword Candidate Selection
Reading 2,565 articles by hand wasn't practical, and most of them aren't about fatal attacks at all — NNA's security category covers everything from troop movements to diplomatic statements. I ran a keyword filter across title and body text — Arabic terms for strike, killed, martyrs, raid, and a handful of attack-type words — to cut that down to 365 candidate articles. I want to be precise about what this step does and doesn't do: it's a recall-oriented filter, not a classifier. Passing the keyword filter doesn't mean an article describes a fatal Israeli attack; it means the article contains language that could describe one, and it moves on to structured classification and manual review. The filter's only job is to make the next step tractable without throwing away anything relevant.
Structured Classification
Every one of the 365 candidates got classified against explicit inclusion criteria: does it describe a fatal Israeli attack, inside Lebanon, within the study window, with at least one confirmed death? Anything that didn't clear that bar — a report about property damage with no deaths, an attack outside Lebanon's borders, a warning or evacuation order with no strike yet — got excluded, and I recorded why for every excluded row rather than just dropping it silently.
One wrinkle: 21 of those articles reported fatal outcomes at more than one genuinely distinct location in a single dispatch, each with its own separately stated death count — 18 of them at two locations, and 3 at three. Article 418093, for example, reported deaths in both “Jbeshit” and “Kfartebnit” in the same piece — those aren't one incident spread across two paragraphs, they're two incidents that happened to be reported together. I split each of those 21 articles into separate candidate rows before classification, which is where the extra 24 rows come from (18 two-way splits + 3 three-way splits = 24 additional rows), taking 365 source articles to 389 classified rows. Of those 389, 329 were coded as included.
For every included row I extracted: event date, town, district, governorate, deaths, injuries, and attack type. Classification was AI-assisted — I used a structured extraction pass to pull these fields into a fixed schema — with every row reviewed by me and every exclusion carrying a stored reason rather than a silent drop.
Dates, Locations, and Missing Values
Three normalization problems came up constantly enough that I want to call them out individually, because each one is a specific, recoverable failure mode if you don't design for it up front.
Publication date isn't event date. NNA sometimes files a report just after midnight describing "last night's" strike — if I'd naively used the article's publish timestamp as the event date, I'd misdate it by a day. My default rule was to use the publish date unless the article's own text explicitly said otherwise (words like "yesterday," "last night," or "the night of Thursday-Friday"), and I built a dedicated scanner to catch every case where that language appeared, so I could go back and check whether the recorded date actually accounted for it. More on what that scanner found in Section 6.
Arabic location names don't have one canonical English spelling. The same town shows up as "Kfartebnit," "Kfar Tebnit," and "Kfartibnit" depending on the source and the transliteration convention in use. I normalized each location against a canonical place table used consistently during incident reconstruction, while preserving every observed transliteration as a searchable alias — critically for Stage 2, I never collapsed variant spellings into a single "clean" form that discarded the originals.
A missing casualty figure is not zero. Some NNA reports describe "a number of martyrs" without giving a figure. It would have been easy — and wrong — to have my extraction default that to 0 when downstream code expects a numeric value. I explicitly distinguished "0 confirmed" from "unspecified, at least 1" throughout the schema, which meant catching and fixing a real bug once I noticed a handful of location-days silently showing zero deaths despite their source text confirming fatalities (Section 6 again).
5. From Reports to Incidents to Location-Days
This is the part of the pipeline that actually decides what counts as "one attack," and it's where almost all of the interesting bugs live.
The merge logic groups classified report rows by canonical location and event date, orders them chronologically within each group, and by default takes the latest reported casualty figure as that incident's running total — because most of the time, a second or third report about the same town on the same day is an update, not a new event. That default is mechanical, though, and it does not know that the final published report isn't always the most complete one: in one case (Tibnine, March 11), a later field report actually named only 5 of the 8 victims an earlier, fuller official bulletin had already counted, and the mechanical rule would have silently shown 5 instead of 8 if I hadn't caught it in the audit pass described in Section 6. Here's a cleaner example — a genuine update chain, taken directly from the dataset — four separate NNA dispatches about the same strike on Nabi Chit on March 6, over about four hours:
 Source: Diagram by the author
All four reports stay in incident_updates.csv — nothing gets discarded — but only the last one, marked final, becomes the incident's deaths_final. That's the easy case.
The hard case is when "latest report, same town, same day" is not an update — it's a second, unrelated strike. My first version of the merge logic didn't distinguish these, and it cost real data (I cover exactly how in Section 6). The fix was to keep the (location, date) grouping as the default but explicitly override it wherever the source text itself signals a second, distinct event — a different named victim or family, an explicitly different target (a home versus a responder team versus a checkpoint), or sequencing language like "a further strike" or "for the second time." In code, that override is a small, explicit table rather than a heuristic buried in the merge function. A simplified excerpt from the override table looks like this:
# validation-audit fix: these article_ids were classified with the same
# town+date as another report and so auto-merged, but re-reading the source
# text shows they describe a DIFFERENT, non-overlapping attack — force them
# into their own incident group instead of merging.
FORCE_SPLIT_KEY = {
    # Jbeshit: 418093 is the dawn single-home strike (6 dead, named family);
    # 418222b is a separate afternoon strike on the town generally (3 dead)
    "418222b": ("جبشيت (Jbeshit - separate afternoon strike)", "2026-03-07"),
    # Kawthariyet al-Rez: 418139 hit the sheikh's home (2 dead, his sons);
    # 418252 is a distinct strike on a civil-defense/health responder team (3 dead)
    "418252": ("كوثرية الرز (Kawthariyet al-Rez - separate responder-team strike)", "2026-03-07"),
    ...
}
Every override entry represents a decision I could point back to specific source text for, not a guess. Every original report — split or not, merged or not — stays in incident_updates.csv, which is the full audit trail behind every row of the cleaner incidents.csv.
That process turned 329 included report rows into 234 reconstructed incidents. But incidents still aren't the unit I searched for in Media Cloud. I used location-days — 229 of them, one row per place-and-calendar-day — as the actual matching unit, for a specific reason: international coverage rarely distinguishes between two separate attacks that happened there the same day. Searching at the incident level would have meant running near-duplicate queries against the same expected coverage, twice, for no gain. location_day.csv groups incidents by (place, day) and deliberately stays agnostic about "was this one attack or two" — that judgment call lives in incidents.csv if you need it, but it doesn't need to be made to search for coverage. Deaths are summed across every component incident at a given location-day; if any of those components has no numeric toll, the total is shown as a partial sum explicitly flagged as containing an unspecified additional count, rather than silently rounding down to what's known. Seven of the 229 location-days carry that flag.
6. The Audit Layer: Bugs That Changed the Dataset
I ran two full audit passes over the Stage 1 output before starting any Media Cloud work, plus a handful of targeted scans for specific failure patterns. I want to walk through the ones that actually changed numbers in the dataset, because each one taught me something about pipeline design that I'd apply to any similar project.
Same-town, same-day strikes getting silently collapsed. This was the most serious bug I found. My merge script's "latest report wins" rule is correct for updates and wrong for a second, distinct strike — and when it's wrong, it doesn't throw an error, it just quietly overwrites the first strike's death toll with the second one's, discarding real deaths from the total with no visible symptom. I caught this by checking every incident where the reported death count decreased somewhere in its report chain — a decrease is the fingerprint of either a legitimate downward revision or a second strike masquerading as an update (a bug). Reading all 17 of those cases against source text turned up four genuine same-day, same-town double strikes that had been merged into one — Jbeshit and Kawthariyet al-Rez among them, both shown in the code excerpt above — plus one further case where a later, partial-victim-list report had wrongly overwritten an earlier, more complete official toll rather than correcting it.
Fixing those errors recovered 20 confirmed deaths that had been silently dropped and added four incidents to the registry.
The zero-versus-unknown bug. Exactly the failure mode described in Section 4 — a handful of location-days with an NNA report reading "a number of martyrs" and no figure had been defaulted to 0 deaths somewhere in an early version of the aggregation script, instead of unspecified. Seven location-days were affected. Once I noticed the pattern, the fix was mechanical: stop treating "no number extracted" and "confirmed zero" as the same value anywhere in the pipeline.
A cumulative bulletin that could have caused double counting. NNA relayed a Ministry of Public Health bulletin citing "41 dead, Nabi Chit and surrounding towns" for March 7. Separately, I already had three individually-tracked incidents for that date and area: a residential strike chain (16 dead), a distinct commando raid corroborated by a military statement (26 dead), and a strike on a nearby village (6 dead). Those three sum to 48, not 41 — the numbers don't reconcile, and there's no way to tell from NNA's text alone which sub-total the 41-figure bulletin is actually summarizing.
Treating the 41-person bulletin as a fourth incident would therefore risk double-counting deaths already represented in the registry. I excluded the bulletin from the incident registry entirely and routed it to a separate audit-only file, with the discrepancy documented rather than silently resolved one way or the other. A simplified excerpt from the exclusion list:
# validation-audit fix: MoPH/NNA "grand total across an entire town cluster"
# bulletins that explicitly overlap other, separately-tracked incidents
# (double-counting risk if left in the incident-level sum). Routed to
# grand_totals_excluded.csv instead of incidents.csv.
GRAND_TOTAL_ARTICLE_IDS = {
    # "Total for Nabi Chit and surrounding towns: 41 dead" — explicitly
    # does not equal 16 (residential) + 26 (commando raid) + 6 (Shamsatar) = 48
    "418161": ...
}
The Kfartebnit split that had to be recovered. This one is a good example of two separate bugs briefly canceling each other out. A report about a medic strike near Kfartebnit had been merged with a separate, lower-casualty report from the same town as a probable duplicate — reasonable, since they landed on adjacent dates. But my retrospective-date scanner later determined the medic-strike article should actually be shifted back one day, based on "night of Thursday-Friday" language in the text. Once I applied that date correction, the two reports no longer shared a date at all, which meant the original "probable duplicate" merge was wrong — they were two separate incidents that happened to look like a duplicate only because one of them had the wrong date. I un-merged them once the date was fixed. Neither bug was visible on its own; the date fix is what exposed the merge error underneath it.
Cross-midnight date errors. The retrospective-language scanner I mentioned in Section 4 flagged 14 reports for manual review. Eleven were already correctly dated. Three were genuinely wrong — all cases where an article's own text described the strike as happening "last night" or "the night of X-Y," but the event date was still sitting on the publish date. Small in count, but each one would have shifted a location-day's confirmed date by a full calendar day, which matters a great deal once you're about to search a three-day coverage window keyed on that exact date.
What all of these have in common: none of them threw an exception. They were silent, plausible-looking, and would have shipped in the final dataset if I hadn't gone looking for specific fingerprints — decreasing casualty counts, grand-total language, retrospective date markers — rather than just spot-checking a random sample and calling it done.
7. Building the Media Cloud Query System
With 229 verified location-days in hand, Stage 2 begins: did international media cover any of them?
I scoped "international" deliberately: Media Cloud's Global English Language Sources collection, 1,602 outlets, with Lebanese-domestic domains excluded from counting as a match. The search window is D0 through D3 — the day of the attack through three days after — with a secondary check at D+7 for slower-developing coverage.
Each of the 229 location-day observations required a search, and a bare place name usually isn't enough. Together, those 229 location-days represented 153 unique locations, for which I built a transliteration alias table covering the systematic ways Arabic place names vary in English transliteration — vowel choice, the al- prefix, consonant doubling, and so on — and joined each location's aliases into a single query:
def build_base_query(loc_row):
    aliases = loc_row["aliases"].split(";")
    alias_clause = " OR ".join(f'"{a.strip()}"' for a in aliases if a.strip())
    q = f"({alias_clause}) AND Lebanon"
    if loc_row["is_ambiguous_common_word"] == "1":
        q += " AND (strike OR airstrike OR raid OR killed OR attack OR shelling)"
    return q
Fifteen locations needed more than that — places named after a major city or district capital, like Beirut, Tyre, or Nabatieh, where the bare name shows up in nearly every dispatch about the wider conflict regardless of whether it's describing this specific attack. For those, I hand-built incident-specific queries that pull in a neighborhood name, a casualty figure, or an attack-type term instead of relying on the place name alone — for example, anchoring a Nabatieh-city query to "Al-Rahibat" or "7 killed" rather than just "Nabatieh." When a base query came back empty, I ran one stricter fallback query built from the incident's own target description and attack type before giving up. A simplified excerpt from that fallback-query builder:
def build_fallback_query(loc_row, ld_row, incidents):
    ...
    alias_clause = " OR ".join(f'"{a.strip()}"' for a in aliases if a.strip())
    if terms:
        term_clause = " OR ".join(f'"{t}"' for t in list(terms)[:6])
        return f'({alias_clause}) AND Lebanon AND ({term_clause})'
    return f'({alias_clause}) AND Lebanon AND (strike OR airstrike OR raid OR killed OR attack OR shelling)'
Every query I ran got logged — the exact query string, the date range, a timestamp, and the raw result count — in media_search_log_full.csv, whether or not it ultimately confirmed anything. I also recorded the execution date explicitly: all searches were run on August 21, 2026. That detail matters more than it might look like it does. A news index isn't static — stories get added, corrected, or occasionally removed after original publication — so "the same query run six months from now" is not guaranteed to return the same result set. Recording when a search was executed is part of making it reproducible, not just documenting what the query was.
8. Validating Coverage Matches
A nonzero Media Cloud result count is not the same thing as confirmed coverage, and treating it as such would have been the single easiest way to make this whole project meaningless. A query can return results because of a Lebanese outlet republishing the same NNA wire text, because of an unrelated story that happens to share a place name, or because of a syndicated wire piece that got picked up by a dozen aggregator domains simultaneously without adding a single independent instance of coverage.
So I checked every non-Lebanese result rather than simply counting it. I first filtered outlet domains against a Lebanese-domestic list, then checked the title and, where needed, the full article text against the specific attack — right location, right date, an attack that actually happened rather than a warning or still-developing report, and language actually referring to this strike rather than a generic regional roundup.
Coverage, in this pipeline, is binary: did at least one qualifying outlet cover the location-day? A concise summary of the study’s findings is available separately, while this article focuses on how those coverage decisions were recorded and audited. I kept the raw, unfiltered Media Cloud results separate from the final validation decisions rather than collapsing everything into a single covered/not-covered field. That separation means any decision can be revisited later if the criteria change or a match needs to be rechecked.
9. What the Pipeline Looks Like End to End
The outputs that matter, if you're going to work with this data directly rather than just reading about it:
incidents.csv— the attack-level registry, 234 rows, each with its final casualty figures, attack type, and full source-article references.incident_updates.csv— every report-to-incident linkage, extracted casualty update, timestamp, source URL, and merge decision used to construct the incident registry, so no merge decision is a black box.location_day.csv— the 229-row place-and-day registry, the actual unit Stage 2 searched against.- Raw Media Cloud results — per-location-day dumps of everything a query returned, before validation.
media_search_log_full.csv— the query log: exact query text, date range, execution timestamp, and result count for every search run, whether or not it confirmed anything.pilot_v2_results_full.csv— one row per location-day with the covered/uncovered/unresolved status, the confirming URL where one exists, and the reasoning behind that call. Kept as a separate file from the query log on purpose, so raw hit counts and validated conclusions are never collapsed into the same column.
Worth being explicit about: the classification and validation files in that list are reproducibility inputs, not outputs a script can regenerate from nothing — they record human review decisions, and re-running the pipeline reproduces the mechanical steps around them, not the judgment calls themselves.
10. Engineering Lessons and Methodological Boundaries
A few things I'd tell myself before starting a similar project again:
- Scraping was the easy part. Getting 2,565 articles off a website is a solved problem. Turning them into 234 correctly-bounded incidents is where the actual engineering work is.
- Publication date is not event date. If your source ever reports something retrospectively — and reports filed close to midnight almost always do, eventually — you need an explicit scanner for that language, not an assumption that publish time equals event time.
- Missing is not zero. Any time a field can legitimately be "unknown," give it a real unknown value. Defaulting to zero silently converts "I don't know" into "confirmed none," and those are very different claims.
- Location normalization has to preserve aliases, not collapse them. You need every spelling variant queryable downstream, even after you've picked one canonical form for display.
- An automated search hit is a candidate, not evidence. Whatever your search API returns still has to clear a real validation step before it counts as anything.
- Design provenance into the pipeline before collecting data, not afterward. Keeping the raw scrape immutable and separate from every derived file is what made it possible to trace every later bug back to its source text instead of guessing.
And, staying strictly on the engineering side, the boundaries worth stating plainly: NNA is a reference source I built this registry from, not a claim to a complete census of every fatal attack that occurred. The media collection I searched is English-language and explicitly excludes Lebanese-domestic outlets. The primary coverage window is D0 through D3, with D+7 checked only as a secondary signal. A known, bounded set of casualty and location ambiguities remains explicitly flagged rather than silently resolved.
The pipeline also covers only one conflict-month. Extending the workflow to another NNA date range is primarily a configuration change, but adapting it to another country or source outlet would mean rebuilding the scraper, candidate vocabulary, classification schema, location aliases, and validation rules.
The next section covers what is configurable in practice.
11. Reproducing the Pipeline
The code and derived data are public on GitHub.
Install:
git clone https://github.com/mohamedsoufan/lebanon-israeli-attacks-media-coverage-2026.git
cd lebanon-israeli-attacks-media-coverage-2026
pip install -r requirements.txt
Media Cloud access: Stage 2 requires a Media Cloud account and API key. Set it as an environment variable in a .env file in the repository root:
MEDIACLOUD_API_KEY=your_key_here
Key configuration variables, if you want to point this at a different conflict, country, or window:
COLLECTION_IDin the Stage 2 scripts — currently set to9272347(Media Cloud's Global English Language Sources collection). Swap this for a different Media Cloud collection to change which outlets count as "international."START_DATE/END_DATEin01_download_sitemaps.py— the NNA scraping window; this alone is enough to point the pipeline at a different date range for the same conflict and source.- The D0–D3 / D+7 windows are set where each location-day's search dates are computed in the Stage 2 search script — widen or narrow them there.
location_aliases.csvand theALIASESdictionary in11_build_aliases.pyare specific to Lebanese place names and will need to be rebuilt entirely for a different country's transliteration conventions.
Changing the date range for NNA itself is a config change. Pointing this whole pipeline at a different source outlet or country is a larger undertaking than swapping a URL — the sitemap scraper, the keyword vocabulary, the classification schema, and the alias tables are all written around NNA's Arabic-language conventions and would need to be rebuilt for a new source, not just repointed.
Script execution order matches the numbering: 01 through 10 build and validate the Stage 1 incident registry; 11 builds location aliases; 12 through 23 are the Stage 2 pilot, full run, and audit scripts. Scripts 24 (the regression) and 25 (a supplementary coverage audit) are analysis-stage scripts that operate on the finished dataset — outside the scope of the pipeline this article covers. Each script reads only from files earlier scripts have already written, so you can re-run from any point without starting over.
What's public: the full derived dataset — incident registry, location-day observations, alias tables, Media Cloud query logs, and validated coverage records — along with all 25 scripts. What's not included is the raw scraped NNA article text itself, since NNA holds copyright on its own wire reporting and I don't have redistribution rights to it; everything derived and structured from that text is there, the copyrighted source text is not.
Conclusion
The central lesson from this project is that matching news coverage to real-world events is not primarily a search problem; it is a provenance problem. The pipeline only became trustworthy once every merge, split, date correction, query, and validation decision left an inspectable trail. The repository provides the code and derived data for readers who want to audit the workflow or adapt its methods to another source. The full substantive coverage findings are reported separately.