
Anurag is an experienced journalist and author who’s been covering tech for the past 5 years, with a focus on Windows, Android, and Apple. He’s written for sites like Android Police, Neowin, Dexerto, and MakeTechEasier. Anurag’s always pumped about tech and loves getting his hands on the latest gadgets. When he's not procrastinating, you’ll probably find him catching the newest movies in theaters or scrolling through Twitter from his bed.
I already run local LLMs on my Mac through LM Studio, and I’ve found plenty of uses for them outside the chat window. Coding is one of the most useful uses because I can connect a model directly to VS Code and get help without switching apps. It also means I don’t lose that assistance when I’m offline, which is a limitation of the Copilot setup I’m replacing. I am using the Continue extension to connect VS Code to LM Studio, with separate models for autocomplete and chat.
Connecting VS Code to my local models
I am using Continue to do that
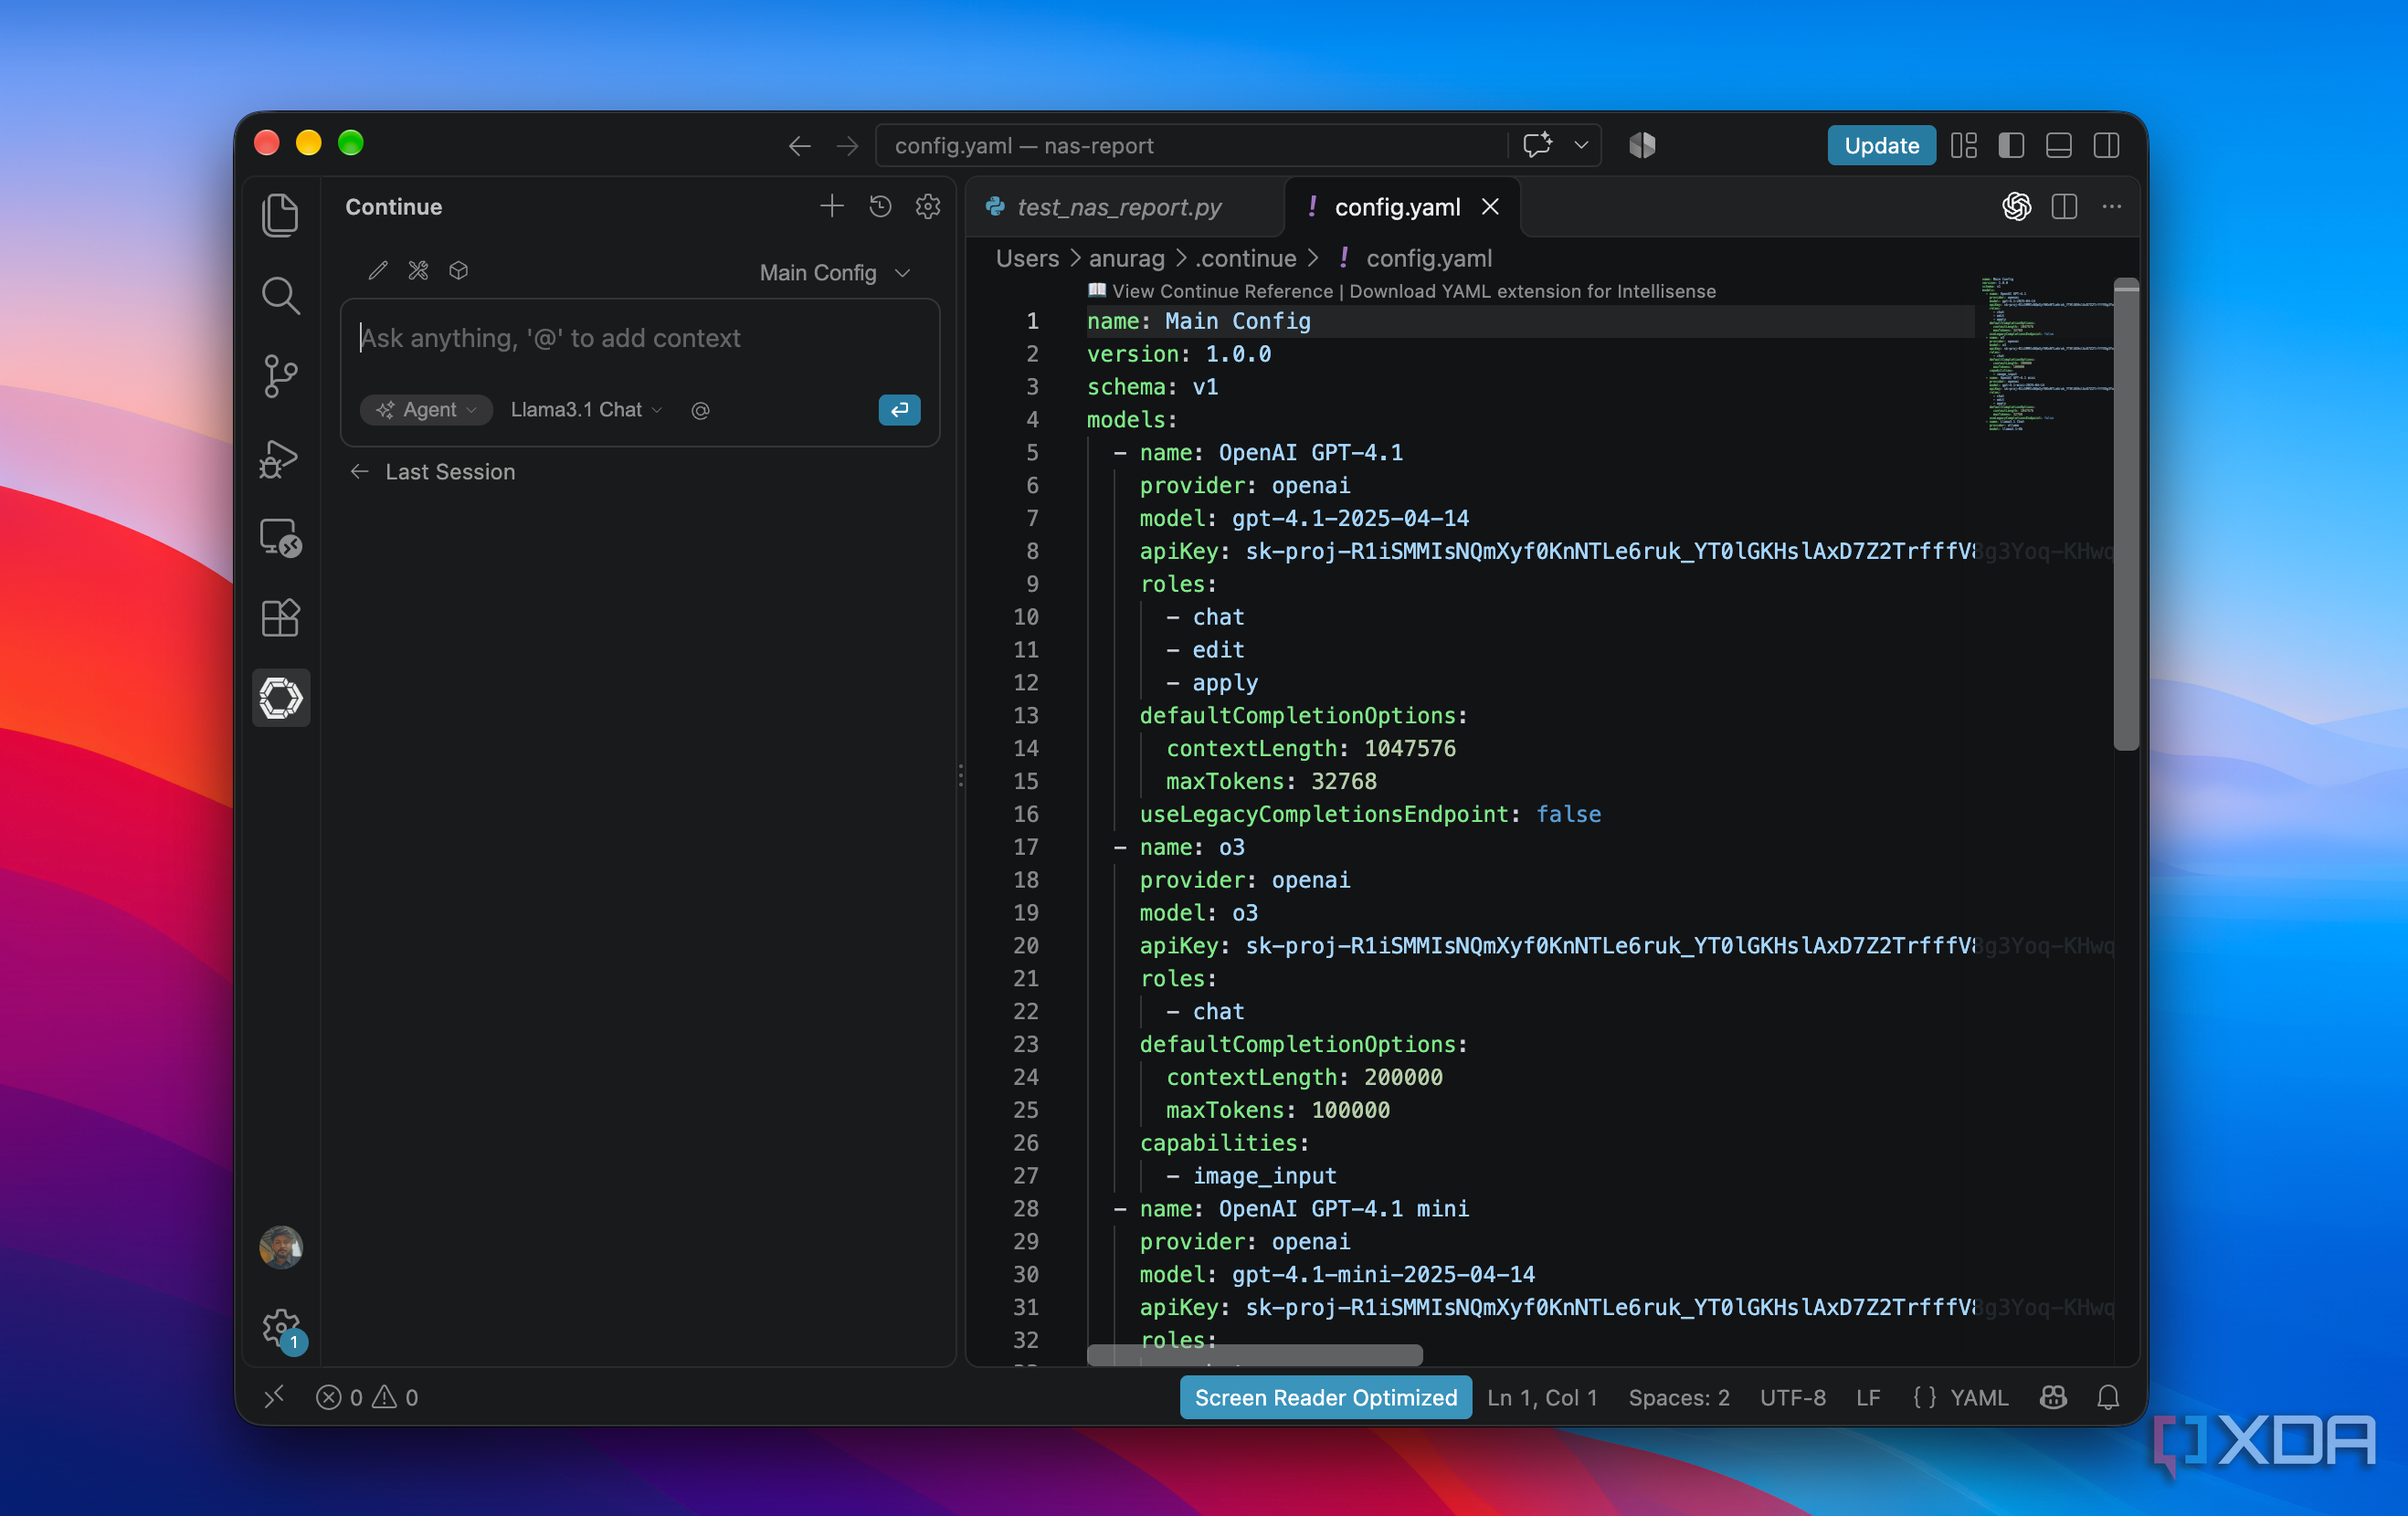
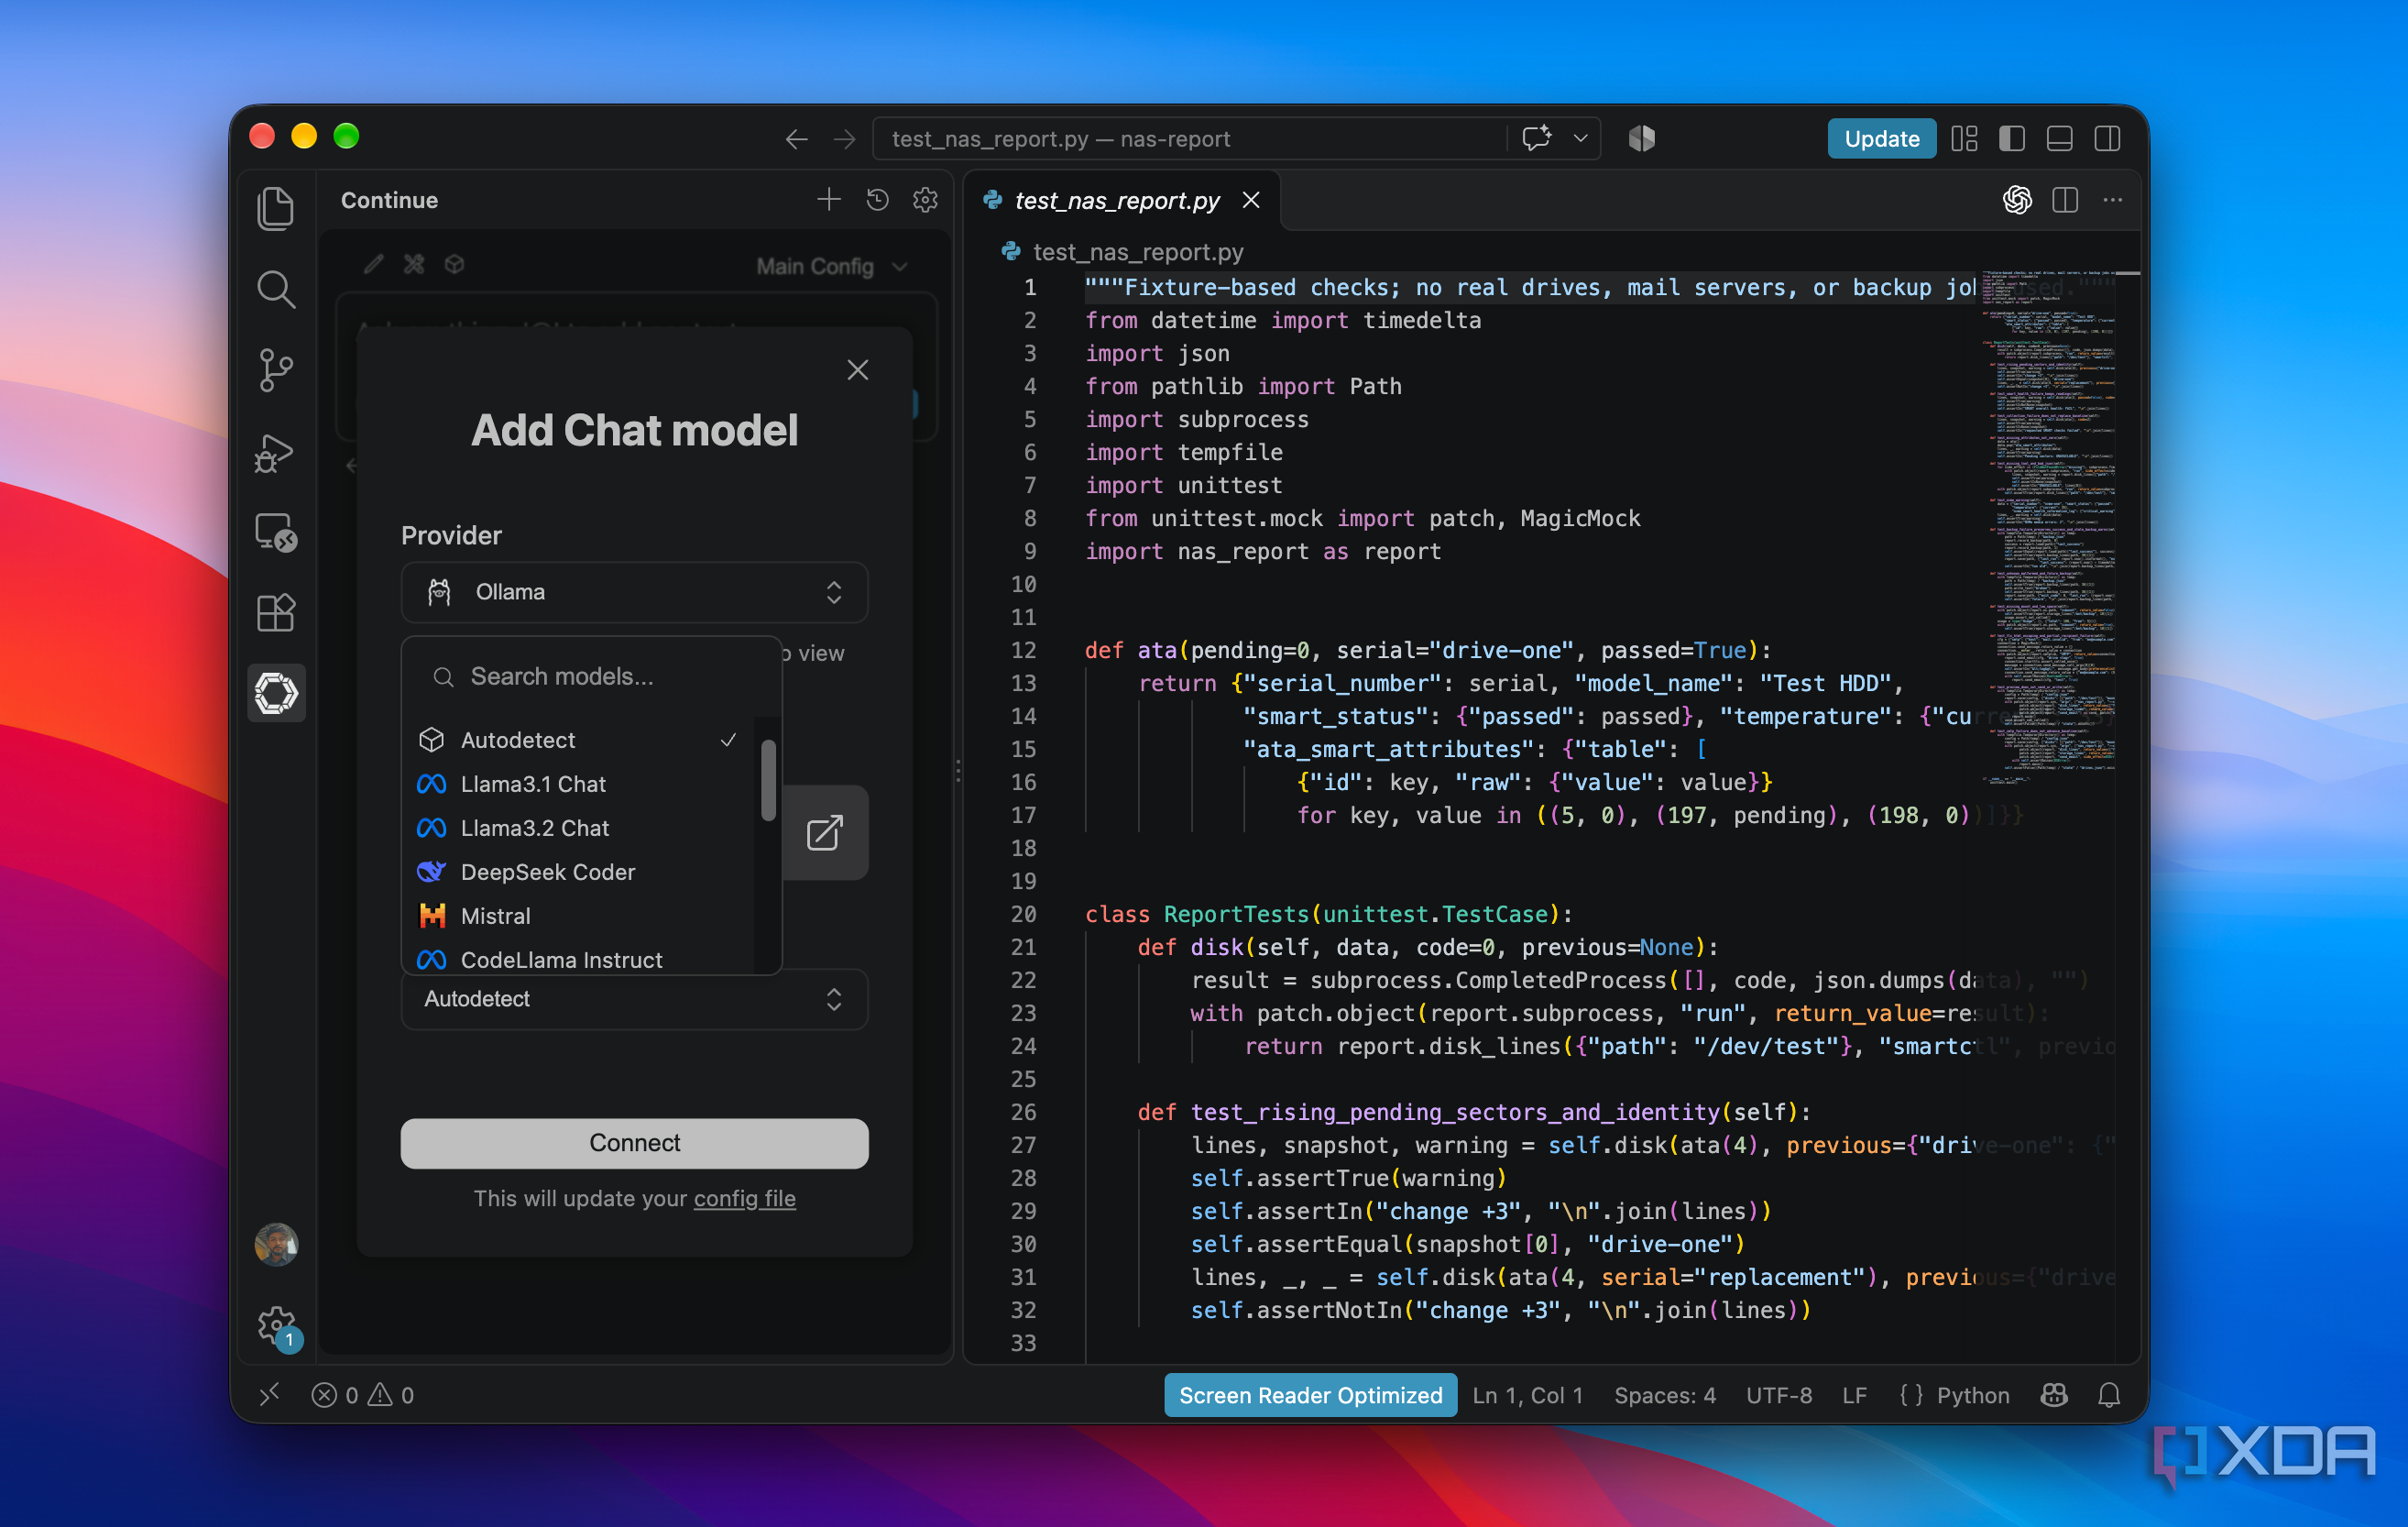
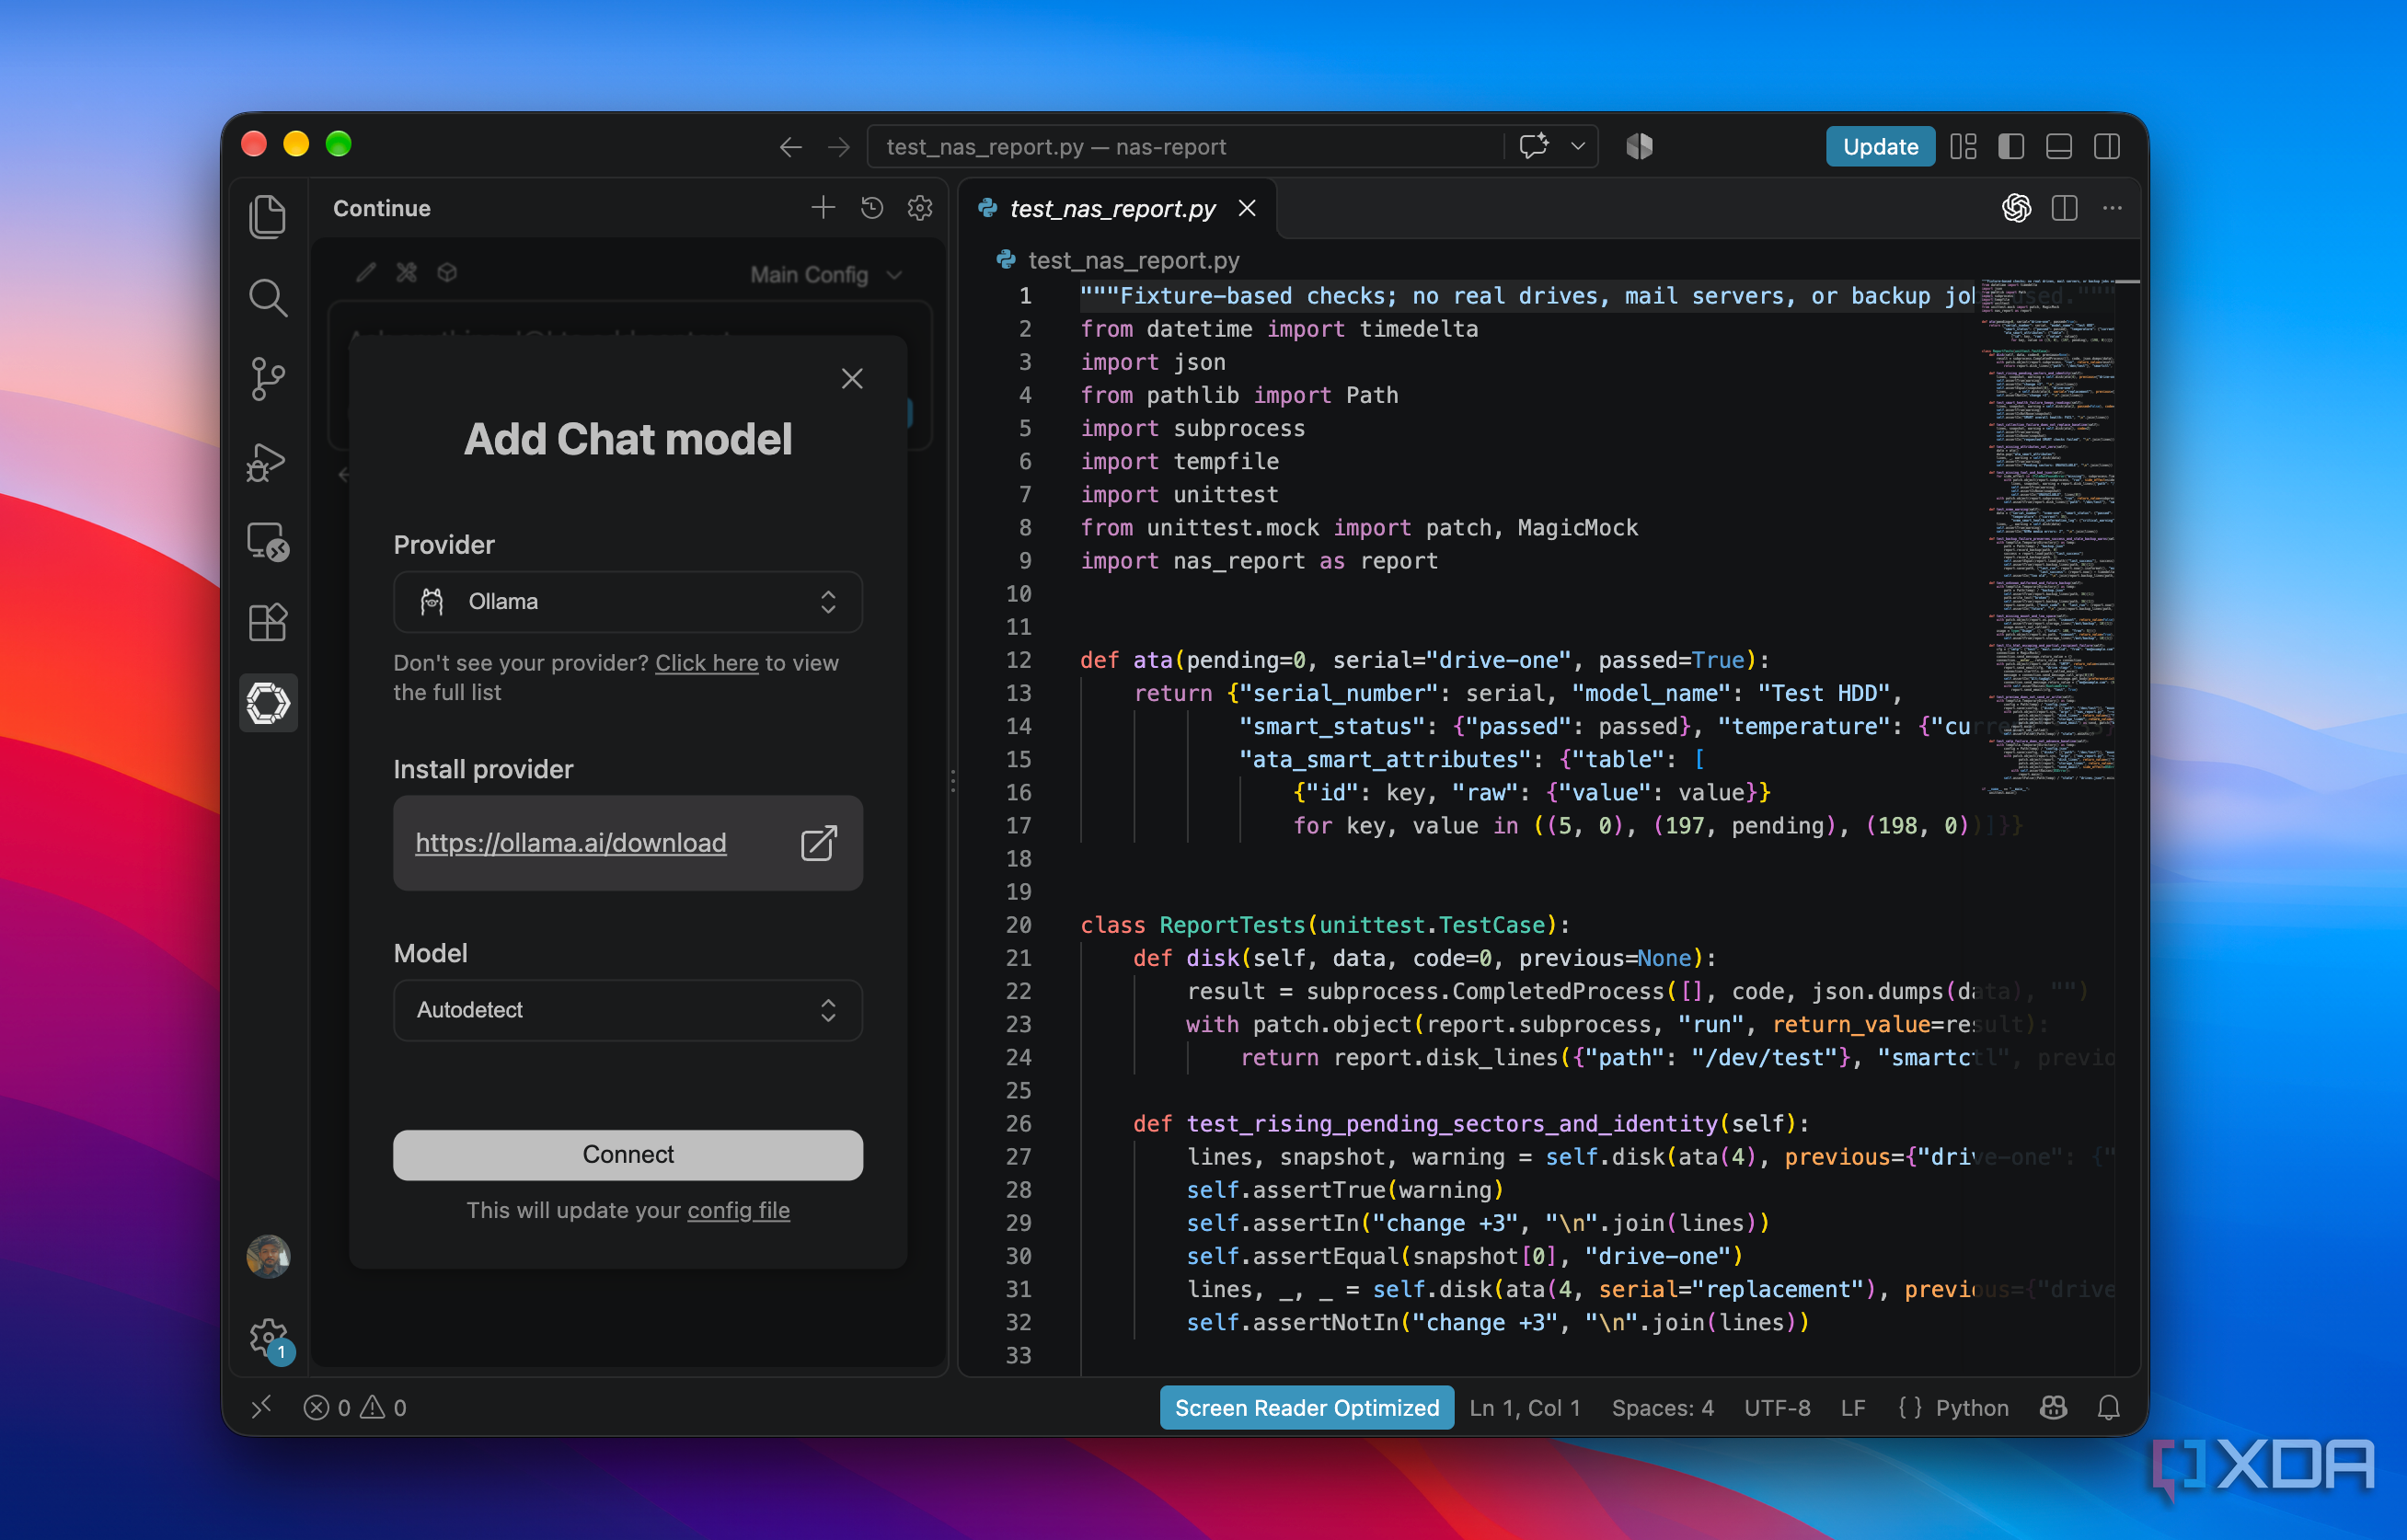
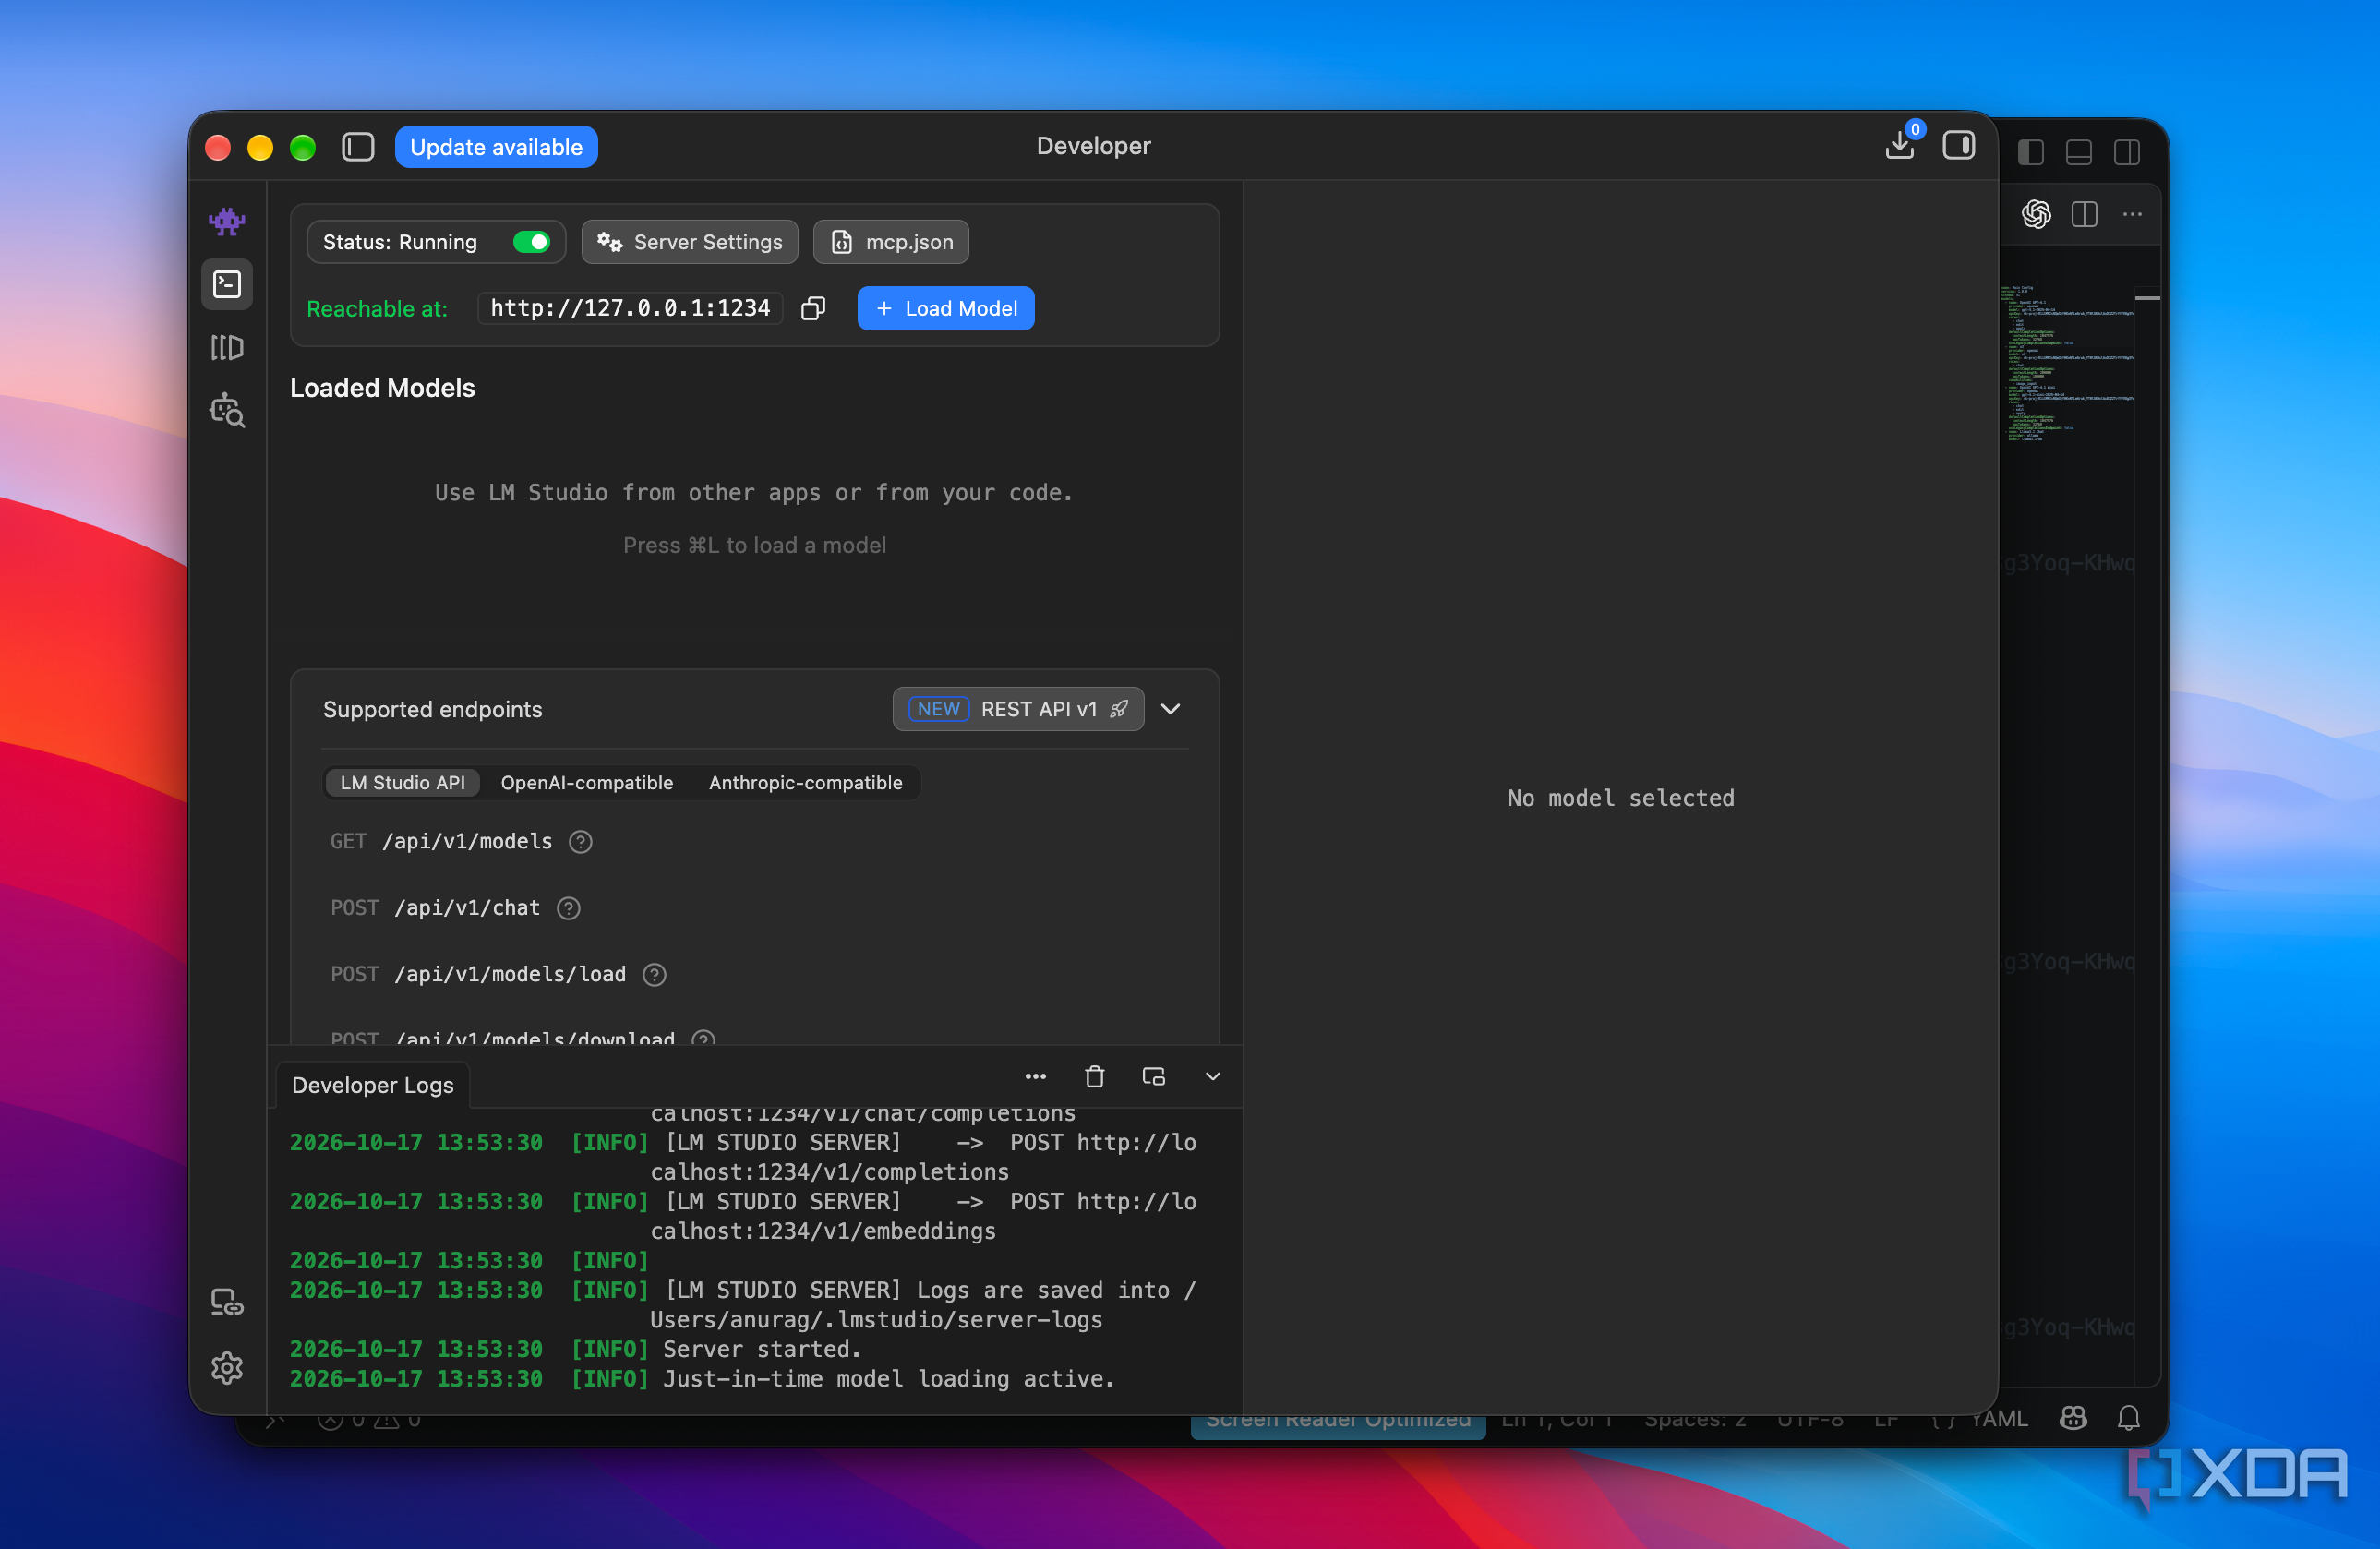
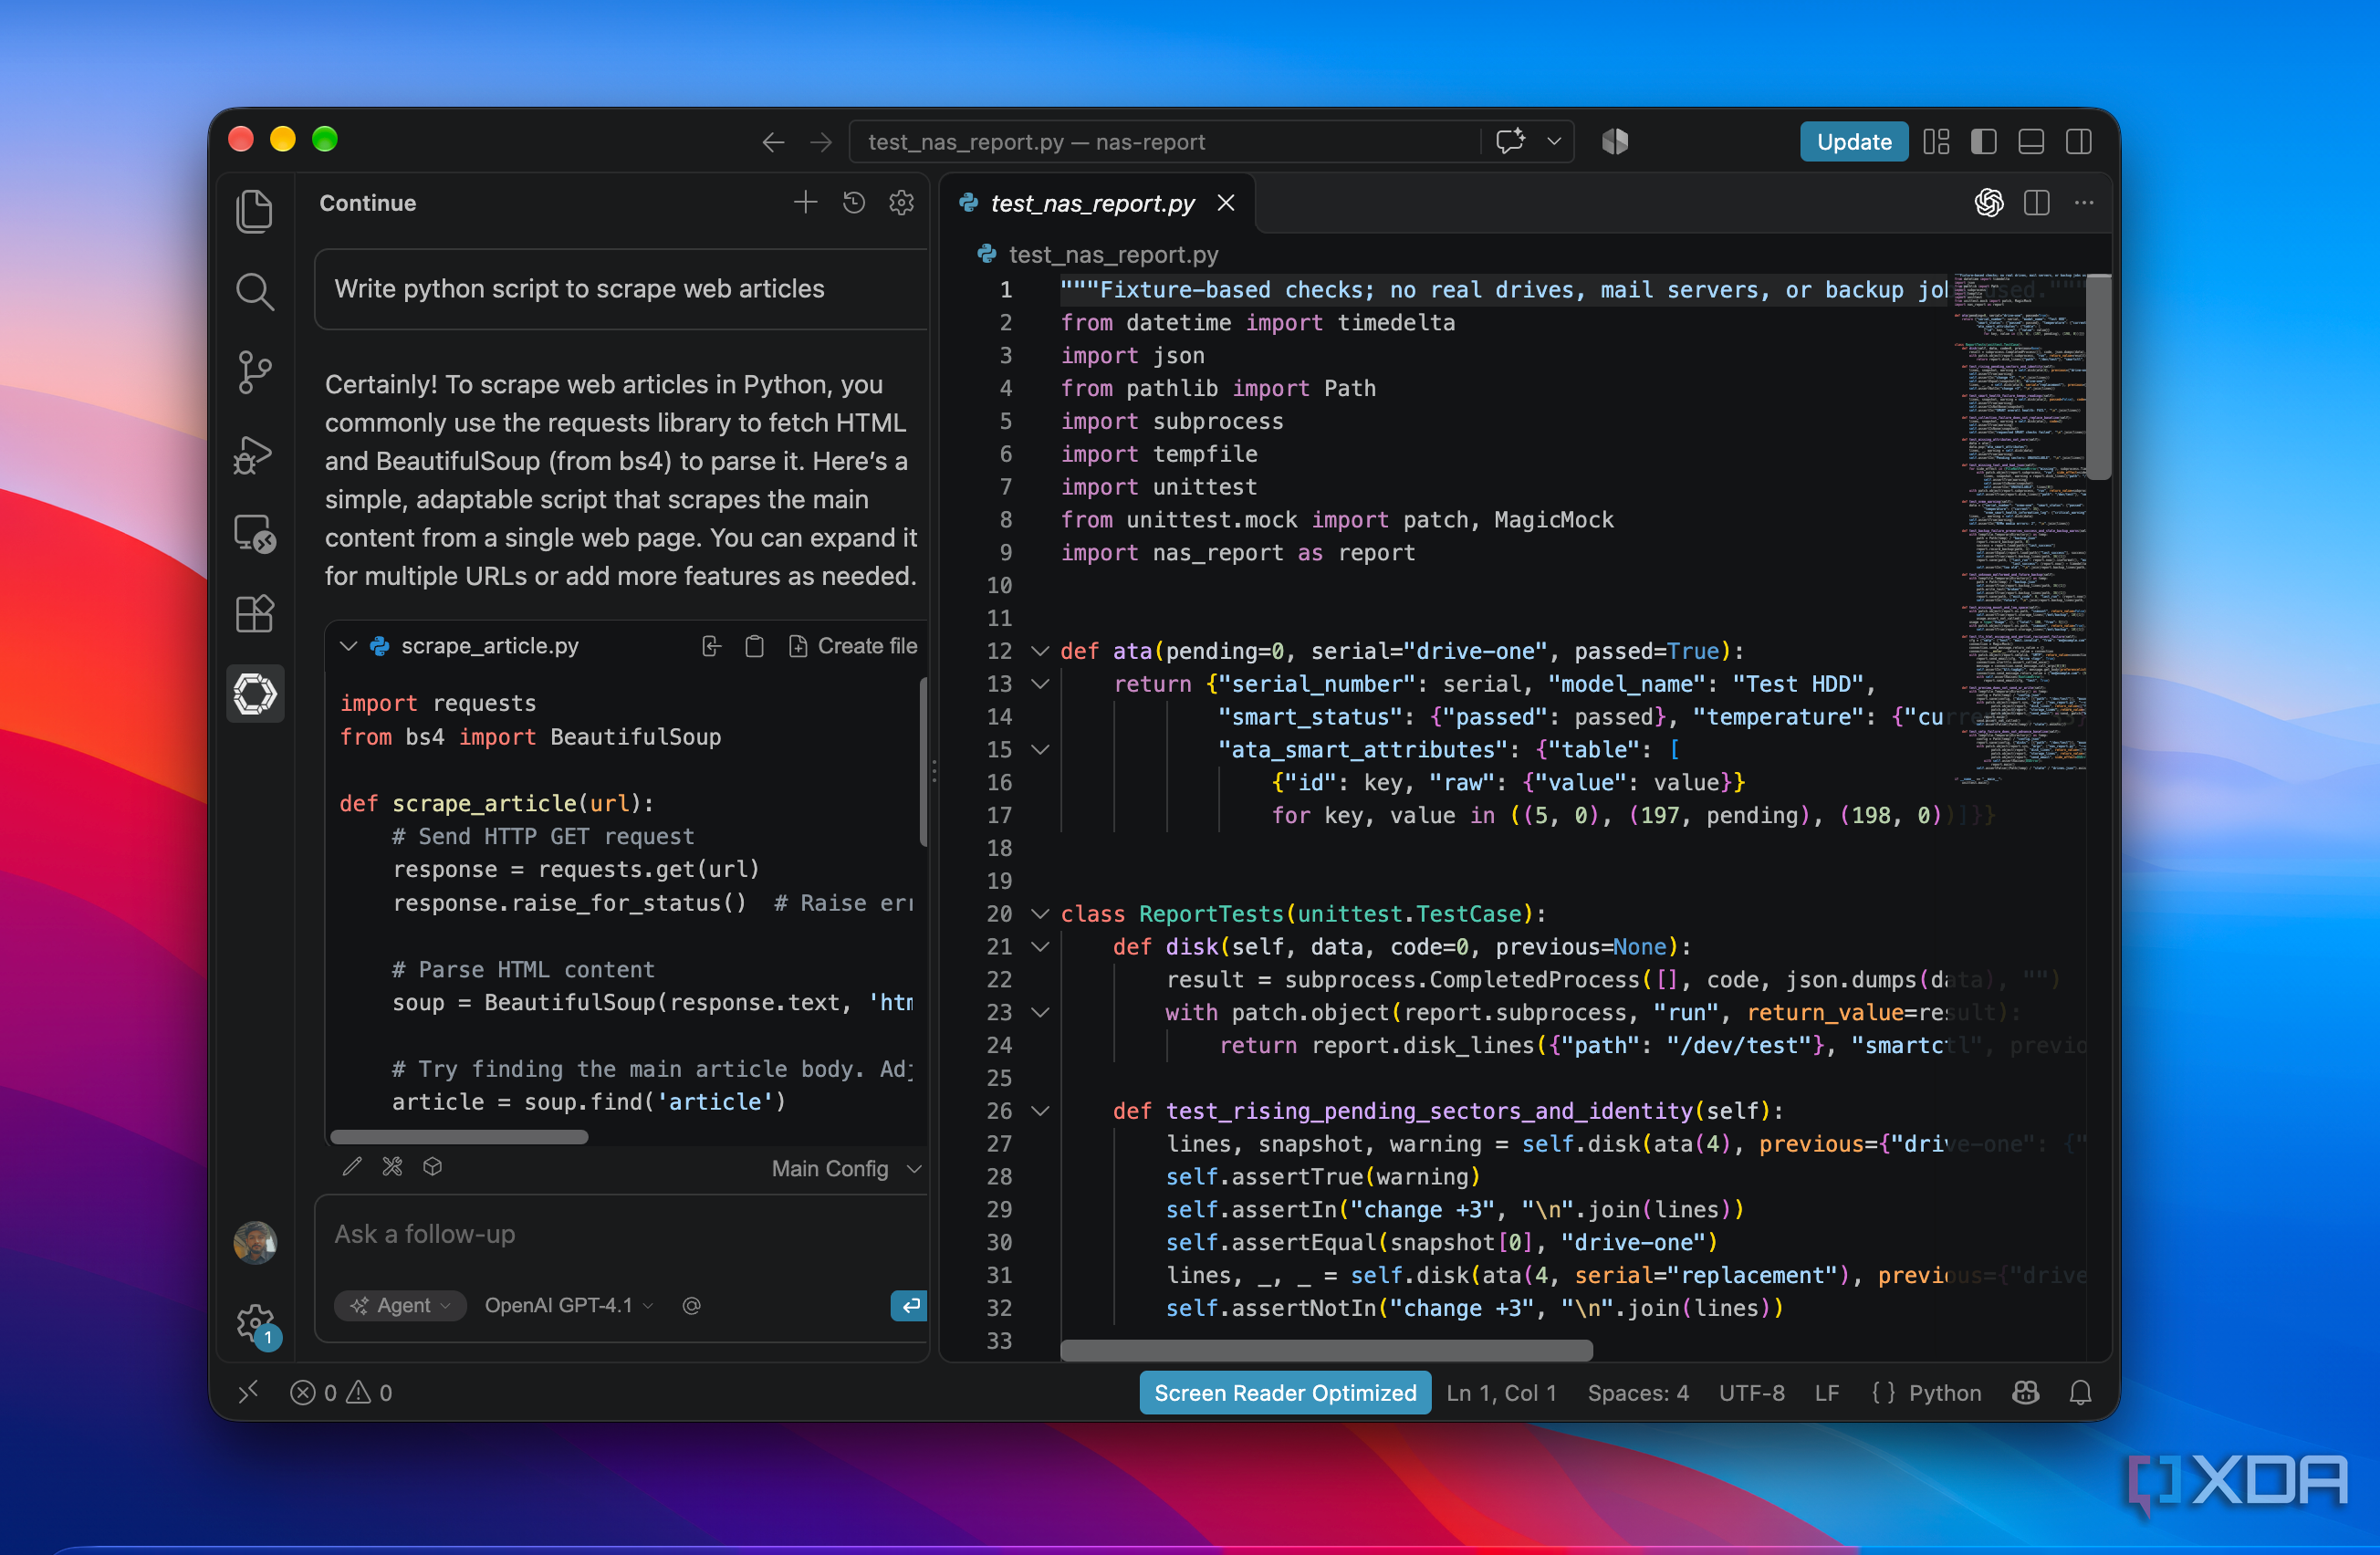
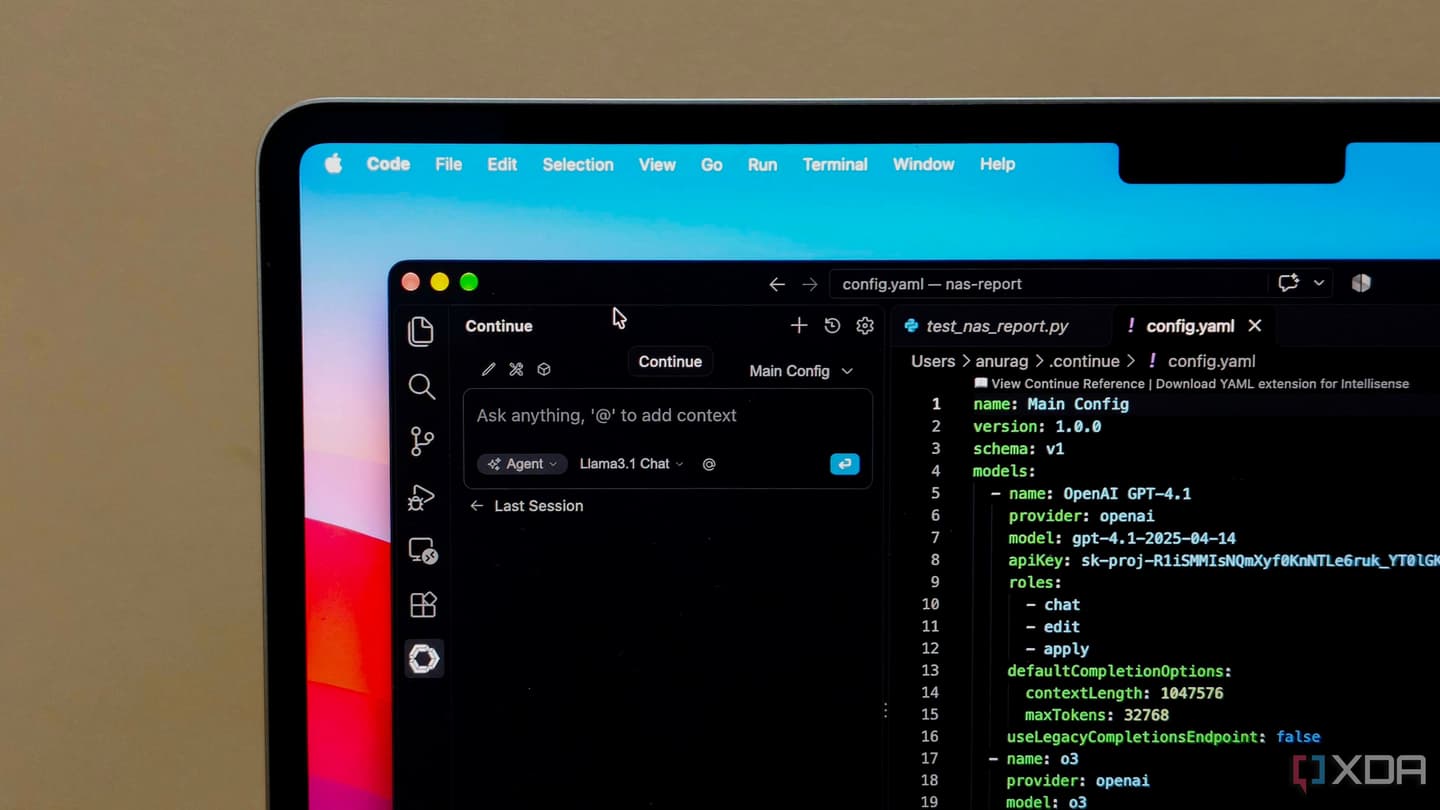
Once you've added Continue to VS Code, you'll see a chat panel, code editing tools, and inline suggestions. Continue is a good enough tool in itself — you can connect it with a cloud API and start working right away. But since the focus of this article is bringing a local LLM inside VS Code, we are going to have to connect Continue with a model runner. I use LM Studio as the model provider, though it also supports alternatives like Ollama.
With a model loaded in LM Studio, enable its local server. This gives you an API endpoint to enter in Continue’s provider configuration. The default address is http://localhost:1234/v1, and requests sent there stay on your computer. Continue’s configuration includes model roles, so you can choose which model to use for autocomplete, chat, and editing. I assign the smaller Qwen model to autocomplete and use the larger one for chat and edits. The model identifier must match what LM Studio’s server exposes, especially if you’ve downloaded several versions.
I also disable Copilot’s inline suggestions to avoid competing completions. Although VS Code already supports local models through its built-in chat interface, that support doesn’t extend to local autocomplete, which is why I use Continue.
Always use a smaller model for autocomplete
You don't want to wait for responses here

I use Qwen 2.5 Coder 1.5B for autocomplete. I’m deliberately using a smaller model because it’s fast and generates suggestions as I code. A larger model has to process more weights to generate suggestions, and that delay interrupts the work it’s supposed to help with. It also takes up more memory, which matters when you’re running it on the same computer as your editor and everything else.
When you use autocomplete, you’re usually asking the model to finish a line, complete a loop, or add more code following an existing pattern. With fill-in-the-middle support, the model uses the code before and after your cursor to work out what belongs between them. You already have function names, variables, and surrounding code to guide the suggestion, so even a small coding model has enough context to be useful here.
You also need to pick a model that supports this completion format, so downloading the newest general-purpose model won’t necessarily give you better suggestions. For example, a reasoning model spends time thinking through its response, which adds a delay when all you need is a few lines of code.
I reserve Qwen 2.5 Coder 7B for questions and code edits, where I’m deliberately asking for help and can give the model more time. For example, you can select a function and ask for an explanation or request a change to its error handling. Those tasks benefit from more capability than I need for routine completions.
I can finish small coding jobs offline
Very helpful when I am traveling

I wouldn’t call this the most powerful coding setup you can have. Copilot is still better at generating code and offering suggestions, and it has more capable agent features than these local models. When you run a model locally, you’re also limited by the hardware in your laptop, mini-PC, or NAS.
The convenience for me is working offline. I travel a lot, and reliable internet is often a problem. Flights are the most obvious example because Wi-Fi is either unavailable or costs extra. Being able to pull out my laptop and start working without worrying about connectivity is brilliant. I don’t get the same performance as Copilot, but I still get suggestions, explanations, and help editing code. That’s enough to get some work done during a flight instead of putting it off until I have an internet connection again.
VS Code with local models is especially helpful when you’re improving a feature or doing regular maintenance work. You can select an existing function and ask for help adding error handling or cleaning up repetitive code.
Local models are not entirely useless
I’ve been self-hosting local models for over a year now, and honestly, I haven’t gotten much out of them because they simply aren’t good enough, and you can’t run very good models on consumer hardware. But I’ve found that when you give them small tasks or break a larger job into smaller ones, they do come in handy, especially for coding and home automation.