Key Takeaways
The Risk of Silent Success. Snowpipes are designed to be resilient by skipping malformed files and continuing ingestion, while that prevents pipeline from failure, it creates critical data gaps because these failures don’t trigger native alerts, which leads to incomplete datasets that are often discovered only much later when caught the attention of analysts, business users etc.
Decoupling with a Reliability Layer. The architecture avoids tight coupling by placing Azure Event Grid and an Azure Storage Queue between Snowflake and the notification service. If the Logic App goes down, failure events are buffered in the queue and processed once it's back online, rather than being lost.
Governance via HTTP Notifications. Instead of built-in email connectors, we routed alerts through internal APIs using HTTP actions. This was driven by security requirements ensuring outbound data stays within controlled infrastructure and follows enterprise governance standards.
Schema Enforcement. A major lesson learned was that Snowflake’s raw failure messages can be inconsistent. To work around that we implemented strict JSON parsing and schema normalization within the Logic App to handle variability in failure payloads.
Trade-offs. This solution prioritizes High Availability over immediate data consistency. By letting Snowpipe continue ingestion despite errors, the system stays online, but it places the entire strain of data integrity on the external layer built in Azure.
Introduction
One of the more subtle challenges in modern data platforms isn't handling failures — it's detecting the ones that don't surface clearly.
In a Snowflake-based platform running on Azure, we ran into this exact issue with Snowpipes. On paper, Snowpipe provides continuous ingestion and handles errors without disruption. In practice, certain classes of failures — such as malformed source files — are quietly skipped while ingestion continues.
At first glance, this behavior seems reasonable. But in a production environment, it creates a blind spot: data loss without immediate visibility.
This article walks through how we addressed that gap by building an event-driven failure handling mechanism using Snowflake and Azure services, and the design decisions that shaped the solution.
The Problem: Silent Failures in Snowpipe
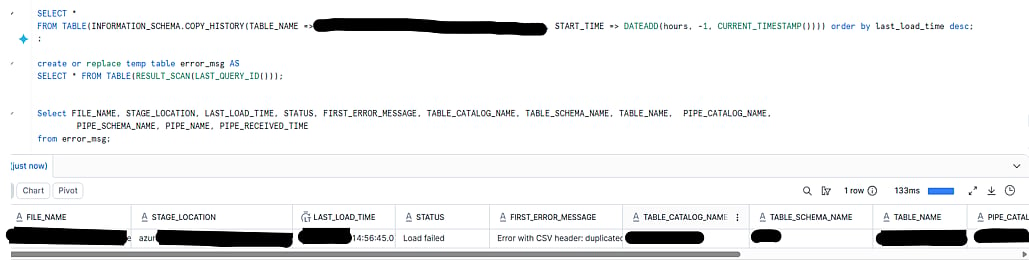
Snowpipe is designed for resilience. When it encounters a problematic file — incorrect format, schema mismatch, or a parsing issue — it skips the file and continues processing the rest. Skipping is the default behavior when you create a Snowpipe, and it's also what makes reliable error capture possible: because ingestion doesn't halt, every subsequent failure still generates its own error signal instead of blocking behind the first one.
While this prevents pipeline disruption, it introduces a different risk:
No immediate alert when a file is skipped.
Missing data may only be discovered downstream, often as feedback from BI, or business users.
Because that discovery usually comes later, from BI or business users noticing that something is off, troubleshooting ends up being reactive instead of proactive
In our case, this led to situations where ingestion appeared successful, but datasets were incomplete.
We needed a way to surface these failures in real time without disrupting ingestion.
Architectural Approach
Instead of trying to change Snowpipe's behavior, we focused on capturing and externalizing failure signals.
The architecture we implemented includes:
Snowflake (Snowpipe + outbound notification integration)
Azure Event Grid (custom topic + subscription)
Azure Storage Queue
Azure Logic Apps (processing and notification)
The goal was simple: every Snowpipe failure should generate a structured event that triggers a response.
Emitting Failure Events from Snowflake
The turning point was leveraging Snowflake's outbound notification capability.
We configured Snowpipe to send a message whenever it encounters a failure condition — particularly when files are skipped due to format or parsing issues. This allowed us to convert what was previously an internal event into an external, actionable signal.
One thing that became clear early on was that Snowflake's raw failure messages aren't always consistent enough for direct consumption. That influenced how we designed downstream processing.
Event Routing with Azure Event Grid
We used an Azure Event Grid custom topic as the entry point for all Snowpipe failure events. The flow is:
Snowflake sends a failure notification.
The event is published to an Event Grid custom topic.
A subscription routes the event to an Azure Storage Queue
We intentionally avoided sending events directly to a consumer service.
Why this mattered
In an earlier iteration, we experimented with more direct integrations. The problem was tight coupling — any downstream failure would impact the delivery of notifications.
Event Grid gave us a clean separation between event production and consumption, and built-in retry behavior is very helpful.
Queue as a Reliability Layer
We placed an Azure Storage Queue between Event Grid and the processing layer. Interestingly, this ended up solving more problems than we initially expected.
Without the queue, we ran into:
It was hard to handle a large number of failures
It limits visibility into unprocessed events
By introducing the queue (in the same storage account that hosts the source file container), we gained:
A reliable buffer for failure events with clear observability into pending issues.
It also gave us the ability to decouple ingestion from notification timing.
This small addition made the system significantly more robust.
Processing Failures with Azure Logic Apps
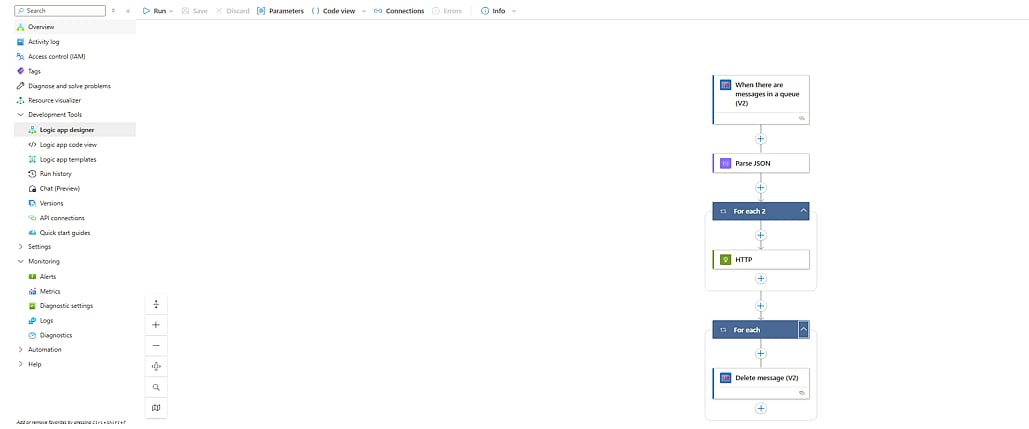
An Azure Logic App consumes messages from the queue and handles the notification workflow. The flow inside the Logic App is straightforward but intentionally structured:
Trigger: When there are messages in the queue
Parse JSON: Normalize and extract relevant fields from the Snowpipe message.
For Each Loop: Iterate through failure events.
HTTP Action: Send notification to the data engineering group (or your support team).
Cleanup Step: Delete the message from the queue after successful processing.
We used an HTTP action instead of a built-in “Send Email” action because we were required to use an HTTP-based approach. You're likely to encounter similar restrictions for a few reasons:
Data leakage risk: prebuilt email connectors can make it easy to send data outside controlled boundaries.
Lack of centralized governance: emails sent directly from Logic Apps may bypass standard auditing, logging, or compliance controls.
Credential management: email connectors often rely on user-scoped credentials (e.g., Outlook or SMTP), which are harder to manage at scale.
Inconsistent policy enforcement: it's more difficult to enforce organization-wide rules like rate limits, content filtering, and routing.
By contrast, an HTTP action typically routes notifications through an internal service or approved endpoint — for example, an internal notification API, messaging gateway, or workflow service. This allows:
Centralized control over outbound communication
Standardized logging and auditing
Better integration with enterprise security policies
Flexibility to evolve notification channels (email, Teams, incident systems) without changing the Logic App
This constraint actually worked in our favor because we were forced to design a more flexible process. Instead of coupling the Logic app directly to emails, we introduced a layer that can adapt as notification requirements evolve.
Two notes worth paying attention to:
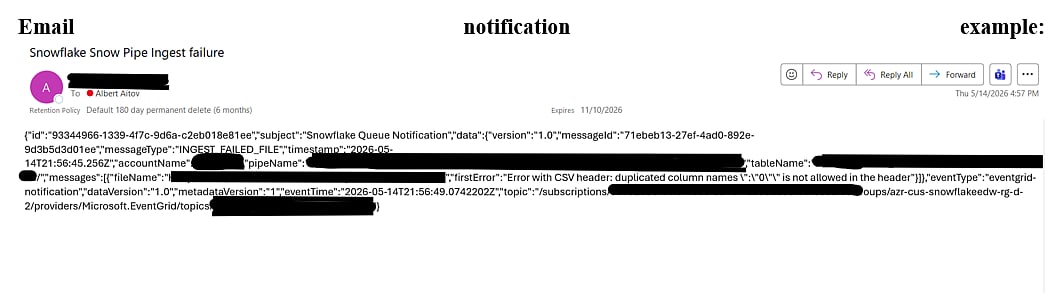
● Payload variability. One issue we encountered early was variability in message payloads — even small inconsistencies made parsing unreliable. We addressed this by enforcing a consistent schema during parsing, rather than relying on implicit structure.
● Monitor the monitor. While your Logic App processes error messages and sends notifications, don't forget to set up an alert for the Logic App itself in case it fails. Use “Alerts” under the “Monitoring” tab of your Logic App.
Logic App design example:
Email notification example:
Key Design Decisions and Tradeoffs
1. Letting Snowpipe Continue on Failure
We intentionally did not try to stop ingestion when a file fails.
Pros: High availability and continuous ingestion
Cons: Requires strong downstream observability
2. Event Grid + Queue Instead of Direct Notifications
We chose a multi-step event routing model.
Pros: Reliability and decoupling.
Cons: Additional components and configuration
In practice, this made the system easier to extend later.
3. Logic Apps for Workflow
We opted for a managed workflow instead of a custom service.
Pros: Faster to implement and maintain
Cons: Limited flexibility for complex transformations
For a notification-driven use case, this was sufficient.
Lessons Learned
A few insights stood out from this implementation:
Silent failures are more dangerous than visible ones.
Event-driven patterns work well even for operational concerns
Schema consistency matters more than we expected.
Small reliability layers, like queues, can have a bigger impact than expected.
One mistake we made early on was assuming Snowpipe's built-in resilience was enough. It wasn't — the system needed an external notification setup.
Where This Approach Falls Short
This design isn't ideal in scenarios where:
Ultra-low latency notifications are required.
Event volume is very high.
Complex enrichment or correlation across multiple systems is needed
In those cases, a streaming platform or custom service may be more appropriate.
Conclusion
Snowpipe's ability to skip problematic files is useful but without visibility, it creates other risks, such as missed data altogether.
By introducing an event-driven failure handling mechanism using Snowflake and Azure services, we were able to address those hidden ingestion issues and capture them without compromising pipeline stability.
The main part was realizing that not all failures break your pipelines, but they can still “break” your data. Designing for all types of failure, including those that are invisible is what ultimately makes a data platform reliable.
References
1 Snowflake Documentation, Enabling Snowpipe error notifications for Microsoft Azure Event Grid (2024), Snowflake — https://docs.snowflake.com/en/user-guide/data-load-snowpipe-errors-azure
2 Snowflake Documentation,Ccreating a Notification Integration to send notifications to a Microsoft Azure Event Grid topic (2024), Snowflake — https://docs.snowflake.com/en/user-guide/notifications/creating-notification-integration-azure-event-grid
About the Author
Albert Aitov is a Data Architect with over 10 years of experience designing, building, and operating data platforms in cloud environments. He specializes in architecting metadata-driven ingestion frameworks, Snowflake-based analytics systems, and Azure-native orchestration pipelines for complex enterprise use cases, with a focus on resilient, scalable architectures that modernize legacy systems and enable data-driven decision-making across organizations.