
Nolen began their writing career in 2019, with three years dedicated to editing the Creative section at MakeUseOf. Their expertise lies at the crossroads of technology and creativity, covering areas like photography, video editing, and graphic design.
Outside of work, you'll often find Nolen diving into a good book, writing their own stories, or playing video games.
Anthropic just made its smallest model a lot cheaper this month, so the timing might be a little awkward for anyone who just started running free models locally. I've been relying on Qwen 3.5 for anything coding-adjacent, so paying for a cloud model on top of that only makes sense if it does something a local one can't. Coding tasks seemed like the best way to test it since that's where small models tend to struggle.
The usual way to test it is asking each model to build something from scratch, which is fine, but that only covers half of the process people lean on AI for. A lot of real coding is just fixing something someone else already wrote, usually with an overlooked problem hiding somewhere that nobody's chased down yet. Coming at it as someone who doesn’t write code, that side felt a lot more relevant to me anyway.
Meet Claude Haiku 5.5
The Claude model that barely touches your usage limits

Haiku 5.5 came out in early October off the Claude 5.5 lineup after Sonnet and Opus. Most of the noise was about price, since Anthropic lists it at $0.10 per million input tokens and $0.50 for output. That’s a tenth of what Haiku 4.5 cost, as long as each prompt stays under 100,000 tokens, which counts everything the model reads at that point, pasted code and earlier chat history included. Go over that and the price jumps to $0.50 in and $2.50 out, but I don't think most tasks like the ones I did here would go over that. It's also the first Haiku model that gets an adjustable effort level.
Anthropic is upfront that it isn't a coding model and that it's instead meant for quick and high-volume jobs like summaries and helping out the bigger models. The company still recommends Sonnet 5.5 and Opus 5.5 for complex coding. I think what matters is that Haiku 5.5 is available on every Claude plan, including Free. I'm on Pro and run Opus a lot, so the API price matters less to me than how much of my allowance is left by Thursday.
How I set up the test
I didn't build anything from scratch this time
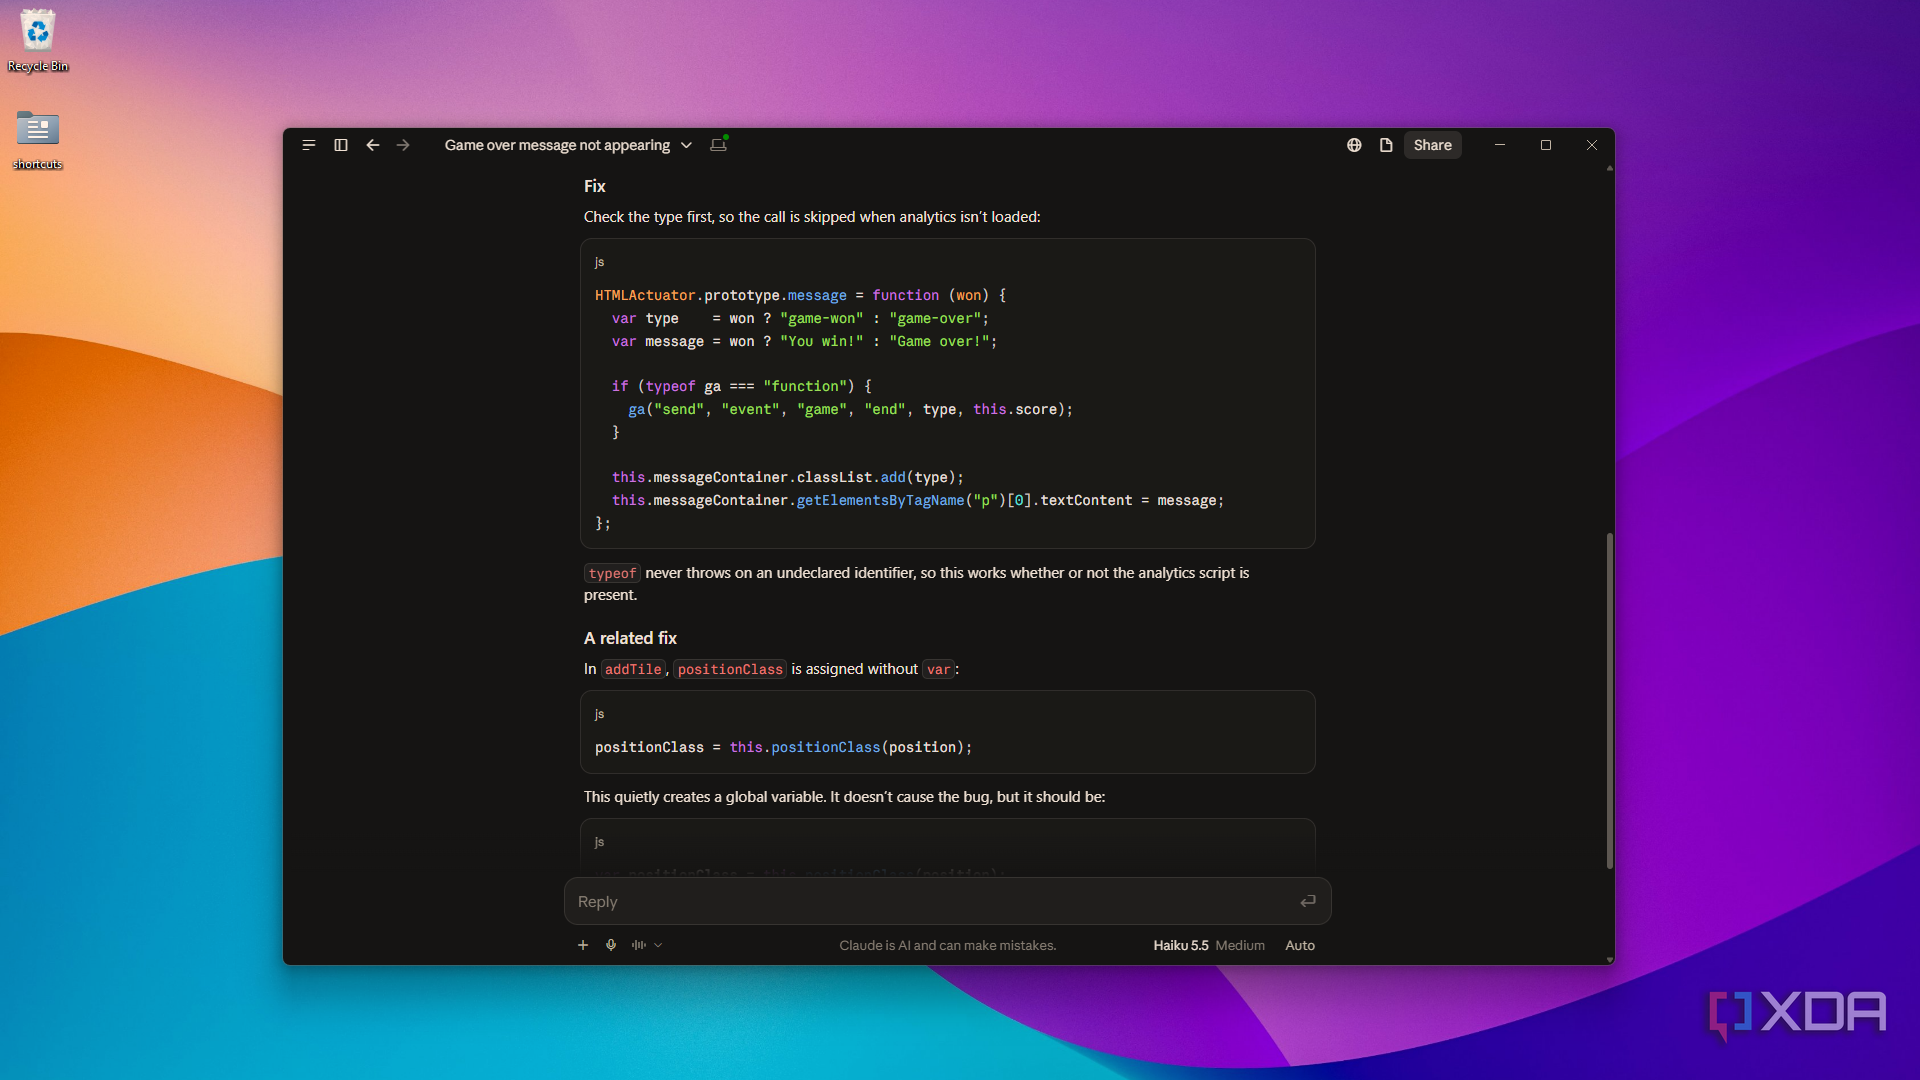
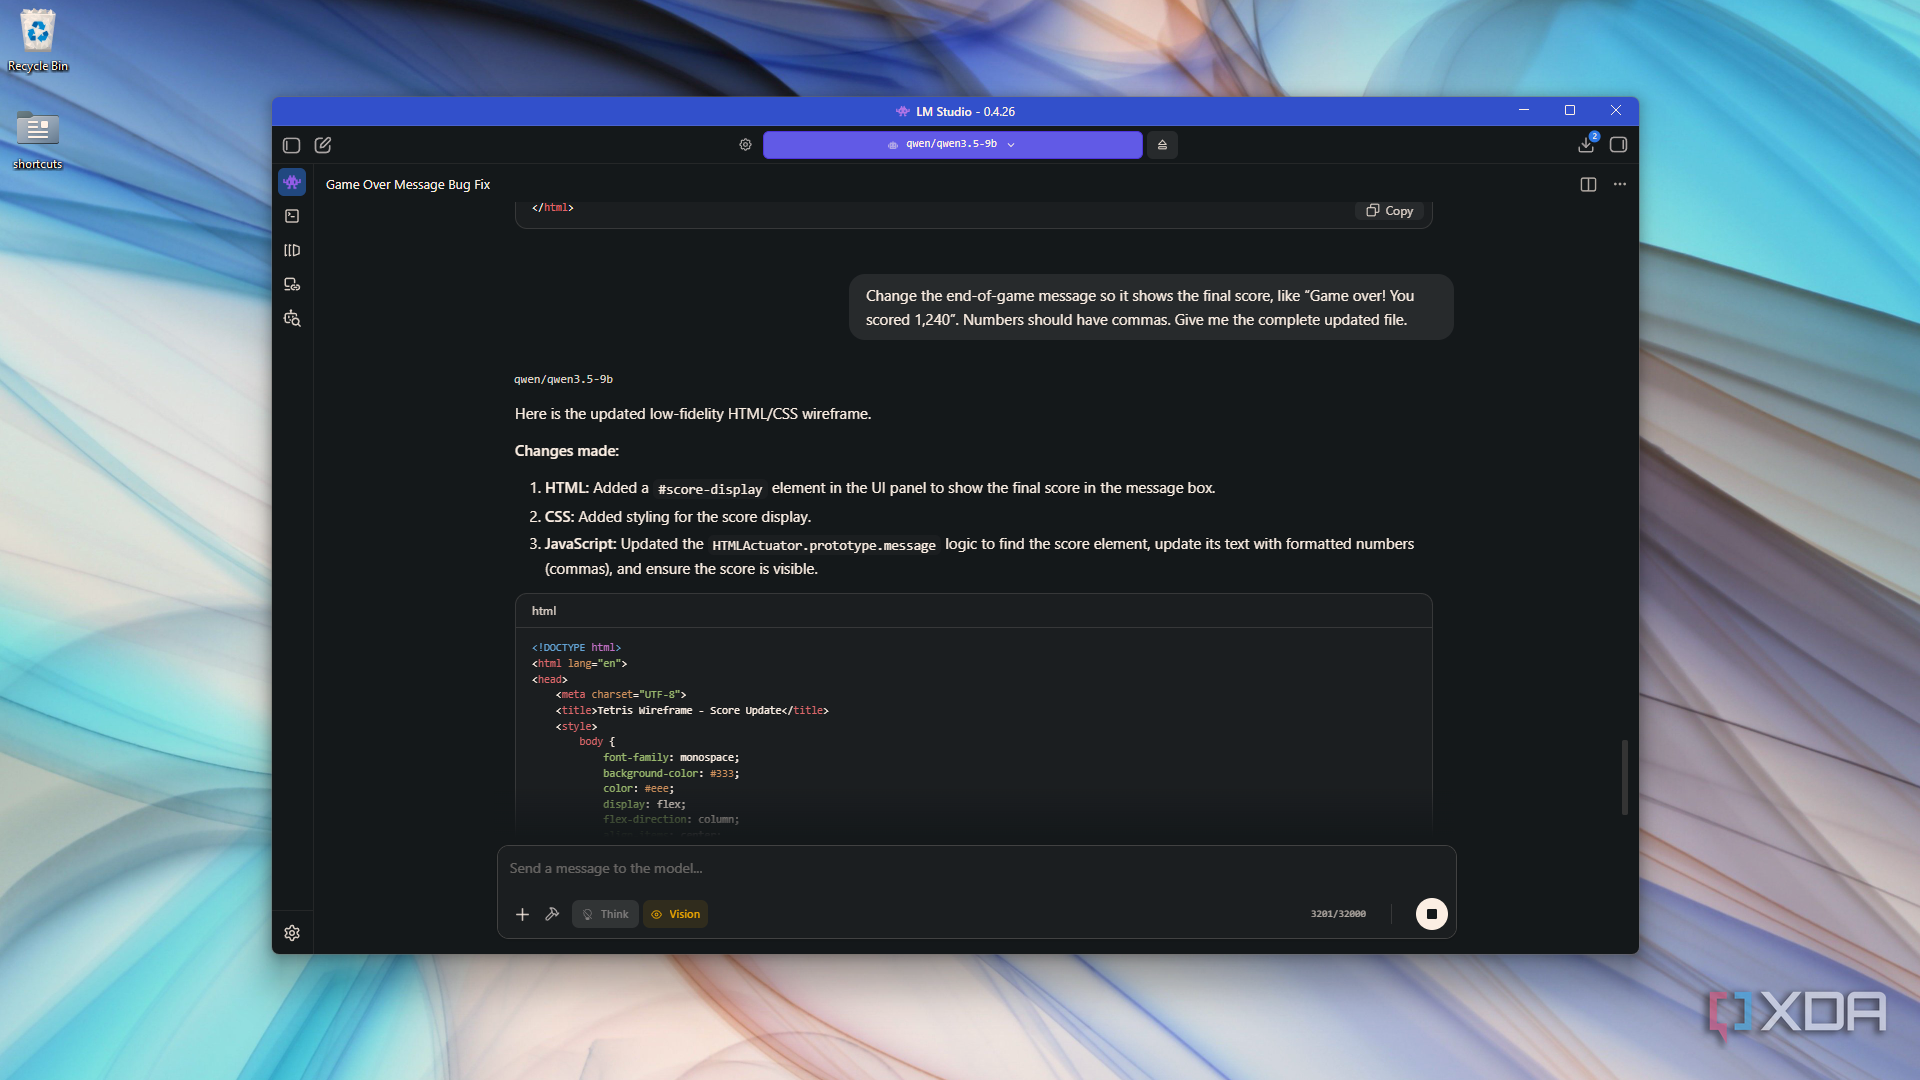
I didn't want to create my millionth productivity tool from scratch again, so this time I went with existing code that had an existing problem. The one I went with was Gabriele Cirulli's open-source 2048, the sliding-tile puzzle game everyone had on their phone in 2014. GitHub keeps every old version of its code, so I grabbed a copy from March 2014, saved just before Cirulli fixed a bug in it. If you play that copy from your own computer and lose, the "Game over!" message never shows up and the board freezes. This is due to a single line trying to send stats to Google Analytics, which isn't loaded when you play offline, so the game trips over it before it's meant to appear.
I ran Haiku on Medium for this, and Anthropic's guidance actually suggests this effort level for getting started with most types of work. Pushing it higher makes it think for longer to the point where Anthropic recommends using Sonnet instead. So Medium it is. For my local LLM, I went with my top model (that I can smoothly run on my 8GB GPU), Qwen 3.5 9B at Q4_K_M, and I capped the context window at 32k, which was plenty for this task. The temperature was 0.7 and I kept Thinking turned off (because historically that just makes Qwen run way too long).
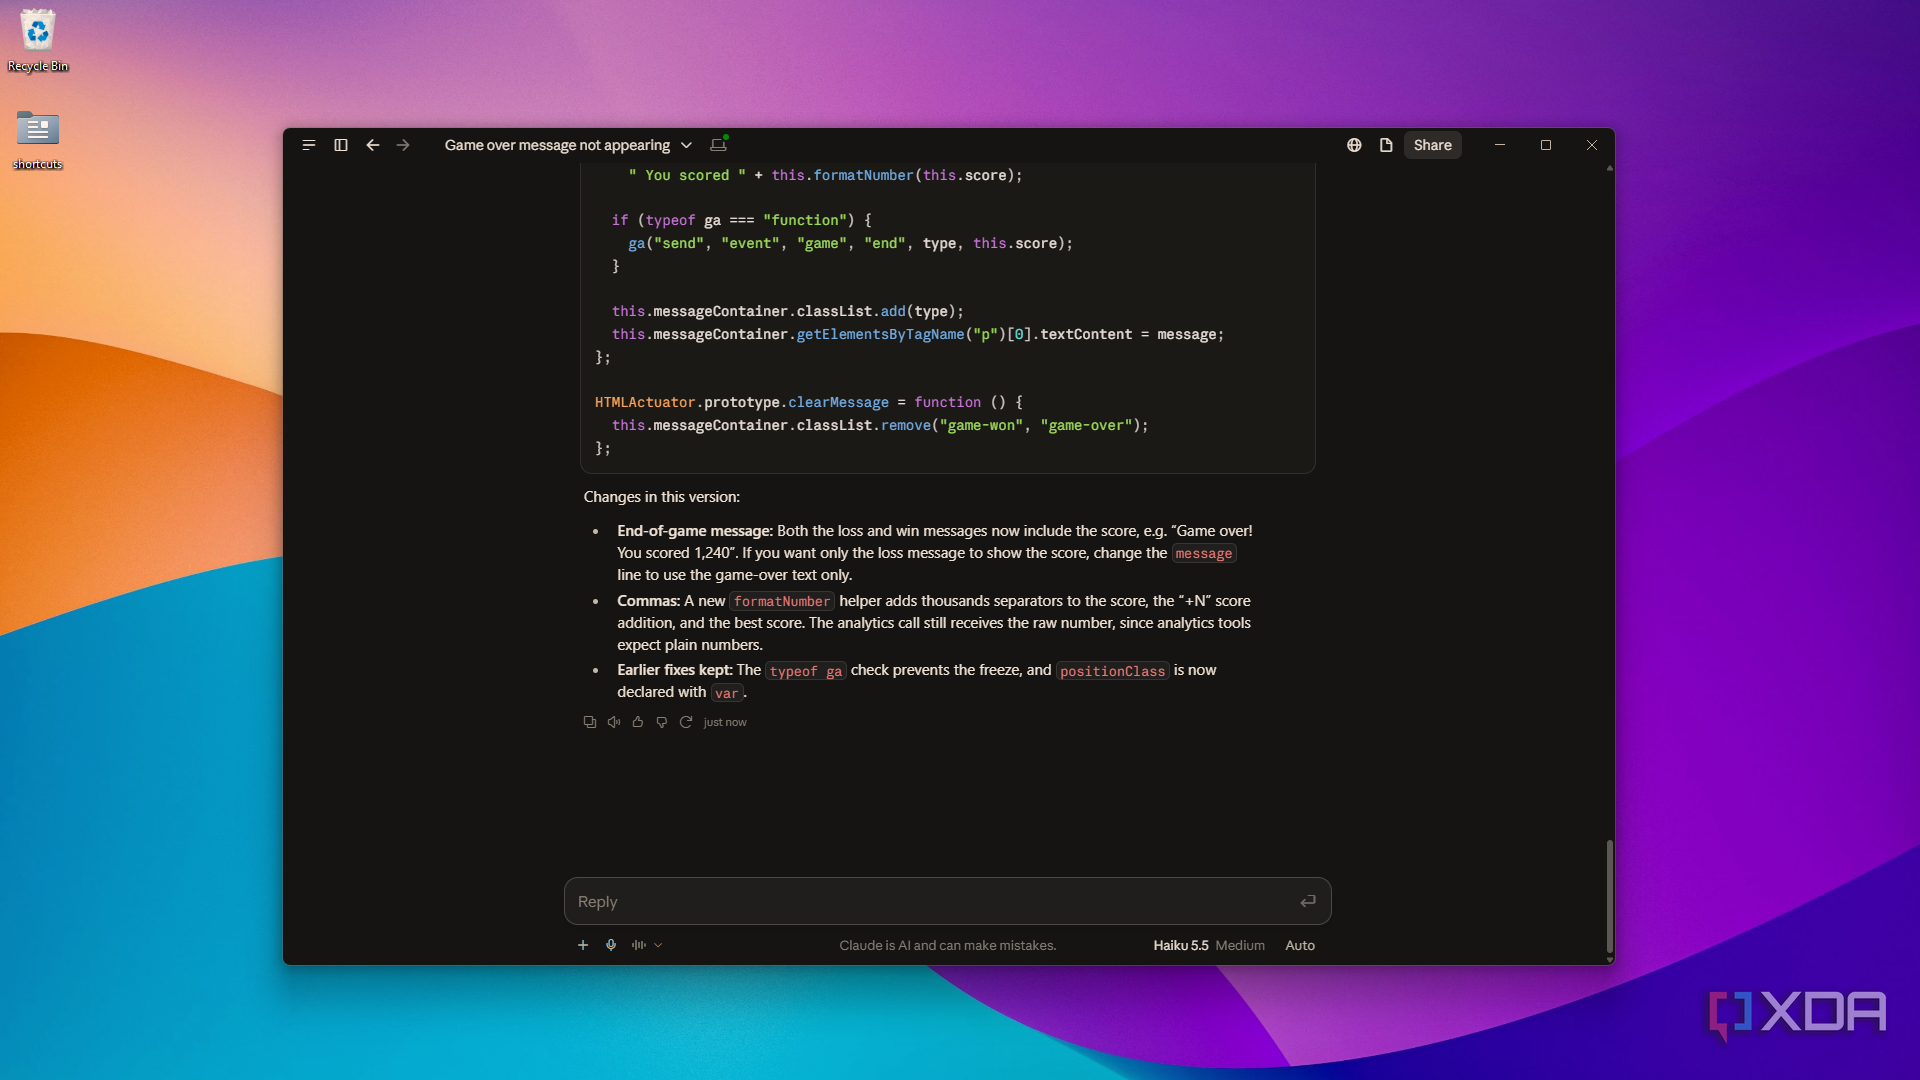
Haiku isn't necessarily the best for agentic work and local models can hit the context very quickly when you point it at a folder of files, so I didn't put either of them in this project folder. Instead, I just gave them the code straight. I knew both would probably catch the bug, so I gave them a little more to work with - I asked for the end message to show the final score with commas, which only works if the original bug gets fixed too, then a review of everything wrong with the file.
How Haiku and Qwen handled the jobs
Fixes, features, and a code review
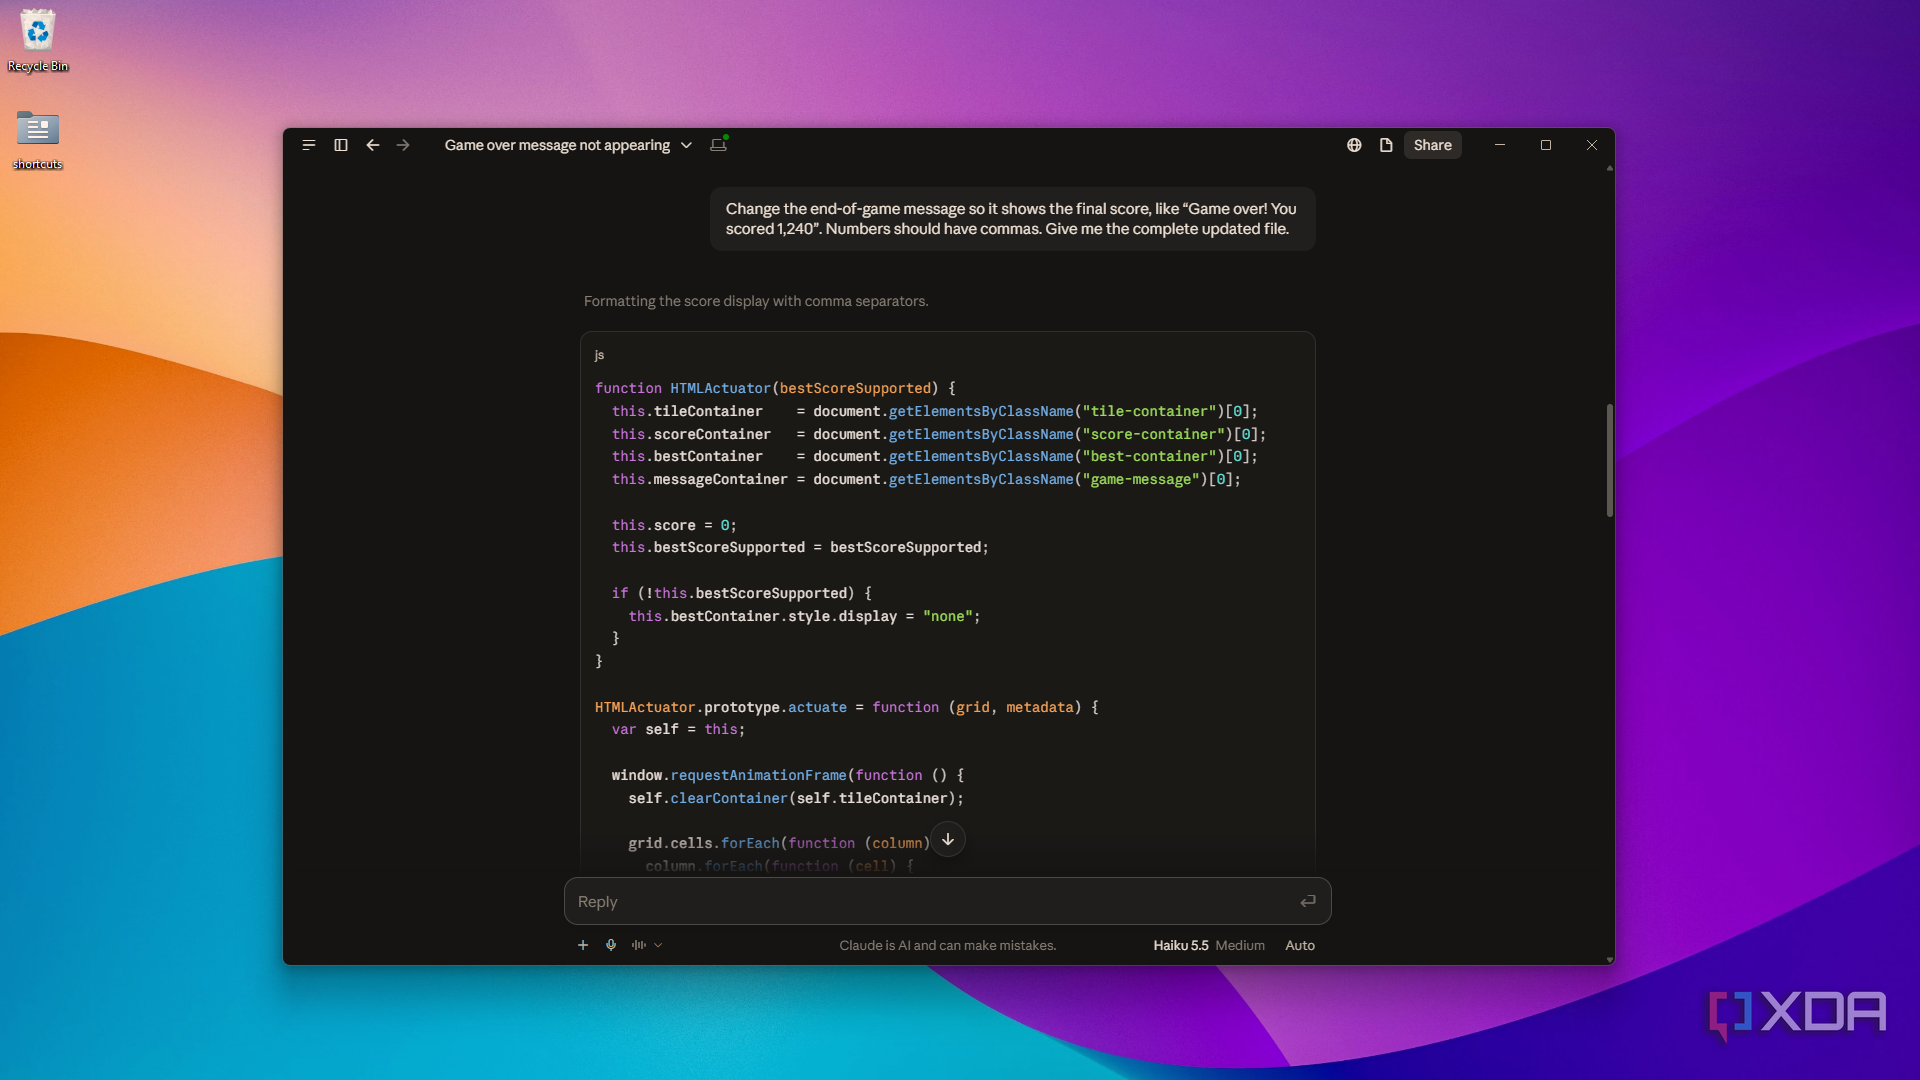
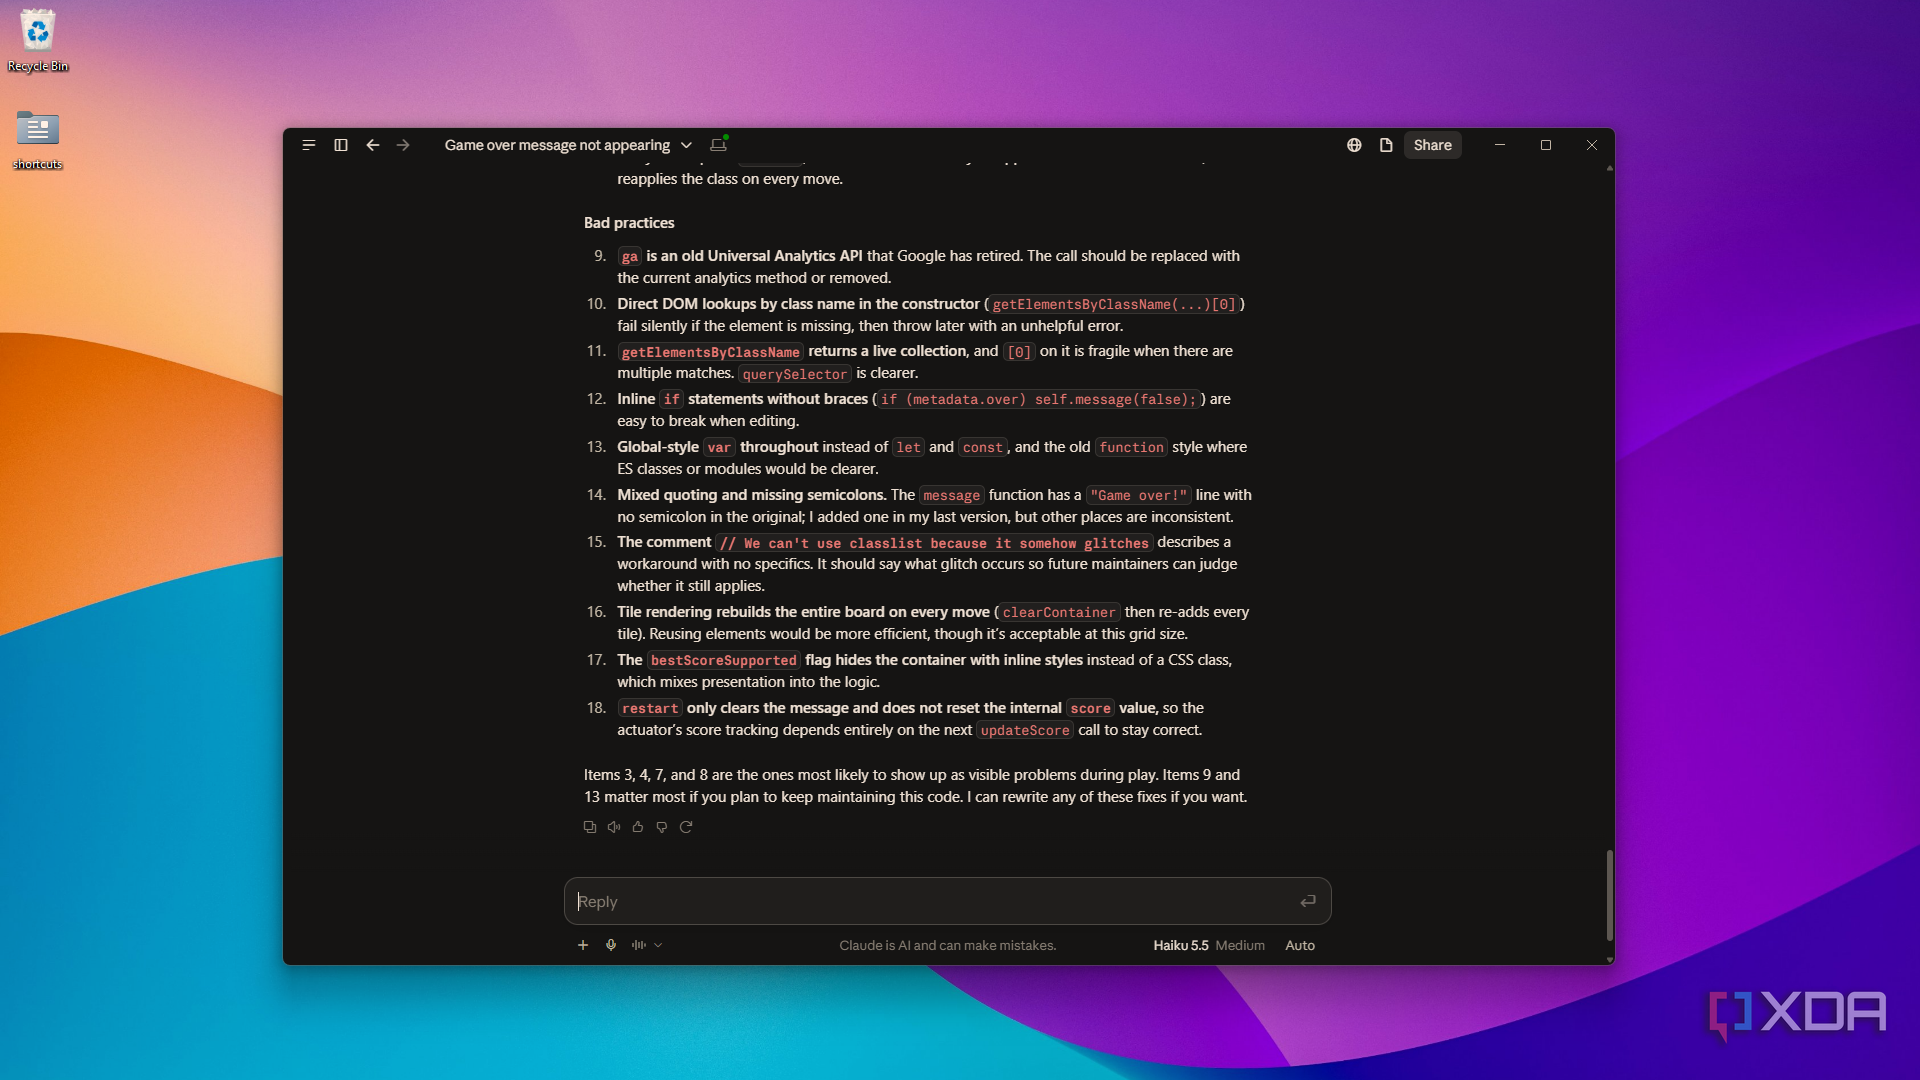
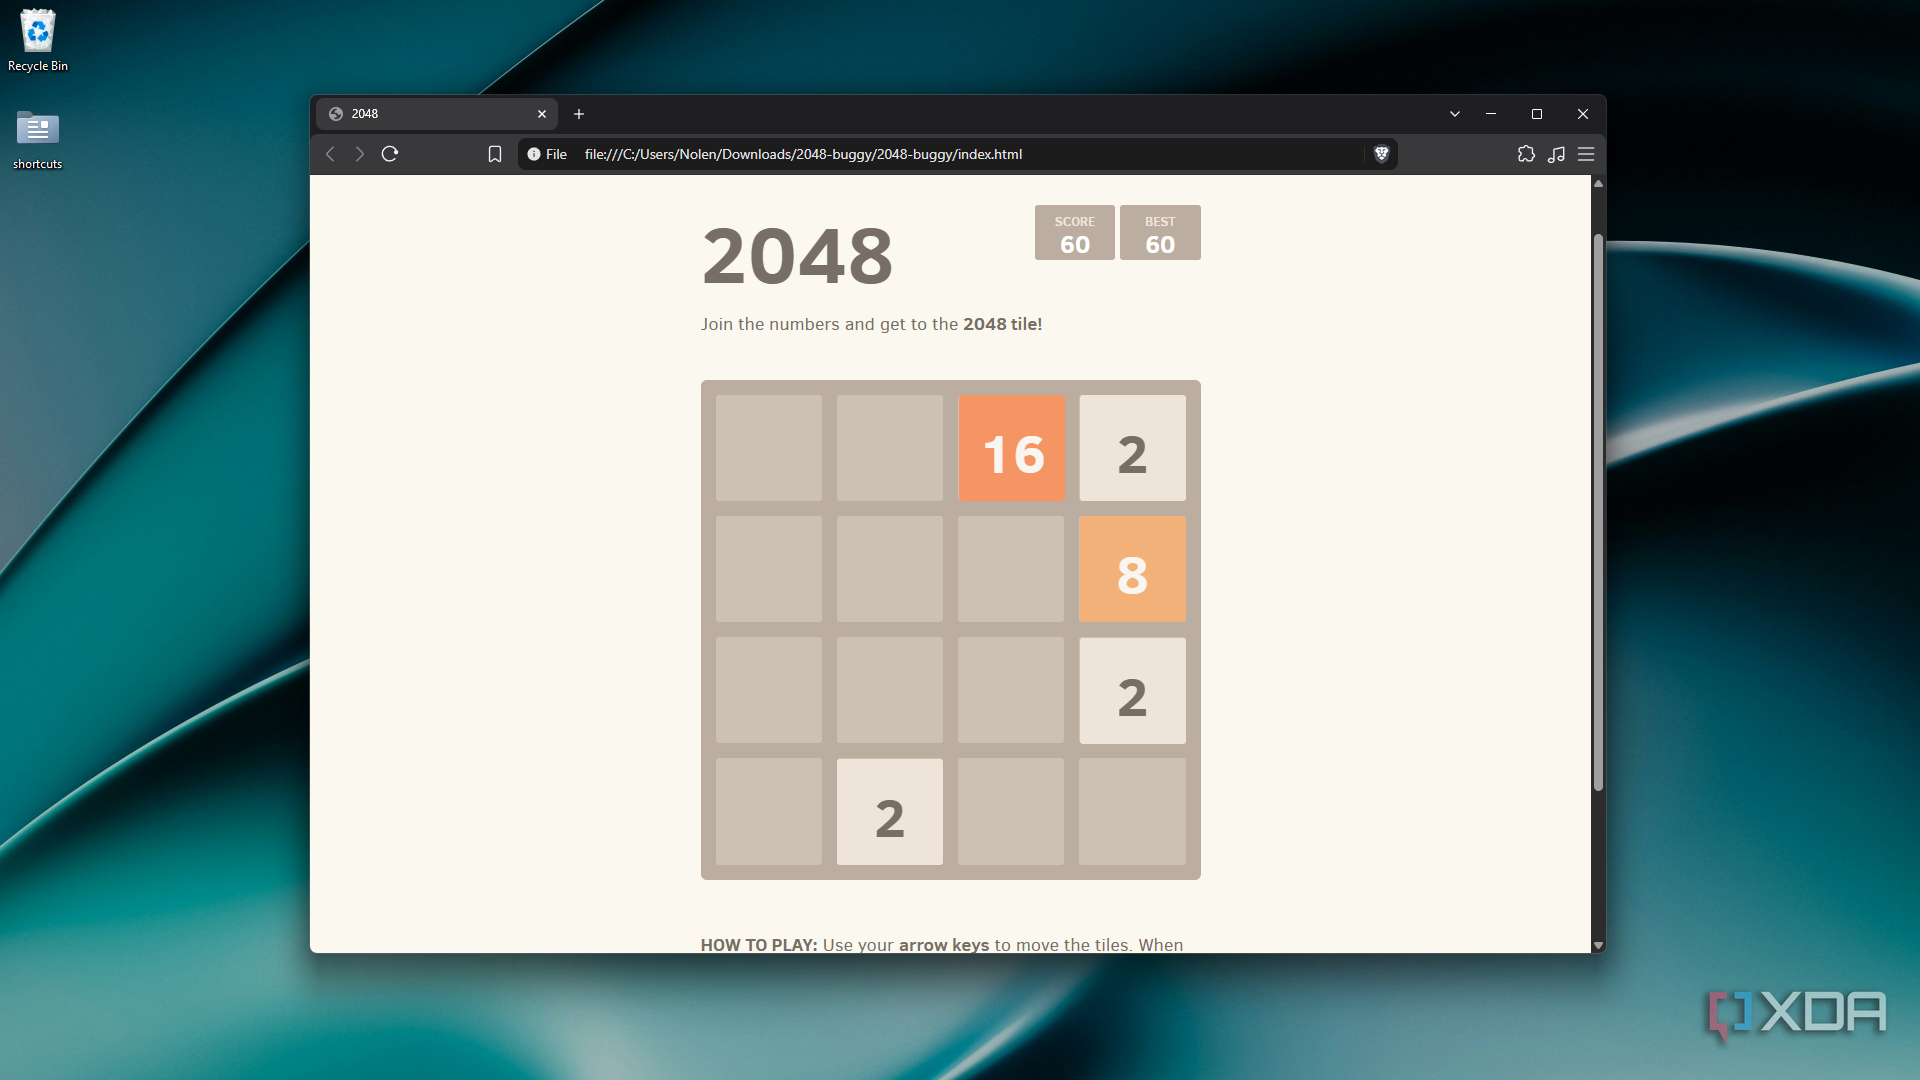
Haiku spotted the bug on the first try and explained it in plain English, pointing at the analytics line and changing it so it only runs when analytics is actually there. Without being asked, it also flagged a second, smaller problem in the same file, where a value meant to stay inside one part of the code was leaking out into the rest of the game. It said that leak wasn’t what was freezing the board, but fixed it anyway.
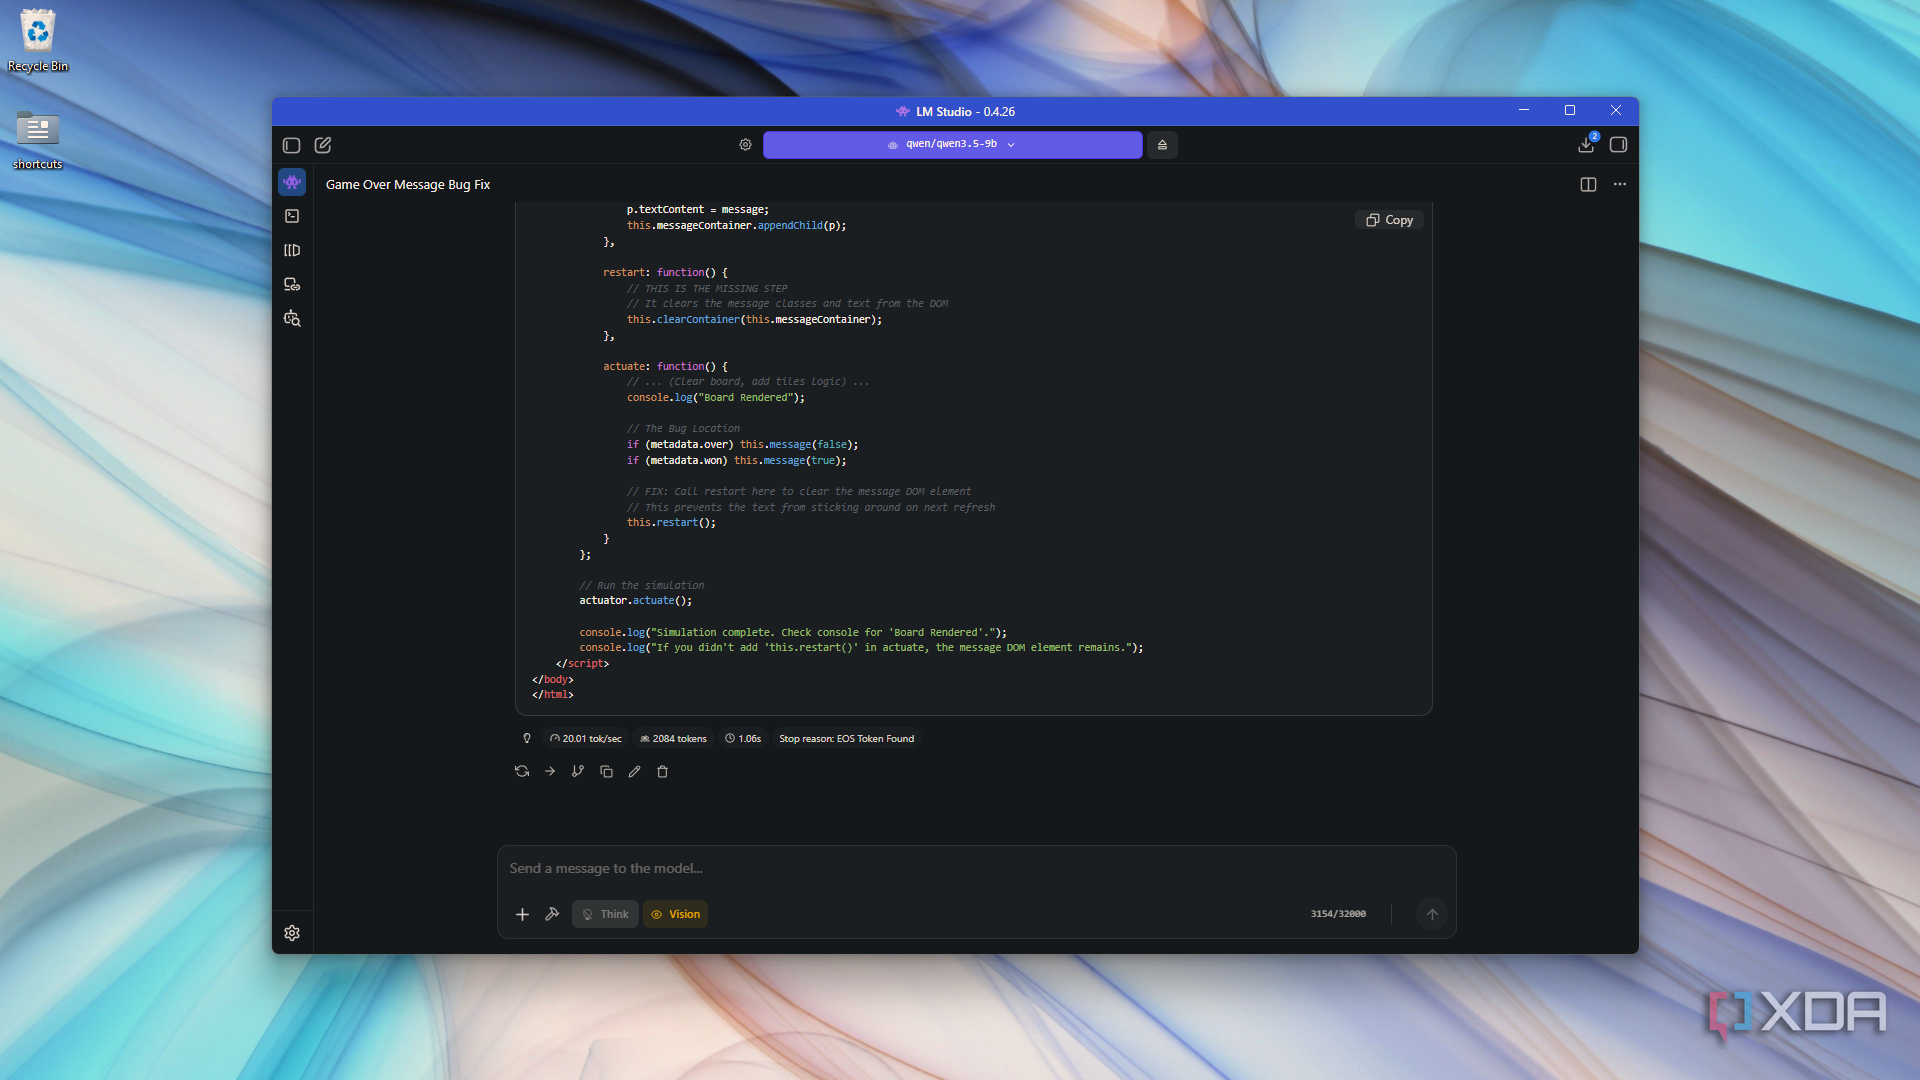
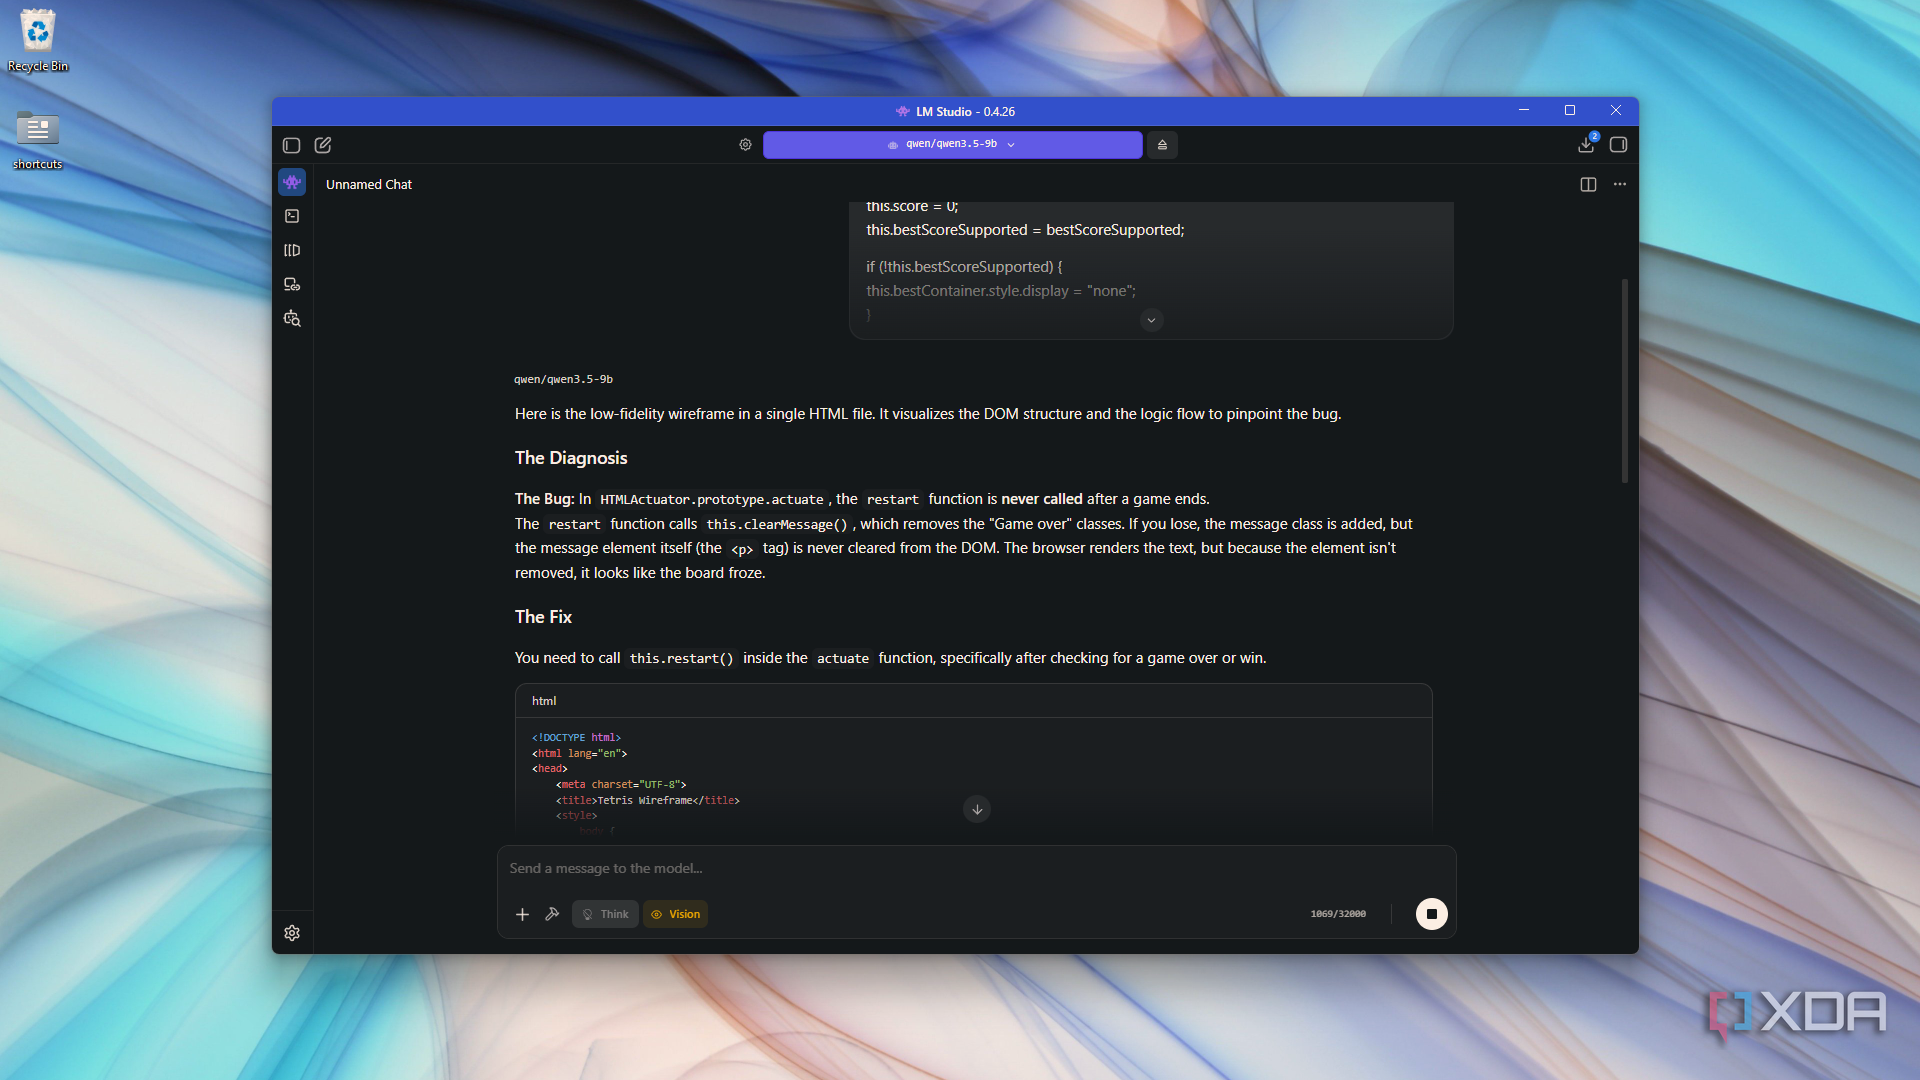
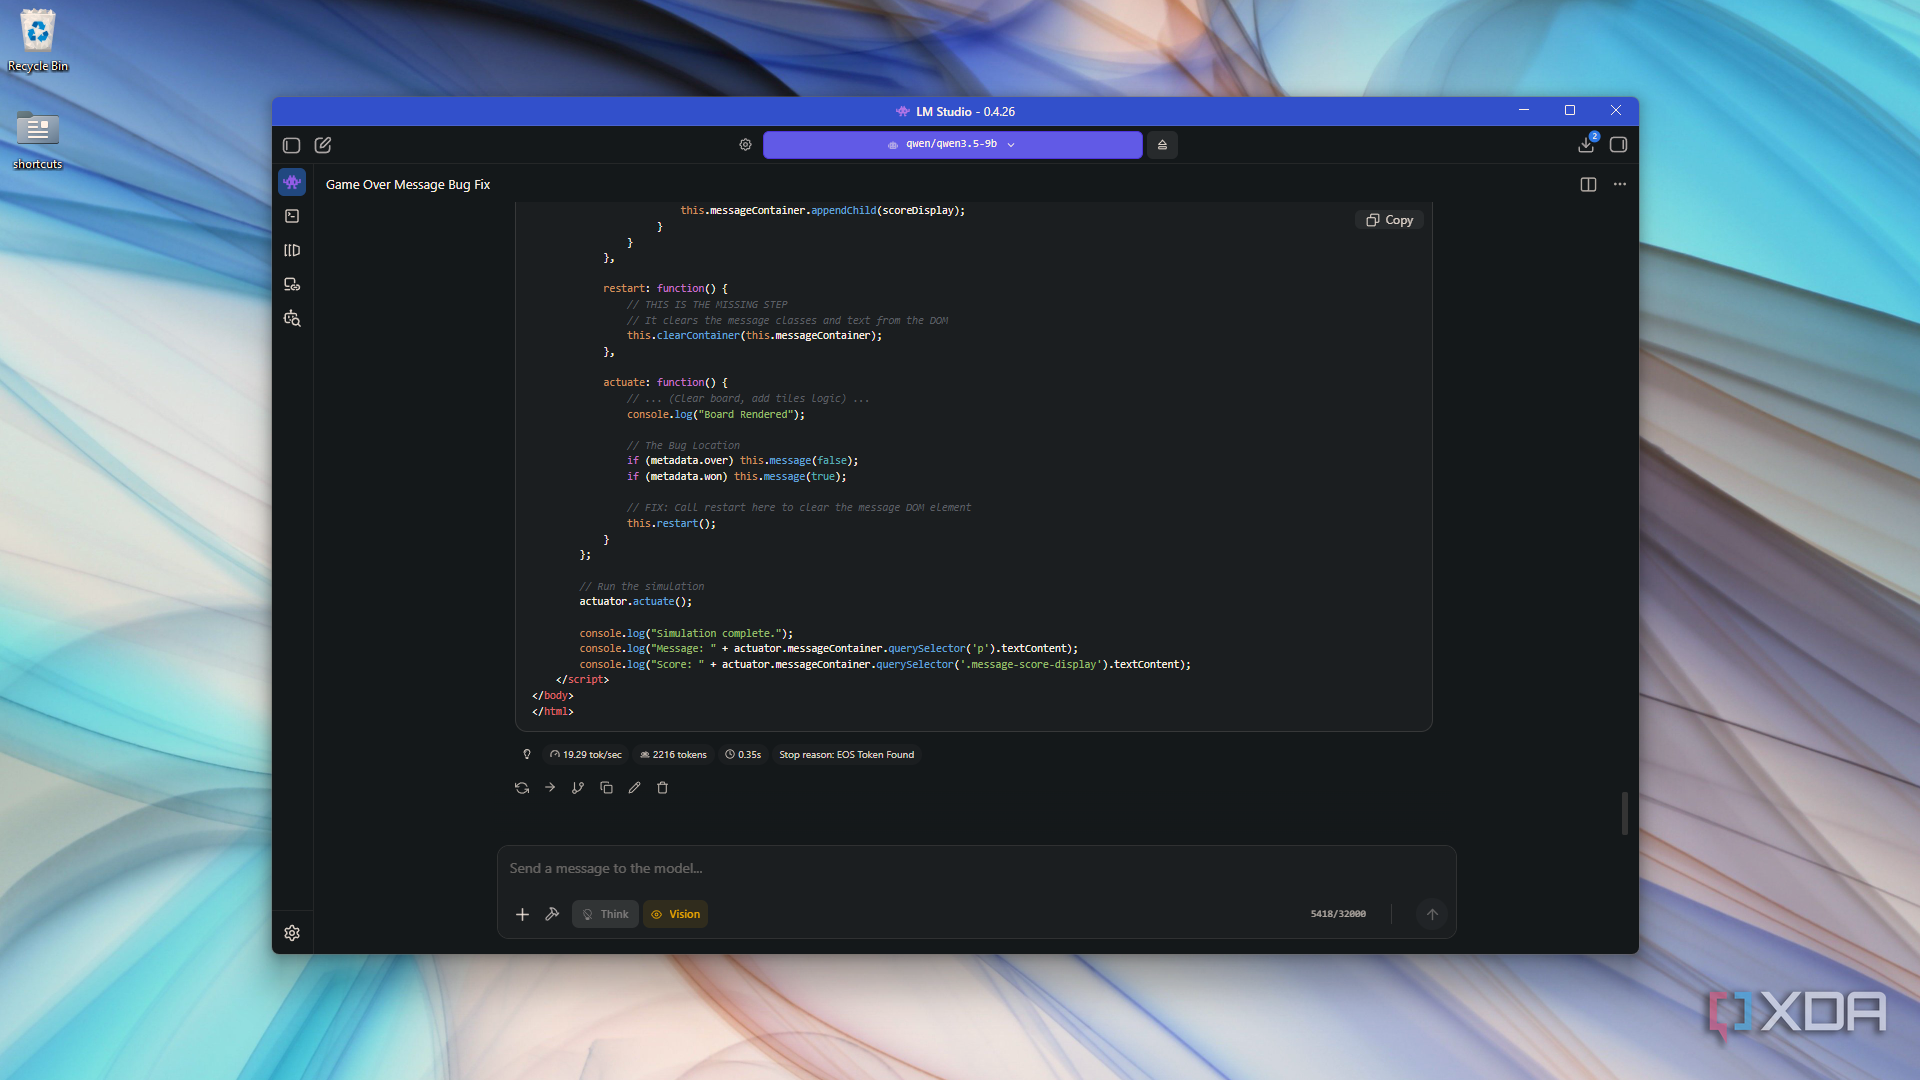
Qwen's first answer was odd from the opening line. It referred to the game as Tetris and called its reply a "low-fidelity wireframe". I thought that this could perhaps be due to my Wireframing preset in LM Studio which includes a system prompt, but there was no preset loaded. Qwen blamed the bug on the game never running its restart step, and its fix would've cleared the message right after showing it, with the analytics line still sitting untouched.
The score feature went the same way. Haiku handed back a full file with the message reading "Game over! You scored 1,240" and both earlier fixes still in place, while Qwen gave me a made-up page with a 10x10 grid that wasn't 2048 at all, crashing line included.
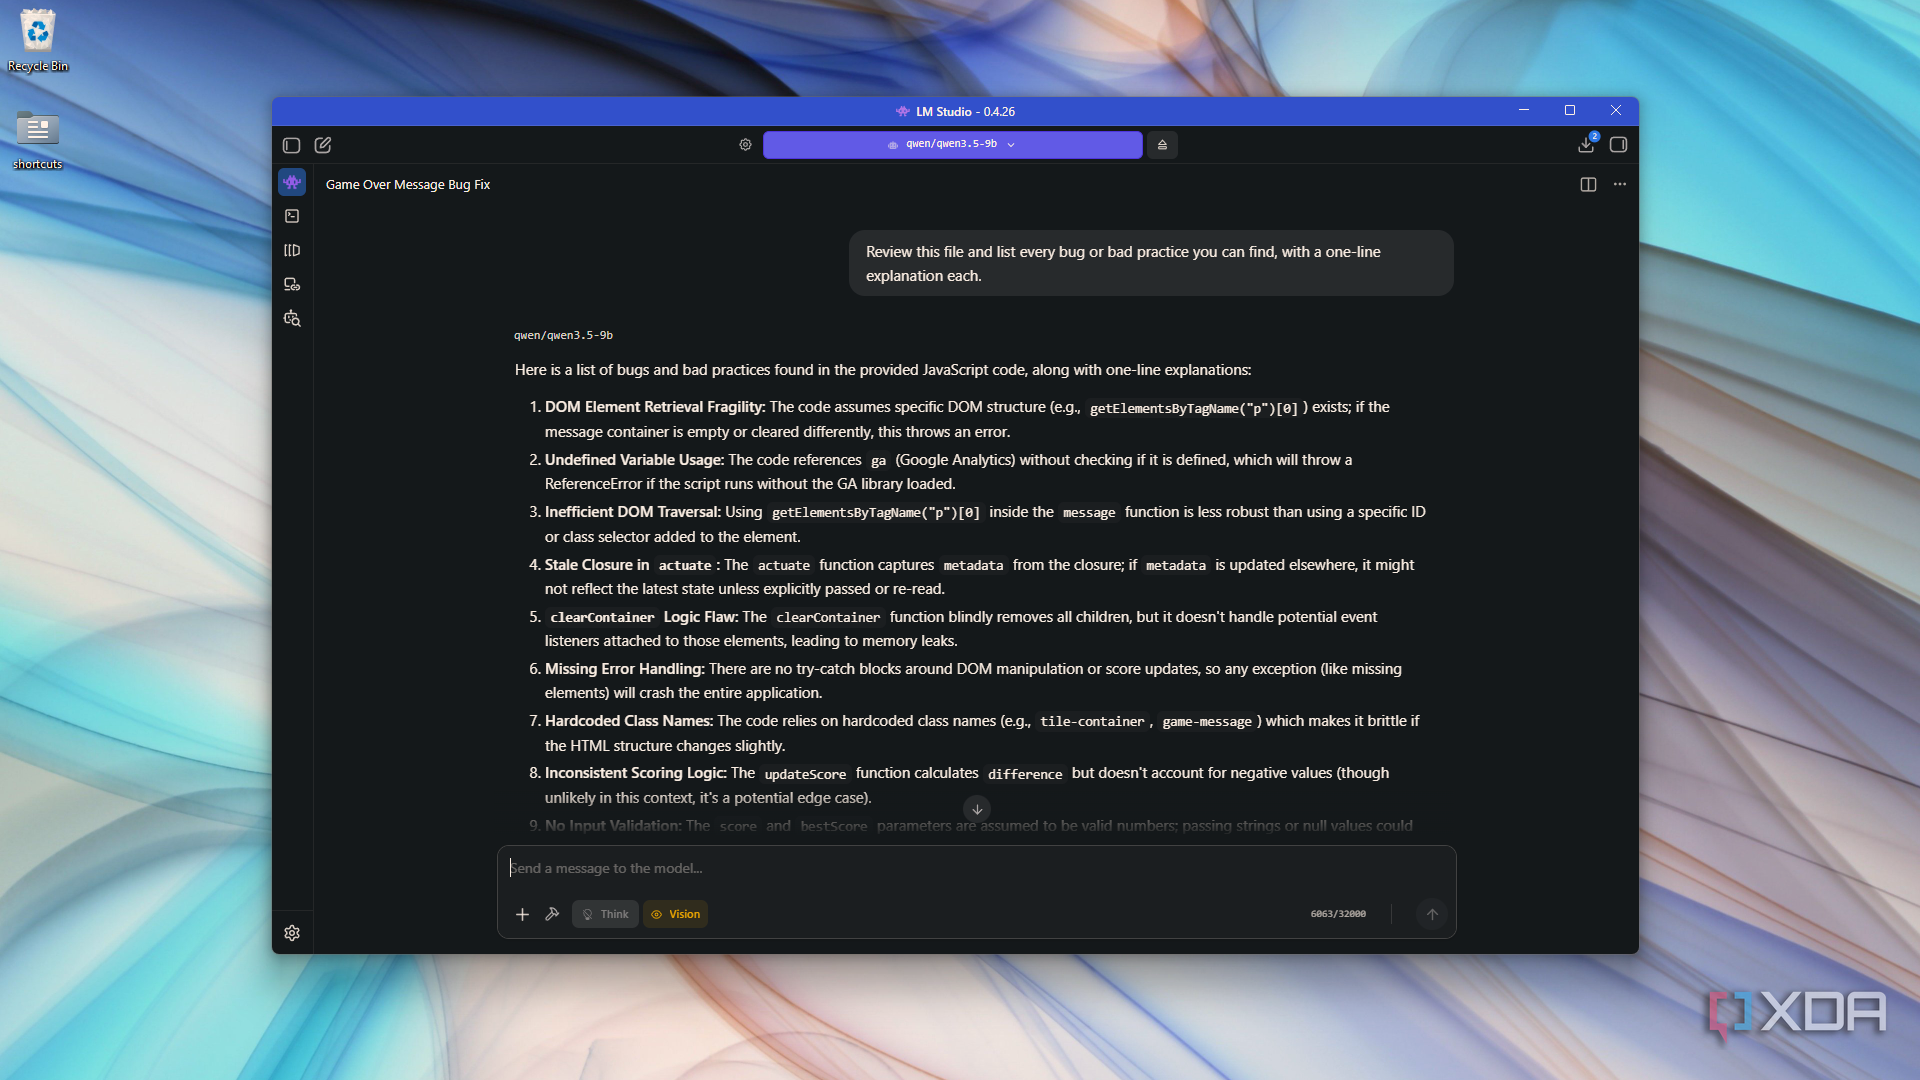
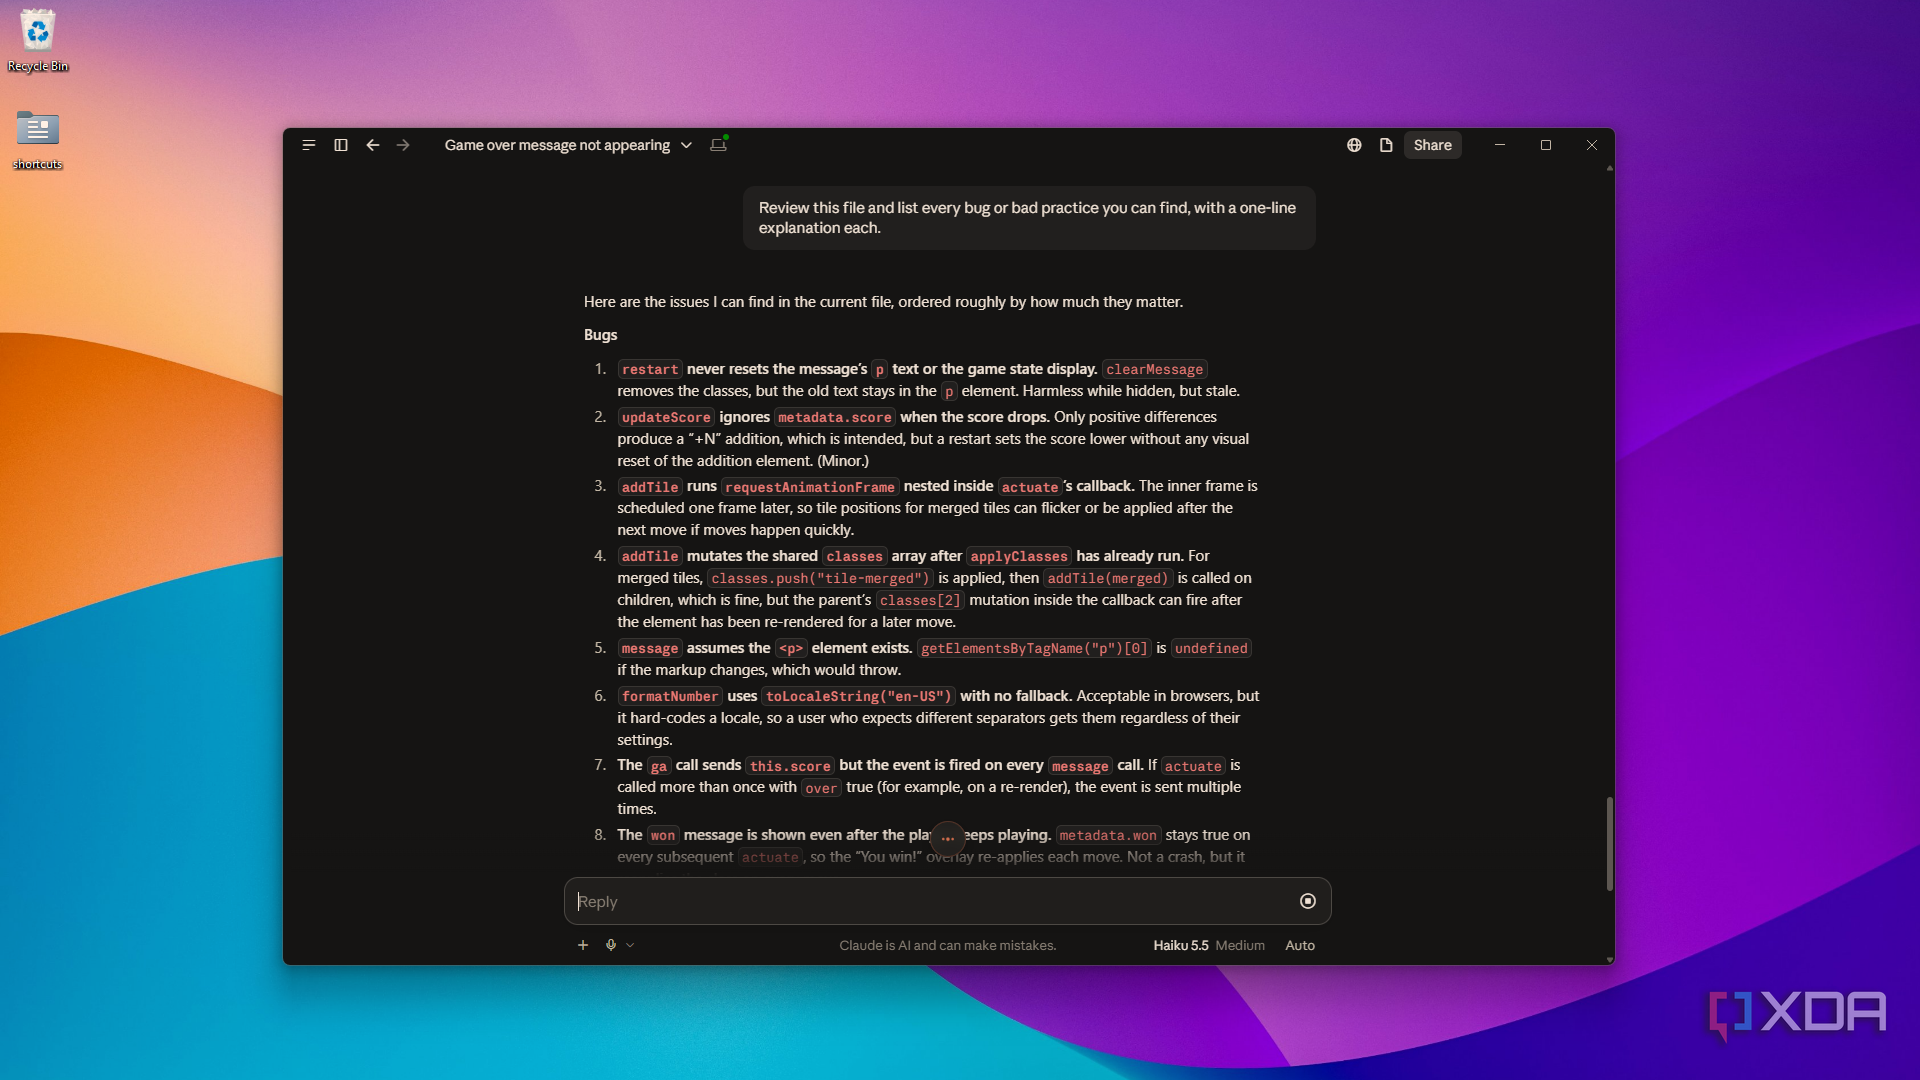
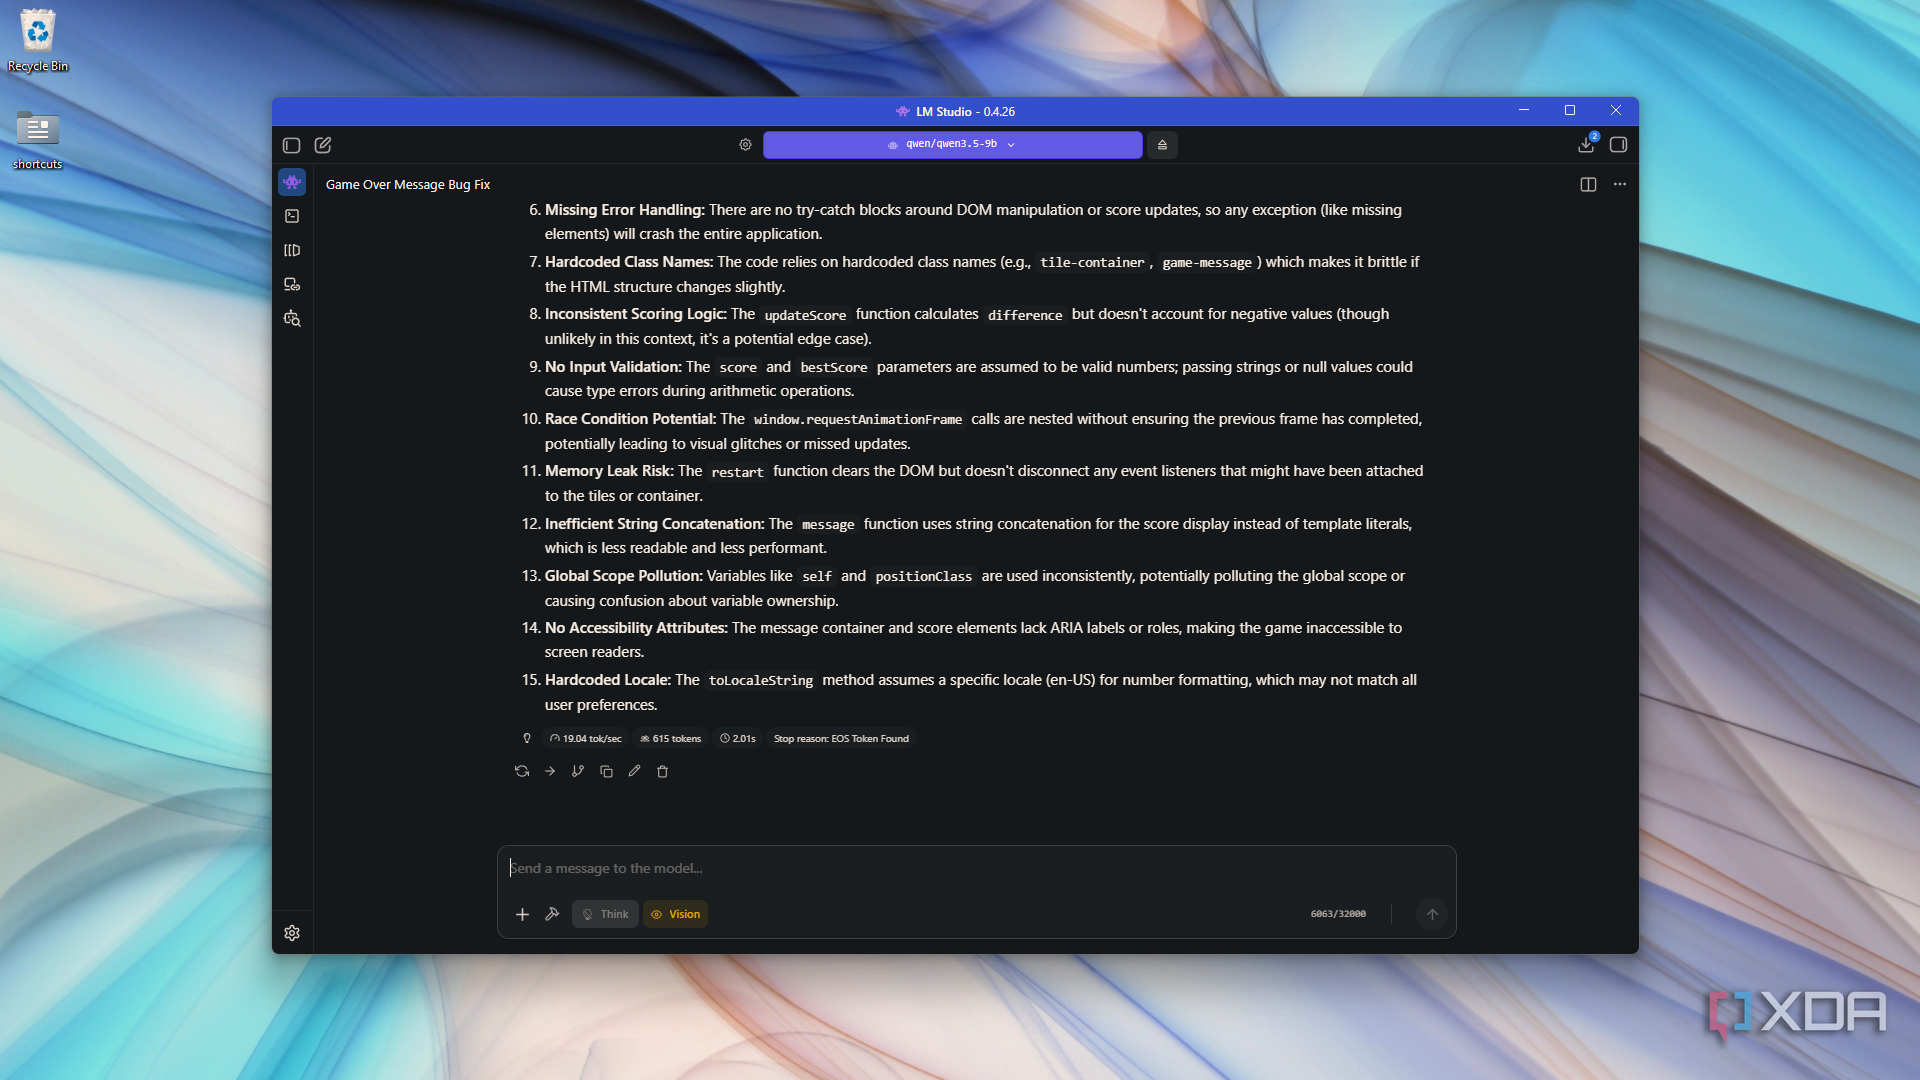
As for the review, Qwen listed the analytics line as a crash risk, second on a list of 15, so it did know the problem was there. It just couldn't fix it when I asked directly, and most of its other points were generic advice you could apply to any code. Meanwhile, Haiku's points were tied to actual lines, and it even noticed the analytics code relies on a Google system that was retired in 2023.
Qwen ran at around 20 tokens a second, which isn't that bad, but Haiku was noticeably faster. This part isn't really a fair comparison because nearly every cloud model will be faster than whatever I have running on my limited hardware. And by my rough maths, all three prompts through Haiku would come to around a cent on the API.
Coding for one cent
I think Haiku takes this win fairly comfortably, and that mainly comes down to it giving me back code that I could paste back into the file and have it work right. I was actually a little surprised since Haiku isn't a strong coding model, but I guess this also wasn't the most intense coding job. Qwen did eventually name the bug in its code review, which was strange after it missed it twice. I'm still keeping Qwen on my PC for work I want to keep local, as long as it's less ambitious work.