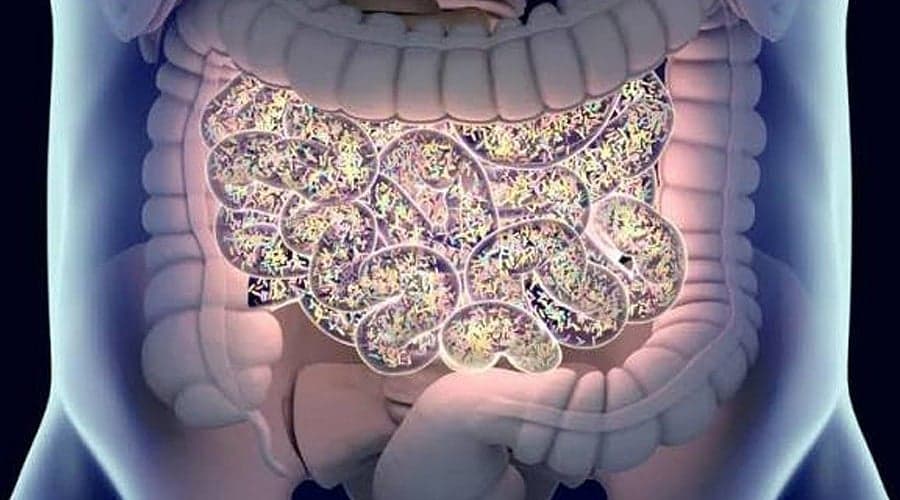
Somewhere in the order of a hundred trillion microorganisms live in the human gut, outnumbering the body's own cells several times over. Each one carries its own genome. Collectively, that's a biological dataset of genuinely staggering scale, and until relatively recently, almost nobody had the tools to read it.
From Biology to Big Data
For most of medical history, the gut microbiome was functionally invisible. You couldn't culture most of these organisms in a lab, and you certainly couldn't analyse them at scale. That changed with metagenomic sequencing, the ability to read the genetic material of an entire microbial community directly from a sample, without needing to isolate and grow each species individually.
The result is a dataset that looks a lot more like something out of a data science problem than a traditional medical test:
Thousands of distinct bacterial species can be present in a single sample.
Relative abundance of each species needs to be calculated, not just presence or absence.
Diversity metrics, how evenly distributed and how varied the bacterial population is, require genuine computational analysis, not a simple readout.
Patterns only become meaningful when compared against reference populations, which itself requires large, well-curated datasets to compare against.
Why This Is a Genuine Analytics Problem, Not Just a Lab Test
A single gut microbiome sample can generate gigabytes of raw sequencing data before it's reduced to anything a clinician can act on. Turning that into something useful involves several layers that look familiar to anyone working in data science:
Bioinformatics pipelines process raw sequencing reads and match them against reference genome databases to identify which species are present.
Statistical modelling is used to calculate diversity indices and detect whether a given sample's composition falls inside or outside a typical range.
Pattern recognition across populations is what allows researchers to link specific microbial signatures to markers like inflammation or metabolic function in the first place, this is population-level data science, not a single test result in isolation.
Longitudinal tracking turns a single data point into a trend, which is where the real analytical value compounds over time.
This is, in a very real sense, a big data problem that happens to live inside the human body rather than a server.
Where the Data Pipeline Still Has a Gap
Here's the part that doesn't get discussed enough: processing the data correctly is only half the problem. A perfectly clean bioinformatics pipeline that outputs a bacterial species list still doesn't tell a person anything useful on its own. Raw output, however analytically sound, needs an interpretation layer sitting on top of it.
That's precisely where a lot of consumer-facing microbiome testing falls short. The sequencing and the statistics can be rigorous, but if the result is simply emailed back as a species list with no clinical context, the analytics pipeline has done its job and then stopped one step too early.
Closing the Loop: Data Plus Clinical Interpretation
Everlab, an Australian preventive health company, is one example of where this gap gets closed properly. Its microbiome test runs the same sequencing and analytical process described above, but the output is reviewed by a doctor before it reaches the member, read alongside their broader health profile rather than handed over as an isolated dataset with no interpretation attached.
That combination, rigorous data processing plus a human expert closing the interpretation gap, is arguably the more interesting story here than the sequencing technology itself. Plenty of fields have learned this lesson already: raw data, however sophisticated the pipeline producing it, is only as useful as the judgement applied on top of it.
The Bigger Picture
The gut microbiome is a genuinely underexplored dataset by the standards of modern data science, millions of base pairs of biological information sitting inside most people, almost never analysed. As sequencing costs continue to fall and computational tools mature, expect this to become a much more mainstream application of the same analytical thinking already reshaping finance, logistics, and nearly every other data-rich industry, just applied, this time, to the body itself.