
Maker, meme-r, and unabashed geek, Joe has been writing about technology since starting his career in 2018 at KnowTechie. He's covered everything from Apple to apps and crowdfunding and loves getting to the bottom of complicated topics. In that time, he's also written for SlashGear and numerous corporate clients before finding his home at XDA in the spring of 2023.
He was the kid who took apart every toy to see how it worked, even if it didn't exactly go back together afterward. That's given him a solid background for explaining how complex systems work together, and he promises he's gotten better at the putting things back together stage since then.
When I set out to train my own ChatGPT-style model from scratch, I assumed raw GPU power would decide everything. I had Andrej Karpathy’s nanochat, a pair of Nvidia DGX Spark mini supercomputers on my desk, and three ways to run the training math: Transformer Engine’s FP8, its newer four-bit NVFP4, and nanochat’s own FP8 code. Fewer bits and newer tools should mean a faster finish. Only one of the three actually delivered.
And the GPU was never really the problem. One Spark spent a week telling me its GPU was 96% busy while using about a fifth of its rated compute, and adding a second Spark swapped one bottleneck for another, and neither was the one I expected. Running models is the easy part, as anyone who has started self-hosting LLMs knows. This is the other side of the coin: training an AI from nothing, and finding out where the time actually goes.
One DGX Spark ran flat out for a week and used a fifth of its compute
Busy isn't the same as productive

The first attempt ran on a single Spark: a 20-layer nanochat model with 896.5 million parameters, trained on 5.2 billion tokens. It took six days and 21 hours. I logged everything to Weights & Biases, and on paper the GPU looked perfect, sitting at 96% utilization from the first hour to the last.
Then I looked at the power draw. The GB10 spent most of that week pulling 50 to 60 W and peaked at 90 W, which isn't what a chip running flat out looks like. GPU utilization measures how often a kernel runs, not how much of the chip that kernel uses. A GPU can be busy all the time and still be coasting. And before anyone asks, this wasn't the power-brick bug some Spark owners have hit, because the clock held around 2,460 MHz all week.

The math backs that up. Nanochat estimated the whole run at about 15 quintillion floating-point operations, which works out to roughly 25 TFLOPS sustained. Nvidia's headline figure for the GB10 is 1 petaFLOP of FP4 with sparsity, which works back to about 125 TFLOPS of dense BF16, and a plain matrix-multiply test on one of my Sparks hit 98.6 TFLOPS while drawing 81 to 85 W. So the chip can get close to its spec when you hand it nothing but math, and nanochat got about a quarter of that at well under that power.
|
BF16 compute on one GB10 |
TFLOPS |
|---|---|
|
Spec (derived from Nvidia's 1 PFLOP FP4 sparse figure) |
~125 |
|
Best-case matrix-multiply test |
98.6 |
|
Nanochat, whole-run average |
~25 |
The log had warned me from step zero. FlashAttention 3 wasn't available, so nanochat fell back to PyTorch's SDPA attention, which can't handle the sliding-window pattern the model used. The warning said, "Your GPU utilization will be terrible," and it wasn't kidding. By the time I'd dug into it, the run was far enough along that restarting would have cost more hours than the fix could win back. At an assumed 20% speedup, restarting a run this long only pays off on roughly the first day, so I let it finish and filed the lesson away for next time: sort out the attention path before you press go.
The dashboards don't help much, either. Nanochat's own efficiency readout printed "bf16_mfu: 0.00" on every single step for six days, because it had no peak-compute figure for the GB10 to divide by. Weights & Biases had its own blind spot: its "GPU Time Spent Accessing Memory" chart sat at 0% all week, because the GB10 doesn't report that metric at all. Neither number means the hardware was idle, but both are easy to misread at a glance.
Memory capacity wasn't the problem either, since at least 26 GB stayed free the whole time. Bandwidth is another story. Nanochat was built on eight H100s, and each H100 has 3.35 TB/s of memory bandwidth, compared with Spark's 273 GB/s, roughly 12 times as much. The GB10 doesn't expose bandwidth counters, so I can't prove it was starving for data, but the hardware nanochat was tuned on had a lot more room to breathe.
So, how does my homemade ChatGPT actually talk?

It still worked, though. Early in the single-Spark run, I asked it to finish "If 5x + 3 = 13, then x is", and the model babbled "5x 5x 5x." By the end, it answered 5. Not a great start, but let's remember that nanochat is around GPT-2 level of smarts, and even the smallest local LLMs have surpassed that mark.

It did much better at writing haiku, where it has a structure and a goal to work within. That's one thing that LLMs are very good at, because of the pattern-recognition aspect of their creation. They're not so good at general questions unless they come from an encyclopedia and were written several years ago. Without access to web search, nanochat is limited to the data used in training and knows nothing about the last couple of years.
A second Spark changed the bottleneck instead of removing it
Every update waits for the slower machine
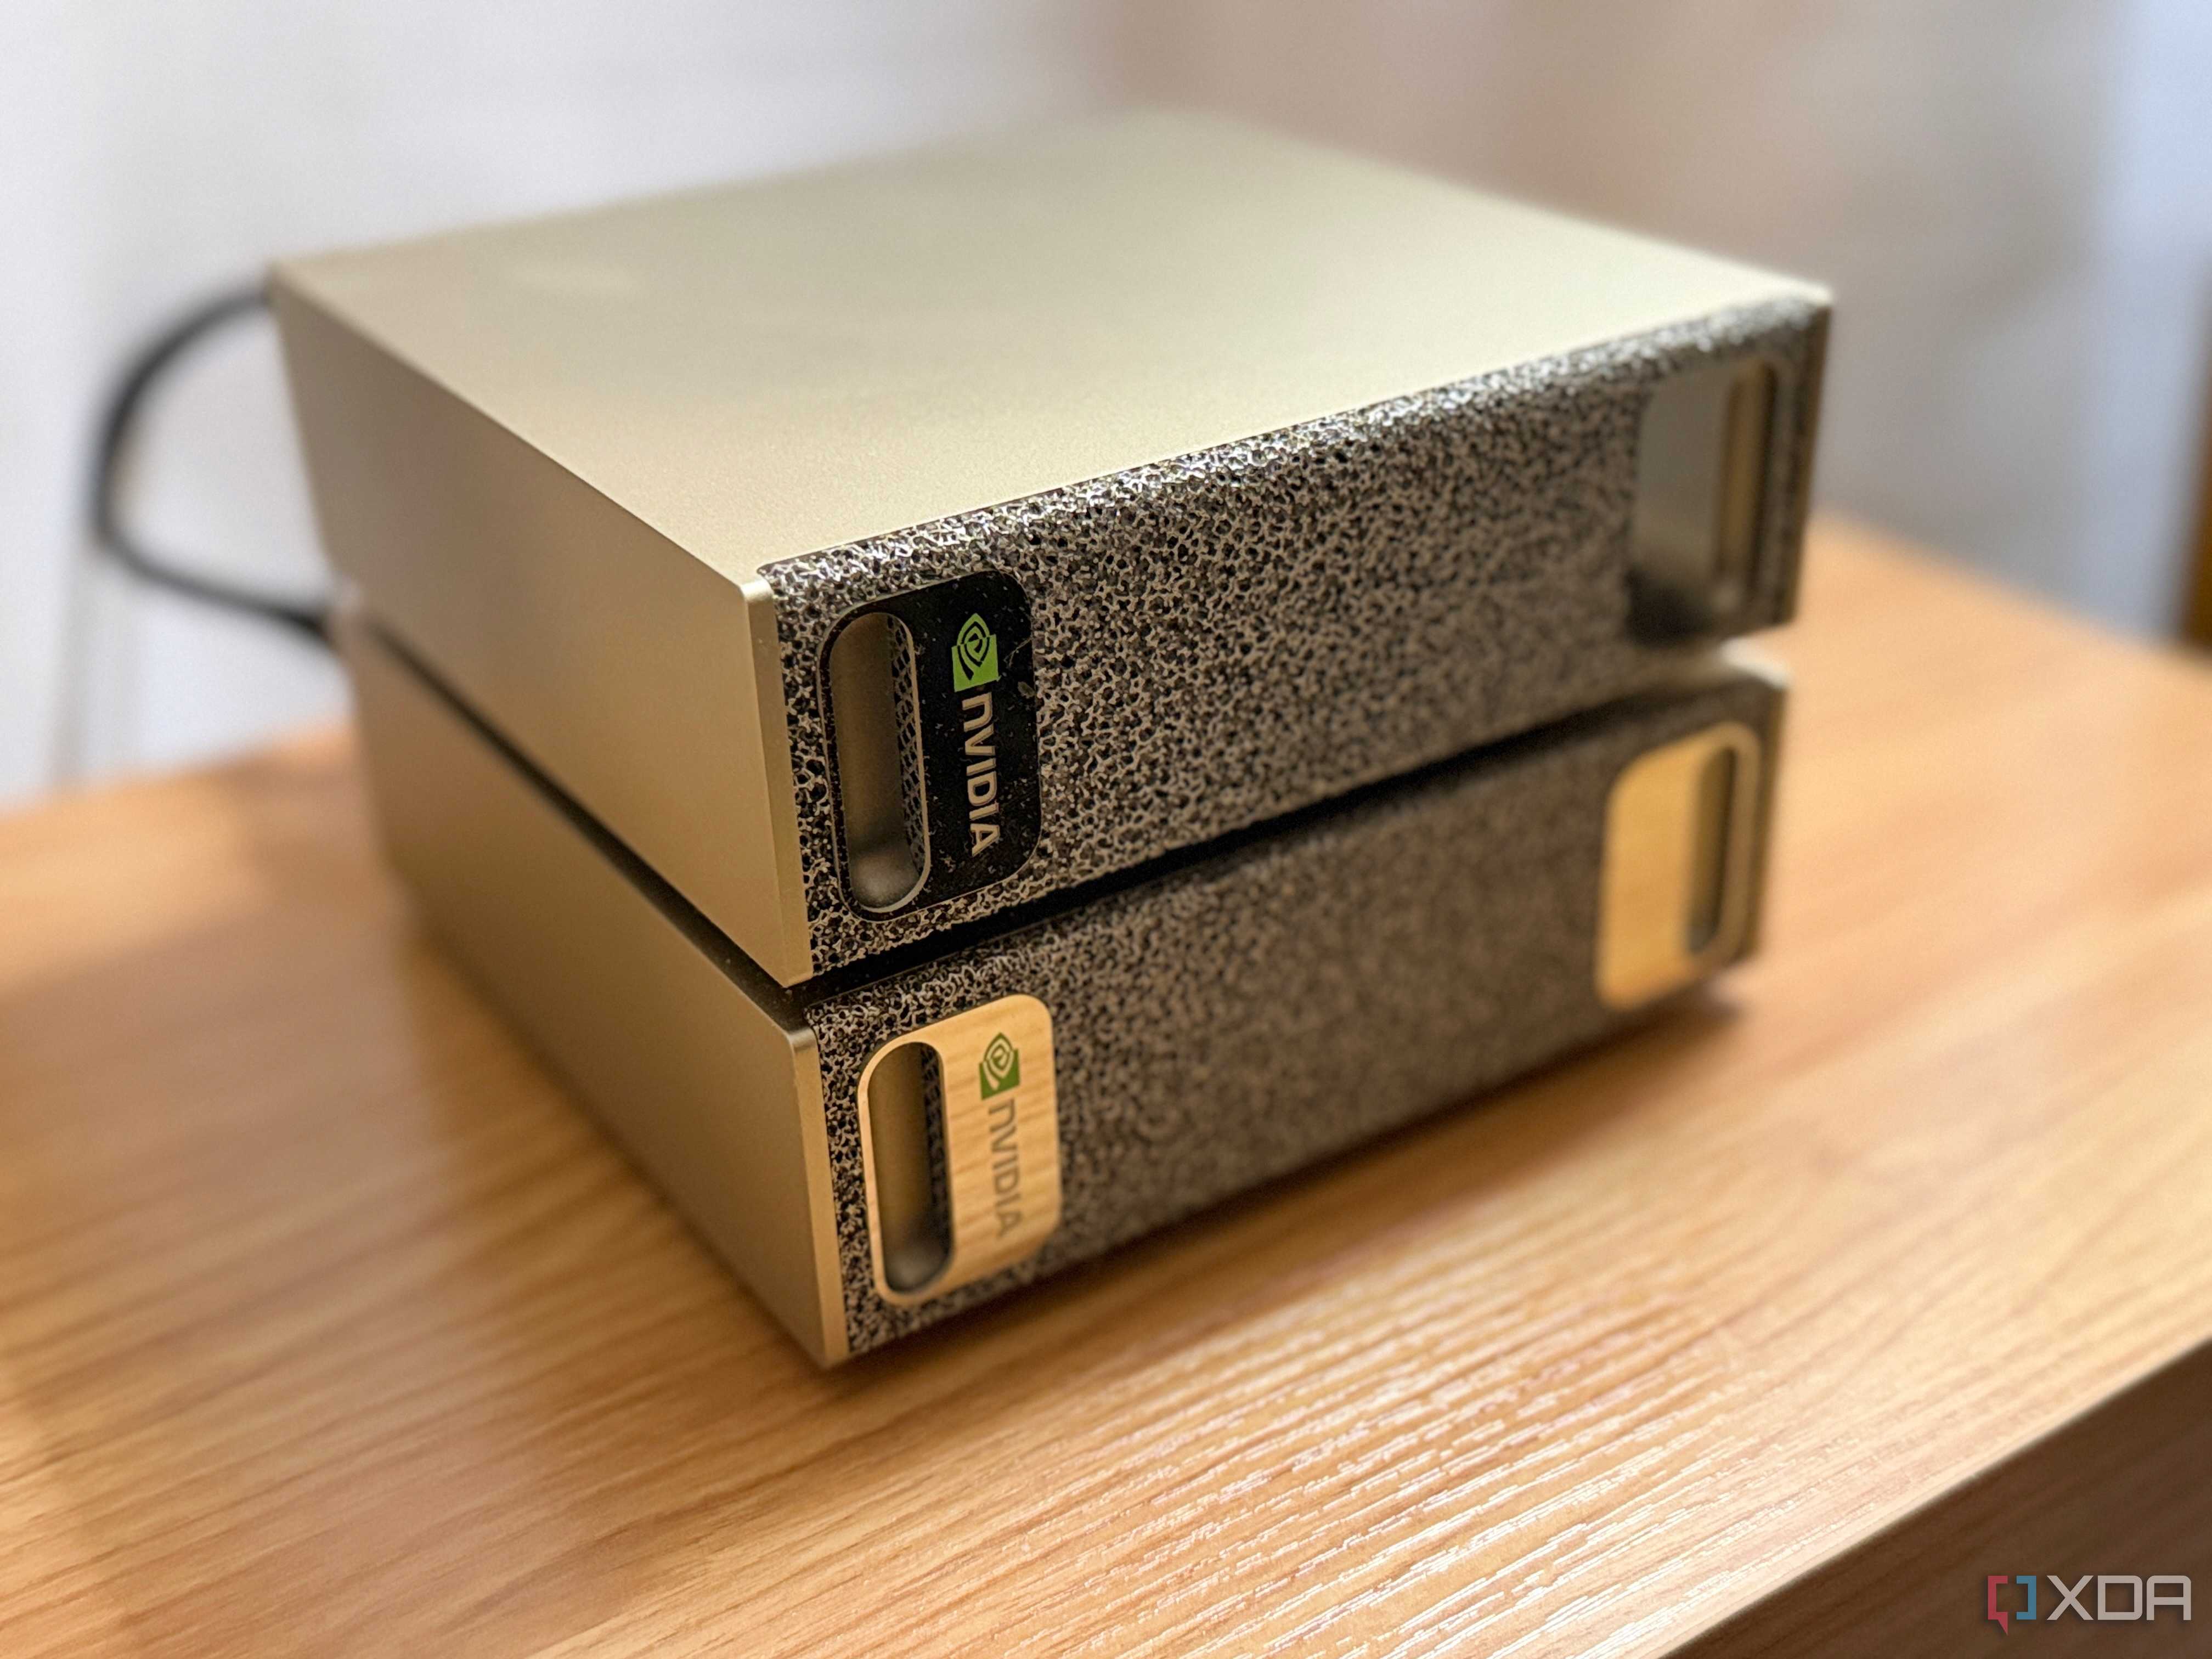
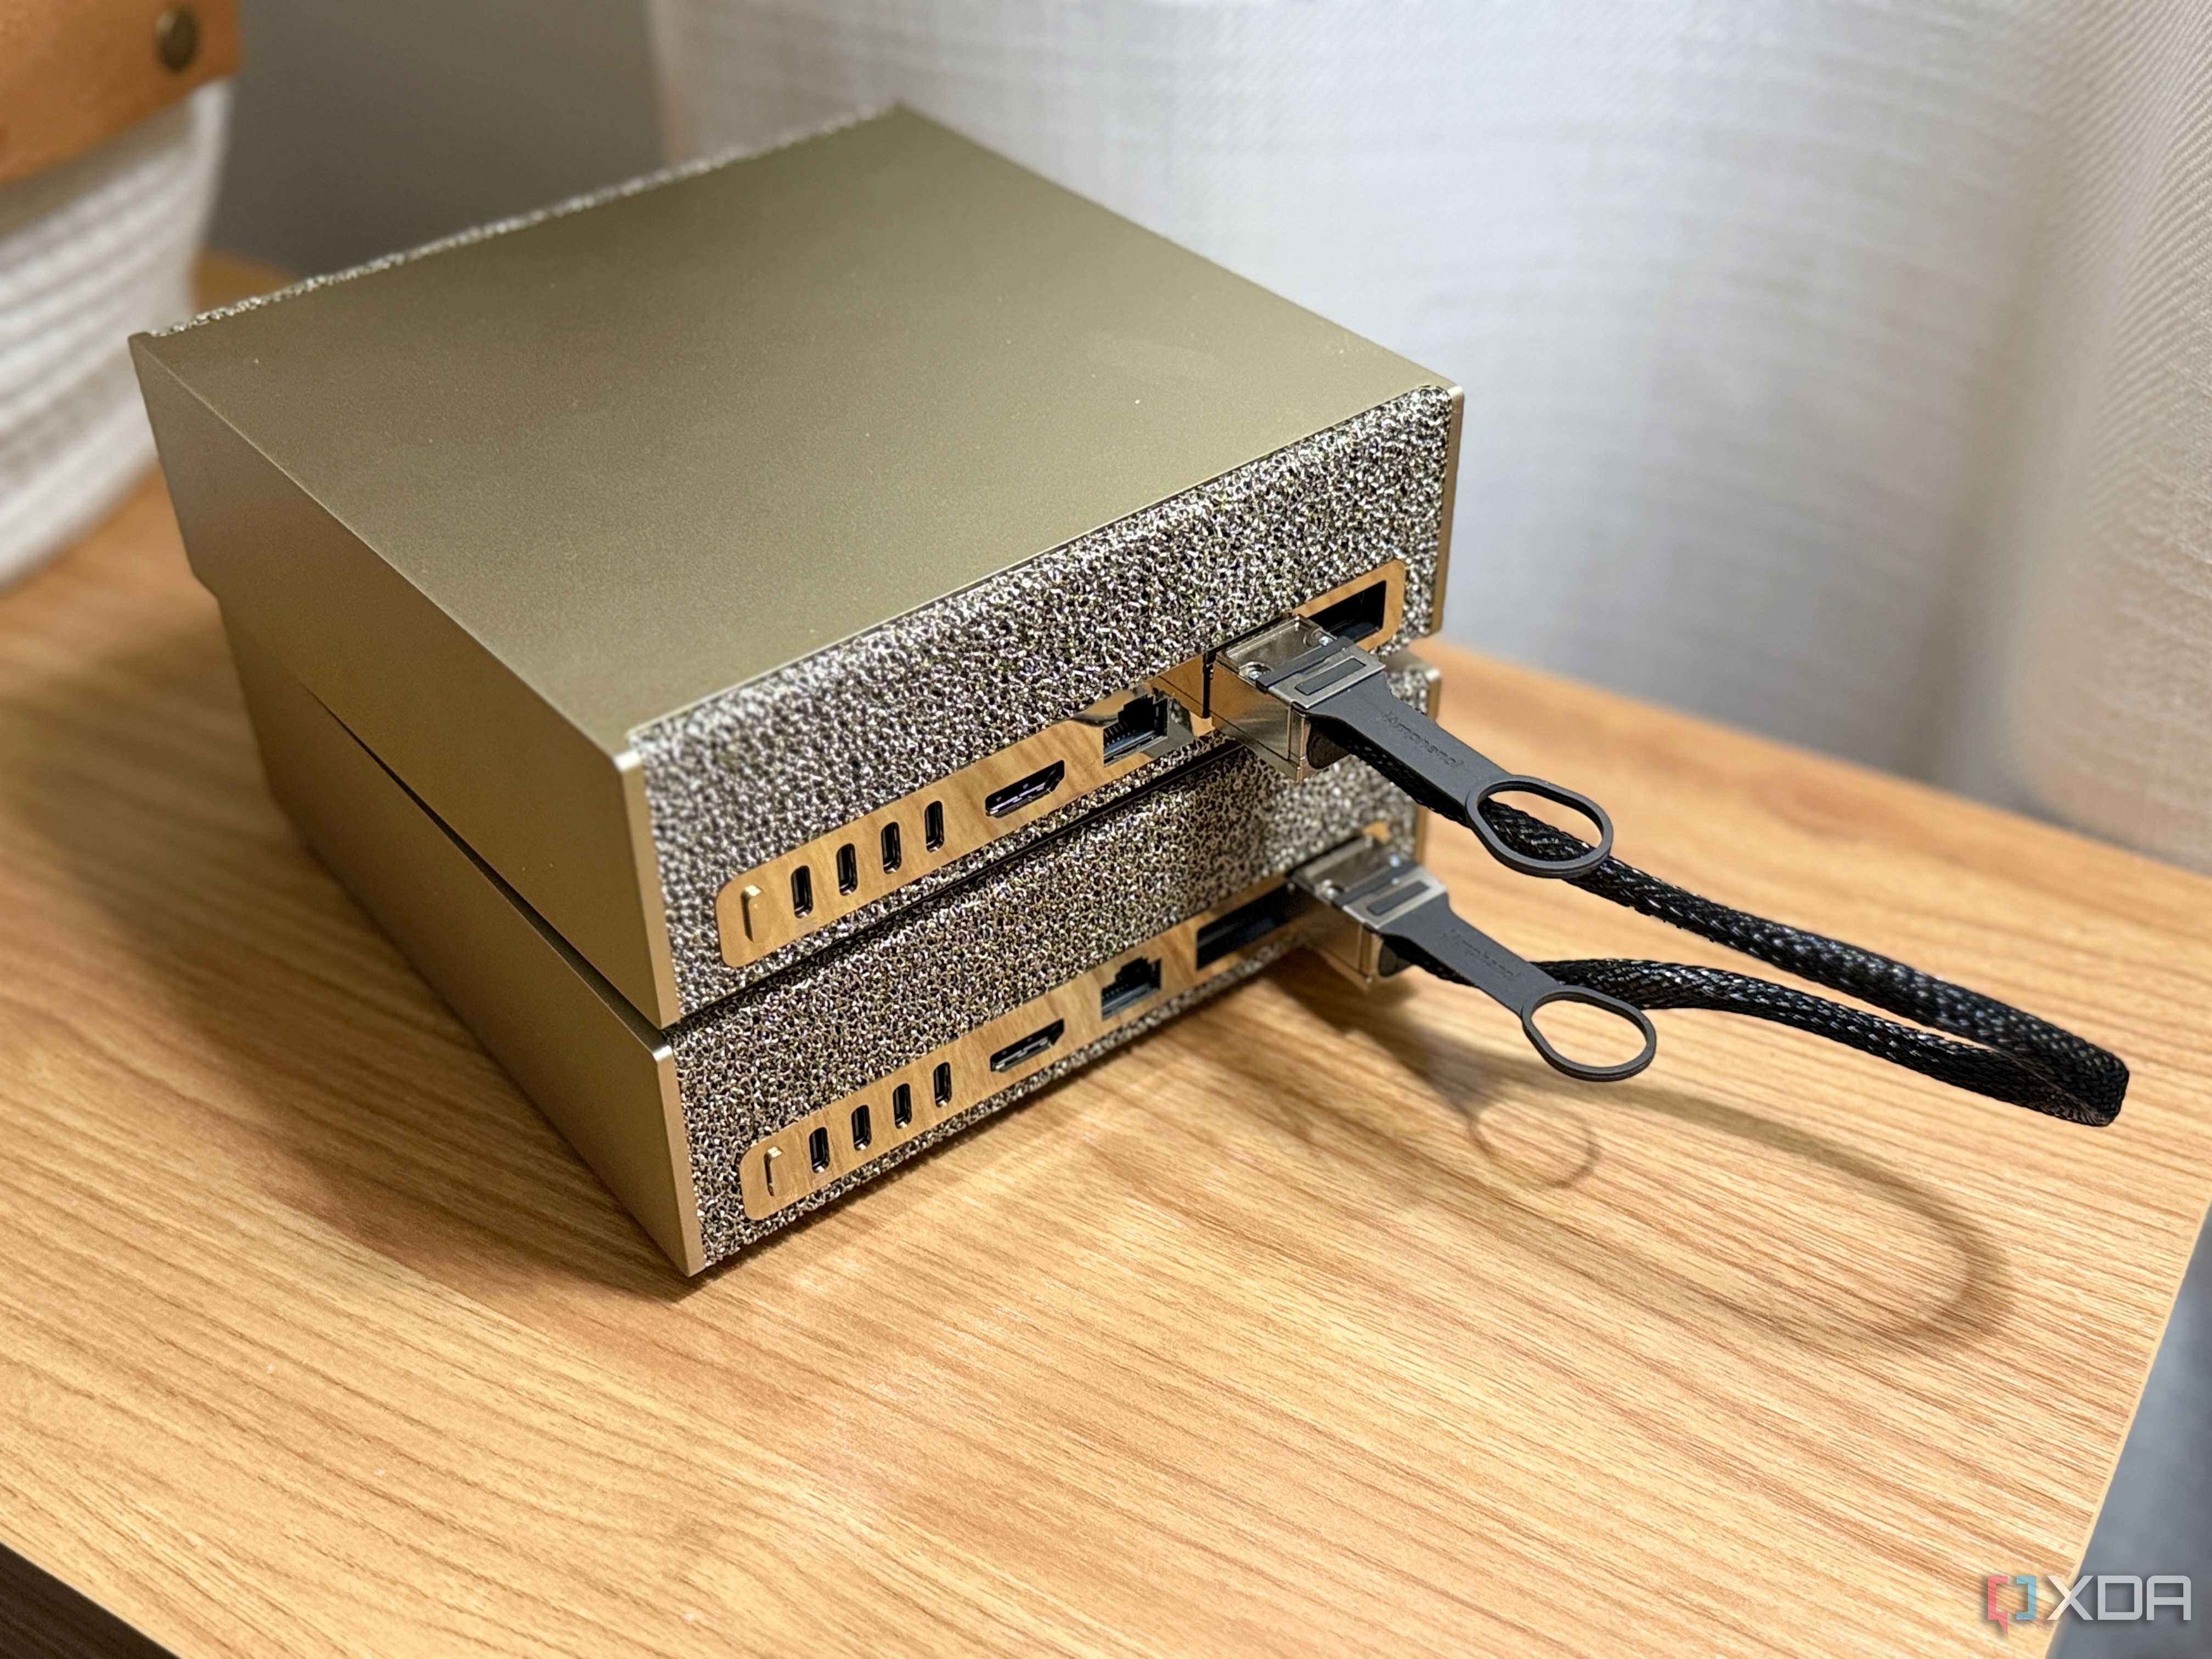
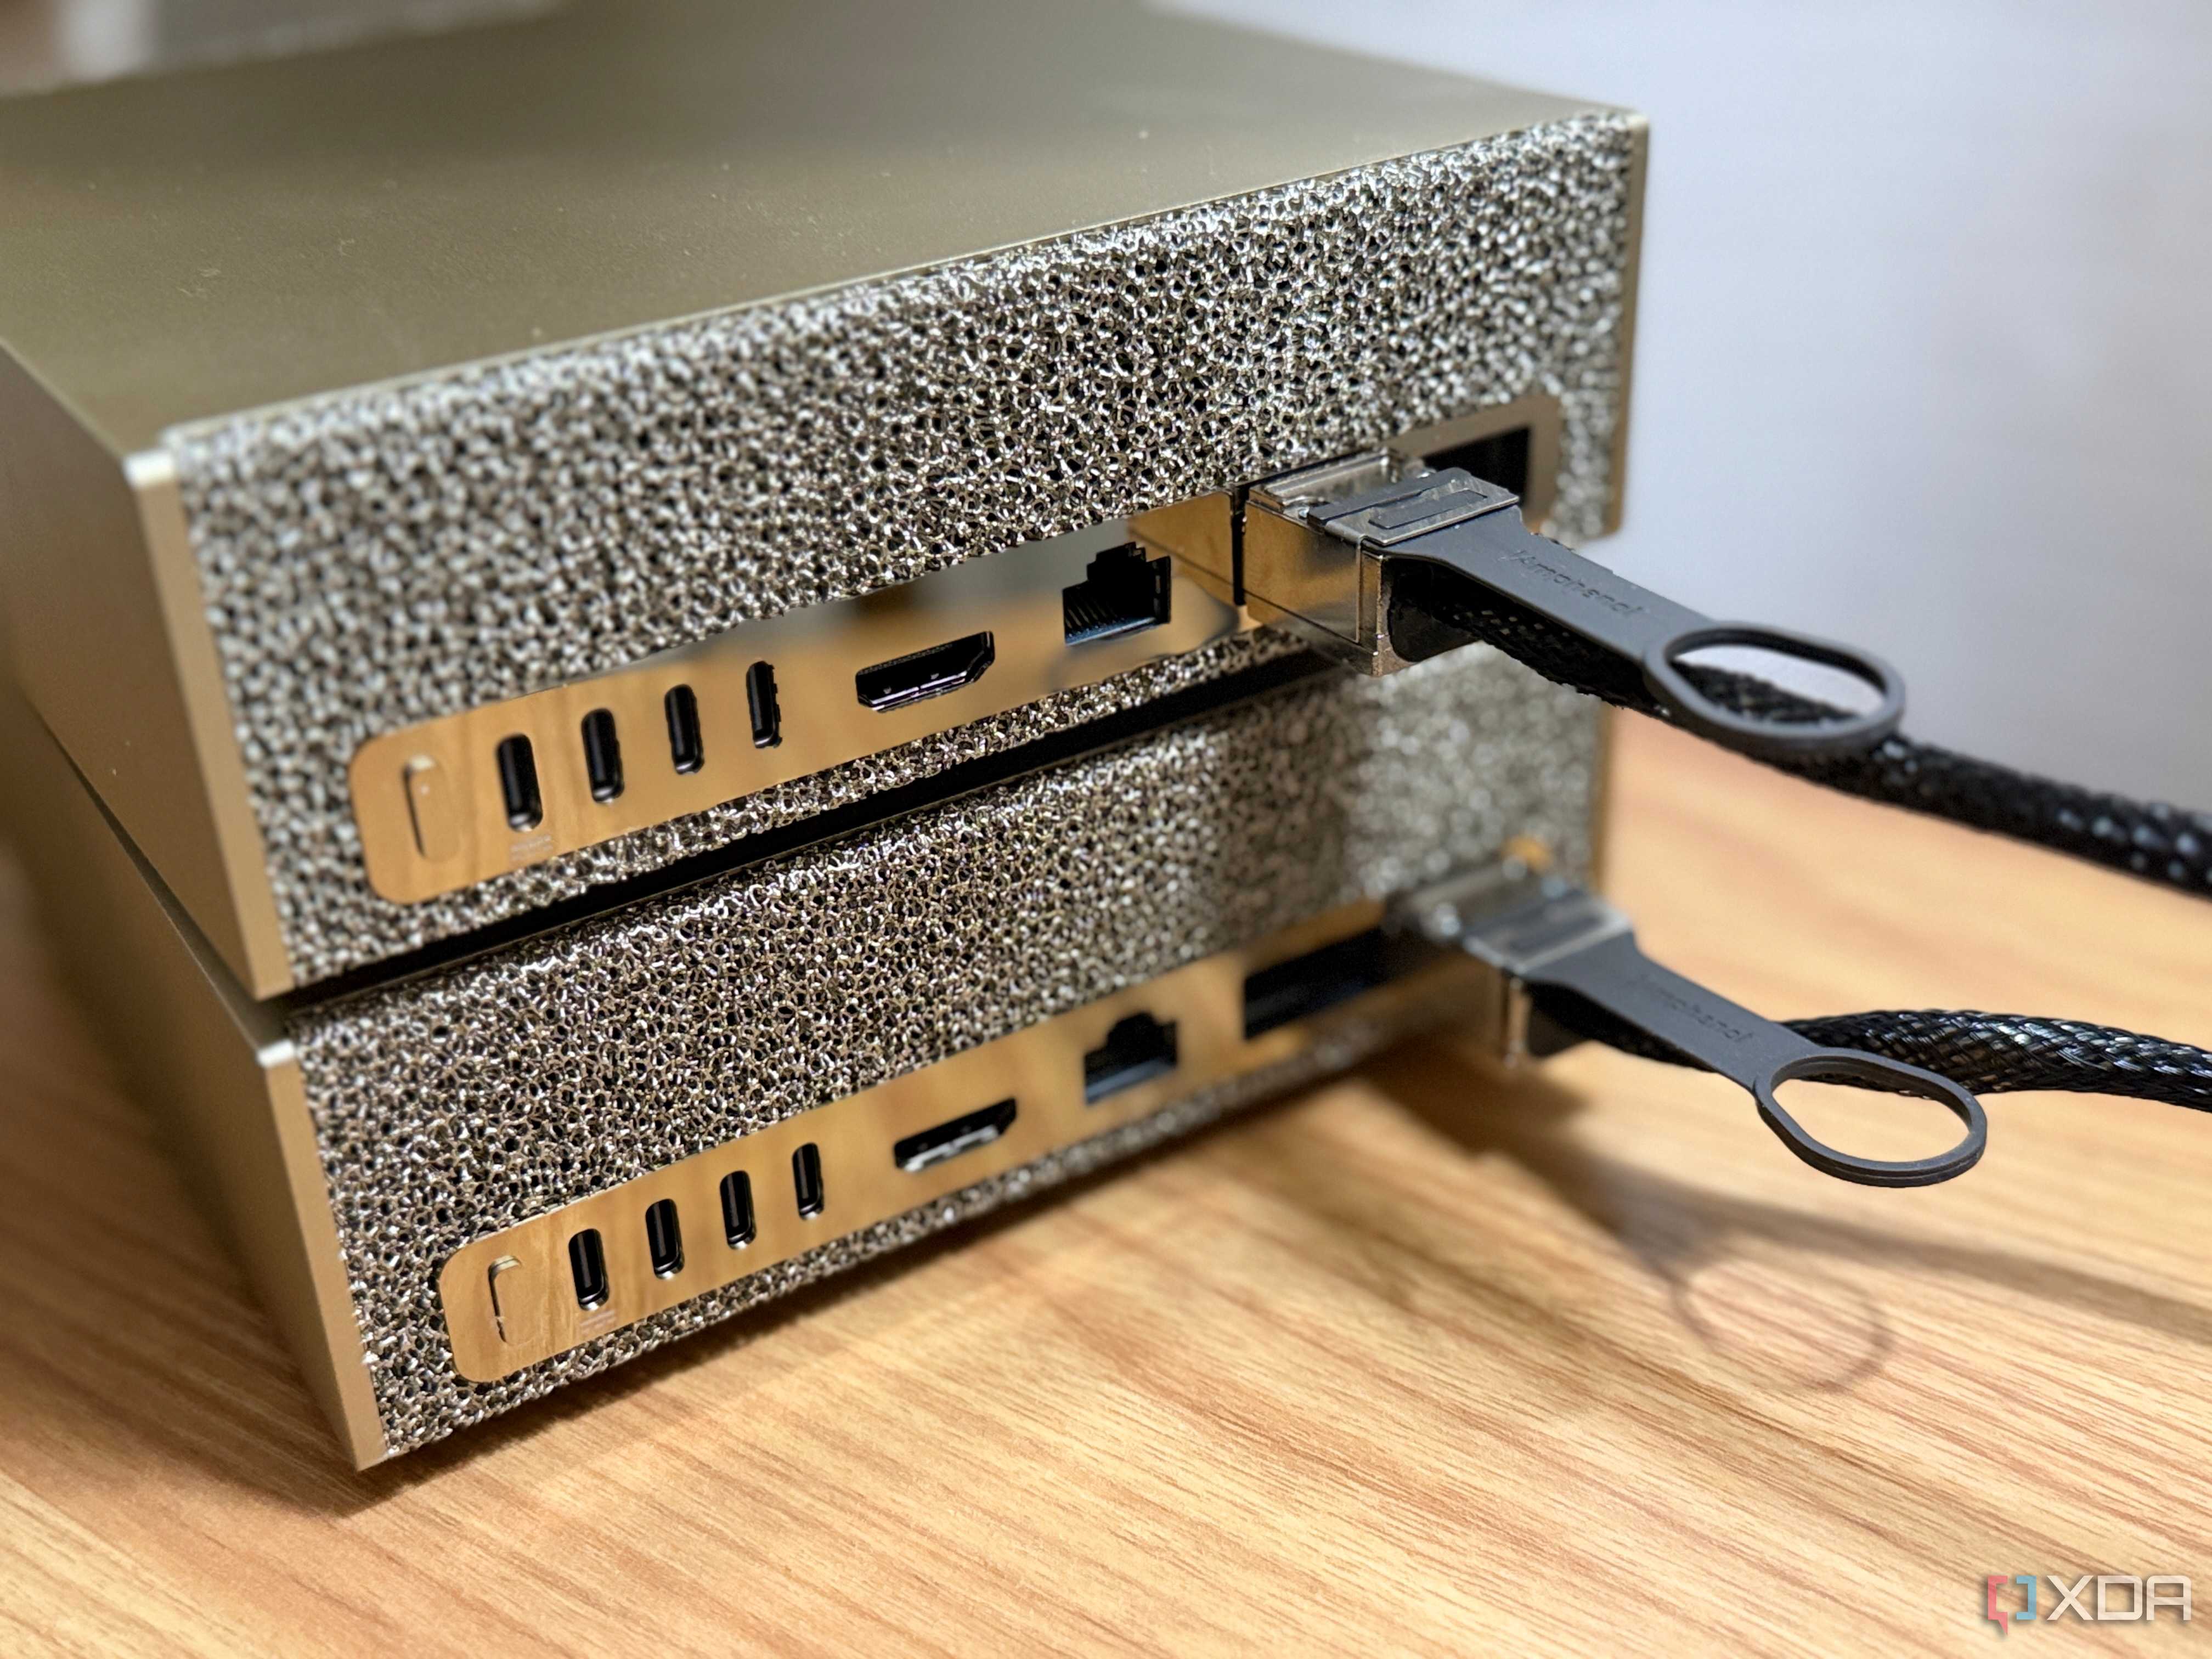
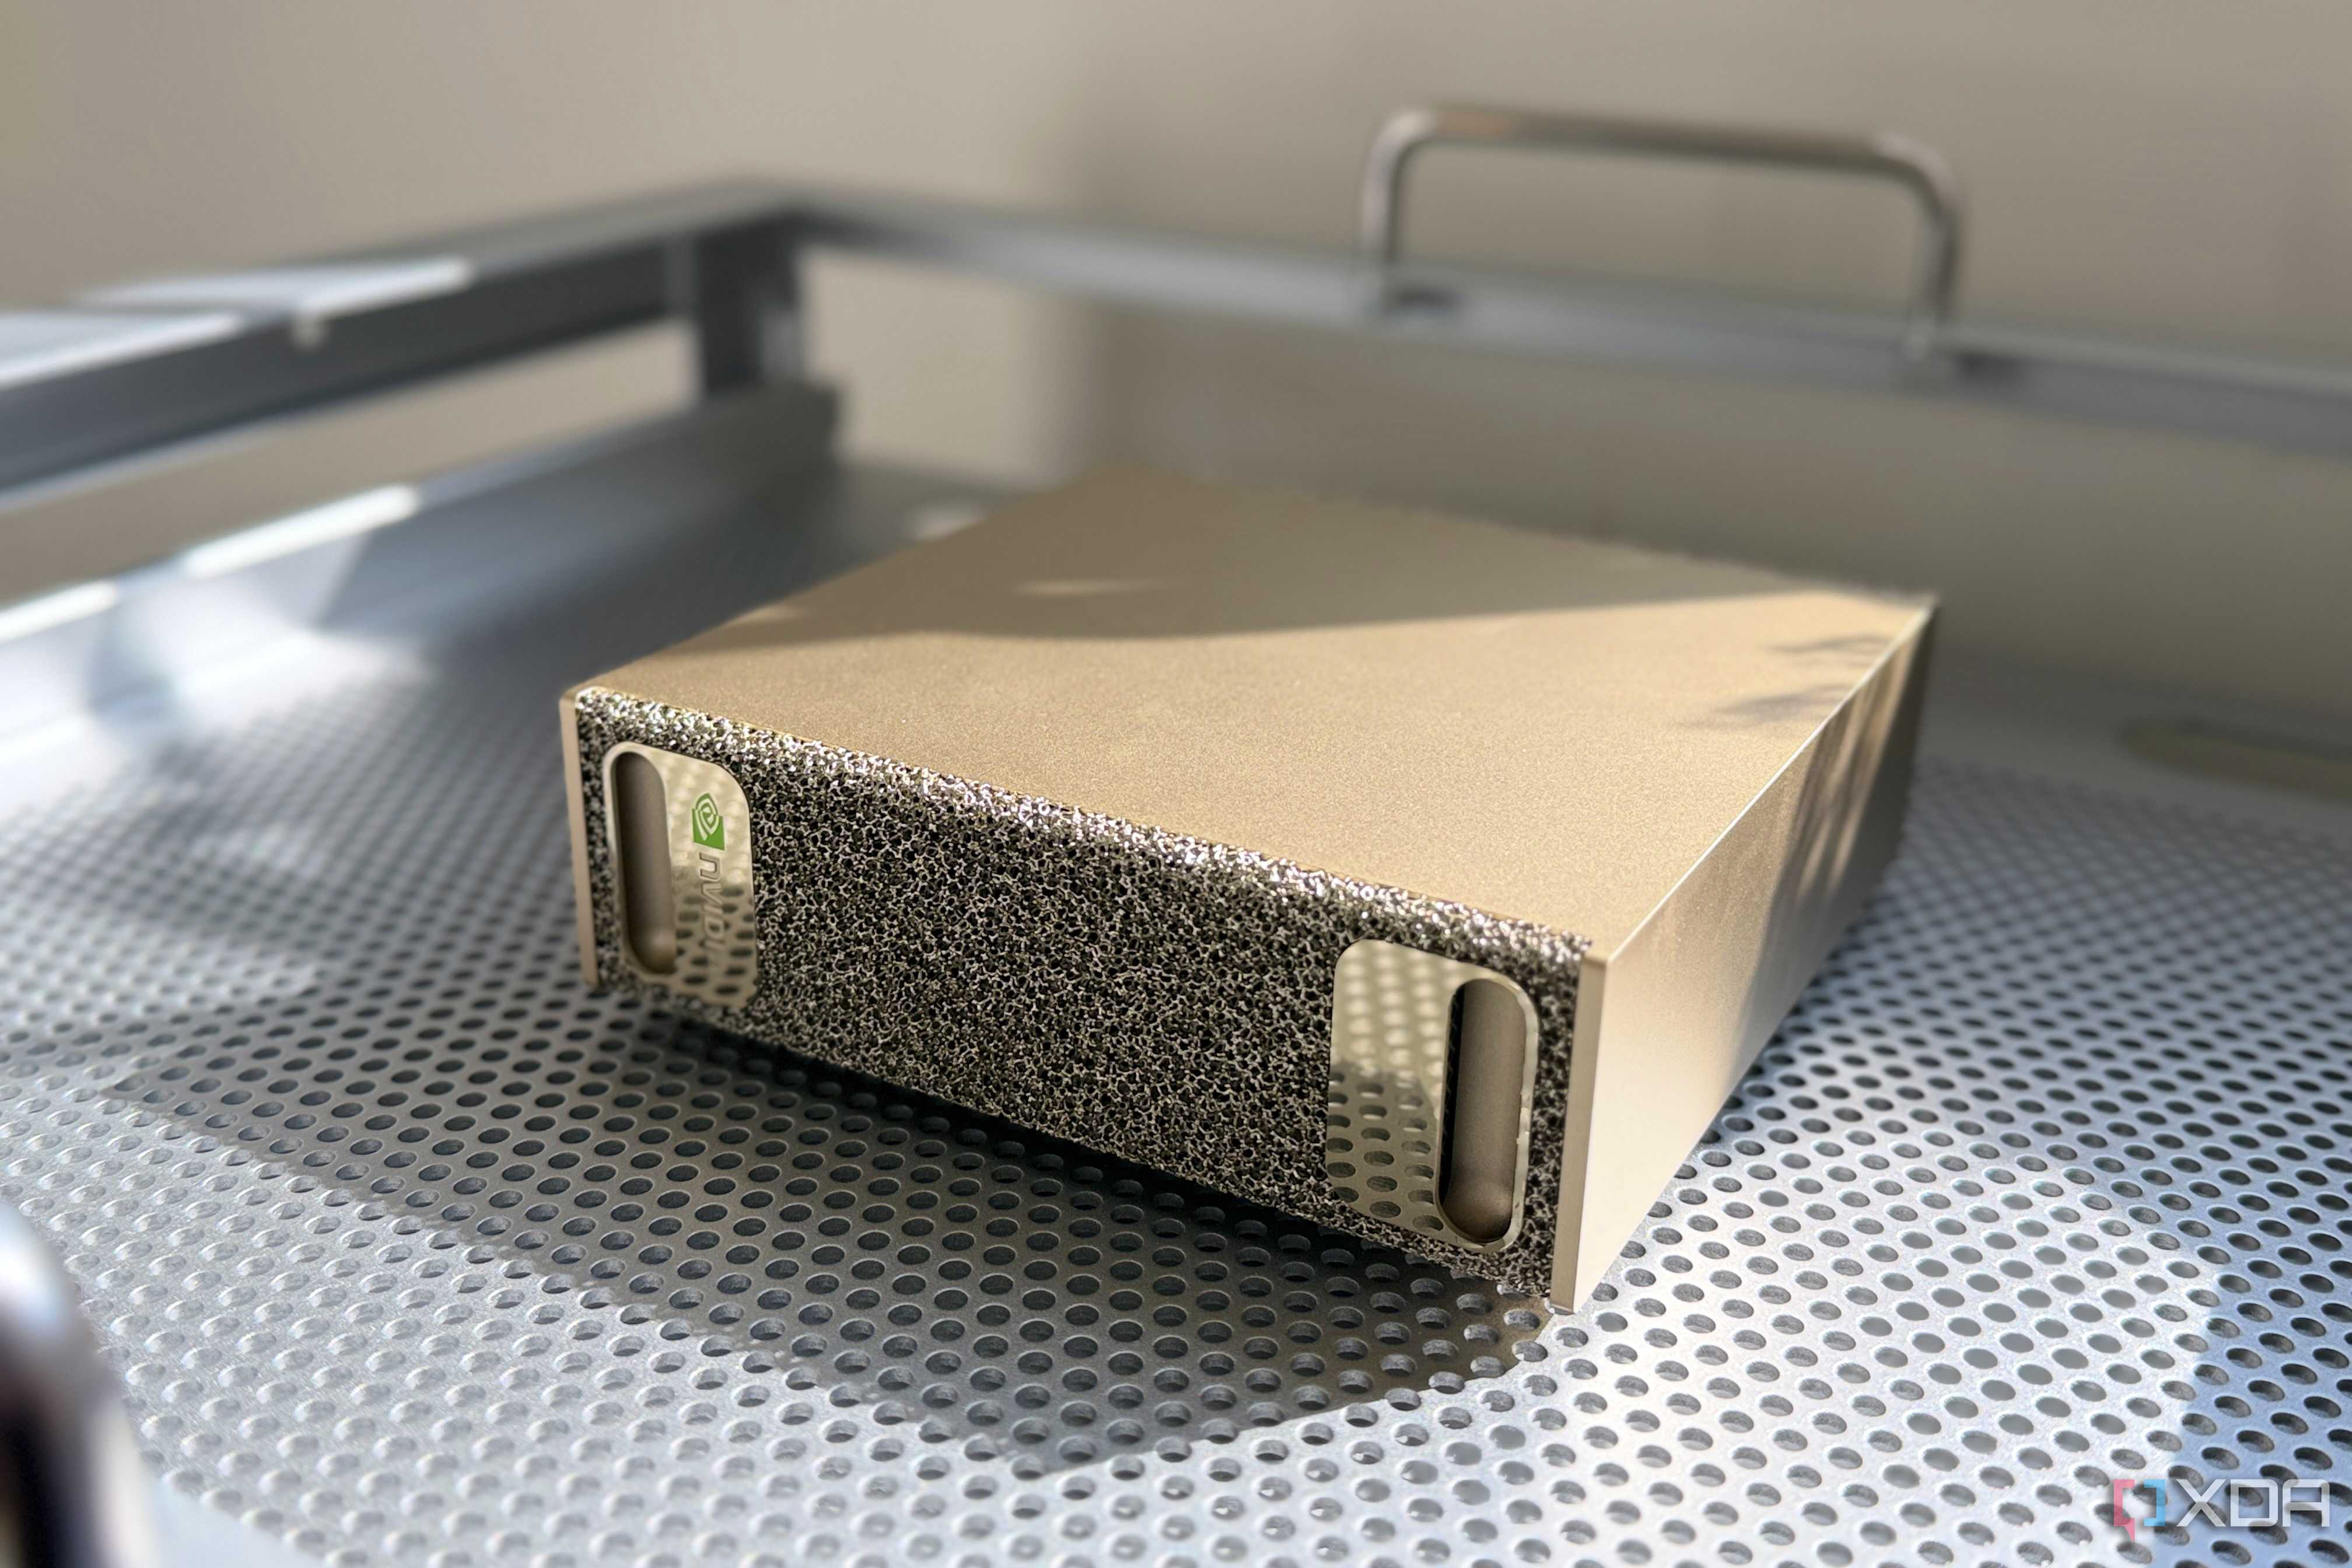
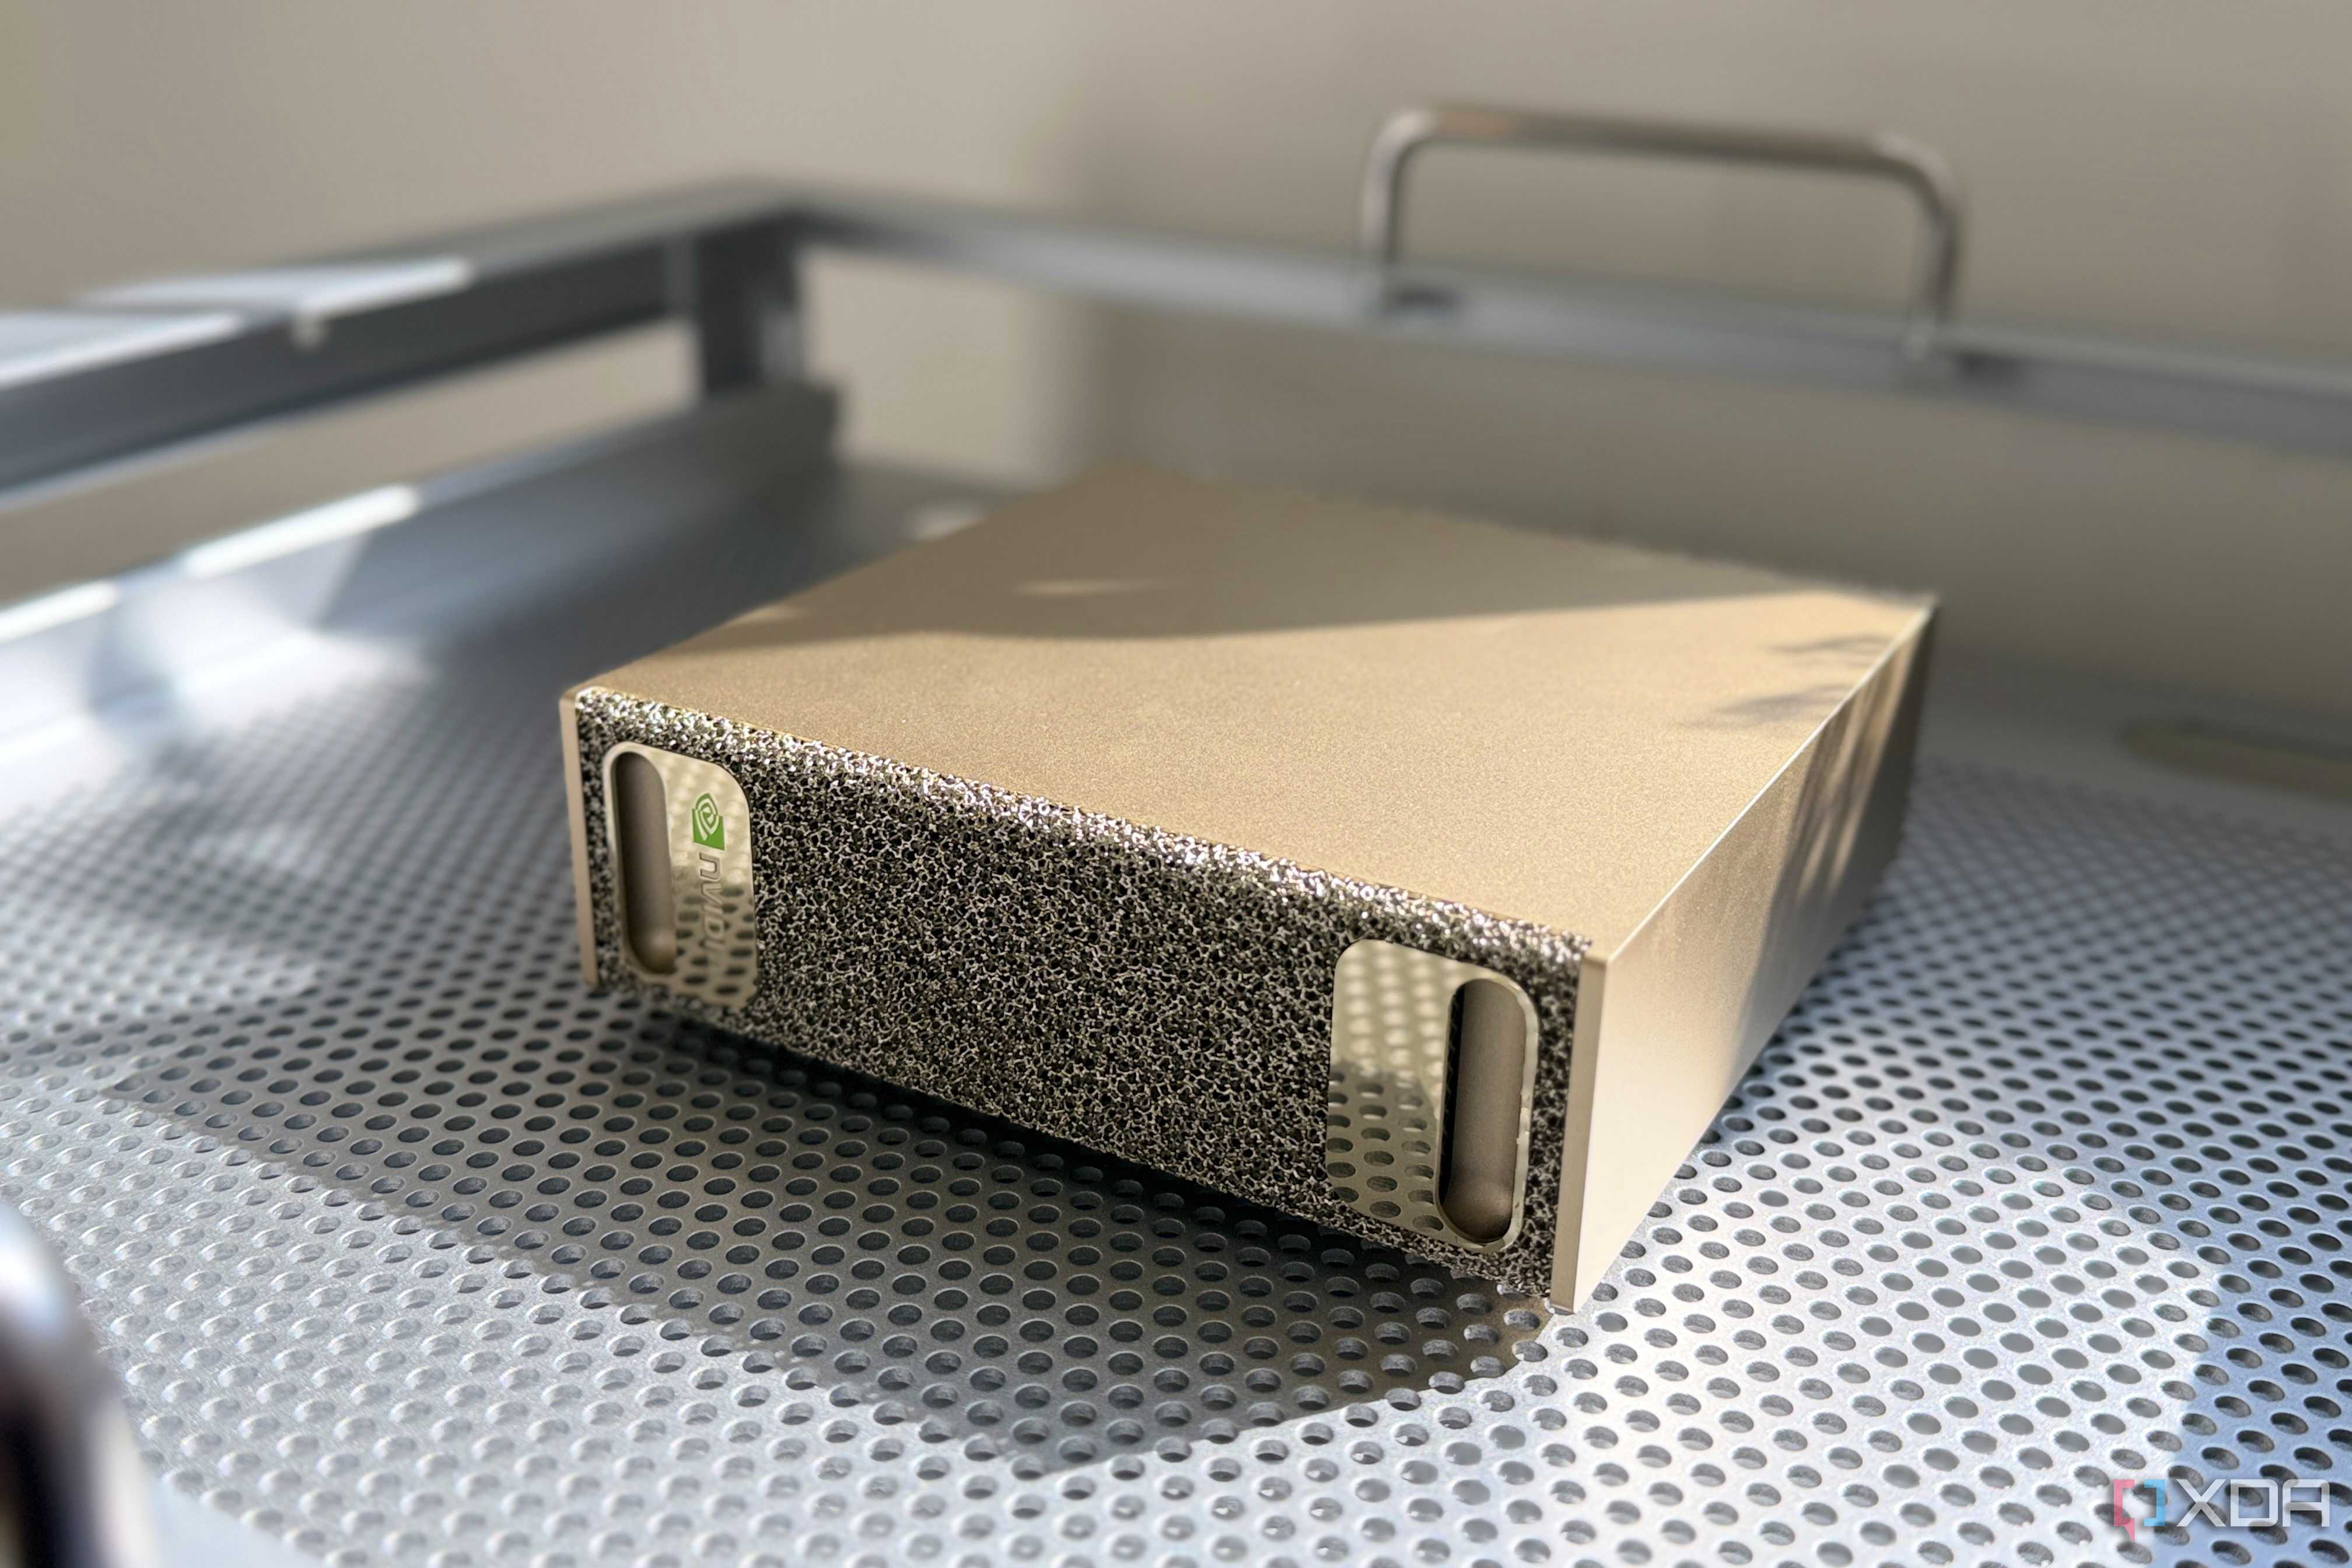
For the main run, I paired two Sparks and stepped up to a 24-layer model with 1.38 billion parameters. This time it used FlashAttention 2, so the fallback was gone, plus FP8 precision through Nvidia's Transformer Engine. Over about 151 hours, it chewed through 133,633 updates and 8.76 billion tokens.
Splitting training across two machines adds a job a single Spark never has to do. Each update covers 65,536 tokens, and after each one, the two Sparks have to swap notes before either can continue. That happened 133,633 times. Neither machine gets to move on until both are done.
Think of it like two people carrying a couch up the stairs. You can only climb as fast as the slower person, and if one of you stops to catch your breath, the other just stands there holding their end. Plus, you'll be eternally tempted to shout "Pivot!" at each other. When both machines are evenly matched, the handoff itself is cheap. When they aren't, the faster one burns its time waiting, and that's exactly what I found later.
Test before you start a long run
Before committing to a week of that, I tested recipes, and the results weren't what I'd bet on. Four-bit NVFP4 used about 7% less memory than FP8 and ran about 7% slower per step, so fewer bits bought me nothing. The real surprise was nanochat's own FP8 code. In the same short test window on the same pair, it took 20.6% less time per update than Transformer Engine's FP8 and used far less memory.
|
FP8 recipe, two Sparks (updates 5 to 20) |
Seconds per update |
Peak memory per Spark |
|---|---|---|
|
Transformer Engine FP8 |
3.967 |
73.3 GiB |
|
Nanochat native FP8 |
3.149 |
51.9 GiB |
So why did the six-day run use the slower path? Transformer Engine was the newer route, and CUDA tooling moves so fast that I wanted to use the up-to-date method rather than one that might get left behind. Newer didn't mean faster, at least not yet, and I didn't stop to profile the gap before launching. The native test only ran 20 steps, so I can't say how many hours it would have saved over the full run, but I know which one I'm starting with next time. A repeat on the healthy pair this week landed on almost exactly the same gap: 20.5%.
After the base run finished, I looked for the memory bottleneck I was sure existed. I ruled out capacity fast, because neither Spark dropped below 32 GiB free across the whole run. The profiler found something much stranger: one Spark's GPU ran at around 600 MHz while its twin sat near 2,190 MHz. The fast one spent about 3.3 seconds of every 7.2-second update doing nothing but waiting for its partner.
To be clear, this didn't hold back the six-day run. That run averaged about 4.07 seconds per update, right in line with my earlier tests, so the throttling showed up afterwards. It looks a lot like a problem other owners have reported: the USB-C power-delivery controller in the power brick gets stuck and pins the GPU near 611 MHz with no throttle flags, and the community fix is to unplug the brick from the wall.
A normal reboot didn't clear it, but after a cold drain of both Sparks, One was back at around 2,190 MHz under load, and the same test dropped from 7.2 to 3.9 seconds per update, with the waiting all but gone. That points the same way, but the Spark's quirks deserve their own write-up.
It's still a perfect demonstration of how a two-machine setup fails, because the pair only ever moves at the speed of its slowest member. And the bandwidth question? Still open, since the GB10's available counters don't report it, even to a profiler.
Two Sparks are only as fast as the slower one
Going in, I thought GPU compute would set the pace, but it didn't. On one Spark, the software path decided how much of the chip got used. A second Spark didn't add so much compute as a second thing that could go wrong, because the pair only ever moves at the speed of the slower machine. When both are healthy, keeping them in step costs very little, but one misbehaving Spark was enough to leave its twin waiting for almost half of every update. The GPU was never the problem. Everything around it was.
If you're planning a run like this, read the startup warnings and fix the attention path before you start, check clocks and drivers on every node, and watch power draw and model FLOPs utilization rather than the utilization graph. Then pilot the full recipe for a few dozen steps before you commit a week of machine time, because a 20-step test told me more than six days of waiting did. If you're new to this, the things worth knowing before you start self-hosting LLMs are a gentler place to begin, but I'd sign up for round two in a heartbeat, ideally with two Sparks running at the same speed.

Nvidia DGX Spark
The DGX Spark is a tiny AI powerhouse, featuring the Grace Superchip and Blackwell GPU cores, with 128GB of unified memory.