Meta started a ground-up overhaul of its AI efforts 14 months ago, and the first result was Muse Spark, which the company used to lay out its approach to "predictable, rigorous scaling". Now, Meta has taken what it calls "the next step" on its "scaling ladder" with the Muse Wonder series, made up of Muse Wonder and Muse Wonder Full.
Meta says these are its most capable models, delivering "state-of-the-art performance on personal and professional agentic tasks". They were trained at the company's gigawatt-scale Prometheus data center, and they accept text, image, video, and audio as input (output is text only), and support a context length of 1 million tokens.
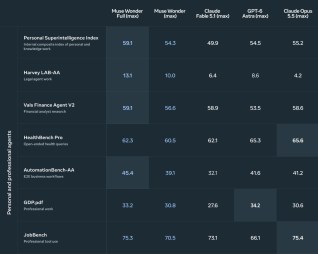
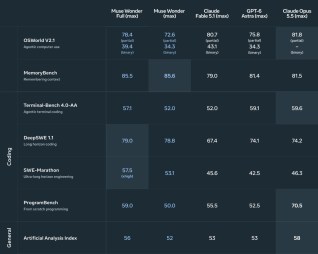
Meta Muse Wonder benchmark comparison with its leading competitors
The headline features are Active Memory and Active Focus. The former carries important context about you across conversations and retrieves the details relevant to the task at hand. The latter describes how the model keeps working toward a difficult goal - trying alternative approaches, working through blockers, and checking in with you before taking important actions. Meta also highlights domain expertise in law, finance, and health, as well as "frontier coding" performance for projects ranging from small apps to complex software.
Muse Wonder is available starting today through the Meta Model API and Muse Code, while Muse Wonder Full is limited to Muse Code subscribers. Muse Wonder will also soon power the Muse agent, rolling out to subscribers first, and Meta plans on using it to develop specialized models that it can bring to everyone using Muse.
Unsurprisingly, Meta frames all of this as "a major leap toward personal superintelligence". The company also calls Muse Wonder its "most aligned model to date", and says a full report with additional safety evaluations will be available soon.