I am a writer and a pre-seed VC investor in France. I am also one of the people behind “Balance ton Claude,” an anonymous X account that, on September 21, published evidence that C’était ça ou mourir, the breakout novel of France’s literary season, had been largely generated by AI.
The book, by the Haitian-Canadian author Thélyson Orélien, had just won several prizes, was the favorite to win the Goncourt (France’s most prestigious literary prize) and was being translated into twenty languages. We ran it through Pangram v.4 (by far the most reliable AI detector, with false positive rates in the order of 0.0041%). Every page came back at or near 100% AI. In the following days, the author was found to have plagiarized much of his literary production before the advent of LLMs (and admitted as much). Furthermore, readers who are used to working with AI quickly identified, throughout the book, the obvious LLM writing habits. In light of the overwhelming evidence, the Académie Goncourt removed the book from its longlist.
Following the disclosure of my name in French media, part of the left (even its fringes usually most opposed to AI) decided to defend the author on the account that he is black and I am a columnist for Le Figaro, a center-right newspaper. My motivations were decried as racist, and several international media outlets amplified this accusation, citing as evidence the fact… that I wrote a book against wokeness a few years ago. I find this counter-accusation unfortunate because it is complete nonsense, but also because it has displaced the debate about AI in writing that we should be having.
Here is why we made the revelation. I have been writing, for several months, about my fear that LLMs could end the civilizational era that was based on reading and writing. A reader of my work came to me with his doubts about Orélien’s novel. We chose to reveal the truth. Actually, we have no problem with people using AI to create content—I, for one, am generally tech-positive and have written at length about my fascination with AI—but because readers care about whether words in a book were chosen by a human or by a machine, it is dishonest to lie to them.
This, I believe, is the necessary conversation. What matters here isn’t Orélien’s race or nationality, or my political views (or the political views that are sometimes attributed to me). The issue is far more universal than that. It’s about whether we are willing to have our literary and public discourse overwhelmed by AI writing—and whether we really will deprive ourselves of the discernment to tell the difference. Since I am not opposed to AI by itself, my argument here may appear a little subtle, but I do believe that there is a line to draw, and that the line has intellectual coherence to it—and, certainly, the “Balance ton Claude” collective and I have been willing to enforce that line. What matters here is that LLMs pose an existential threat to literature.
As the scandal has shown, AI can already produce writing not only good enough to pass the Turing test, but to win national literary prizes. Models will keep improving, their writing ticks will fade, and they will increasingly one-shot content indistinguishable in form and substance from the work of the most talented human authors. Pangram could unfortunately become fallible (it already generates some false negatives, and many are fine-tuning open-source models so as to make its writing undetectable to Pangram). Furthermore, people who pride themselves on always spotting LLM prose probably exhibit a misplaced confidence: they don’t account for the progress to come, and they never notice the times they are fooled. As Benjamin Todd from “80,000 Hours” put it on X: “Plastic surgery is most noticeable when it’s bad, so it’s more widespread and successful than it looks. Same with AI writing.”
So, what will happen? LLM-written text will make up a growing share of what appears on social media, in academic journals, and in bookshops. If even 0.001% of AI output is good enough to pass as good human content, this will represent a massive volume because AI-writing can be produced in a few seconds, at almost no cost, without limit. The logic of that is it will eventually crowd out human content. An ever-smaller share of human attention will go towards human-written text. Human writers will be discouraged, and many will stop writing. Why spend weeks on an essay that will be suspected of being AI-generated anyway, that may be no better than what a model could produce in a few seconds, and that will struggle to find readers?
There will always be some demand for human content, but if readers cannot tell human and AI content apart, that demand will not be able to be expressed. The supply (texts whose words were chosen by a human) therefore won’t be produced.
The Market for Lemons
There is a strong parallel here with the situation described in George Akerlof’s famous 1970 paper, “The Market for Lemons.” Imagine a market for used cars. Most cars are good, worth say $10,000. They trade at that price; both buyers and sellers are happy. One day, the owners of bad cars (“lemons,” worth close to nothing), find a way to make them indistinguishable, to the buyer, from good cars. They start selling. Word spreads that some lemons are masquerading as good cars. Buyers now ask to be compensated for the risk of getting a lemon and price every car at the expected value of a random car on the market, say $8,000. But at that price, some owners of good cars (who know what they hold) refuse to sell and withdraw from the market. The average quality of cars on sale falls. Buyers observe this and revise their offers down again, say to $6,000, to reflect the new expected value of a car. More good cars withdraw. The spiral continues until the market unravels: only lemons are left, and nobody buys.
Now consider the marketplace for texts on social media. The currency in which readers pay is attention (which, like money, is a finite resource). Before LLMs, the probability that a given block of text was a good car (a text whose words a human had chosen) was 100%. The reader applied no discount in the attention allocated to the block of text. One day, LLMs appear. The probability drops slightly, say to 80%. Facing the same block of text as before, the reader becomes slightly less likely to read. Some writers, losing audience, stop expending effort to write. The share of human text falls to 70%. The reader applies a further discount in the attention allocated, disincentivizing more potential writers. The spiral continues—the same for writing as for used cars. (In this example, AI texts are lemons not because they are objectively of lower quality, but simply because some readers have a subjective preference against them.)
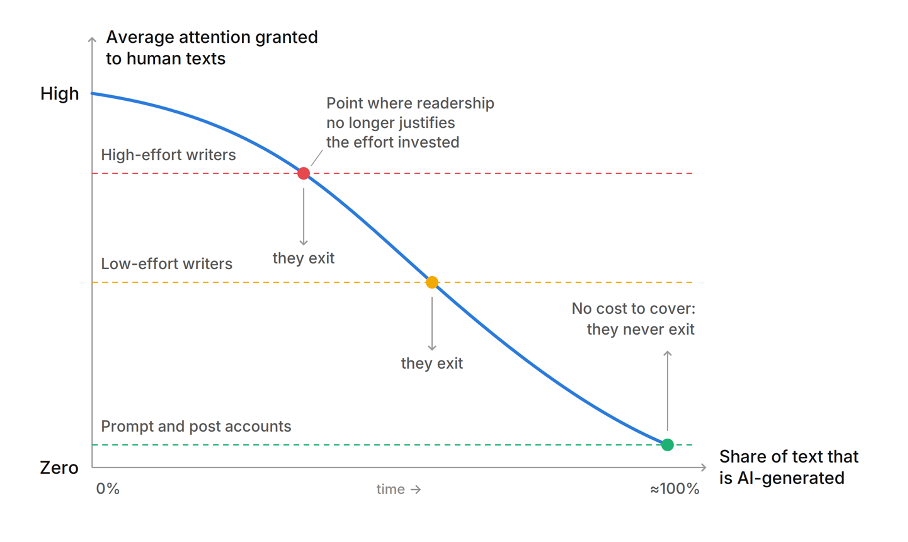
Note that the reader’s discount falls on every text, human or machine, but a reduced reward eliminates only human writers, because they alone have costs to cover. Each drop in attention pushes some human writers below their break-even point, while no drop in attention can push an AI copy-paster below theirs. So, the composition of the pool keeps worsening, with human writers exiting from the content producer pool first, followed by effortful prompters, and finally leaving only the cheapest producible text. (Those who defend AI writing would do well to recognize that the same dynamics affect the effortful prompters.) At some point the reader understands that the probability of facing human text is close to zero and stops allocating attention to text altogether: the chance that what is being read is ChatGPT prose is simply too high. Without readers, the remaining writers quit. The market unravels.
I’ve tried to put this dynamic in visual form with the following graph:
One source of stability in the market is writers with pre-AI reputations, who have proved they can write without LLMs. They will benefit from a presumption of authenticity, and their texts will not be discounted as much as the average text by readers (perhaps in the short-term, these writers will even benefit from an attention premium!). But unknown writers will face a massive suspicion of copy-pasting AI. Soon every aspiring author will think: “why spend weeks to do marginally better (perhaps worse) than an LLM, only to be suspected of having used one anyway, and to fail to reach an audience anyway?” When legacy authors have retired, few will write.
In places where that sort of earned reputation is absent by design, the unraveling is already visible. Geoffrey Litt, who did graduate work in human computer interaction at MIT, reports that he takes no more pleasure in reviewing anonymous academic submissions in the peer-review context: he always wonders whether he is reading a colleague’s thinking or Claude’s, and fears he is spending more time reading than the author spent writing. He predicts anonymous peer review in its current form will not survive AI. What has already happened to anonymous submissions will happen to every text by an author with no pre-existing reputation, meaning, eventually, to almost every text. One possible exception is that we may continue to read people whose standing comes from something other than writing: central bankers, politicians, CEOs, famous actors, etc, either because their public record makes them trustworthy or because their position makes their opinion worth knowing even if an LLM or ghostwriter chose the actual words. Note that this scenario implies that standing becomes a precondition for being read, and standing cannot be acquired by writing—and that (very-plausible) scenario serves as an answer to the oft-heard argument that “AI will democratize writing.” Here, in the long run, only the famous get read. The anonymous but talented young thinker has no chance.