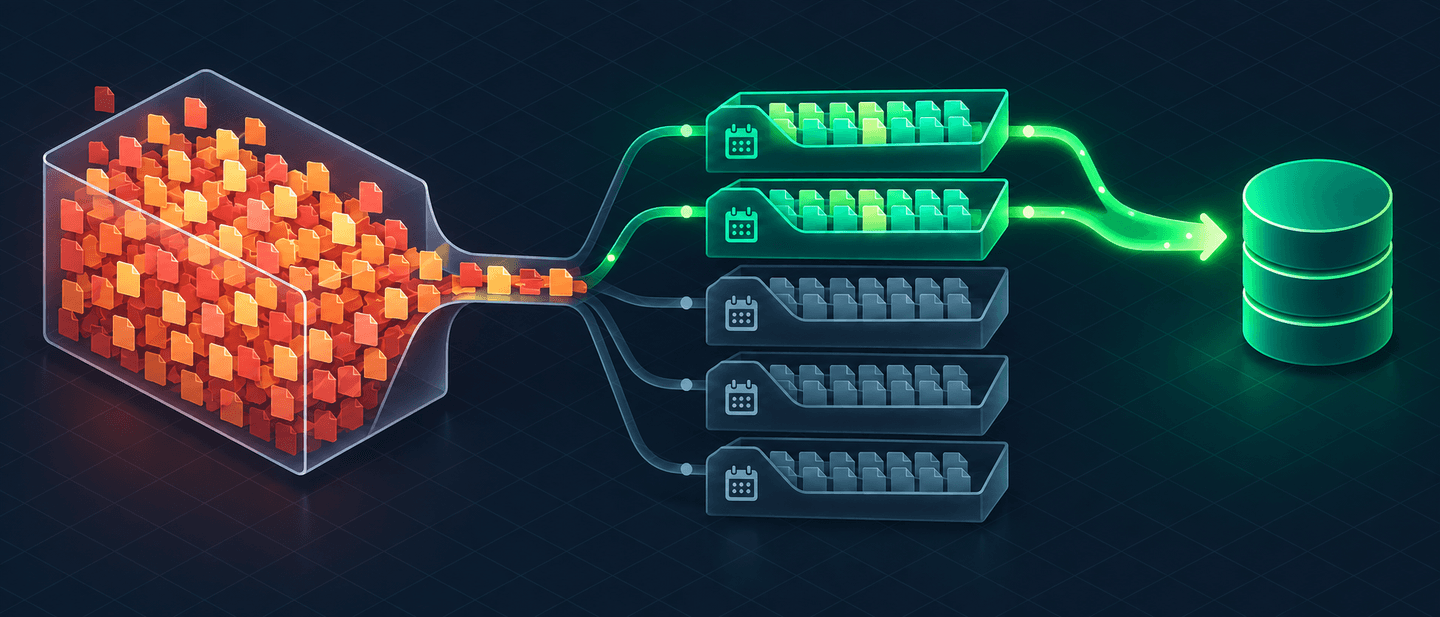
The ingestion jobs kept running out of memory. Adding compute bought us time, but the failures came back as the export history grew. Before a job could process the latest delivery records, it had to work through a growing inventory of old files.
I am a senior data engineer, and I owned the pipelines that brought message delivery data from a third-party marketing vendor into our warehouse. Those records supported campaign analysis and compliance investigations across email, SMS, and push notifications. When ingestion stalled, the teams using that data were left waiting.
The bottleneck crossed a company boundary. Our consumer was doing the work, but the export layout that made the work expensive was controlled by the vendor. I worked with the vendor's engineering team on date-partitioned delivery and prepared our consumer for the new layout while they built it.
The vendor is unnamed here; this account focuses on the engineering decisions in that integration. The lesson is useful wherever a vendor delivers files that another team must discover, ingest, and recover after failure.
The Expensive Part Was Finding the Files
The symptoms initially pointed toward our own infrastructure. Jobs that had finished in minutes began taking hours. Some exhausted memory. Retrying a failed run repeated much of the discovery work. Increasing compute capacity made the failures less frequent without addressing why the workload kept expanding.
Our integration discovered exports by listing objects under a shared, unpartitioned prefix. Historical exports and recent deliveries accumulated in the same namespace. To identify the files relevant to a run, the consumer had to enumerate a much broader set of objects and then filter them.
That distinction matters: listing object metadata is different from downloading and parsing every file. The discovery step alone can become expensive when the number of keys grows. An implementation that accumulates those keys in memory can also fail before it gets far into processing the actual events.
Pagination can bound the memory used by listing, provided the consumer processes each page without accumulating the full result. It does not eliminate the repeated enumeration of historical objects. I needed to reduce how much history a normal run had to consider.
The useful diagnostic question was simple: did ingestion cost track the amount of new data, or the amount of data we had ever received? In this integration, retained history was becoming part of the cost of every run.
Turning a Support Problem Into an Engineering Proposal
I could have built another layer that copied the exports into a layout we controlled. That would have introduced a second delivery path to operate, monitor, and reconcile. I wanted to address the source layout with the vendor first.
I approached the discussion as a design review. My role was to explain the consumer's failure mode, make the request concrete, and keep our implementation ready for the change. The vendor's engineers owned the exporter and the work required to change it.
Three things helped the conversation move forward.
First, I worked to understand how their export process produced files. A useful proposal had to fit the producer's constraints as well as ours.
Second, I connected the symptoms to a specific access pattern: broad object enumeration, increasing discovery overhead, memory pressure, and retries that repeated the same work. The case was stronger than a general request to make delivery faster.
Third, I proposed date-partitioned output as a reusable capability. A consumer that needs a particular time window should be able to address that window directly. That would also make day-level retries and historical backfills easier to isolate.
The discussions took sustained follow-up. The vendor agreed to add date-partitioned delivery, and I worked on the corresponding consumer changes in parallel. The outcome depended on both sides delivering their part of the interface.
What Date Partitioning Actually Changes
The layout below is illustrative. It uses event_date to show the intended access pattern; the paths, filenames, and dates are not a specification of the vendor's export format.
Before: one prefix to enumerate
exports/file-a
exports/file-b
exports/file-c
After: addressable event-date prefixes
exports/event_date=2026-08-01/file-a
exports/event_date=2026-08-02/file-b
exports/event_date=2026-08-03/file-c
With this layout, a run targeting August 3 can list the August 3 prefix. A backfill for August 1 can address that date without enumerating unrelated dates.
In this object-storage model, a prefix is the beginning of an object key rather than a physical directory. A prefix-filtered listing returns keys that begin with the specified value. This example illustrates the access pattern without identifying the storage provider.
For a listing-based consumer, the difference can be expressed as a simple model:
H = all historical objects under the shared prefix
W = objects in the event-date window selected for this run

Broad discovery:       enumerate H object keys
Partitioned discovery: enumerate W object keys
This is a model of discovery work, not a benchmark or a guarantee of runtime. It helps when the selected window is much smaller than the full history. Data volume, file sizes, API overhead, and processing cost still matter. A single busy date can itself contain many files.
Partitioned storage is also not the only possible solution. An object manifest, inventory, or notification-driven consumer can provide another way to discover new files. The important property is that routine ingestion should have a bounded discovery path, with a separate way to recover missed data.
Event Dates Need a Late-Arrival Policy
Date partitioning does not make a pipeline complete or exactly-once by itself. This is especially important when the partition key is an event date rather than the date a file arrived.
An event from August 1 might be delivered on August 3. A consumer that reads only today's event-date prefix would miss it. Yesterday's successful run does not prove that yesterday's partition can never receive another object.
For a reader implementing this pattern, I would put the following questions into the producer-consumer contract:
- What timestamp and timezone determine the partition date?
- Can older partitions receive new files, corrections, or replacements?
- How are new objects discovered, and how is completion signalled, if at all?
- What identifies an object version and an individual event across retries?
- How long is data retained for reprocessing and reconciliation?
A consumer can revisit a recent window of event dates, provided the window reflects an agreed lateness policy. Events arriving outside that window still need a recovery route, such as reconciliation and targeted backfills. A lookback window alone is not a completeness guarantee.
The processing sequence also needs careful failure handling. A useful design sketch is:
for each date in the agreed reprocessing window:
    list that date's prefix one page at a time
    for each unprocessed object version:
        validate its records
        write using stable event identities
        commit the data
        record durable completion for the object version
This is pseudocode for the pattern, not our production implementation. If a worker crashes after committing data but before recording completion, it may replay the object. The sink must tolerate that replay, or the data write and completion marker must be committed atomically. Object-level tracking alone does not remove duplicate events delivered in different files.
These details are what make a partitioned layout useful in a reliable system. The folder structure creates a smaller unit of work; the processing contract determines whether that unit can be safely retried.
Preparing the Consumer Before the Exporter Shipped
While the vendor worked on the export changes, I built the consumer for the new layout and staged it in development. The downstream schema and destination tables stayed consistent. The change was in how the pipeline found and read the delivered files.
I validated against sample outputs and worked through mismatches before the production release. This let the two implementations converge while there was still time to adjust them.
When the vendor validated its production output, our consumer was already prepared for promotion. We did not have to begin a separate implementation cycle after the vendor finished.
For teams planning a similar cutover, I would make the switch criteria explicit: schema compatibility, record reconciliation across an overlapping period, duplicate handling, freshness checks, and a rollback boundary that avoids uncontrolled double ingestion. These are recommendations for the migration plan, not a claim that a new directory layout guarantees a lossless switch.
What Changed, and What I Would Repeat
The partitioned delivery made our ingestion more reliable and gave us a practical way to target retries and backfills by date. Downstream teams could continue using the same tables while the ingestion path changed underneath them.
Our consumer could now select a bounded slice of the export history. That made recovery easier to reason about: a failed day could be revisited as a day, rather than treated as another search through the entire collection.
The experience changed what I look for in a file-based integration. I now treat discovery, partition semantics, late arrivals, and replay behaviour as part of the interface, alongside the schema. A correct record is not very useful if the consumer cannot reliably find it.
It also reinforced the value of working directly with the team on the other side of that interface. I brought the failure evidence and the consumer changes. The vendor's engineers brought the exporter changes. Preparing both sides together was what turned date partitioning from a proposal into a working integration.