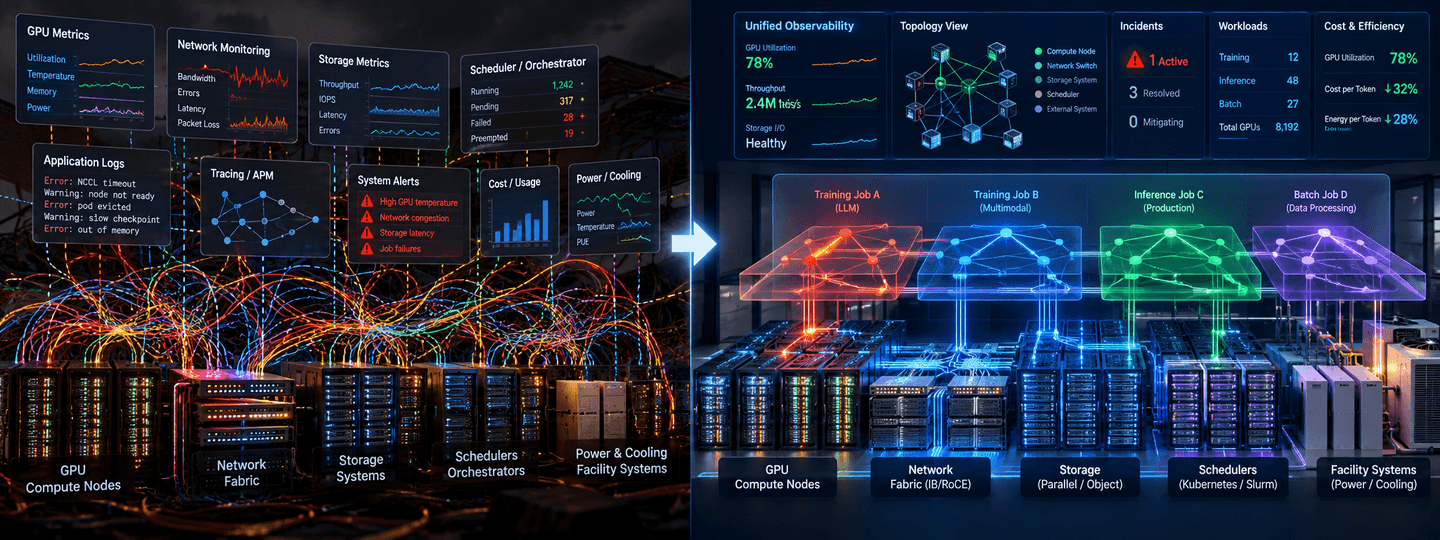
The Challenge of Topology-Aware Observability in NeoClouds
Imagine a customer training a model on hundreds of GPUs. The job has not crashed. The GPUs are visible, the servers are online, and no major network outage has been reported. Yet training is taking longer than expected.
The ML team sees workers waiting during synchronization. The GPU team sees accelerators that appear busy. The network team has thousands of port counters to inspect. Storage monitoring reports changing latency, but not necessarily an outright failure. Every team has a legitimate observation. None can immediately explain the customer’s slowdown.
Where would you begin?
The answer might be a GPU running below its expected clock speed, a congested fabric path, a slow data loader, an overloaded storage service, or a change in the training workload. The first challenge is not producing another chart. It is finding the relevant components, knowing how they were connected when the slowdown occurred, and testing which explanation is supported by the evidence.
This is a hypothetical incident, but the engineering problem is real: a NeoCloud is a tightly coupled system, while monitoring is often organized by component and team.
NeoCloud operators have a more immediate responsibility than developing a perfect observability platform. They must procure and deploy hardware, bring clusters online, provision tenants, support new accelerators, and deliver usable GPU capacity to customers. Monitoring therefore often grows one subsystem at a time. That is sensible, until a performance problem crosses subsystem boundaries.
The result is a paradox: a cloud can have enormous amounts of telemetry and still struggle to answer a basic question: Which component is affecting this workload, and what should we do about it?
This is the promise of topology-aware observability: connect the physical cloud to the jobs running on it, then relate that changing picture to telemetry. It is difficult to build, but it is a tractable engineering problem.
This article walks through the NeoCloud stack, the operational problems that make GPU clouds unusual, the limits of disconnected monitoring tools, and the engineering work required to build a live, trustworthy topology. It then shows how topology-aware observability can support practical operations: faster investigations, productive GPU usage, better placement, clearer customer-impact analysis, and controlled remediation.
The discussion is vendor-neutral. The same underlying technical problems arise in private GPU clouds, although commercial NeoClouds face additional pressure from multi-tenancy, customer isolation, reservations, and service-level commitments.
1. A NeoCloud Is a Connected System, Not Just a GPU Cluster
What makes a NeoCloud different?
Traditional clouds were built to serve a wide range of applications. NeoClouds are designed primarily for accelerated computing, especially AI training and inference. Their design priorities reflect the nature of these workloads: large GPU allocations, very high bandwidth between accelerators, predictable communication performance, and efficient use of power and cooling.
A NeoCloud is more than GPU capacity offered through an API. It is an integrated system in which compute, network, storage, and scheduling decisions affect one another.
For example, a customer may request hundreds of GPUs for a distributed training run. Having that number of GPUs available is not enough. The GPUs must be allocated in suitable groups, connected through a fabric that meets the job's communication needs, and supplied with data fast enough to keep the accelerators working. The scheduler must also account for tenant isolation and the operational health of the underlying components.
NeoClouds often use bare-metal infrastructure or configurations that provide near-direct access to accelerators and high-performance networking. They also use container platforms, specialized schedulers, and hardware-aware allocation policies. The exact approach varies across providers and workloads.
Follow a workload through the infrastructure
A useful way to understand a NeoCloud is to follow a workload from its customer-facing request down to the physical equipment that executes it. This is also the path that an investigation must follow in reverse when the workload misbehaves.

|
Layer |
What it includes |
Why it matters operationally |
|---|---|---|
|
Compute |
GPU accelerators, CPU hosts, GPU memory, PCIe, intra-node GPU interconnects |
Determines execution speed, accelerator health, and memory capacity |
|
Scale-out network |
Host network adapters, optical links, leaf/spine switches, InfiniBand or RDMA over Ethernet |
Connects GPUs across nodes; congestion or link degradation can affect entire distributed jobs |
|
Storage |
Local NVMe, shared or parallel file systems, object storage |
Feeds datasets to jobs and receives checkpoints and model artifacts |
|
Control plane |
Provisioning, Kubernetes or HPC schedulers, resource allocation, tenant management |
Decides which resources a job receives and manages their lifecycle |
|
Power and cooling |
Rack power, power distribution units, liquid-cooling equipment, environmental sensors |
Keeps high-density equipment within safe operating limits and affects sustained performance |
|
Workload and customer layer |
Training and inference jobs, services, reservations, tenants, SLAs |
Connects technical behavior to customer experience and business outcomes |
These layers are tightly coupled. A GPU can be healthy but underutilized because storage cannot deliver data quickly enough. A network link may remain operational while errors or congestion reduce effective throughput. A group of free GPUs may be unusable for a particular job because the allocation cannot satisfy its topology requirements.
The important operational question is therefore not only “Is this component healthy?” It is also “What depends on it, and what happens when it degrades?”
Why training, fine-tuning, and inference behave differently
NeoCloud operators support different workloads, and the same infrastructure issue may affect each workload differently.
Distributed training. Large training jobs spread computation across many GPUs and frequently synchronize results. Collective communication operations require participating workers to exchange data and progress together. A slow GPU, congested network path, or failed node may delay the broader job. Checkpointing also creates substantial bursts of storage traffic.
Fine-tuning and reinforcement-learning workflows. These combine phases of model execution, data processing, and parameter updates. Their resource requirements can change over time, creating varying pressure on GPUs, memory, networking, and storage.
Inference. Serving models emphasizes response time, throughput, memory availability, and predictable performance under changing demand. Model prefill and token generation have different compute and memory characteristics. Operators may care about time to first token, token-generation latency, and the efficiency of model placement.
These distinctions matter for observability. High GPU utilization is not necessarily a sign that a workload is progressing efficiently, and low utilization does not always indicate waste. Useful analysis must combine component metrics with workload behavior and allocation context.
The dependencies that rarely appear on one screen
An operator needs to know more than which devices exist. The operator needs to know how they connect and which jobs rely on them.
The cloud has a physical topology: racks, servers, GPUs, adapters, switches, ports, cables, and dependencies on power, cooling, and storage. On that infrastructure sit multiple logical topologies, including network partitions, tenant boundaries, and a changing overlay for each active job. A job's overlay connects its allocated GPUs and workers to their communication and storage dependencies.
The physical relationships are relatively stable; job allocations and their logical relationships can change minute by minute. Two jobs may use different GPUs while sharing a switch, storage service, or cooling system. If that shared component degrades, the operator needs to know which job overlays intersect the affected infrastructure.
A deployment-time diagram cannot answer that question reliably. An operational model needs intended relationships from inventory and configuration, observed relationships from discovery, and current and historical allocations from schedulers. Section 4 explains how those views can be reconciled.
2. When the Components Look Healthy, but the Cloud Does Not
Bringing GPU capacity online takes priority. Teams must deploy expensive equipment, onboard customers, manage reservations, and keep services running. Monitoring often grows subsystem by subsystem. That works until a problem crosses those boundaries.
The resulting challenges are not all the same, but they share a requirement: connect telemetry to topology, workload behavior, and customer context.
One slow participant can slow a whole job
In a synchronized training job, one GPU or worker running behind the others can delay progress for the entire group. This is often called the straggler phenomenon. The slow participant may be throttled, waiting for data, delayed by the network, or held back by application behavior. Not every slowdown is caused by a straggler, but synchronized workloads make these differences especially costly.
The operator needs to identify which participants slowed down, what resources they used, and what changed at the same time. Knowing only that the GPUs are online is not enough. A physical dependency can suggest which jobs might be exposed; correlated performance evidence is needed to establish actual impact.
Allocation is not the same as productive work
A GPU can hold allocated memory and consume power while doing little useful computation. It may be waiting for data or synchronization, attached to a stalled job, or deliberately reserved. Equally, a healthy GPU cluster can deliver disappointing customer performance without reporting a device fault.
Operators therefore need three complementary views: what was allocated, what the hardware was doing, and whether the workload made useful progress. Connecting those views helps distinguish wasted GPU-hours from legitimate low-activity periods, and customer impact from an isolated hardware alert.
Free GPUs may not form a usable allocation
A cloud can have many unallocated GPUs but still be unable to place a large job. The free devices may span incompatible GPU types, network regions, tenant pools, or node groups. The scheduler must satisfy the job's placement and communication requirements, not just count devices.
This is capacity fragmentation. Understanding it requires the locations and connections of available GPUs, as well as active reservations and workload constraints.
Short-lived signals need careful handling
Some important events, such as brief congestion bursts or rising link errors, can disappear in coarse averages. Yet retaining every raw high-frequency sample indefinitely can be prohibitively expensive.
A practical system evaluates time-sensitive signals promptly and retains important events, selected high-resolution evidence, and useful summaries. It can discard raw samples that are no longer needed without discarding the evidence required to explain a failure. Collection frequency and retention should follow the operational question.
What leadership actually needs to know
The questions that matter to a CEO, CTO, operations leader, or customer are straightforward:
|
Leadership or customer question |
Operational capability required |
|---|---|
|
Why did a customer's training job slow down? |
Workload-progress evidence correlated with GPU, fabric, and storage signals |
|
Which customers are affected by a failing switch or link? |
Physical dependencies connected to job allocations and tenant context |
|
Where are we losing productive GPU-hours? |
Allocation, device activity, and useful workload-progress analysis |
|
Why can't we schedule a job when GPUs appear available? |
Topology-aware capacity and placement analysis |
|
Can we prevent or reduce a repeat incident? |
Timely signals, reliable investigation, and controlled remediation |
These are not dashboard questions. They ask about outcomes. Topology provides the relationships. Telemetry shows what is happening. Workload and customer context make the evidence actionable.
3. Why Excellent Monitoring Tools Can Still Leave Operators in the Dark
NeoCloud teams already have sophisticated tools for GPUs, networking, storage, scheduling, servers, and facilities. Each tool serves an important purpose. The difficulty is following evidence across them when a problem does not respect team boundaries.
Every team has a useful piece of the picture
Different teams need different views of the infrastructure.
|
Team |
What its tools typically show |
What may still be missing |
|---|---|---|
|
GPU and server operations |
Accelerator utilization, temperature, errors, host and interconnect health |
Which jobs are affected by a slow or degraded component |
|
Network operations |
Link status, traffic, errors, congestion, switch health |
Which workloads depend on the affected ports or paths |
|
Storage operations |
Capacity, throughput, latency, volume and device health |
Whether storage delays are leaving particular GPUs idle |
|
Platform and scheduling |
Job placement, reservations, pending jobs, node availability |
Whether available capacity is usable given physical connectivity and health |
|
Facilities |
Power draw, cooling loops, rack and environmental conditions |
Which compute nodes and customer workloads depend on a troubled power or cooling component |
|
AI workload teams |
Training progress, collective-operation delays, inference latency |
Which infrastructure event explains an application-level slowdown |
None of these views is wrong. Each is incomplete for an investigation that spans several layers.
The missing connections between the data
A unified view requires five connections that are often missing:
- Common identities. The same physical GPU may be identified by a device UUID, a host name, a Kubernetes resource, and a scheduler allocation. Those names must resolve to the same component, without confusing temporary assignments with permanent hardware identities.
- Common time. A network event, a GPU slowdown, and a job failure must be compared on a consistent timeline. Different collection intervals, delayed events, and clock offsets can otherwise distort the sequence.
- Common meaning. Vendors may report similar information using different names, units, counters, and severity levels. Data must be normalized while preserving the original source and its meaning.
- Topology. Knowing that a port has errors is not enough. The operator needs to know what is connected to that port, what routes may use it, and which jobs depend on those resources.
- Workload context. Hardware symptoms become operationally meaningful when connected to active jobs, tenants, reservations, and service commitments.
For example, a switch counter can show a rise in errors, while a scheduler shows active jobs. The missing connection is whether those jobs could depend on that port at the time of the event.
The questions that a shared view should answer
The value is not in putting more dashboards together. It is in giving engineers a reliable way to ask:
- Which component or workload is behaving abnormally?
- What physical and logical relationships might explain that behavior?
- Which jobs or tenants may be affected?
- What other signals changed around the same time?
- What evidence supports a possible cause, and what should be checked next?
These questions turn separate observations into a cross-domain investigation.
Keep specialist tools; connect their evidence
A NeoCloud does not need to discard the specialized tools its teams already use. Those tools remain valuable for detailed diagnostics and equipment-specific operations.
A unified observability layer should work with them. It should collect or reference their data, standardize important identifiers, connect the data to topology and workloads, and provide a cross-domain investigation view. Engineers should be able to move from a high-level symptom to the underlying specialist tool when deeper analysis is required.
This avoids forcing every team into a single replacement tool. It also lets the observability architecture evolve as the NeoCloud adds new GPU generations, network vendors, storage platforms, and schedulers.
The difficult engineering work is maintaining the shared relationships as the infrastructure and jobs change. That is the subject of the next section.
4. The Hard Part: Building a Topology That Reflects Reality
Topology is often treated as a diagram created when a cluster is deployed. For observability, that is not enough. A useful topology must describe what exists, how it is connected, what is running on it, and how those relationships are changing.
This is a significant engineering challenge. A NeoCloud includes physical equipment, several networks, logical partitions, and short-lived workload assignments. No single source is guaranteed to contain the full picture.
There is no single topology
A useful model keeps the relatively persistent physical topology separate from the changing logical overlays for tenants and jobs. It connects several kinds of relationships:
|
Topology |
Example relationships |
Questions it helps answer |
|---|---|---|
|
Compute and intra-node |
GPU to host, PCIe hierarchy, GPU-to-GPU interconnect, GPU to network adapter |
Is a slow GPU or local interconnect affecting a job? |
|
Network fabric |
Adapter to port, port to cable, switch to switch, network segment or rail |
Which nodes can communicate through an affected link or device? |
|
Storage |
Node or job to mounted volume, volume to storage service or device |
Which workloads may be waiting on a troubled storage service? |
|
Power and cooling |
Server to rack power, rack to cooling unit or loop |
Which equipment is exposed to a power or cooling problem? |
|
Logical and workload |
Tenant to job, job to pod or process, process to allocated GPU and node |
Which active customers and jobs use the affected infrastructure? |
The per-job overlay matters. Imagine Job A and Job B using different GPU nodes but sharing part of a fabric. A degraded switch may expose both jobs to risk, even if only one shows a performance change. Historical overlays show which allocations existed when the event occurred.
Connected to is not the same as currently used by. A physical network path may exist without carrying traffic for a given job. The system must distinguish confirmed relationships, configured paths, and inferred dependencies when estimating impact.

Three ways to find the relationships
There are three main sources of topology information. Each contributes something different.
Approach A: Inventory and configuration. Infrastructure inventories, data-center management systems, provisioning tools, and network configuration provide the intended structure of the cloud: which rack contains a server, which port should connect to which device, and which network or storage resources are configured.
This is often the best starting point because it provides broad coverage and stable equipment identities. But it may not reflect an emergency repair, a mis-cabled connection, a degraded link, or a change that was not recorded.
Approach B: Observed infrastructure and telemetry. Device discovery, neighbor protocols, hardware interfaces, network controllers, and operational signals reveal what equipment currently reports. For example, PCIe and GPU-management interfaces describe local accelerator connections; LLDP or fabric-management information can help identify physical network neighbors; link-state and error telemetry describe present conditions.
This is valuable for verifying reality against the configured design. But metrics alone cannot reliably reconstruct every connection or dependency. A quiet link does not prove that it is disconnected, and two components showing correlated errors are not necessarily directly connected.
Approach C: A hybrid model with workload data. The strongest practical approach combines inventory and configuration with discovery, telemetry, and live scheduler information. This adds the missing relationship between physical infrastructure and the workloads consuming it.
|
Source |
Main contribution |
Typical limitation |
|---|---|---|
|
Inventory and configuration |
Intended assets, ownership, physical layout, configured connections |
Can be stale or incomplete |
|
Device and fabric discovery |
Observed equipment and connectivity |
Coverage varies by protocol, device, and access rights |
|
Telemetry and event streams |
Health, errors, traffic, state changes |
Describes behavior; does not always prove physical relationships |
|
Schedulers and control planes |
Jobs, tenants, allocations, runtime state |
Usually lacks complete physical network and facilities context |
Recommendation: Treat the hybrid model as the reference architecture. Keep the inventory's intended state and discovery's observed state distinct, then reconcile them. Neither should silently overwrite the other when they disagree.
Constructing a unified topology, step by step
A topology engine can be built in seven practical steps:
1. Establish a starting inventory. Import assets and known relationships: sites, racks, servers, GPUs, network devices, ports, cables, storage resources, and relevant power or cooling equipment. Use existing source-of-truth systems instead of requiring a second inventory to be maintained by hand.
2. Discover what is actually present. Query device and fabric interfaces to confirm connections and health. Examples include host hardware information, GPU management interfaces, network neighbor discovery, and storage or facilities controllers. Discovery capabilities differ by environment, so gaps should be visible rather than filled with guesses.
3. Resolve identities. Match records across systems using durable identifiers where available, such as GPU UUIDs, device serial numbers, switch and port identifiers, or host identifiers. Maintain aliases for tool-specific names. A job ID or pod name should not be used as the permanent identity of a physical GPU.
4. Reconcile intended and observed state. Compare expected connections and settings with observed ones. Flag missing equipment, unexpected neighbors, speed mismatches, stale records, and conflicting information. Preserve the evidence and its source so an operator can investigate the discrepancy.
5. Add active workload relationships. Connect scheduler and orchestration data to hosts and allocated GPUs, then to jobs, services, tenants, and reservations. Record the time interval during which each allocation was valid. The graph now connects a physical failure to the workloads that may depend on it.
6. Keep the model current. Use change events where available, including device state changes, allocation events, provisioning updates, and network changes. Periodic reconciliation remains useful to catch missed events and incomplete discovery. An event-driven system reduces unnecessary full scans; it does not eliminate the need to check for drift.
7. Track freshness and confidence. Record when a relationship was last confirmed and where it came from. An observed cable connection, an intended configuration, and a relationship inferred from traffic should not be presented with the same certainty. Unknown or stale relationships are operationally important facts.
The output is not merely a network map. It is a continuously updated model of infrastructure and workloads, with enough history to reconstruct what the system looked like when an incident occurred.

Topology shows potential impact, not automatic proof of cause
A topology model becomes operationally useful when a component degrades or fails. An impact investigation can follow five steps:
- Locate the component. Identify its physical location, connected equipment, and relevant logical resources.
- Traverse dependencies. Find nodes, services, and active job allocations associated with those resources.
- Check actual use. Use available routing, fabric, traffic, or scheduler evidence to narrow the potentially affected set. Connectivity alone does not prove that a job used a particular path.
- Correlate telemetry. Compare health changes with workload behavior on the timeline of the incident.
- Classify impact. Distinguish confirmed impact, possible impact, and unaffected workloads where evidence supports that conclusion.
This is failure-impact analysis: understanding what a problem may affect. Root-cause analysis asks a different question: what initiated the problem? Topology helps narrow that investigation, but timing, diagnostic tests, and other evidence are needed to support a causal explanation. The first practical example later in this article walks through that distinction.
Beyond incidents: utilization and placement
Topology helps beyond incidents. It shows whether free GPUs form a usable group for a requested job, given accelerator type, node boundaries, connectivity, and placement constraints. It also relates GPU activity to the storage and communication dependencies that may be slowing useful work.
The same relationships can support maintenance planning by showing which jobs and tenants may depend on a rack, switch, cooling unit, or storage service. The practical examples below show how the same relationships help with placement and operational decisions.
Where real deployments become difficult
Several details determine whether a topology model is trustworthy.
- Incomplete discovery: Some devices or facilities systems expose limited interfaces. The model must tolerate gaps.
- Multiple network paths: Physical connectivity does not always reveal the path used by a flow. Routing, rail selection, and congestion conditions may change the relevant dependencies.
- Fast-changing allocations: Jobs and pods come and go. The topology must reflect assignments at the time of an event, not just at the time of investigation.
- Conflicting sources: Inventory may disagree with discovery. Conflicts should be recorded and reconciled rather than hidden.
- Scale: A large NeoCloud can contain enormous numbers of components and relationships. Updating changed portions of the graph is more practical than rebuilding everything after each event.
- Tenant boundaries: Operators need broad infrastructure visibility, while customer-facing views must not expose other tenants' resources or data.
A sensible implementation begins with the relationships that unlock the highest-value operational questions: GPU → node → network adapter → fabric; job → allocated GPU; and job → tenant. Storage, power, cooling, and more detailed path modeling can be added progressively.
The objective is not a perfect digital twin on day one. It is a sufficiently accurate, current, and explainable topology that makes real operational decisions better.
5. From a Topology Graph to an Operational Observability System
Section 4 described how to construct and maintain the topology. This section addresses the next question: how do we use it in a working observability system?
The answer combines existing telemetry sources with common identities, appropriate processing and retention, cross-domain analysis, and interfaces built around operational decisions. The reference architecture below describes responsibilities, not a prescribed vendor or technology stack.
The major building blocks

The architecture has six main capabilities:
|
Capability |
Responsibility |
|---|---|
|
Collection and integration |
Receive metrics, logs, events, and state from devices, collectors, controllers, and existing monitoring tools |
|
Normalization and identity |
Align names, units, timestamps, and component identifiers while retaining source details |
|
Topology management |
Construct and update physical, logical, and workload relationships, including their history and confidence |
|
Telemetry processing and storage |
Evaluate urgent signals, retain useful detail, and support historical analysis at an acceptable cost |
|
Correlation and analysis |
Connect symptoms to dependent components, affected jobs, likely explanations, and operational trends |
|
Experience and operations |
Provide dashboards, investigation workflows, queries, alerts, reports, APIs, and carefully controlled remediation |
These are logical responsibilities, not necessarily separate services. In particular, the topology-management capability described in Section 4 becomes a shared source of context for detection, investigation, and reporting.
Collection and normalization
Sources differ widely. A GPU may expose metrics through a hardware management interface, a switch through streaming network telemetry, a server through system exporters, and a cooling controller through a facilities protocol. Kubernetes and HPC schedulers expose allocations through APIs and events.
Common interfaces include Prometheus-compatible metrics, OpenTelemetry, gNMI, SNMP, Redfish, and vendor-specific APIs. No single protocol covers every layer.
Adapters should translate these sources into a consistent data model while keeping enough original detail for specialist diagnosis. For every important signal, the system should be able to answer:
- What component produced it?
- Which location, cluster, and tenant or workload does it relate to, if known?
- What does the measurement mean, and in what units?
- When did the event occur, and when was it received?
- What source and transformation produced the stored value?
Normalization is especially important when a cloud operates several generations of hardware or uses equipment from multiple vendors. It should not erase meaningful differences between devices.
Fast detection and long-term history need different paths
Not all telemetry needs the same collection frequency or retention period.
A short network microburst may require fine-grained sampling or hardware-generated events to detect. GPU temperature trends, daily capacity usage, and facility measurements may be useful at different intervals.
A practical design uses three processing paths:
- Immediate signals: Critical fault notifications and selected high-frequency indicators are evaluated close to the source or in a low-latency stream. These support rapid alerts and, where safe, predefined actions.
- Operational history: Detailed recent telemetry and event timelines support investigations, workload correlation, and diagnosis.
- Long-term analysis: Aggregates and selected raw evidence support capacity planning, performance trends, reliability reviews, and cost analysis.
This prevents the system from storing every short-lived sample forever. At the same time, aggressive aggregation must not discard the spikes, error sequences, or timing needed for incident analysis. Sampling and retention should follow the use case, not one fixed rule for every signal.
The pipeline also needs buffering and backpressure controls so a burst of telemetry or a temporary storage outage does not become a second operational failure. Where possible, important events should remain recoverable and their delivery status visible.
Correlation requires time, topology, and workload context
With a current and historical topology available, analysis must establish how a workload's symptoms relate to events in time. It needs several forms of evidence:
- Workload state: What changed in job progress, step time, throughput, or inference latency?
- Time: When were signals measured, received, and recorded? Collection delays and clock differences matter.
- Topology at the time: Which GPUs, hosts, fabric resources, and storage services were related to the job during the event, not merely at the time of investigation?
- Corroborating signals: Which hardware errors, congestion indicators, workload traces, or configuration changes support or contradict a possible explanation?
- Confidence and gaps: Which observations are confirmed, which dependencies are inferred, and what data is still missing?
The output should let an engineer trace a proposed explanation back to the underlying telemetry and topology. Where evidence is incomplete, the system should present a hypothesis or a next diagnostic step rather than assert a root cause.
The same process can support utilization investigations, planned maintenance, and tenant-impact reporting.
Design the interface around the decision
Different users need different levels of detail.
Executives and cloud operations leadership need trends in productive utilization, customer impact, service reliability, capacity constraints, and recurring sources of waste.
SREs and operations teams need a current operational map, incident timelines, affected services, health changes, and actions that are available now.
Infrastructure specialists need full access to component-level details: GPU errors, switch counters, link states, storage performance, and facilities data, with a path back to their existing diagnostic tools.
Customer-facing teams need a tenant-scoped view of service impact and relevant performance information without exposing other customers' data.
All these views should be based on the same identities, topology, and event history. Otherwise, different dashboards can disagree about what happened.
Secure visibility and safe remediation are design requirements
A NeoCloud's observability platform can see sensitive infrastructure and customer relationships. It should support isolation between tenants, role-based access, audit records, and appropriate retention controls. Deployment boundaries and data access should match the provider's security requirements.
Remediation also needs safeguards. Detecting a degraded link or an unhealthy node does not automatically mean it is safe to drain it. The action may affect active jobs or remove needed redundancy.
A sensible progression is:
- Observe: Detect a problem and present supporting evidence.
- Recommend: Identify possible actions and estimate affected workloads.
- Approve and act: Let an operator confirm the action, or use a narrow, explicitly authorized policy.
- Verify: Check whether the action helped and whether it created new problems.
Automation should also avoid repeated drain-and-restore cycles when an unstable component briefly appears healthy. Quarantine, cooldown periods, and recovery tests can reduce such oscillation.
Build in stages, each tied to an operational outcome
A NeoCloud does not have to implement the entire architecture at once. A staged approach can provide value while limiting engineering risk.
|
Stage |
Initial scope |
Useful outcome |
|---|---|---|
|
1. Unify identifiers and inventory |
GPUs, nodes, network devices, job allocations, key metrics |
A consistent view of assets and where workloads run |
|
2. Connect topology to live workloads |
Node and fabric relationships, scheduler data, current health |
Identify possible job and tenant impact from infrastructure problems |
|
3. Add cross-domain investigations |
Correlate GPU, network, storage, and job timelines |
Reduce manual handoffs and narrow the search for causes |
|
4. Improve efficiency and capacity |
Reservations, GPU activity, progress, placement constraints |
Expose idle allocations and explain stranded capacity |
|
5. Add governed remediation |
Runbooks, impact checks, approvals, recovery verification |
Reduce response time without introducing uncontrolled changes |
At each stage, operators should measure whether the new capability actually improves incident investigation, productive GPU-hours, placement decisions, or customer communication.
The end goal is not an observability system that stores more data. It is an operational platform that helps teams understand the cloud, recognize impact early, and keep valuable GPU capacity productive.
6. Six Questions a NeoCloud Operator Should Be Able to Answer
The preceding sections explain the architecture. The six scenarios below are hypothetical examples, not reports of customer incidents. They deliberately revisit some earlier challenges, this time showing how an operator could investigate and act using topology, telemetry, and workload context.
1. Why did this training job slow down?
A customer is training a model across 512 GPUs. The job is still running, but each training step takes longer than expected. The customer sees slower progress. GPU dashboards show a mixture of high utilization and periods of waiting. No server or switch has gone completely offline.
There are several possible explanations. One GPU may be running at a reduced clock speed. A network path may be congested. A storage system may be delaying data delivery. The training code itself may have changed. The operator should not assume a network fault simply because a collective operation is slow.
A unified investigation follows the workload through the infrastructure:
- Start with the job. Compare step time, throughput, collective-operation timing, and recent changes against the job's normal behavior.
- Find its allocation. Identify the 512 GPUs, their hosts, network adapters, and relevant fabric dependencies at the time of the slowdown.
- Compare participants. Look for stragglers, clock throttling, GPU or memory errors, unusual interconnect behavior, and workers waiting for synchronization.
- Check connected systems. Examine network error and congestion signals, storage latency, and data-loading behavior on the same timeline.
- Test the leading explanation. Use path information, diagnostics, and recent changes to distinguish an initiating fault from symptoms created elsewhere.
For example, rising errors on a fabric link that serves some of the job's nodes may make the link a strong suspect. But a relationship in the topology graph shows possible dependency, not proof that the job used that exact path. Routing or fabric information and correlated timing strengthen the case.
Operational value: Narrow the investigation from hundreds of GPUs and many systems to a smaller set of components, tests, and actions. The result is a faster, better-supported investigation, not a guarantee of root-cause identification.

2. Where are expensive GPU-hours being lost?
A cloud reports that most GPUs are allocated. Yet customer workloads may be doing less useful work than the allocation numbers suggest.
Consider three situations:
- A job reserves GPUs but remains stalled after a worker fails.
- GPUs spend long periods waiting for data because the input pipeline cannot keep up.
- A distributed job spends more time waiting for its slowest participant than computing.
A GPU can hold memory and consume power in each case. A simple utilization percentage does not explain whether the allocation is productive.
An effective analysis connects reservation and allocation, device activity, and workload progress. It can compare allocated GPU-hours with execution behavior, job state, training throughput, and periods spent waiting on networking or storage. Operators can then distinguish recoverable waste from intentional reservations or normal workload phases.
Actions might include notifying the customer, repairing a blocked pipeline, restarting a failed worker, or returning an abandoned allocation to the pool. The decision should respect reservations, customer policies, checkpoint requirements, and the risk of losing work.
Operational value: Measure and recover productive capacity without treating every idle GPU as a fault.
3. Why can’t we place a job when GPUs are free?
Suppose 80 GPUs are unallocated, and a customer requests 64. An aggregate capacity dashboard suggests there should be enough room. The scheduler cannot place the job.
The missing detail may be where those GPUs are. They could be split across different accelerator types, network groups, racks, or isolated tenant pools. A large job may need whole nodes, specific GPU memory capacity, or a fabric placement that meets its communication requirements. Free resources are not always a usable allocation.
A topology-aware capacity view can show:
- Free GPUs by type, node, rack, network group, and health state
- The constraints on the requested job
- Which constraint blocks placement
- Which existing reservations or fragmented allocations contribute to the problem
- Whether a different placement or later reservation window could satisfy the request
This analysis should complement the scheduler rather than silently override its placement and isolation rules.
Operational value: Explain stranded capacity, improve placement decisions, and make capacity planning more useful than a single cluster-wide utilization figure.
4. Which customers are actually affected?
A network switch, storage service, or cooling unit reports a serious problem. Infrastructure teams know the component is unhealthy. Customer-facing teams need a different answer: Who is affected, and how badly?
The investigation proceeds from the infrastructure component outward:
- Identify its confirmed physical and logical dependencies.
- Find active jobs, services, or reservations mapped to those dependencies.
- Check whether those workloads show abnormal performance or errors during the event.
- Separate confirmed impact, possible impact, and no observed impact.
- Produce a tenant-scoped incident timeline for operations and customer communication.
For a network event, several jobs may be connected to the same fabric region, but only some may have used the affected paths. The system should be explicit about that uncertainty. For a cooling problem, the dependency may be more direct: a rack's servers share a cooling unit even if they run unrelated jobs.
Operational value: Prioritize incidents by customer impact, support more accurate SLA reporting, and communicate without guessing or exposing other tenants' data.
5. Is storage holding back the GPUs?
A training job's GPUs are intermittently idle. GPU monitoring shows the symptom, but the underlying problem may be a shared file system, networked storage service, or input-data pipeline.
To investigate, the operator needs to connect the job's allocated nodes with the datasets, mounts, storage services, and I/O paths it uses. The analysis can then compare GPU wait periods with storage throughput, queue depth, read latency, and application data-loading events.
Checkpointing creates a related problem. Many workers may write large model states at roughly the same time. If the storage service slows down during these bursts, the impact can appear as a training-performance problem rather than a storage failure.
A shared timeline helps operators decide whether to investigate data loading, storage capacity and performance, network congestion, or workload behavior. It also identifies other jobs that might be competing for the same service.
Operational value: Avoid investigating healthy GPUs when the constraint is elsewhere in the system.
6. Can we act before degradation becomes an outage?
Not every failure begins with a component going offline. A network link may accumulate errors while remaining up. A GPU may reduce its clock speed under sustained thermal pressure. A cooling loop may drift toward an unsafe operating range.
An observability system can recognize these trends and use topology to identify the workloads exposed to them. It may recommend moving a future allocation, cordoning a node after a job reaches a safe checkpoint, or removing a degraded link if the fabric can tolerate that change.
Automatic actions require care. Draining a link may shift traffic onto a more congested path. Removing a node may interrupt a large training run. Reintroducing an unstable link too soon can create repeated failures.
A safe process is detect → estimate impact → recommend or approve → act → verify. It should include cooldown periods, recovery checks, audit records, and a way to stop or roll back supported actions.
Operational value: Reduce the impact of degradation without making remediation itself a source of instability.
Measure the outcomes, not the dashboard count
The success of observability should be measured by operational improvements, not just the number of collected metrics or dashboards.
|
Objective |
Measures worth tracking |
Important qualification |
|---|---|---|
|
Faster incident response |
Time to detect, time to identify affected workloads, time to resolve |
Compare similar incident types; severity and workload mix differ |
|
More productive GPU use |
Allocated GPU-hours, idle or blocked allocation time, workload progress |
Low utilization can be normal or intentional |
|
Better capacity placement |
Placement success, pending-job reasons, topology-constrained free capacity |
Some constraints are deliberate for performance or isolation |
|
Clearer customer accountability |
Time to identify affected tenants, completeness of incident timelines, SLA evidence |
Distinguish suspected impact from confirmed impact |
|
Safer operations |
Repeated incidents, successful mitigations, failed or reversed actions |
Automation should not be rewarded merely for taking more actions |
These measures can be established before a new capability is deployed and reviewed after it has been used in real operations. The desired outcome is fewer hours of productive capacity lost, less time spent on manual investigation, and more reliable customer service.
7. The Real Goal: Make the Whole Cloud Understandable
Observability is often presented as a collection of metrics, alerts, and dashboards. Those are necessary, but they are not the end product an operator needs.
An operator wants to know why a training job slowed down. A customer team wants to know whether a fault affected its tenants. A capacity planner wants to know why GPUs counted as free cannot be allocated. And a CTO wants to know whether the cloud is delivering useful compute capacity reliably and economically.
Answering those questions requires a picture of the system, not just its parts. Inventory explains the intended infrastructure. Device and fabric discovery reveal what is observed. Scheduler data connects physical resources to active jobs and customers. Telemetry supplies evidence of behavior and change. A time-aware topology ties the information together.
None of this makes root-cause analysis automatic. A topology shows dependencies and possible exposure; sound diagnosis still requires timing, corroborating evidence, and testing. Nor does it mean every NeoCloud needs to replace its monitoring tools or build an enormous platform before seeing value. The work can begin with stable identities, a trustworthy view of current allocations, and one painful cross-domain investigation.
As a NeoCloud grows, the cost of disconnected operational knowledge grows with it. The most useful observability architecture is therefore the one that helps people answer real questions faster, keep GPU capacity productive, and give customers dependable service.
A NeoCloud should not have to choose between knowing how its individual components behave and understanding how the cloud behaves as a whole.
This article was published under HackerNoon's Business Blogging program.