
Maker, meme-r, and unabashed geek, Joe has been writing about technology since starting his career in 2018 at KnowTechie. He's covered everything from Apple to apps and crowdfunding and loves getting to the bottom of complicated topics. In that time, he's also written for SlashGear and numerous corporate clients before finding his home at XDA in the spring of 2023.
He was the kid who took apart every toy to see how it worked, even if it didn't exactly go back together afterward. That's given him a solid background for explaining how complex systems work together, and he promises he's gotten better at the putting things back together stage since then.
I write about AI coding agents a lot, and somewhere along the way I'd decided the model was doing all the heavy lifting. Swap Claude Code for Codex or Cursor, keep the same brain underneath, and you should get the same work back. So I put that to the test.
I gave all three Claude Sonnet 5.5 at high reasoning, the same buggy WebSocket proxy that feeds my Kindle data from Home Assistant, 30 minutes, and $10 each. Every one of them scored a perfect 16 out of 16 on the final code, but that's the last thing they had in common.
Making three tools use the same model was harder than expected
At least, without upgrading some subscription plans

You'd think that choosing the model would be the easy part, but it turned out to be more complicated than I expected. We've tested these three tools extensively with the default models, but to create a more controlled experiment I wanted to reduce the variables.
There are no models that are native to Claude Code, Codex, and Cursor, which meant that at least one of the tools would have to use their model through a translation layer. I also wanted to stick to documented official routes, and that kept pointing in one direction.
Cursor uses a subscription model, and you need one to use third-party models. That's anything but Grok, just in case you needed a reminder. Codex has a supported route using OpenRouter as the endpoint for third-party models. And while Claude Code can use third party models, it was built to only talk to Claude, so other models introduce a second translation layer that none of the providers guarantees will work.
That last point really was the decider, at least for testing these three tools objectively. If Claude Code only guarantees runs to work with Claude models, then that's it. Cursor has Sonnet 5.5 via API credits, and Codex supports OpenRouter, so I could use API calls there too. Cursor and Codex defaulted to high reasoning, so I had to change Claude Code's default of medium, and then all three tools used the same model with the same setup.
The job before them
I already had a project for the agents to work on. The Kindle dashboard for Home Assistant that I'd ported from the supported Kindle Paperwhite version to the device I actually own. It already has four bugs that I had been meaning to fix, plus I wanted an auto-reconnect feature for the proxy server. There's also another trap, because the Kindle is so old it only supports ECMAScript 5. That means no modern JavaScript conveniences to use, and plenty of room for the agentic coding tools to get something wrong.
I also added a second prompt with a request for new features, Home Assistant status messages and an offline badge to alert me if the server went down. This was scored using a 16 test routine that was deliberately kept out of the folders the agentic tools could use, because I've learned that a test the agent can see is one that it will write around to pass even if the code doesn't work for the intended use.
All three passed my testing suite
The model decided what got built, including some features I didn't ask for
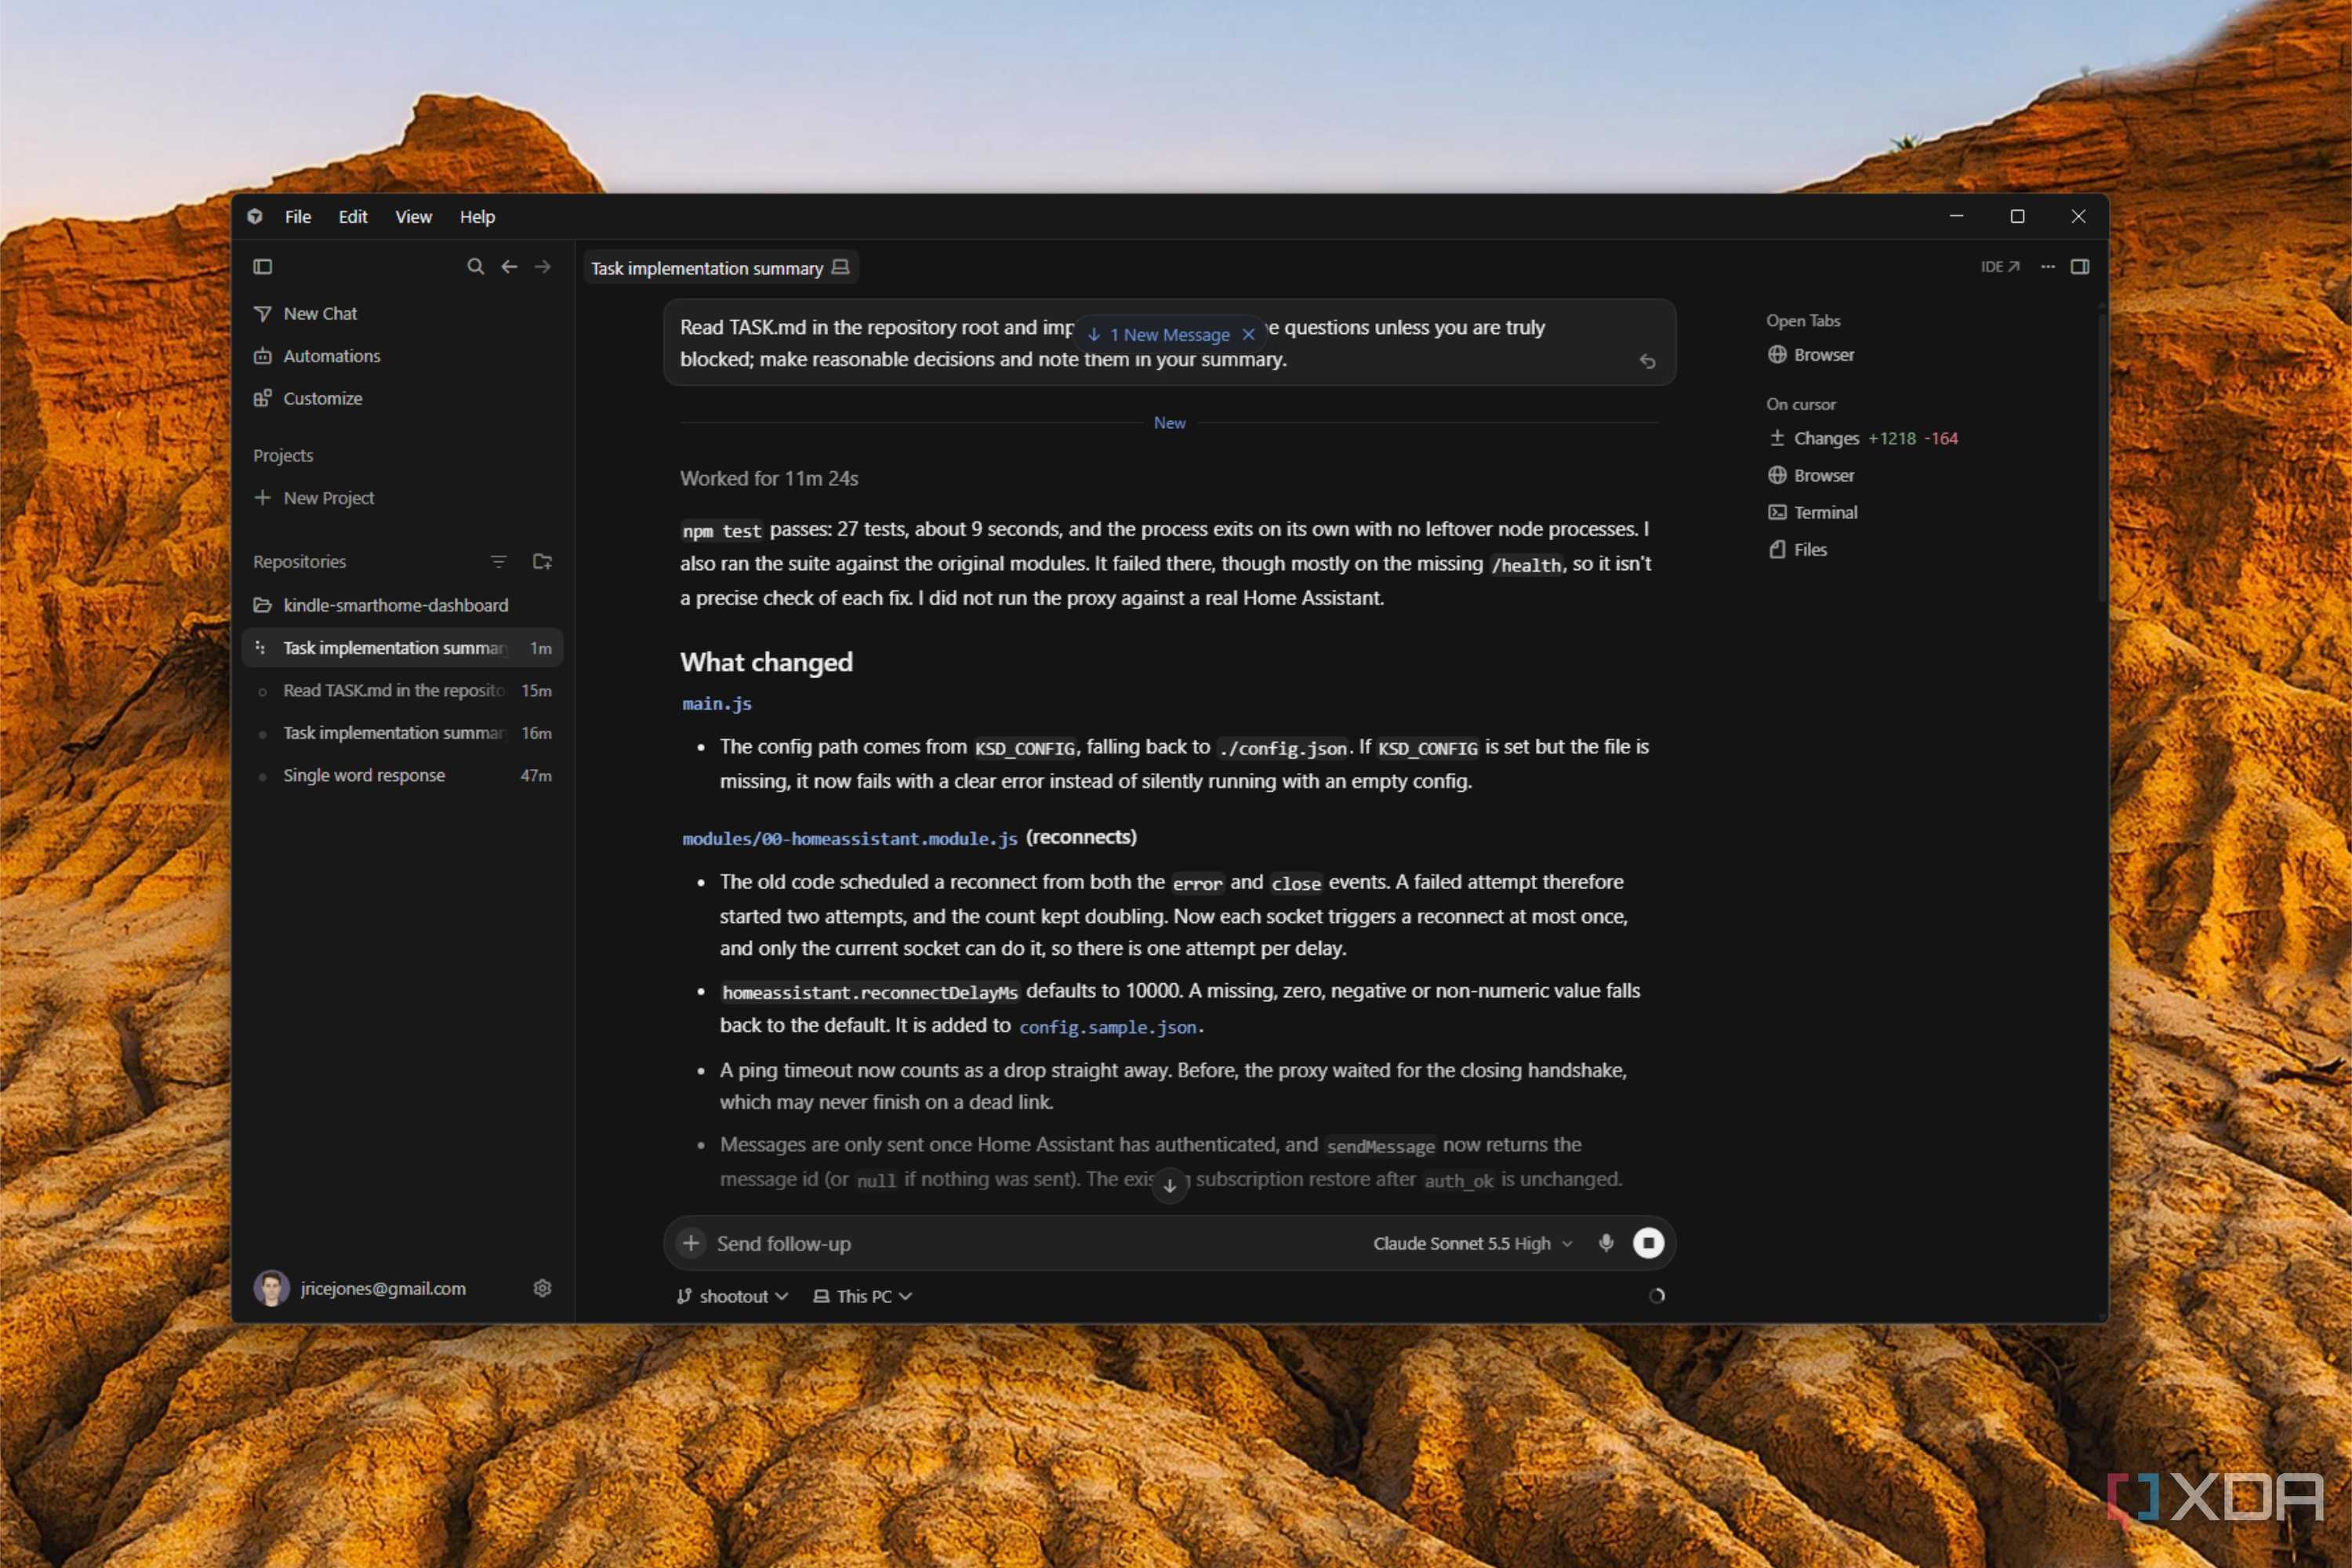
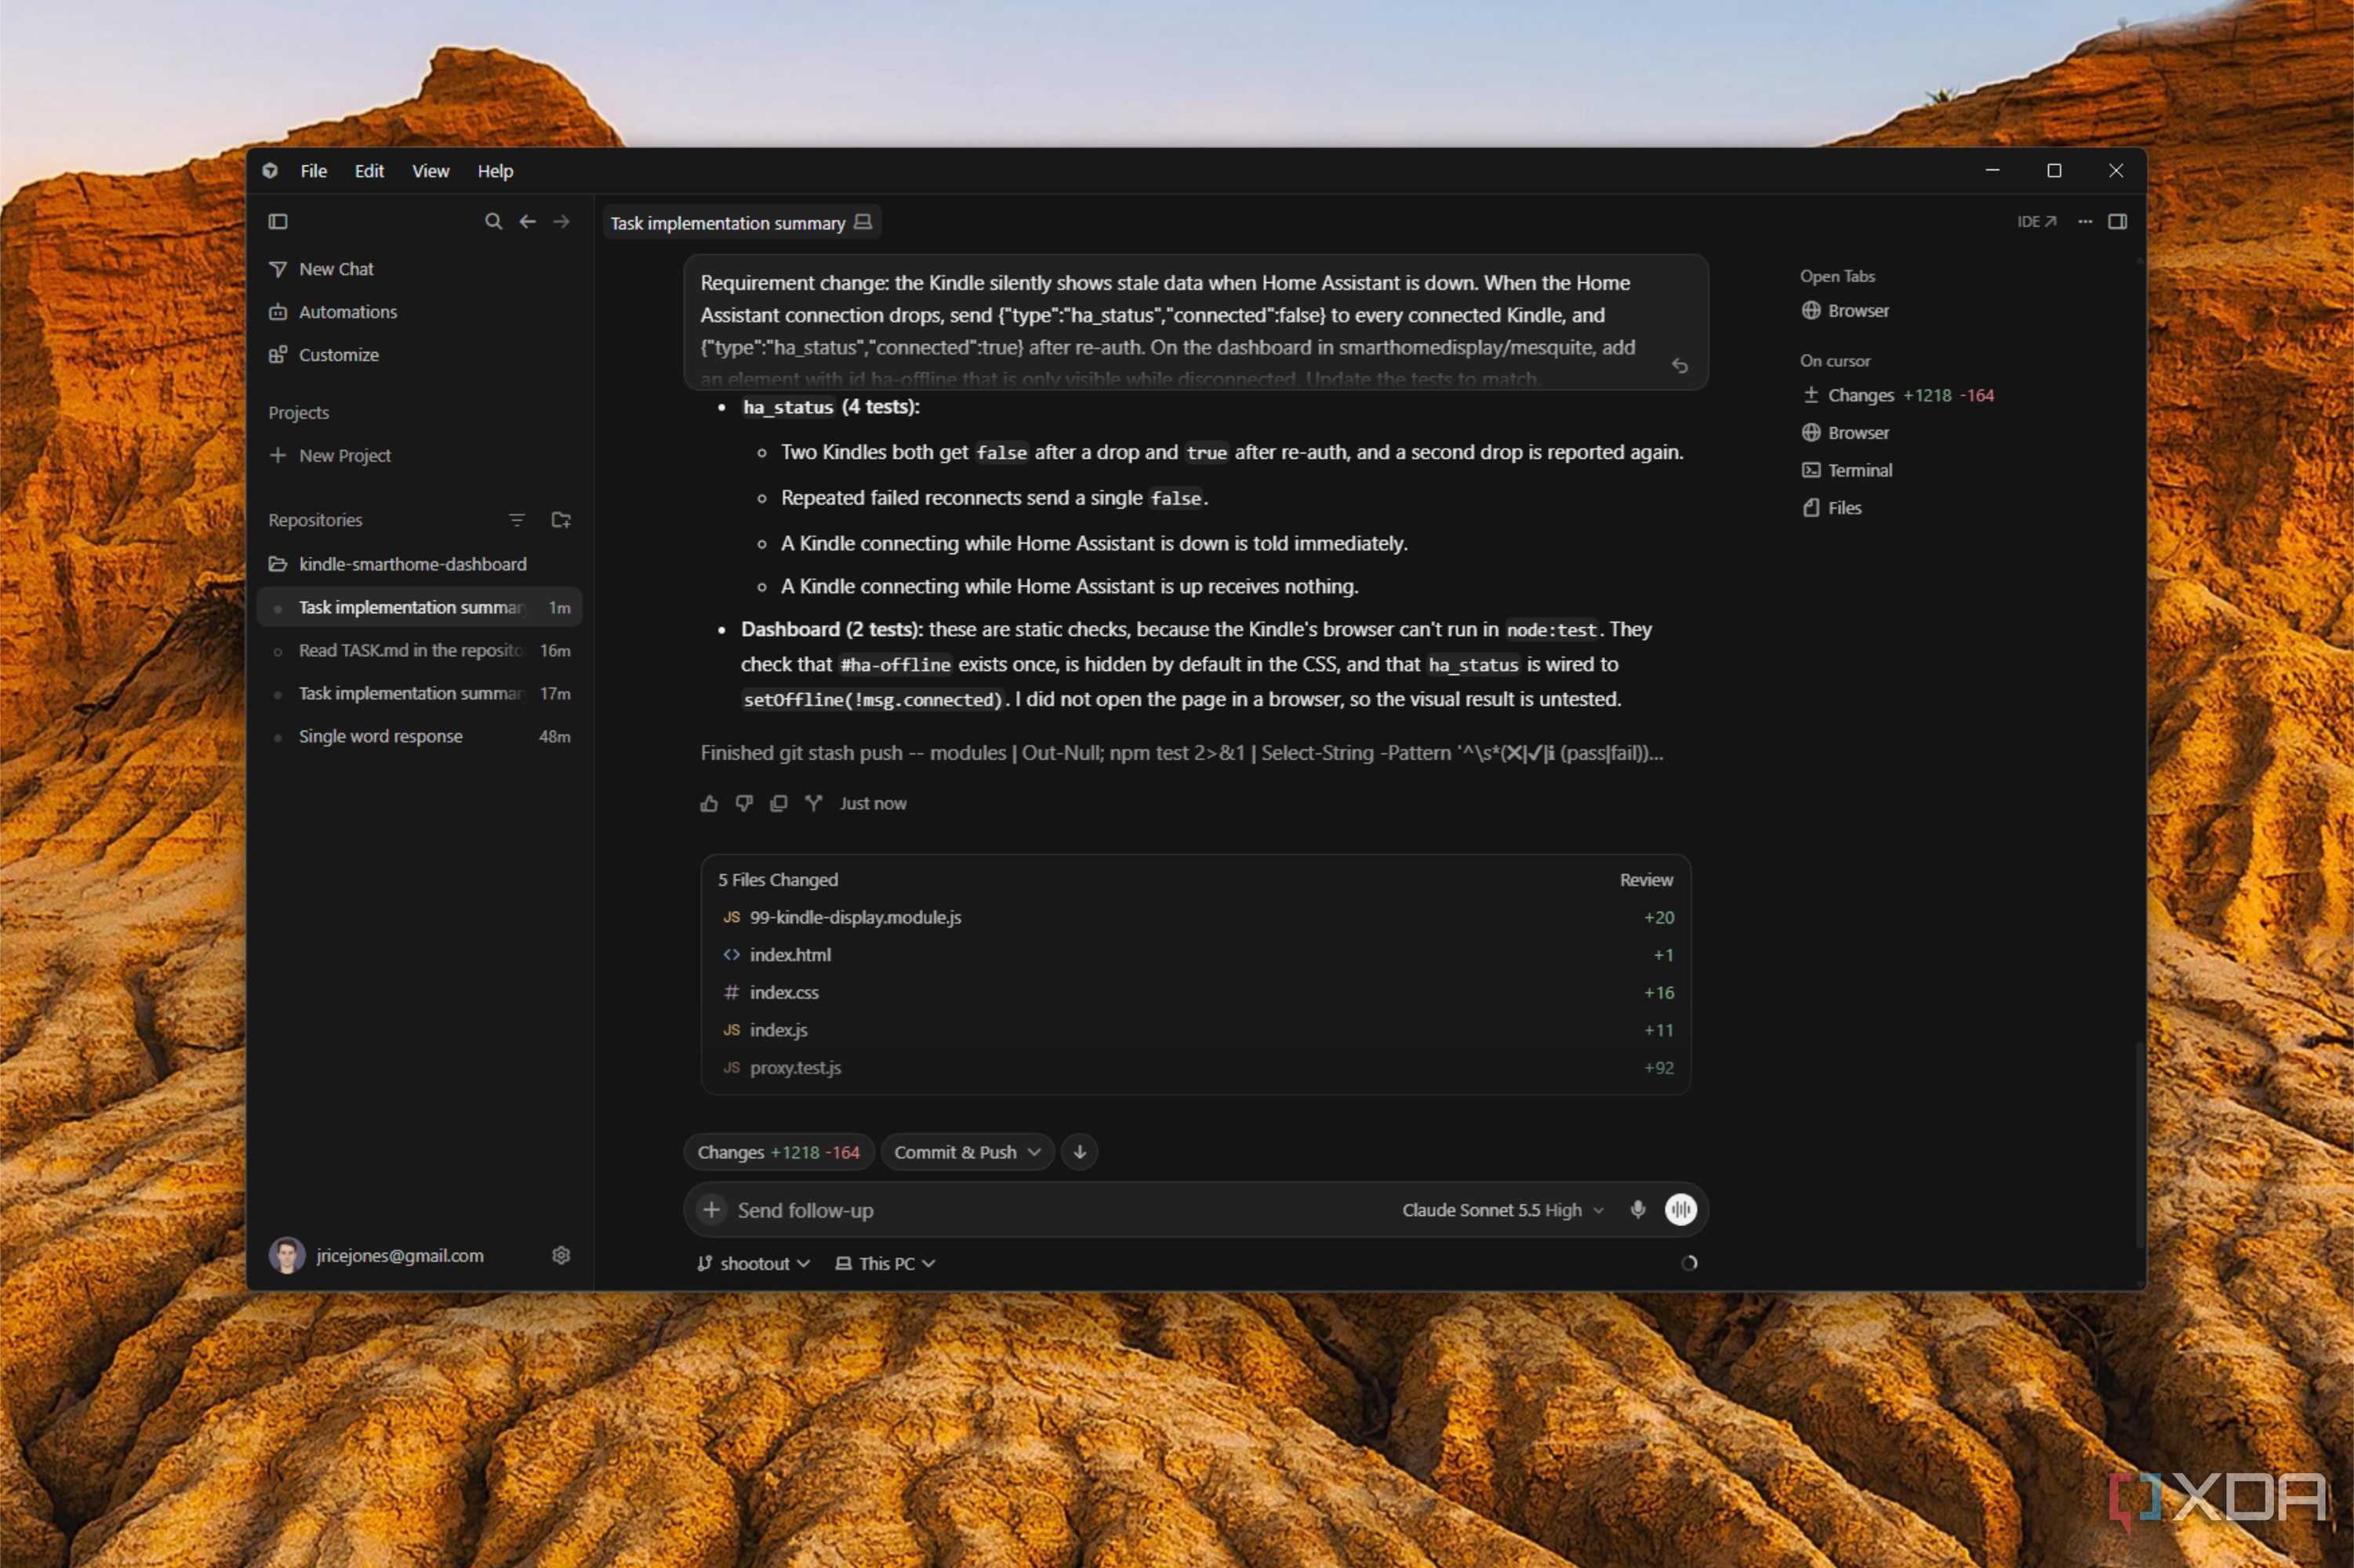
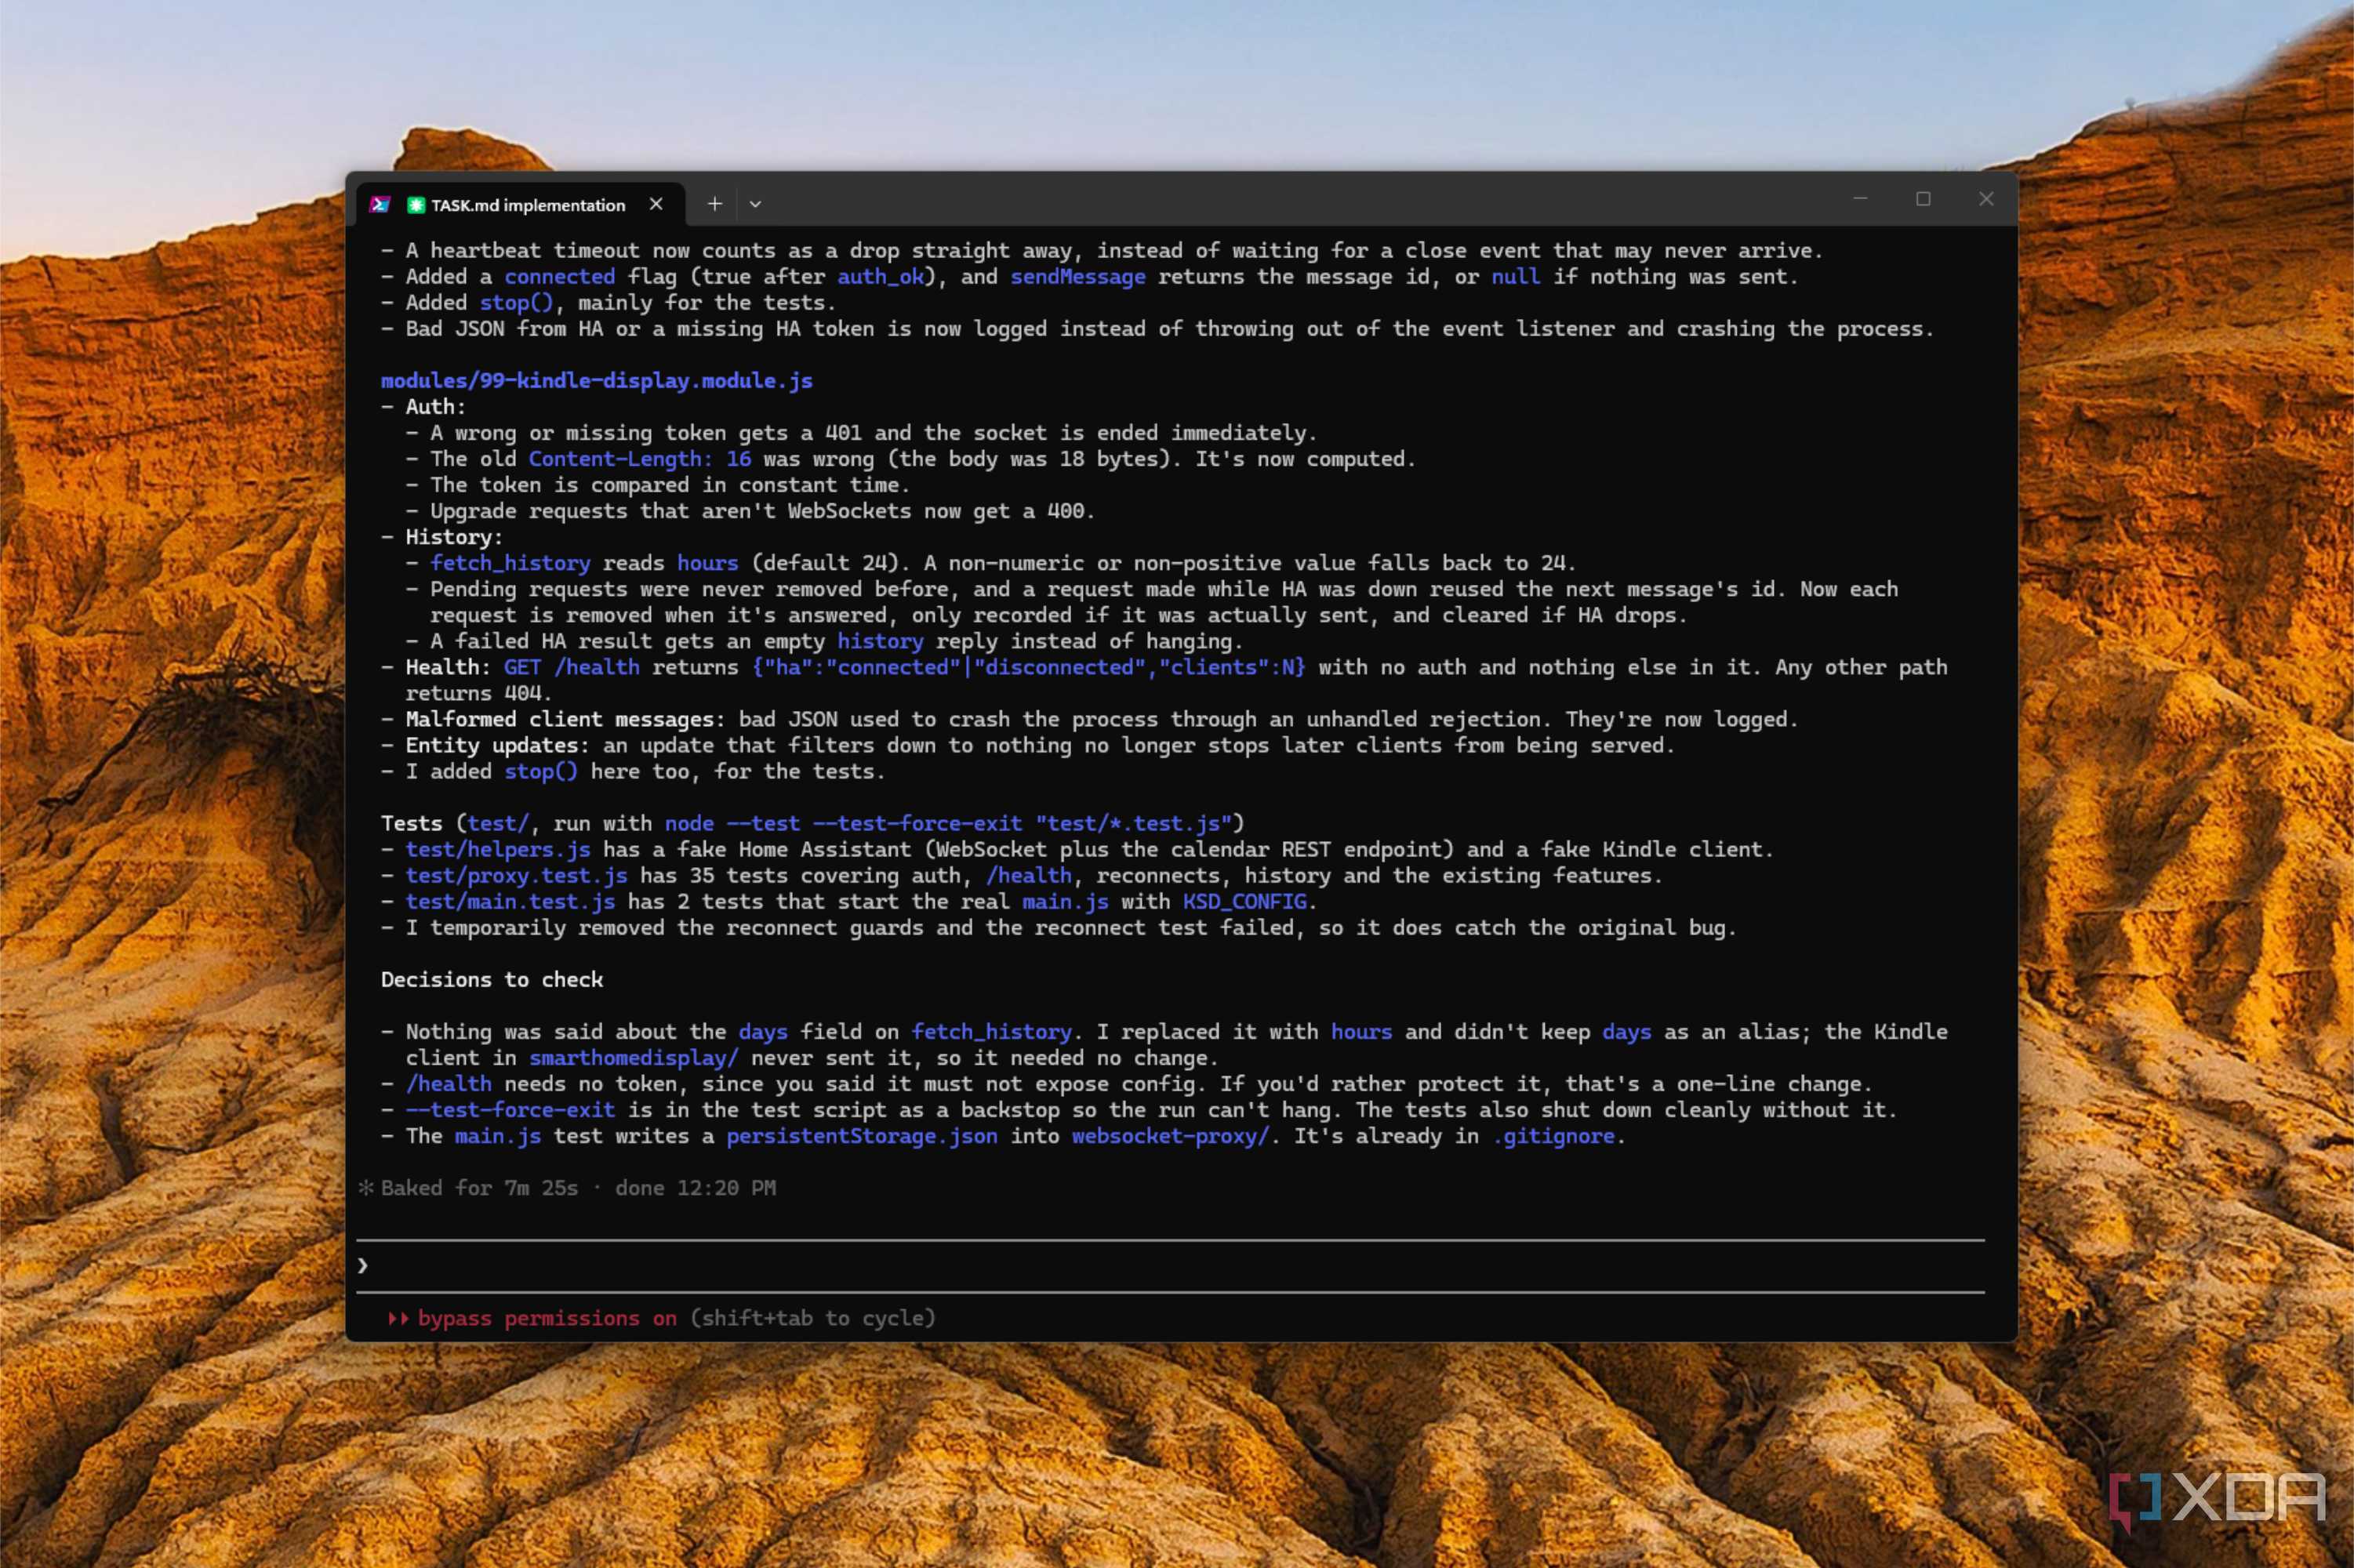
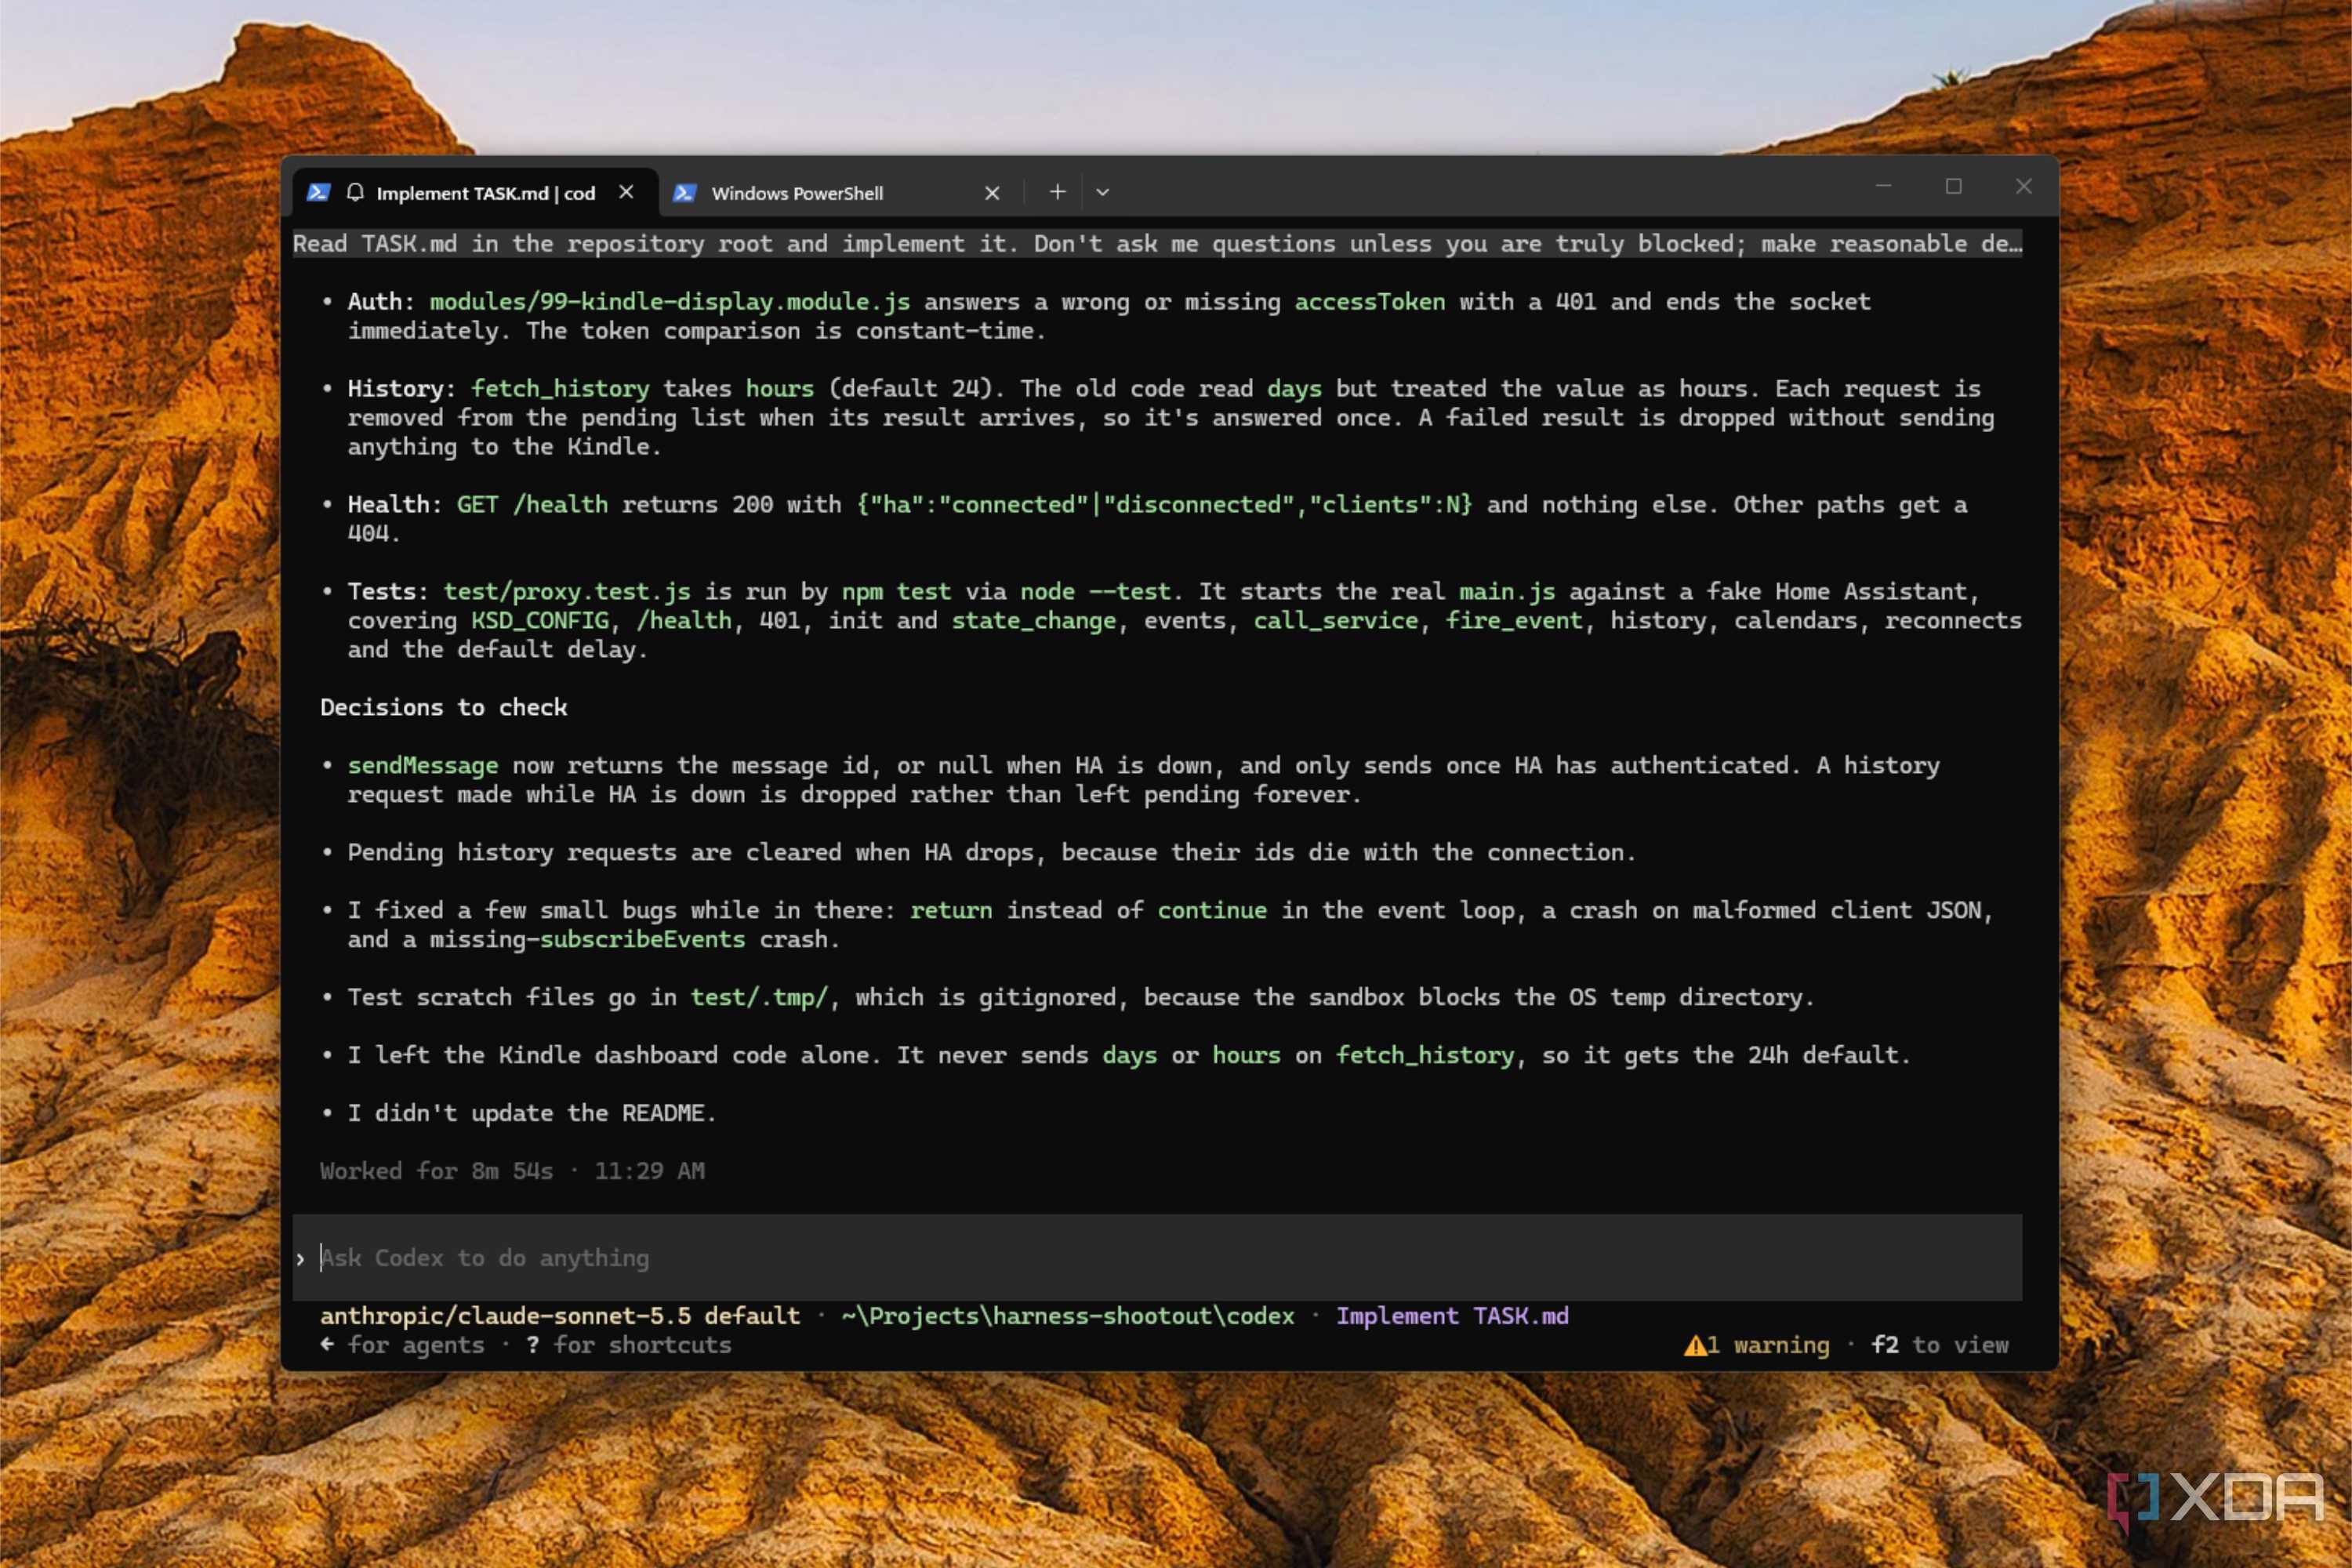
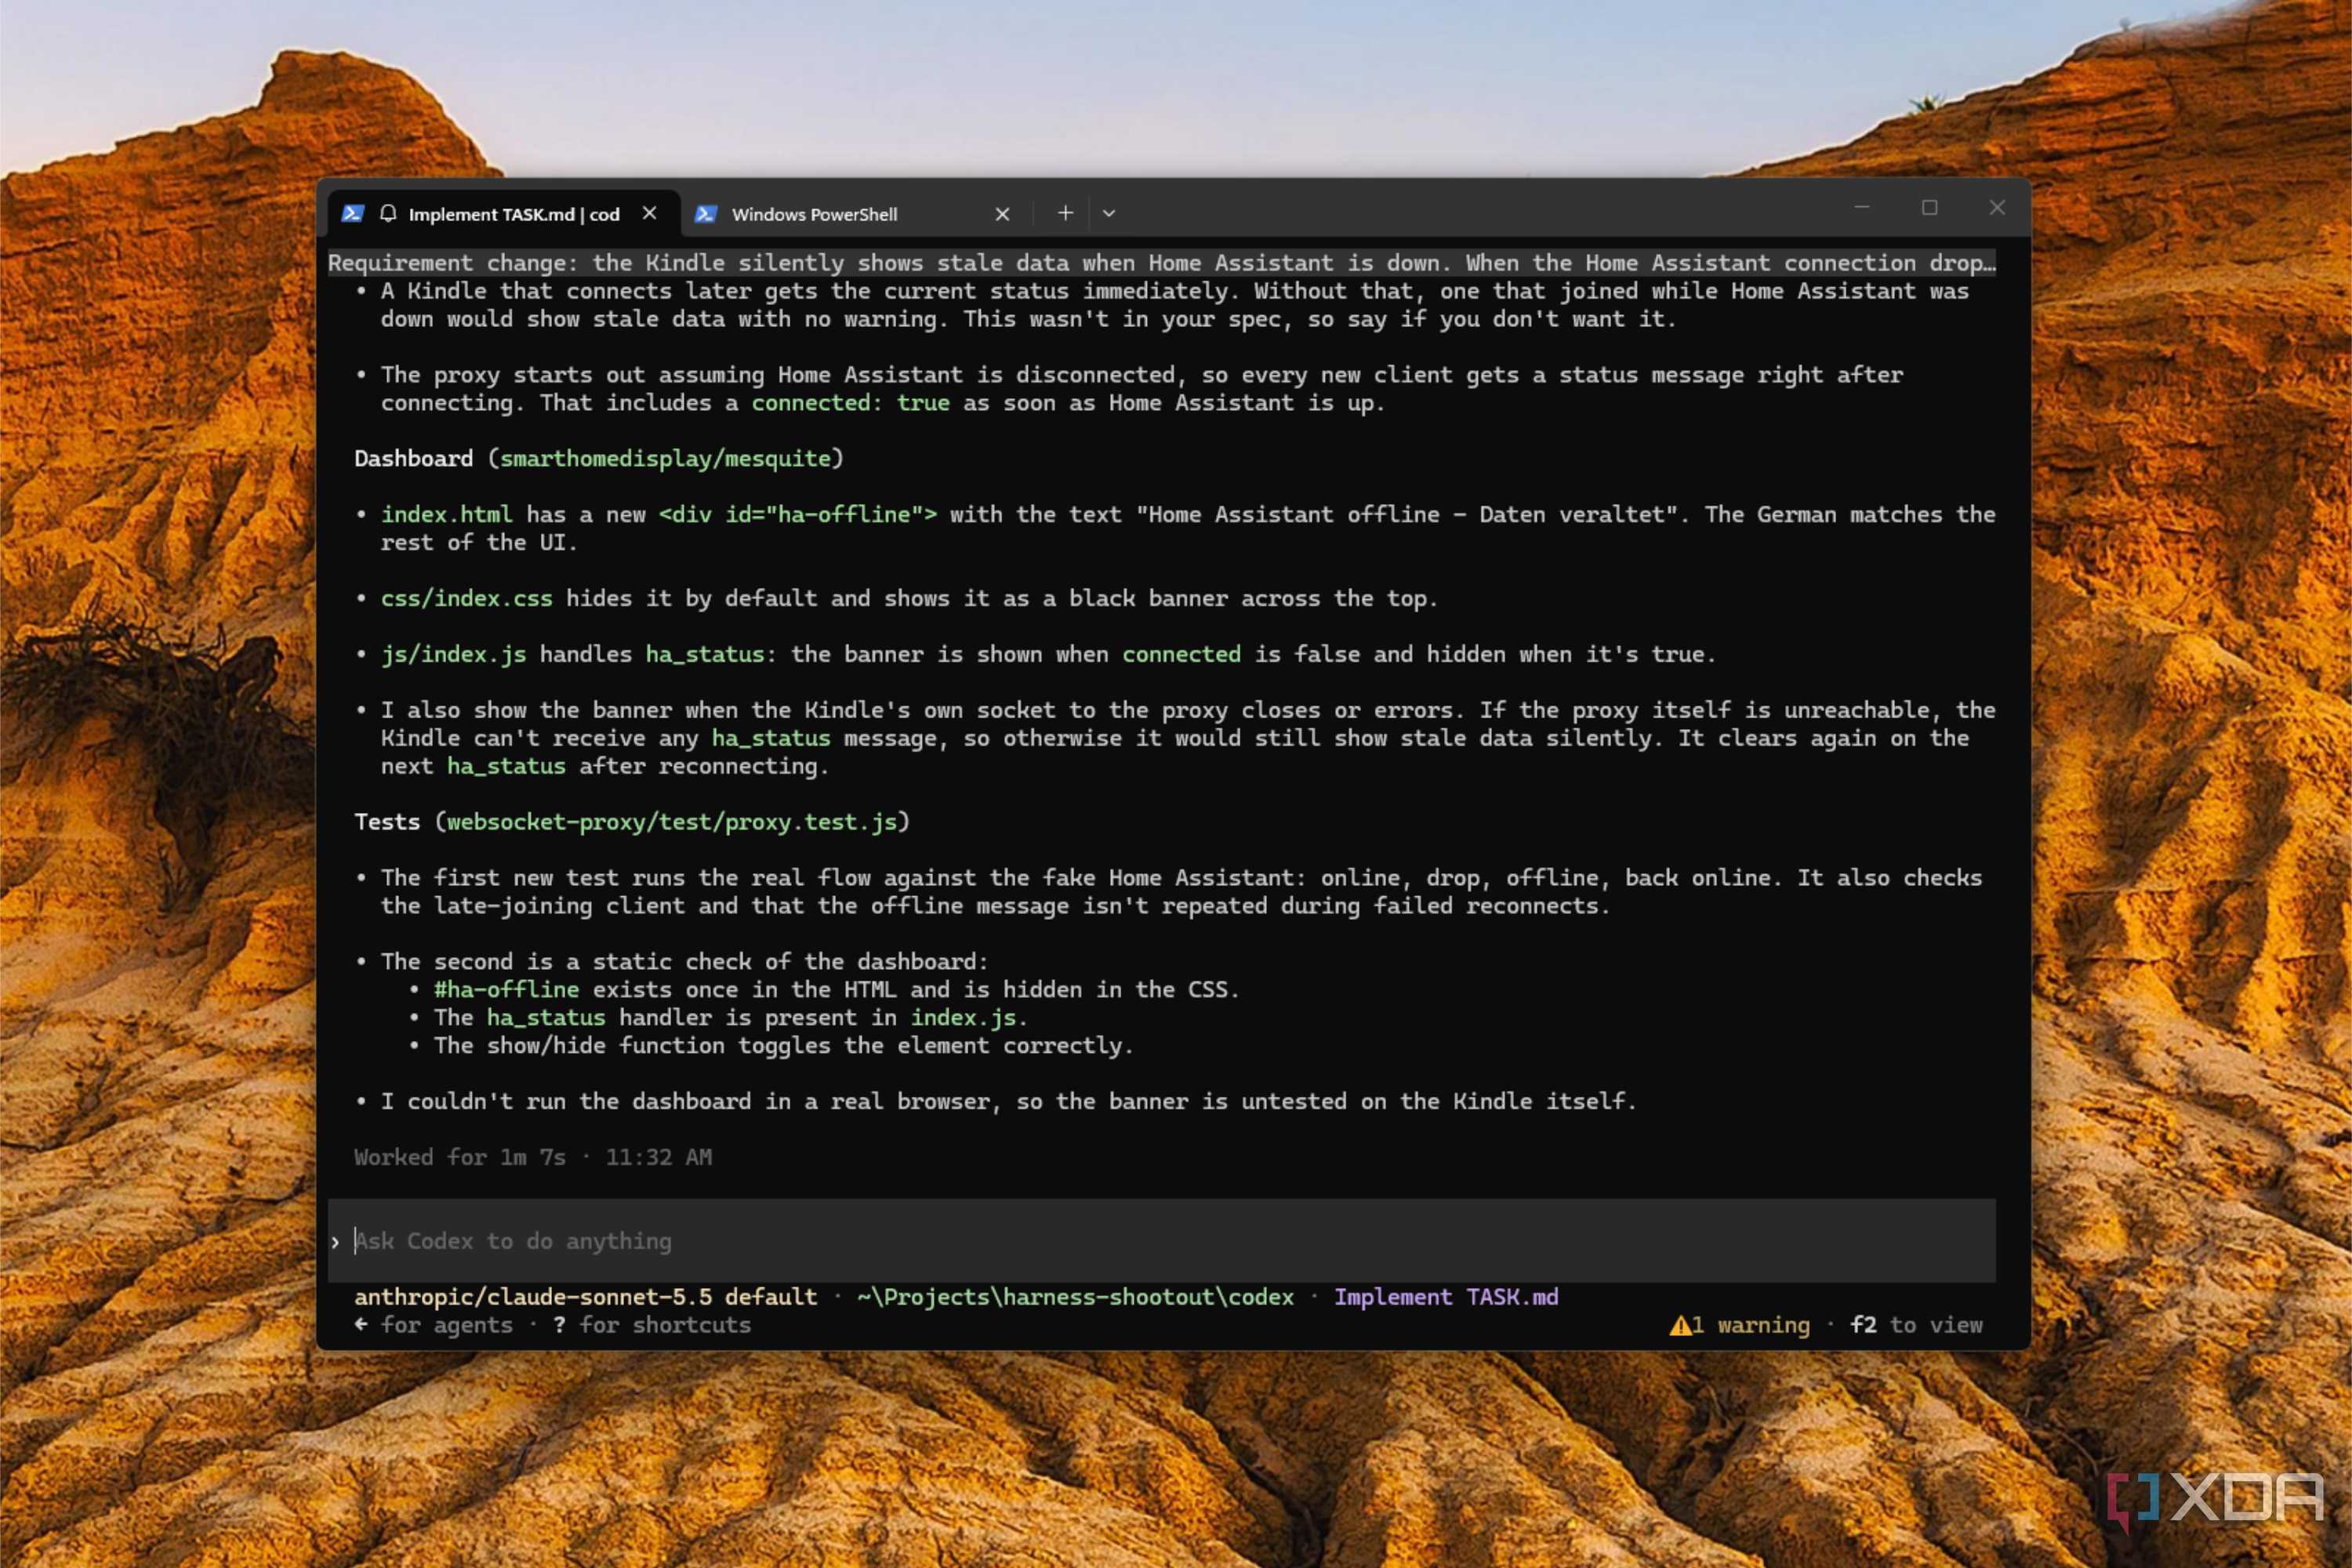
If you were expecting one of the tools to fail, you're going to be disappointed. All three used the same model, and the finished code passed all of my tests. It passed all the additional tests that the harness wrote along the way, although each of the tools decided on different tests to check its own work.
|
Tool |
Tests written by agent |
Tests written by me |
Total time |
|---|---|---|---|
|
Codex |
10 |
16/16 |
≈10:07 |
|
Cursor |
33 |
16/16 |
≈13:01 |
|
Claude Code |
42 (run 3× on the change) |
16/16 |
≈14:33 |
The change to the dashboard was almost identical between the tools, and both Codex and Claude Code used the same function name to build it with. That pattern held for the reconnect fix as well, with the same names used by the same model in three different tools. That's an underlying fingerprint of Sonnet 5.5, not a quirk of the harnesses used.
When fixing the Kindle proxy module, Codex kept most of the original code, deciding that it would patch it instead of rewriting. Both Cursor and Claude Code restructured it into smaller methods. Cursor kept 43% of the original code and said that it rewrote the file in its summary, while Claude Code stripped it back to 34% of the original.
All three tools also added the same unrequested extras. A banner that shows when the Kindle loses connection to the proxy. Fixes for a malformed JSON crash and a return-vs-continue bug, along with a check on the status of the proxy when first connected. None of these were in the TASK.md planning document in the working folder, but it's interesting to see the same model come to the same conclusions about fixing bugs across multiple tools.
Wherever the job was small and clear, the same model wrote almost identical code across the three tools. Where it differed was in open-ended questions, things like how much of an existing file to restructure, how much defensive code to add, and how much additional testing to build.
One other interesting fact. The original repo for the Kindle dashboard was in German. Codex and Cursor used German when rewriting the UI elements of the dashboard, while Claude Code wrote English. Not a huge worry either way, as you could ask the agent to change to your preferred language, and I don't want to speculate as to why each tool handled it the way they did.
Where the tools actually split
Speed, self-checks, and quirks

Think about the last time you had to use a rental car, rather than the one you're used to driving daily. Same driver, different vehicle, and same daily commute. Except it's never exactly the same, is it? Your driving habits are one thing, but fuel economy, ergonomics, and other things come into play.
And that's analagous to what happened here. Sonnet 5.5 wrote almost the same code regardless of what it was driving, but the overall experience was different. Not meaningfully enough that I could say objectively which of the three tools is better, but enough that I have strong feelings over which one I prefer.
|
Tool |
Hidden |
Original task |
Second prompt |
Total |
Tokens |
Cost |
Lines +/− |
|---|---|---|---|---|---|---|---|
|
Codex |
16/16 |
9:00 |
1:07 |
≈10:07 |
1.64M |
$3.73 |
+754 / −74 |
|
Cursor |
16/16 |
11:24 |
1:37 |
≈13:01 |
3.31M |
$1.11 |
+1,218 / −164 |
|
Claude Code |
16/16 |
7:25 |
7:08 |
≈14:33 |
2.55M |
≈$0.96 (API-equiv.) |
+1,179 / −176 |
Codex and Cursor handled things in a similar fashion, with both prompts taking a similar split in how long they took. But Codex only ran ten tests, Cursor ran 33. And Claude Code ended up running 42 tests because it ran the same suite three times to ensure accuracy. Claude Code also put the original bug back into the code, to ensure that the tests it wrote caught the issue. It didn't matter on this occasion, but on messier, larger codebases that could have been the decider between working output code and not.
Both Claude Code and Codex finished before the ten-minute mark for the first test, which meant only Cursor got to test how steering worked with the second prompt. Except, it didn't test steering at all because, by default, it queues the next command instead. I could have changed that, but I wanted to test defaults wherever I could.
And all three tools needed some setup time to get them to behave on Windows. Codex ignored the --ask-for-approval flag until I added it to the TOML settings file, then the server crashed because it couldn't launch PowerShell without an environment value being set. Claude Code prefers Bash, so I had to set a flag for it to use PowerShell instead of it trying to use WSL. Cursor opened the run in ask for approval mode, even though I had set it to auto.
Pricing wise, it's probably not a surprise that Claude Code was the cheapest to use Sonnet 5.5 with. What I didn't expect was that Codex would pay full price for its OpenRouter method, with seemingly no tokens coming from cache reads. And Cursor might have made me pay for the $30 premium plan to run third-party models via an additional API billing cost, but it looks like it cached tokens because I paid $1.11 for roughly 3.31 million tokens, compared to $3.73 for 1.64 million tokens on Codex/OpenRouter. The only way that math works is if most of those Cursor reads were from the cache.
Which of the three I'd hand a real repo to
Every tool created working code, with not much to decide between them. That means which tool to use depends on your preferences, whether that's minimal diffs and speed (Codex), an agent that checks its own work (Claude Code), or you prefer to work in an IDE and don't mind a higher overall cost (Cursor). Out of the three, I feel more at home in Claude Code, but it's still not perfect. I don't like how it gives me summaries instead of detailed planning, which is why I do most of my agentic coding in Crush.