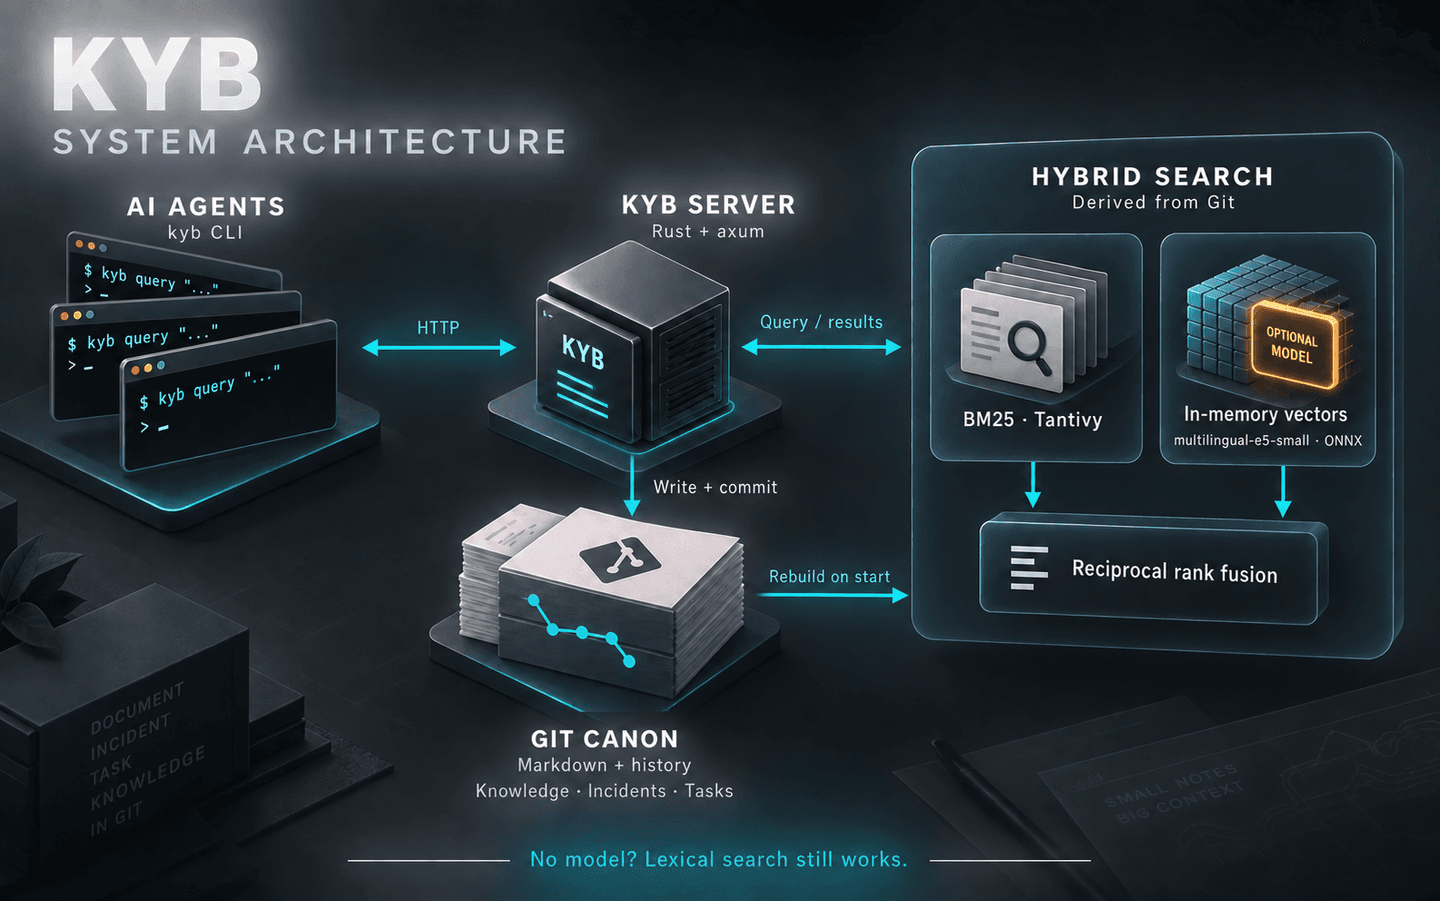
I work with Claude Code, OpenAI's Codex coding agent, and Google's Antigravity IDE. I wanted a solution found in one session to stay found, so the next session wouldn't have to dig it up all over again. I'm the author of KYB — Know Your Business, a shared knowledge base I built with these agents for that purpose. When I say "we" below, I mean the agents and me.
Saving an entry turned out to be only the beginning. First, an agent could miss an entry because of the language of its query. Then Antigravity skipped an installed guide because of a YAML error. And in October, a check showed that "as of a date" search could return text that had already been replaced. Each time, the data was already in the base; what broke was the next step between writing it down and getting it back to an agent.
This story follows internal KYB entries and saved session reports from July to October 2026, with links to public code changes where available. The internal records are not published.
July: A Shared Base and the First Search Misses
By July 20, I was already keeping working knowledge in a local KYB instance. That day, its entries moved to a shared server. The base held instructions, decisions, and write-ups of mistakes: where a service runs, how to update it, why an earlier approach didn't work out. At this stage, all three environments used kyb, the command-line interface (CLI), to access that base. MCP support came later, in September.
It mattered to me that the content stay plain text. So a KYB entry is a Markdown file, and its changes are stored in Git. The updated text becomes the current version; the previous version can be opened by its commit ID. The search index is built separately and can be rebuilt from the stored data. KYB's source code is open.
This is just one way to design memory. In Agents have Amnesia. I Gave It a RocksDB, the author stores knowledge in RocksDB; a graph-vector implementation uses ChromaDB and Neo4j. For my workflow, I wanted readable files and a straightforward way to compare revisions.
That same day, a specific miss was recorded in KYB: the query knowledge base returned nothing in cases where the Russian реестр знаний ("knowledge registry") worked. The base mixed Russian and English entries, while keyword search matched the words actually written in them; translating the query could lose that match. We agreed to write entries in English and keep exact technical names as they are.
Questions, though, could still be asked in Russian. For cross-language search, we chose the multilingual-e5-small model. It turns a question and an entry into numerical representations so they can be compared by meaning, but it doesn't write the answer itself. In KYB, the model runs locally on ONNX Runtime, and its results are merged with keyword search built on Tantivy.
The two reported search checks are easier to read side by side. Top-1 counts questions for which the expected entry ranked first:
|
Check |
Query language |
Knowledge base |
Keyword top-1 |
Hybrid top-1 |
|---|---|---|---|---|
|
July 20, internal note |
Russian, as described in the note |
English entries; size not specified |
2/14 |
9/14 |
|
September 22, published README |
English in the published script |
643 entries |
1/14 |
3/14 |
These are separate checks, not a controlled before-and-after comparison. The documented query languages and bases differ, and three expected keys were missing from the September base. The July note contains no separate result for the original knowledge base / реестр знаний query pair.
The September README also says an earlier table reported 9/14 for hybrid top-1. It explains that those scores came from the base the example questions were written for and did not reproduce elsewhere. The matching number does not establish that this was the same run as the July note. It does show why a search score needs its dataset and conditions attached: otherwise a result from one base reads like a promise about every base.
August: The Guide Was Installed, but the Agent Skipped It
Back on July 20, so that the agents would know the base existed, a short pointer was added to each environment's always-loaded instructions: first check what's already known, then save any verified refinement back. Instructions for using the KYB CLI lived in a separate guide, SKILL.md.
On August 16, a bug in that guide was analyzed in its own incident report. The file was where it should be, but Antigravity skipped it because of a parse error. When the installed copies were checked, Ruby's Psych YAML parser reported:
mapping values are not allowed in this context
The cause was the description at the top of the file. It had been written as one long unquoted line, and somewhere inside it was Triggers, in any language: "remember this". A colon followed by a space isn't allowed inside that kind of unquoted YAML value.
The description was rewritten as a text block. Here's an excerpt from the actual fix; long stretches are abbreviated where you see …:
-description: Our internal infrastructure knowledge base — … Triggers, in any language: "remember this", …
+description: >-
+  Our internal infrastructure knowledge base — …
+  Search it before reasoning about our infra; write back verified facts, …
+  Use for questions about our hosts, … including requests such as "remember this", …
In a block like this, ordinary line breaks fold into spaces, and a colon inside the text is allowed. The fix also rewrote the list of requests without a colon. The installer started checking for the description: >- form before copying and in every installed copy. Its validator also uses Ruby's Psych for an independent YAML parse when Ruby is available.
Claude Code and Codex had malformed files too, but the recorded observation that the guide was being skipped applies specifically to Antigravity. After the fix, fresh sessions were started in all three environments. By their own reports, Claude loaded the guide, Antigravity and Codex saw KYB in their skills lists, and all three checked their connection to the server. That confirmed availability. Whether an agent will actually turn to the base during everyday work is a separate question.
September: The Fix Is There, but the Wrong Text Still Comes First
Correcting entries revealed a different trap. The September write-up records two cases from a single entry about Git commit attribution. First, a correct explanation was added below an incorrect table, while the table itself stayed at the top. Then came a faulty recommendation: change both the author and the committer of every commit, which would have been wrong for commits where GitHub itself was the committer. Once again, the caveat was added as the next section, while the heading above it still claimed the opposite.
Here is the shape of that contradiction, simplified rather than quoted from the record:
Main instruction:
  Change the author and committer of every commit.

Caveat added below:
  Preserve the committer when it is GitHub.
The correction was in the document. But a reader who stopped at the first section still got the old claim. The write-up itself notes that the second case happened within an hour of the first one being discussed. Naming the mistake did not prevent it from happening again.
We came up with a simple rule: replace the wrong text in the current entry, then search for the retracted wording. Asking "did we add the correct paragraph?" is too weak a check, because that paragraph can sit below the error. Git history already exists for the old text; there's no reason to keep two incompatible recommendations in the current version.
On its own, this rule doesn't keep the whole base in order. While preparing this article, I also ran into the same operational snippet, copied into two entries: later, a note marking a mode as obsolete was added to only one of them. Each file's history was preserved, but the fix didn't automatically carry over from one copy to the other.
October: Search Returned a Version That Had Already Been Replaced
Even careful editing turned out not to be enough. The KYB CLI exposes point-in-time search through kyb query --as-of. It is supposed to return results from whichever version of each entry was current at the chosen moment. That's different from searching the full history, where old wording is exactly what you're after.
On October 11, during release testing, a temporary entry was created containing the artificial word amberquartzreviewoldterm. Two seconds later, the word was replaced with cobaltquartzreviewnewterm. Both texts were stored in Git. The recorded test result says that searching for the old word as of a moment after the replacement still returned the first version.
The bug was in the order of operations. Search first found the versions containing the query word, then picked the latest of those. The new version no longer contained the old word, so it was filtered out at the first step. That left the old version as the only candidate: an accurate quote from the wrong point in time.
For this test, the expected behavior can be shown without going into the search engine's internals:
R1: the entry contains the old word
R2: the old word is replaced with the new one
T:  a moment after R2

Search for the old word as of T: nothing
Search for the new word as of T: R2
Search for the old word across the full history: R1
PR #17 reversed the order: first select each key's version as of the date, then search within the selected versions. The PR also describes a regression test that failed on the old code. The saved result of the post-release check reports the expected outcome: the old word no longer returned the replaced version, the new word found R2, and the history search still found R1.
What This Doesn't Prove
The October check used a temporary entry. It exposed a search bug, but it did not establish that an agent had changed a live system based on a stale answer. I did not rerun the historical tests for this article.
In a directed check the next day, a fresh Claude session read two July versions of a NATS rule and identified the added rationale. The rule also appeared in global instructions, so the answer cannot be credited to KYB alone; neither this exercise nor the installation checks measured a reduction in repeated mistakes across agents.
These days I check three things after correcting an entry:
- Was the wrong claim removed from the current text?
- Is a copy of it still present under another key?
- Does search return the version that was current at the requested time?
An old version of an entry is useful when I'm the one opening the history. The trouble starts when it reaches the next agent as the current answer.
Code and setup instructions: KYB on GitHub.