
Most large language models (LLMs) use transformer architectures with softmax attention. During inference, their key-value (KV) cache grows with the conversation or document context. This can reduce concurrency, increase serving cost, and force agentic applications to discard useful history.
i14 designed Laplace 3B as a linear attention alternative. Its recurrent state stays at 29.5 MB per sequence, independent of context length. Working with AWS, i14 used native PyTorch support through TorchNeuron Native to bring this custom architecture to AWS Trainium2. This preserved its Gated Linear Attention (GLA) design and Muon optimizer.
On one trn2.48xlarge instance, Laplace 3B trained at about 120,000 tokens per second. The model served 11,544 output tokens per second across 1,280 concurrent sequences. This post explains the model design, the changes i14 made for Trainium2, and the training and inference results.
About i14
i14 is an AI research and technology company that develops model architectures, components, and runtimes. Its work draws on AI, computational cognitive science, and research into how biological systems learn over time. i14 applies these ideas to models that can retain long-range context without allowing serving state to grow with every token.
Why linear attention models?
Transformer softmax attention compares tokens across the context. During training, this computation grows quadratically with sequence length. During inference, the KV cache grows as the model processes more tokens.
Linear attention reorganizes the computation around a recurrent state that is updated for each token. Laplace 3B uses GLA to compress prior context into a fixed-size matrix state. This changes training attention from O(T2) to O(T) and keeps inference state fixed at 29.5 MB per sequence.
| Consideration | Transformer softmax attention | Laplace 3B with GLA |
| Training attention | Builds pairwise token scores with O(T2) scaling | Updates chunked recurrent state with O(T) scaling |
| Inference memory | KV cache grows with context | Recurrent state remains fixed in size |
| Longer contexts | Each sequence consumes more accelerator memory | Context length does not increase recurrent-state allocation |
| Implementation | Uses widely optimized attention kernels | Requires architecture-specific kernels and compiler tuning |
Linear attention compresses history rather than retaining every key and value. You must therefore evaluate retrieval quality for your workloads. The fixed state can benefit long-running agents, large-document analysis, and applications that need persistent memory with predictable serving requirements.
How i14 adapted Laplace 3B for AWS Trainium2
The original implementation of Laplace 3B used GPU-optimized Triton kernels. The AWS Generative AI Innovation Center (GenAIIC) team first rewrote the GLA kernel with standard PyTorch operators for Trainium2. After comparing both approaches, the team chose the beta version of TorchNeuron Native, the native PyTorch backend for AWS Trainium, because it performed better.
The implementation required three changes:
- Using native PyTorch for the GLA attention kernel. The team replaced the GPU-specific fused_chunk_simple_gla Triton kernel with standard PyTorch operators, using 16 chunks of 128 tokens to match the 128 partitions of the NeuronCore on-chip buffer.
- Redesigning how Muon communicates. Two all_to_all collectives in MuonFSDP2 cut per-rank traffic by 24 times and raised throughput by 1.63 times.
- Compiling the sequential backward pass. The team statically unrolled the 16 chunk steps of the GLA recurrence to fit the graph-size and on-chip memory limits of the compiler.
The engineering challenges section describes each change in detail.
Why AWS Trainium accelerators?
AWS Trainium is a family of AWS machine learning (ML) accelerators designed for model training and inference. A trn2.48xlarge instance combines 16 Trainium2 chips, 64 logical NeuronCores, high-bandwidth memory, and NeuronLink-v3 connectivity. These resources support the distributed training and inference configurations described in this post.
Three properties of Trainium2 shaped the implementation: software-managed on-chip memory (Challenge 1), a fast chip-to-chip interconnect (Challenge 2), and a static compiler (Challenge 3). The compiler traces the GLA recurrence as a fixed graph.
Software-managed on-chip memory. Each NeuronCore has a 28 MiB State Buffer (SBUF) with 128 partitions and a 2 MiB partial-sum buffer (PSUM). The PSUM is wired to a 128×128 systolic Tensor Engine, alongside separate vector and scalar units. The SBUF is not a cache: the compiler schedules every HBM-to-SBUF transfer ahead of time, so the data is in place with no evictions or misses (Figure 1).
Figure 1: NeuronCore-v3 internal architecture. Software-managed SBUF (28 MiB, 128 partitions), Tensor Engine (128×128 systolic array), Vector Engine, Scalar Engine, and GPSIMD cores.
i14 and the Laplace 3B architecture
Laplace 3B is the 24-layer i14 decoder, where every layer replaces softmax attention with Simple GLA. Figure 2 follows one layer from the input xt at the top to the output xt + 1 at the bottom. This section explains each module: normalization and convolution, the QKVG projection, the GLA mixer, and the feed-forward channel mixer.
Normalization and convolution. Each token’s residual-stream vector xt ∈ ℝD (D = 3, 072) passes through a LayerNorm and a depth-wise causal Conv1d of width k = 4 with SiLU. This gives every position a 4-gram summary before the mixer. The GLA mixer then does content-based retrieval over the whole history through its decaying state.
QKVG projection. The post-conv output goes through one fused matrix Wqkvg ∈ ℝ9, 216 × 3, 072, where 9, 216 = H × (2dk + 2dv). It splits into four per-token streams: queries qt, keys kt, values vt, and a gate gt (H = 16, dk = 96, dv = 192). The gate is used after the mixer.
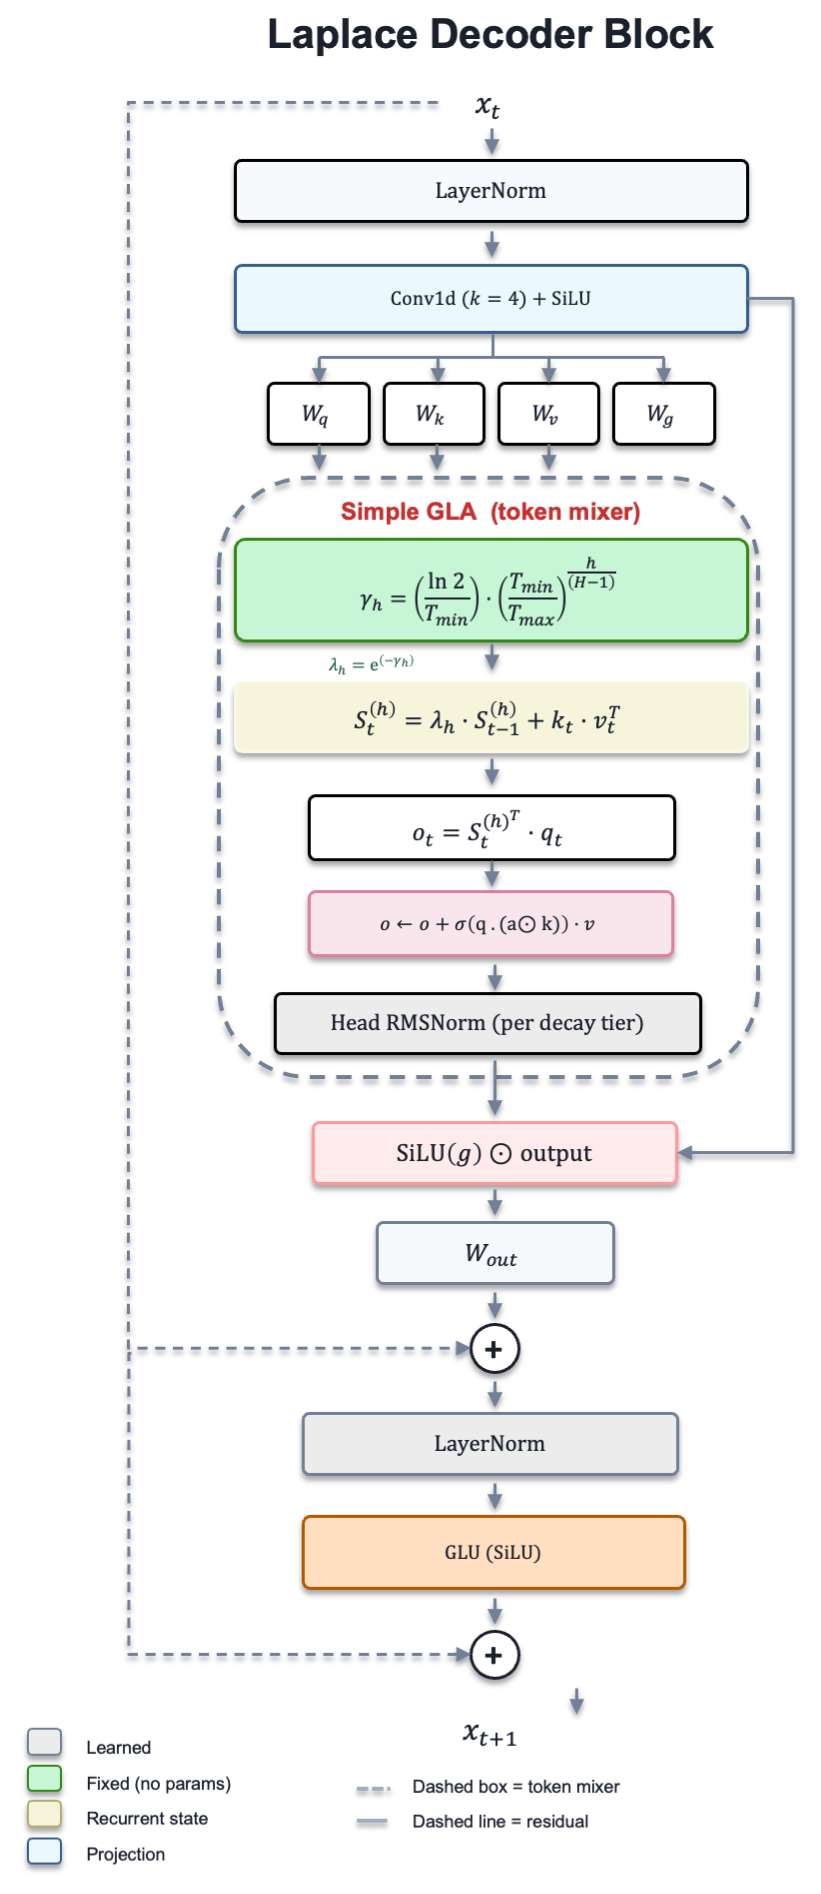
Figure 2: Laplace decoder layer architecture. Green = fixed (no params), gray = learned, yellow = recurrent state, blue = projection.
GLA mixer. Each head h keeps a matrix state St(h) of size dk × dv (96 × 192), a compressed, decaying record of past key-value pairs. At each token, it updates as:
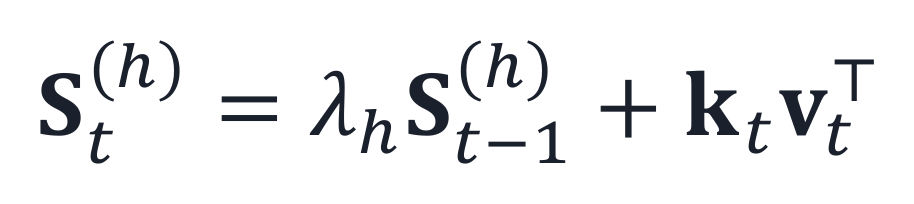
GLA recurrent-state update equation
Here λh is the fixed per-head decay, and ktvt⊤ is the rank-1 outer product that writes the current key-value pair into the state. The readout queries the state:
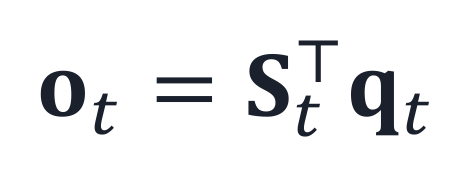
GLA state-readout equation
Next, a self-augmentation step adds a gated copy of the value to each head’s output:
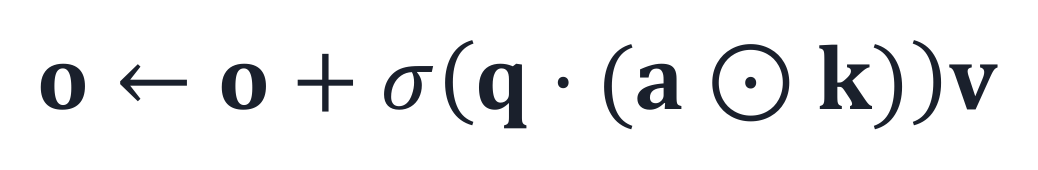
GLA self-augmentation equation
Here σ is the sigmoid and ⊙ is the element-wise product. The gate is the query dotted with a learned per-channel rescaling of the key, where a is the learned scale (aug_balance). At initialization, a = 0, which gives a half-strength skip of the value. The per-head outputs pass through a Head RMSNorm within each decay tier, are concatenated, gated by SiLU(gt), and projected by Wout ∈ ℝD × D back to the residual stream.
Decay schedule. The per-head decay rate λh controls how fast a head forgets past tokens. It is fixed at initialization (not learned) and set by a geometric schedule. The schedule gives the 16 heads a spread of memory lengths and defines each head’s log-decay rate γh:
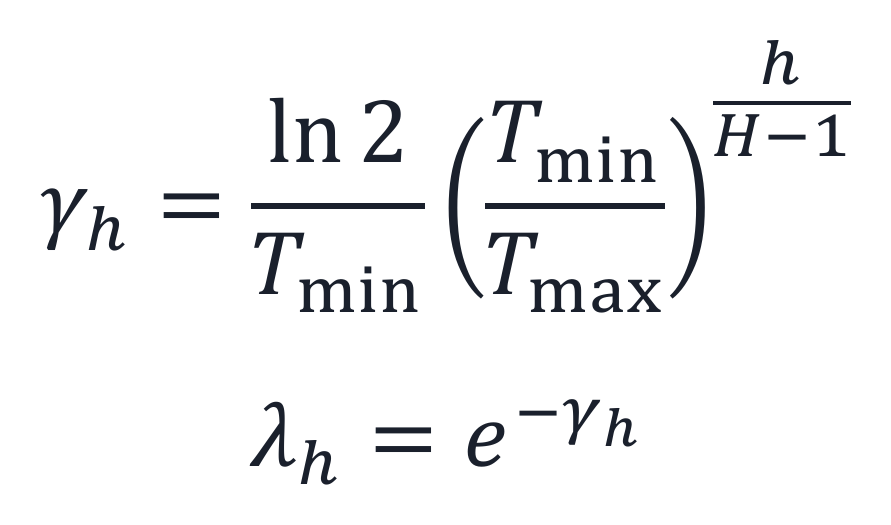
GLA decay schedule equations
Decay schedule’s reach. For this model, Tmin = 1 and Tmax = 2, 048. Head 0 therefore has λ0 = 0.5 (half-life of one token), and head 15 has λ15 ≈ 0.9997 (half-life of 2,048 tokens). Heads are grouped into tiers, each sharing a Head RMSNorm.
Channel mixer (FFN). After the attention block and its residual, a second LayerNorm feeds a GLU (SiLU) FFN with inner dimension 8,192. Its three matrices are two up-projections W1, W2 ∈ ℝ8, 192 × D and one down-projection W3 ∈ ℝD × 8, 192. A second residual follows.
The state S(h) is fixed at dk × dv = 96 × 192 per head regardless of sequence length. As a result, inference is O(1) per token, and training is O(T) rather than O(T2).
| Parameter | Value |
| Parameters | 3.028B total (2.718B Muon + 309.6M AdamW) |
| Layers | 24 decoder layers, D = 3, 072 hidden dim |
| Heads | 16 heads, dk = 96 (half-width Q/K), dv = 192 (full-width V) |
| Mixer | Simple GLA with fixed geometric decay (Tmin = 1, Tmax = 2, 048) |
| Conv | Depth-wise causal Conv1d, kernel width 4, SiLU |
| FFN | GLU (SiLU), inner dim 8,192 |
| Norm | LayerNorm pre-attn + Head RMSNorm (per tier) + LayerNorm pre-FFN |
| Vocab | 50,304 (padded to multiple of 64) |
| Sequence | 2,048 |
| Training data | 100B tokens, FineWeb-Edu |
| Optimizer | Muon for 2D weight matrices; AdamW for embeddings, norms |
| Batch size | 524,288 tokens/step, cosine LR, 3,815-step warmup |
Engineering challenges
Each of the three changes raised its own engineering challenge.
Challenge 1: Using native PyTorch on Trainium for GLA
On GPU, GLA runs as the fused Triton kernel fused_chunk_simple_gla from the flash-linear-attention library. The GenAIIC team re-expressed it with standard PyTorch operators running through TorchNeuron Native, as explicit loops over fixed-size chunks. The chunk count is fixed at compile time and sets the backward-unroll depth. The team uses fla_num_chunks = 16, so each chunk holds C = 128 tokens.
Within each chunk c, the intra-chunk output is masked linear attention, and the running state S adds earlier context:
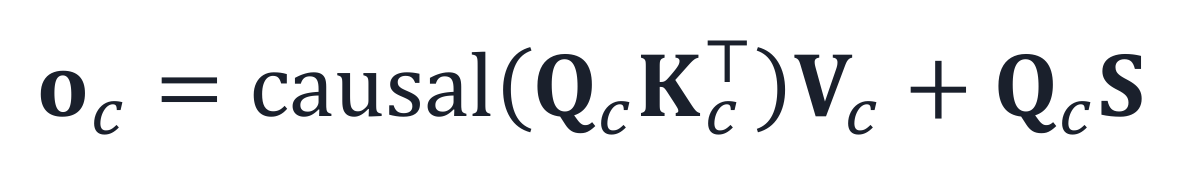
Chunked GLA intra-chunk output
The state then advances to the next chunk:
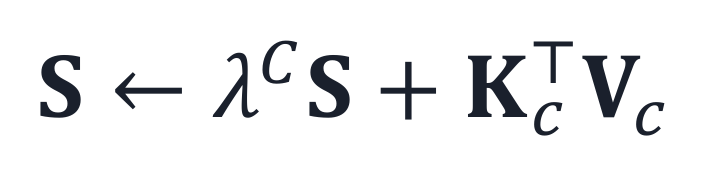
Chunked GLA state update
Here λC is the per-head decay compounded over the chunk. The 16 intra-chunk computations run in parallel, and only the state update is sequential (Figure 3).
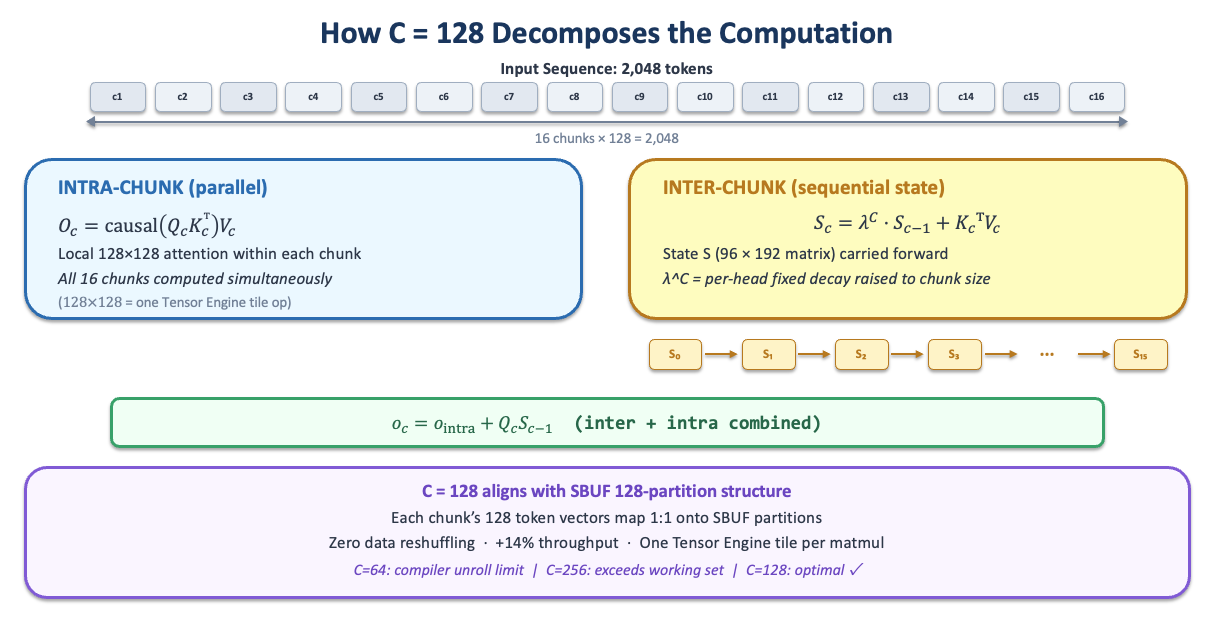
Figure 3: GLA chunked recurrence with parallel intra-chunk attention and a sequential state chain.
Because the SBUF has 128 partitions, each 128-token chunk maps one token per partition, with no padding or cross-partition movement. This alignment increased measured throughput by 14 percent (Figure 4).
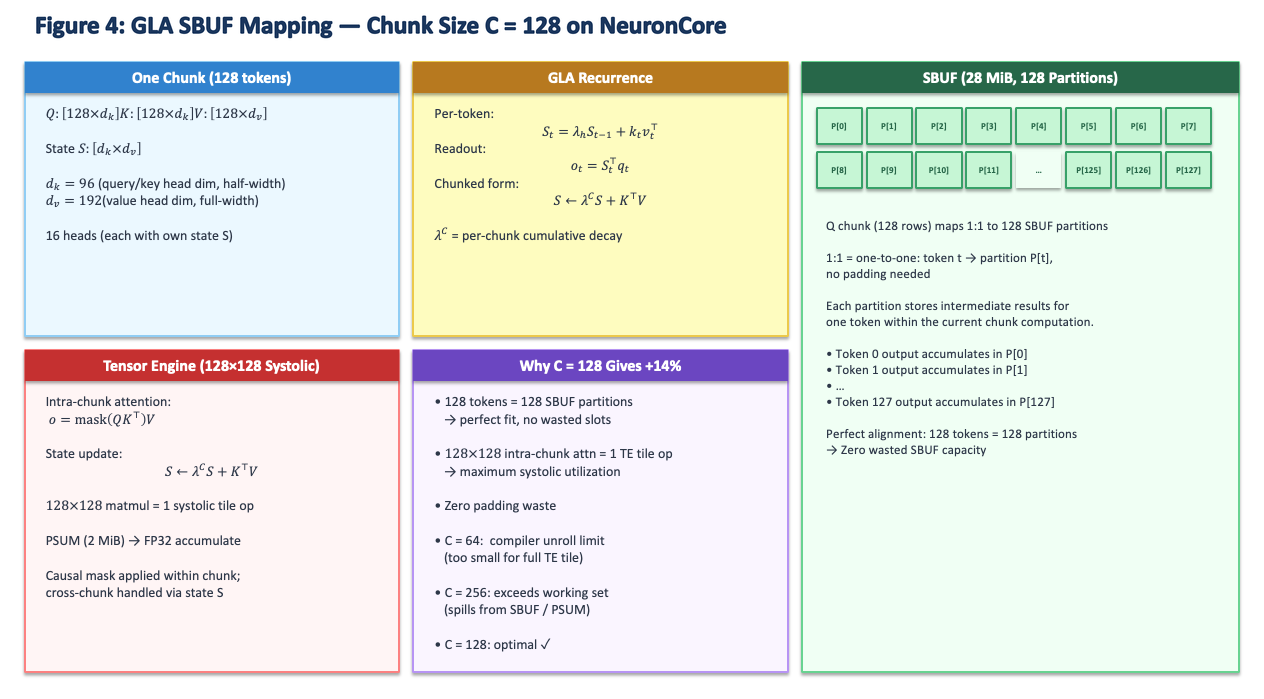
Figure 4: Chunk size C = 128 maps one-to-one onto the 128 SBUF partitions.
Challenge 2: Distributed Muon orthogonalization under FSDP2
Muon orthogonalizes each gradient before the update. For each of the 96 two-dimensional weight matrices (2.718 billion parameters), it runs five Newton–Schulz iterations (Algorithm 1).
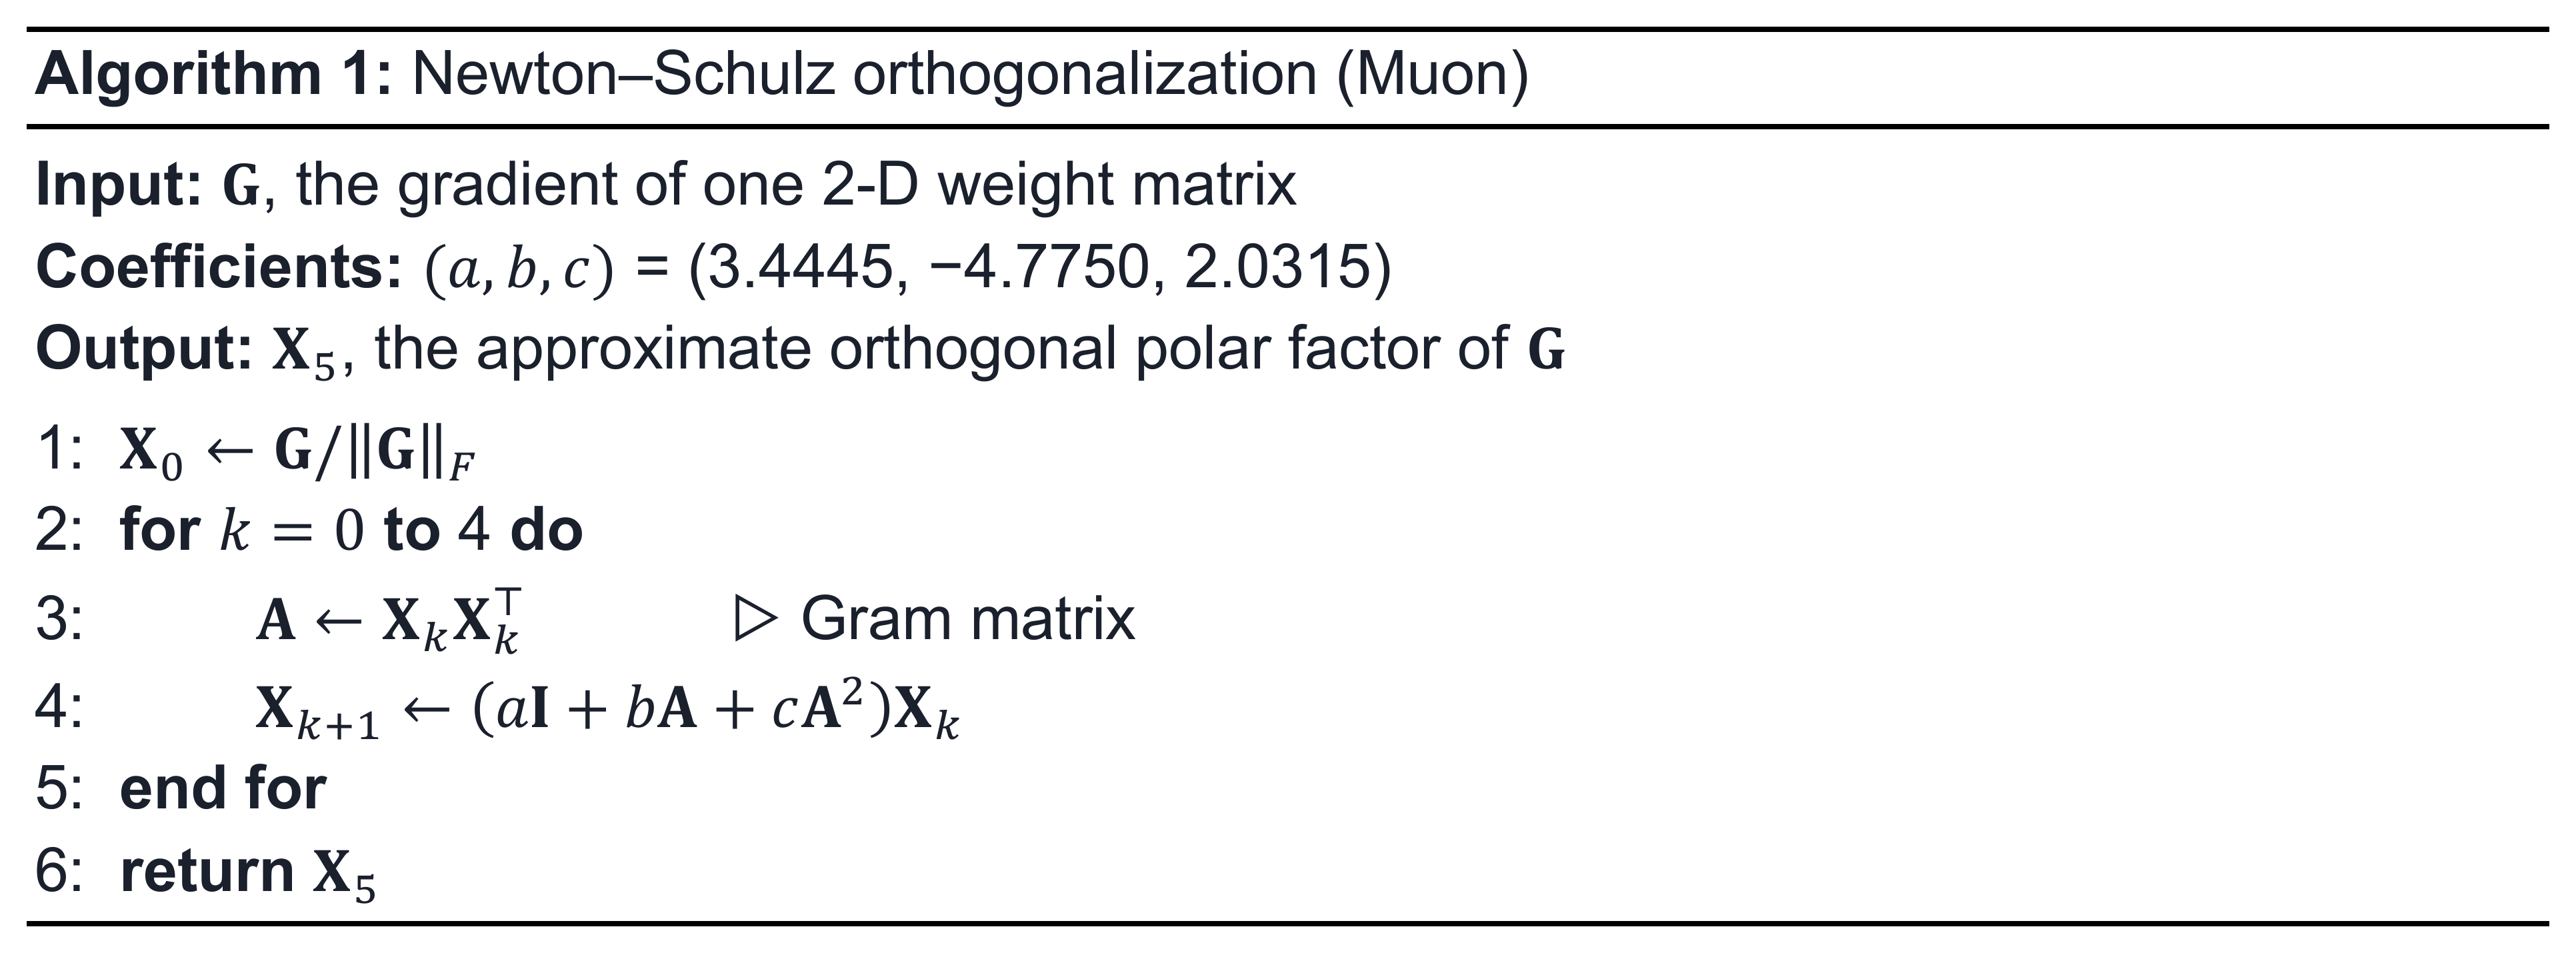
The Newton-Schulz algorithm
The distributed problem. The Gram matrix A = XX⊤ correlates every row of the weight with every other row. Under Fully Sharded Data Parallel (FSDP2), each of the 64 ranks holds only 1/64 of the rows. A shard-local XX⊤ therefore yields only a diagonal block and drops every cross-shard term (Figure 5).
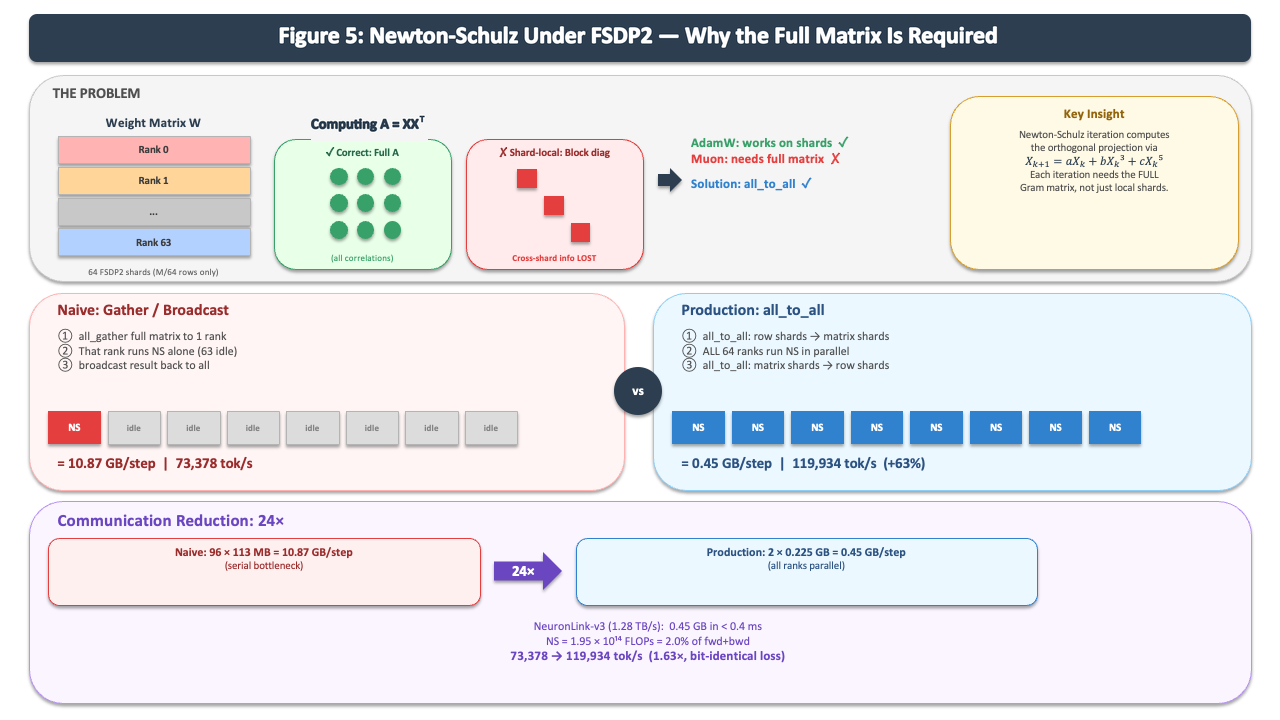
Figure 5: Newton–Schulz under FSDP2: the shard-local Gram block, and gather/broadcast compared with all_to_all.
Naive approach: Gather and broadcast. Every rank gathers the full gradient (5.44 GB), one rank runs Newton–Schulz, and it broadcasts the result. This moves 10.87 GB per step while the other 63 ranks wait.
Production approach: all_to_all transposition. In MuonFSDP2, one all_to_all gives each rank a few complete matrices, all 64 ranks run Newton–Schulz in parallel, and a second all_to_all returns the results. Per-rank traffic drops to 0.45 GB, 24 times less. Throughput rises from 73,378 to 119,934 tokens per second, 1.63 times higher, with a bit-identical loss curve (Figure 6).
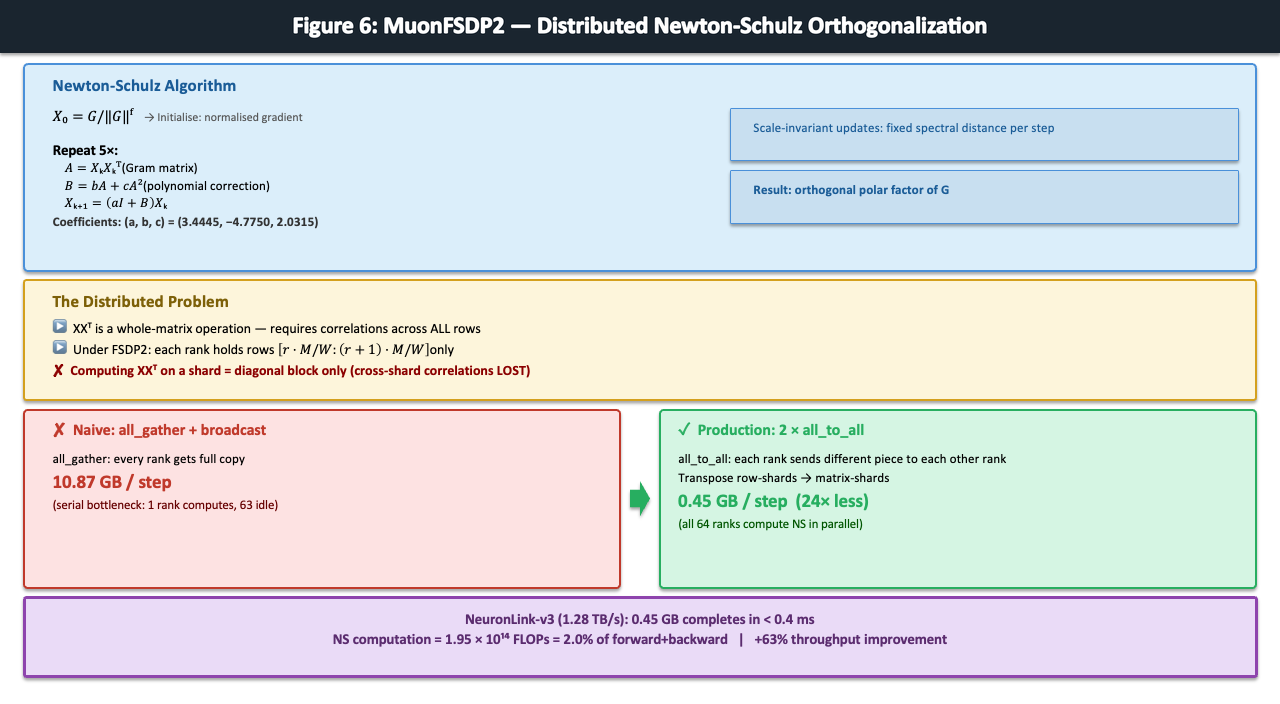
Figure 6: Per-step communication volume: 10.87 GB with all_gather compared with 0.45 GB with all_to_all.
Communication cost. Newton–Schulz is only about 2 percent of the FLOPs in a training step (1.95 × 10¹⁴ of 9.53 × 10¹⁵), so communication was the bottleneck. Over NeuronLink-v3 at 1.28 TB/s, the 0.45 GB exchange takes under 0.4 ms of the roughly 4.4-second step.
Challenge 3: Backward-pass unrolling for a sequential recurrence
The backward pass differentiates through all 16 sequential state updates. On GPU, autograd builds this graph at runtime. On Trainium2, the compiler must see the whole unrolled 16-step graph in advance, which creates three constraints.
Graph depth grows with chunk count: at 32 chunks (C = 64), the graph overflowed the scheduler. Per-chunk memory grows with chunk size: at 8 chunks (C = 256), intermediates spilled into HBM. Every shape is fixed at trace time, so each loop intermediate needs its own static allocation.
Sixteen chunks (C = 128) satisfy all three: the unroll fits the scheduler, intermediates stay on chip, and tiles align with the 128 SBUF partitions.
Training results
The GenAIIC team trained Laplace 3B on one trn2.48xlarge instance using all 64 logical NeuronCores and the all_to_all Muon path. The full recipe is 190,735 steps (100 billion FineWeb-Edu tokens). The following results are through step 84,210, about 44 billion tokens.
Throughput. After compilation warmup, throughput settles at roughly 120,000 tokens per second and holds there through step 84,210.
Loss and gradient stability. The loss (Figure 7a) drops smoothly from about 11.4 to 2.3729 at step 84,210. The gradient norm (Figure 7b) shows the expected early spike then a steady decline to about 0.05, with no post-warmup spikes, divergence, or NaN/Inf values.
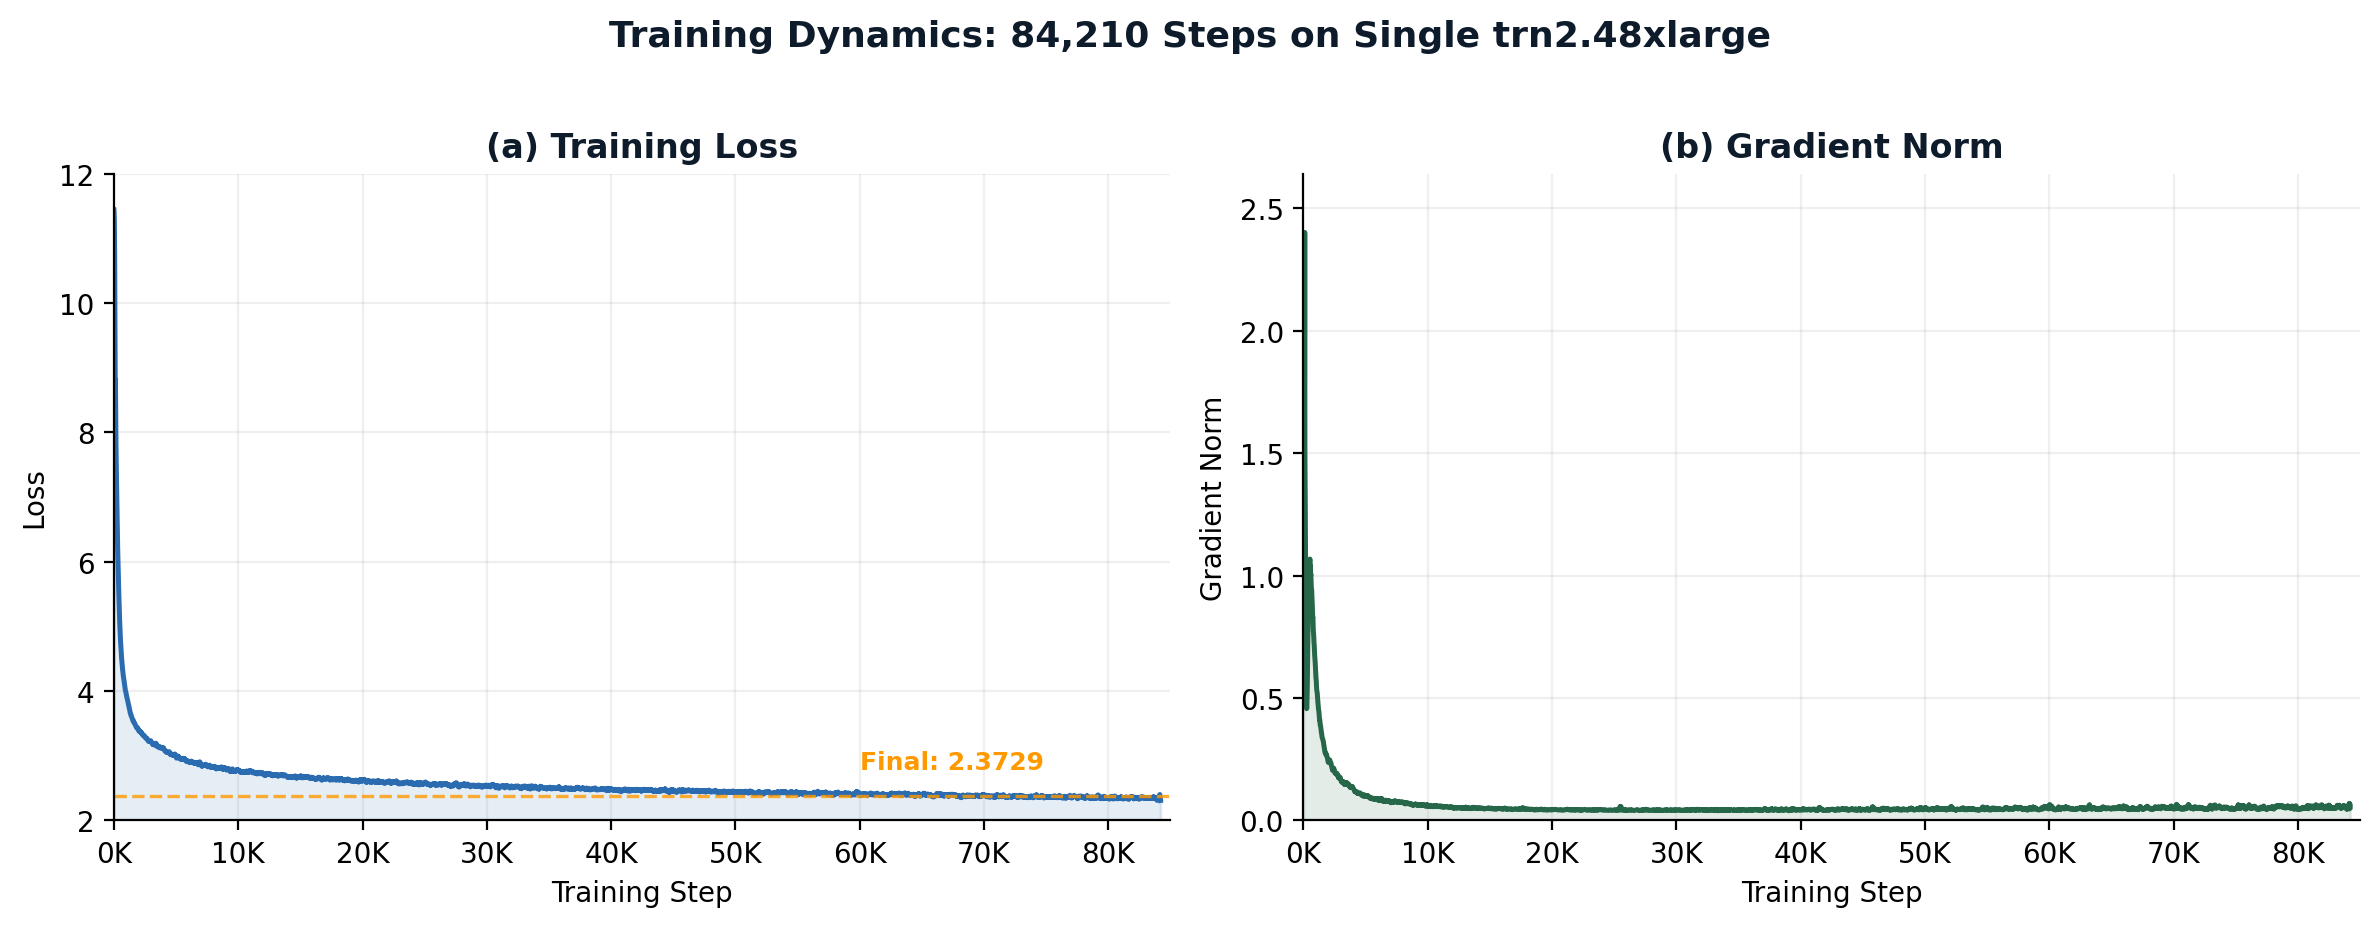
Figure 7: Training dynamics. (a) Loss 11.4 → 2.3729. (b) Gradient norm from TensorBoard data.
Inference optimization on Trainium2
Through an unmodified vLLM engine, the GenAIIC team served 11,544 output tokens per second at 1,280 concurrent sequences on one trn2.48xlarge instance.
Constant serving state. The 29.5 MB recurrent state per sequence is roughly 82 times smaller than a comparable KV cache at 8,192 tokens. Increasing the prompt from 2,048 to 8,192 tokens added only 0.5% to the cost per output token.
Unmodified vLLM. A wrapper replaces one attribute per decoder layer, the token mixer, to read and write the recurrent state in the vLLM pool. Because the model declares itself attention-free, vLLM allocates one fixed page per sequence. Outputs matched the i14 reference token for token (48/48 steps on 3/3 prompts in BF16).
Finding the bottleneck. A linear fit of decode time against the number of decoder layers L gives:
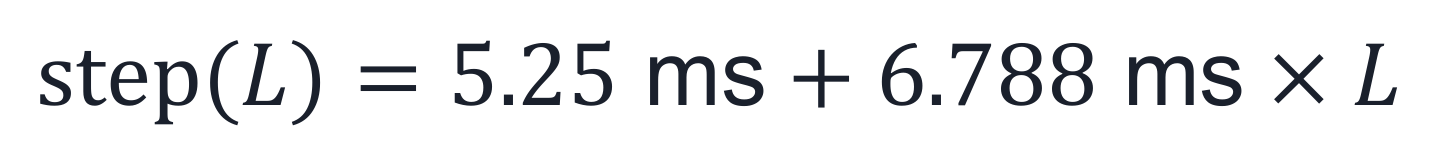
At L = 24, that is 168.1 ms per step, 96.9 percent of it inside the decoder layers. The large projections cost 13.27 ms, near the 12 ms HBM-streaming floor. Most time went to small operators dispatched one at a time under eager PyTorch.
Scaling to a full instance. Without tensor parallelism, throughput scales through replicas, with one engine and 20 sequences per logical NeuronCore. Eager throughput grew from 133 output tokens per second on one replica to 6,772 on 64, where host CPU usage reached 82 percent. Compiling the decode step removed per-operator dispatch and raised throughput 1.7 times, to 11,544 (Figure 8).
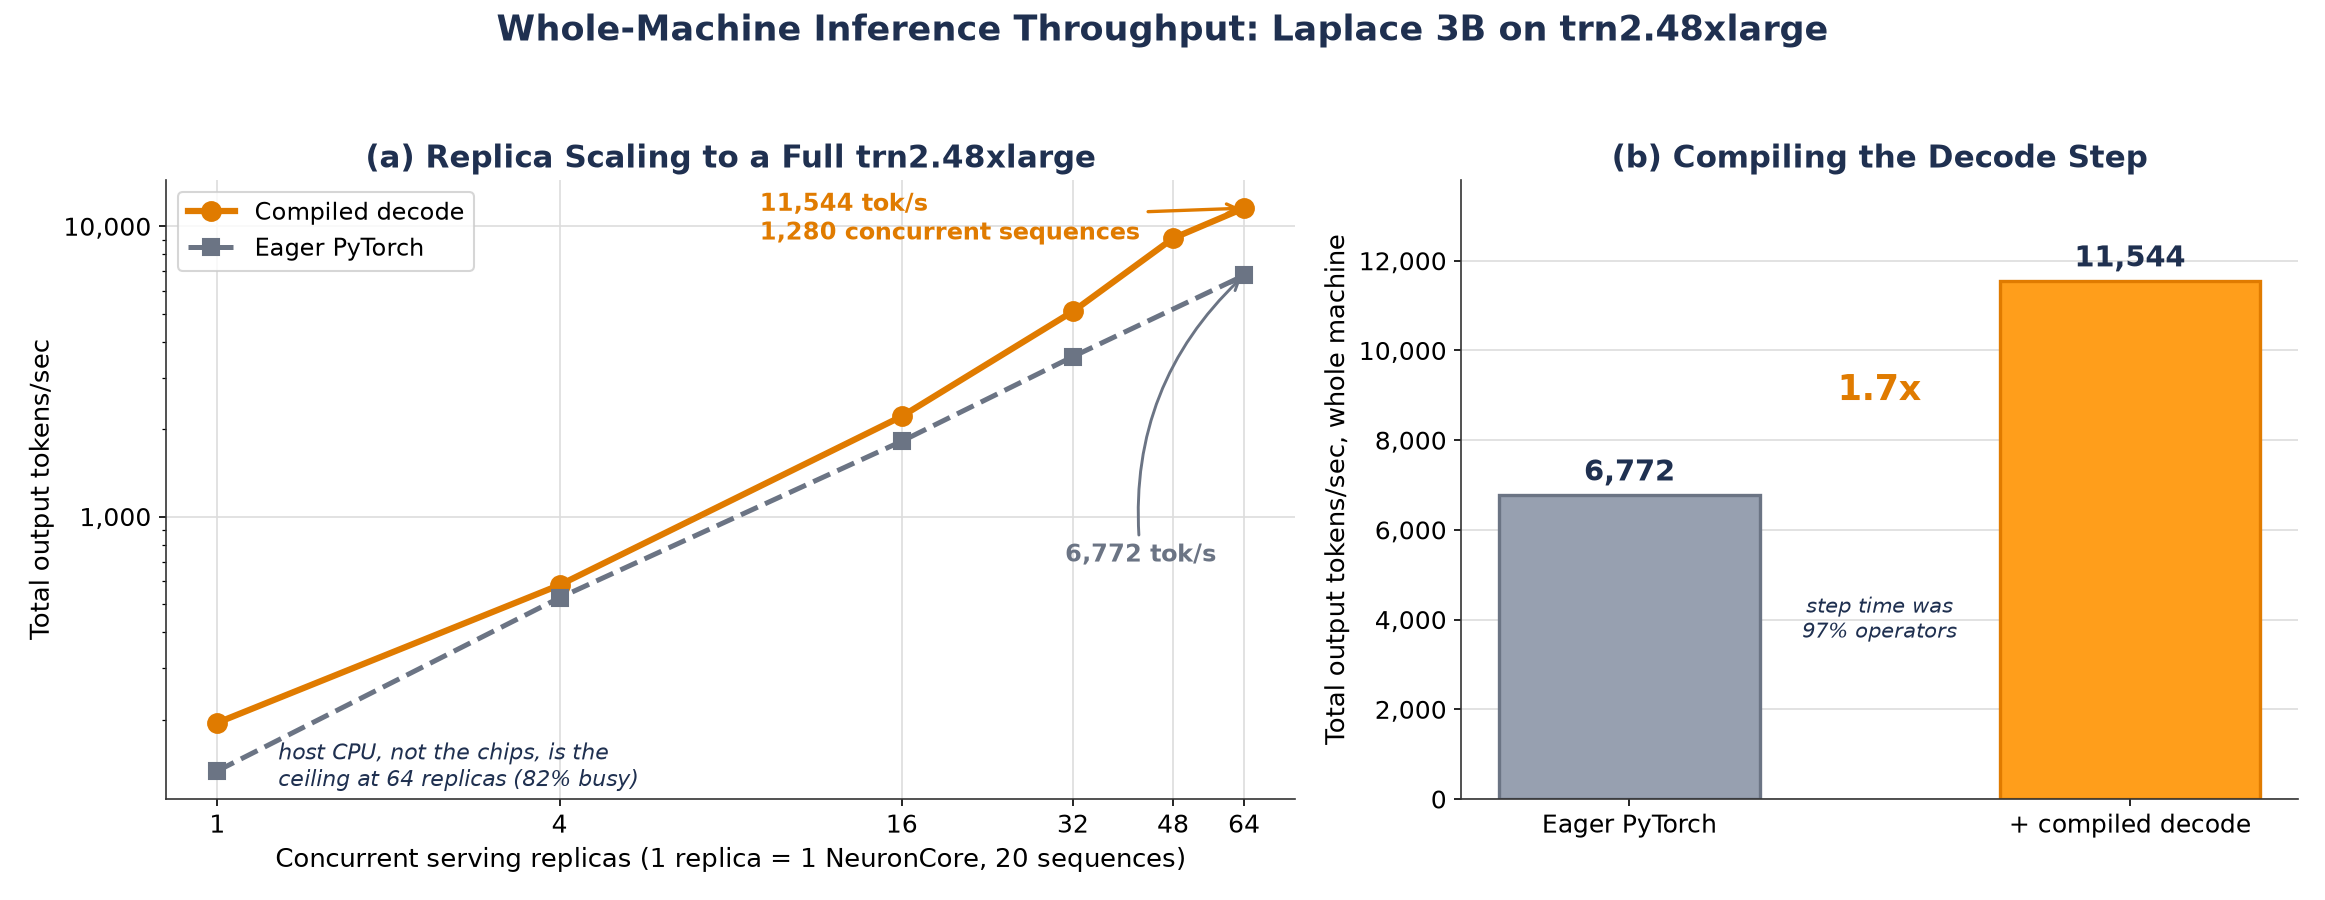
Figure 8: Whole-instance inference throughput. (a) Replica scaling on eager and compiled decode. (b) Compiled decode lifts throughput from 6,772 to 11,544 output tokens per second.
What fixed-batch benchmarks hide. Under real traffic, each new decode batch width is a separately compiled shape whose first use costs about 11 seconds. These steps were only 1.1 percent of the total but consumed 47.5 percent of decode time. Padding to fixed widths removed this cost with bit-exact results. Compiled decode then improved per-replica throughput 3.52 times under staggered arrivals, compared with 1.46 times on fixed batches. Because BF16 reassociation makes compiled output differ slightly from eager, use eager decode when exact reproducibility matters.
Key takeaways
The project produced lessons across both training and inference:
- Native PyTorch can support custom architectures on Trainium2. i14 retained the GLA architecture and used TorchNeuron Native for the final implementation.
- Communication design matters for custom optimizers. The Muon all_to_all design reduced per-rank traffic by 24 times and increased training throughput by 1.63 times.
- Fixed state keeps inference memory predictable. Each sequence uses 29.5 MB regardless of context length.
- Profile before compiling. Operator dispatch, rather than arithmetic or HBM bandwidth, accounted for most decode time.
- Benchmark realistic arrival patterns. Fixed batches hid the cost of compiling new shapes for changing batch widths.
Conclusion
Laplace 3B shows that AWS Trainium2 can support model architectures beyond standard transformers. Using native PyTorch through TorchNeuron Native and the AWS Neuron SDK, i14 trained and served its GLA-based model while preserving a fixed recurrent state.
For agentic systems, this changes a basic serving constraint. Longer histories don’t require a larger per-sequence state, which can help teams retain more context while keeping memory use predictable.
If growing context is increasing serving cost, reducing concurrency, or limiting agent memory, try i14 or contact your AWS account team to evaluate Laplace 3B on AWS Trainium2.
Resources
- Try i14
- AWS Trainium and Trainium2
- AWS Neuron SDK documentation
- Native PyTorch support on AWS Trainium with TorchNeuron Native
- Gated Linear Attention Transformers with Hardware-Efficient Training
- Muon optimizer reference implementation
- AWS Generative AI Innovation Center