SILICON VALLEY — Microsoft, the world's largest hyperscaler, unveiled a new in-house artificial intelligence chip just a year after its last one and said it will operate gigawatt-scale infrastructure packed with its own chips and high-bandwidth memory. The move signals Microsoft's intent to reduce its reliance on Nvidia graphics processing units and compete with Google and Amazon Web Services, which have already accelerated development of their own chips. Analysts expect demand for HBM made by Samsung Electronics (005930.KS) and SK hynix (000660.KS) to grow further in the inference market.
Microsoft said on the 12th that it unveiled Maia 300, its third-generation in-house AI accelerator, and will begin deploying it next year. The new chip is optimized for the latest AI workloads, including long-running inference, latency-sensitive tasks and multistep agents, to support the development and operation of increasingly advanced AI models.
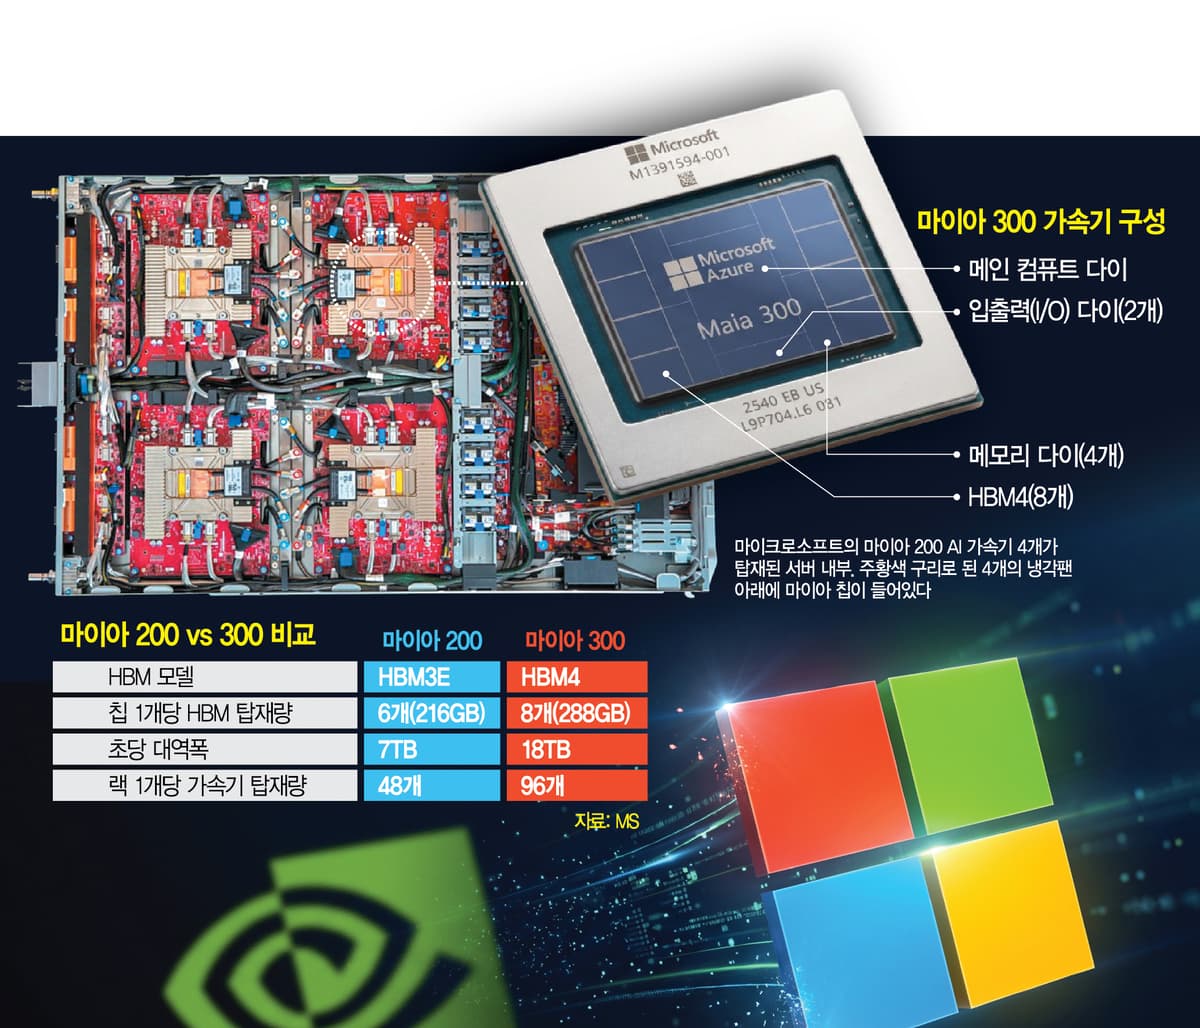
Maia is a custom chip, or accelerator, that Microsoft developed to reduce dependence on Nvidia and AMD GPUs and improve efficiency in the infrastructure of Azure, its cloud platform. The Maia 300 accelerator carries its own compute die, the main body of the chip, along with eight HBM4 units. Each Microsoft server holds four AI accelerators, and a rack including servers and networking equipment holds 96 accelerators.
Counting HBM units alone, Maia 300 raises the number of HBM chips per accelerator to eight HBM4 units from six HBM3E units in the previous Maia 200, while the number of accelerators per rack rises to 96 from 48. As a result, the HBM count in a single rack climbs to 768 from 288, an increase of about 2.7 times. Because clusters of racks make up a data center, demand for the latest HBM is bound to rise sharply.

Microsoft's weakness compared with other hyperscalers has been the pace of its in-house chip development. Google and AWS released their own chips, the Tensor Processing Unit and Inferentia, in 2016 and 2019, respectively, while Microsoft's first in-house chip, Maia 100, was not unveiled until November 2023. Google and Amazon have secured customers for data centers equipped with their chips or even begun selling the chips, but Microsoft, a late starter, uses its chips only internally.
To catch up with Google and AWS, Microsoft declared it will build a gigawatt-scale Maia Azure system. A gigawatt-scale data center typically holds AI chips numbering in the millions, reflecting enormous computing capacity. In terms of electricity, one gigawatt is the capacity of a single nuclear reactor and can supply power to one million people. Google is pushing to produce three million TPUs this year and more than five million next year, leading the inference chip market, and Microsoft has now declared it will use millions of its own chips.

Microsoft sharply raised HBM performance and capacity to maximize Maia's inference capability. Inference chips narrow the gap between the AI processor handling computation and the memory to raise bandwidth, or the volume of data transferred per unit of time, and the key component in that approach is HBM, which is built by stacking memory. The previous Maia 200, unveiled in January this year, carried six HBM3E units, the fifth generation of HBM, limiting memory capacity to 216 gigabytes. Maia 300 carries eight sixth-generation HBM4 units, raising capacity to 288 gigabytes. Thanks to the HBM upgrade, Maia's bandwidth rose sharply to 18 terabytes per second from 7 terabytes per second, based on a thermal design power of 950 watts.
Microsoft also focused on improving rack-level efficiency, targeting moves by Nvidia and AMD, which previously supplied only chips, into server racks such as Vera Rubin and Helios. A rack holds structures carrying AI chips and networking infrastructure. One Maia 300 rack holds 96 accelerators, twice as many as the previous generation. Rack-level HBM capacity rose to 27.6 terabytes from 10.4 terabytes, and bandwidth jumped to 1,728 terabytes per second from 341 terabytes per second. HBM bandwidth per watt also rose to 10.6 gigabytes per second from 5.3 gigabytes per second. Some in the industry say the gain in bandwidth is a more meaningful advance than the increase in the number of HBM units.
As hyperscaler infrastructure competition shifts from chips to servers, HBM demand is expected to grow further. "As AI workloads become increasingly memory-constrained, Maia 300 delivers higher memory bandwidth per watt," Microsoft said, adding that Maia 300 processes 40% more tokens per megawatt than leading GPU-based systems and, on a rack basis, can process up to seven times more tokens than its predecessor. The impact on South Korea's chip industry also draws attention. Microsoft did not disclose which manufacturer supplies the HBM4 used in Maia 300, but SK hynix HBM was used in Maia 200.