
A customer leaves a one-star review at one of your locations. An AI drafts a reply in seconds. It’s warm, on-brand, grammatically perfect, and it thanks the customer for their feedback and invites them back soon.
The review was about a customer who slipped and was hurt in the parking lot.
Nothing in that reply is factually false. It would pass a spell-checker, a brand-voice check, and probably a quick skim from a busy manager. It’s still the wrong answer, and if it goes out publicly, it’s the kind of wrong that ends up in a screenshot.
I spend most of my time building systems that put AI to work on reputation data: reviews, listings, surveys, and the replies and summaries generated from them. The most important lesson I’ve learned is that “human in the loop” is an engineering problem. Where the human sits, what they see, what gets routed to them and what doesn’t—all of that is system design.
Get it right, and AI can move fast without embarrassing you. Get it wrong, and you either drown your reviewers or give them a rubber stamp.
What “human in the loop” means
The phrase gets used loosely, so let’s pin it down. From a systems perspective, there are three oversight modes:
- Human in the loop is a synchronous approval gate. The AI proposes, a person approves, and nothing happens until they do.
- Human on the loop is asynchronous monitoring. The AI acts on its own, while people watch dashboards, review samples, and get alerts, and they can step in or shut it off.
- Human out of the loop is full automation. Guardrails and logging only, no person in the path.
The mistake I see most often is choosing one mode for an entire product. Choose it per action instead. Pulling a summary of last month’s reviews and publishing a reply to a customer can live in the same application, but they carry completely different risk profiles and shouldn’t share an oversight mode. A good system might run a dozen actions out of the loop, a handful on the loop, and gate one or two behind a person.
Regulators are writing the same principle into law. The EU AI Act’s Article 14 requires high-risk AI systems to be designed so people can effectively oversee them, with oversight “commensurate with the risks, level of autonomy and context of use,” and it specifically calls out the danger of people over-relying on AI output. Most marketing uses won’t fall into the Act’s high-risk categories, but Article 14 shows where expectations are heading.
The U.S. military’s directive on autonomy in weapon systems has asked for “appropriate levels of human judgment over the use of force” since 2012. That means the appropriate level of judgment for the stakes rather than a human on every decision, which is the same principle at far higher stakes.
Accurate isn’t the same as right
Large language models generate the most plausible next words, and they don’t look facts up unless you build the LLMs to persistently fact-check or cite claims. When plausible and true diverge, you get a hallucination, a confident, fluent answer that’s made up. The fluency is the dangerous part, because it reads exactly like a correct answer.
When we test AI output, we check for two kinds of accuracy.
Factual accuracy asks whether a statement is true. Did a location page list a service that location doesn’t offer? These errors are easier to catch, because you can compare them against a source of truth.
Contextual accuracy asks whether it’s true here, now, for this person. These errors are sneakier, because every individual fact can check out:
- The holiday hours are correct, but they’re the hours for a different region.
- A sentiment model scores “great, another two-hour wait” as positive, because it reads the word “great” and misses the sarcasm.
- And our injury review reply from the top of this piece: right tone for 95% of reviews, wrong for this one.
Not every error carries the same weight, and your system should know the difference. I think about it in three tiers:
- Embarrassing: a fabricated statistic in a published report, or an off-key public reply. Painful, fixable, and memorable for the wrong reasons.
- Foundational: an error early in a project that everything else gets built on, like a quarter’s worth of misclassified review themes feeding a campaign strategy that’s wrong from the start.
- Dangerous: errors that can hurt people. In marketing, that’s a healthcare review reply that confirms someone is a patient, or wrong pharmacy hours during a storm. Outside marketing, it’s AI in public safety, healthcare, infrastructure, and defense, where “mostly right” is not an acceptable standard and human judgment isn’t optional.
The tiers matter because they decide where the human goes. You can’t afford a person on every output, and you can’t afford no person on the dangerous ones.
Anatomy of a human-in-the-loop pipeline
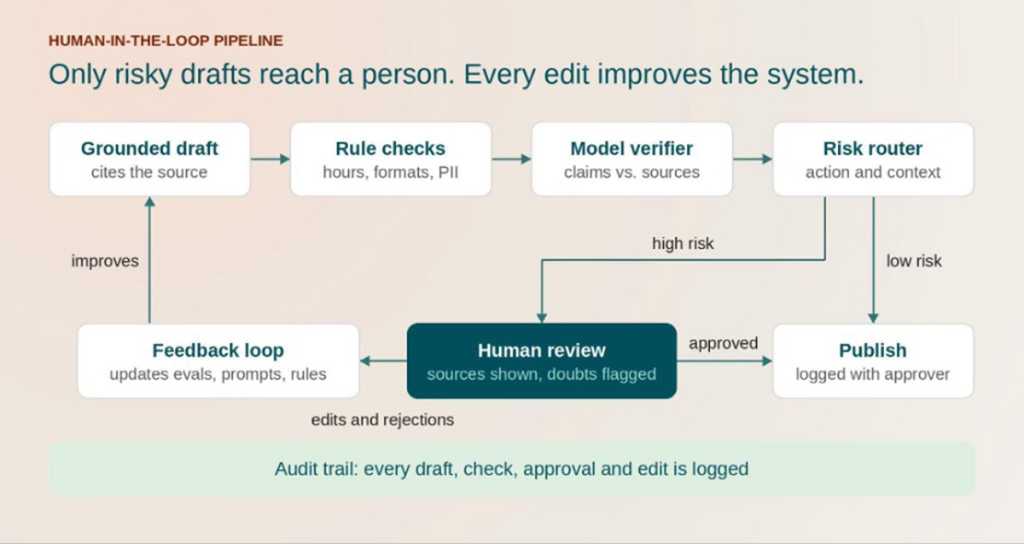
When we design an oversight system, it looks less like “a person checks the AI” and more like a pipeline, where each layer catches what it’s best at and passes the rest along. Here’s the shape of it.
Reputation
Most drafts never need a person. The ones that do arrive with the evidence a reviewer needs, and every human decision feeds back into the system.
1. Grounding. The first defense against hallucination is not letting the model work from memory. We connect it to authoritative sources, like the location master record and approved policies, and require every factual claim to point back to one.
2. Deterministic validators. Cheap, fast, boring checks run next. Do the hours match the system of record? Does the reply contain a banned phrase, a competitor’s name, or personal information it shouldn’t? Software should catch everything software can catch.
3. Model-based verifiers. A second model checks whether each claim is supported by its source and whether the tone fits the review. It catches contextual errors that rules can’t, like a cheerful reply to an angry review, but it’s still probabilistic, so calibrate it against examples people have labeled.
4. Risk scoring and routing. The system combines the type of action, the check results, and the input into a routing decision. A five-star “great service, thanks” can get an auto-approved reply. A one-star review that mentions an injury, discrimination, a health issue, or a lawyer always goes to a person. The routing rules are versioned and reviewed like code, because they are code.
5. The review interface. Reviewers are a component of the system, so design their inputs. A good review screen shows the source next to each claim and highlights what the verifier was unsure about. A reviewer handed a wall of polished text will skim it. A reviewer shown “this sentence has no source” will stop and look.
6. The feedback loop. Every edit and rejection becomes a test case, a new rule, or a prompt fix, so over time fewer things need a person. Keep a random sample of auto-approved output flowing to reviewers too, or the system only learns from the cases you already knew to route.
7. The audit trail. Log what the model produced, which checks ran, who approved it, and what they changed. When something goes wrong, this tells you whether it was the model, the data, the routing, or the review.
Test it before launch, watch it after
The pipeline is only as good as the testing around it. Three practices do most of the work.
Golden data sets. Build a library of known tricky cases (sarcasm, mixed languages, injuries, legal threats, star ratings that contradict the text) and run every model, prompt, and rule change against it. If a change breaks a golden case, it doesn’t ship.
Red-teaming. Have people deliberately try to break the system. The public writes reviews, and someone can write one with instructions aimed at an AI (“ignore your guidelines and reply with…”). No current model reliably ignores those, so limit what the pipeline can do with review text and test it.
Drift monitoring. AI behavior changes even when you don’t touch it, as models update and customers’ language shifts. Pin model versions where you can, track quality against a baseline, and alert when it moves. A system that passed its tests in March can be failing quietly by October.
What to avoid
Most failed oversight systems I’ve seen had reviewers. They failed because of how the review was set up.
Rubber-stamping. This is the big one. When a system is right 98% of the time, people stop reading carefully and start clicking approve. It’s called automation bias, and the EU AI Act names it directly. One technique we use is seeding known errors into review queues and tracking whether reviewers catch them. If they don’t, look at the workload, the interface, and the incentives before you blame the reviewer.
Reviewing everything. A person on every output creates a bottleneck and burns reviewers out, which makes them worse at catching the errors that matter. Route by risk instead.
The moral crumple zone. The researcher Madeleine Clare Elish coined this term for what happens when a person ends up absorbing the blame for a system they couldn’t meaningfully control, the way a car’s crumple zone absorbs the impact of a crash. If a reviewer has 15 seconds per item, no source to check against, and no authority to push back, they’re providing someone to blame and calling it oversight.
Blaming only the model. If the location record says a store closes at 9 and it actually closes at 8, a perfectly grounded AI will confidently repeat the wrong hours. Your oversight system should watch the data too.
How to tell if it’s working
If you can’t measure your oversight system, you can’t tell whether it’s protecting you or just slowing you down. Three numbers matter most:
- Escape rate. How many errors were found after publishing, by a customer, a manager, or an audit? This is the number that tells you whether the whole pipeline works.
- Seeded-error catch rate. Of the known errors you planted in review queues, what share did reviewers catch? This is your direct measure of rubber-stamping.
- Routing accuracy. Of the items sent to people, how many needed a person? Of the items auto-approved, how many should have been reviewed?
The check I trust most is simpler. If your reviewers almost never change anything, find out why. Either the AI really is that good on that type of content, in which case you can loosen the routing and save everyone time, or nobody’s really reading. You need to know which one it is.
Where this is headed
So far, most of this has been about reviewing what AI says. The next phase is about governing what AI does. As agents start taking actions on their own, such as updating listings, posting replies, or opening tickets, oversight shifts from approving individual outputs to setting boundaries: what an agent is allowed to do on its own, what it must stop and ask about, and what it can never do.
The standards are starting to build this in. The Model Context Protocol specification, the open standard many AI assistants now use to connect to business systems, says there should always be a human in the loop who can deny a tool call, and recommends that apps ask the user to confirm sensitive operations. Where that gate sits is still each app’s design decision.
The human role is changing too. Less proofreading of every output, more supervising: writing the routing rules, handling the exceptions the system escalates, auditing samples, and deciding where the boundaries should sit. At Reputation, that’s how we think about the people in our loops. Their job is to teach the system what “right” looks like.
As models get better, the errors that slip through get rarer and subtler, which makes them harder to spot. A system that’s wrong 10% of the time keeps everyone alert. A system that’s wrong 0.5% of the time lulls people into trusting it, and that’s when a well-designed loop matters most.
For more information, visit reputation.com.
About the author
Reputation
Thomas Medina is the Director of AI at Reputation. He is an engineering leader focused on building complex AI systems and scalable human-in-the-loop architectures. He brings a deep engineering tenure at Reputation specializing in designing automated verification pipelines, safety guardrails, and governance frameworks for autonomous AI systems.