
Dhruv Bhutani has been writing about consumer technology since 2008, offering deep insights into the personal technology landscape through features and opinion pieces. He writes for XDA-Developers, where he focuses on topics like productivity, networking, self-hosting, and more. Over the years, his work has also appeared in leading publications such as Android Police, Android Authority, CNET, PCMag, and more. Outside of his professional work, Dhruv is an avid fan of horror media spanning films and literature, enjoys fitness activities, collects vinyl records, and plays the guitar.
I watch a lot of old-school movies while I'm working, and not a lot of them have subtitles. I've built the collection over the years from an assortment of sources, and even when subtitles are available, the quality can be all over the place. I've tried using tools like Bazarr to solve the problem with limited success. But lately, as I've been reorganizing my media library, I've been looking for a better solution.
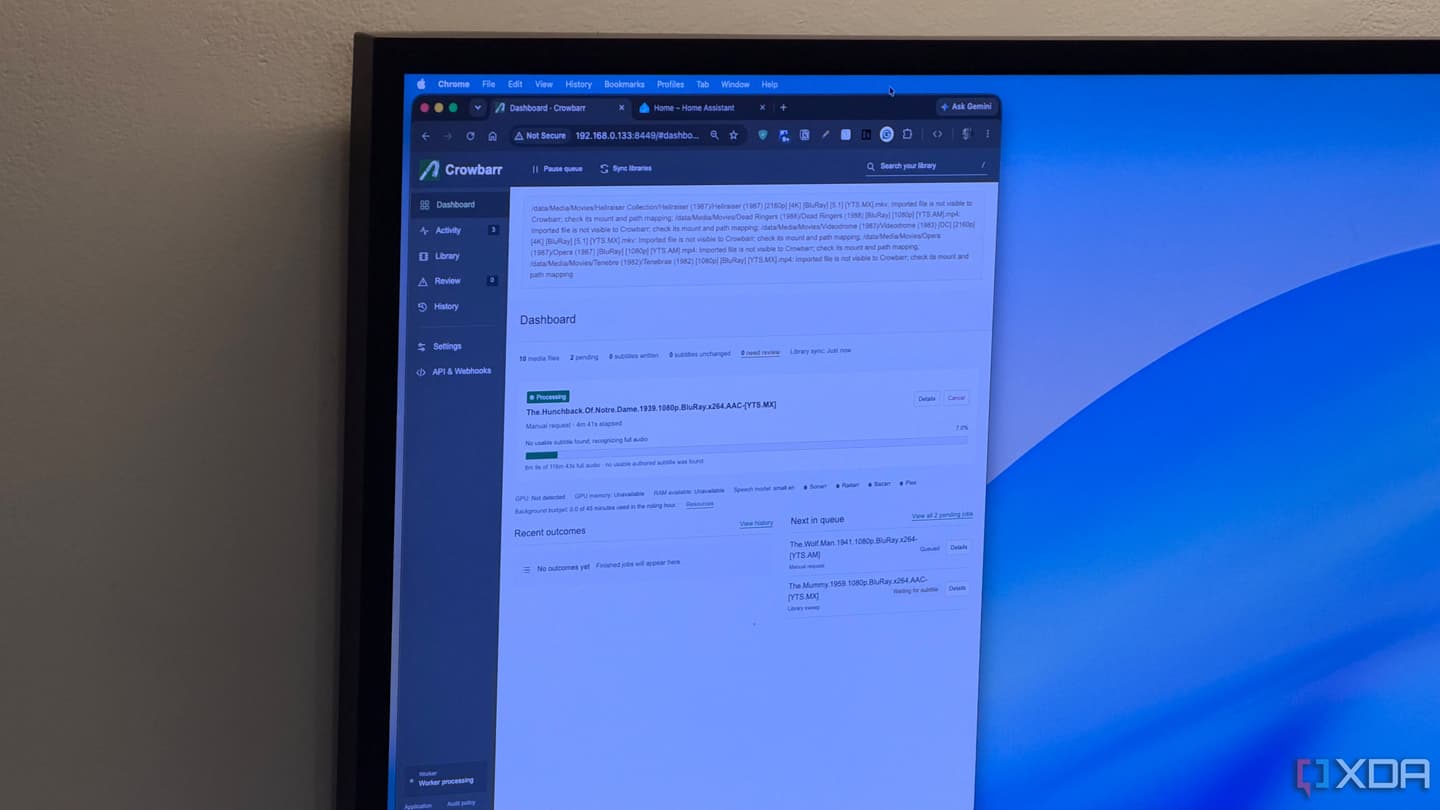
That solution turned out to be Crowbarr. This open-source tool uses local AI to check, repair and generate subtitles for your media library, and it's absolutely brilliant at it.
Use local AI to sync, verify and generate missing subtitles

My media stack is pretty well organized. I keep all my media on my NAS, Plex handles playback across all my devices, and the ever-popular arrr stack helps me organize and manage mycollection. For modern content, Bazarr does swimmingly for finding subtitles. But that accuracy drops quite dramatically the moment we start talking about older media. Specifically, my flavor of media, which tends to include 90-year-old horror movies. Oddly specific, and not a very good candidate for finding the perfect subtitle file.
I run into this problem often enough. Even when subtitles exist, the timing is often off, or the text doesn't match the audio. This usually happens because I use media from different sources. The video might be ripped from a VHS or CD, while the DVD was some streaming rip, or even a manual file. Yes, go back far enough, and you'll find those.
Crowbarr solves this specific problem by comparing the subtitles in the subtitle file with the video's actual dialogue. Instead of just using whatever subtitle file exists, it uses Whisper, an open-source speech recognition model, to transcribe the full audio. It then uses the transcription to compare the text and timing of the subtitles with the audio.
If the subtitles sync up perfectly, it'll leave them be. If not, it can adjust the timing or even generate a full replacement subtitle file if the existing subtitles are useless or missing.
That last part is particularly useful because my biggest problem was the lack of subtitles, not just poor-quality subtitles. That said, Crowbarr's ability to fix timing comes in handy when you're just trying to line up text with the dialogue. Moreover, it does this without replacing the original subtitle file, so you won't lose your data. In Plex, Jellyfin, or your preferred media player, you can switch between the old and new subtitles and pick what works best for you.
It's a pretty well-thought-out app too. Crowbarr integrates deeply with Radarr and Sonarr. So whenever fresh media gets imported or upgraded, it picks it up and starts verifying the media and subtitles. It can also work with an existing media collection, which makes it useful for checking older movies and TV episodes. All I had to do was add the media volumes on my NAS to the Compose file, and I was able to import all the movies.
Setting up Crowbarr is easy, but local AI processing needs fast hardware
Connect Crowbarr to your media stack for more automation
Which brings me to the next part: ease of use. Installing Crowbarr is straightforward via the provided Docker Compose file. From there, enter the IP address and API key for your Radarr and Sonarr instances. To integrate Plex as well, you'll need a Plex token. Or you can just import your media files directly if you wish. Tap the button to get started, and Crowbarr will begin analyzing your media.
A few more things to keep in mind, though. The beauty of Crowbarr is that all speech recognition runs locally. Since I run my entire stack locally, this works well for me. But it also means you'll need hardware to keep up.
Yes, it supports CPU processing, but in my experience, transcribing a full movie takes time, especially with larger models. And if you've got a sizable library, this could be a particularly time-consuming job. That said, GPU acceleration is supported if you have a supported GPU.
That said, I can't really complain about the speed here since the tool does something almost no other tool does. After all, this is media we're talking about, and I'm okay with waiting 10–15 minutes for it to finish processing the file.
In my testing, Crowbarr generally does an excellent job as long as the media is in English. Accents can absolutely throw it off, and once in a while, it'll misspell something. As far as I can tell, it doesn't support any other language at the moment.
Finally, I like that you can pair it with Bazarr. Anytime you import fresh media, Crowbarr first checks Bazarr, and if it can't find verified subtitles, it kicks off AI transcription.
Crowbarr makes subtitle management easy
I've been automating as much of my media stack as possible, and Crowbarr has been a wonderful addition to solving the subtitle problem. I still prefer human-authored subtitles wherever possible, but when none exist or the quality isn't up to scratch, Crowbarr steps in and fixes them. If you watch a lot of media you've struggled to find subtitles for, this tool can be a great addition to your self-hosted stack.
Crowbarr: This open-source, self-hosted tool uses local AI to sync, fix, or generate fresh subtitles for your media files