Picking an LLM API used to mean picking a vendor. In 2026 it means picking one model out of hundreds, and the price list alone does not tell you which one. A model with a low price per token can still cost more per request if it writes long answers. A model with a fast median response can still be slow for one user in ten. Leaderboard scores help, but only a test on your own questions shows what a model costs and how it behaves in your product.
We ran a small test to show how price, speed and accuracy interact. We sent the same 300 questions to five models through AI/ML API, a platform that gives developers access to hundreds of models with one key. For every request we recorded the answer, the cost and the response time.
How We Tested
The questions came from xRouteBench, a public benchmark for AI model selection published by researchers at the University of Illinois. We used 300 of them. 160 were easy, such as school science and grade school word problems. 90 were medium, mostly multiple choice questions across academic and professional subjects. 50 were hard, mostly competition math.
The easy group had five source datasets. BoolQ gave 20 questions, CommonsenseQA 20, OpenBookQA 30, ARC Challenge 40 and GSM8K 50. The medium group took 40 questions from MMLU and 50 from MMLU-Pro. The hard group took 40 problems from MATH and 10 from AIME.
Every model received the same prompt through the chat completions endpoint with temperature 0 and max_tokens set to 2048. We did not change any reasoning settings, so DeepSeek V4.1 Flash used its default thinking mode. The runner sent eight requests in parallel and wrote every result to a JSONL file, so an interrupted run could resume without repeating calls. The API sits behind Cloudflare, which rejects requests that have no User-Agent header, so the runner sets one.
Scoring is exact match with no human review. For multiple choice the scorer extracts the option letter. For GSM8K it extracts the final number. For MATH and AIME it reads the value inside the boxed answer. When a model replied with option text such as "(No)" instead of a letter, the scorer maps it to the matching letter. That rule applies only to multiple choice questions.
Cost is calculated per request from the usage field in the API response. Input tokens are multiplied by the input price and output tokens by the output price. For DeepSeek V4.1 Flash the reasoning tokens count as output tokens, so they are billed. Response time was measured on the client side by the runner. Prices come from the AI/ML API pricing page on September 30, 2026.
Accuracy and Price per Request
The table shows what each model did on the full set of 300 questions.
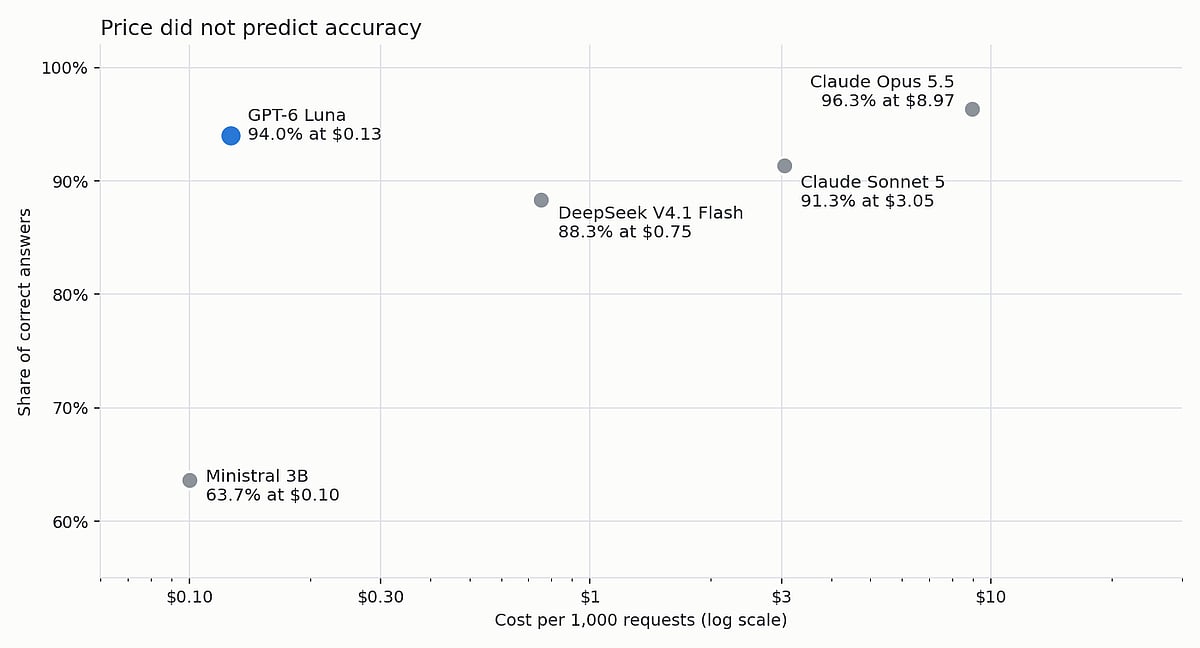
Price per token and price per request are different things. Ministral 3B had the lowest cost per 1,000 requests, yet it answered only 63.7% of the questions correctly. GPT-6 Luna cost $0.13 and answered 94.0% correctly. Claude Opus 5.5 was the most accurate at 96.3%, but it cost about 70 times more than Luna.
Answer length explains part of the gap. DeepSeek V4.1 Flash has a low token price, but it thinks before it answers and wrote 444 tokens on average. Luna wrote 168. When you compare models, multiply the token price by the output you actually get.
Accuracy by difficulty group shows where the models separate.
Price also did not predict quality. Claude Sonnet 5 cost 24 times more than Luna and scored lower on hard problems, 82.0% against 94.0%. On easy questions Luna scored 97.5% and Opus scored 96.9%. Opus pulled ahead on medium questions, 94.4% against 87.8% for Luna.
Cost per Correct Answer
A cheap wrong answer is not a saving. A fairer number is the cost of 1,000 correct answers. It is the cost per 1,000 requests divided by the share of correct answers.
By this measure GPT-6 Luna came first. Ministral 3B had the lowest price per request but dropped to second place once its errors were counted. Claude Opus 5.5 cost about 70 times more per correct answer than Luna. For a task where an error is cheap to fix, that gap decides the choice. For a task where an error is expensive, the extra 2.3 points of accuracy may justify it.
Speed Is More Than the Median
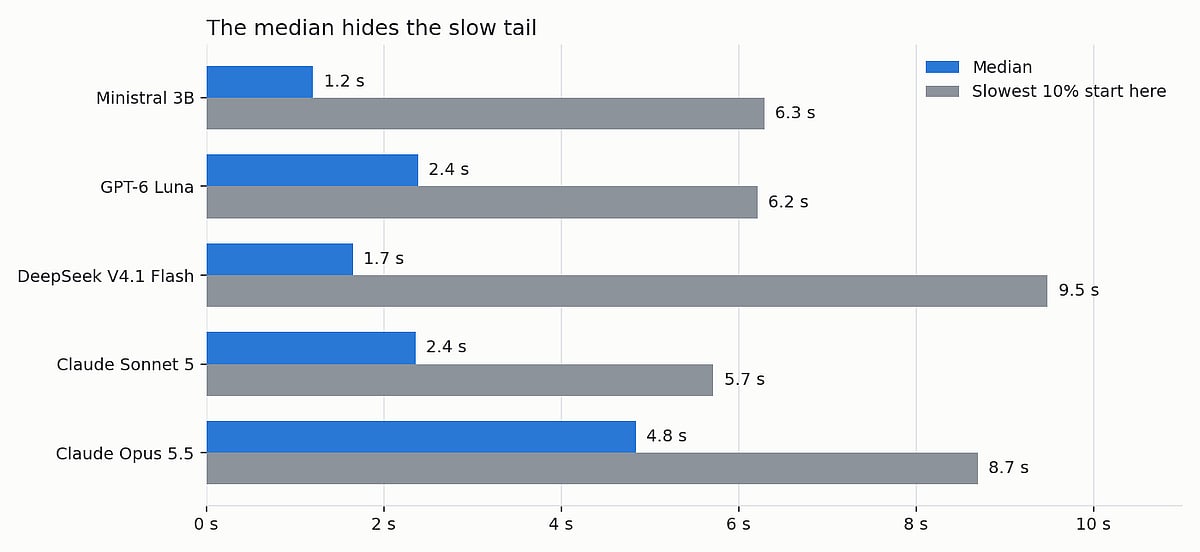
The median hides the slow responses that users notice. Ministral 3B had the fastest median at 1.2 seconds, but one request in ten took 6.3 seconds or longer. DeepSeek V4.1 Flash had a median of 1.7 seconds, yet its slowest tenth started at 9.5 seconds, which fits its habit of reasoning before it answers. Claude Opus 5.5 had the slowest median at 4.8 seconds.
Response time combines the wait before generation and the generation itself, so it grows with answer length. DeepSeek V4.1 Flash wrote 444 tokens on average and Luna wrote 168, which is part of why their slowest tenth differs. If your product streams text, also measure time to first token, because users see the first word long before the full answer is ready. AI/ML API publishes live latency figures for each model at api.aimlapi.com/models/metrics over a five minute window. Time to first token is reported only for streamed requests.
For chat and voice products, look at the 90th percentile. For batch jobs, response time matters less than total cost. Response times also depend on provider load, so repeat the measurement at different hours.
A Checklist for Choosing an LLM API
Collect 100 to 300 real examples from your product with known correct answers.
Send the same examples to three or four models with identical settings. A model catalog that uses one API format lets you change only the model name in the request.
Fix temperature and max_tokens for every model. Log the usage field from each response instead of estimating tokens. Record accuracy, cost per 1,000 requests, and response time at the median and at the 90th percentile.
Divide cost by accuracy to get the cost per correct answer.
Check the newest build from each vendor. The catalog description of DeepSeek V4.1 Flash says DeepSeek reports it surpasses DeepSeek V4 Pro on performance, cost and speed, so an older family member may no longer be the best choice.
Pick the cheapest model that meets your quality bar, keep a second model as a fallback, and repeat the test every few months.
Limits of This Test
The test used 300 academic questions, not product traffic. Each question ran once, and response times depend on provider load at the time of the run. We did not tune prompts for any model, and extended reasoning settings could change the results. A limit of 2,048 output tokens can cut off long answers from models that think before they reply. The medium and hard groups are small, so small gaps are not reliable. The numbers describe five models between September 30 and October 1, 2026.
Conclusion
No single number picks an LLM API. In our test the lowest price per request was not the lowest price per correct answer, the fastest median hid a slow tail, and the most expensive model led only on the harder questions. Developers who test a few models on their own examples and compare cost per correct answer make better choices than developers who read price lists.
FAQ
Which LLM API is the cheapest?
It depends on what you count. Ministral 3B had the lowest cost per 1,000 requests at $0.10, but GPT-6 Luna had the lowest cost per 1,000 correct answers at $0.14.
Does a higher price mean better answers?
Not always. Claude Sonnet 5 cost 24 times more than GPT-6 Luna and scored 91.3% against 94.0%. Only Claude Opus 5.5 beat Luna overall, with 96.3%.
Which speed metric should developers track?
Track the 90th percentile next to the median. Ministral 3B had a median of 1.2 seconds, yet one request in ten took 6.3 seconds or longer.
How many examples are enough for a model comparison?
100 to 300 real examples from your product give a useful first signal. Small gaps between models on a sample this size are not reliable, so repeat the test when two models score close to each other.