
Shekhar Vaidya is a veteran technology journalist and computer science engineer. He is the founder of TechLatest, where he has spent years providing technical analysis on hardware and Windows ecosystems. Now a Computing Writer at XDA, Shekhar leverages his deep background in NAS, storage solutions, and PC internals to help readers master their tech.
I have become so dependent on AI that even for small tasks like summarizing or replying to emails, I always turn to cloud AIs like ChatGPT or Claude. Since I can’t stop going to AI, I have been trying to cut down on cloud AI and use self-hosted local LLMs whenever I can.
For instance, most of the time on my PC, I use Gemma 4 E4B. But I can’t always keep my PC running, so I thought of running a local LLM on my old Galaxy S23 FE. I knew it could run an LLM, so my real question was whether I could move some of the daily usage to it.
The model I wanted crashed the app, so I went around it
E2B crashed PocketPal, then loaded in Termux
My Galaxy S23 FE is the Exynos 2200 variant with 8 GB of RAM (7.3 GB visible to Android). So, even before starting, I knew memory was going to be a problem. I had two ways to host a local LLM: either a client application like PocketPal or a llama server via Termux.
I started with PocketPal because it was simple: open the app and download the model I wanted. It also offers a built-in chat UI, so it was the easiest ChatGPT and Claude alternative for my daily general use. The good thing about PocketPal is that it only shows the models that it thinks are good for the hardware. So, when I went to the Models page, it offered seven different models. From Gemma 3 1B to Gemma 4 E2B, and a few others like Bonsai and Phi-4 Mini.
I had a previous good experience with Gemma 4 E4B on my PC, so I made up my mind about E2B. If it runs properly on my Galaxy, I wouldn’t even test other models. But the memory was also an issue because when I checked it, 4.6 GB was already being used out of 8 GB. So, I started with the smallest model, Gemma 3 1B. It ran without throttling the phone. I didn’t judge the answers it gave at that time; I was checking the performance. So I immediately unloaded it and downloaded Gemma 4 E2B.
When I tried to load the model, it gave me a memory warning saying the model may exceed the available memory. I proceeded anyway, and while loading the model, the app crashed. Not once, but multiple times, so I thought removing the PocketPal layer might help. That was when Termux as an option became the only option.
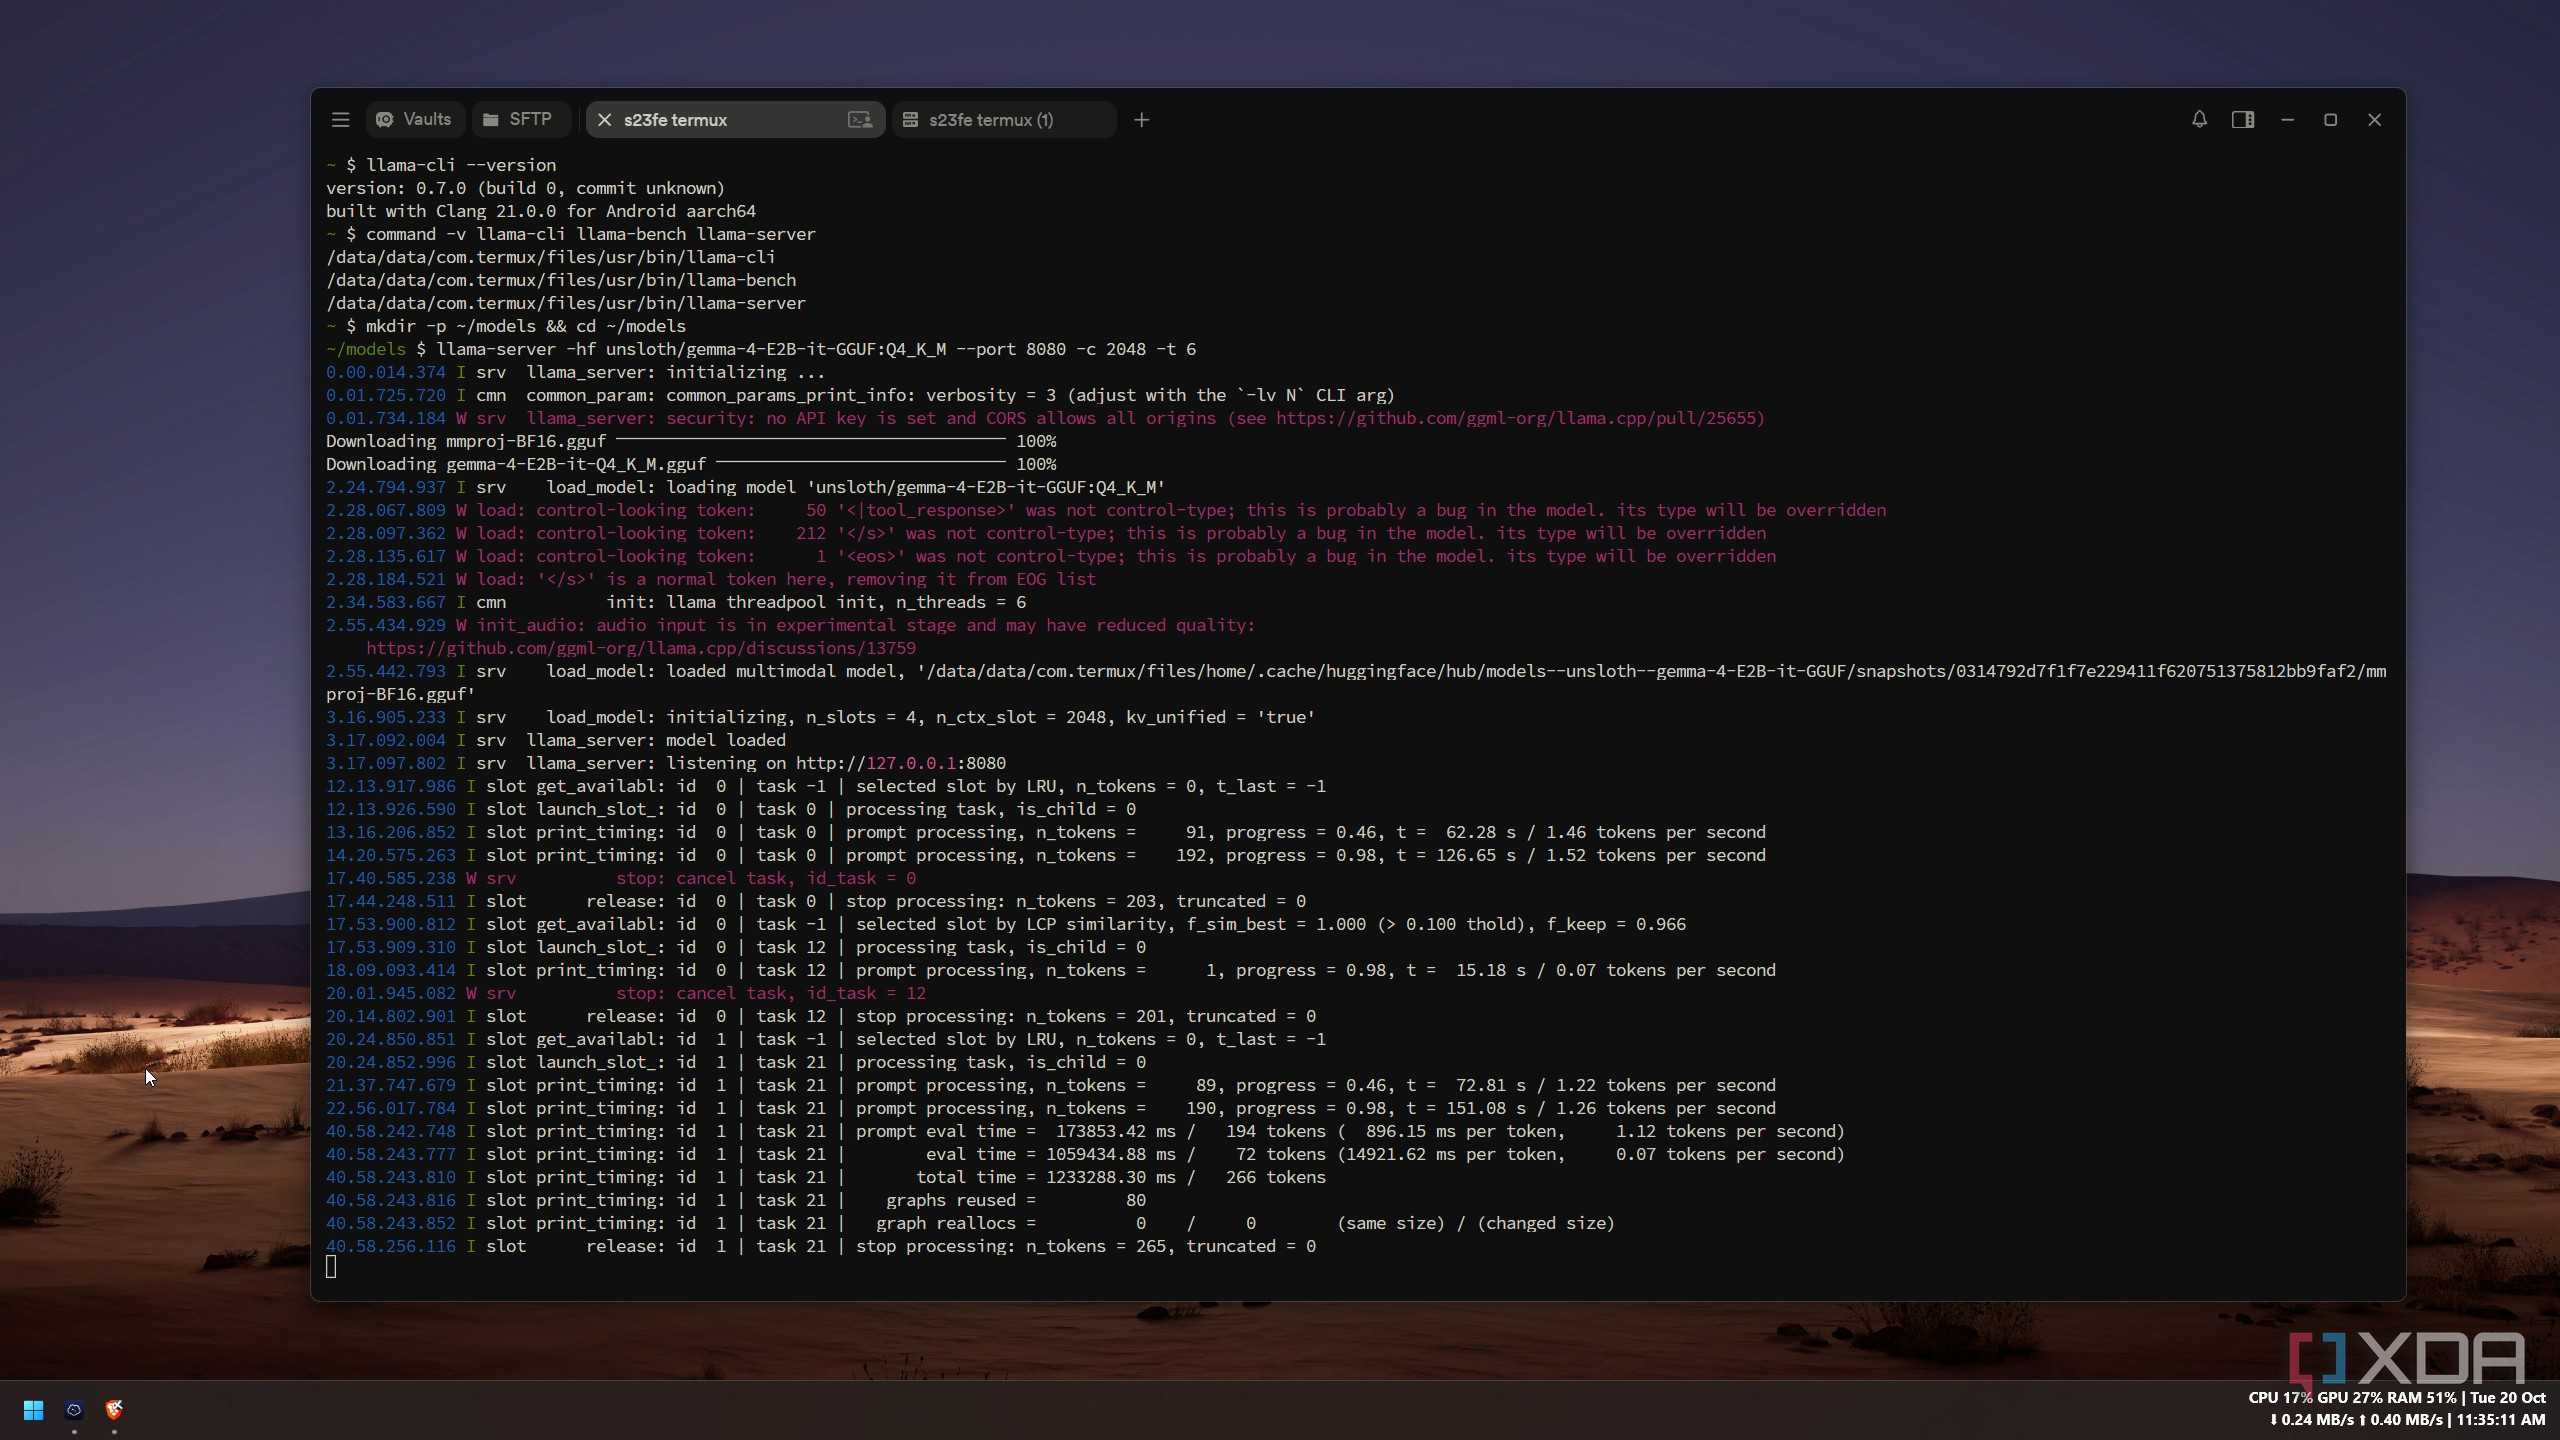
I already had Termux on the phone, so I just installed the llama-cpp package via it. And then loaded Gemma 4 E2B using the Unsloth Q4_K_M build. For context, it is listed on Hugging Face with 2.8GB in size and approximately 4.65 billion parameters with embeddings. It easily loaded the model and started the server at localhost:8080. And when I checked the RAM usage, it looked fine, so I thought that was it.
It's fast, but only while I'm looking at it
0.1 tok/s, and it wasn’t the battery settings
I opened the llama web UI in the browser and ran a simple prompt: say hello in five words. I thought this would give me an idea about the performance. I was surprised to see what came next. The 103-token prefill ran at 1.27 tok/s, and the actual generation was 0.11 tok/s, taking 1 min 11 seconds to generate eight tokens.
I thought it might be warming up, so I ran another prompt to summarize a small paragraph in two lines. The performance was just as slow. This time the 194-token prefill ran at 1.54 tok/s and generated a 68-token output in 11 minutes and 56 seconds at 0.09 tok/s. I started thinking about what might have happened and the reason for this poor performance.
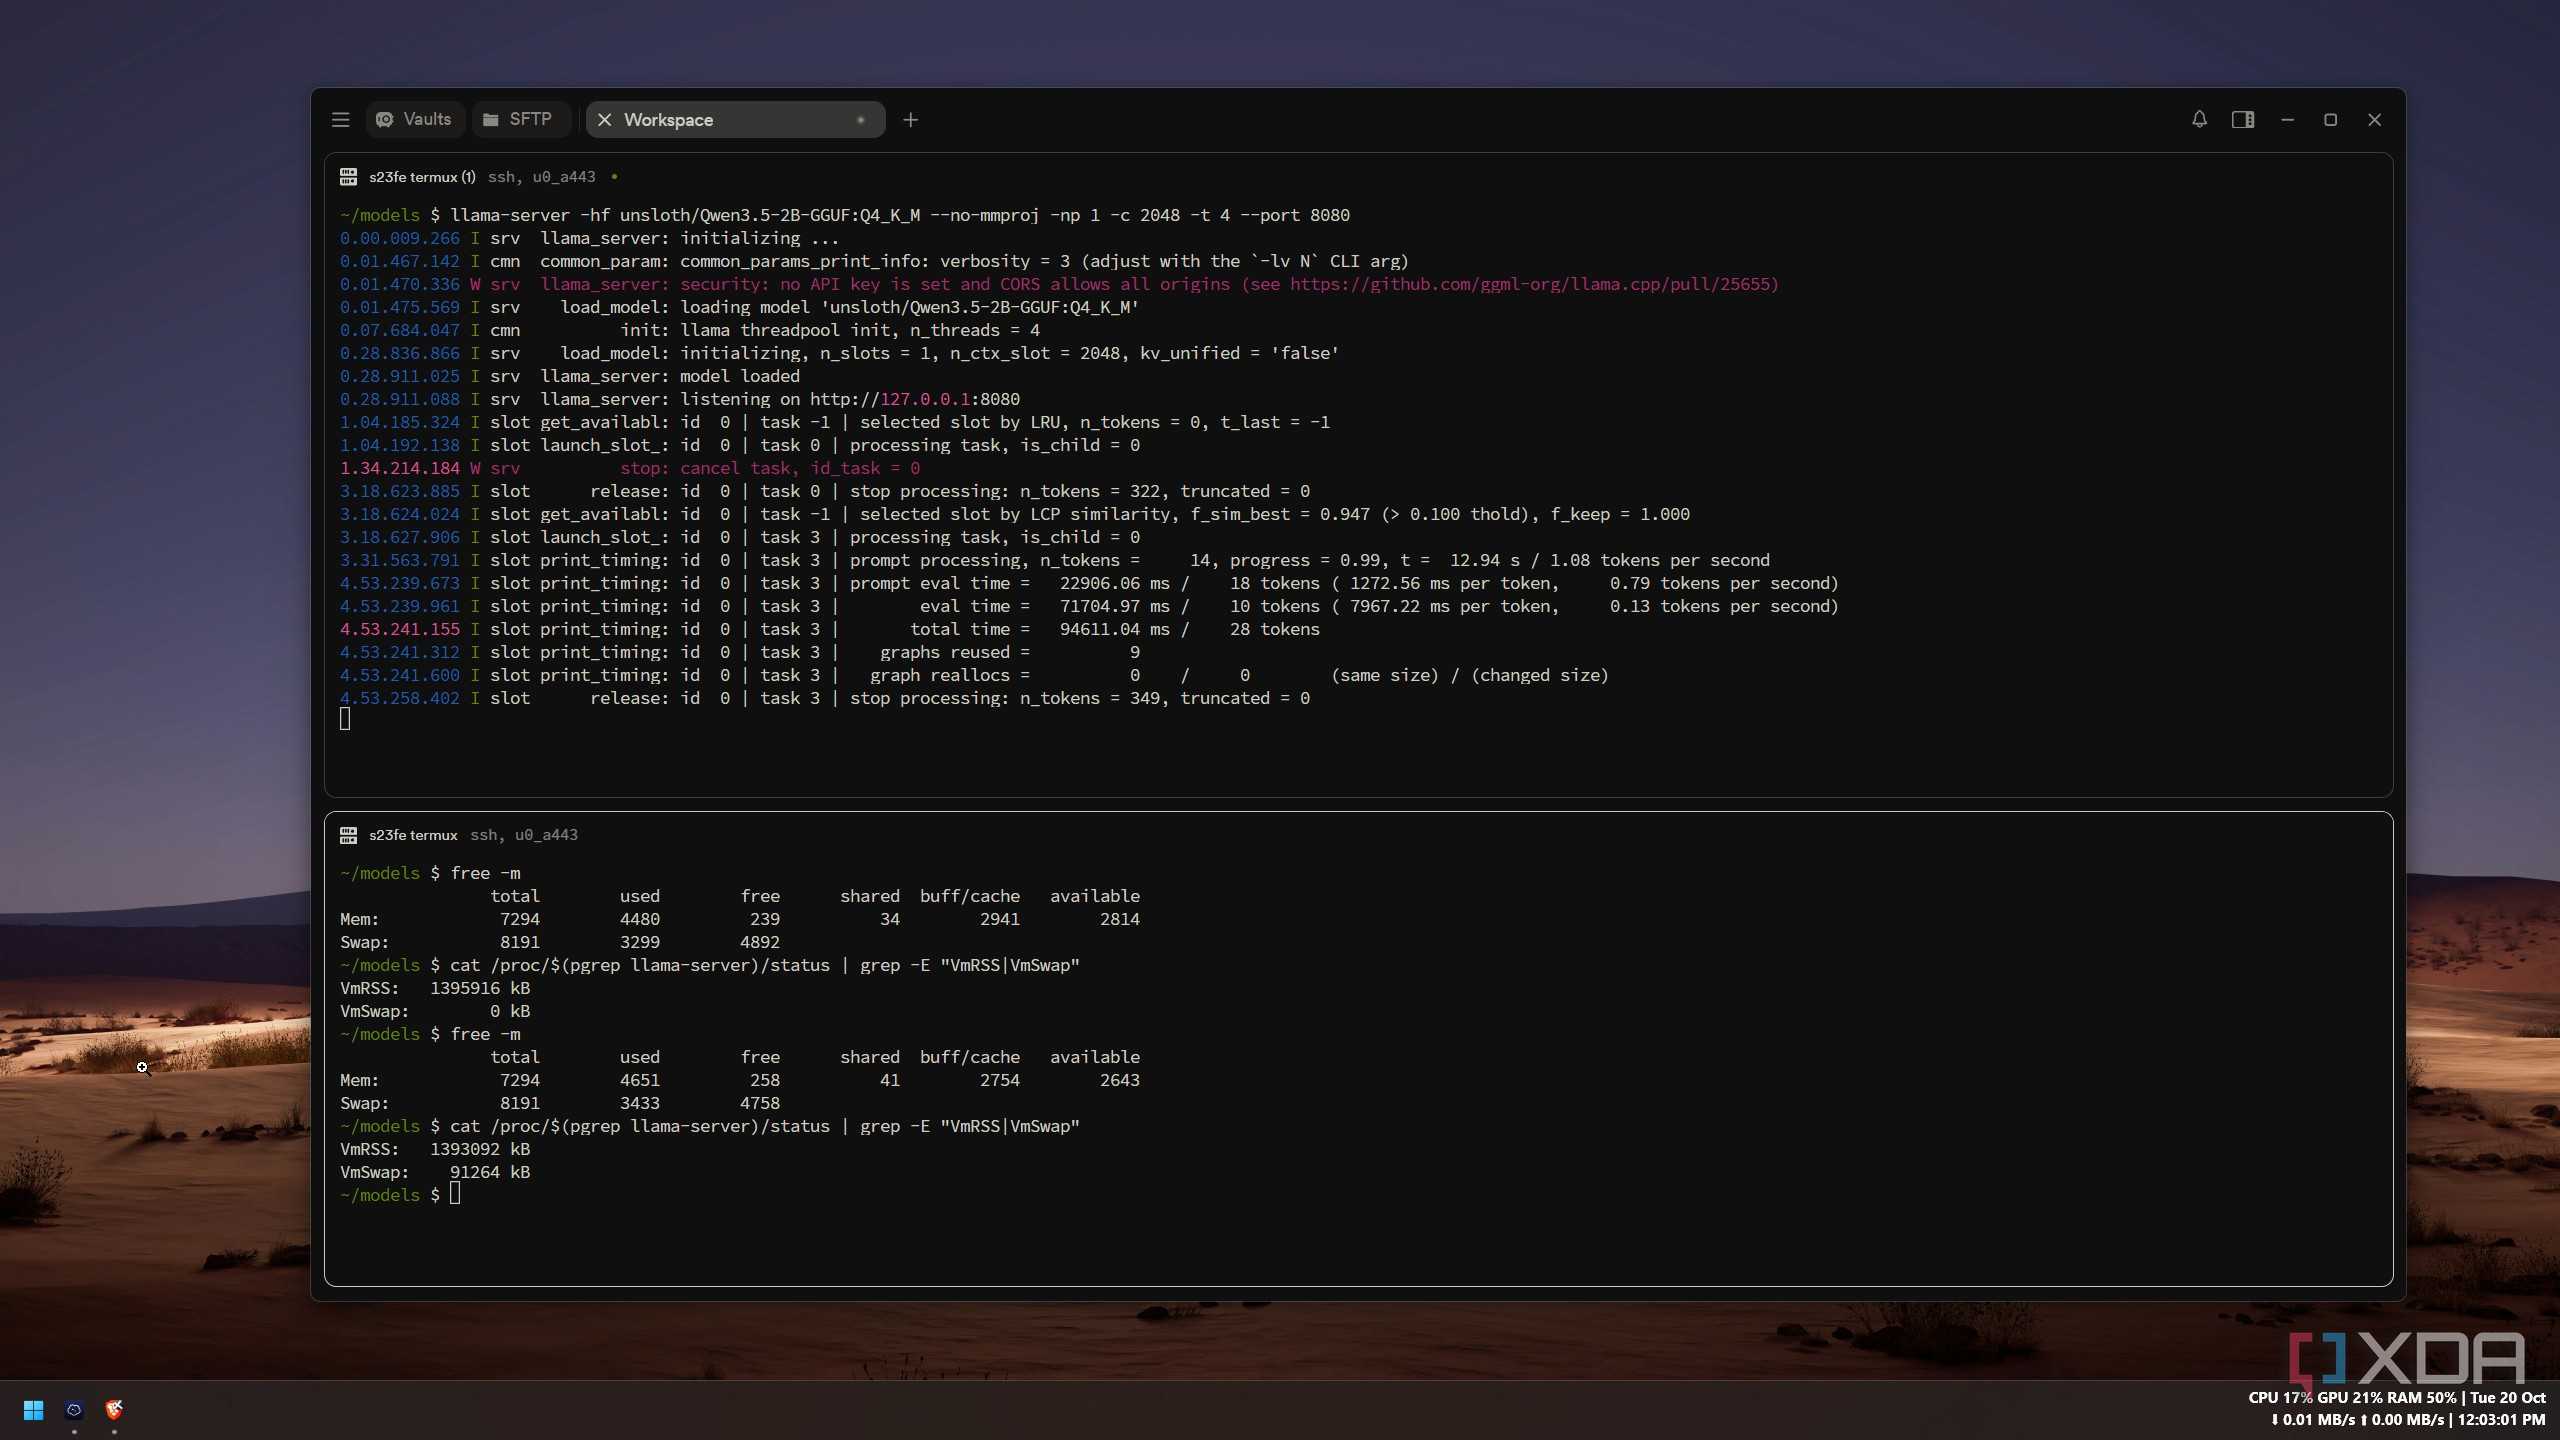
My thought was maybe Termux was running in the background, and the Galaxy’s power settings were limiting the performance. I started checking everything, and Termux’s battery setting was already Unrestricted, Put unused apps to sleep was disabled, and power saving was off, so power settings were not the issue. That was when I decided to install another small model, thinking E2B itself might be the problem. I unloaded E2B and loaded Qwen 3.5 2B using the Unsloth Q4_K_M model at approximately 1.18 GiB. It performed poorly again, so I went back to PocketPal, thinking it might not crash.
I downloaded the model and loaded it. It worked fine. PocketPal's built-in benchmark achieved 54.54 tok/s prefill and 11.14 tok/s generation, and the real tests ran at a usable ~9 tok/s generation. Then I started testing the model thoroughly as per my general use case. Most of the generations had a lot of hallucinations and invented facts, but I was ready to keep it anyway, as E2B didn’t work the way expected.
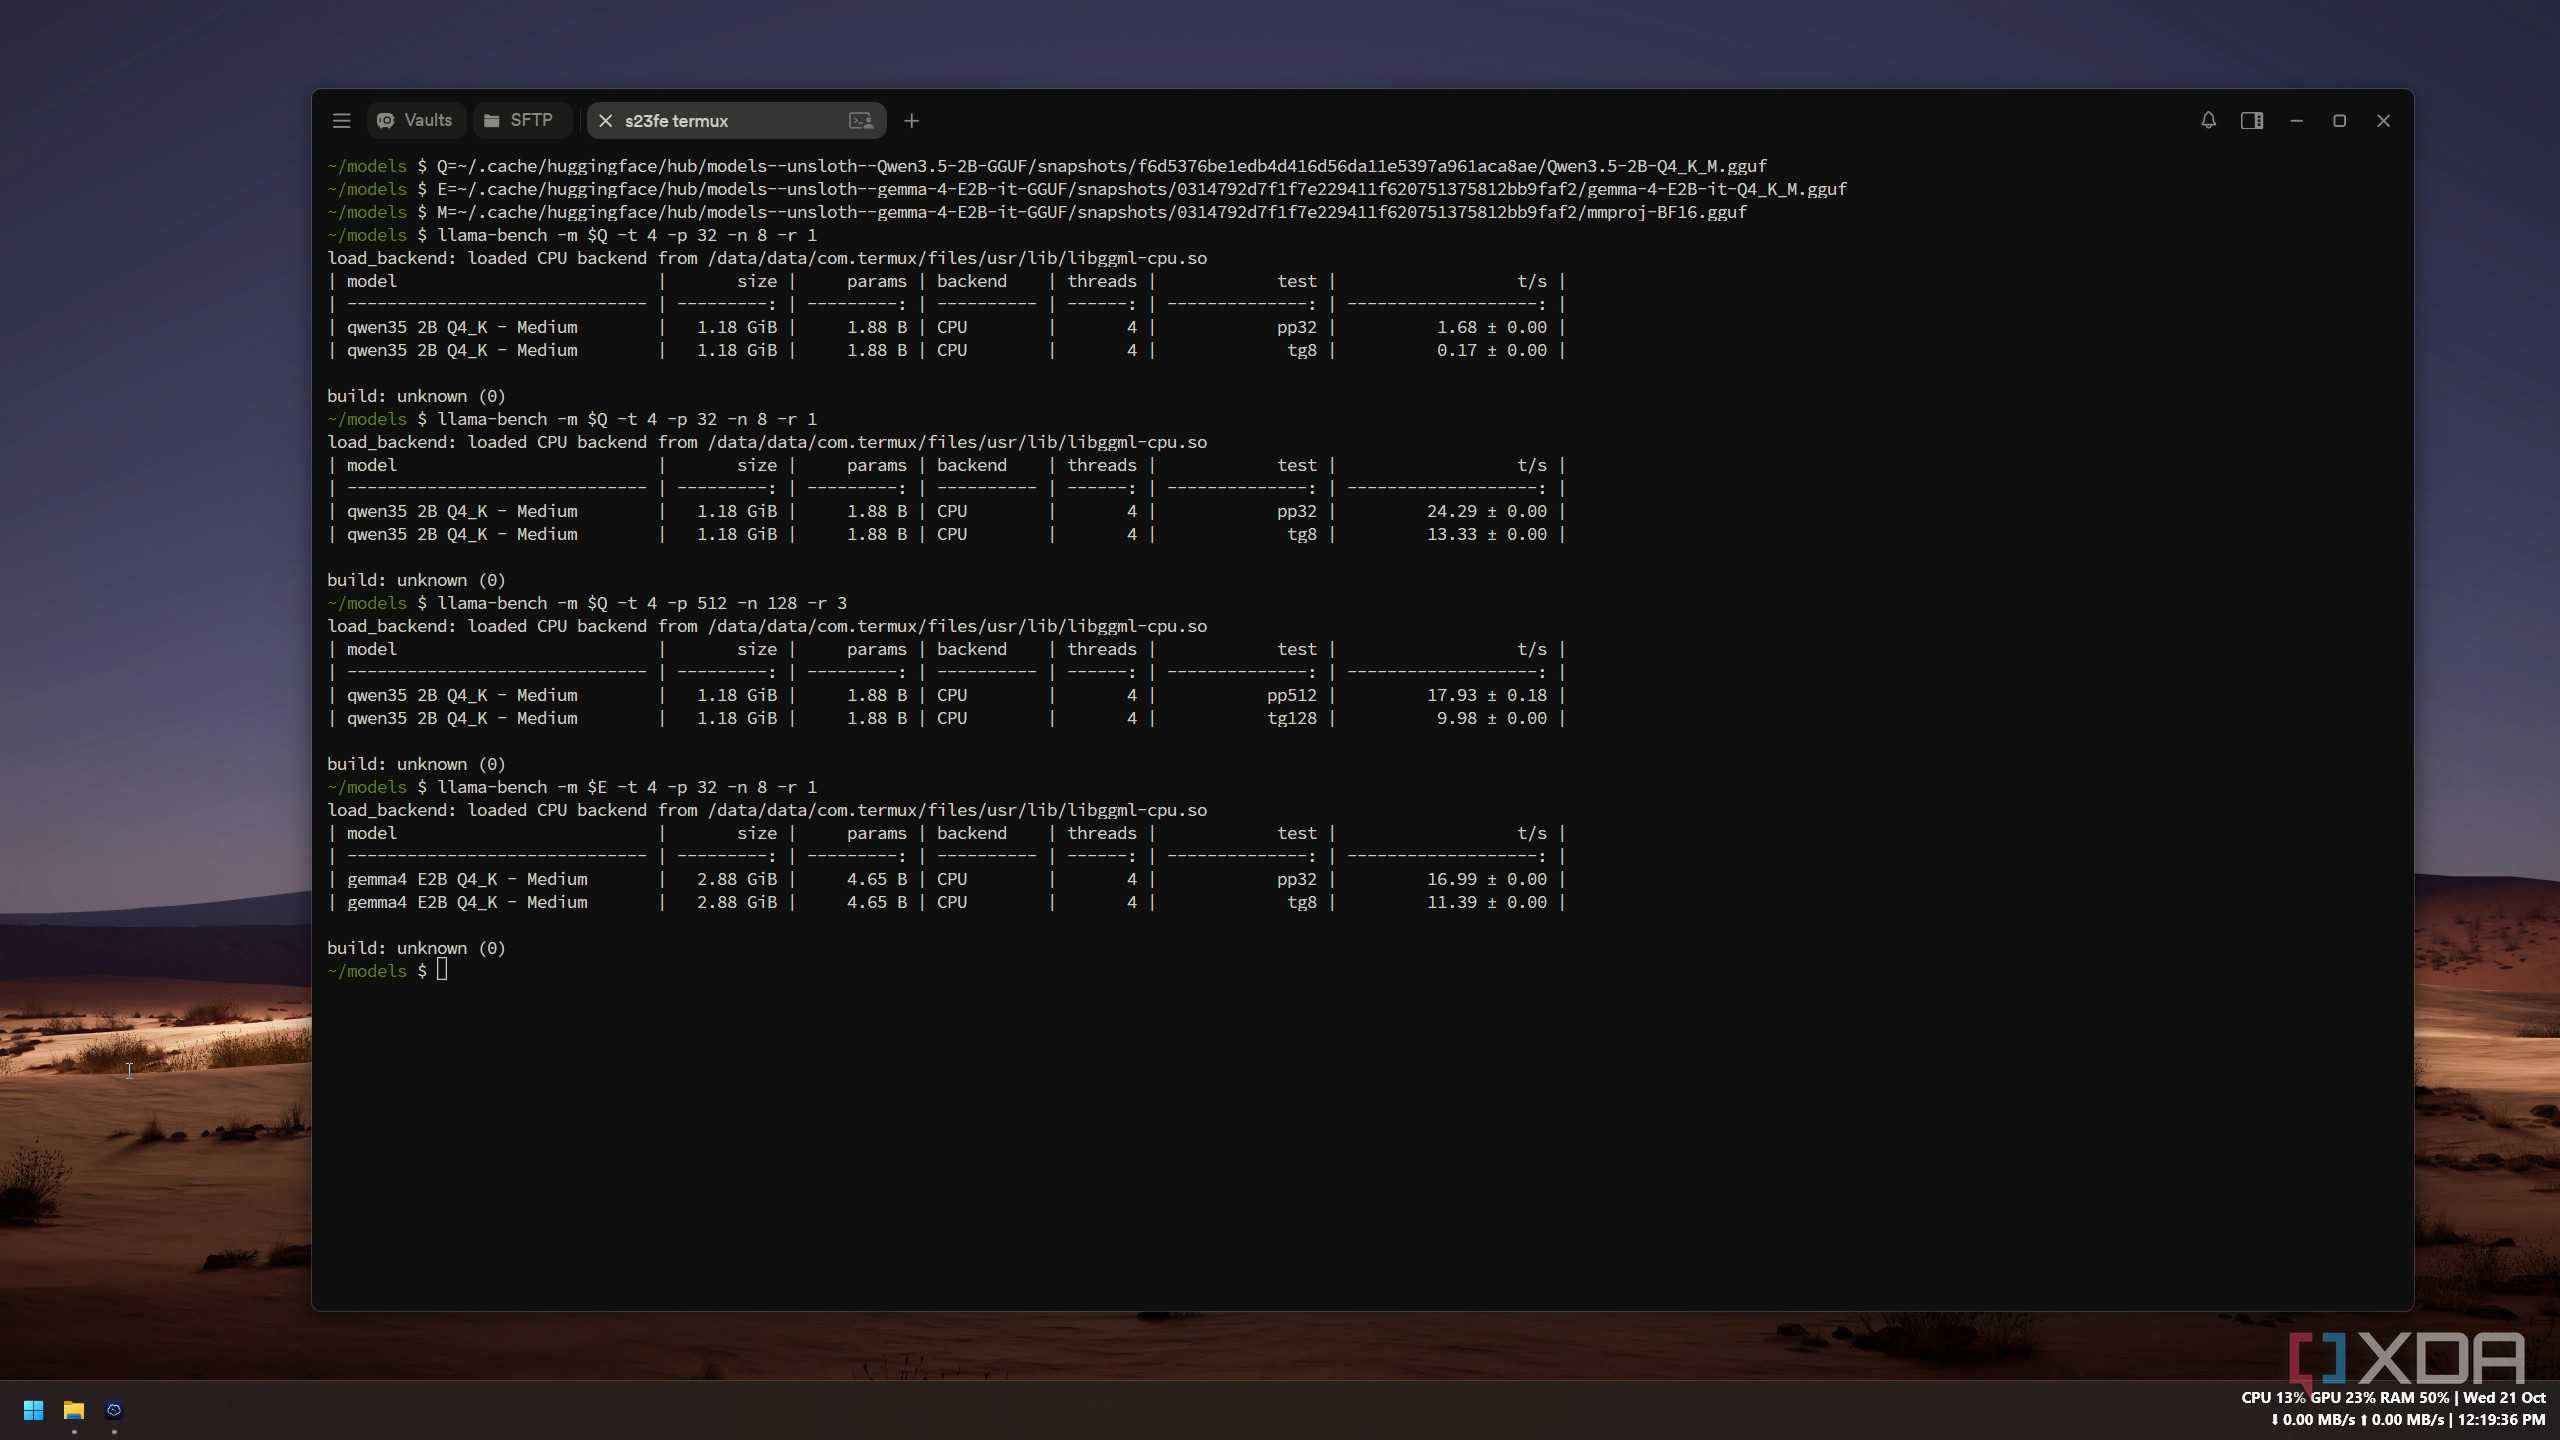
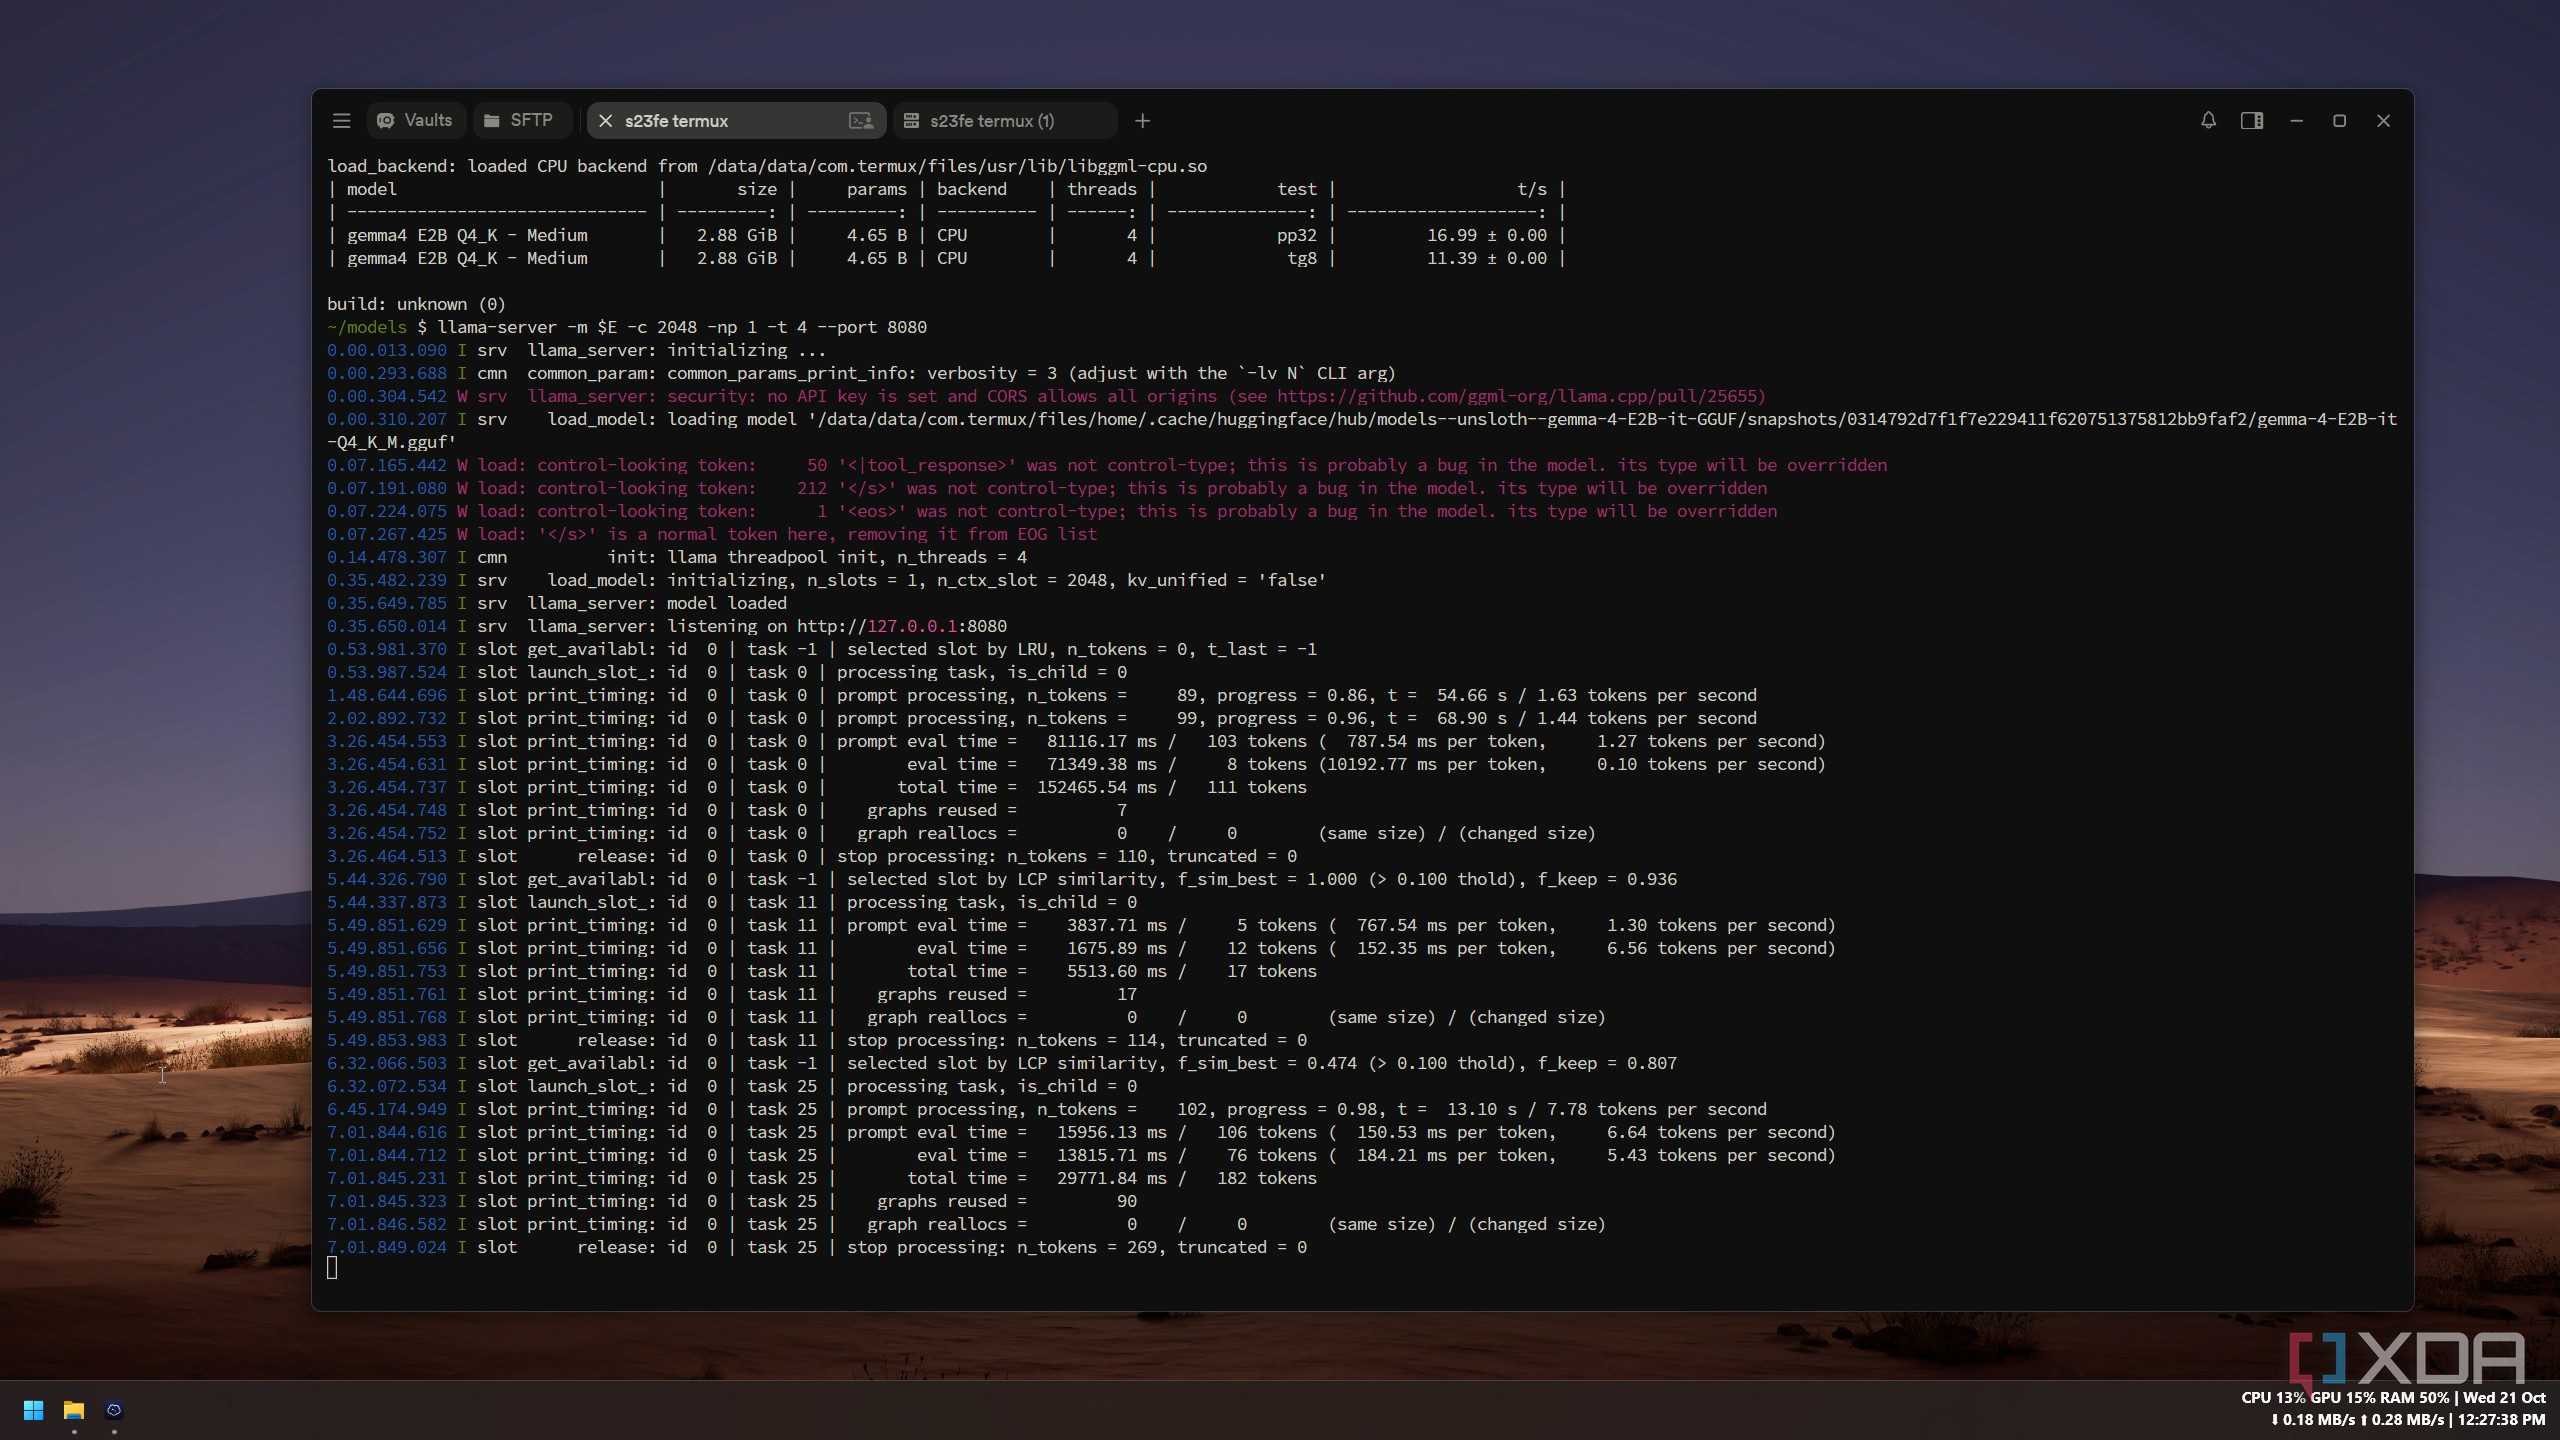
But before finalizing the model, one thought was still bugging me. I was still thinking the poor performance was something to do with the Termux running in the background. So, I decided to do a llama-bench test on Termux itself (SSH’s from PC). I started with Qwen 3.5, then moved to Gemma 4. The results were literally the opposite, and my doubt was right.
|
Test |
Model (Q4_K_M) |
Run |
Termux in front? |
Prompt processing (pp) |
Token Generation (tg) |
|---|---|---|---|---|---|
|
1 |
Qwen3.5 2B |
Short (pp32 / tg8) |
No, Chrome was |
1.68 tok/s |
0.17 tok/s |
|
2 |
Qwen3.5 2B |
Short (pp32 / tg8) |
Yes |
24.29 tok/s |
13.33 tok/s |
|
3 |
Qwen3.5 2B |
Long (pp512 / tg128, 3 reps) |
Yes |
17.93 ± 0.18 tok/s |
9.98 ± 0.00 tok/s |
|
4 |
Gemma 4 E2B |
Short (pp32 / tg8) |
Yes |
16.99 tok/s |
11.39 tok/s |
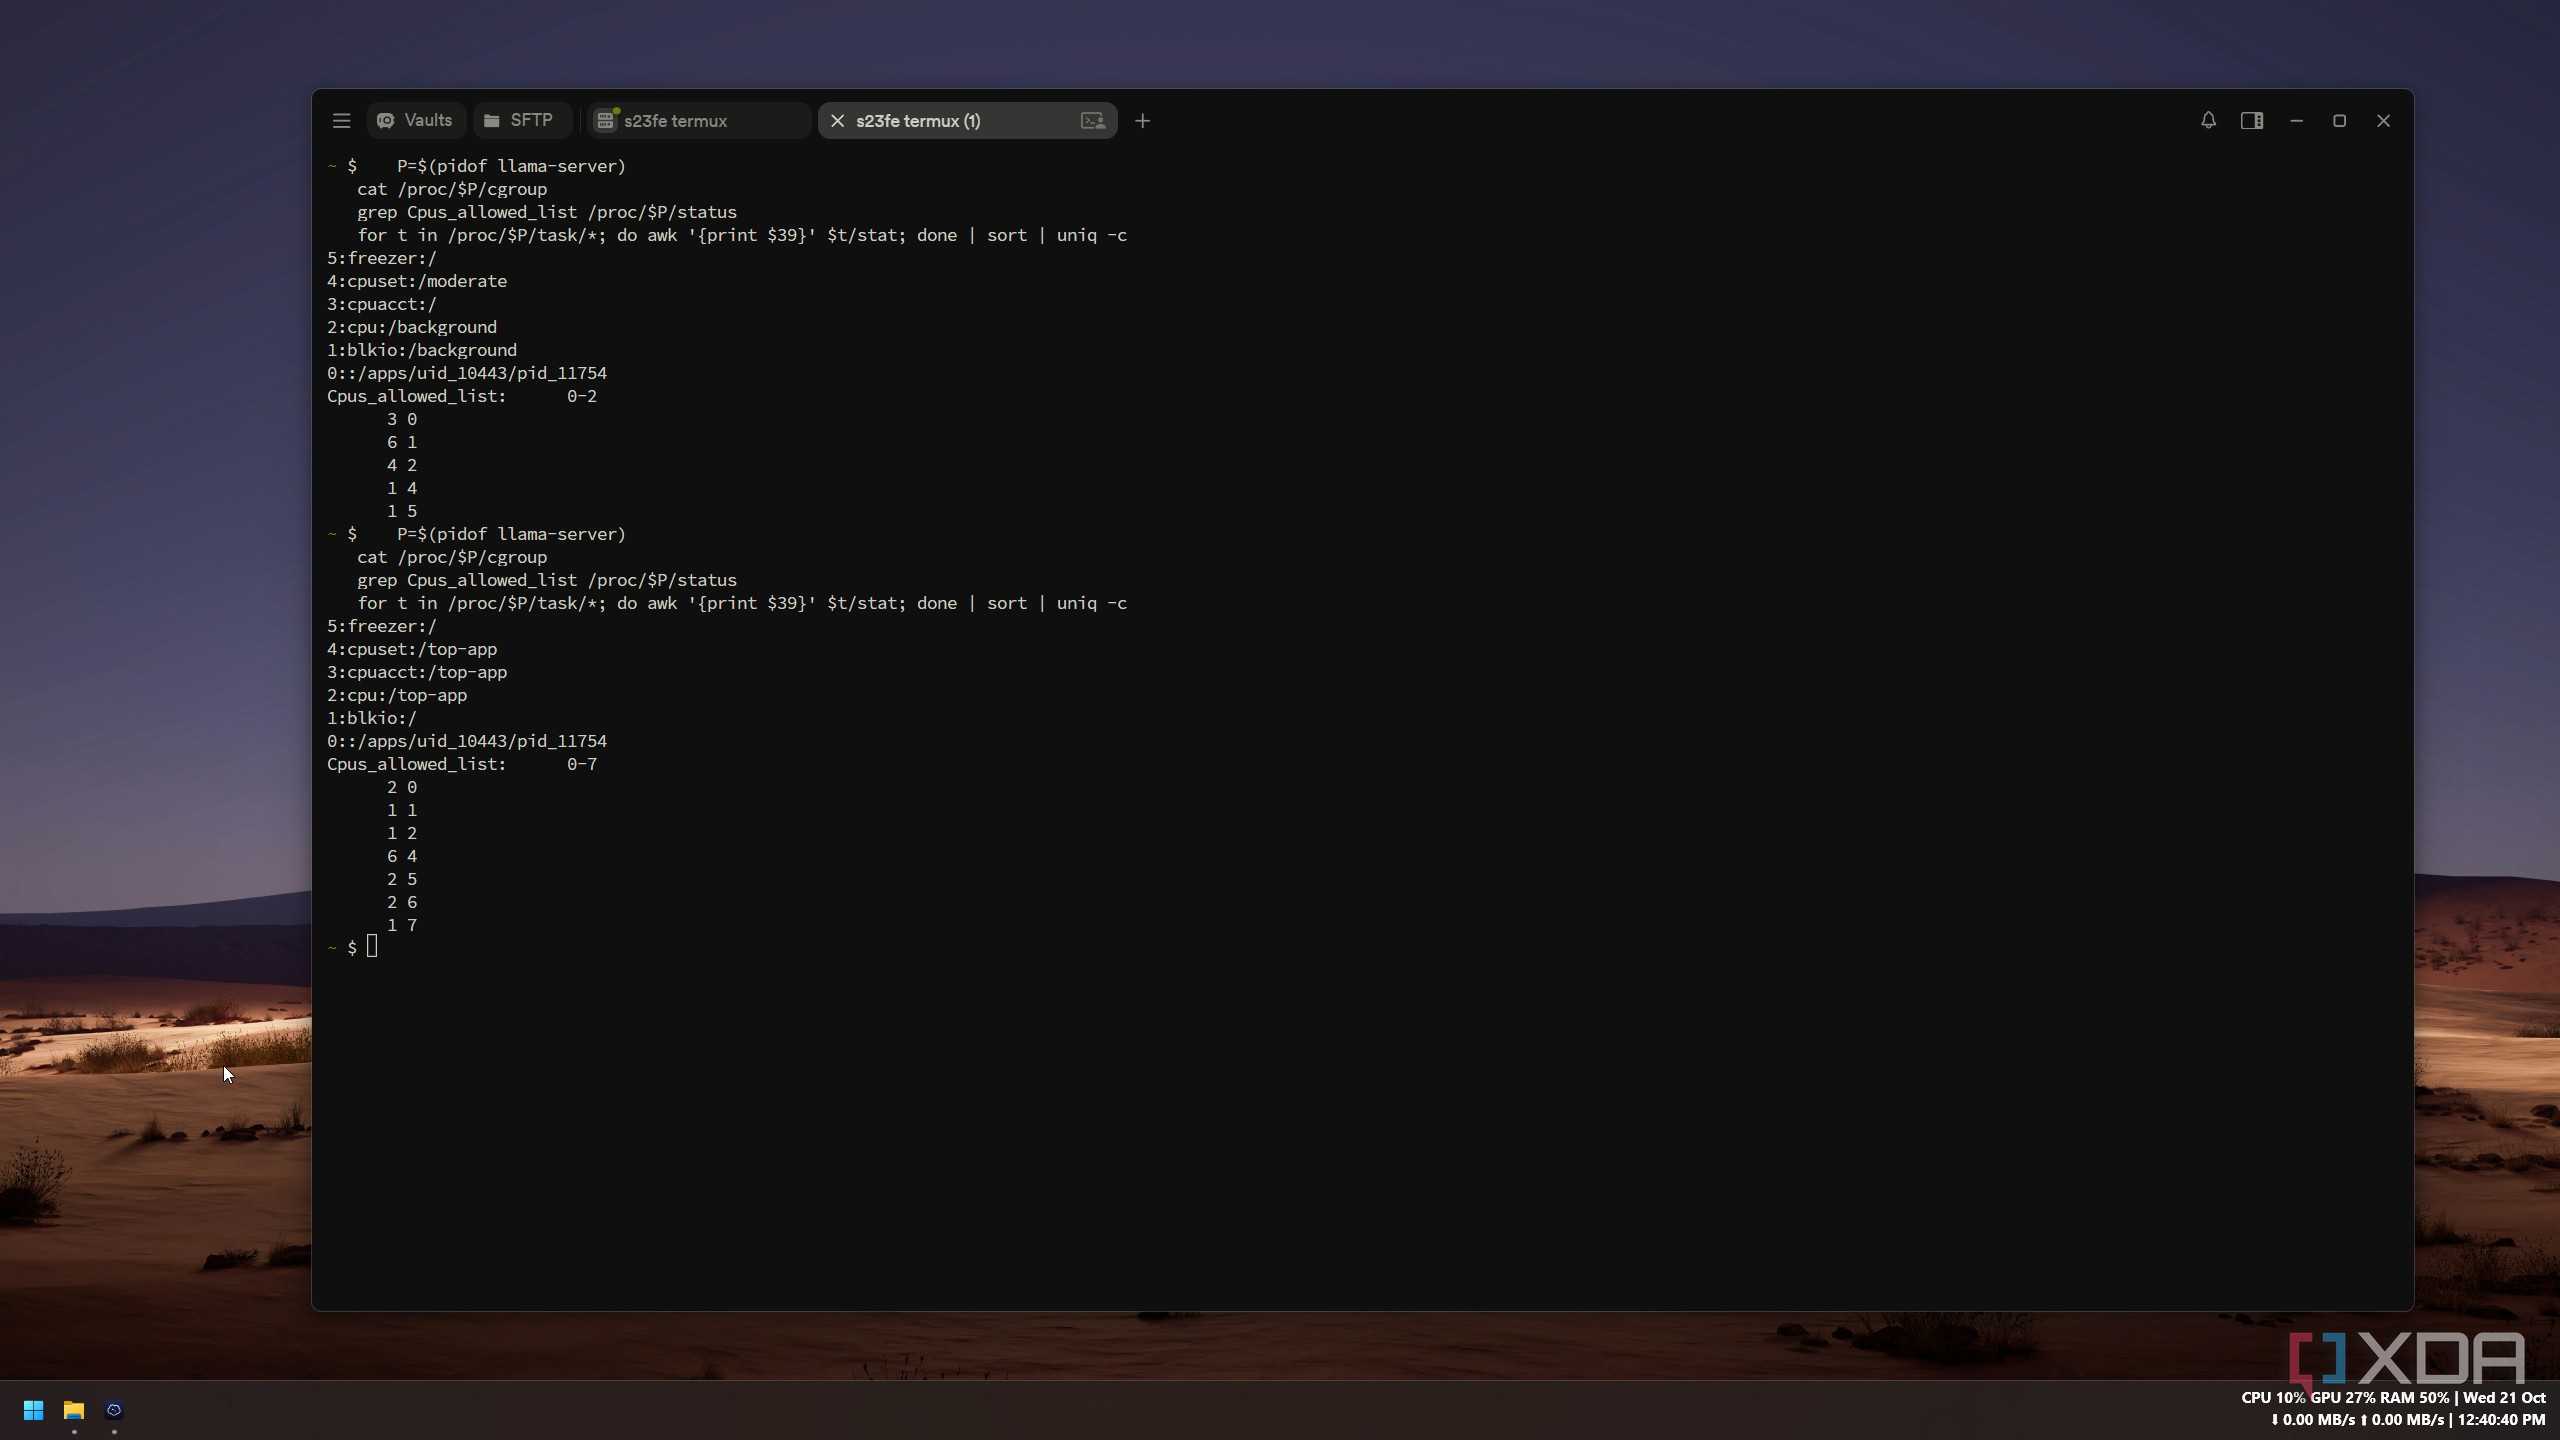
Gemma 4’s 0.1 tok/s generation jumped to 11.39 tok/s. That was about 100x improvement. So, I started digging into why it was happening. And landed on half of the cause when I checked the core count on each scenario (inspected /proc/
My hypothesis is that Android restricts apps without a visible window, and Samsung’s group seems to allow only three cores for apps in the background group. In the end, the viable solution was running both Termux and Chrome in split mode. And it worked as expected. With Gemma 4 E2B loaded and split screen, I got around 5.4-6.6 tok/s, which was usable. In a stress test, it generated 730 tokens in 2 min and 4 sec.
Good enough for the small stuff, if you check it
E2B got right what Qwen3.5 2B invented
Once that was settled, I needed to test Gemma 4 again for my use case. My day-to-day use cases are summarization, replying to emails, and sometimes a few technical calculations. As I expected, where Qwen 3.5 failed, it generated accurate answers without any iterations.
But I was not surprised by Gemma 4’s performance, because I have been using Gemma 4 on PC since its launch. On the other hand, Qwen 3.5 invented many things; for example, when I asked Qwen about Gemma, it invented model variants such as 4.5, 2.5, Ultra, and Turbo, and even gave me incorrect release dates with confidence. But this is the drawback of small models.
Now, coming back to the question I asked myself in the beginning: whether an old phone can take over some of the tasks I usually run on a cloud AI. The answer is yes, but with some conditions. The first wall is the split mode; I always have to keep both Termux and Chrome active. Second, since these are small models, I always have to double-check the results.
Not a replacement, but a good first stop
After a few days with this setup, I can say my Galaxy S23 FE won’t replace ChatGPT or Claude, but for small general tasks, I don’t have to run to them every time. The Gemma 4 E2B in split screen can handle straightforward rewriting, summarization, and classification with just a couple of caveats. I still don’t know if foreground scheduling was an Android issue or a Samsung one, so the next step is to test the same setup on a non-Samsung Android phone.