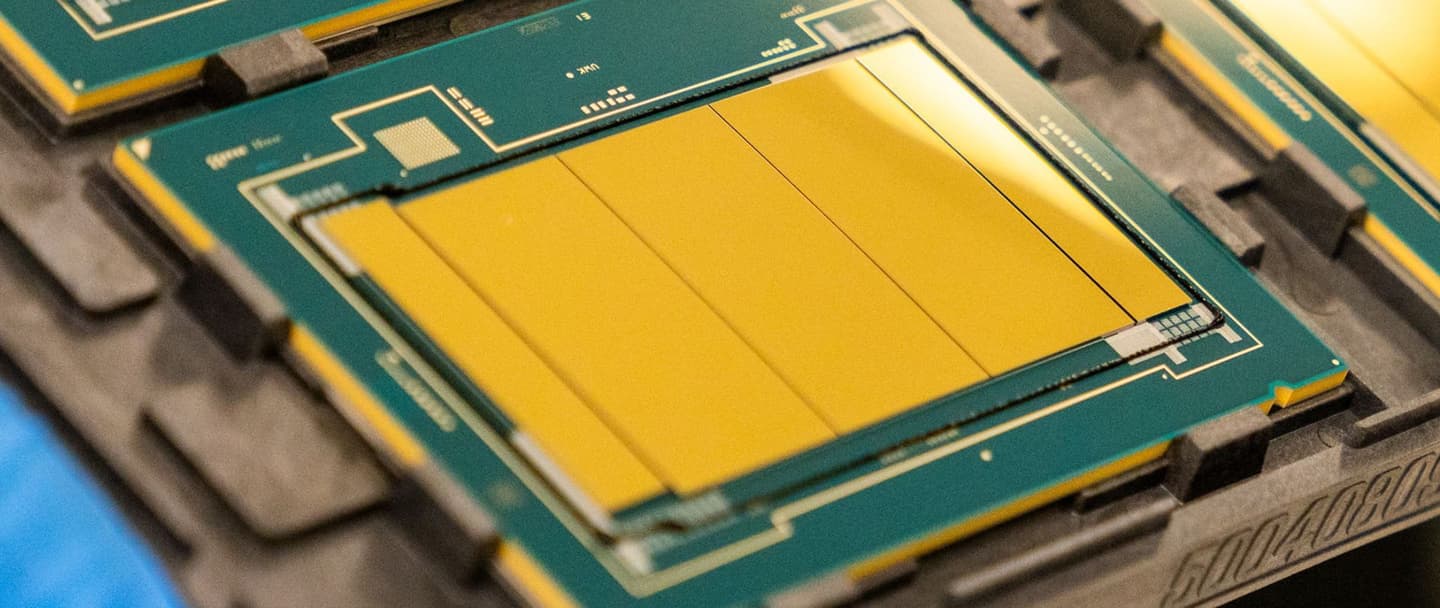
Advanced packaging technologies have become integral parts of advanced CPU and GPU designs, and virtually all of Intel's high-end client and data center CPUs rely on its Embedded Multi-die Interconnect Bridge (EMIB) and Foveros technologies. But what's next for these two advanced packaging methods? Before we try to see where both technologies are going, let's first take stock of where we are today.
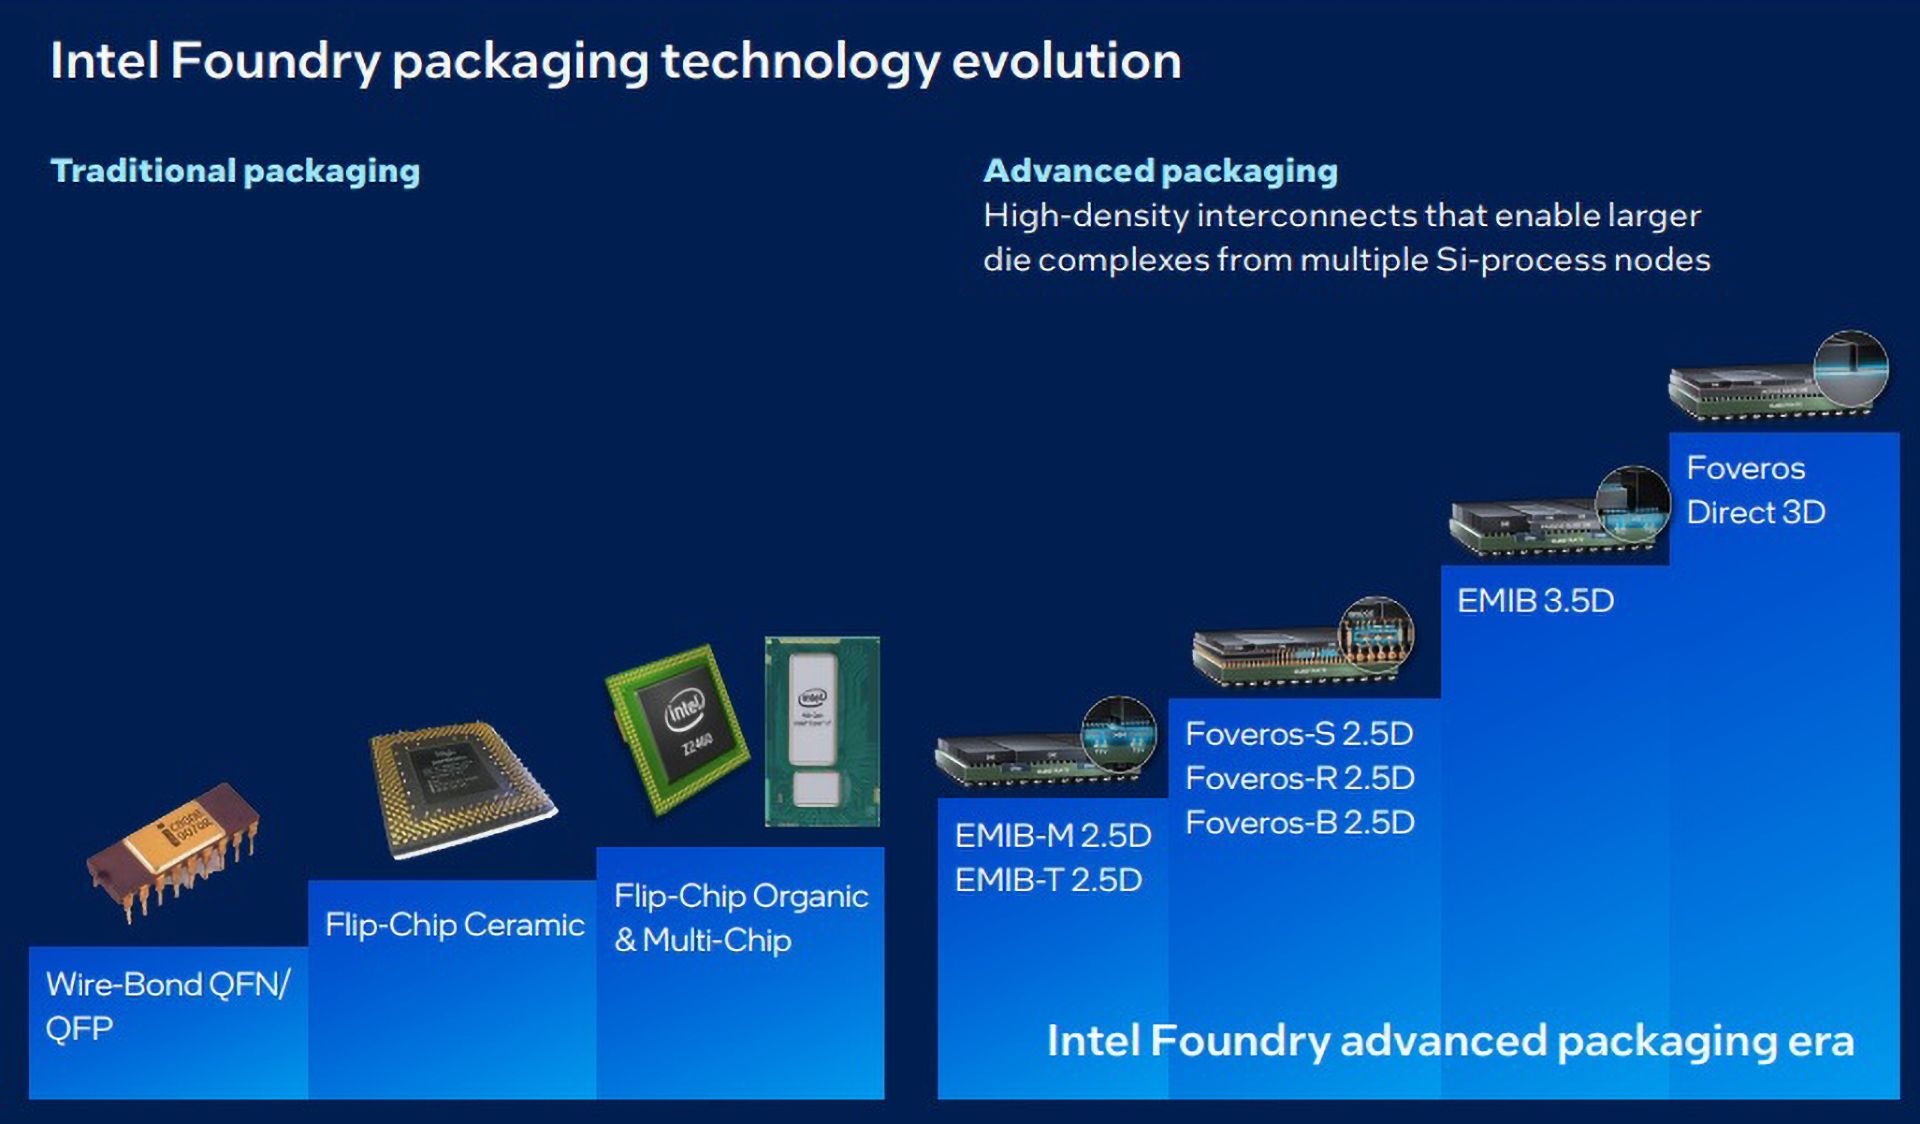
Although Intel's advanced packaging saga began in 2017 with the Kaby Lake-G CPUs and Stratix 10 FPGAs, packaging technologies weren't quite the hot topic they are today. However, both Intel and its industry peers were working relentlessly to advance these technologies, so Intel was among the first companies to outline a detailed roadmap for multi-chiplet processors featuring its 2.5D and 3D integration technologies — EMIB and Foveros — back in 2020. Following the fiasco with its initial 10nm process technology, the company made it clear that its multi-chiplet strategy is a sustainable way to deliver performance and feature enhancements cost-efficiently and at a predictable cadence. While we certainly cannot say that all of Intel's multi-chiplet projects were a success, it is safe to say that the majority of Intel's client and data center CPU products launched in recent years use multiple chiplets and rely on EMIB and Foveros advanced packaging technology.
In fact, as Intel's advanced packaging roadmap evolves, EMIB and Foveros not only become more sophisticated to address the demands, but they also become simpler to cover cost-sensitive products. Another peculiarity about Intel's packaging duo is that they no longer seem to be two mostly separate technologies. In many cases, they complement each other and Intel's upcoming process technologies, thereby becoming key building blocks of the company's future products. The ultimate goal is to build system-in-packages (SiPs) the size of 12 reticles using both EMIB and Foveros Direct 3D, but Intel is not quite there yet, so let's take a look at where we are today and what's on the horizon.
EMIB: Fantastic bridges and where to find them
Intel's EMIB has evolved dramatically since entering high-volume manufacturing in 2017. What started as a relatively straightforward way to connect adjacent chiplets without using an expensive silicon interposer has become a sophisticated packaging technology used for data center processors and is set to enable massive AI accelerators 12 times the size of a reticle with dozens of silicon bridges, more than 24 HBM stacks, and advanced power delivery.
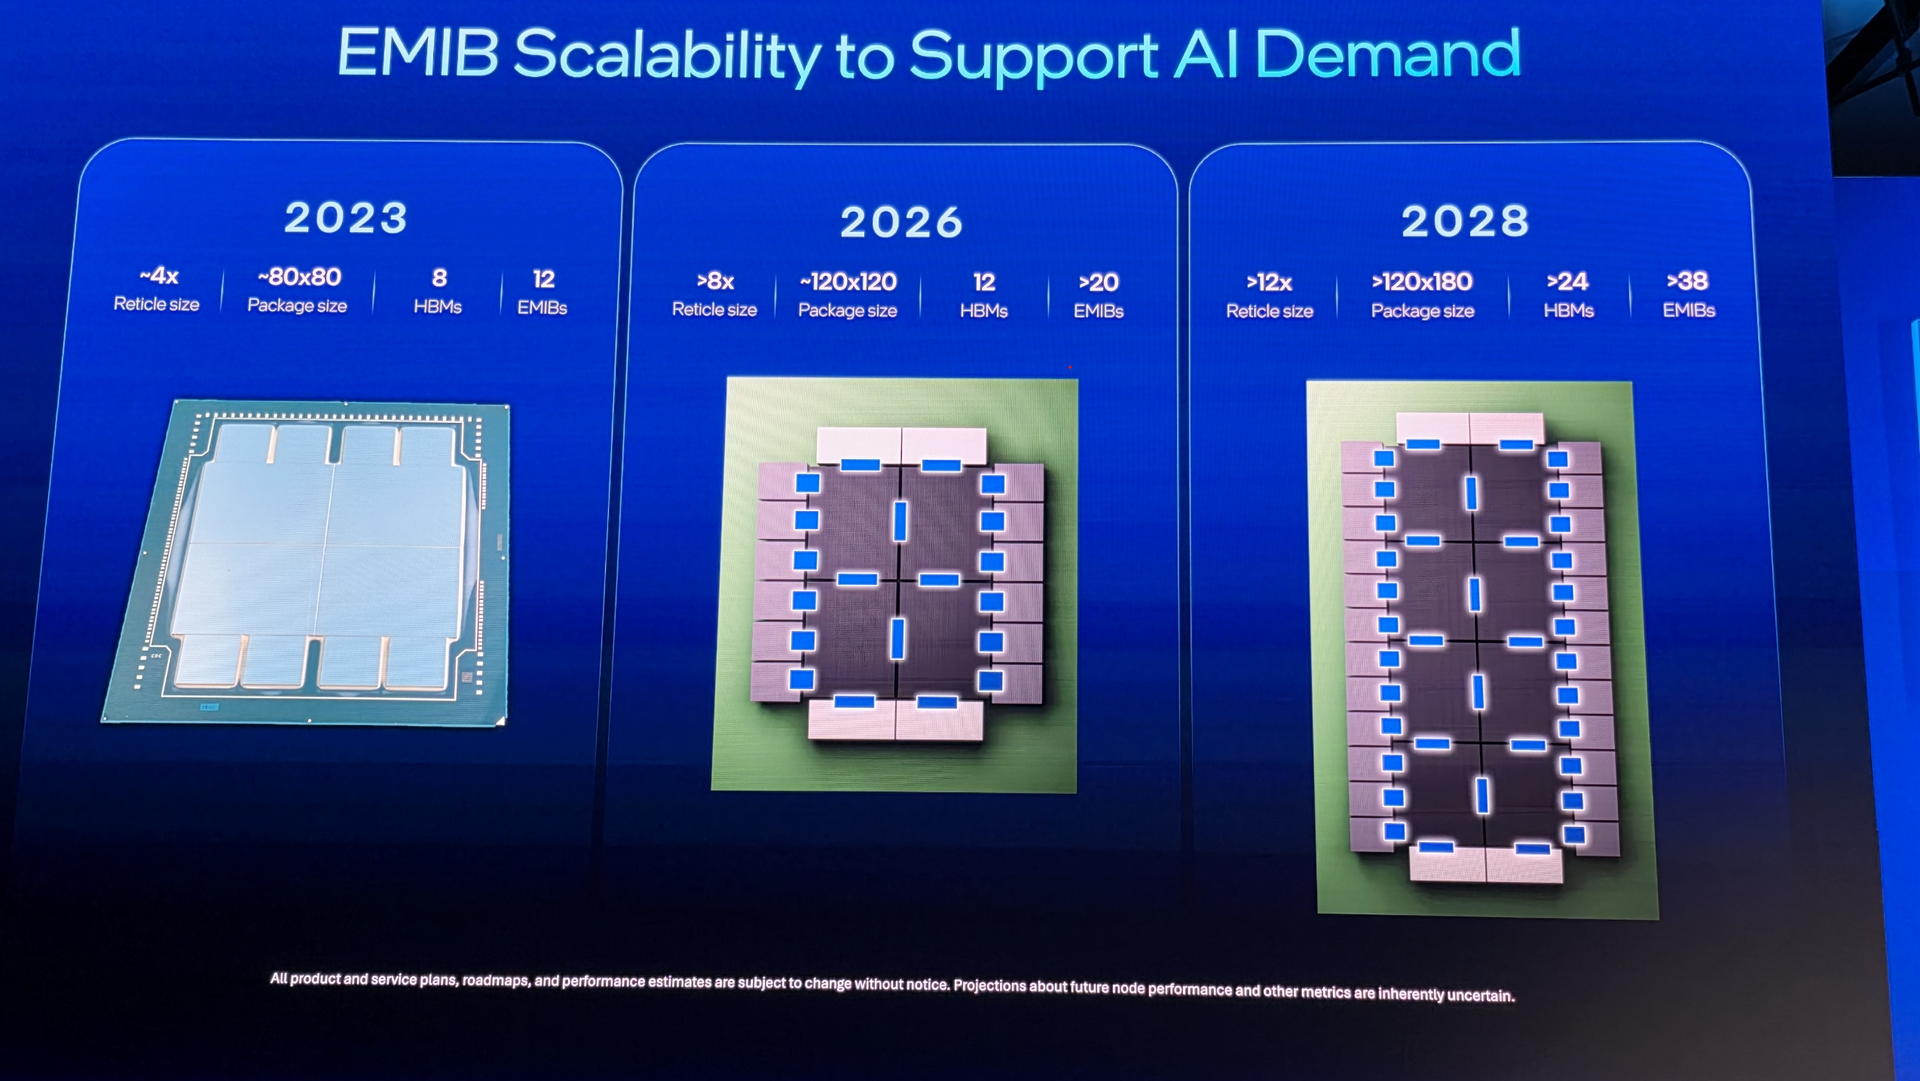
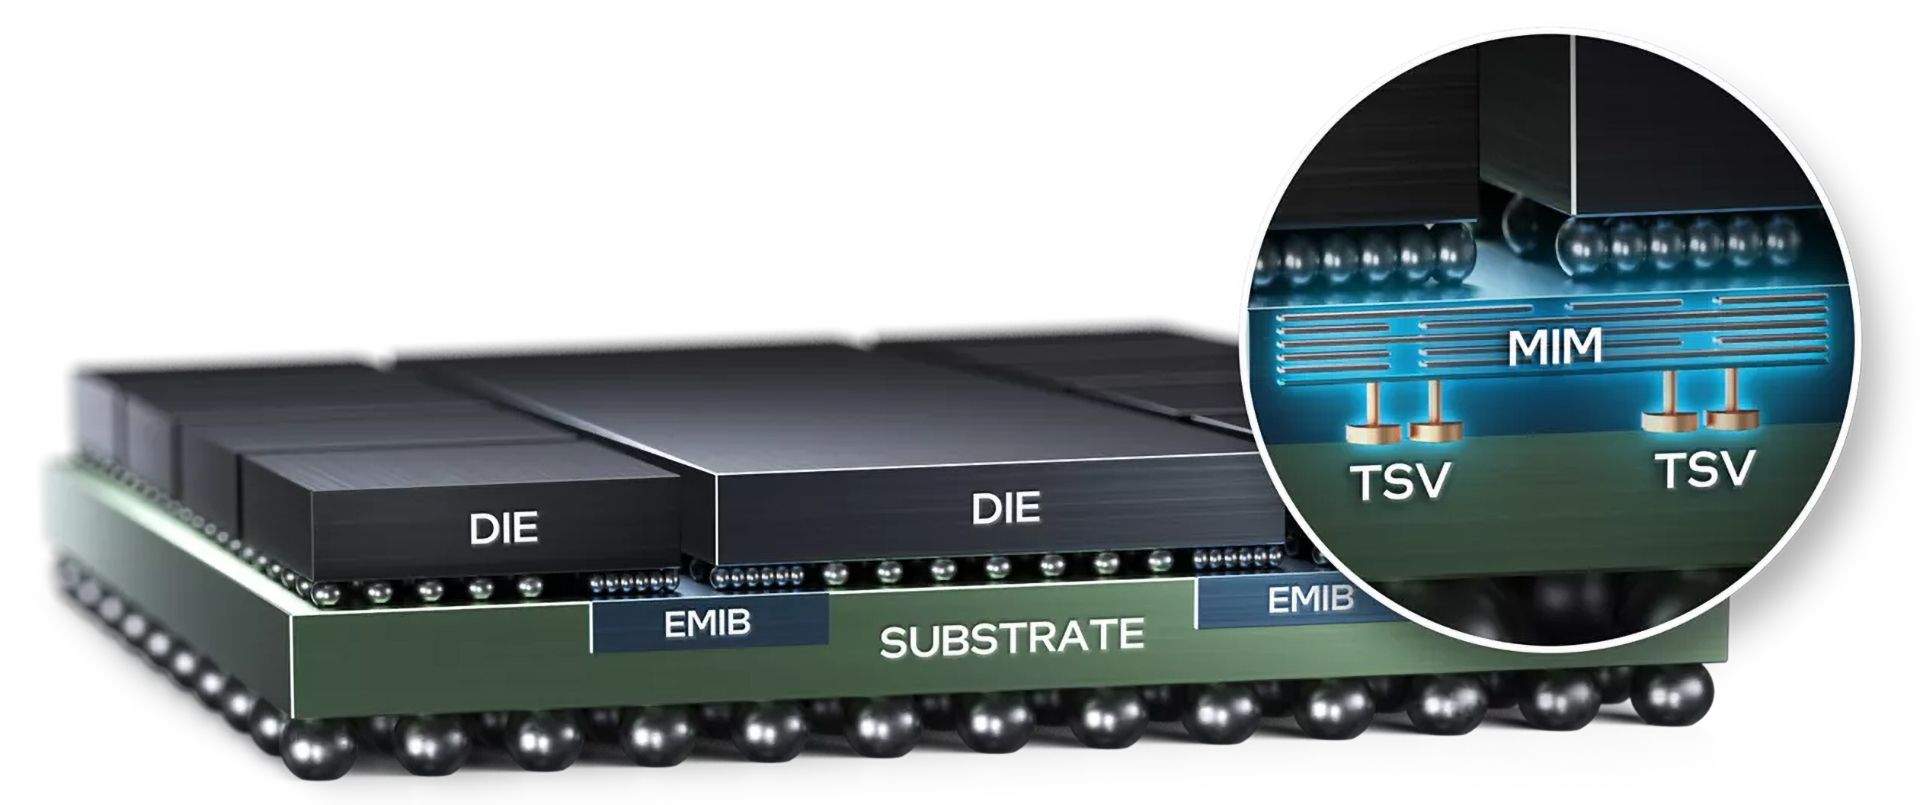
The basic idea behind EMIB remains unchanged almost a decade after its first introduction. Instead of placing compute and memory dies on a large silicon interposer, Intel embeds tiny silicon bridges into an organic package substrate only where high-density die-to-die connectivity is required (try to find those bridges!). This reduces silicon usage and allows the rest of the package to use conventional substrate wiring and relaxed bump pitches. Early EMIB implementations used a 55-µm first-layer-interconnect (FLI) bump pitch, which Intel subsequently reduced to 45 µm. Intel's recent roadmaps indicate further reductions to around 36 µm and ultimately 25 µm, which dramatically increases the number of connections that can fit along a chiplet's edge (shoreline density).
In addition to shrinking FLI bump pitches and increasing connection density, Intel is also adding functionality to the bridges themselves. EMIB-M incorporates metal-insulator-metal (MIM) capacitors into the bridge to improve power delivery and suppress voltage fluctuations close to compute dies. The newer EMIB-T takes this concept considerably further by adding through-silicon vias (TSVs), which enable power to travel vertically through the bridge instead of taking longer paths around it. This becomes increasingly important for multi-kilowatt system-in-packages (SiPs) and HBM4-class memory subsystems, where both current density and power integrity are major packaging constraints.
EMIB 1st Gen | EMIB 2nd Gen | EMIB-M | EMIB-T | EMIB-T evo | EMIB-T glass | |
Bump Pitch | 55 µm | 45 µm | 45 µm ~ 36 µm | 45 µm ~ 36 µm | 25 µm | <25 µm |
Number of Bridges | 6 | 12 | >20 | >38 | ? | ? |
Bump Density | 330 mm^2 | 494 mm^2 | 494 => 772 mm^2 | 494 => 772 mm^2 | 1600 mm^2 | 1600 mm^2 |
C2C Power | 0.5 pJ/bit | 0.3 - 0.5 pJ/bit | 0.25 pJ/bit | 0.25 pJ/bit | ? | ? |
TSV | - | - | - | + | + | + |
Die Complex | 2X reticles | 4X reticles | 8X reticles | 12X reticles | ? | panel |
HBM Stacks | 4 | 8 | 12 | 24 | ? | ? |
Capacitor | - | - | MIM | MIM | MIM (?) | MIM (?) |
Substrate | organic | organic | organic | organic | organic | glass |
Package size (mm) | 50 × 50 | 80 × 80 | 120 × 120 | 120 × 180 | ? | 240 × 240 (?) |
Year | 2017 - 2023 | 2023 | 2024 - 2026 | 2028 | ? | 2030+ |
Such SiPs are not only complex, but they are physically large, so Intel's EMIB has evolved to support larger designs. Firstly, a finer FLI pitch increases the interconnect density required to build bigger SiPs. Secondly, EMIB-M addresses the power-integrity problem created by big processors, such as Intel's Xeon 6 'Granite Rapids.' Thirdly, EMIB-T simplifies power routing, lowers impedance, and reduces noise, which will get more important when faster versions of UCIe (32 GT/s and higher) become commonplace. Intel's consistent EMIB technology development has enabled the company to move from an SiP of 4X reticle size on an 80×80 mm package earlier this decade, to something closer to 8X reticles on a 120×120 mm package today, and even larger 12X SiPs on a 120×180 mm package in the future.
Eventually, Intel plans to combine finer-pitch EMIB technology with glass-core substrates. Glass offers better stability and reduced warpage compared with organic materials, which becomes increasingly important as packages grow to enormous sizes. Glass will likely be one of EMIB's biggest advancements, as it will enable improvements in multiple directions, including performance and dimensions.
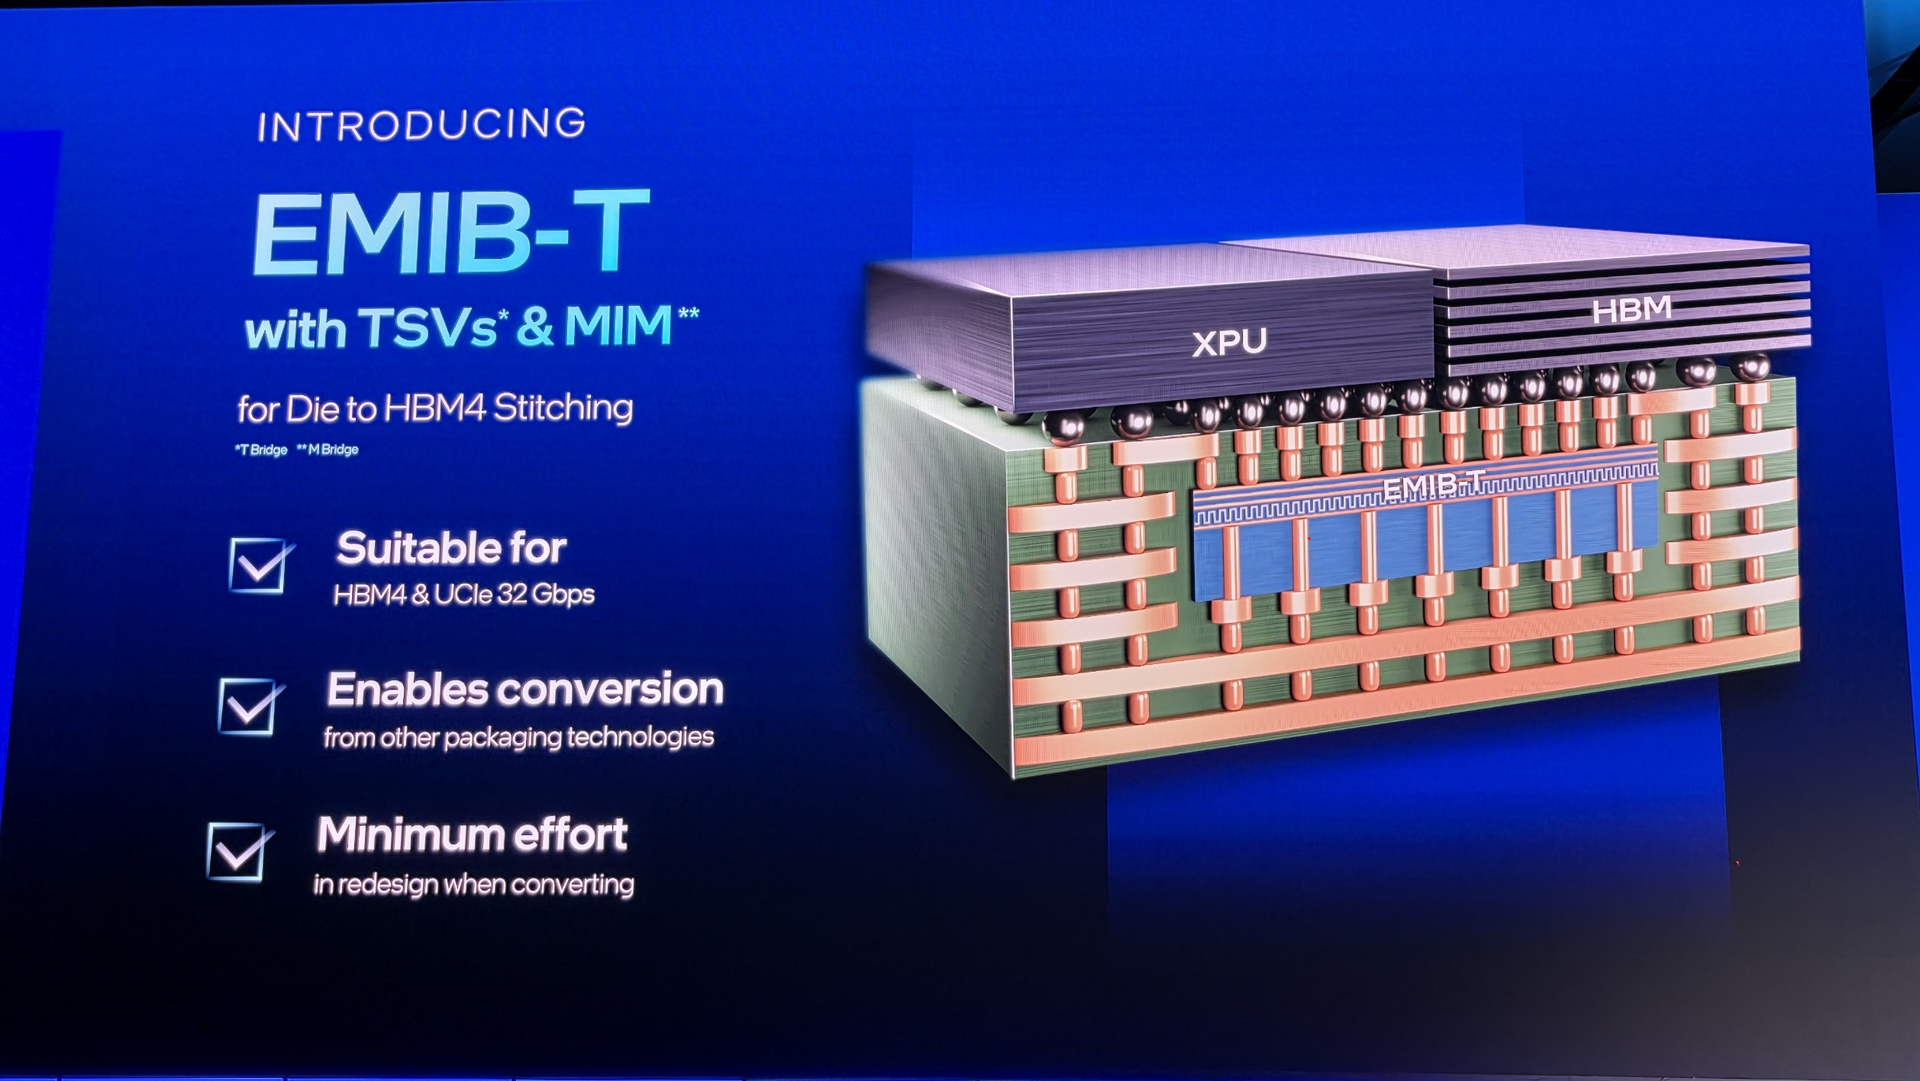
Intel says EMIB-T is on track for mass production in 2027 and its yields and reliability are meeting its targets. If those ramps proceed as planned, EMIB will have evolved from an alternative to a silicon interposer into one of Intel Foundry's key technologies for building massive AI systems.
"Customer interest in EMIB-T continues to be very high – the technology is compelling, providing capabilities for advanced AI silicon solutions which are not possible with today's mainstream offerings," said Lip Bu Tan, chief executive of Intel, in an August 2026 earnings call. "We continue to have a growing EMIB-T backlog, yield and reliability are hitting targets, and we are focused on ramping the technology into high volume and high quality to support customer ramps in 2027."
Intel is scaling EMIB along several directions simultaneously: finer interconnect pitch, more bridges, larger substrates, denser power delivery, faster memory interfaces, and dramatically larger SiPs. Intel formally positions EMIB as a cost-effective advanced packaging technology that uses local silicon bridges for logic-to-logic and logic-to-HBM connections in an organic substrate instead of large silicon interposers used by solutions like TSMC's CoWoS-S. Meanwhile, there are applications that can benefit from large, rigid interposers or flexible organic redistribution layer interposers. To address these applications, Intel's Foveros portfolio includes Foveros-S, Foveros-R, and Foveros-B, which more directly mirror TSMC's CoWoS-S, CoWoS-R, and CoWoS-L packaging technologies, respectively.
Foveros 2.5D: A fistful of packages
Intel's Foveros packaging technology is evolving from its original chip-on-wafer implementation that emerged in 2019 with the Lakefield processor into a broad family of 2.5D and 3D integration technologies designed to address everything from cost-sensitive client processors to large HPC and AI systems.
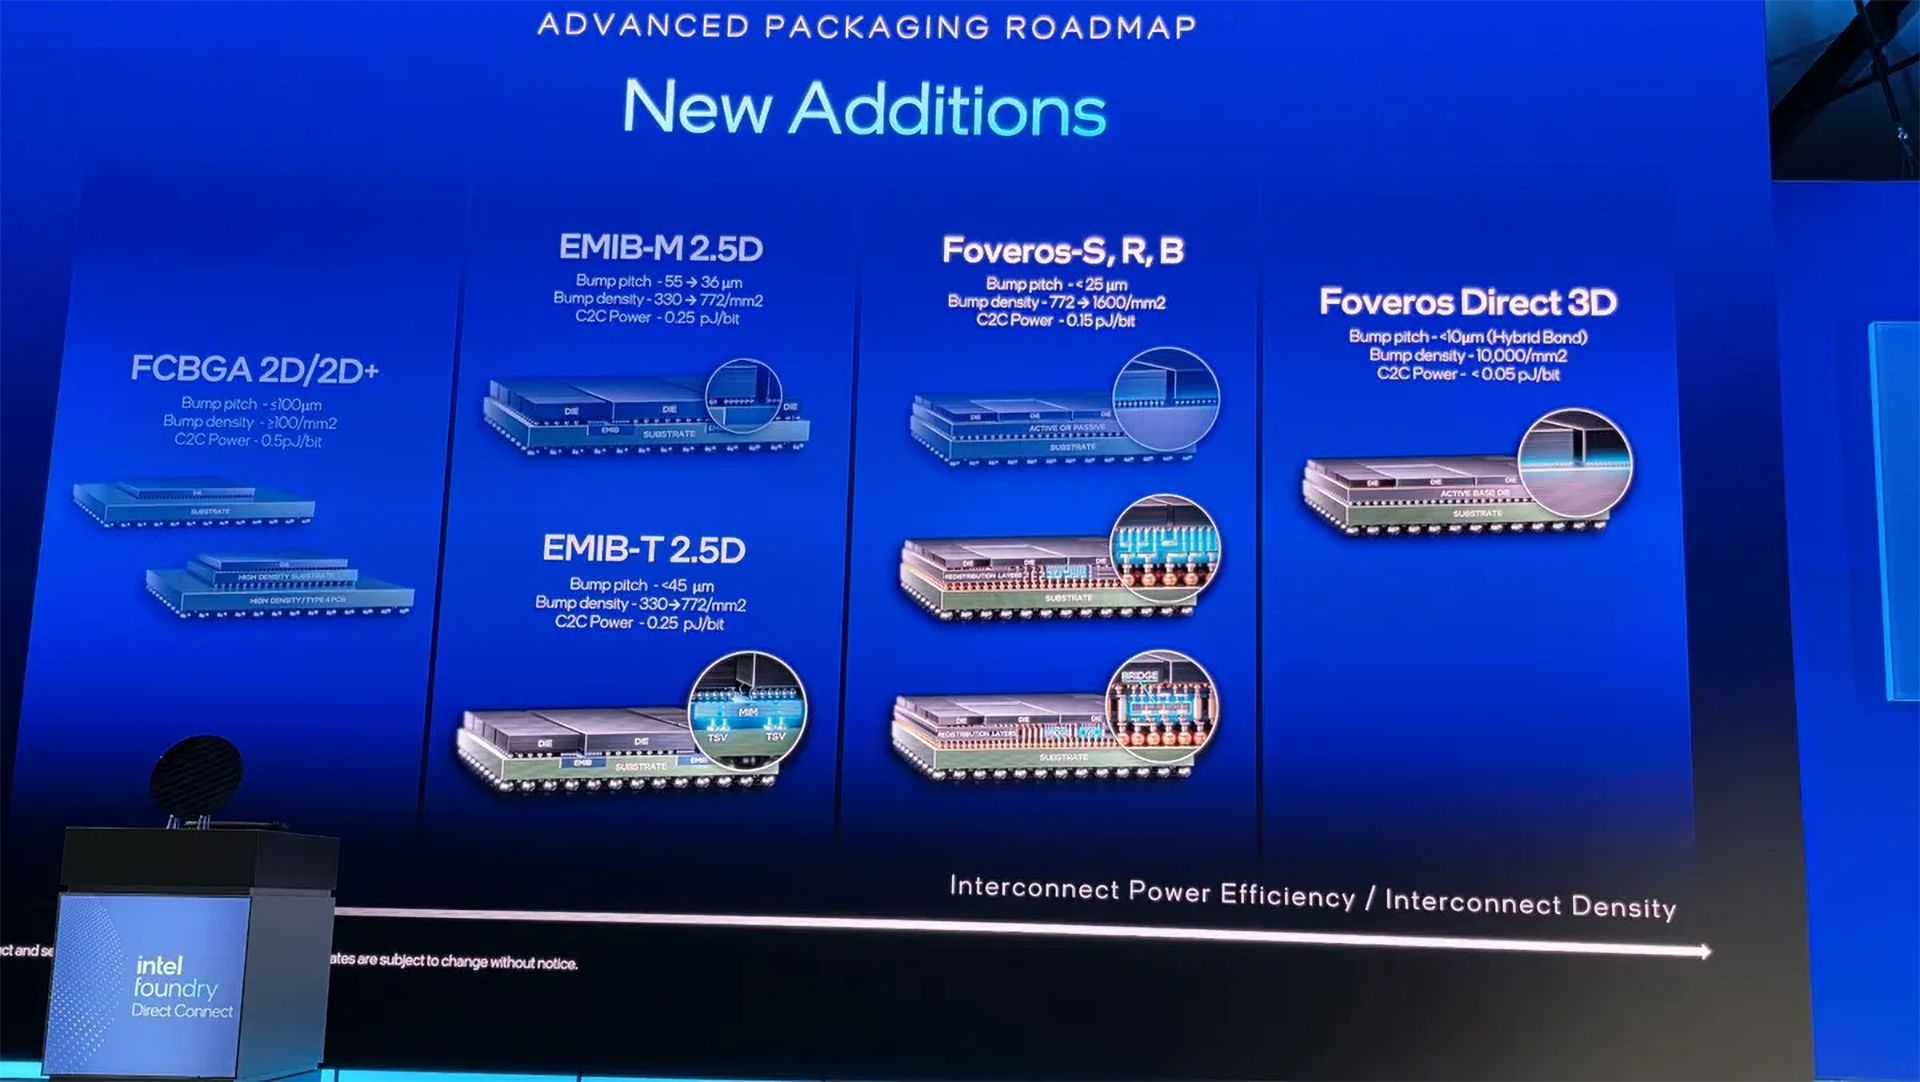
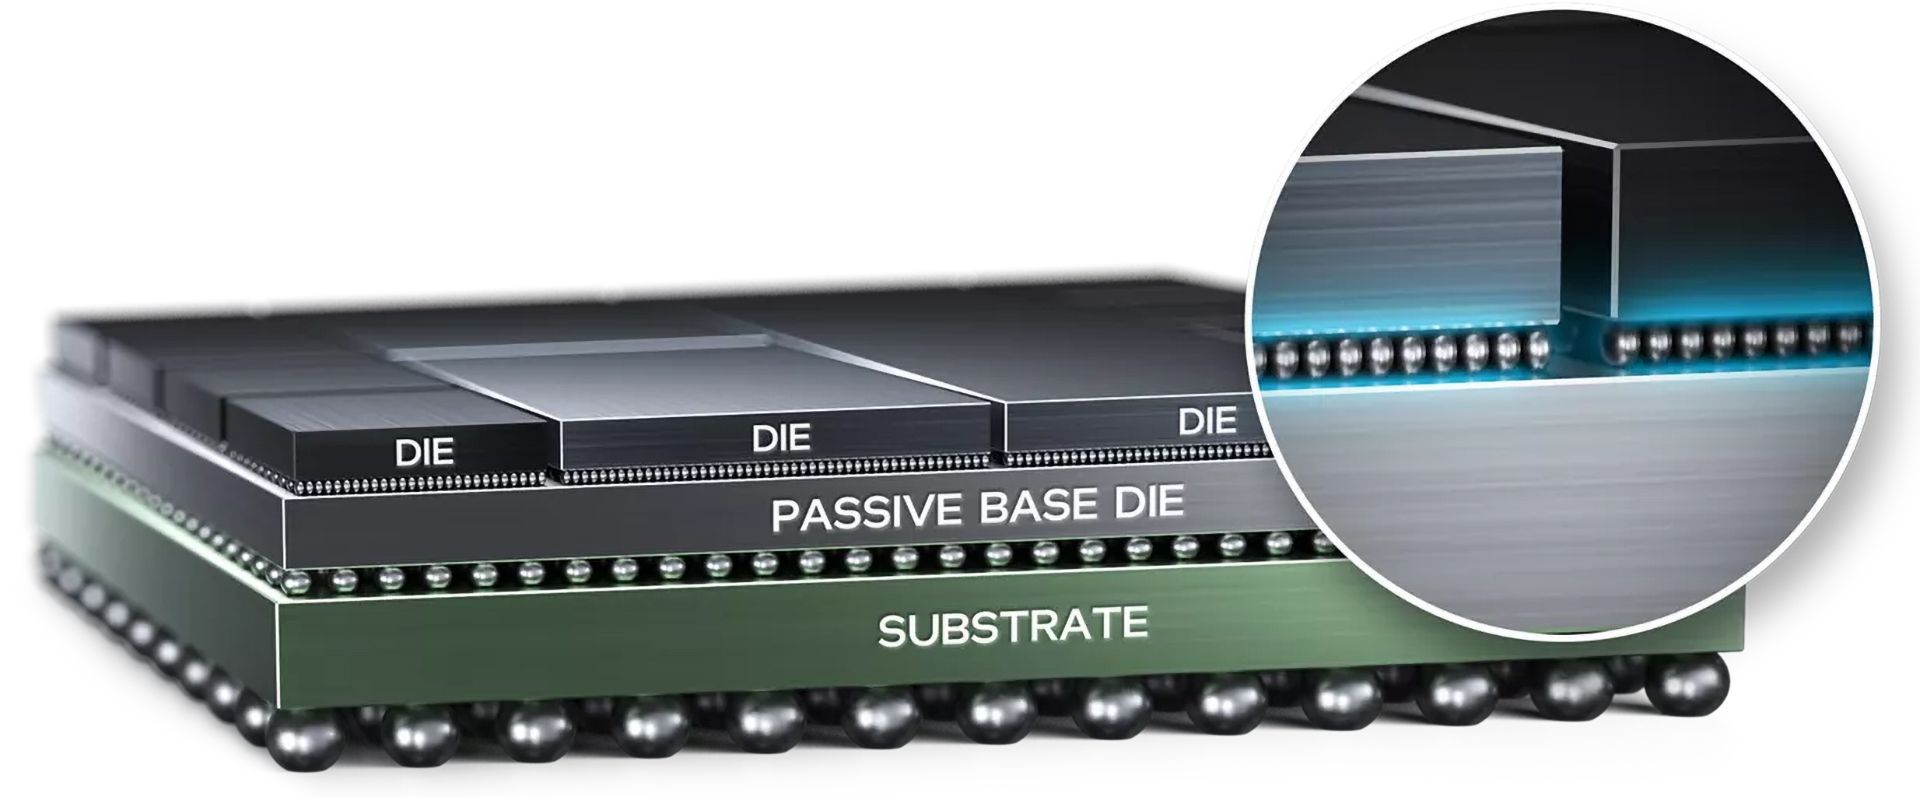
The original Foveros technology used an active 22FFL-based silicon base die, or interposer, with through-silicon vias (TSVs) and active dies attached using face-to-face bonding. Intel's Lakefield and Ponte Vecchio used active base dies and 36 µm microbump pitches, whereas Meteor Lake, Arrow Lake, and Panther Lake implementations use a passive base with a 36 µm microbump pitch. Since the introduction of Foveros with active and passive base dies in 2019 – 2023, Intel has also diversified Foveros to address different cost and integration requirements. The latest Foveros 2.5D roadmap — which mentions -S, -R, and -B variants with similar characteristics — presented in mid-2025, takes Foveros considerably further from its original capabilities: it targets pitches below 25 µm, bump density increase from 772 to 1,600 connections per mm², and chip-to-chip interconnect power of 0.15 pJ/bit.
Foveros-S | Foveros-R | Foveros-B | |
Bump Pitch | 36µm => 25µm => <25µm | 36µm => 25µm => <25µm | 36µm => 25µm => <25µm |
Hybrid Bonding | - | - | - |
Local Bridges | - | - | Yes |
Bump Density | 772-> 1600/mm^2 | 772-> 1600/mm^2 | 772-> 1600/mm^2 |
C2C Power | 0.15 pJ/bit | 0.15 pJ/bit | 0.15 pJ/bit |
TSV | - | - | ? |
Die Complex | 4X reticle | RDL limited | Bridge limited |
HBM Stacks | 8 (?) | Dependant upon interposer size | Dependant upon interposer size |
Capacitor | - | ? | |
Substrate | Organic | Organic | Organic |
Package size (mm) | ? | ? | ? |
Year | 2019 | 2027 | ? |
For now, the most advanced and yet production-proven Foveros 2.5D technology is Foveros-S. This packaging technology places multiple chiplets on a silicon interposer and currently supports packages up to four reticles in size, which is below what TSMC offers with CoWoS-S (up to 5.5X reticles). Since Foveros-S is essentially an evolution of the original Foveros from 2019, Intel legitimately says that it has been in volume production since 2019. Yet, going forward, Foveros-S will be evolving in multiple directions, which includes larger package sizes, interconnect density, and interconnect power efficiency.
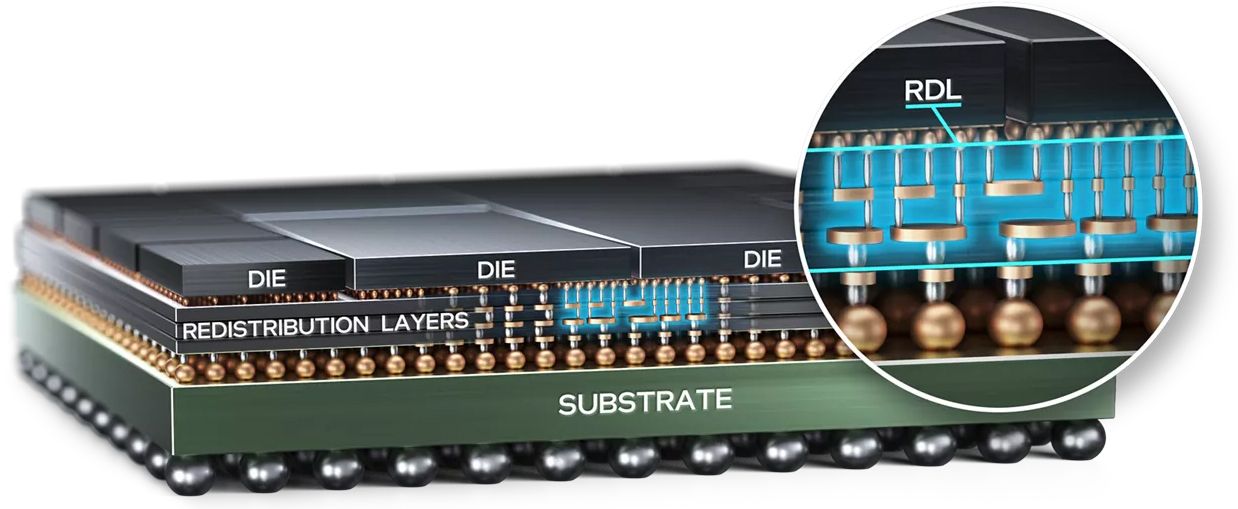
Foveros-R removes the silicon interposer altogether and uses fan-out RDL technology to optimize cost and interconnect density. Intel says the implementation can use up to three redistribution layers. The method is designed to offer a balance between cost and interconnect density and enable heterogeneous integration of chiplets from different sources through UCIe. Like the other members of Intel's current Foveros 2.5D family, the technology uses 36 µm microbump pitches, but is designed to support pitches below 25 µm as well as bump density scaling from 772 to 1,600/mm² and chip-to-chip interconnect power of 0.15 pJ/bit. Intel says Foveros-R will be production-ready in 2027.
Foveros-B extends the concept toward larger and more complex AI/HPC designs. Instead of relying on a full silicon interposer, the technology combines RDLs with local active or passive silicon bridges that provide high-density connections only where they are needed. This potentially gives Intel an intermediate option between an RDL-only implementation and a large silicon interposer, as well as a direct competitor for TSMC's CoWoS-R.
Note that Intel does not explicitly say that Foveros-B uses EMIB bridges, though given similar microbump pitch sizes and the plan to use active local bridges in the future, Foveros-B's bridges are likely to closely resemble EMIB-M and EMIB-T bridges. If Foveros-B can indeed use EMIB bridges, future Foveros-B designs could also incorporate cache disaggregation, integrated voltage regulators (IVRs), or MIM capacitors.
As for interconnection densities and power, Foveros-B is listed as designed to support pitches below 25 µm, bump density scaling up to 1,600/mm², and chip-to-chip interconnect power of 0.15 pJ/bit. Meanwhile, Intel has not disclosed when Foveros-B will be ready for commercial production, so its actual specifications remain to be seen.
With EMIB and the Foveros 2.5D portfolio, Intel can address a broad range of applications, but Intel's scaling is not stopping. In addition to 2.5D lateral scaling enabled by EMIB or Foveros 2.5D, it can stack chiplets on top of each other using its Foveros 3D and EMIB 3.5D packaging technologies.
Foveros Direct 3D: There will be copper (and no bumps)
Unlike simple package-on-package stacking, which has existed for decades, densely interconnected 3D stacking essentially turns separate dies into parts of the same tightly coupled chip, increasing bandwidth, reducing latency, cutting interconnect power, and shrinking footprint. The challenge is manufacturing thousands of extremely fine connections between dies while maintaining yield, power delivery, signal integrity, and — perhaps most importantly — removing heat from chips buried inside the stack.
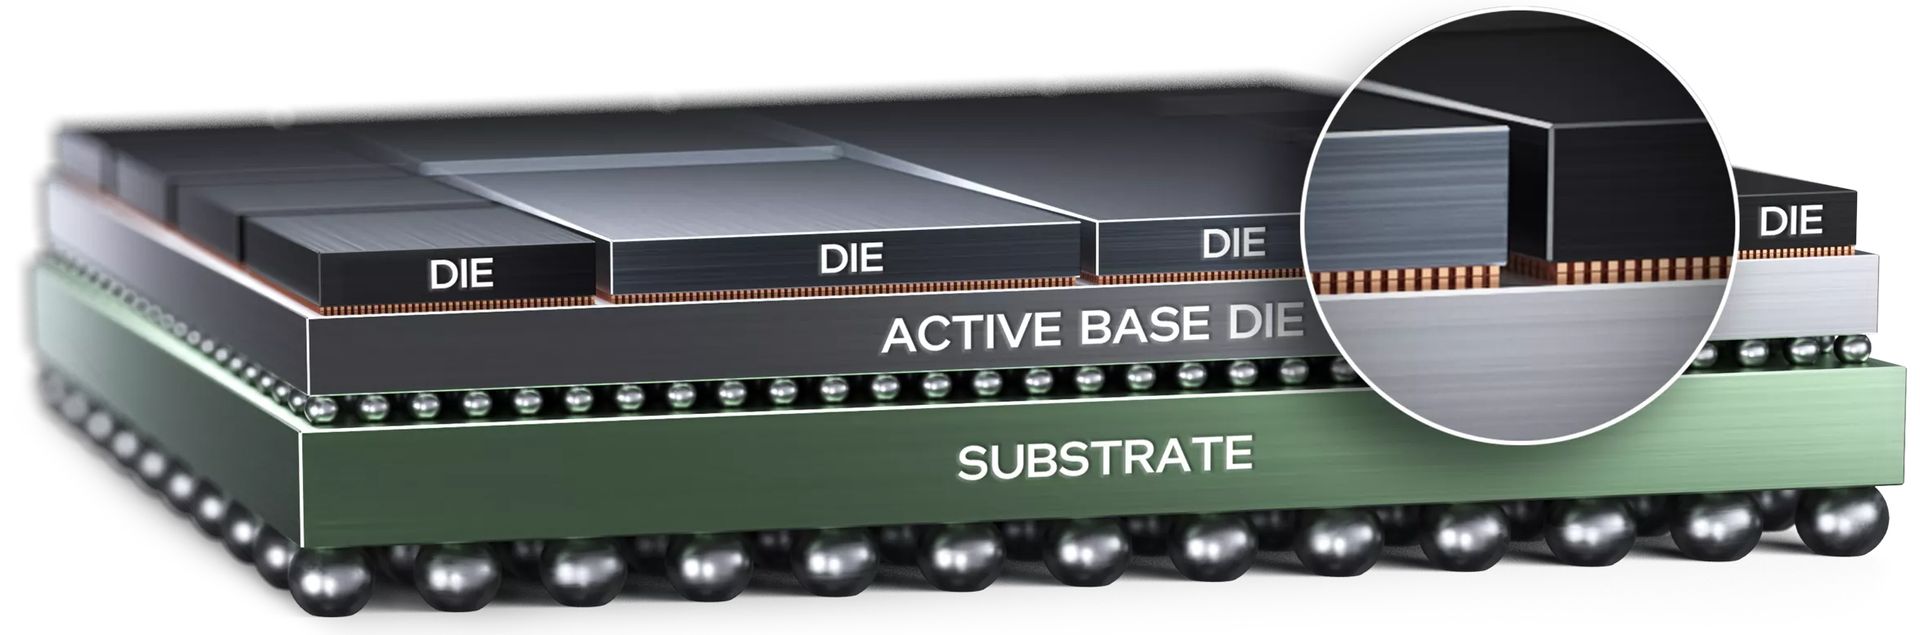
The biggest architectural step in Intel's Foveros roadmap is Foveros Direct 3D, which moves from microbump-based connections toward direct copper-to-copper hybrid bonding. Conventional microbumps cannot shrink forever, as solder bumps need sufficient dimensions to maintain manufacturing yield and reliability, while the solder itself introduces additional resistance and parasitic effects. Foveros Direct 3D eliminates solder altogether and directly bonds copper pads on one die to those on another, which enables an interconnect pitch below 10 µm — up to 10 times finer than conventional microbump technology.
Foveros Direct 3D 1st Gen | Foveros Direct 3D 2nd Gen | |
Joint | Cu–Cu hybrid bond (no solder) | Cu–Cu hybrid bond (no solder) |
Pitch | 9 µm (public “sub-10 µm”) | 3 µm |
Pad Density | ~12,300/mm^2 (Intel: >10,000) | Over 100,000/mm^2 |
C2C Power | <0.05 pJ/bit | Not published (same class or lower) |
Base die | Active | Active |
TSV | + (in base; 18A-PT adds pass-through TSV) | + |
Capacitor/Extras in Base | MIM; Clearwater Fores adds LLC + IVR | MIM; Clearwater Fores adds LLC + IVR |
HBM Stacks | No direct limit — attached via EMIB 3.5D | No direct limit — attached via EMIB 3.5D |
Die Complex | Set by EMIB 3.5D when used together | Set by EMIB 3.5D when used together |
Substrate | Organic (glass later if EMIB-T glass) | Organic (glass later if EMIB-T glass) |
Package Size | Follows EMIB 3.5D (~80×80 → 120×180) | Follows EMIB 3.5D (~80×80 → 120×180) |
Year | 2026 | Later |
Intel claims that Foveros Direct 3D can offer bonding pitch of sub-10 µm, interconnect density of up to 10,000 connections per mm², and chip-to-chip interconnect power below 0.05 pJ/bit. Such dense connectivity shortens signal paths between stacked dies, increases bandwidth, reduces latency, and cuts the energy required to move data. In addition to electrical advantages, direct bonding creates more continuous thermal paths between dies, which Intel says improves heat dissipation compared with conventional packaging, which is crucially important as vertically stacked logic pushes power density dramatically higher.
Intel's Foveros Direct 3D bonding interface supports both face-to-back and face-to-face stacking. In addition, Intel has described chip-to-wafer as well as wafer-to-wafer bonding.
As Intel's schematic drawing of a Foveros Direct 3D-based system-in-package shows (and Intel confirms), the technology is much more flexible than simply placing one logic die on top of another. The method can support different die sizes, multiple stacking levels, and can combine dies manufactured using different process technologies in one SiP.
Intel's Xeon 6+ 'Clearwater Forest' processor is the first product to use Foveros Direct 3D copper bonding in volume to attach Intel 18A compute chiplets to active base dies. The CPU uses the 1st Generation Foveros Direct 3D with 9 µm copper bonding pitch. Meanwhile, Intel plans to shrink bonding pitch to 3 µm with its 2nd Gen Foveros Direct 3D. To put these numbers into perspective, TSMC's 1st Gen SoIC from 2023 supports pitches of 9 µm (AMD's 2nd Gen 3D V-Cache uses this version), whereas the latest generation that entered volume production in 2025 features bonding pitches of 6 µm. TSMC expects to shrink SoIC's interconnection pitch to 4.5 µm by 2029.
EMIB 3.5D: Everything everywhere all at once
Finally, Foveros and EMIB do not have to operate independently. Intel can combine Foveros 2.5D or Foveros Direct 3D with substrate-embedded EMIB bridges to create what it calls EMIB 3.5D in a bid to build its ultimate products. In this architecture, Foveros provides dense local 2.5D or 3D connectivity within individual chiplet assemblies, while EMIB provides high-bandwidth horizontal connections between these modules, essentially building a massive system-in-package out of smaller SiPs. Intel says the individual SiPs can be identical to scale performance, or distinctive, to enable different functionality.
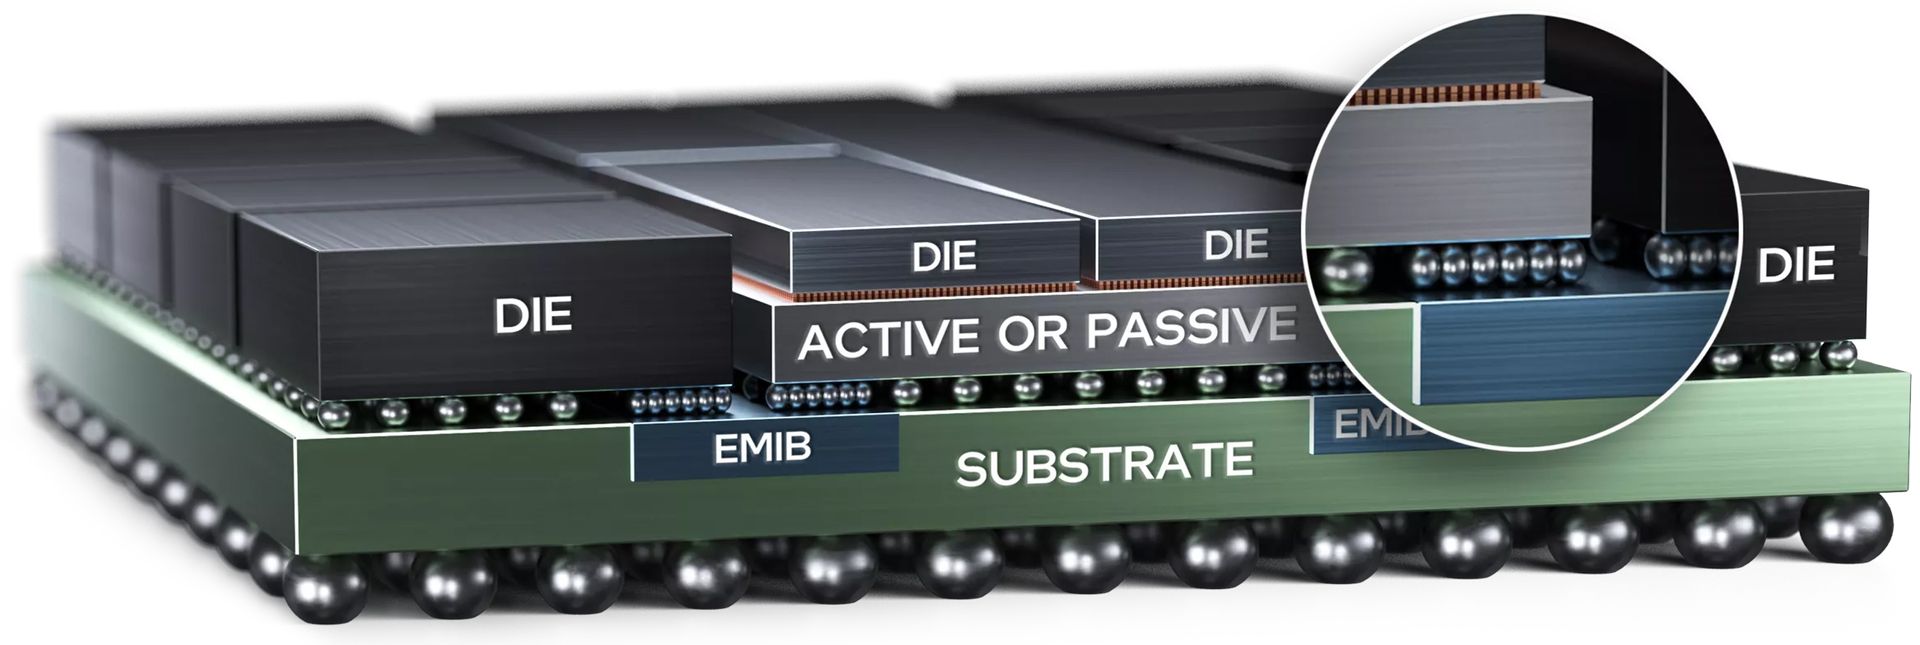
The combination of EMIB and Foveros is particularly useful because it enables Intel to scale both horizontally and vertically without placing the entire system on one massive silicon interposer. Intel says EMIB 3.5D can achieve a total silicon surface area considerably larger than what its existing silicon-interposer-based technologies can accommodate. Intel first used EMIB 3.5D to build its Ponte Vecchio compute GPU that integrated 47 active tiles manufactured on five process nodes and contained more than 100 billion transistors. Although Intel's Data Center GPU Max can hardly be called a smashing success, it certainly demonstrated what Intel can do with its advanced packaging technologies.
EMIB 3.5D (Foveros) | EMIB 3.5D (Direct 1st Gen) | EMIB 3.5D (Direct 2nd Gen + EMIB-T) | |
Vertical Joint | solder microbump | Cu–Cu hybrid | Cu–Cu hybrid |
Vertical Pitch | 36 µm | 9 µm | 3 µm |
Vertical Density | 828 /mm² (Intel) | >10,000 /mm² (Intel) | Not published |
Energy | ~0.15 pJ/bit | <0.05 pJ/bit | Not published |
Lateral Joint | EMIB 1st gen | EMIB 2nd gen | EMIB-T |
Lateral Pitch | 55 µm | 45 µm | 45 → 36 → 25 µm |
Lateral Energy | ~0.5 pJ/bit | 0.25 pJ/bit | 0.25 pJ/bit |
Base Die | Active | Active | Active |
TSV | Foveros base | Foveros base | Base + EMIB-T |
HBM | via EMIB (PVC: 8) | Optional (CWF: DDR) | via EMIB-T (12 → >24) |
Bridges (example) | 11 (PVC) | 12 (CWF) | >20 → >38 |
Package | ~80 × 80 mm | Xeon module | 120 × 120 → 120 × 180 mm |
Product | Ponte Vecchio | Clearwater Forest | TBC |
Year | 2022 | 2026 | Later |
Going forward, the EMIB 3.5D architecture becomes considerably more promising when combined with Foveros Direct 3D. Using both will enable Intel to build tightly coupled compute modules using ultra-dense vertical copper-to-copper connections, and then link multiple modules laterally using EMIB, essentially scaling complex processors both vertically and horizontally. However, surprisingly, Intel decided not to use EMIB 3.5D for its next-generation Xeon 'Diamond Rapids' processor: while the CPU uses Foveros Direct 3D for vertical integration, UCIe-S connections are used for lateral interconnects.
Multi-die another day
While Intel's EMIB and Foveros technologies emerged to serve different kinds of scaling, the company is evolving them into a complementary platform that can scale complex processors both horizontally and vertically.
EMIB is progressing toward finer interconnect pitches, vertical power delivery, glass substrates, and packages exceeding 12 reticles with more than 24 HBM stacks, while the expanding Foveros family spans from 2.5D integration all the way to ultra-dense Foveros Direct 3D hybrid bonding. In fact, Foveros Direct 3D already enables sub-10-µm copper-to-copper connections and is headed toward even finer pitches.
Meanwhile, EMIB 3.5D combines vertically stacked modules with lateral EMIB links to create large heterogeneous system-in-packages for ultimate AI and HPC applications without using enormous silicon interposers.
What is perhaps interesting to note is that, for now, Intel lacks a system-on-wafer platform to enable Cerebras WSE and Tesla Dojo-like wafer-scale processors, though this is explainable, as demand for such technologies is too limited today and may not pick up significantly tomorrow.