Welcome, guys, to another ML article.
In this one, I want to talk about a problem I ran into while working on my Clash of Clans ML lab.
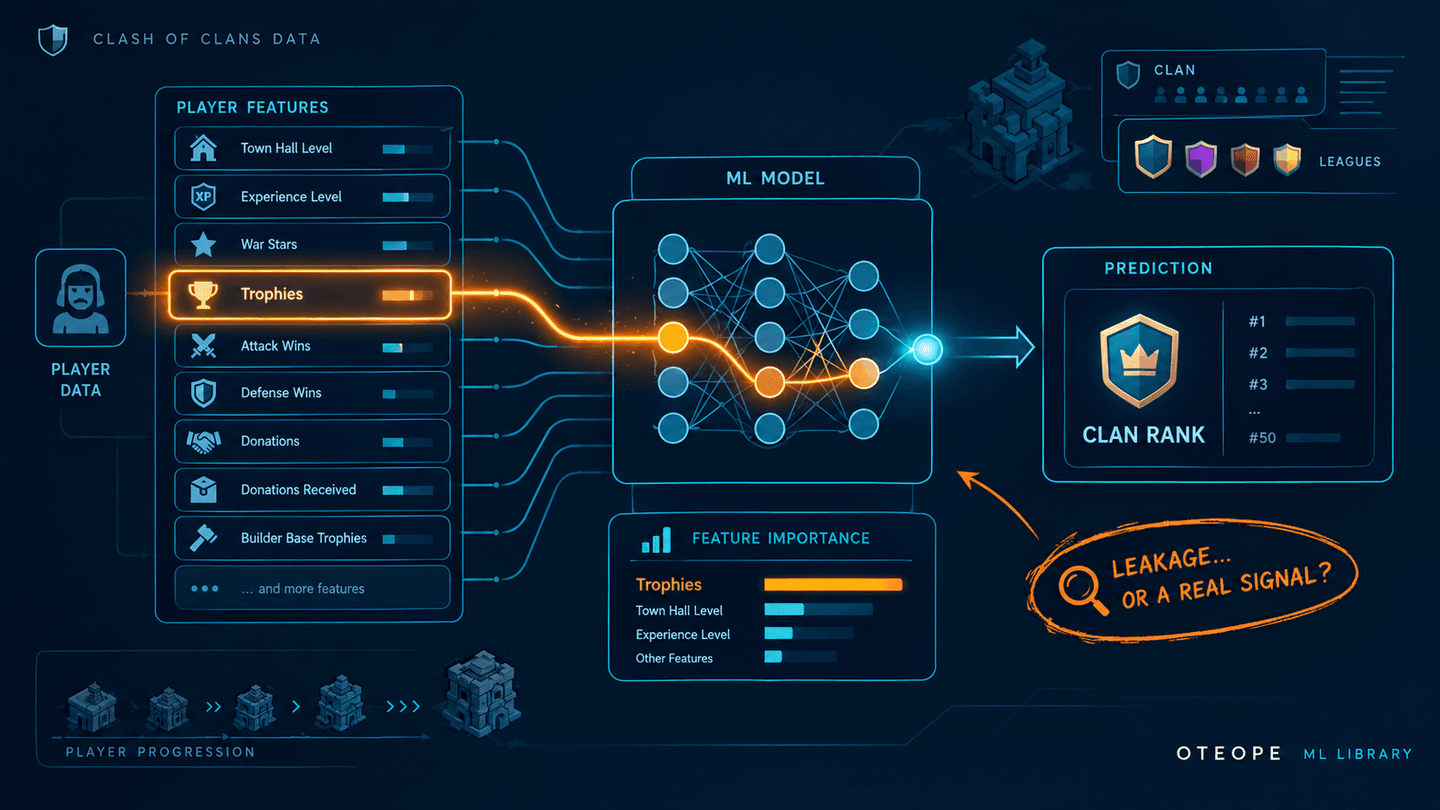
While preparing the dataset for the ML problem, I found something strange. A group of trophy-related features seemed to contain a huge amount of predictive information about the target. At first, that sounds great, because a highly predictive feature is usually exactly what we want in a machine learning model. But something about these features made me want to look a little closer.
When a feature is too predictive, there is always a question worth asking: why?
Maybe the feature contains information the model shouldn't have. Maybe it's indirectly encoding the target. Or maybe it's simply a very strong signal that the model is completely justified in using.
This is where data leakage comes into the picture. Leakage happens when information that shouldn't be available to the model ends up in the training data, so the model makes predictions using something it wouldn't have in the real prediction scenario. The result can be a model that looks incredibly strong during evaluation but performs much worse once that information is no longer available.
There's another possibility, though: the feature could be acting as a proxy. A proxy doesn't directly contain the target, but it's strongly related to it, so it gives the model a very powerful shortcut for making predictions.
The tricky part is that a feature can be extremely predictive without necessarily being leakage. So how do we tell the difference? That was the question I wanted to investigate:
When does a highly predictive feature stop being useful information and start becoming a proxy for information the model should not have?
To answer it, I took a closer look at one particular case from my Clash of Clans dataset: trophies.

2. The Clash of Clans Dataset
Now let’s talk about the dataset and, more importantly, what exactly we are trying to predict.
What Are We Predicting?
clan_rank is the target of this problem. It represents the position a player has within their clan according to the game’s ranking system.
If you don’t play Clash of Clans, don’t worry. I’ll explain how the ranking system works, because it matters a lot for understanding this problem.
In the past, Clash of Clans had a simpler trophy-based system: players earned trophies, and the more trophies they had, the higher they were placed within the clan. The current system is different, though.
I thought this was an interesting ML problem because I wanted to find out which features actually matter for getting a higher position in the clan. In other words, could we use a player’s data to understand what makes them rank higher?
The Data
All the raw data was extracted from the official Clash of Clans Developer API, which provides a lot of useful player and clan information and makes it a pretty good source for an ML project.
Each row in the raw data represents a player, with around 33 features depending on the dataset. From that raw data, I built a specific dataset for this problem using feature engineering, so the final set of features is not just a copy of the original API data.
For this particular problem, the dataset contains around 837k players.
I also created features that describe a player’s position relative to the rest of their clan. For example, instead of only looking at a player’s trophies, we can also look at their difference from the clan average, their ratio to the clan average, or their percentile within the clan. This gives the model some information about how strong a player is compared with the other players around them.

The ML Setup
I went with regression. Predicting a player's exact position out of around 50 possible spots isn't really a problem where I wanted to treat each position as a completely separate class.
I tested three different models:
- Ridge Regression
- Random Forest
- XGBoost
For evaluation, I used MAE, RMSE, and R². For me, a good result was not just about getting strong metrics. What mattered was whether those metrics could help me understand what information the models were actually using to make their predictions.
I also built two different versions of the dataset: one including trophy-related features and one without them. The idea was not to assume that trophies were problematic from the beginning. I wanted to compare both versions and see how much the trophy-related information changed the results. That gave me a cleaner way to investigate what was happening than just removing the features because they looked suspicious.
Something Interesting Appeared During EDA
While doing the EDA, I noticed something else. There were a lot of highly correlated features according to both Pearson and Spearman correlation, which at first could make the dataset look like it was full of duplicated information or unnecessary noise.
But there was another possible explanation. Clash of Clans is a progression-based game, so as players progress, a lot of their stats naturally increase or change together. A player with more progression will usually have several other features reflecting that same progression.
So instead of simply removing all the highly correlated features, I took a closer look at them. That's when one particular group of features started to look especially suspicious: trophy-related features. They were not just correlated with other variables. They seemed to contain a surprisingly large amount of predictive information about the target.
And that raised the question:
Why are trophies so predictive of clan rank?
3. The First Audit: Leakage or Proxy?
My first step, before training any models, was to check whether the trophy-related features were actually a problem.
Instead of removing them right away, I built a small feature analyzer specifically for this problem. The goal was to screen the candidate variables and see whether any of them showed a suspiciously strong relationship with clan_rank.
I defined three possible outcomes for a feature:
- SAFE — the feature did not meet the thresholds I defined for a potential proxy or overly direct relationship.
- POTENTIAL PROXY — the feature had a strong relationship with
clan_rankand needed further investigation. - TOO DIRECT — the relationship was so strong that the feature could be encoding almost the same information as the ranking itself.

I also defined some variables that could never be used as predictors, such as clan_rank itself, previous_clan_rank, and role.
The key part was how I measured the relationship. Instead of calculating one global correlation across the whole dataset, I calculated Spearman correlation separately inside each clan. This made more sense for the problem because clan_rank is a position within a clan, so I wanted to know whether a feature was strongly related to ranking inside individual clans, rather than just across all players.
The analyzer then summarized those correlations using three values:
- the median Spearman correlation across clans
- the 90th percentile of the absolute correlations
- the percentage of clans where the absolute correlation was greater than 0.9
The classification was based on those values. For example, a variable was marked as TOO_DIRECT when the absolute value of the median Spearman correlation was at least 0.95 and at least 80% of the clans had an absolute correlation above 0.9.
The core of the analysis was basically this:
corr_series = _per_clan_spearman(merged, variable).dropna()

median = float(np.nanmedian(corr_series))
p90_abs = float(np.nanpercentile(np.abs(corr_series), 90))
high_pct = float((np.abs(corr_series) > 0.9).mean())
And then I used those values to classify each feature:
if abs(median) >= 0.95 and high_pct >= 0.8:
    classification = "TOO_DIRECT"
elif abs(median) >= 0.8 or high_pct >= 0.5:
    classification = "POTENTIAL PROXY"
else:
    classification = "SAFE"
I ran this analysis across several candidate variables, including trophies, town_hall_level, exp_level, war_stars, attack_wins, defense_wins, donations, donations_received, capital_contributions, and builder_base_trophies.
The first result was quite unexpected. According to the thresholds I had defined for the audit, trophies were classified as SAFE. The median Spearman correlation between trophies and clan_rank was -0.3963. The 90th percentile of the absolute correlation was 1.0, and 17.28% of clans had an absolute correlation greater than 0.9.

So, according to my own criteria, trophies did not look like a direct leakage feature or even a strong proxy at the overall level. The rest of the candidate features were also classified as SAFE, with capital_contributions being the only variable for which the analyzer reported insufficient data.
At that point, the analyzer was basically telling me:
Nothing looks obviously wrong.
But that was not really the end of the investigation. The results still left me with a question: if trophies were supposedly safe, why did they appear to be so predictive when I looked at the dataset?
4. The Trophy Problem
By now I knew that trophies were strongly related to clan_rank in some parts of the dataset, but I still didn't fully understand why. So I went back to the game itself. To understand what the model was seeing, we first need to understand how Clash of Clans actually determines a player's position within a clan.
How Clan Rank Actually Works
In the current Clash of Clans system, players within a clan are ordered mainly according to their league. However, when players are in the same league, their trophies are used to break the tie.

This immediately makes trophies much more interesting. If two players are in the same league, the player with more trophies will be placed higher in the clan ranking. So trophies are not just another random player statistic: in certain situations, they are directly involved in determining the player's position.
It also explains something from the previous section. Remember that the analyzer gave trophies a median Spearman correlation of only -0.3963, but its 90th percentile of absolute correlation was 1.0. That suddenly makes a lot more sense.
Why Top Clans Are Different
A significant part of my dataset comes from very advanced clans, where many players are already at the highest levels of the game and concentrated in the highest leagues. Once several players are in the same league, the league itself becomes much less useful for distinguishing their positions.
In that situation, trophies become extremely important. Instead of having to predict the ranking from many different player characteristics, the model can exploit a much simpler relationship: among players in the same league, their trophies can tell us a lot about where they will appear in the clan ranking.
This also explains why the relationship is not equally strong across all clans. In some clans, league differences are enough to separate many players. In others, especially highly advanced clans, many players already share the same league, which makes trophies much more informative. So the strange combination we saw earlier — a moderate overall correlation but almost perfect correlations in some clans — starts to make sense.
And Then There Is Town Hall Level
Trophies are not the only feature that stands out here. town_hall_level also showed a relatively strong relationship with clan_rank, which at first might look unrelated to the ranking problem. But Clash of Clans has progression mechanics that connect Town Hall level with the league system.
To prevent highly advanced players from dropping too far down the league system, there are league floors depending on the player's Town Hall level. This means that if a player is in a league below the minimum allowed for their Town Hall level, the game can move them back up to the appropriate league. So Town Hall level can influence the league a player can be in, and if league influences clan_rank, Town Hall level can become predictive of clan rank without directly determining the ranking itself.
This is exactly the kind of relationship that can be easy to miss if we only look at individual features without understanding the domain behind the data.
The Weekly Reset
There is one more detail about trophies worth knowing. They are reset with the beginning of a new league cycle, so unlike something such as Town Hall level, they are not simply a permanent measure of player progression. Their value depends partly on where we are in the current league cycle, which means the same trophy value can represent different situations depending on the context in which it appears.
Now we have a much clearer picture of what was happening in the dataset. Trophies are strongly connected to clan rank. Town Hall level is connected to the league system, and the league system is connected to clan rank. And in highly competitive clans, trophies can become especially important because many players share the same league.
So the feature that initially looked suspicious has a perfectly plausible explanation. But there is still an important question left:
Is the model simply learning a legitimate game mechanic, or are we accidentally giving it information that makes the prediction too easy?
I couldn't answer that just by looking at correlations. I needed to test it.
5. Testing the Hypothesis
I now had a pretty good idea of what was happening, so the next step was to put it to the test.
If trophies were creating a leakage-driven shortcut, removing them should reduce the model's predictive performance. On the other hand, if they were simply providing useful information, the model should still be able to learn a lot from the remaining features.
This is why I created the two dataset versions I mentioned earlier: one with trophy-related features and one without them.
For both versions, I used the same general setup. I split the data using train_test_split from scikit-learn, with a 20% test set and random_state=42. I then trained three different regression models:
- Ridge Regression
- Random Forest
- XGBoost
As the experiments progressed, I also used Optuna to optimize the XGBoost hyperparameters, which eventually produced the best-performing model in both dataset variants.
With Trophies
When trophy-related features were included, the best model was XGBoost optimized with Optuna. The results were:
| Metric | XGBoost + Optuna |
|---|---|
| MAE | 3.5295 |
| RMSE | 5.3803 |
| R² | 0.7710 |
This means the model explained around 77% of the variance in clan_rank, while making an average absolute error of roughly three to four ranking positions. Random Forest was also very close, with an MAE of 3.6783 and an R² of 0.7523. The difference between the two models was not huge, but XGBoost was still the strongest overall.
So far, nothing too surprising. Trophies looked very useful. The interesting part came when I removed them.
Without Trophies
For the second experiment, I removed not only trophies, but also the trophy-related features derived from it, such as the player's trophy difference from the clan mean, trophy ratio to the clan mean, trophy percentile within the clan, best_trophies, and other related variables. Again, XGBoost + Optuna was the best-performing model.
This time, the results were:
| Metric | XGBoost + Optuna |
|---|---|
| MAE | 4.1183 |
| RMSE | 6.0131 |
| R² | 0.7140 |
Removing trophies clearly hurt performance. The MAE and RMSE increased, while R² dropped from 0.7710 to 0.7140. But there was something more important in those numbers: the model still achieved an R² of 0.7140 without any of the explicitly trophy-related variables.
And that was the moment when I thought:
Eureka.
Trophies were not making the model magically predict the target. They were simply providing a lot of useful information. Removing them did not destroy the model's predictive ability, which made the idea that trophies were responsible for the model's overall performance through leakage much less convincing.
With vs. Without Trophies
Putting the two experiments side by side makes the difference easier to see:
| Dataset | MAE | RMSE | R² |
|---|---|---|---|
| With trophies | 3.5295 | 5.3803 | 0.7710 |
| Without trophies | 4.1183 | 6.0131 | 0.7140 |

So yes, trophies matter. Removing them makes the problem harder, but it does not make the model collapse. The remaining player progression and clan-related features still contain enough information to predict clan_rank very well.
For me, this was the most important result of the whole investigation so far. The suspicious feature was not simply giving the model the answer. It was giving the model high-quality signal. A feature can be highly predictive because it contains meaningful information about the target, and that does not automatically make it leakage.
What Is the Model Actually Using?
After seeing the difference in overall performance, I also wanted to know whether the models were relying heavily on trophies or using a broader set of signals. The feature-importance analysis gave me a more interesting picture.

town_hall_level_clan_pct is a good example of a feature that stays relevant everywhere: it ranks among the top features for both XGBoost and Random Forest, in both dataset variants. That fits exactly with what we found earlier — Town Hall level connects to the league system, and the league system is a big part of what determines clan_rank.
What changes the most between the two variants is which feature picks up the slack once trophies are gone, and it's different for each model. For Random Forest, members — simply the size of the clan — becomes by far the single most important feature once the trophy-related columns are removed, far ahead of anything else in the whole comparison. For XGBoost, it's attack_wins_clan_pct — a player's share of attack wins relative to the rest of their clan — that jumps the most once trophies disappear.
trophies_clan_pct, the player's trophy standing relative to the rest of the clan, does show up among the top features in the with-trophies models — Random Forest leans on it the most of the three — but even there, it's smaller than several non-trophy features. It shares the spotlight rather than dominating it. Ridge, meanwhile, spreads its importance much more evenly across a wider set of features (completion ratios for equipment and troops, hero levels) instead of leaning hard on one or two, which is a good reminder that "what matters most" depends on the model as much as on the data.
And that brings us back to something we saw earlier:
context matters.A feature can tell the model much more when we understand how it relates to the other variables around it.
6. What This Means for ML Engineering
After going through all of this, the main lesson I take from this problem is quite simple:
Before removing a feature, you need to understand exactly what is happening with it.It would have been very easy to look at the correlation between trophies and clan_rank, decide that the feature was suspicious, and remove it from the dataset. But that would have meant removing useful information without really understanding why it was there in the first place.
I think this is where domain knowledge becomes extremely important in ML Engineering. For this project, the domain was a game, and I had to understand how Clash of Clans progression, leagues, trophies, and clan rankings work in order to make sense of what I was seeing in the data. But this applies to much more than games.
Imagine you are working on a market analysis project, some variable suddenly changes, and the model starts behaving differently. Without understanding the market, you might blame the model or the project itself without realizing that there is a perfectly valid reason behind the change. The same thing can happen in finance, healthcare, marketing, or pretty much any other domain.
For me, this is what makes an ML Engineer different from someone who only knows how to train a model.
You need to understand what your data actually represents.
A model can only work with the information you give it, so understanding where that information comes from is just as important as knowing which algorithm to use.
This is also why the feature analyzer turned out to be so useful. It was not just a way of automatically deciding which features to remove. It gave me a way to investigate the dataset and understand why a feature was related to the target. A feature should not be in a model just because it happens to be available in the dataset, and it should not be removed just because it has a strong correlation with the target either. What matters is knowing what the feature represents, how it was generated, and why it is predictive.
For the same reason, I think feature auditing should be part of the ML workflow, especially before making decisions about removing potentially problematic variables.
In the end, this whole investigation started with a simple question about trophies, but it ended up reinforcing a much bigger idea:
Good ML Engineering is not only about building models. It is about understanding the data well enough to know why the model is able to make its predictions.
And sometimes, that means looking much deeper into the domain than you expected.
7. Conclusion
I started this project with a simple question: why were trophies so predictive of clan rank?
At first, it looked like I had found a data leakage problem. Instead of removing the feature and moving on, I decided to investigate what was actually happening.
The first audit did not flag trophies as problematic according to the thresholds I had defined. Looking deeper into the game mechanics revealed why: league determines the main ranking context, while trophies can separate players within the same league. This becomes especially important in highly advanced clans, where many players are already competing in the same league.
Then I tested the hypothesis. With trophy-related features, XGBoost reached an R² of 0.7710. After removing them, performance dropped to 0.7140, but the model still retained most of its predictive power. And that was the moment everything clicked.
Trophies were not giving the model the answer outright. They were giving it good information.
The important lesson is not that highly predictive features are suspicious. It is that predictive power alone does not tell you whether a feature is good or bad. Before removing a feature, understand where it comes from, what it represents, and why it is predictive. In this case, what first looked like leakage turned out to be a strong signal created by the system itself.
Good ML Engineering is not just about building a model that predicts well. It is about understanding why it predicts well.