
Nolen began their writing career in 2019, with three years dedicated to editing the Creative section at MakeUseOf. Their expertise lies at the crossroads of technology and creativity, covering areas like photography, video editing, and graphic design.
Outside of work, you'll often find Nolen diving into a good book, writing their own stories, or playing video games.
Every new model drop used to feel like a whole event. People would clear their entire afternoon to test it out on new tasks and builds, then spend the rest of the week arguing online whether it was actually better than the last one. The ritual hasn't really changed, but the thing is that it happens all the time now.
OpenAI, Anthropic, and Google seem to drop something new every single week now, and keeping up with it all has started to feel more like homework than a fun side thing. Every launch also brings with it a fresh round of benchmark charts, and with this comes this inkling that whatever you're using now isn't good enough anymore and that upgrading isn't optional.
I spent most of this year chasing this feeling, but I'd argue that this isn't actually normal; it's a pretty strange thing to feel about a tool you were perfectly happy with yesterday. And it cost me more than I'd like to admit, perhaps you too.
New models are landing faster than anyone can test them
Three new ones will drop before I've properly tested the last one

OpenAI went 29 months between GPT-3 and GPT-4, and back then it wasn't considered slow at all. These days the wait between flagship drops is measured in mere days. One analysis of seven major labs found the average time between them fell from 38 days in 2023 to 8 in the first half of 2026. Another count from September lands around one every 17 days for 2026. Whichever source you look at, the pattern is the same: models are dropping faster than we can test them.
Part of the reason this is happening is pretty simple: labs are using AI to build more AI now. This is called recursive self-improvement. In addition, they're also hiring record numbers of human experts to curate the training data, and a lot of launches are simply earlier flagships repackaged at a lower price.
Anthropic launched Claude Opus 5.5 and OpenAI launched GPT-6 Sol on the same day. GPT-6.1 Sol then turned up a week later, so the OpenAI model I'd only just started using in Codex was already a version behind before I could really form an opinion of it. Local models don't offer much of an escape from this conveyor belt either. Alibaba alone put out nine Qwen 3.5 models over 16 days, and Google released the Gemma family just one month later.
Keeping up with every release has costs
Every new drop comes with homework I never signed up for

Model fatigue looks like testing everything but never finishing anything. Something new will drop, you feel like you should try it, then the next drop happens before you could even assess whether the previous one was the right fit. This leaves you with a million unfinished or incongruent sessions, and just a bunch of decision fatigue. I don't think I've properly settled into a model most of the year.
Benchmarks are the biggest part that feeds into this. Half of them I couldn't even explain to you off the top of my head, but I still end up digging through the charts every new release as if I'm going to discover something life-changing. Newer doesn't always look better on them either, since GPT-6 Sol's best scores came in below GPT-5.6 Sol's on two benchmarks OpenAI reported itself.
Then there's the reality of your old favorites becoming worse. This is rooted in two things: it simply feels worse compared to more advanced releases, but the older ones do also start to drift. AI labs frequently alter parameters and quantize the model weights behind the scenes to save on GPU costs, and they also just continuously push upgrades and fix bugs, which can change how a model behaves.
For example, in April, Anthropic published a postmortem tracing weeks of Claude Code complaints to a handful of product changes, including a lower default reasoning effort and a cache bug, while saying the API itself wasn't affected. Coding quality dipped on Opus 4.6 and 4.7. So if you feel like your old favs changed, or are getting worse, you're probably not imagining it.
Then there's the cost. I've had my Claude Pro subscription all year, and even though I swore I wouldn't get any more AI subs, I ended up getting ChatGPT and Gemini plans anyway. This just felt like a necessity if I actually wanted to test the newer models to their full capacity, and also write about them. Usage takes a hit too. When I tracked my Claude Code sessions, one of the patterns that kept popping up was how I was using more advanced models for mundane tasks.
The system I now use instead of chasing every new launch
Each model gets one job
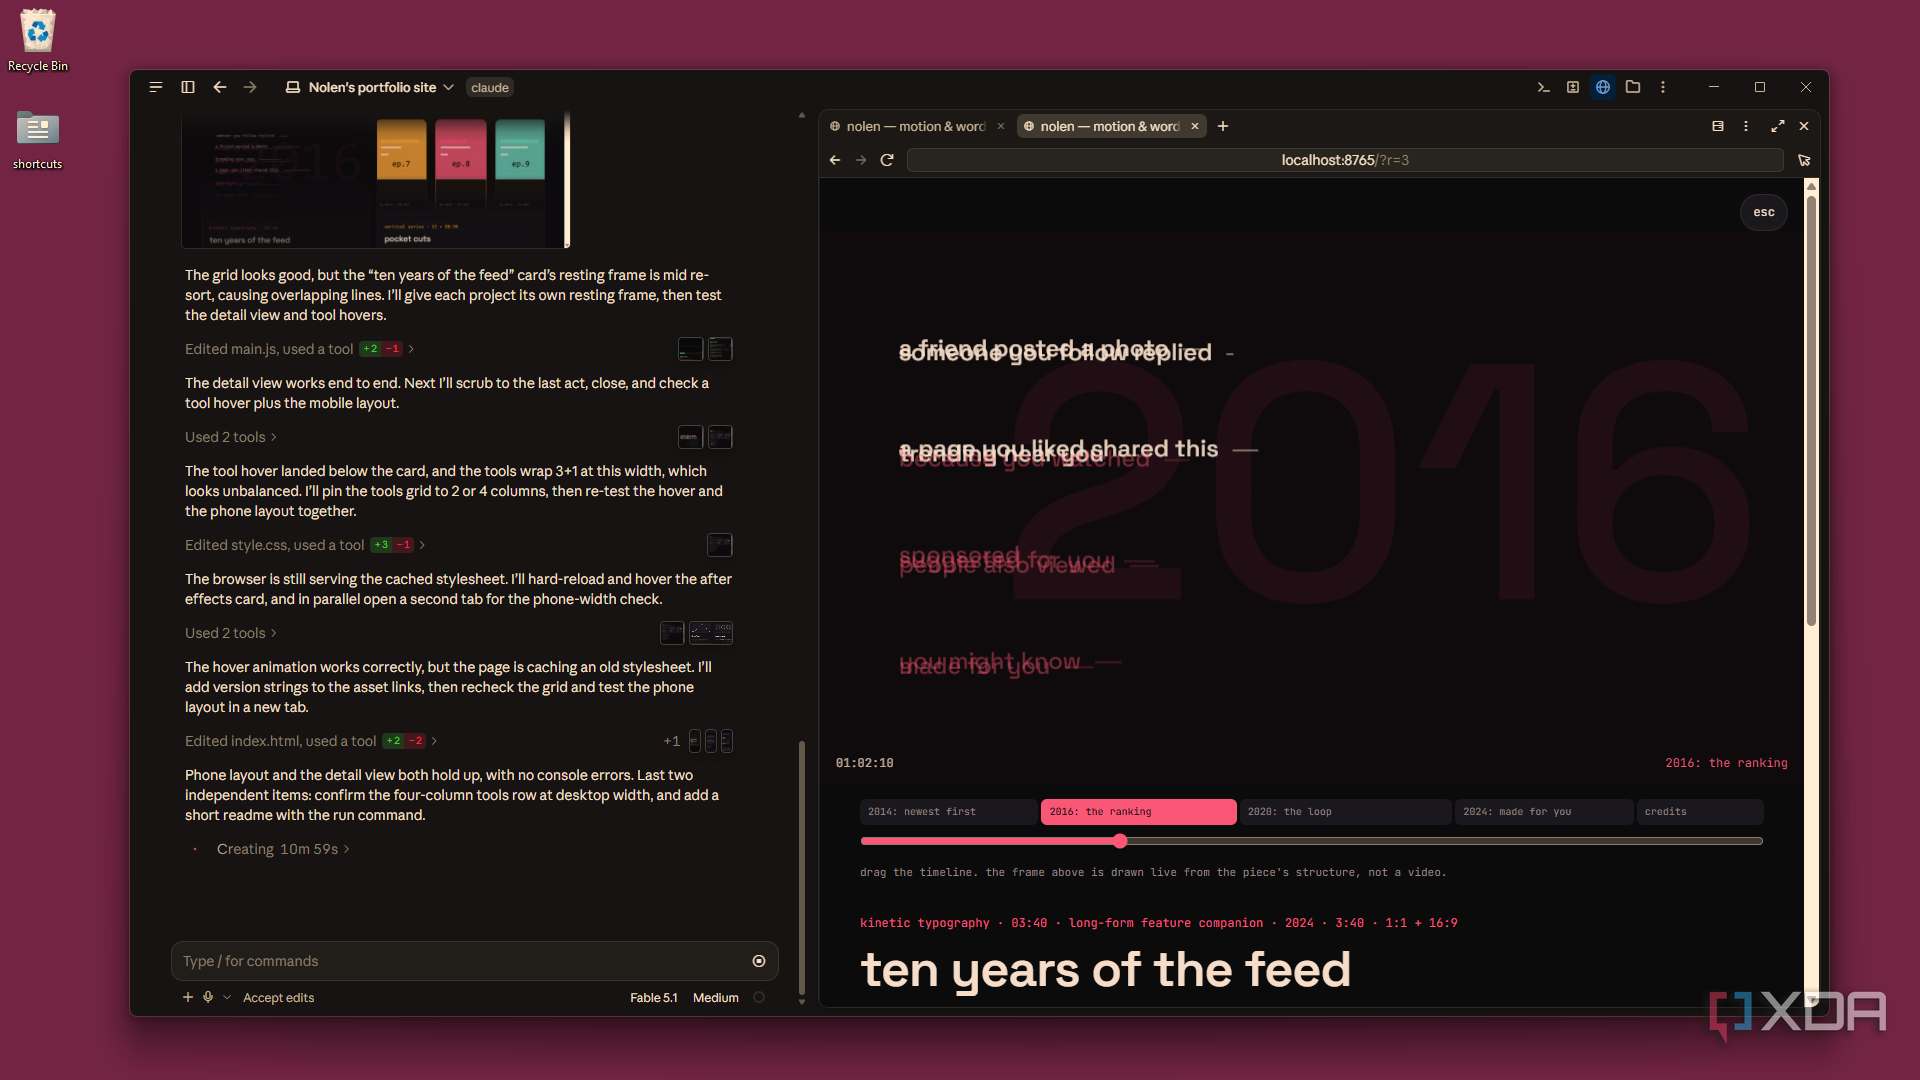
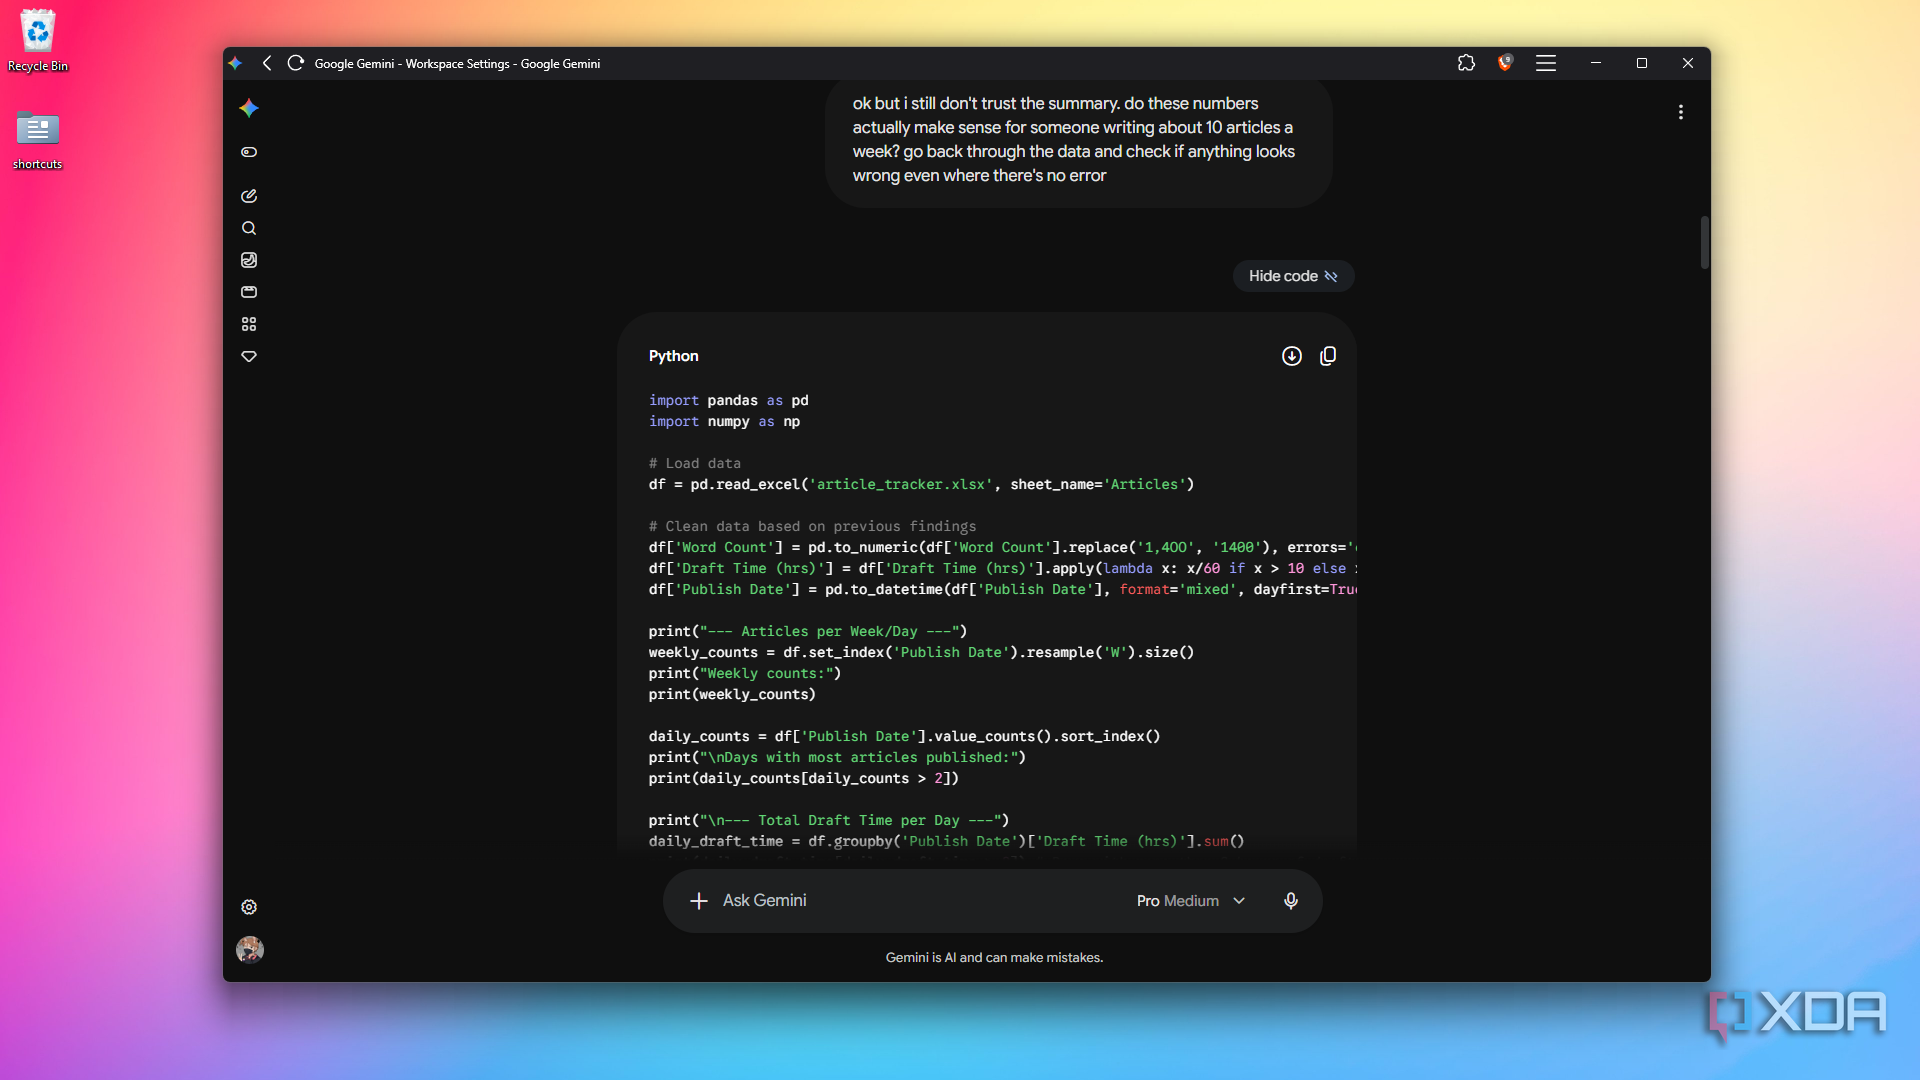
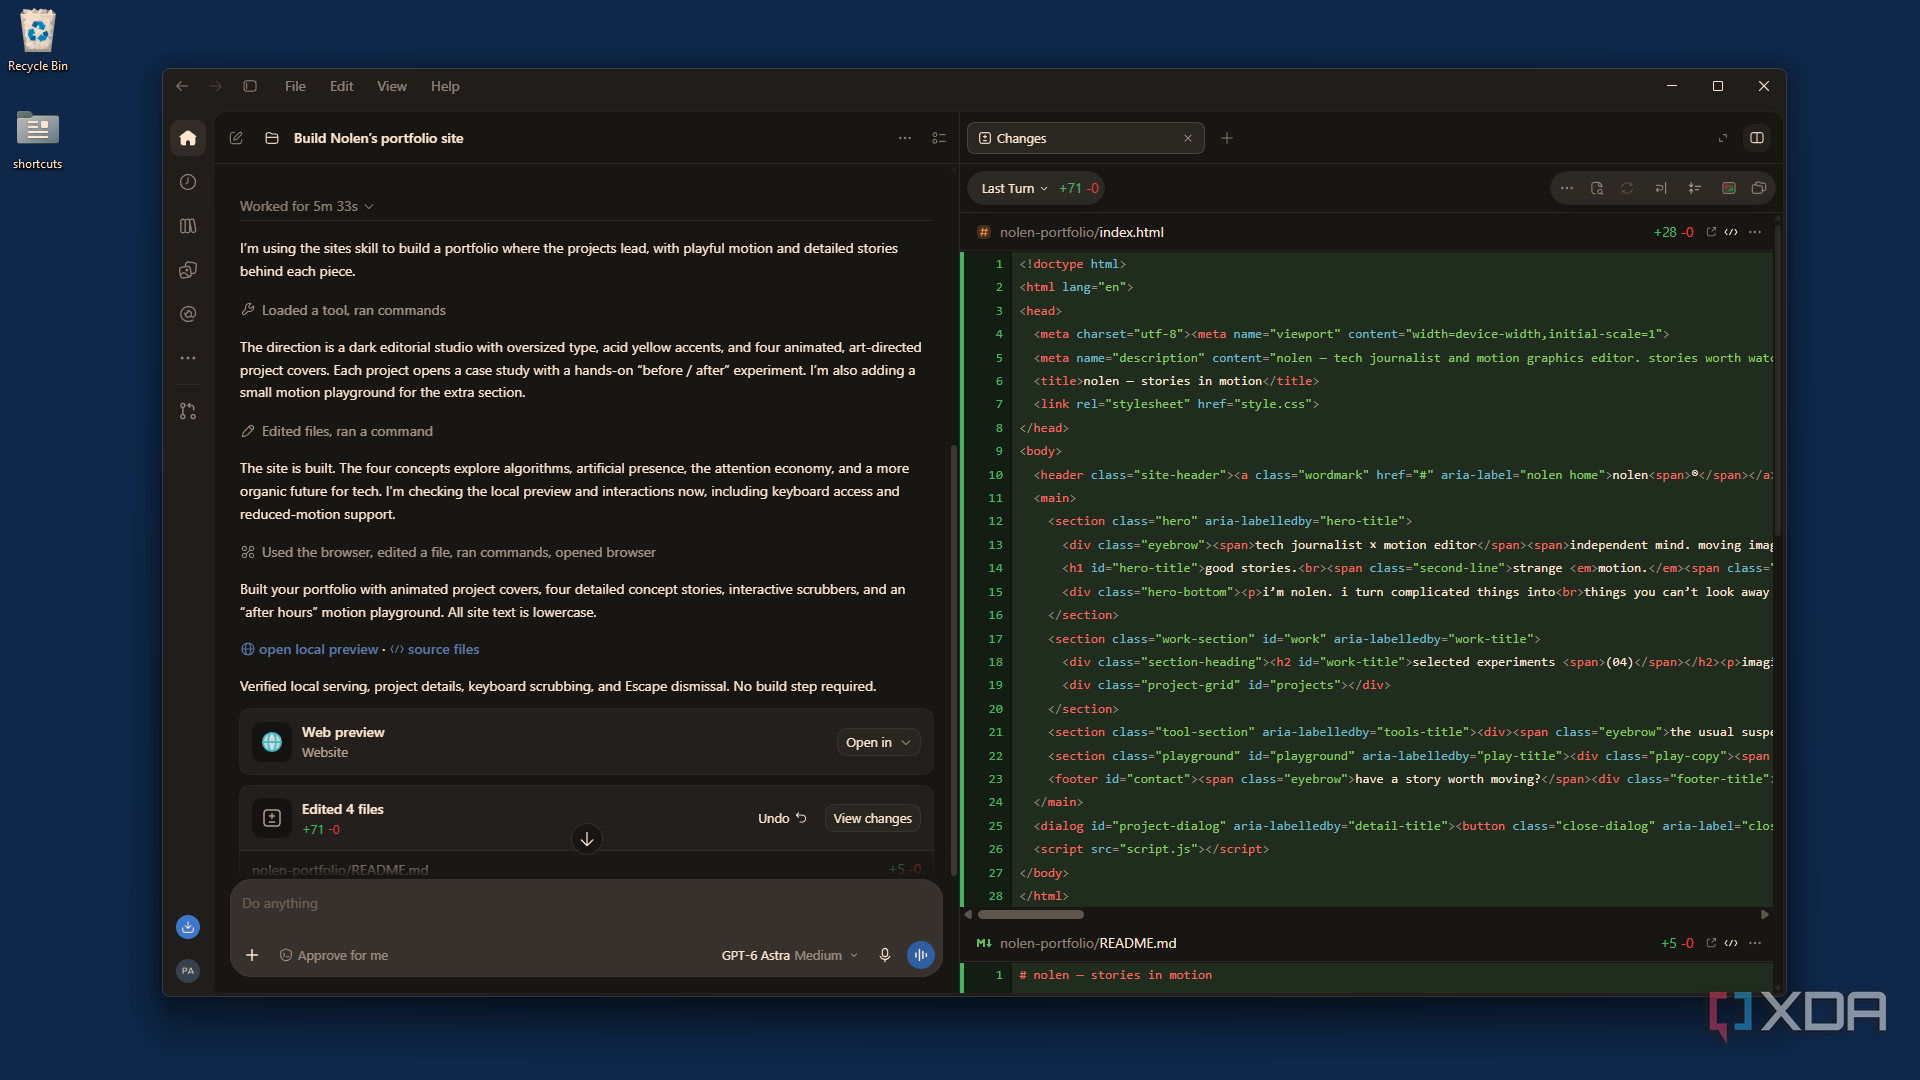
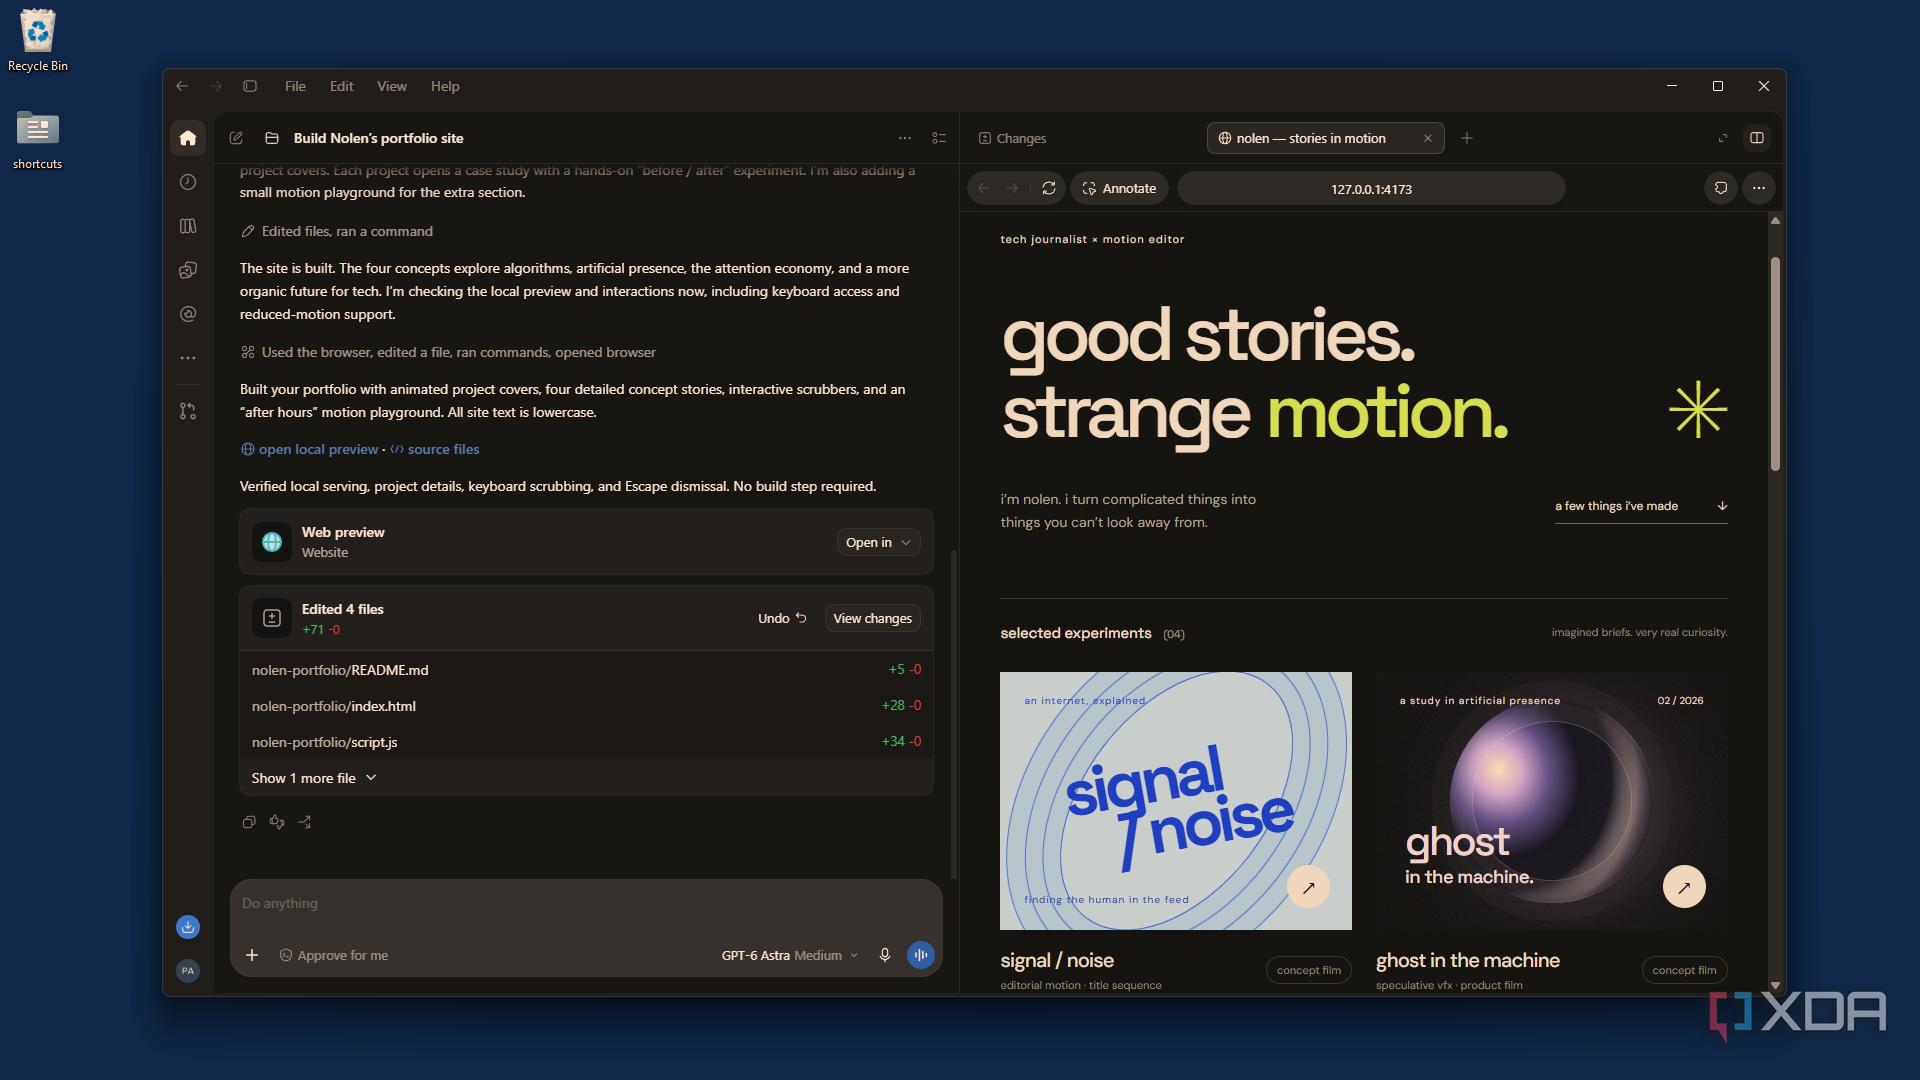
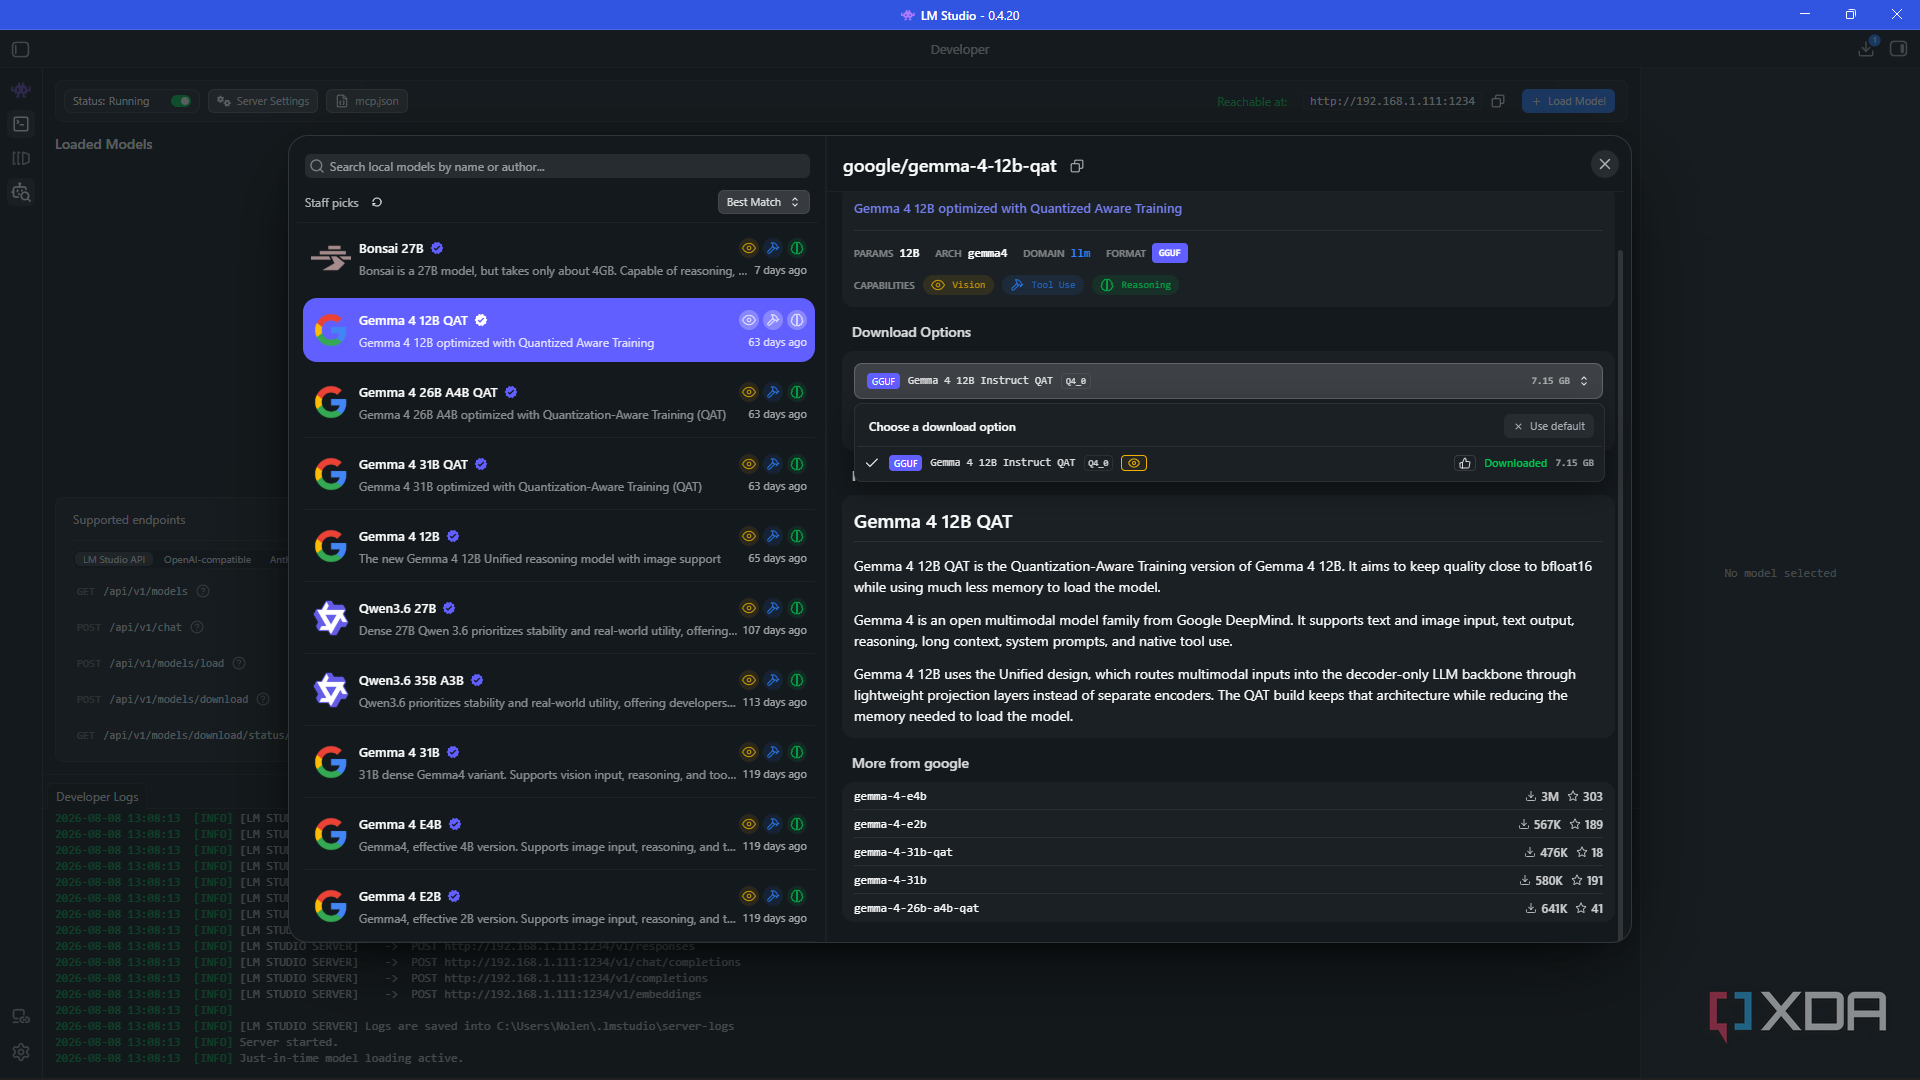
Let's be real, we're all probably going to keep testing the new releases. But what helped me save on usage and decision fatigue was giving each model a job and sticking to it for at least several months. Asking which model is best overall is pointless, since they all excel at different tasks.
Right now, Opus 5.5 is my favorite for anything that involves real projects with research and brainstorming. It reads nuance better than anything else I've tried, and it's been lighter on tokens than I thought it would be. For lighter admin tasks, I still use Opus 4.7, which is probably a little overkill still, but it catches stuff I'd skim past. Design experiments are a bit messier, since I usually run GPT-6 Sol in Codex with Opus 5.5 open next to it and compare the directions they take. Studying and research go to either Opus 5.5 or Gemini 3.1 Pro, leaning to the latter because Gemini has some great studying features.
As for new models, I give them a small test kit I've compiled. It's basically just a plain note with a prompt for each of the above jobs with a few curveballs (such as planting a wrong fact to see if it catches it). And as for local models, I'm still sticking it out with my tried-and-true Gemma E4B for chat and Qwen 3.5 9B for coding and design.
New models will keep launching, but you don't have to drop everything for them
Sonnet 5.5 came out a couple of weeks ago, with Haiku 5.5 nine days behind it, and I still haven't opened either one. I only just finished testing the ones that came before them for spreadsheet debugging and a portfolio design, it's just not realistic to make the switch so quickly and get a fair overview. Doesn't mean I'm never testing them, I'm just more mindful about it.