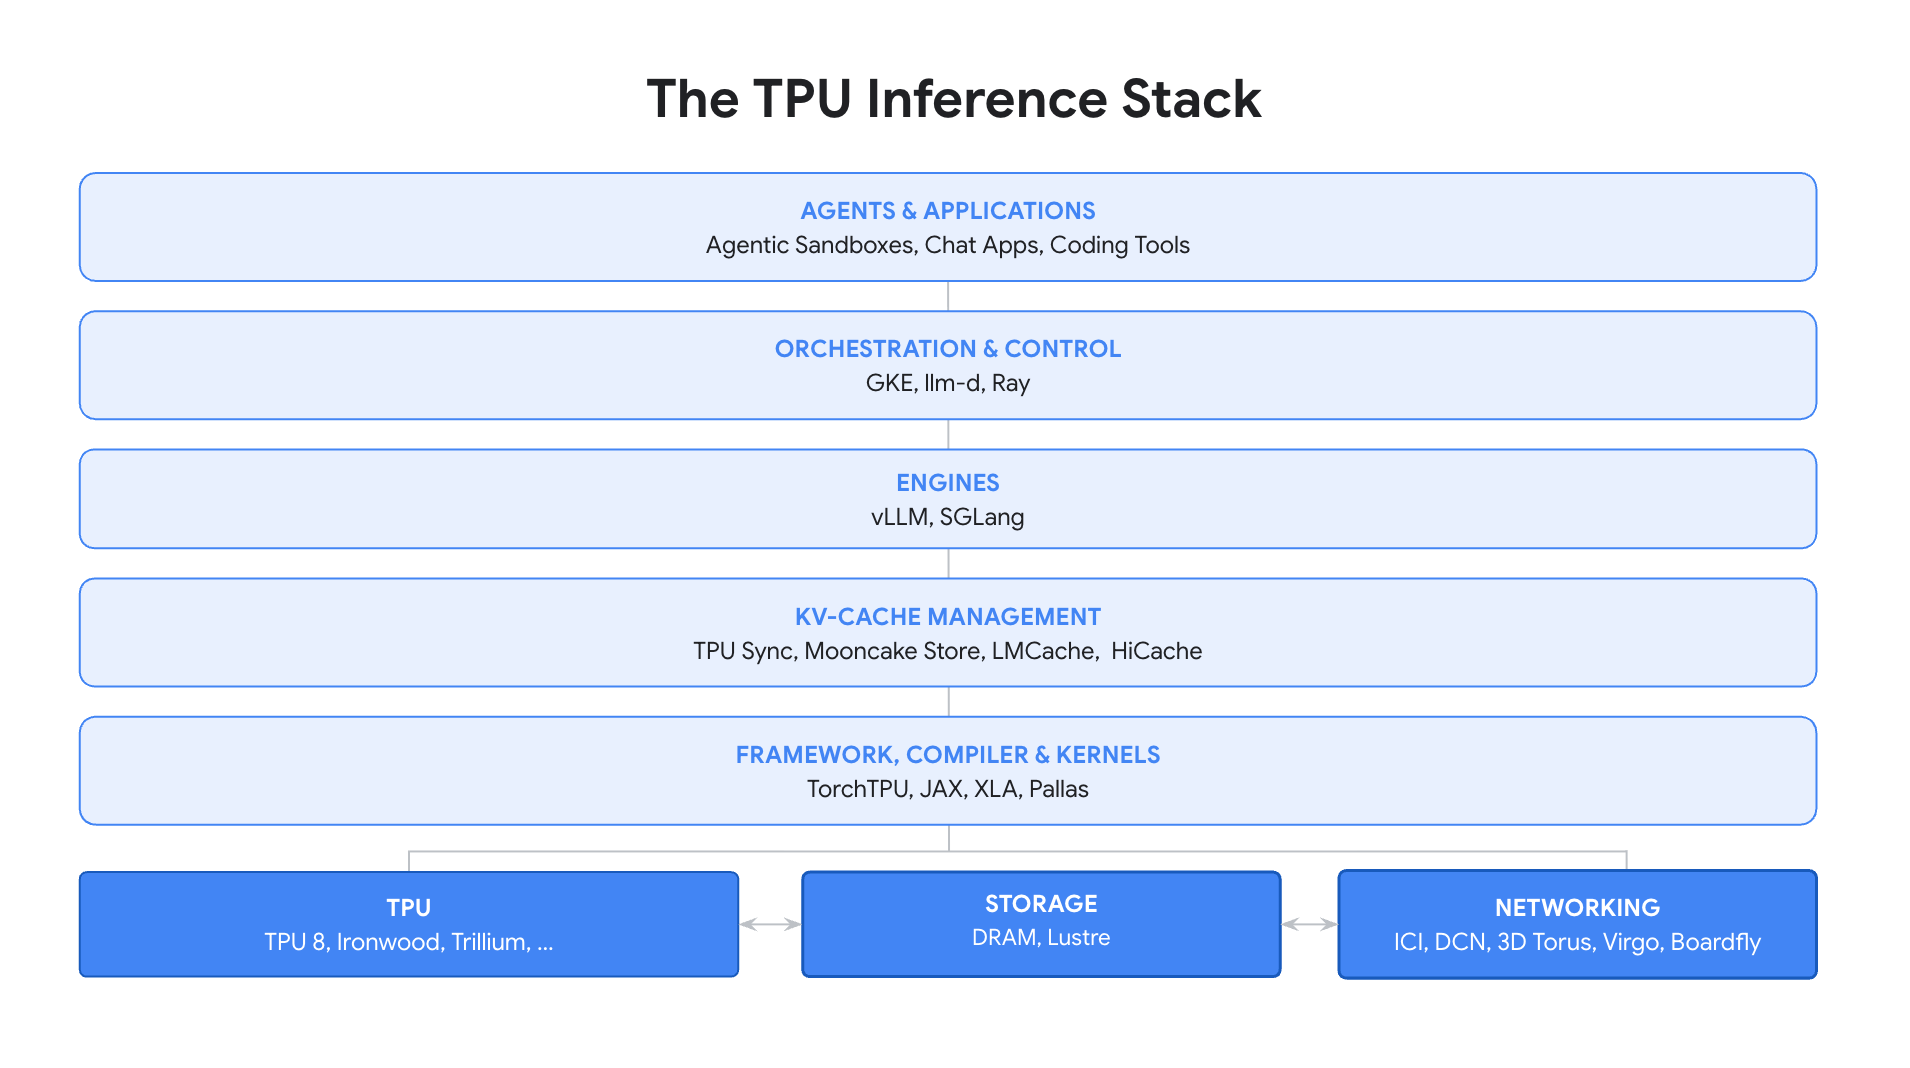
Google’s tensor processing units (TPUs) — its custom AI chips — now serve AI in production at Meta (creator of the widely used PyTorch AI framework) through a new PyTorch-native version of the SGLang inference engine, announced on Google’s developer blog. A matching version of vLLM, another widely used inference engine, was also announced as open source.
Previously, both engines used Google’s own JAX AI framework to run on TPUs. The new versions allow the hardware to be a native option for PyTorch, mostly without rewriting.
- The data center cooling state of play
- The custom AI ASIC state of play
- America’s AI chip rules keep changing — and the rest of the world is paying the price
- GTC 2026: Ian Buck press Q&A transcript — VP of Hyperscale and HPC speaks out on shelving CPX and shipping LPU decode this year
- Demand for data center CPUs has surged, and AI agents are responsible
“SGLang-TorchTPU is running in production at Meta today” after “a close three-way collaboration between Meta, Google, and the SGLang team,” said Meta’s PyTorch-TPU lead Zongwei Zhou. That team works at RadixArk, a startup founded by SGLang’s creators, which built the engine with Google and Meta. The engine, he said, gives Meta “a remarkably mature, PyTorch-native serving stack.”
Jana van Greunen, director of PyTorch engineering at Meta, added in Google’s TorchTPU post that Meta “cannot be constrained by a single hardware architecture” and that TorchTPU “enables us to deploy our PyTorch workloads to Google TPUs.” Google said it co-developed TorchTPU with Meta’s PyTorch team.
This is not Meta’s first attempt at using TPUs. Google calls PyTorch/XLA, the older bridge from PyTorch to TPUs, a "predecessor" to the new TorchTPU, and SemiAnalysis reported last year that Meta research teams used TPUs through this bridge from 2020 to 2023 before Meta canceled those contracts. Google’s PyTorch-on-TPU push was aimed mainly at Meta, which did not want to migrate to JAX.
Although it is unclear where Meta’s production TPUs sit, talks last year reportedly included Google Cloud TPU rentals in 2026 with purchases in 2027, and Meta later reportedly signed a multi-year rental agreement.
BREAKING NEWS🚨🚨: TODAY META CONFIRMS THEY ARE RUNNING TPU INFERENCE IN PRODUCTION. What does this mean for the CUDA moat?For those who read our public newsletter, this is not a surprise, as on Nov 28, 2025, we publicly wrote that Meta is a TPU customer & has lots of engineers working on TPUs. Our accelerator supply chain model has details about Meta's TPU procurement!October 21, 2026
The announcement came one day after Amazon said it was open-sourcing TorchNeuron, its own native PyTorch backend for its Trainium2 and Trainium3 chips, at the same PyTorch Conference. Both moves appear to be aimed at loosening Nvidia’s software lock-in.
On performance, a tuned vLLM setup serving Moonshot AI’s open-weight, 2.8-trillion-parameter Kimi K3 model reportedly tops 700 tokens per second for a single user on the seventh-generation Ironwood TPU. That speed figure comes from Inferact, the startup founded by vLLM’s creators that helped Google build vLLM-TorchTPU. Its test ran 16 Ironwood chips with speculative decoding, a method of speeding up large language model inference with a small draft model, against vLLM’s published setup on 16 Nvidia GB200s, which reached 452 tokens per second. Its kernels for Kimi K3 and Qwen 3.8 27B deliver roughly 1.4 to 2 times the GB200 baseline’s throughput at small batch sizes without speculative decoding.
SGLang-TorchTPU will keep adding models, starting with DeepSeek V4.1 Flash and Reflection Beam. It's also working toward Day 0 TPU support for new open models, meaning support on release day, by the first quarter of 2027, according to RadixArk. Google, Meta and RadixArk plan to share more at SGLang Summit 2026, Nov. 12–13 in San Francisco.