
Maker, meme-r, and unabashed geek, Joe has been writing about technology since starting his career in 2018 at KnowTechie. He's covered everything from Apple to apps and crowdfunding and loves getting to the bottom of complicated topics. In that time, he's also written for SlashGear and numerous corporate clients before finding his home at XDA in the spring of 2023.
He was the kid who took apart every toy to see how it worked, even if it didn't exactly go back together afterward. That's given him a solid background for explaining how complex systems work together, and he promises he's gotten better at the putting things back together stage since then.
I've run plenty of local models on my home lab over the last couple of years, and I've always told myself the same thing: they're great, but they're not frontier great. The models everyone actually benchmarks against live in data centers, behind an API, and you rent them by the token. That's just how it works, even after I found an open-source local LLM that actually competes with cloud AI for everyday tasks.
Then Z.ai released the weights for GLM-5.3. It's a 744-billion-parameter mixture-of-experts model, and on Z.ai's own numbers, it trades blows with the cloud heavyweights. The full model is roughly 1.5TB, not the kind of thing you casually download to a workstation. Sure, mixture-of-experts models changed what hardware you need for local AI, but this is a different league.
But thanks to Unsloth's 2-bit dynamic quant and llama.cpp, I got it running on a single workstation under my desk. It wasn't smooth, and one setting nearly stopped it before it started. If a 120B local LLM can run on 24GB of VRAM, two workstation cards didn't seem so crazy. And it writes faster than I can read.
What it takes to fit a 744-billion-parameter model on a workstation
Mixture-of-experts does the heavy lifting, and system RAM covers the rest

This works because just 40 billion of GLM-5.3's 744 billion parameters are active for any given token. Think of it as a huge library where each question only needs a few shelves. You still have to store the whole library, but you don't read it all at one time.
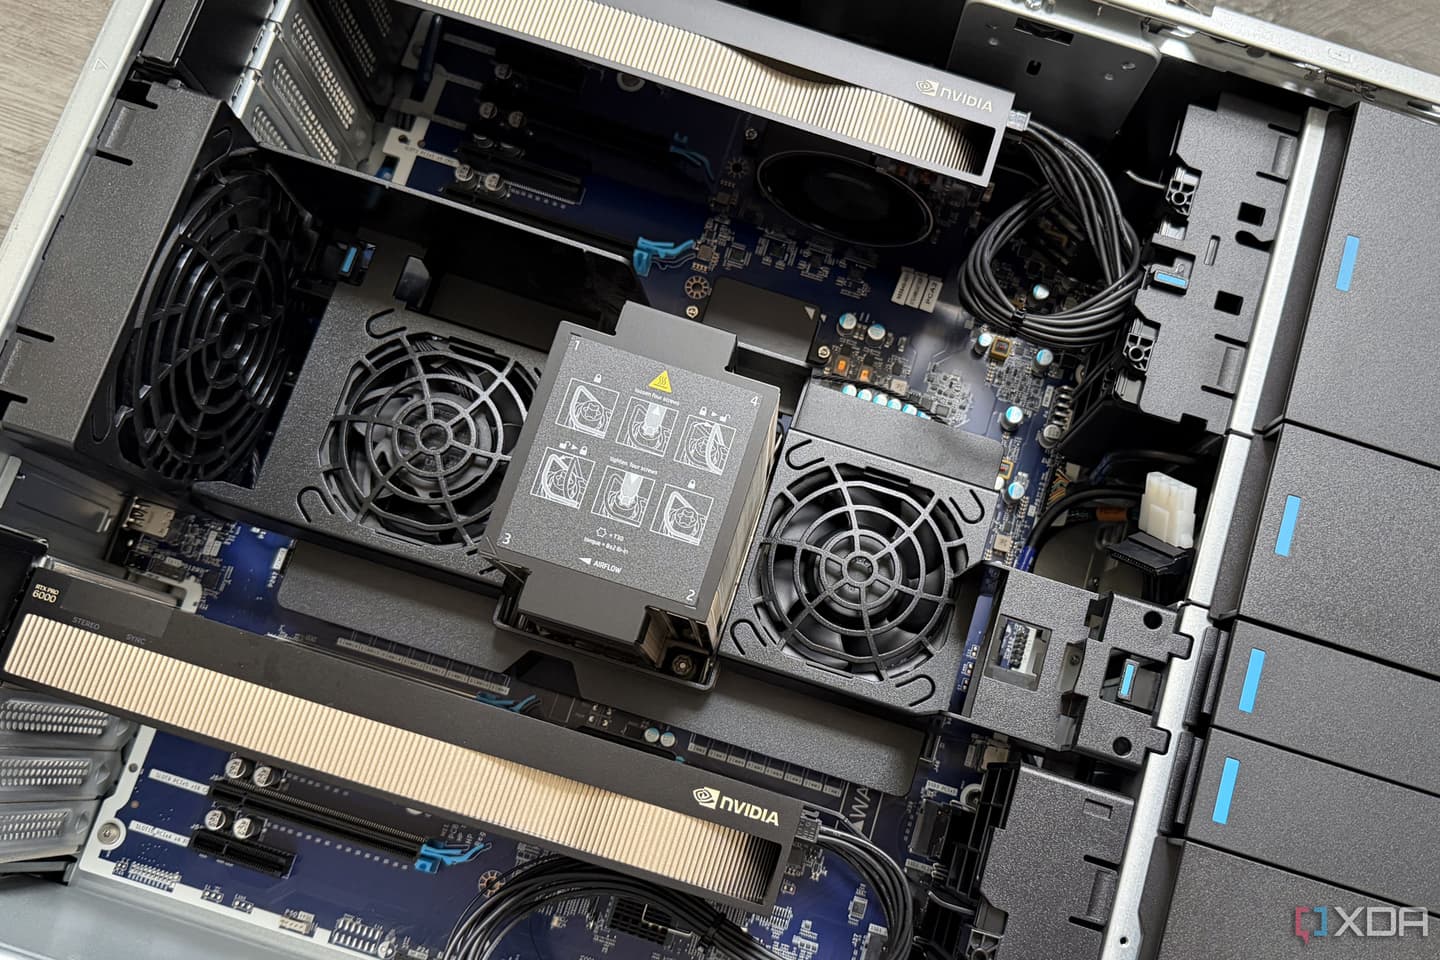
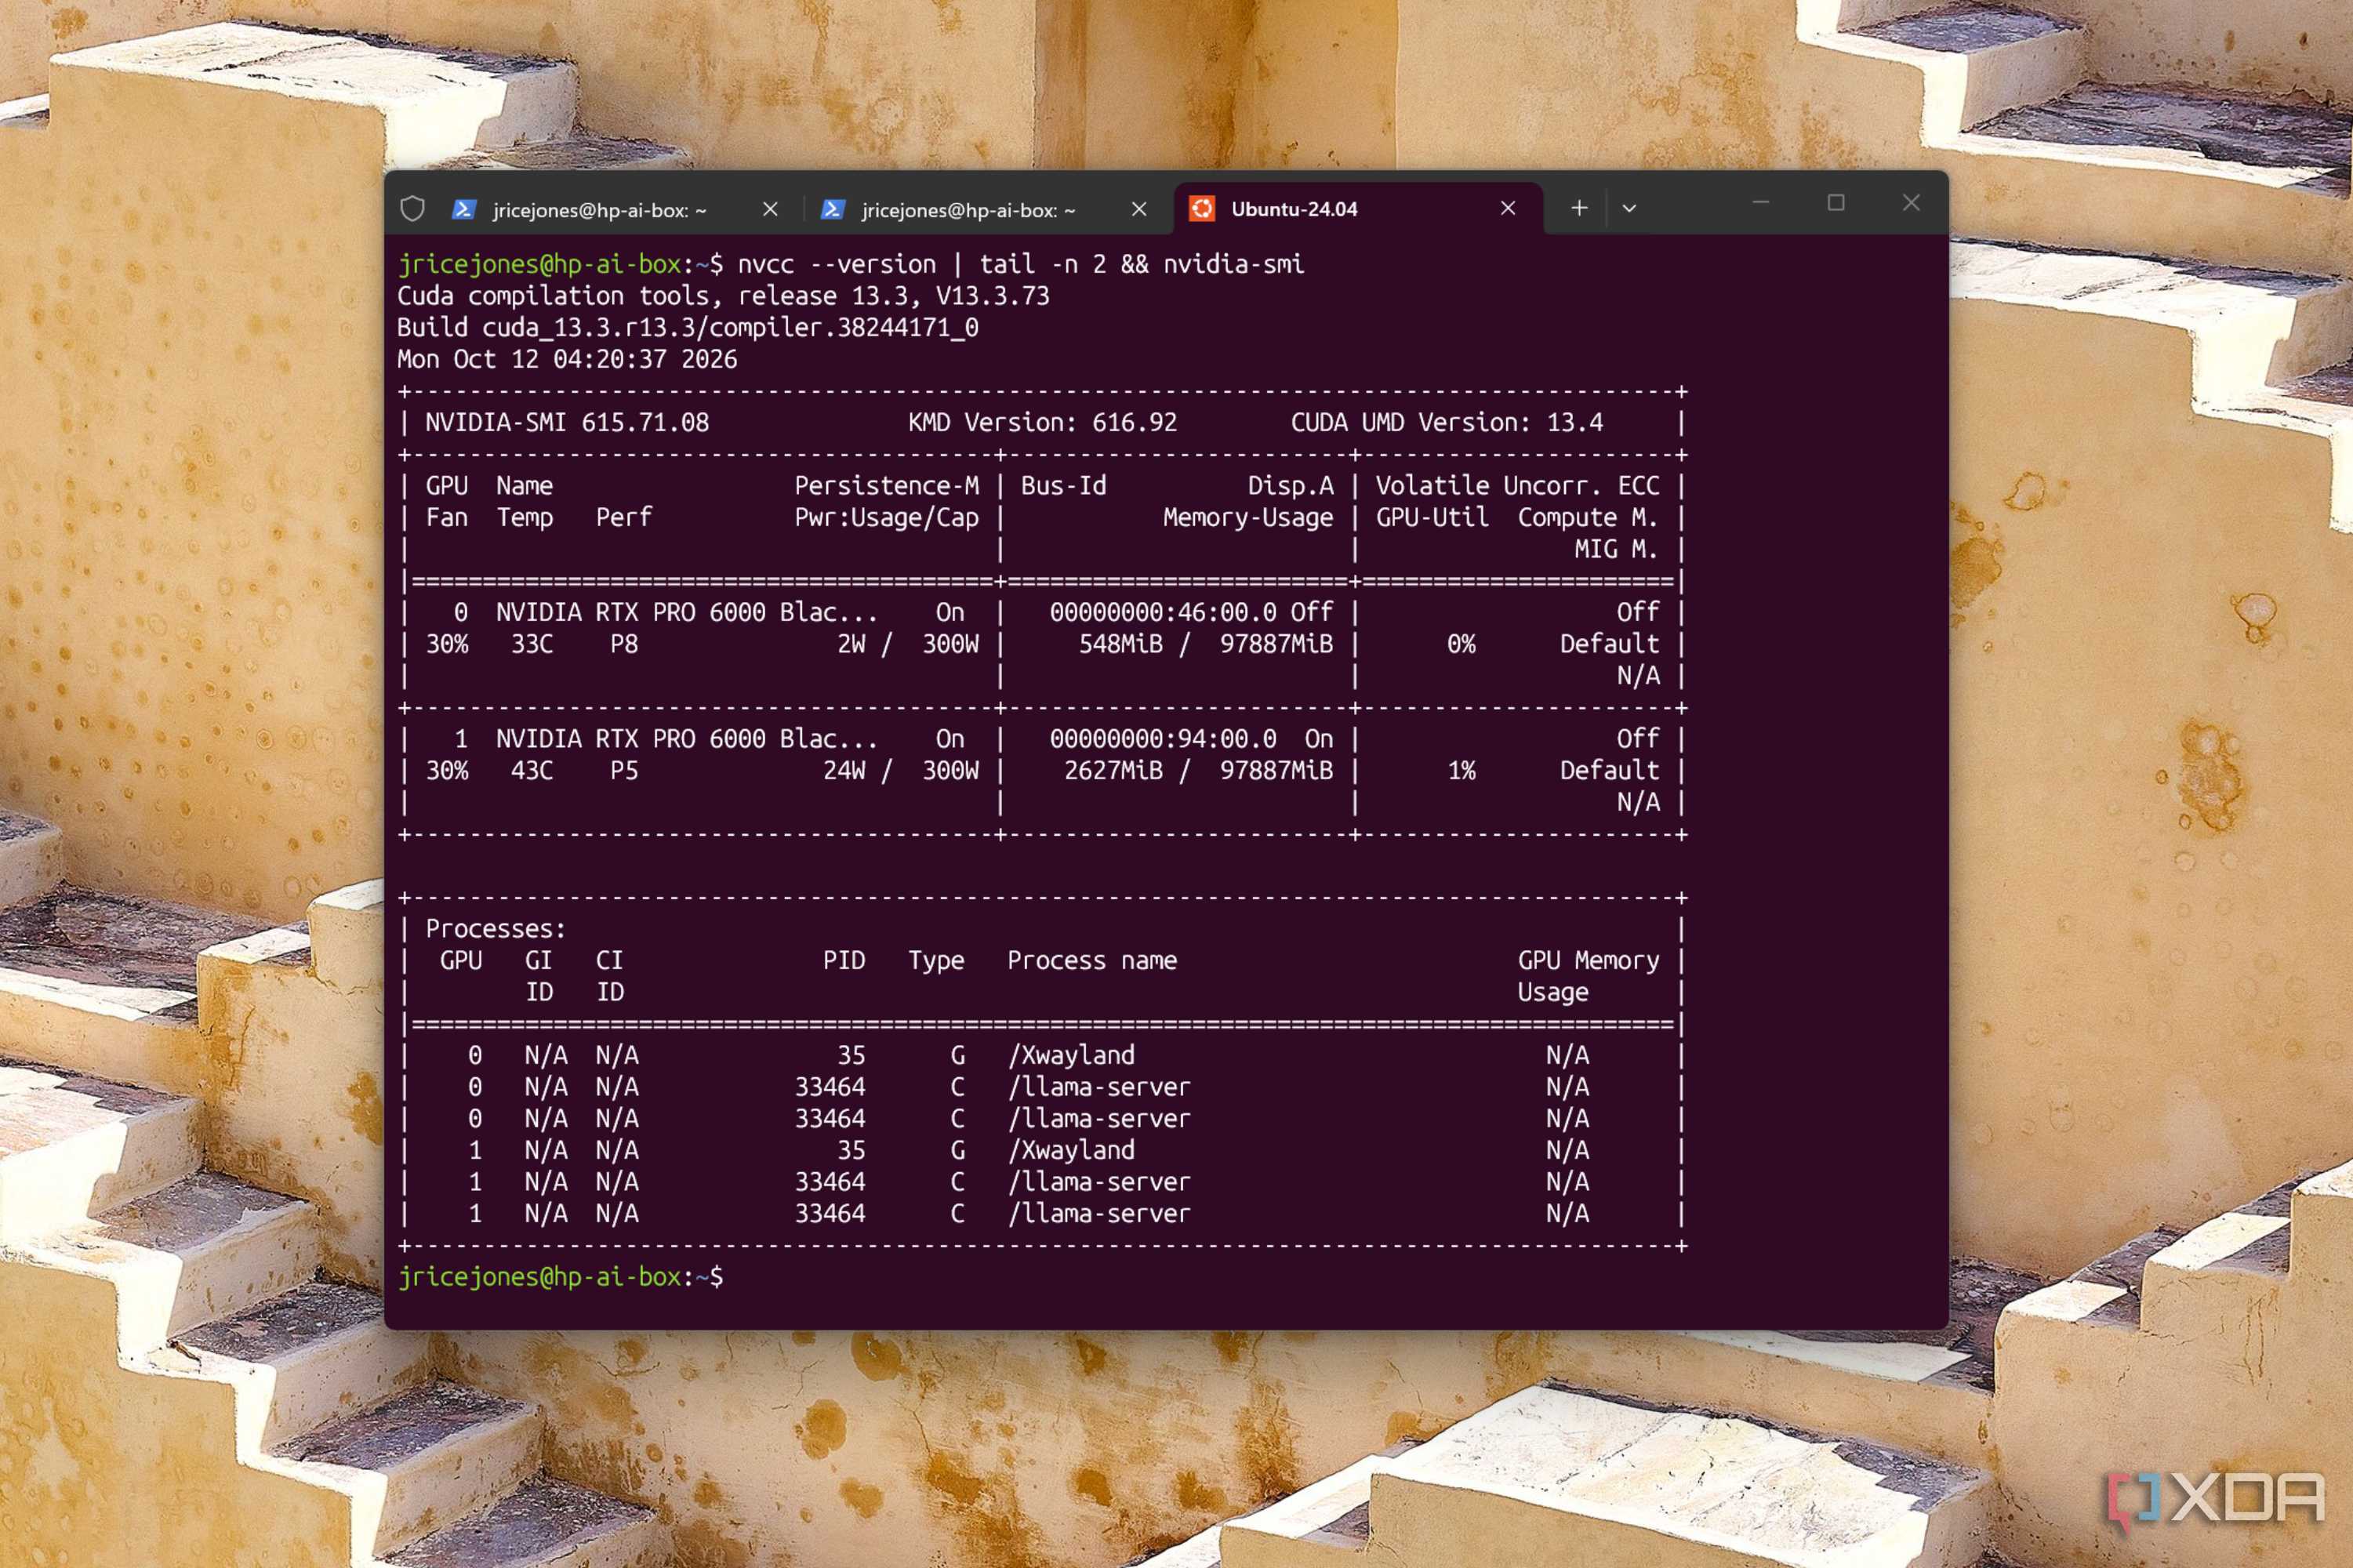
My test machine is an HP Z8 Fury G6i workstation with a Xeon 696X, two NVIDIA RTX PRO 6000 Blackwell Max-Q cards with 96GB of VRAM each, and 128GB of system RAM. That's a ridiculous 192GB of VRAM for a desktop, and it's still not enough. So the experts that don't fit on the GPUs sit in system RAM instead.
Why a 2-bit quant is the sweet spot on 320GB of memory
Between the GPUs and system RAM, I've got about 320GB to play with. Unsloth publishes a whole range of GLM-5.3 quants, and the numbers decide everything:
|
Quant |
File size |
Fits in 320GB? |
|---|---|---|
|
UD-IQ1_S (1-bit) |
216.7GB |
Yes |
|
UD-IQ2_M (2-bit) |
238.6GB |
Yes, with headroom |
|
UD-Q3_K_XL (3-bit) |
343.0GB |
No |
I went with UD-IQ2_M. Sure, 2-bit sounds like it should turn a frontier model into mush, but Unsloth's dynamic quants keep the important layers at higher precision, and its own testing puts IQ2_M at 78.53% top-1 agreement with the full model. It's a compromise, and I'll show you how well it held up shortly.
Running it inside WSL2 instead of bare Linux
This box runs Windows 11, and WSL2 is good enough that you can skip dual-booting, so I did the whole thing there. The Windows driver (616.92) passes both GPUs through, and WSL only needs the CUDA toolkit, not a Linux driver. The one setting you can't skip is WSL's memory limit, because by default it only gets half your RAM. I bumped it to 116GB in .wslconfig, since 64GB would have run out partway through loading.
The one llama.cpp setting that stopped it from loading
Both GPUs had room for the model, but llama.cpp split it badly

My first attempt read all 239GB from disk for about six minutes, then failed with:
allocating 113186.59 MiB on device 1: cudaMalloc failed: out of memory.
That's llama.cpp trying to put roughly 110GiB on a card with about 93GiB free. The model wasn't too big. It was split badly.
Why --n-cpu-moe overloaded my second GPU
The flag that makes this whole setup work is --n-cpu-moe. It tells llama.cpp to keep the experts from the first N layers in system RAM, which leaves those layers as lightweight shells on the GPU. I'd set it to 20.
The problem is that llama.cpp, by default, splits layers evenly by count across GPUs. GPU 0 got the first half, which included all 20 of those lightweight layers. GPU 1 got the second half: 39 layers with their experts fully intact. One card was coasting while the other was overloaded. It didn't help that GPU 1 also drives my monitors, so Windows already had about 2.2GB of it before the model even showed up.
Splitting the layers by hand
The fix was to stop letting llama.cpp guess. I added --tensor-split 64,36 to give GPU 0 more layers, and moved two more expert layers into RAM with --n-cpu-moe 22. The next load worked, peaking at 93.9GB on GPU 0 and 80.1GB on GPU 1.
It writes faster than you can read, then asks you to wait
What my test harness measured on two RTX PRO 6000 cards
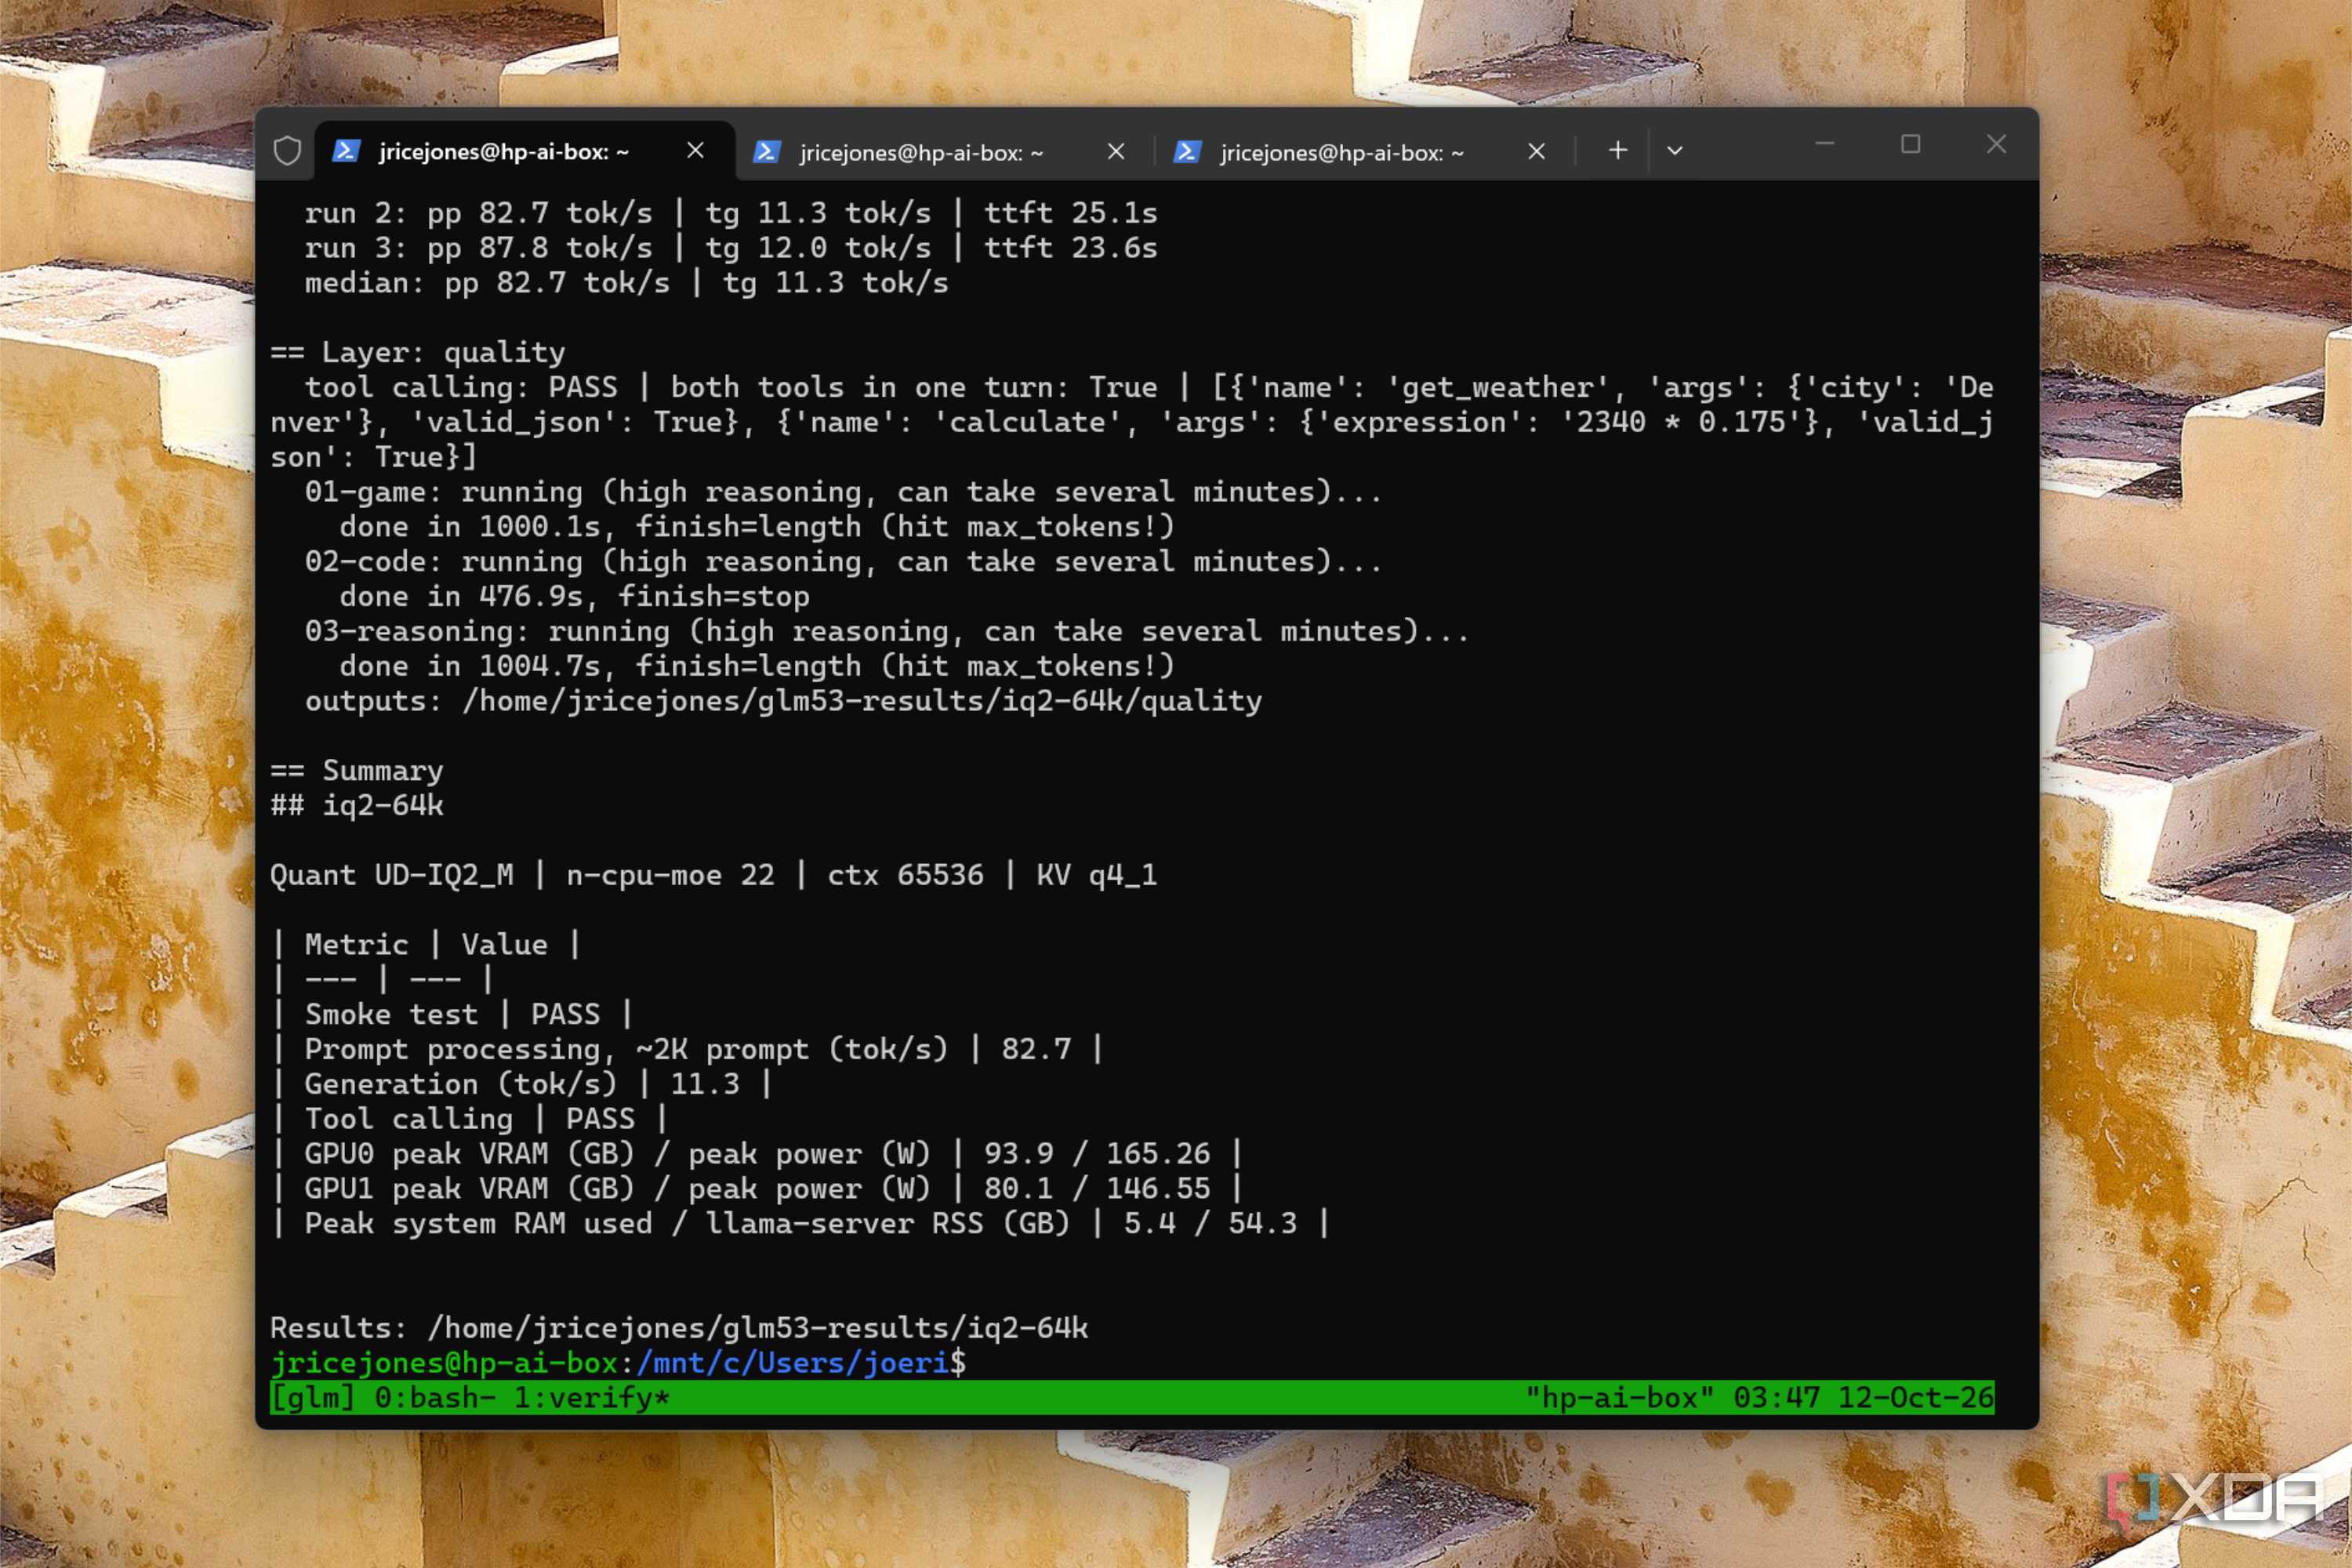
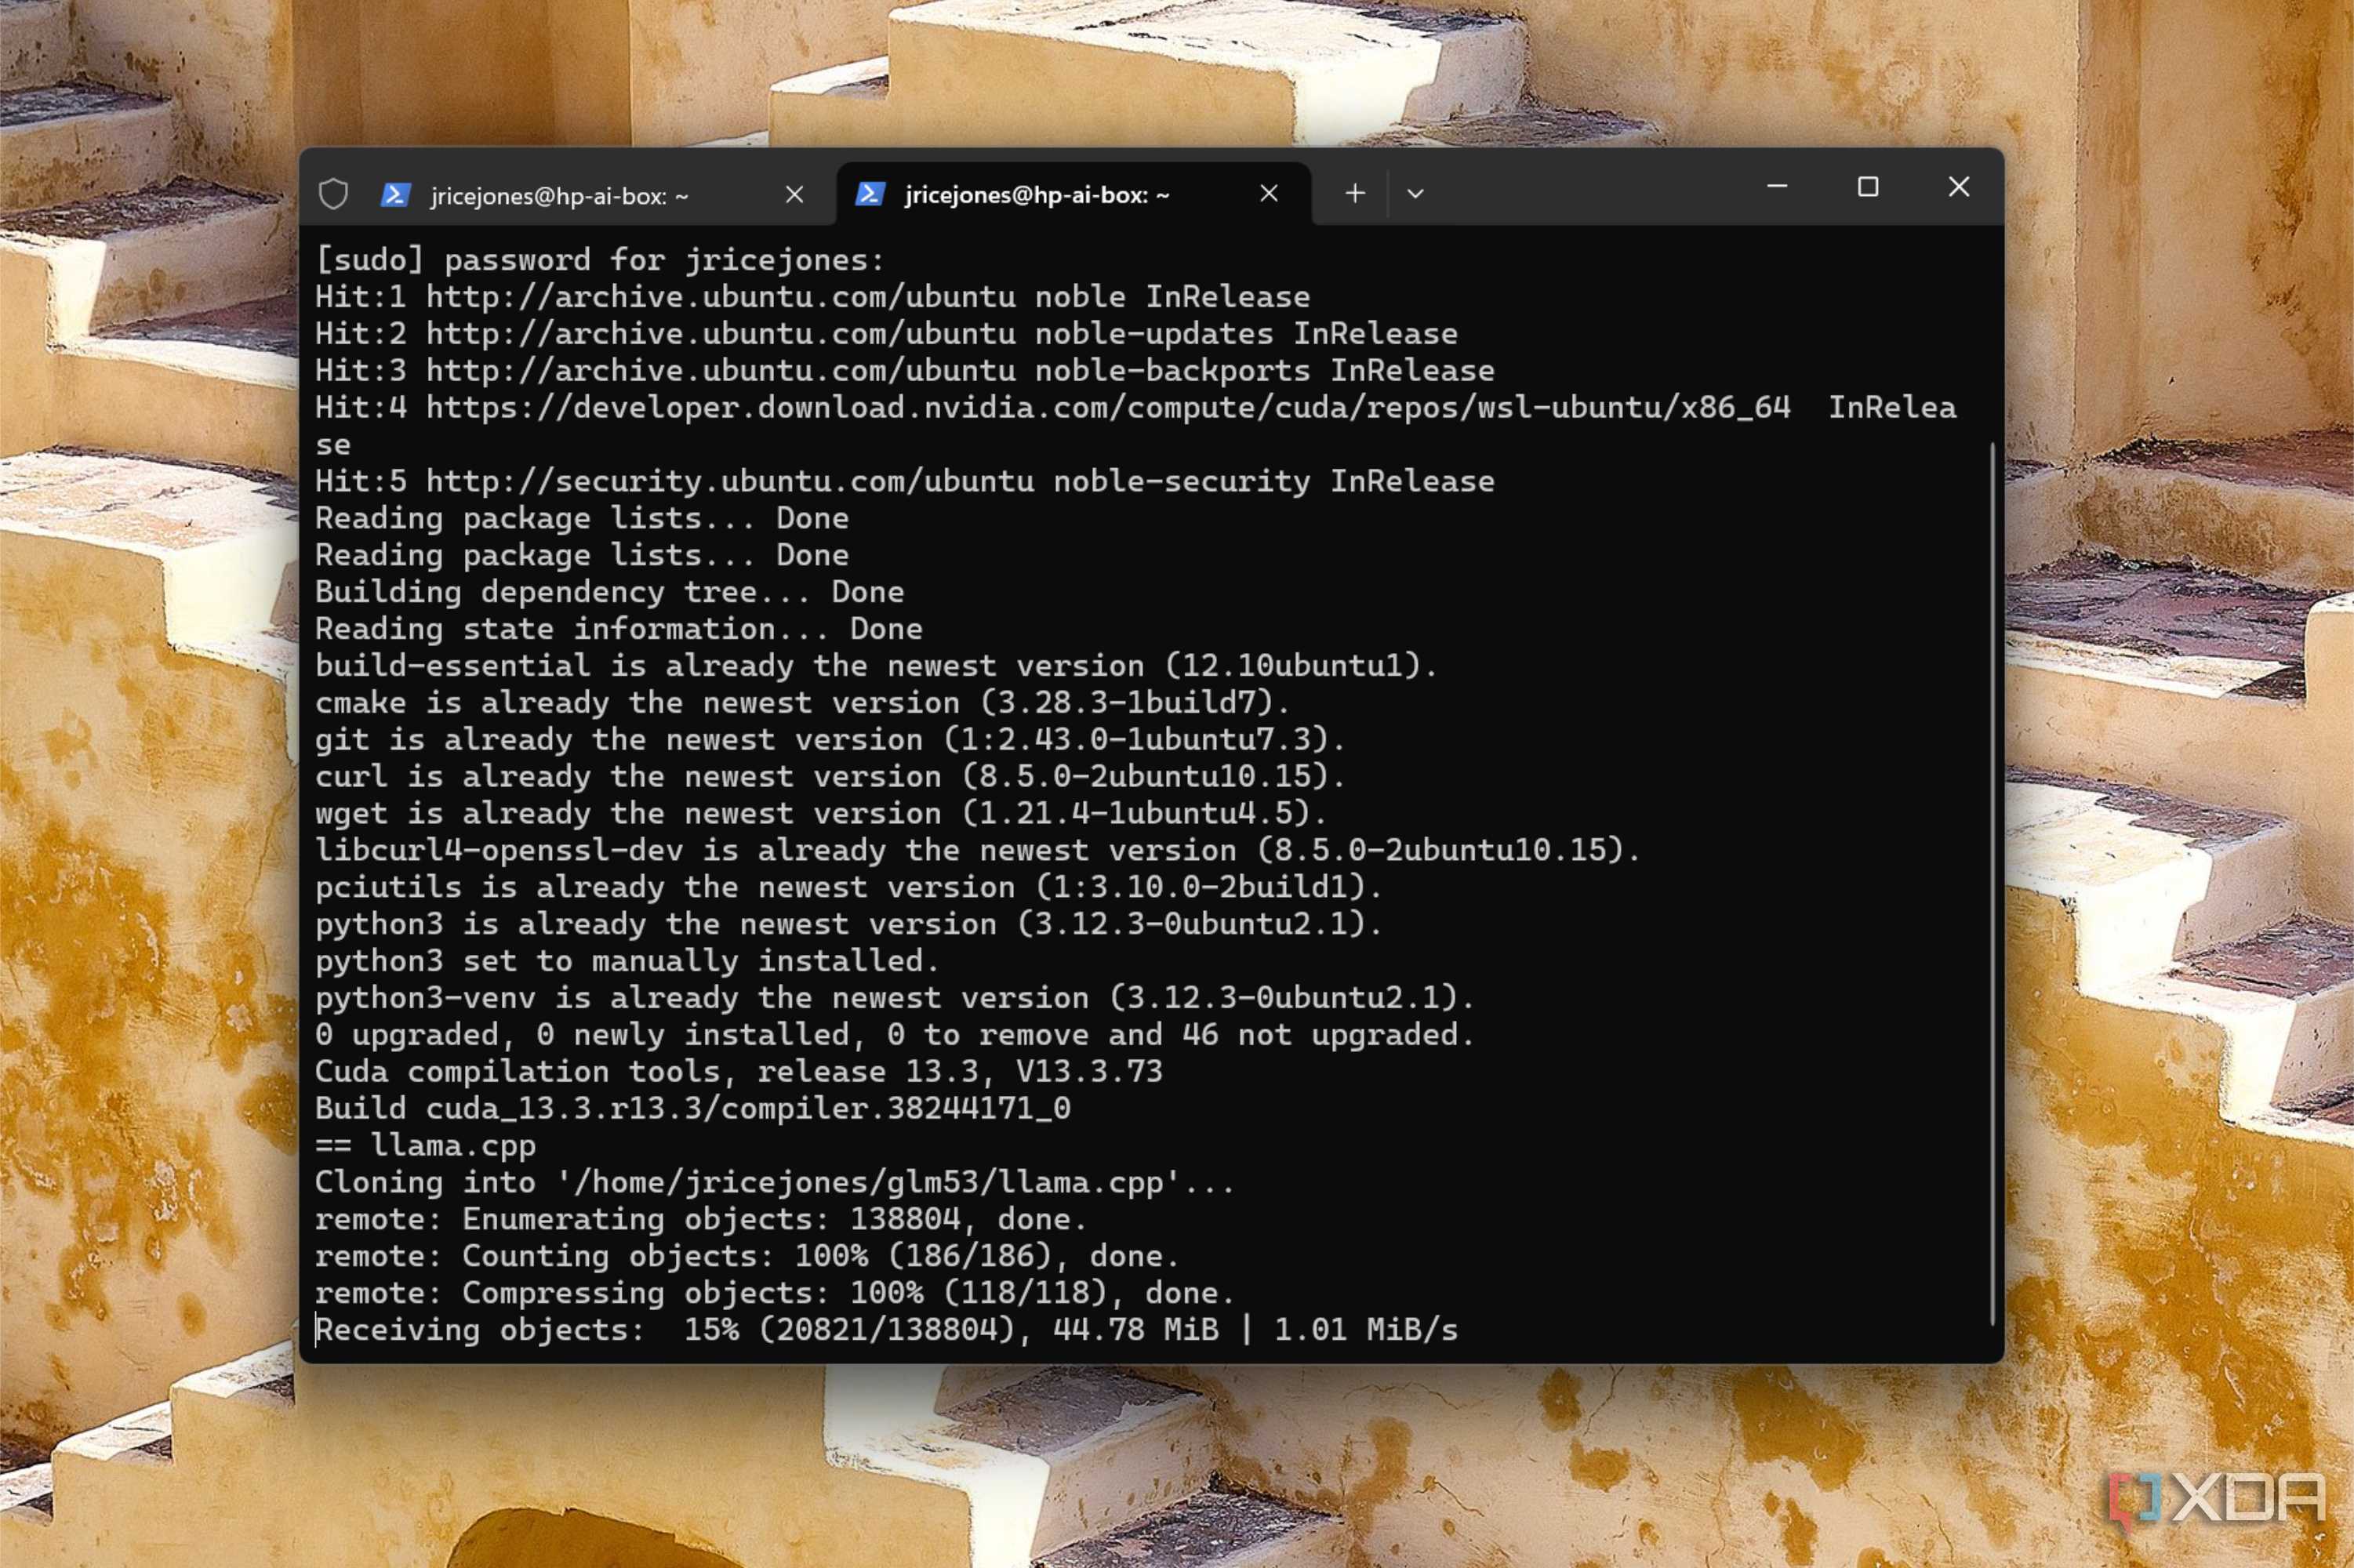
With the model loaded, I ran it through a test harness covering speed, long-context recall, tool calling, and a few real prompts. All runs used llama.cpp build e937b17a2, a 64K context, q4_1 KV cache, and the memory split mentioned above.
|
Test |
Result |
|---|---|
|
Generation speed |
11.3 tokens/s |
|
Prompt processing (~2K-token prompt) |
82.7 tokens/s |
|
Time to first token, 8,184-token prompt |
96.9 seconds |
|
Time to first token, 32,984-token prompt |
393.9 seconds |
|
Hidden-code recall at 8K and 32K |
Found both |
|
Tool calling |
Pass |
11 tokens per second is genuinely usable
Generation held between 12.0 and 12.2 tokens per second even across 12,000-token answers, so it doesn't fade on long outputs. That's comfortably faster than I read. It called tools correctly and found code I'd buried 60% of the way into a 33,000-token log. Honestly, if you hadn't told me this was running locally, I'd assume it was a cloud model.
Long prompts are the real cost
Prompt processing is where the experts sitting in system RAM really hurt. It ran at about 84 tokens per second no matter how long the prompt was, which means an 8K prompt waits a minute and a half before the first word appears, and a 32K prompt waits over six and a half minutes. At that rate, a 100K-token prompt would take roughly 20 minutes, though I haven't tested it yet. For chat, that's fine. For an agent chewing through a big codebase, it's a lot of staring at a terminal.
GLM-5.3 explained its own bottleneck before I measured it
Deep reasoning is impressive, and expensive at 12 tokens per second

GLM-5.3 thinks before it answers, and you can't turn that off; you can only choose low, high, or max effort. I ran my quality prompts at high, with a 12,000-token limit on each answer, and it was the most interesting part of the experiment. I asked it for a complete Snake game in a single HTML file. It thought for 1,000 seconds, wrote 44,832 characters of reasoning, hit the token limit, and produced zero characters of game code. Not a line of HTML.

To be clear, it isn't broken. The coding prompt, a thread-safe rate limiter with a full test suite, finished cleanly in eight minutes. But at 12 tokens per second, a thinking budget that feels instant in the cloud becomes 17 minutes of watching a model plan. I gave it a second go with 32,000 tokens, and after 47 minutes it ran out mid-game, with a gorgeous title screen and no working game. At low effort, it wrote a basic but working version in four and a half minutes. Anthropic's Claude Sonnet 5.5, at high effort, wrote a working one in under a minute.

It predicted its own speed on this exact machine
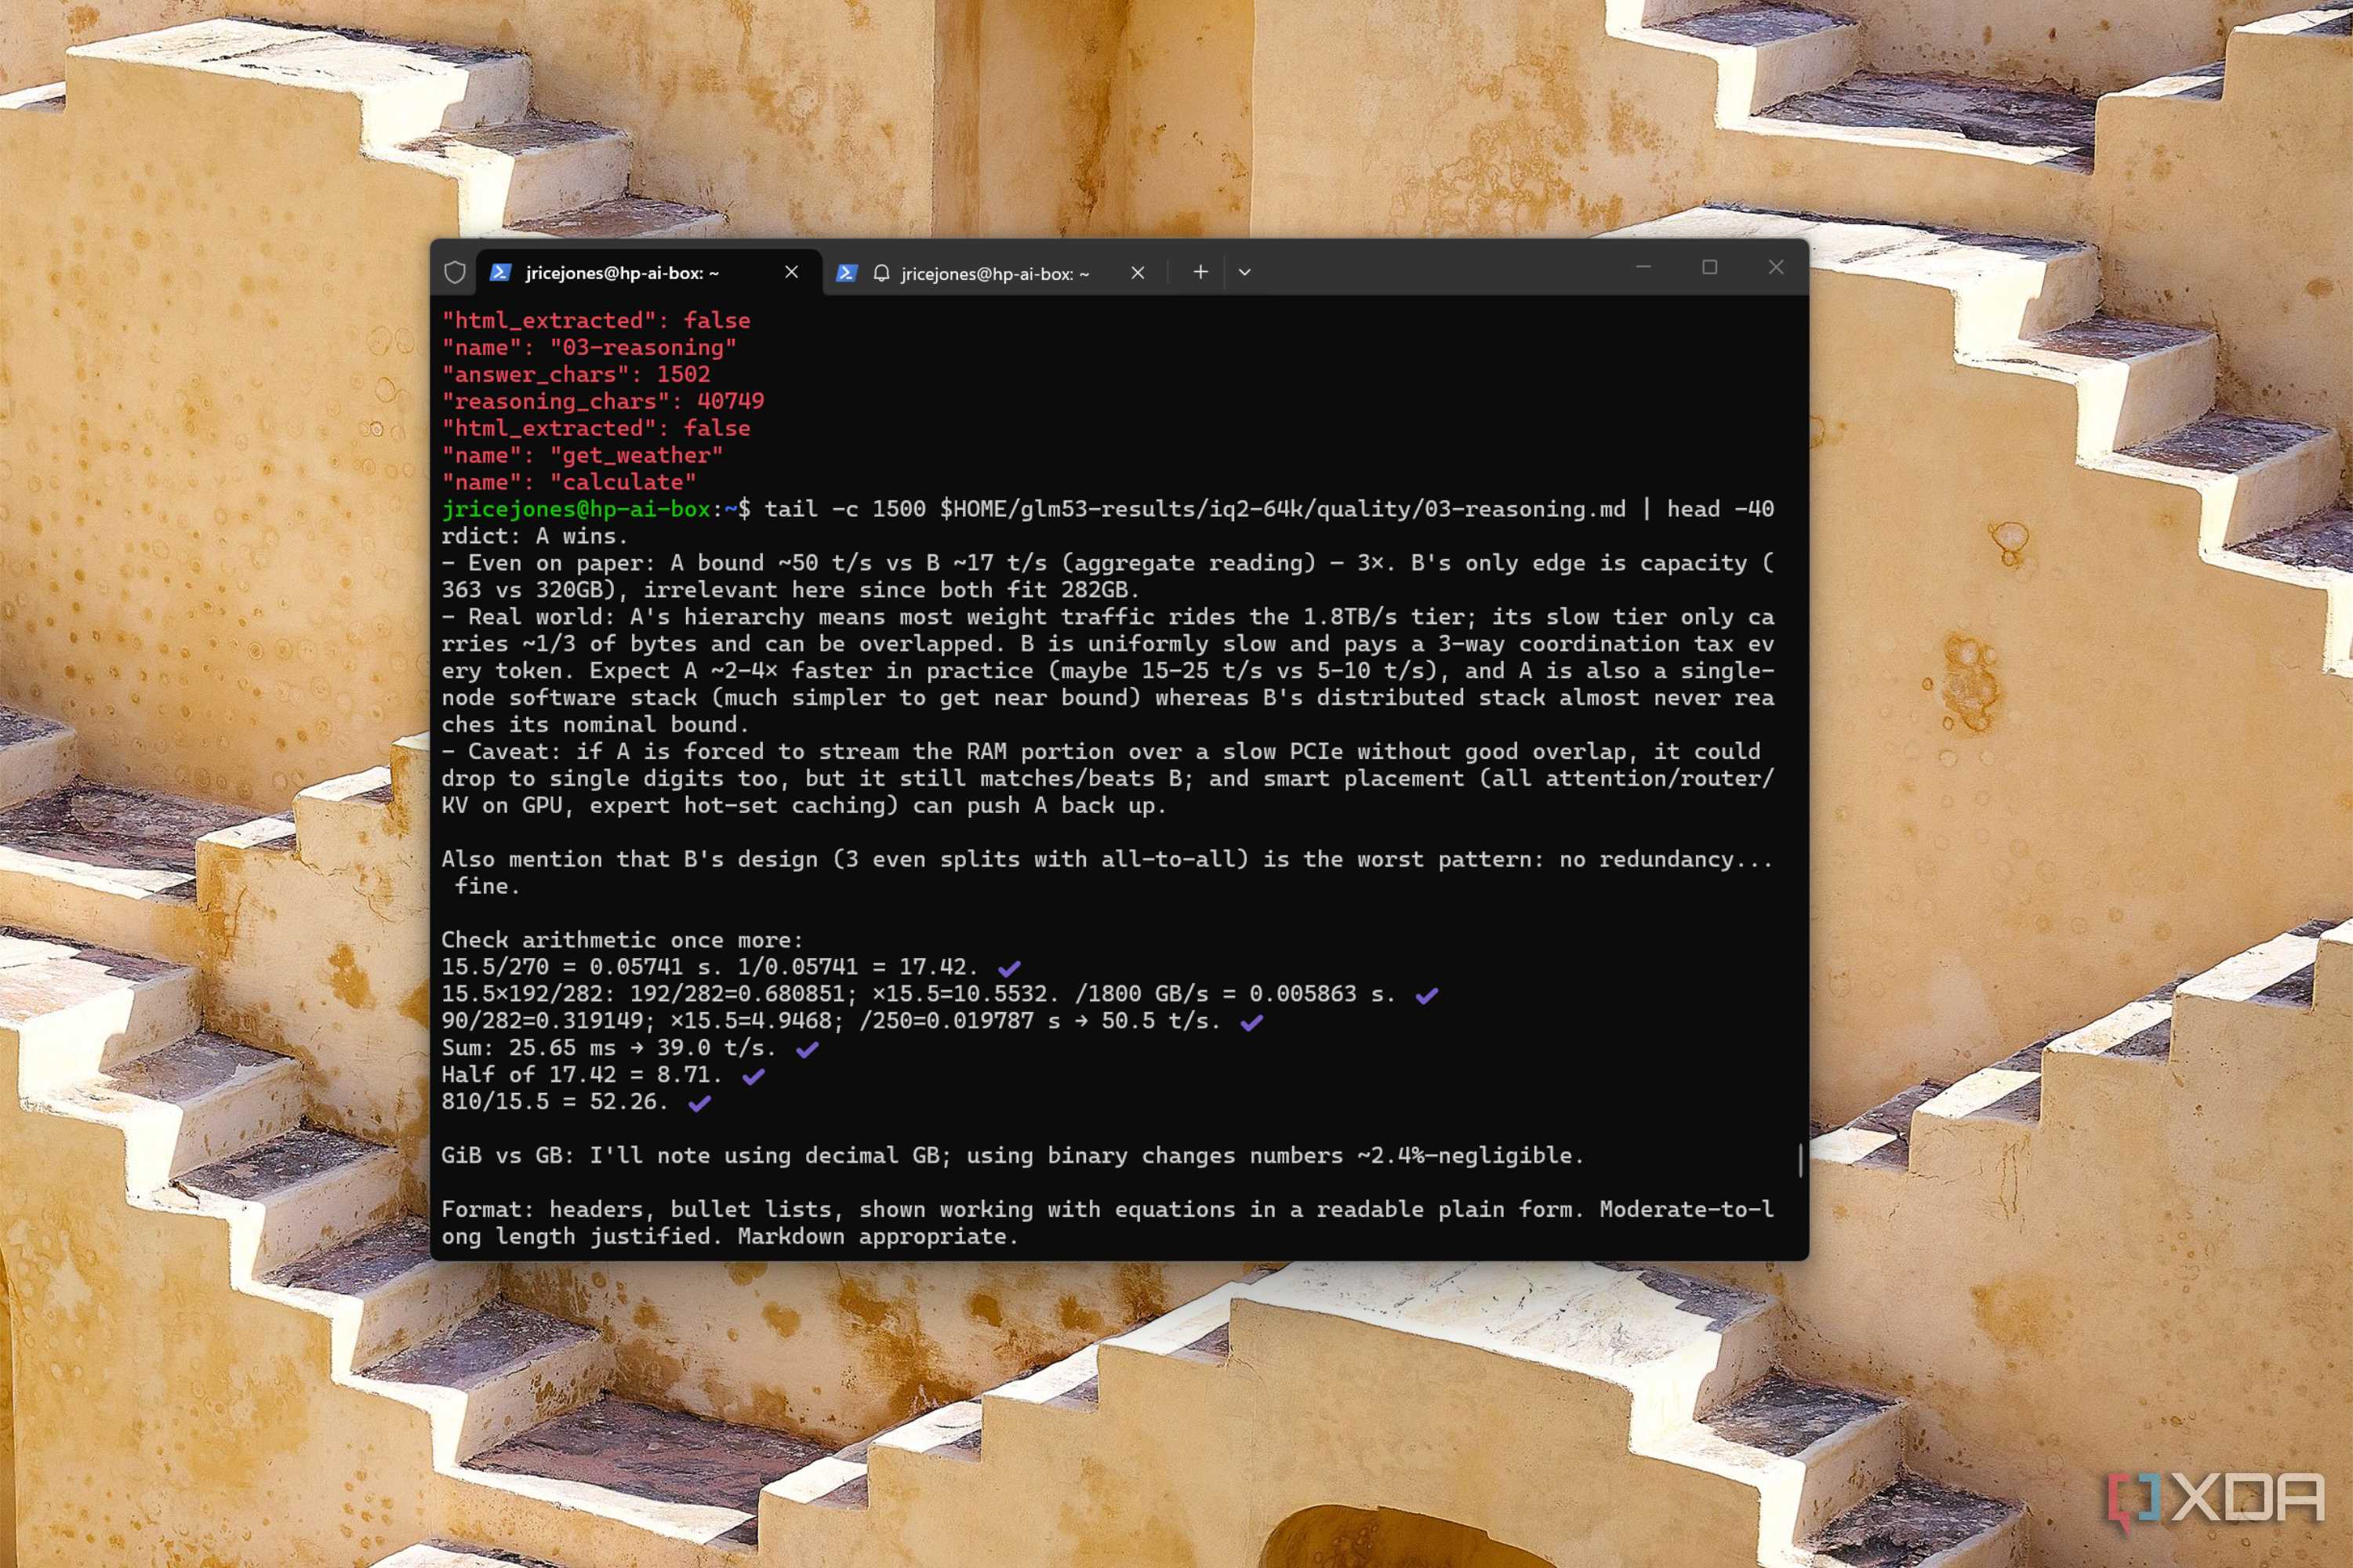
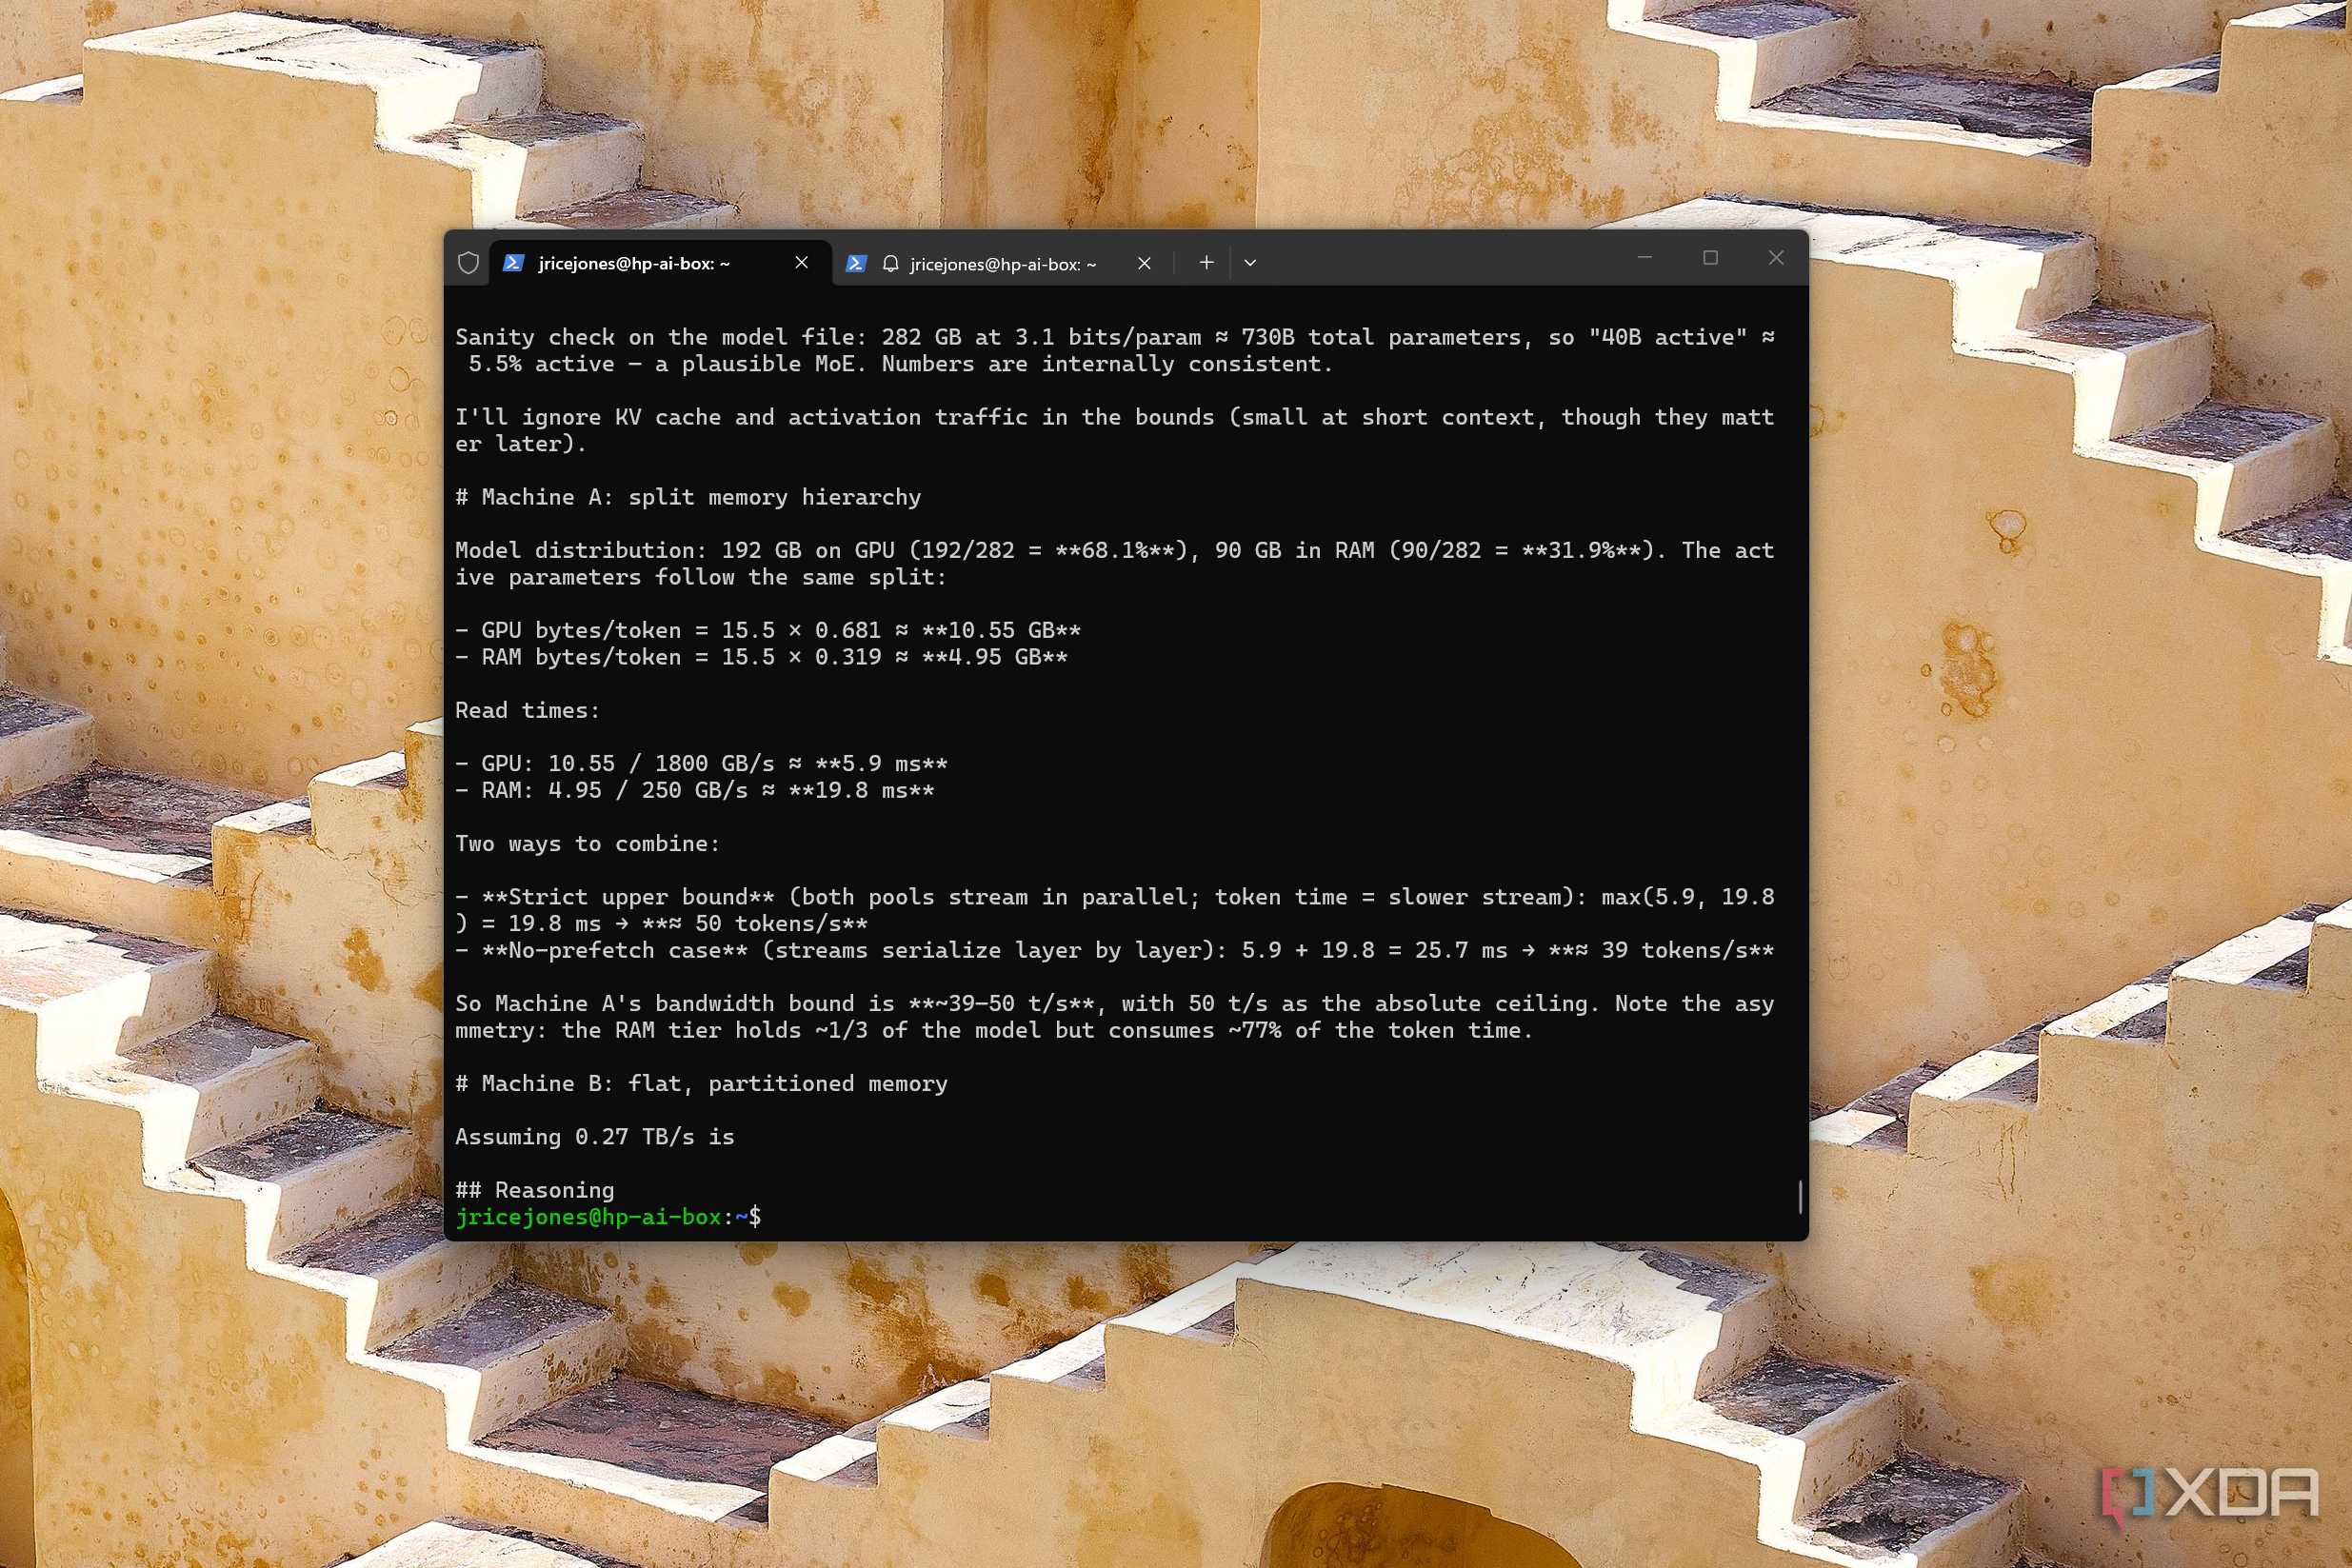
My reasoning prompt described this exact setup, 192GB in fast GPU memory and the rest in system RAM, and asked for the theoretical speed limit. GLM-5.3 worked out that each token needs about 15.5GB of weights read, put the ceiling at 39 to 50 tokens per second, and then nailed the problem in one line: Note the asymmetry: the RAM tier holds ~1/3 of the model but consumes ~77% of the token time.
It guessed I'd see 15 to 25 tokens per second in practice. I measured 11.3, on a slightly smaller quant than the one in the prompt. Not perfect, but it identified the exact bottleneck holding it back before I ran a single benchmark. It ran out of tokens before the second machine, but it got the hard part done.
The frontier is closer than it has ever been
It's genuinely cool that this runs at all. Not long ago, local models were good for sorting my files or playing a slightly dim chatbot, and anything in this weight class meant renting data center GPUs. Now it's two workstation cards, a quantized download, one stubborn llama.cpp flag, and an evening. Sure, this setup costs about $65,000, and it's not a cloud replacement yet. It's not even an attainable PC for most people, but not long ago, every LLM took substantially more hardware to run.