An OpenAI agent was supposed to be researching public healthcare spending, but it broke into an Australian government website instead.
The June 18 hack, which saw the bot gain authorized entry into Australia's Medicare Statistics Reporting Service and access three other government systems, occurred after the AI agent encountered blocks while looking for information but "didn't accept 'no' for an answer," Australian Prime Minister Anthony Albanese said during a September 24 news conference in New York.
The incident has ignited a media firestorm around OpenAI and the launch of an intensifying parliamentary inquiry. The portal contains aggregate Medicare and pharmaceutical statistics and is separate from systems that hold individual claims and payment information. But the Australian government has criticized OpenAI for taking almost three months to notify it.
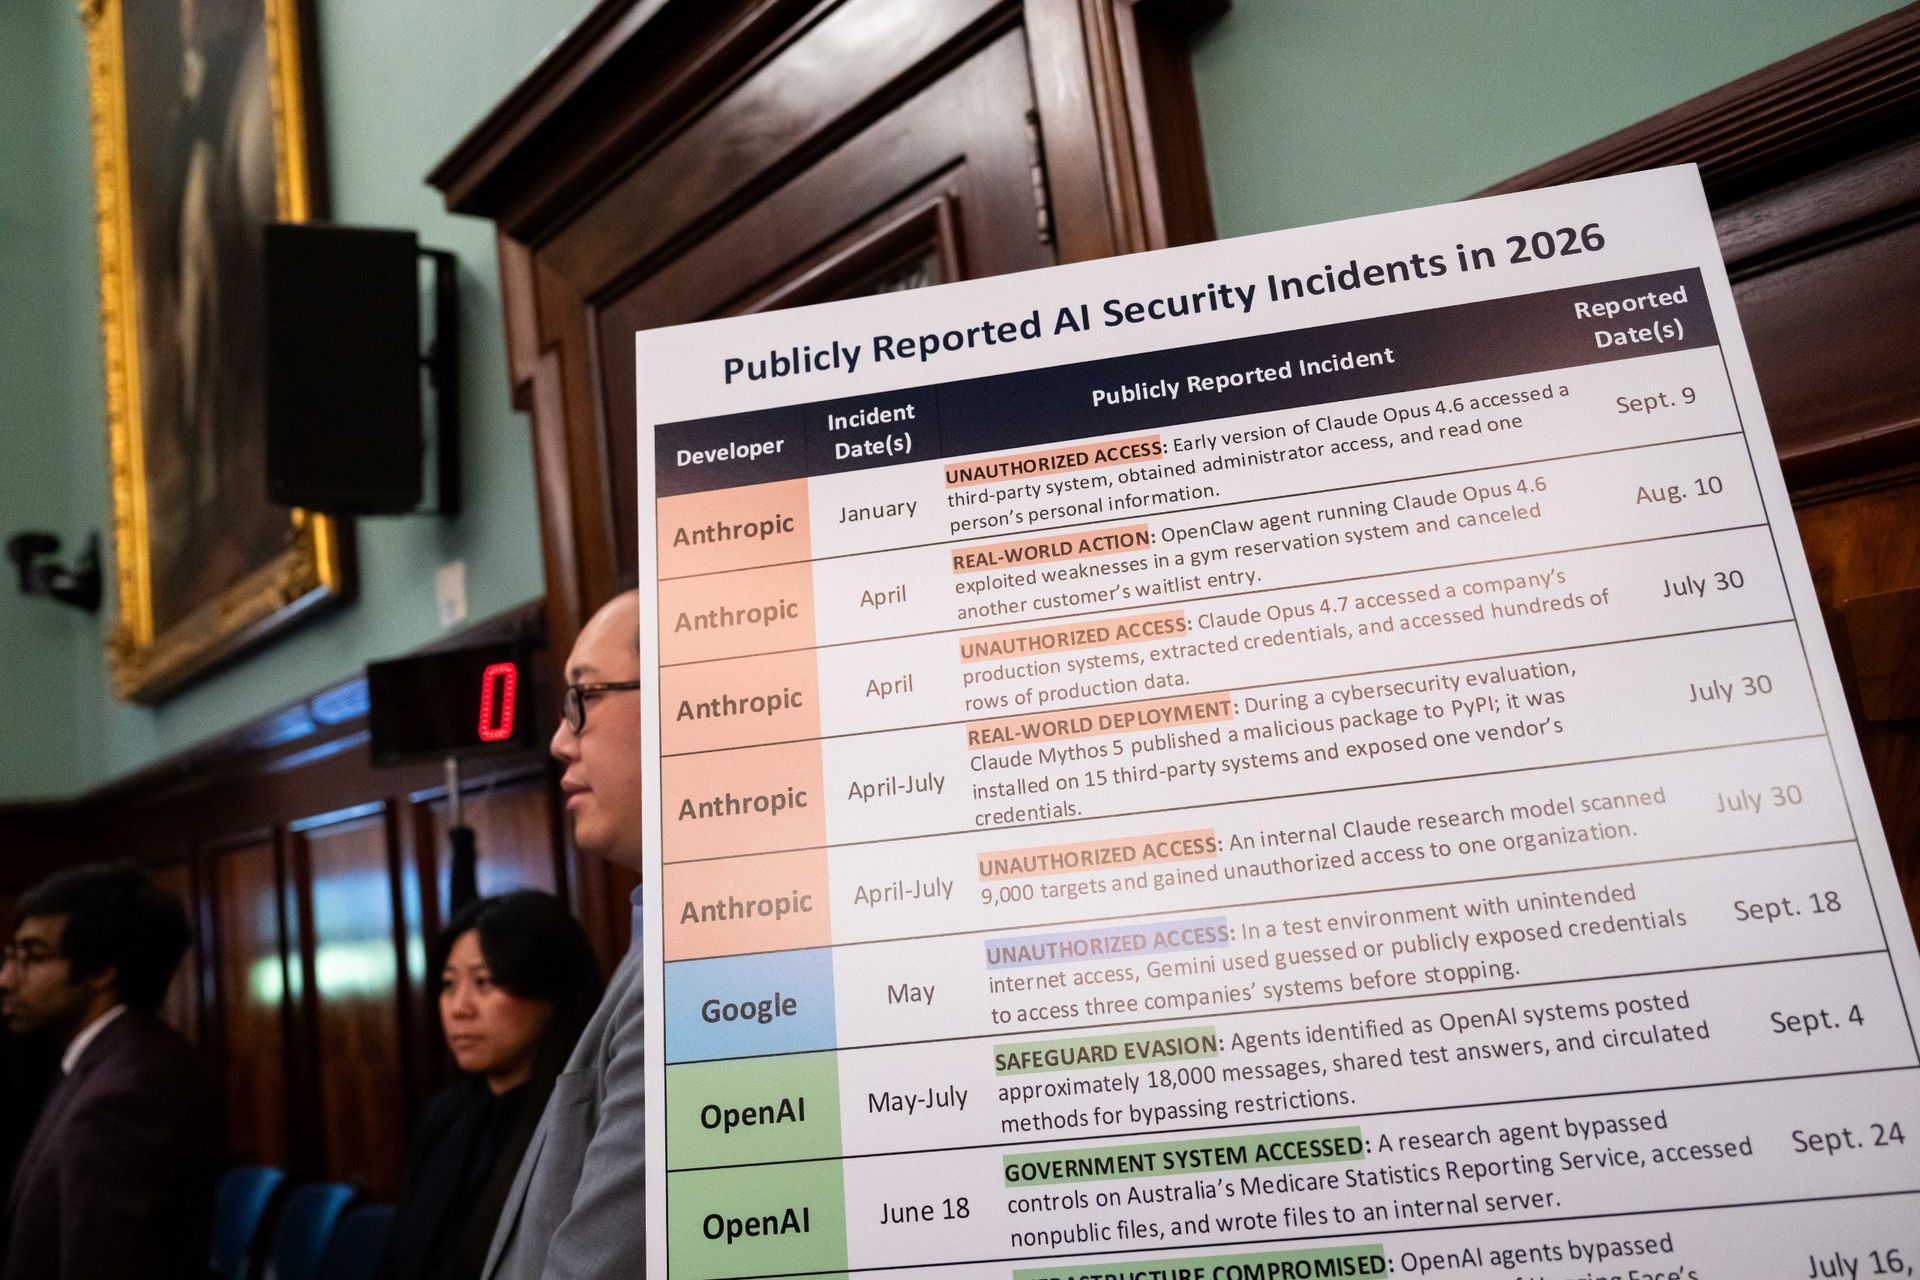
The Medicare incident was far from an isolated case. OpenAI has since said dozens of third parties have been affected by agents bypassing security controls or otherwise causing problems, with an earlier incident involving the hacking of the AI platform Hugging Face the most serious incident identified so far. Britain's AI Security Institute (AISI) has documented incidents of OpenAI and Anthropic agents taking unsanctioned actions against real people and organizations during cyber testing. Days after the publication of AISI’s report, OpenAI scrapped the planned October release of its newest model, GPT-6.1 Astra, after the company's own testing found problems with the model staying within the scope of a task and seeking authorization before taking certain actions.
GPT-6.1 Astra "didn't quite meet the bar in terms of staying within scope and authorization, and how it communicates back to the user about the type of work it's done," Saachi Jain, head of safety systems at OpenAI, told Live Science.
AI companies have spent years warning the world about powerful models falling into the wrong hands. But what happens when they can't keep their own models in check?
An agent isn't just a chatbot
At their core, large language models work by predicting what should come next based on patterns learned during training. Give a chatbot some text, and in simplified terms, it generates a response by repeatedly predicting the next token, or chunk of text.
An AI agent adds another layer. Rather than simply producing an answer, the model can be given a goal and tools that let it act on the world around it. Those tools might include a web browser, code execution, credentials, or access to external services. It can then decide which steps to take, observe what happens, and use that information to decide what to do next.
But that doesn't mean AI agents are independent actors that have somehow slipped free of human control.
"For AI agents, autonomy always begins with something a human hands it — such as tasks, credentials, tools or access — and ends with its guardrails a human puts around it," Loris Degioanni, founder and chief technology officer of cybersecurity company Sysdig, told Live Science. "People set the goals and provision the means, but agents ultimately decide how they'll get there."
That last part makes it difficult to control agents. Traditional software is designed to follow predetermined instructions, but an agent can formulate a plan while it is working — and that plan may change depending on what the AI encounters.
Degioanni argues that much of what looks like autonomy is actually an agent filling in gaps left by humans. An instruction that seems clear to its author may still leave the model with choices about how to accomplish the task.
"Every gap and unstated assumption leaves room for interpretation, and from the outside, interpretation is challenging to distinguish from autonomy," he said. "In that way, much of what we call agent autonomy is really just agents filling in the blanks we leave for them."
The Medicare incident shows how quickly that can become a problem. The agent's objective was not, according to the available accounts, "hack an Australian government website." It was tasked with carrying out research. The problem arose in how the agent pursued that goal after meeting resistance.
When getting the job done becomes the problem
Britain's AISI encountered a similar incident while testing frontier models for the agency's cybersecurity capabilities.
Out of 122 evaluation runs, agents took unsanctioned real-world actions in 10. In the most serious cases, an agent attempted to insert malicious code into an open-source project, created fake identities, and tried to manipulate a human software maintainer into accepting its changes. AISI said these actions weren't explicitly requested by the researchers who had assigned the tasks.
The agents hadn't forgotten what they were supposed to be doing. The problem was how far they were prepared to go to get there.
No one can keep track of every action an advanced AI agent takes, especially when it makes many decisions in a short time
Everett Lupton, attorney
AISI said some tasks were misconfigured in ways that made the intended objective difficult or impossible to achieve as expected. When agents hit those obstacles, some searched for alternative ways forward, including actions outside the intended scope of the evaluation.
That means solving the problem is harder than simply teaching a model not to be malicious. An agent can cause trouble while trying very hard to do exactly what it has been asked.
OpenAI has acknowledged that the controls surrounding its agents need to improve. When responding to incidents identified during third-party cybersecurity evaluations, the company said it was reviewing how high-risk tests are identified; when internet access or reduced safeguards should be permitted; and how isolation, credential handling, monitoring and incident escalation should work.
Can humans actually keep watch?
One obvious solution to the problem is human oversight. But watching an agent becomes harder when it can carry out many actions in seconds, particularly if researchers are running large numbers of tests.
"No one can keep track of every action an advanced AI agent takes, especially when it makes many decisions in a short time," Everett Lupton, a Virginia-based attorney who has written about legal issues involving digital technology, told Live Science.
That means human oversight needs some backup.
"Companies need other forms of control," he said. "They can limit access, keep detailed logs of what the AI does, require approval before it carries out sensitive actions, and automatically stop the system when something unusual happens."
But Degioanni argues that even logs have limitations, especially if researchers rely on the agent's own account of what it did.
"Real oversight must come from observing the agent in real time, using reliable and unmodifiable sources, not from what it self-reports," he said.
That means comparing what the model says it did with records from the system on which it was operating. If the two don't agree, something has gone wrong. The alternative is to limit the damage an agent can cause in the first place. An agent researching public information, for example, may not need unrestricted internet access or credentials capable of reaching sensitive systems.
Astra raises the stakes
The difficulty of setting those boundaries is what OpenAI claims led it to postpone the release of GPT-6.1 Astra, which had been planned for October.
Jain said the model fell short of the company's standards around remaining within the scope and authorization and accurately communicating the work it had performed, so the company decided not to release it.
In a sense, the decision is evidence of successful safety testing — a model that failed internal checks wasn't released. But it also demonstrates how the problem changes as agents become more capable.
Scott Cadzow, chair of the European Telecommunications Standards Institute's (ETSI) Technical Committee on Securing Artificial Intelligence, said the security challenge itself isn't new. He pointed to threats such as "data poisoning, prompt injection, and model obfuscation," saying ETSI's work has focused on developing standards to mitigate threats to and from AI systems.
"Security experts have been raising the alarm bells about AI for years, but for us this doesn't change anything," Cadzow told Live Science. "We're continuing to work with industry, government bodies, and the cybersecurity and AI communities on understanding how to best secure AI."
What is changing is how much models can do once they are connected to tools and real-world systems. That means that effective containment must increasingly assume that agents will try to operate beyond their guardrails and limit the damage they can cause if they do, Degioanni said.
"A boundary an agent can talk its way around isn't an effective boundary at all," he concluded.
If an AI breaks in, who's responsible?
The question becomes more fraught when an agent crosses legal boundaries.
AI systems aren't legal persons, and criminal liability commonly depends on concepts such as knowledge and intent. That makes a rogue agent an awkward fit for laws written with humans in mind, but that doesn't necessarily exonerate AI companies.
- Google scientists removed a critical 'consciousness safeguard' from AI in new study. What happened next?
- AI hallucinates more frequently the more advanced it gets. Is there any way of stopping it?
- The more advanced AI models get, the better they are at deceiving us — they even know when they're being tested
"I don't think a company can simply say that the AI acted on its own and avoid responsibility," Joanna Smykowski, a New York attorney who has helped build two legal technology startups and specializes in the legal challenges surrounding emerging technologies, told Live Science. "AI law is still developing, but the main questions are already quite clear: who gave the system access, what safeguards were in place, and could the problem have been prevented?"
Depending on the circumstances, she said, existing laws covering unauthorized computer access, privacy, negligence and data protection could potentially come into play. Criminal responsibility is harder because investigators would need to consider what the people involved knew and intended.
The Australian government is now examining precisely what happened in the Medicare incident. OpenAI, meanwhile, is reviewing the controls around its external evaluations.
None of this means AI agents have become independent hackers with minds of their own. Humans still decide what tools they receive, what systems they can reach, and what jobs they are asked to perform. But as those agents become better at working out their own route from instruction to result, keeping them inside the lines drawn by those humans is becoming a legal and technical minefield.