SILICON VALLEY — SK hynix (000660.KS) has proposed a system design that places memory at the center of AI rack systems, offering it as a way to overcome the memory shortages created by the artificial intelligence boom. Memory has long been treated as a subordinate component to graphics processing units and central processing units, but as it emerges as the most critical infrastructure in the era of agentic AI, the proposal marks a shift in thinking toward building servers that maximize memory efficiency.
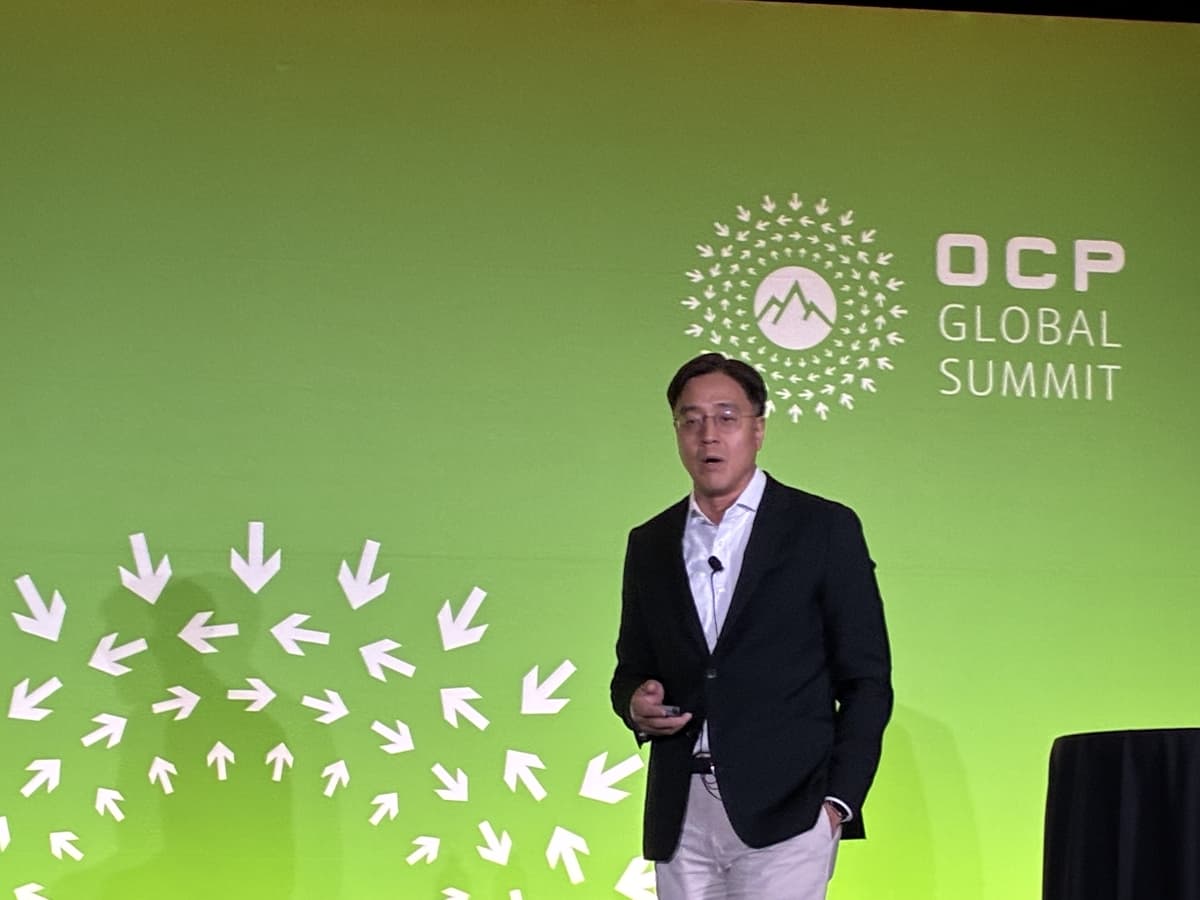
Kim Ho-shik, executive vice president at SK hynix, delivered a presentation titled "Introduction to Memory-centric AI Rack System (MARS)" at the Open Compute Project Global Summit held at the San Jose Convention Center in California on the 12th.
A server rack is a structure of network equipment that houses AI processors including GPUs and CPUs, memory such as high-bandwidth memory (HBM), cooling systems and switches. Hundreds to thousands of server racks together power a data center. Processors were the core of AI in the market for training, but as the industry moves into the era of inference-based agents, fast and economical computation has grown more important. As a result, AI companies are competing to improve efficiency through the way they configure server racks.
The problem is that memory is the key infrastructure determining inference performance, yet server racks are designed around AI chips — lowering memory efficiency and worsening supply shortages. The explosive growth of generative AI and hyperscale data centers has created severe bottlenecks, such as the memory wall, in servers designed around CPUs and GPUs, while also amplifying power consumption.
In a processor-centric server rack, for example, when some servers run short of memory capacity, they cannot draw on spare memory from other servers and additional memory must be purchased. Buying more GPUs to improve memory access raises costs, making it economically wasteful as well. "Memory demand in AI is rising sharply, but GPU memory — that is, HBM — faces physical and economic constraints," Kim said. "Delivering next-generation AI performance requires a fundamental rethinking of how data is stored, accessed and shared."
Kim argues that these problems stem from rack designs built on a structure in which CPUs or GPUs perform computation and memory serves only as a simple auxiliary. Shifting to a memory-centric approach, he explained, would allow large shared memory to support multiple computing units and enable flexible access to data. "Now is the right time to talk about memory-centric rack systems," he said. "Computing systems must be redesigned around disaggregated memory and solid-state drive systems."
Memory disaggregation involves separating the memory attached to CPUs and GPUs to create a large memory pool. The pool keeps demand balanced across servers and allows servers running short to make up memory capacity without adding AI processors. Capacity is allocated according to demand, saving the cost of unnecessary server purchases. The pool also enables high-speed data sharing. SK hynix introduced the concept of disaggregated memory in the journal Nature Electronics in August. "We are currently supporting customized testing for MARS and expanding the system with a number of partner companies," Kim said. "If you are interested, please join us at any time."