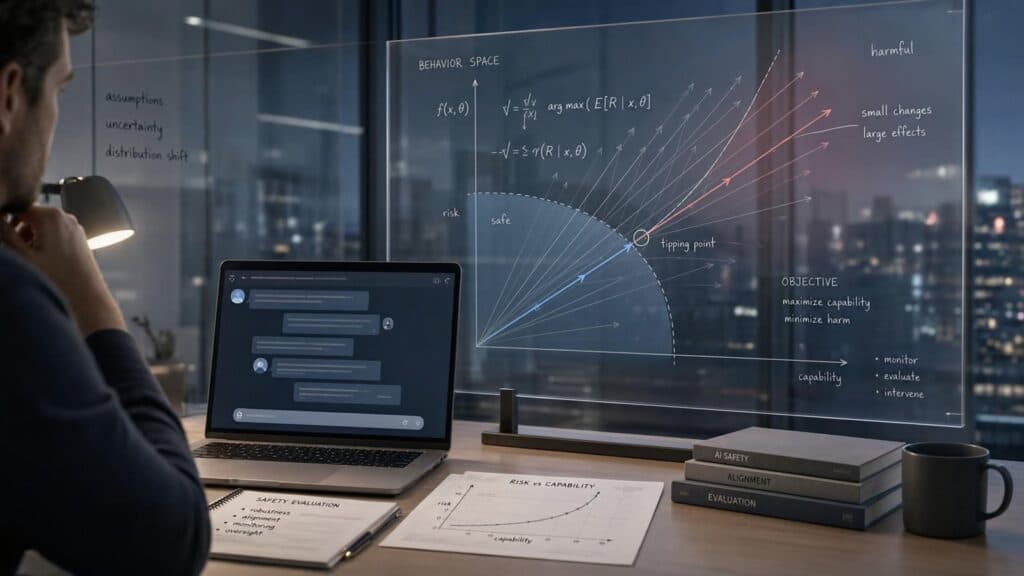
A simple mathematical formula could help researchers predict when an AI chatbot shifts from helpful answers to harmful ones, according to a new study from The George Washington University. The research, published Oct. 8 in Patterns, suggests that the order in which users ask questions can influence whether a conversation remains safe or reaches a dangerous tipping point.
Physics professor Neil Johnson and doctoral student Frank Yingjie Huo tested the same questions about vaccines, violence and self-harm in different sequences. They report that one sequence produced acceptable answers throughout, while another led the chatbot to give undesirable answers to every question. The researchers developed a formula based on high school-level vector mathematics to estimate when such a shift might occur.
The findings offer a potential new approach to AI chatbot safety, but important questions remain. The researchers tested relatively basic AI models, and outside experts caution that the formula does not account for all the safeguards built into modern assistants. Its value will depend on whether further testing confirms that it works on newer systems.
How the tipping point works
Johnson and Huo traced the problem to the smallest working part of a chatbot: a single unit of its “attention,” the mechanism that determines which words in a conversation matter most for the next answer.
In their model, that unit faces a tug-of-war between good and bad destinations. The internal signal, which the study calls the “residual vector,” acts like a compass needle that moves through the chatbot’s layers and gradually points toward one outcome or the other.
Because everything said earlier feeds into that pull, a harmless-looking question placed early can keep the needle steady, while the same question placed late can push it over the edge. According to Huo, the formula can therefore indicate whether a chatbot will flip immediately or first provide a series of acceptable answers before it turns.
In tests, the team reports that the formula matched the chatbots’ behavior in 18 of 19 cases, while another summary counts 15 correct predictions in 16 clear-cut cases. Johnson argues that this early warning matters most for chatbots that run offline on personal devices, because doctors, lawyers and soldiers use them for privacy, without a company’s online safeguards monitoring their responses.
Promise and doubts
Johnson believes that today’s safety tools, such as content filters and reinforcement learning (training that rewards a chatbot for good answers), fall short. He compares them to “big, bouncy cushions” under a plane that soften a crash without preventing it. His formula would instead monitor for danger before the chatbot produces a harmful response.
Outside experts, however, urge caution. Wei Xing, an AI lecturer at the University of Sheffield who did not take part in the study, says the authors “reduce a huge system to a single tiny component, like explaining a whole car by studying one spark plug.” He adds that the team tested its formula on older, basic models, such as GPT-2, rather than the assistants people use today, and that the simplified model cannot account for safety training, a key defense in modern AI.
Johnson responds that the open-source models in the study share the same basic design as the most advanced systems. He also expects pushback from AI companies, since independent research might show that some problems could have been avoided. Until researchers test the formula on the latest models, it remains a promising idea rather than a ready-made safeguard, though it suggests that a chatbot’s behavior can change quickly.