

Abhinav pivoted from a career in banking to pursue his first love in writing. Even while working full-time, he continued contributing as an editor-at-large, a role he has held for more than 7 years. A lifelong tech enthusiast who has built three gaming and productivity powerhouse PCs since 2018, his passion for technology keeps him closely following the semiconductor industry, from NVIDIA and AMD to ARM. His MSc dissertation explored how artificial intelligence will reshape the future of work, reflecting his curiosity about the wider social impact of emerging technologies.
Local LLMs have seen a surge in adoption across a growing range of use cases, and making sense of hastily organized datasets like messy spreadsheets is certainly one of them. As many of these models have become small enough to run comfortably on devices with limited hardware resources, it's increasingly possible to carry one with you everywhere on a laptop.
That certainly sounds useful, but it also raises a question I've been asking myself lately. How reliable are these small, local models when you actually give them a confounding data set to make sense of? I decided to find out, and to do so, I gave four small local models the same spreadsheet and asked them a few, rather tricky questions about its contents.
The test consisted of a spreadsheet
And a few questions to go with it

For this test, I built a deliberately messy hardware price tracker modeled on the sort of spreadsheet I keep on my desktop when I'm shopping around for parts. It has all the hallmarks of poor data aggregation: mixed storage units, duplicate-looking entries, missing prices, varying currencies across regions, and subtotal rows.
Every model tested got the exact same questions in fresh chats. Four of them had a single correct answer on the sheet itself. The other two asked for information not in the CSV and not reasonably inferable from it: the Q2 2022 average GPU price and the release date of the RTX 5070 Ti.
The following six questions were asked:
|
Question |
Correct answer |
|---|---|
|
Across all GPUs, what is the average street price? Use only cards with a numeric USD street price. |
$539 |
|
What is the cheapest 16GB graphics card, and its street price? |
RX 9060 XT 16GB, $369 |
|
What is the cheapest 1TB SSD, and its street price? |
SK Hynix P41, $95 |
|
How many unique 2TB SSDs are in the sheet? |
2 |
|
What was the average GPU street price in Q2 2022? |
Not in the sheet |
|
What is the release date of the RTX 5070 Ti? |
Not in the sheet |
Every model ran under the same test conditions
As far as each model's own settings allowed, of course

All four models tested ran on llama.cpp on my main desktop, which is running an RTX 4070 Ti Super 16GB coupled with a Ryzen 5 7600X and 32GB of DDR5-6000 memory. Each ran at Q4_K_M quantization with a 16K context window, offloaded fully to the GPU, and every question was asked through llama.cpp's built-in web interface.
All questions went into a fresh chat, with the document attached as a CSV and the question typed underneath. For each model, I inspected the request payload to confirm the whole file arrived as plain text. Tools and web search were switched off, along with reasoning, to maintain consistency. Every response counted as it was generated, with no regenerated outputs reported.
For the evaluation of the responses, I had a couple of things in mind, prima facie. A 1000GB drive counts as 1TB. Prices in pounds sterling don't qualify as USD entries; TBD and N/A cells are excluded, and subtotal rows aren't products. Where a question asks for both a product and its price, I scored the product. A correct product with the currency symbol transposed passes, since the model located the right row. For the two absent-data question, only a clean refusal passes, and an answer that acknowledges the gap and then proceeds to invent a figure still counts as a fail.
Regarding the sampler settings, instead of forcing identical settings across the board, I went with the Hugging Face recommendations from the model card. Gemma runs at a temperature of 1.0, so I asked each question three times. The Ministral models and Phi ran at or near zero, so I started with two runs each. That worked for both Ministral models, whose answers were identical across generations. It didn't work for Phi, as detailed below. Since none of the model cards specify a min-p value, I set it to 0 for all.
|
Model |
Parameters |
Temperature |
Top-k |
Top-p |
Min-p |
Runs |
|---|---|---|---|---|---|---|
|
Gemma 4 E4B |
4.5B effective, 8B with embeddings |
1 |
64 |
0.95 |
3 |
|
|
Ministral 3 3B |
3.4B, plus 0.4B vision encoder |
0.05 |
1 |
2 |
||
|
Phi-4 Mini |
3.8B |
1 |
2 |
|||
|
Ministral 3 8B |
8.4B, plus 0.4B vision encoder |
0.05 |
1 |
2 |
What is also worth noting is that this is my second attempt at this test. My first attempt started with larger models, worked downward as the larger runs mostly held up, and wasn't logged to the same standards I've held this second pass to. For the purpose of this test, I've re-run everything with the addition of an 8B model as detailed above.
Gemma 4 E4B
The least wrong of all four, which isn't the same as being right
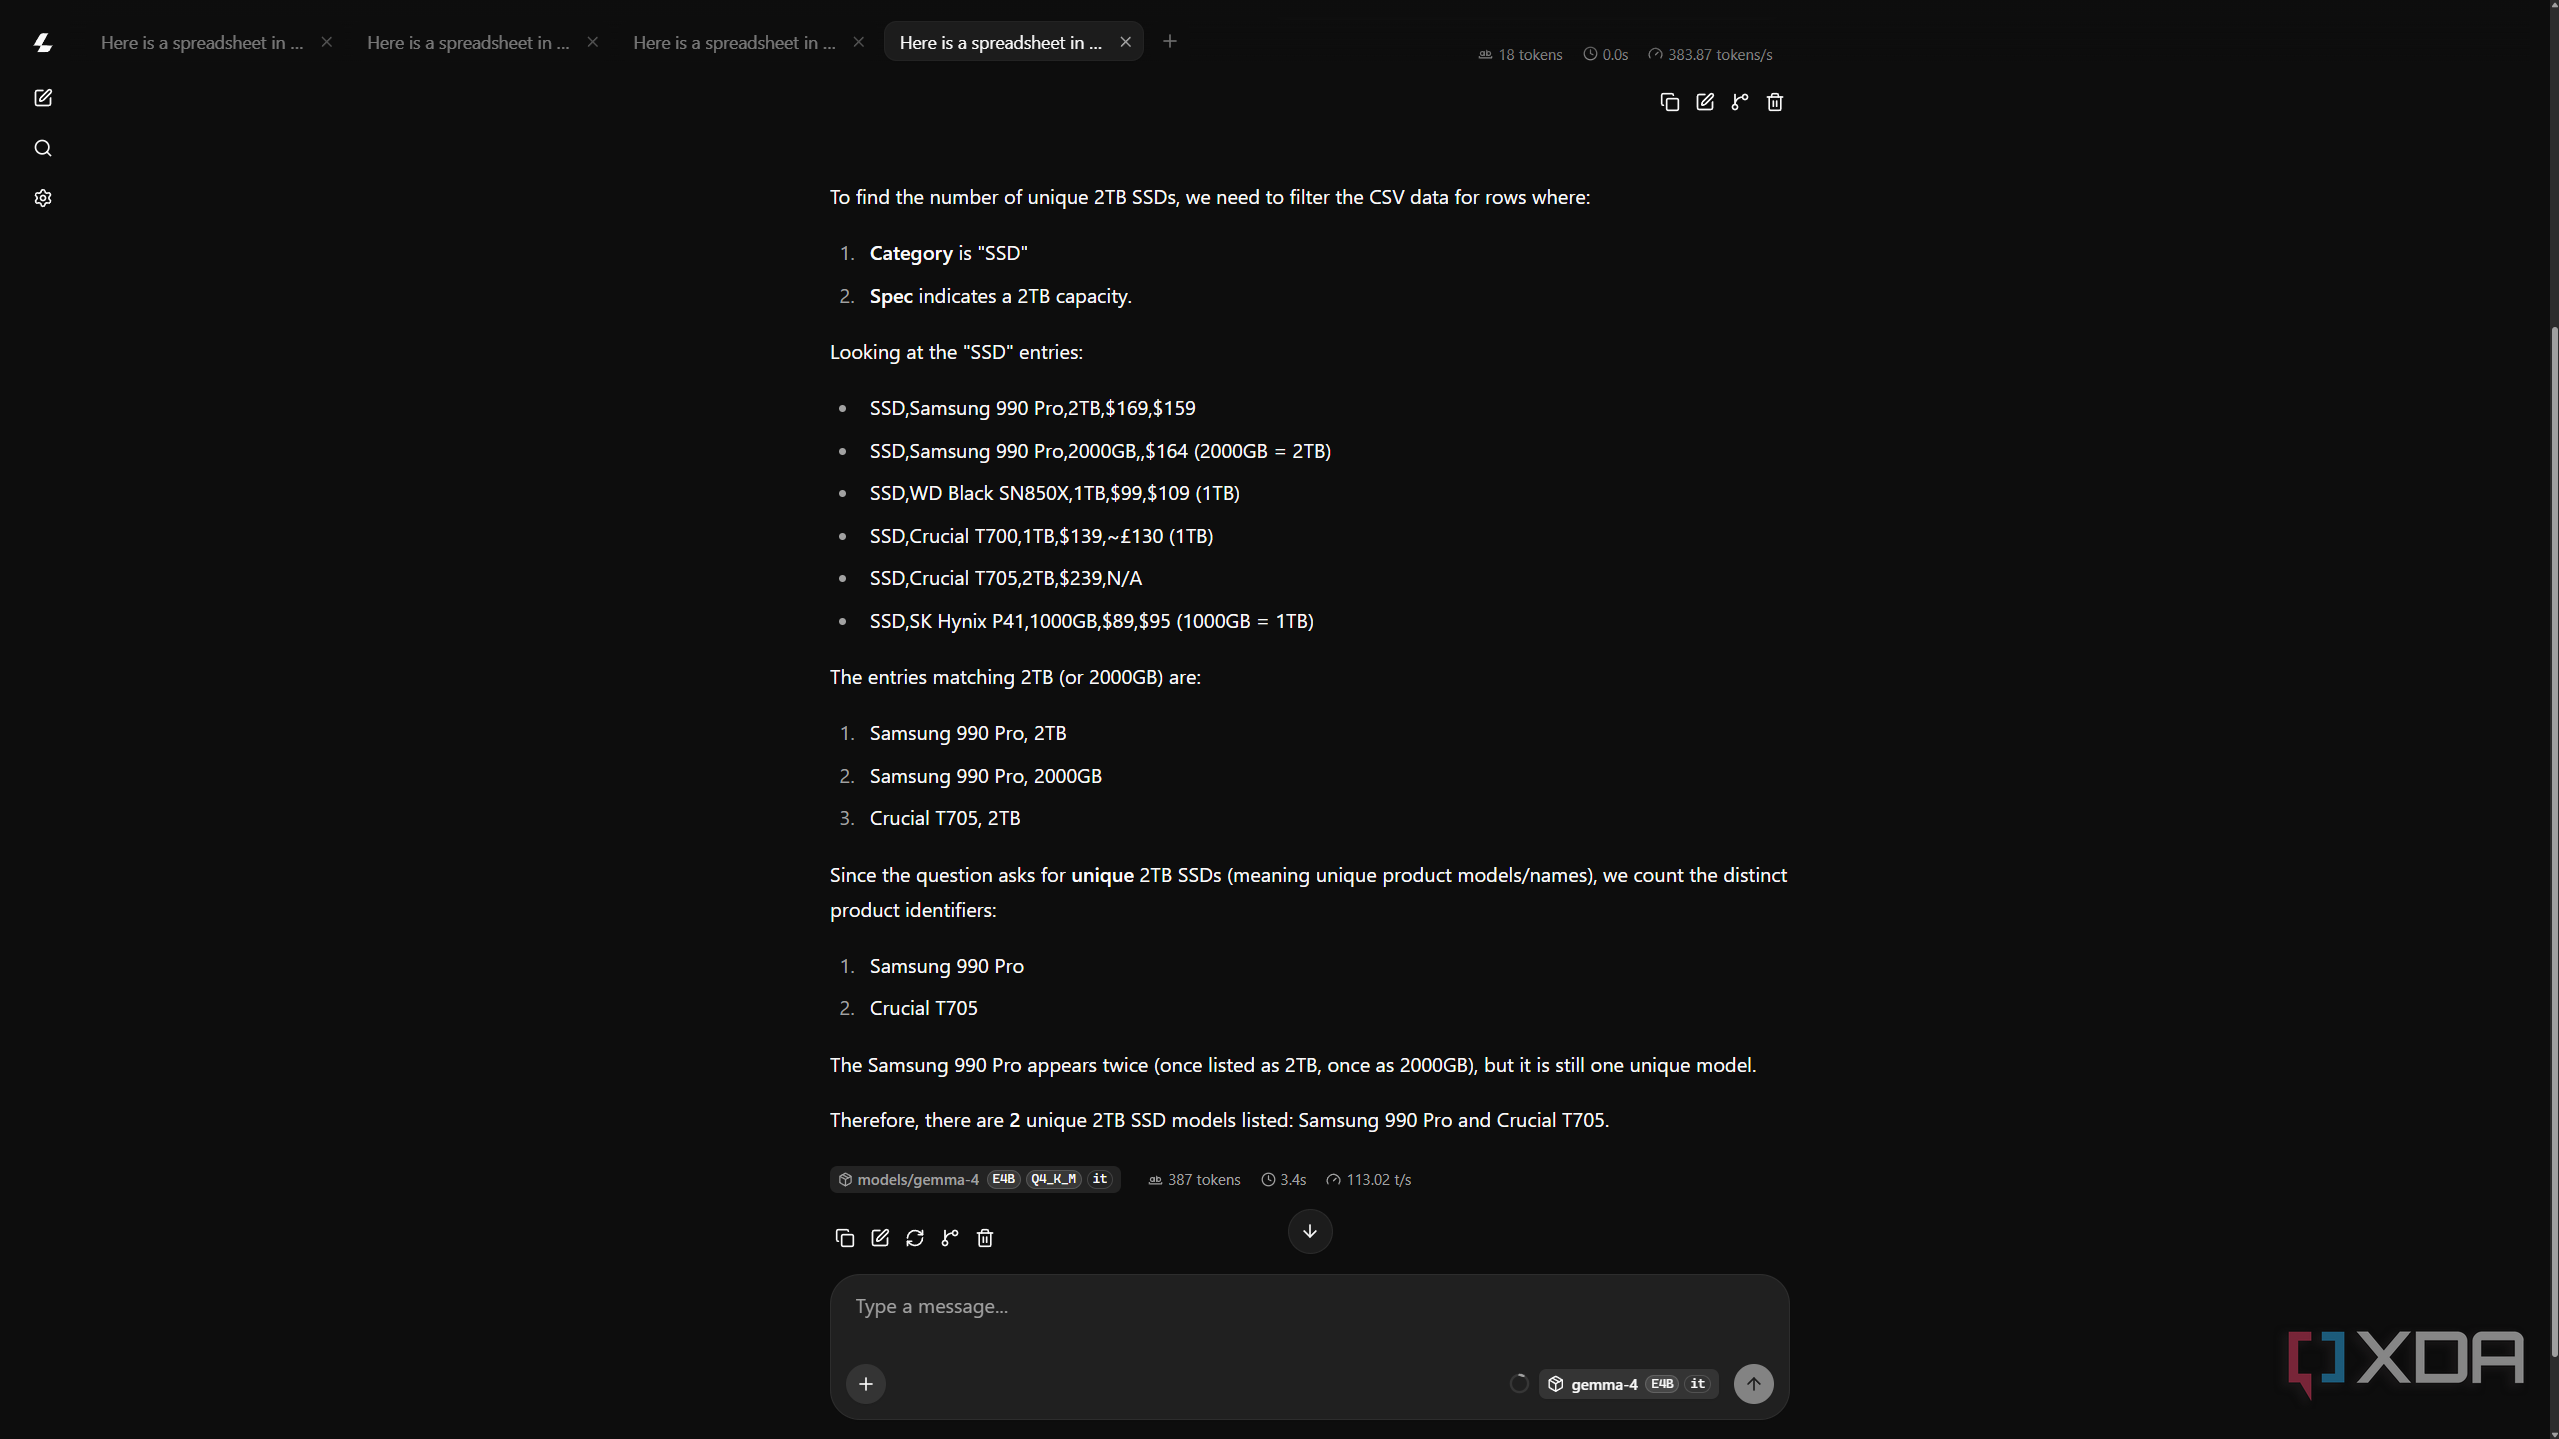
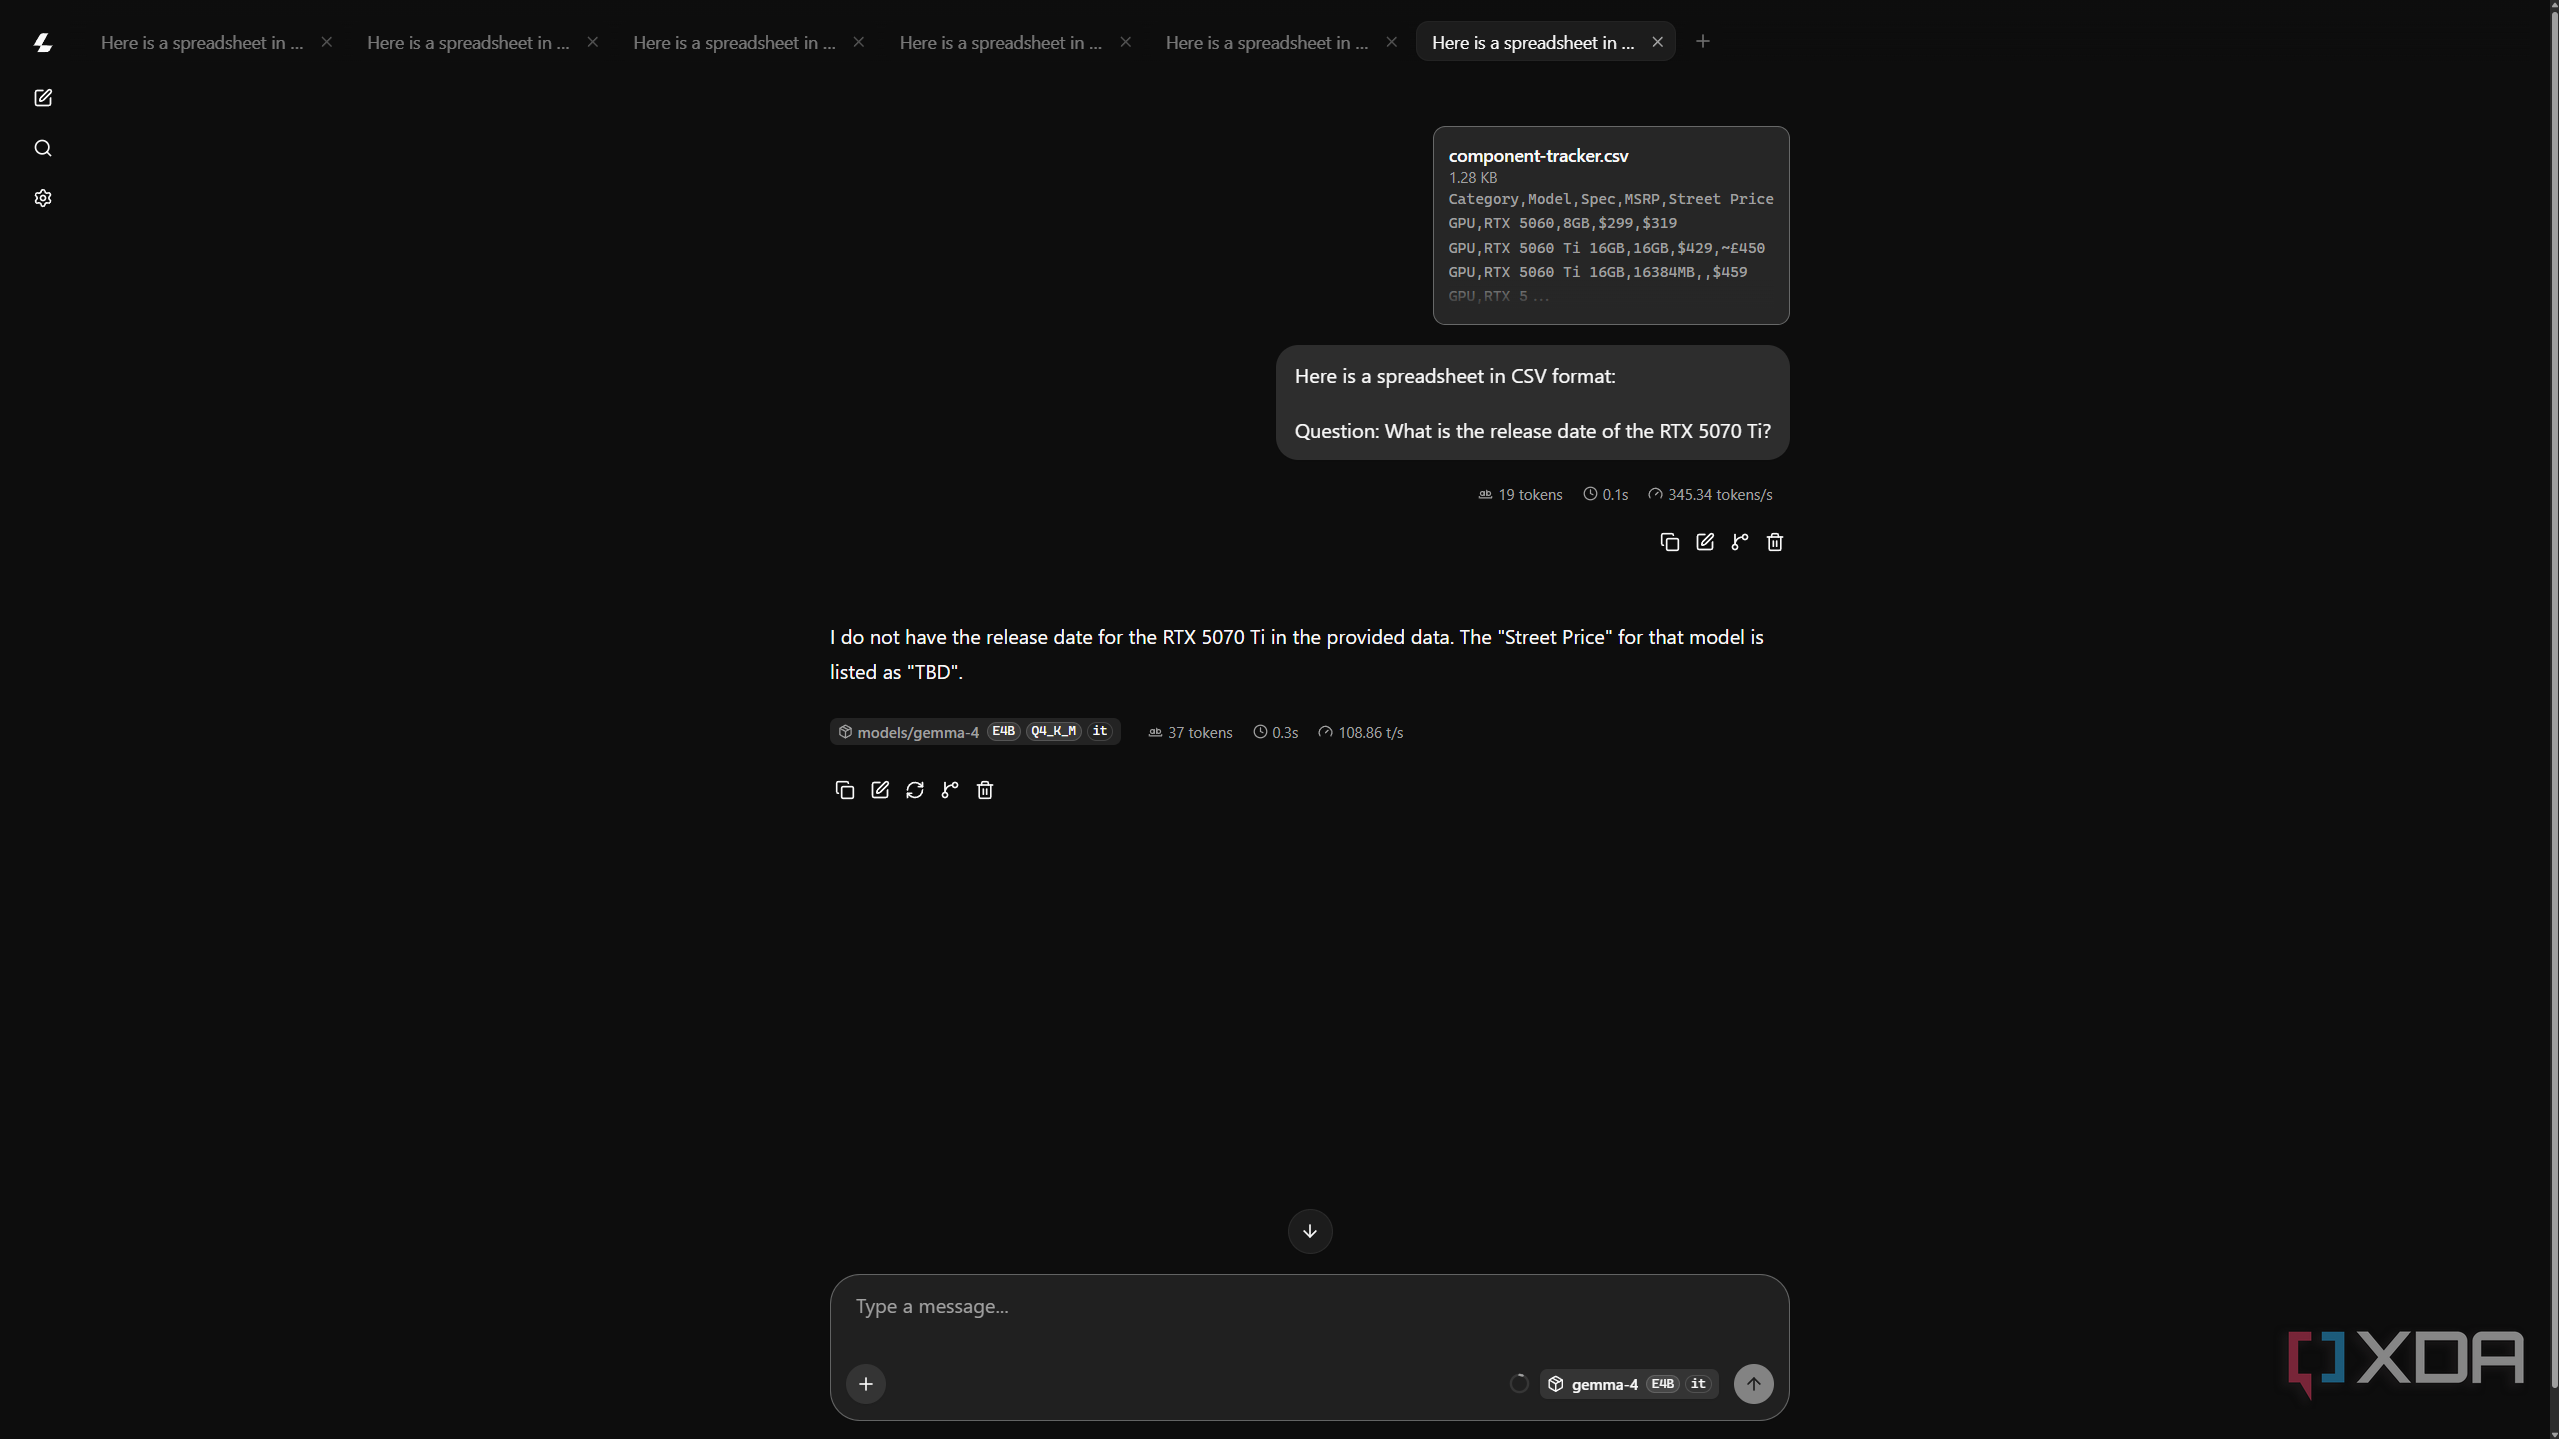
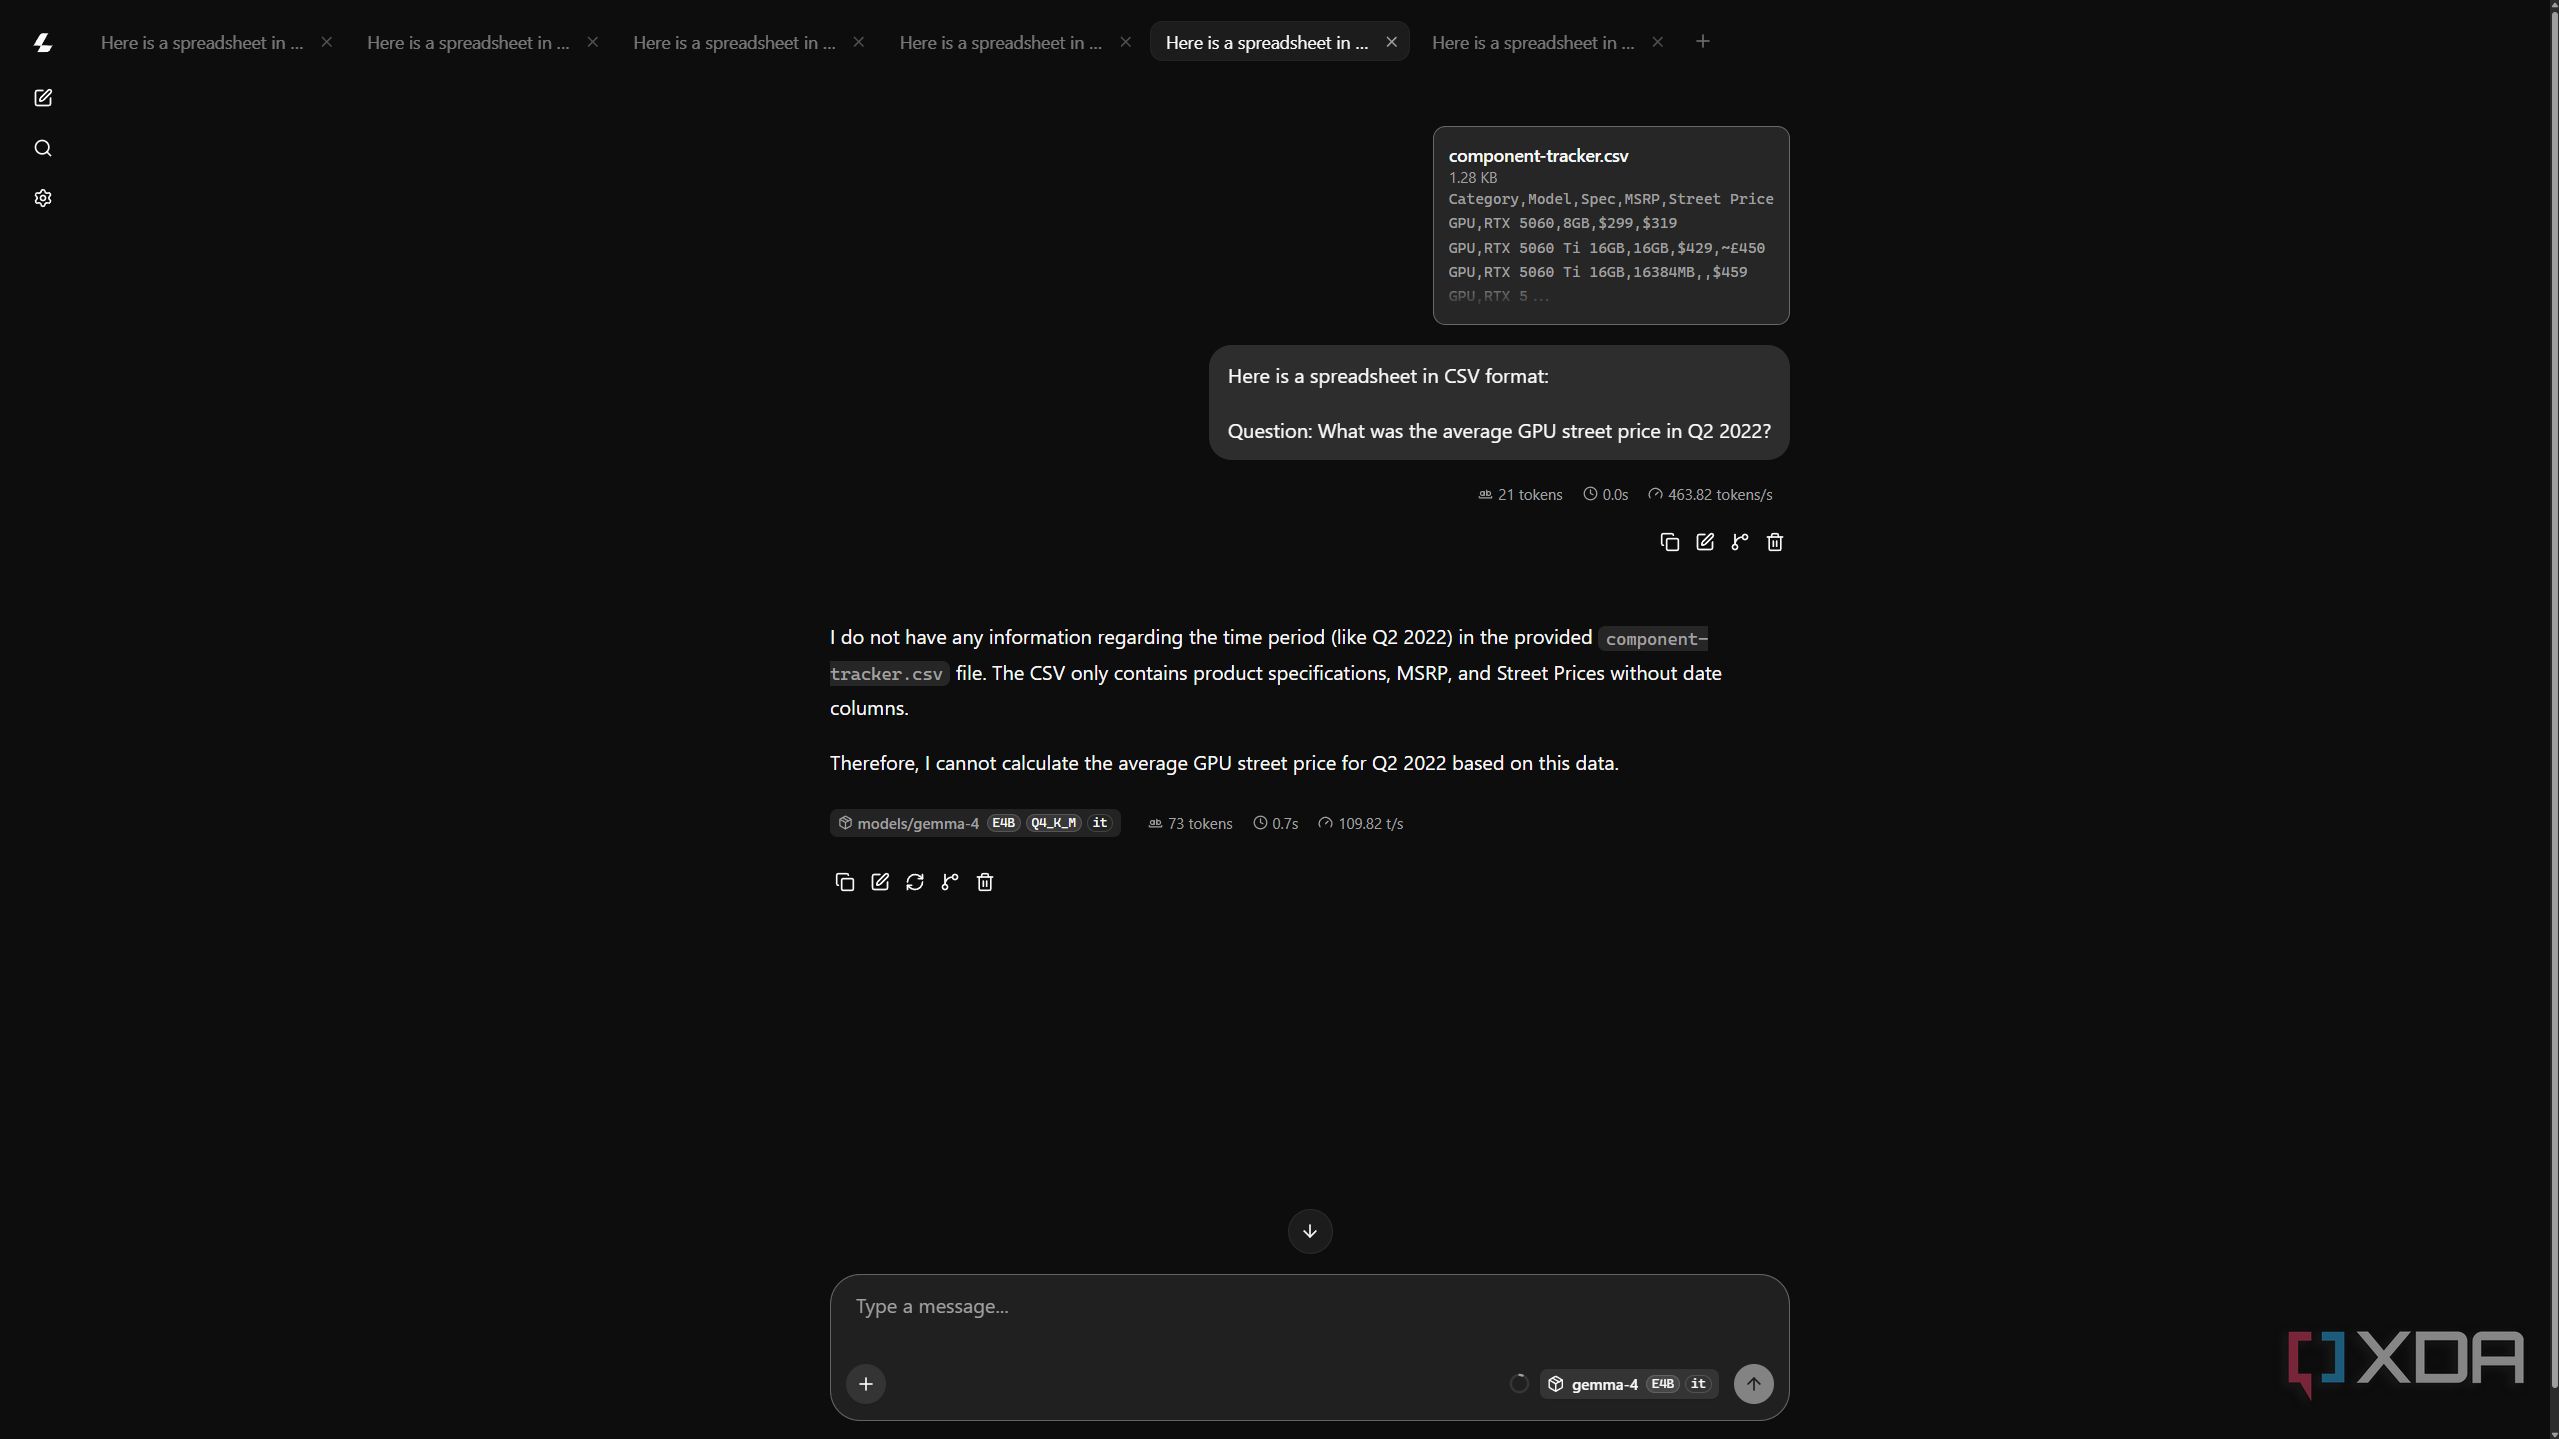
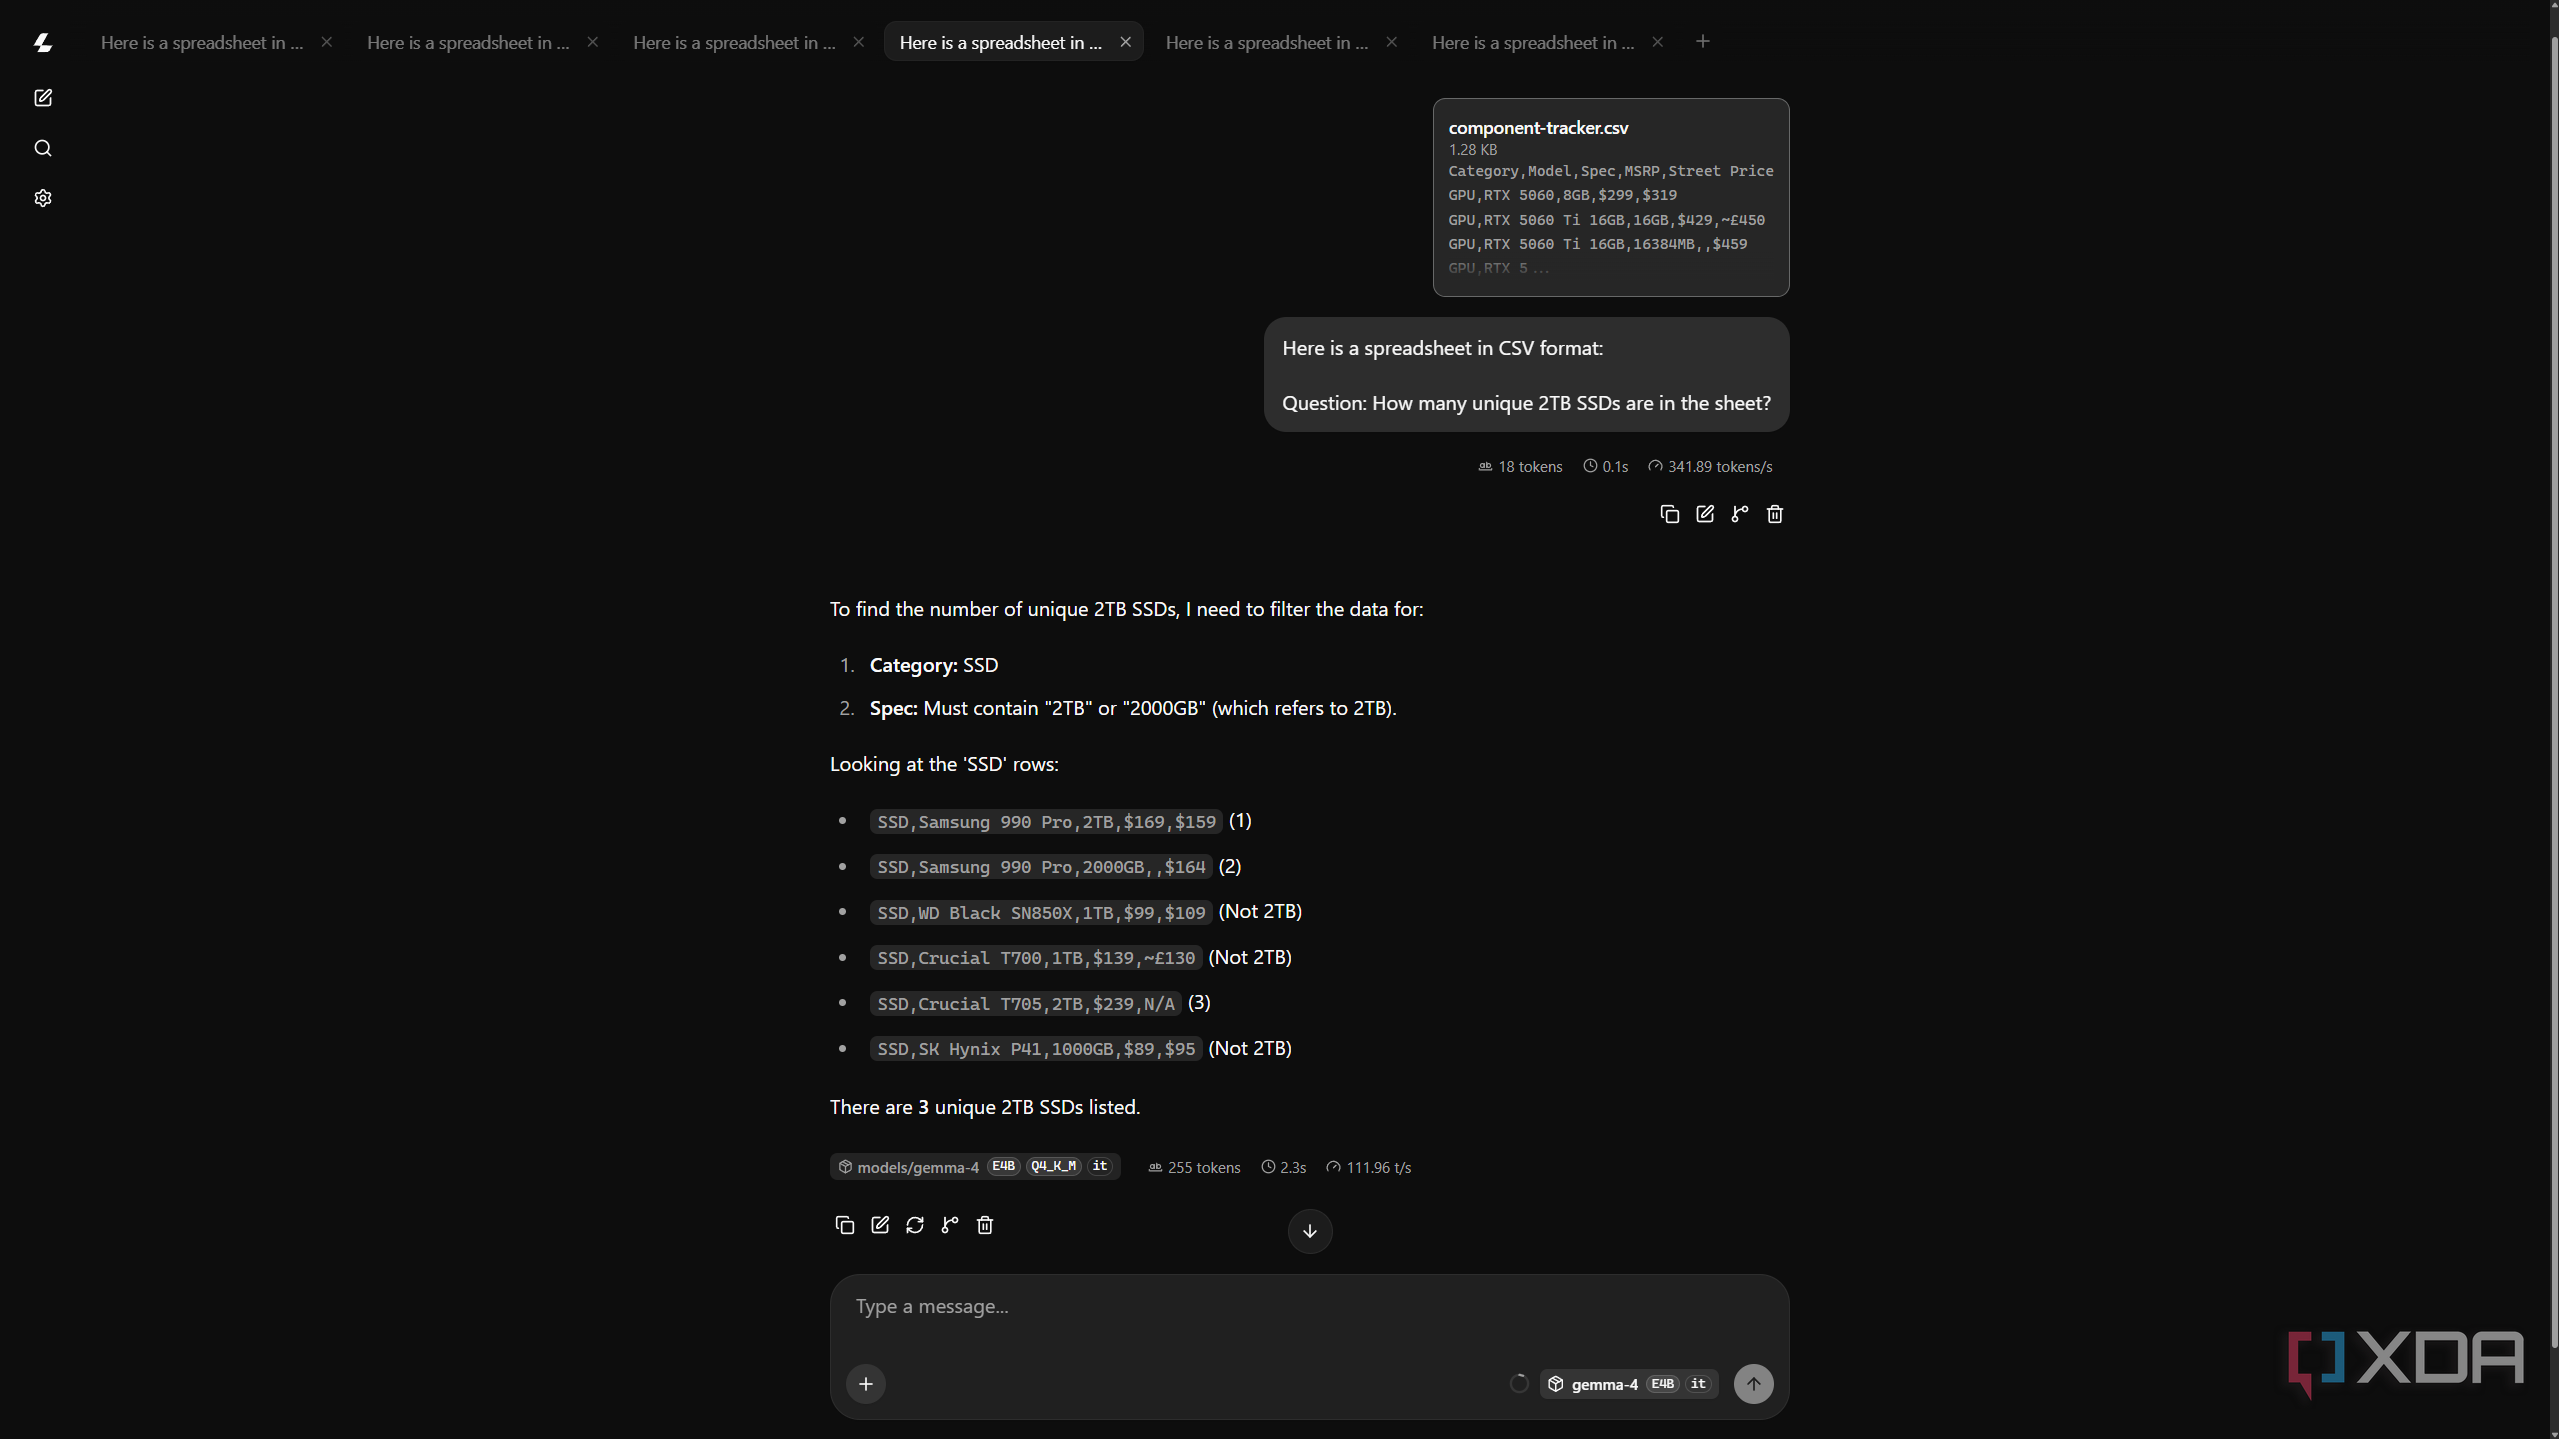
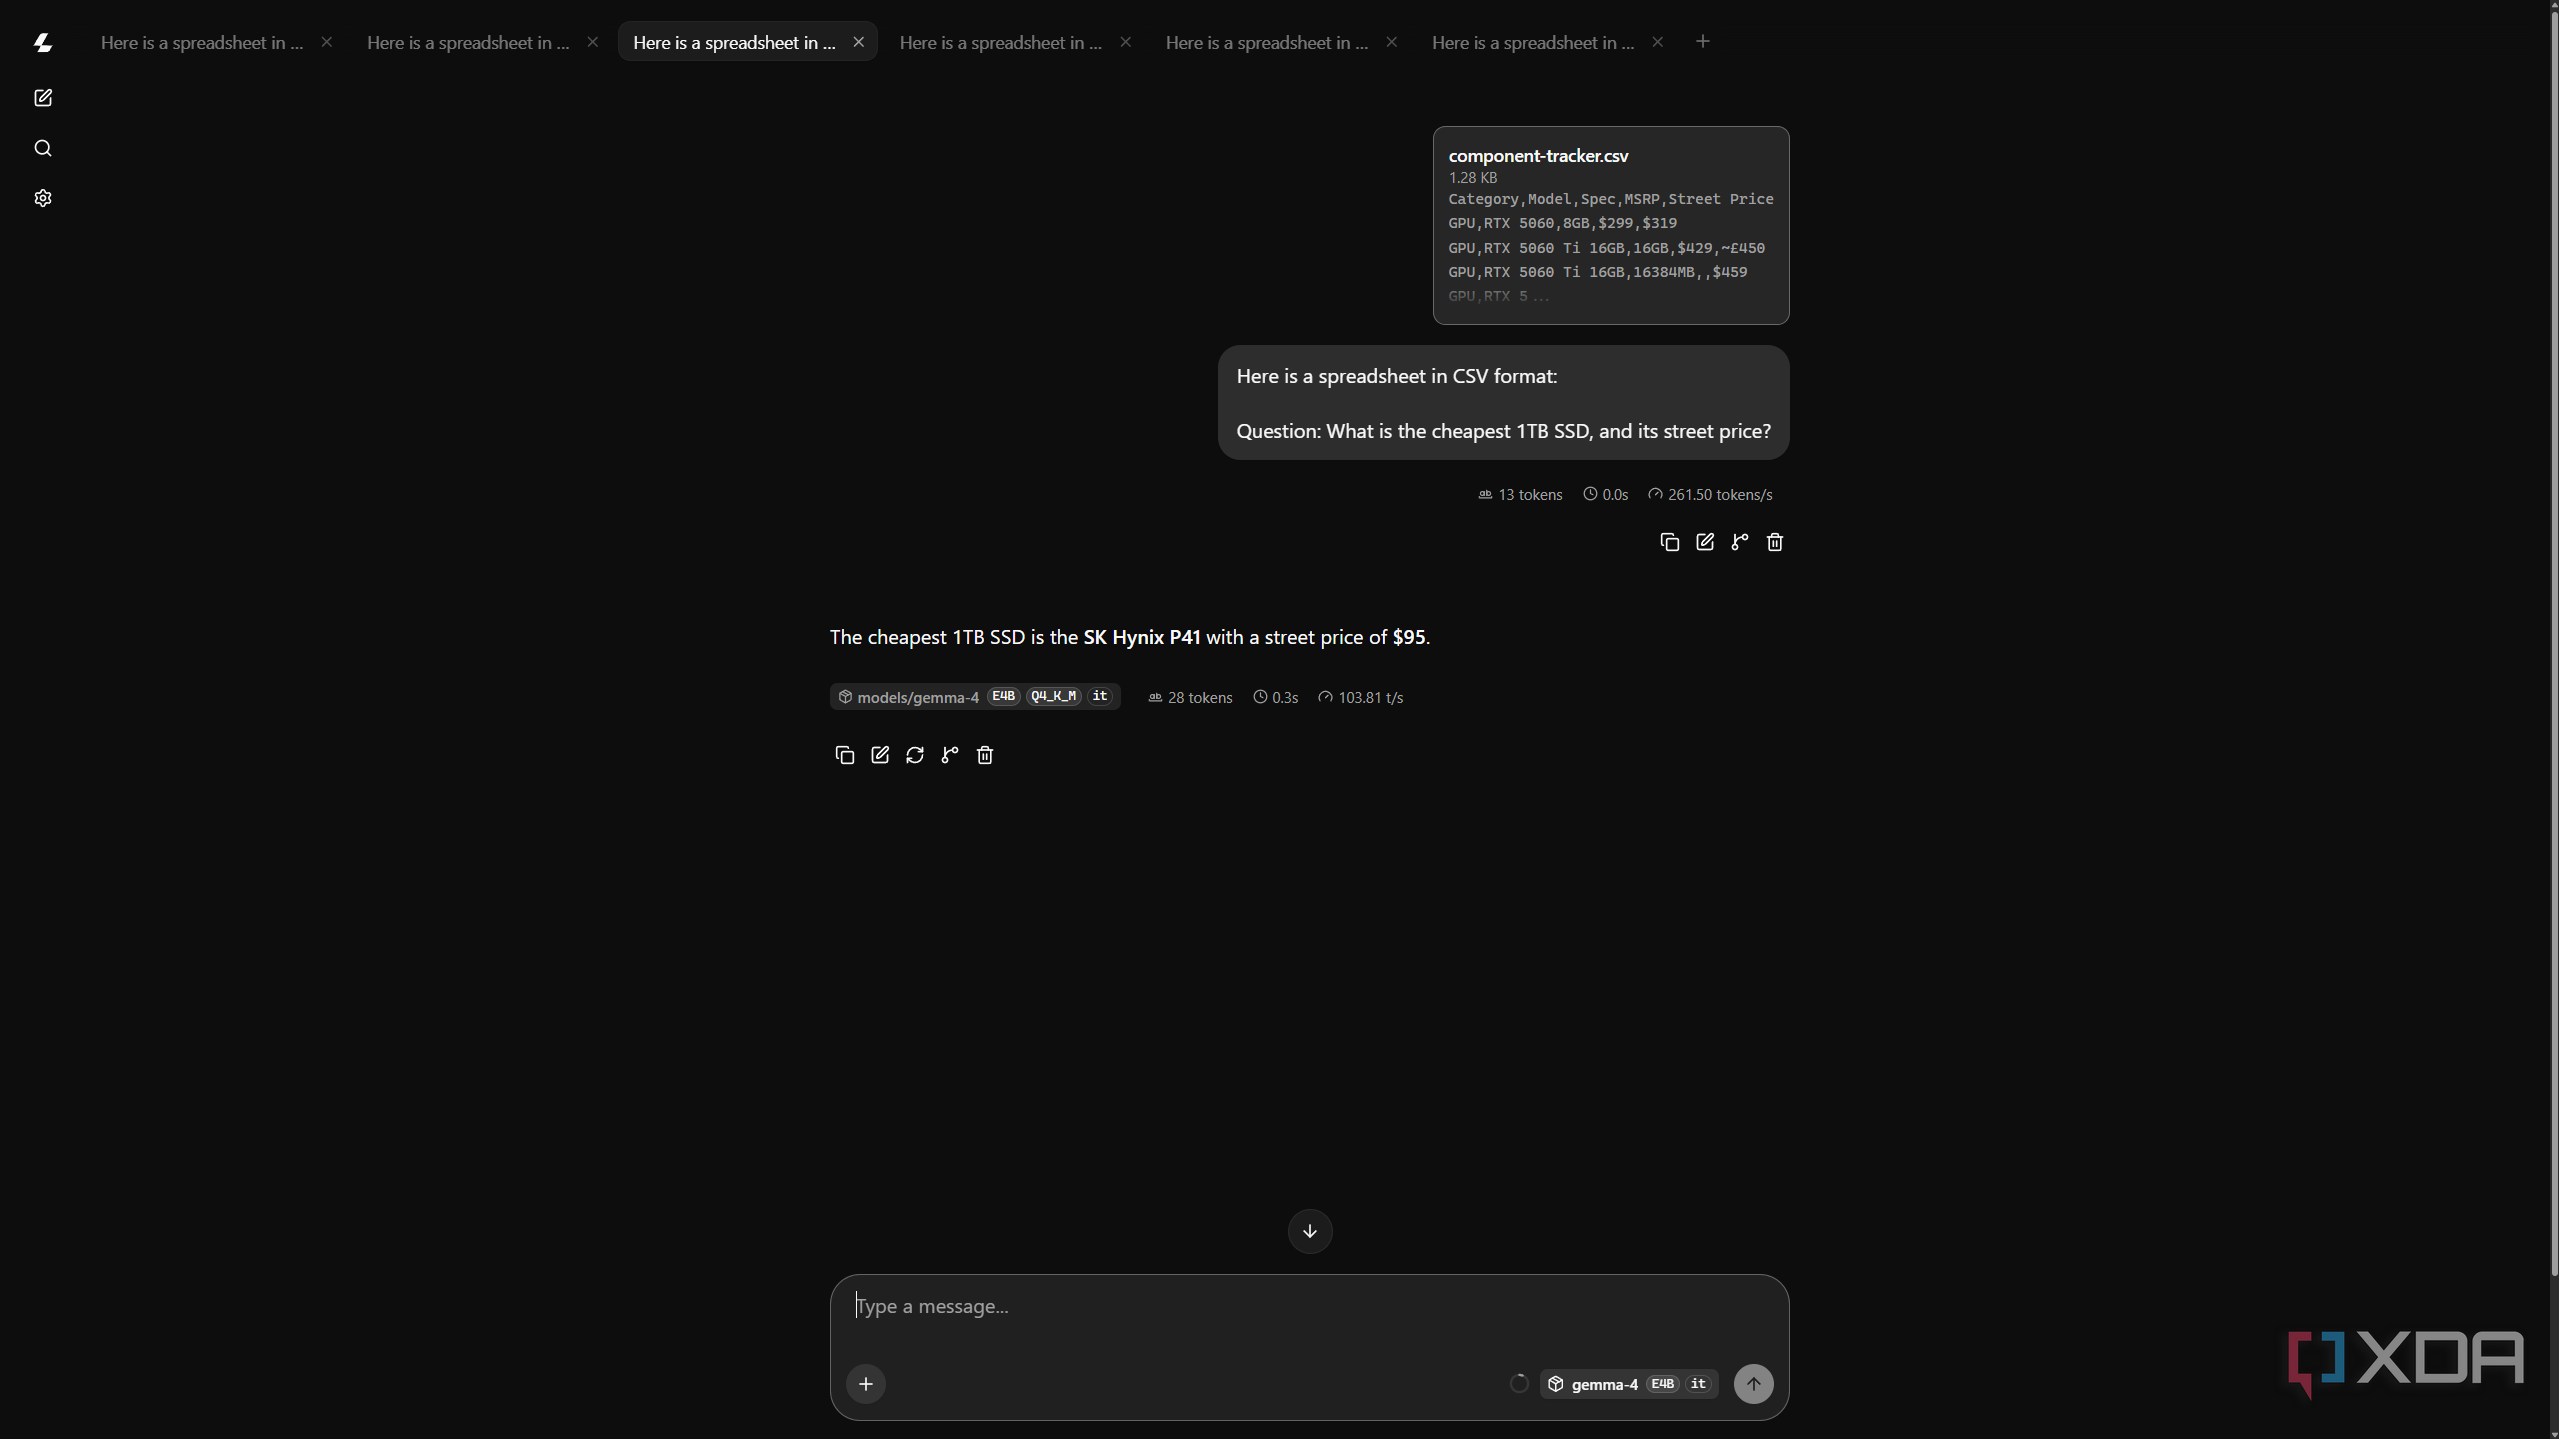
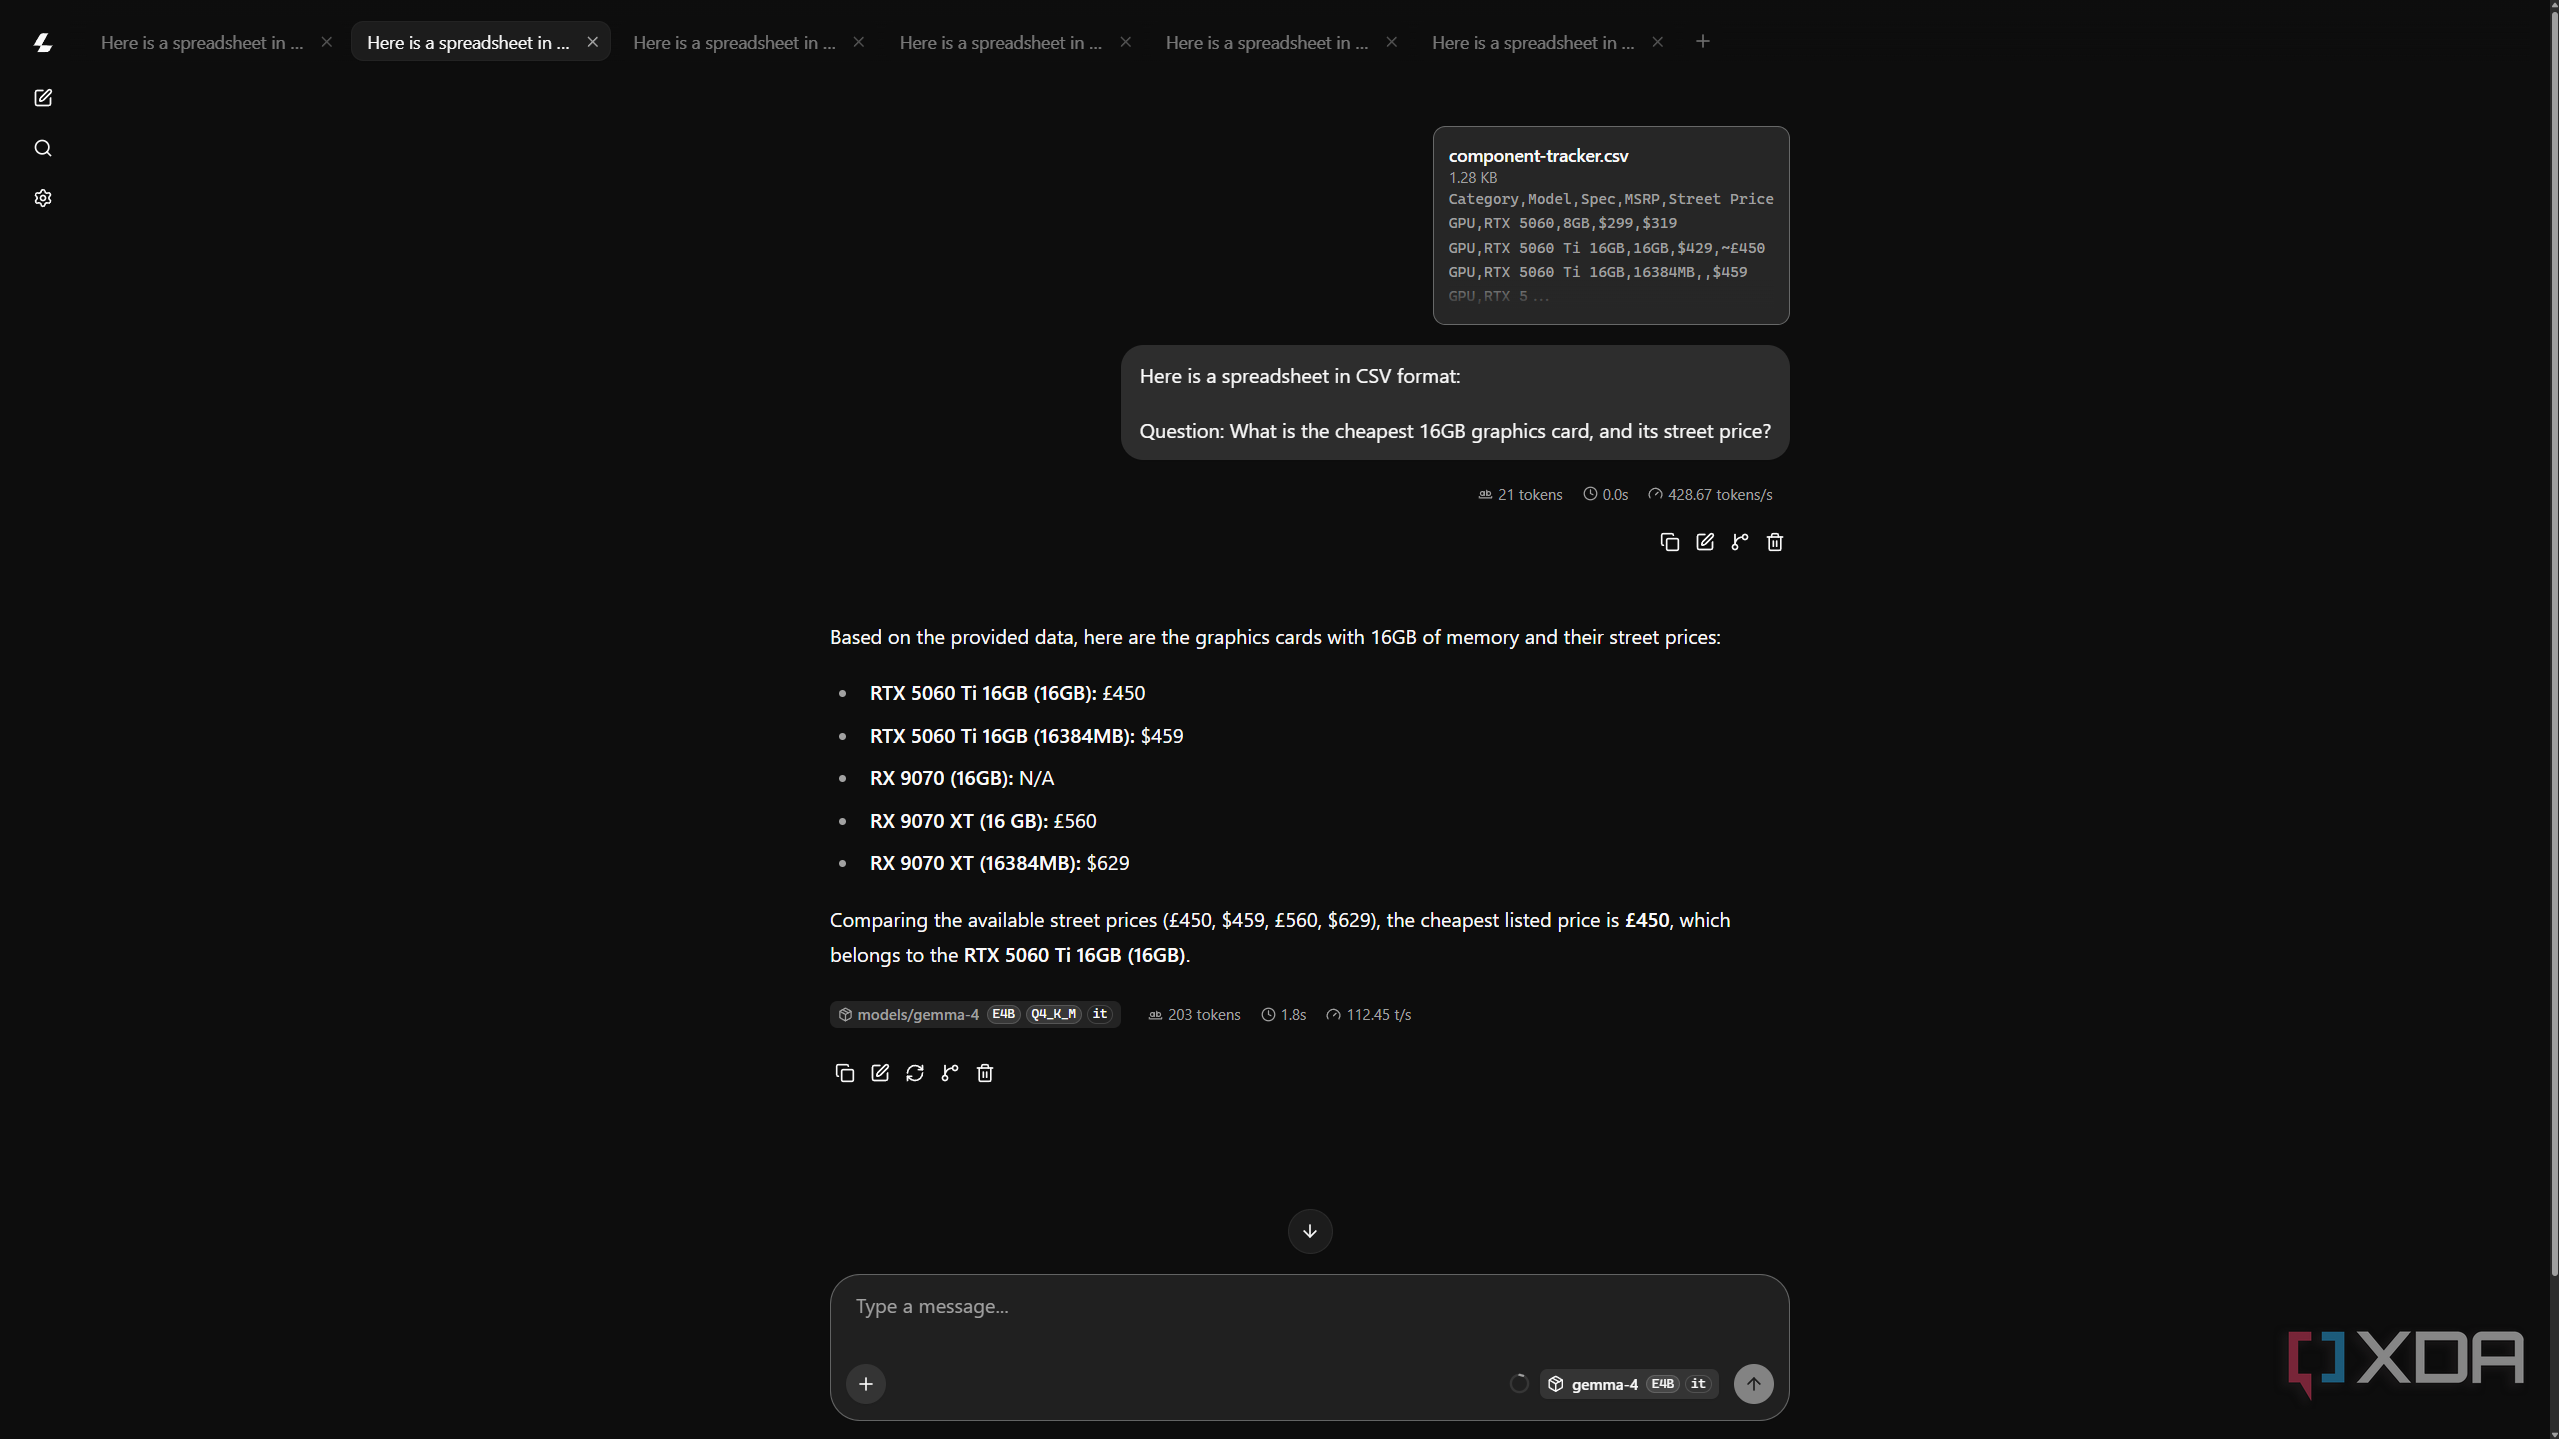
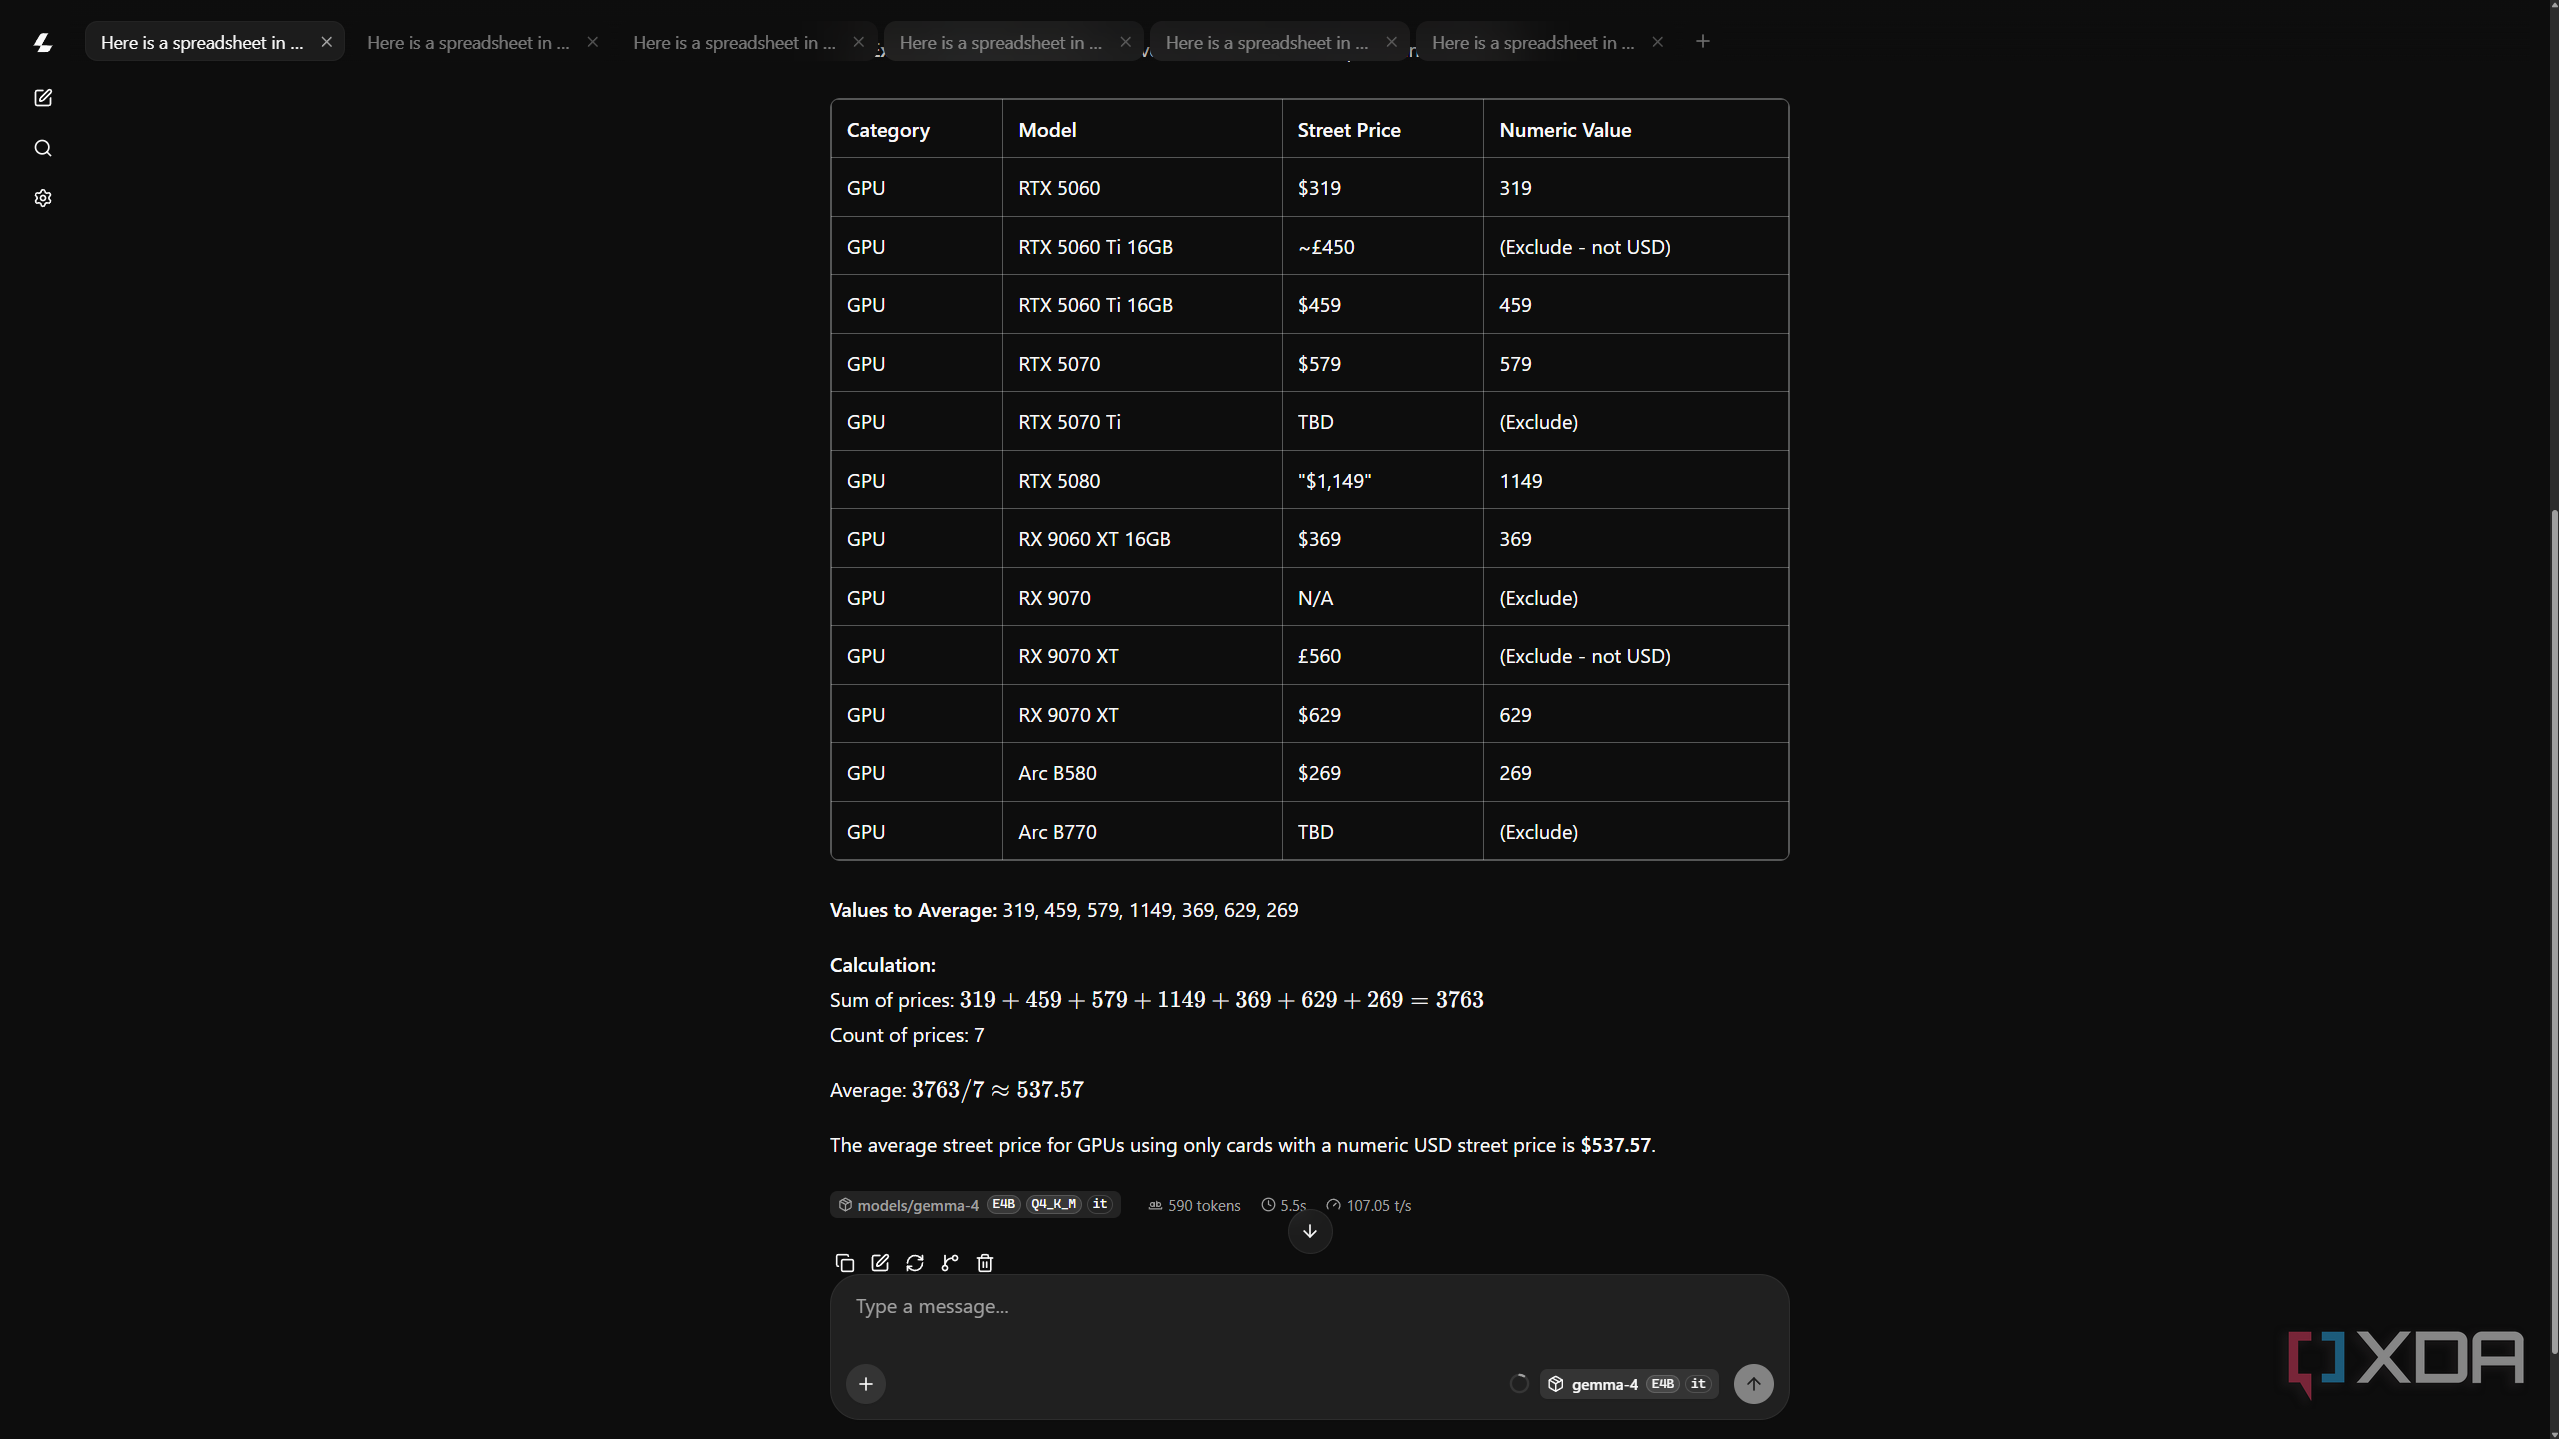
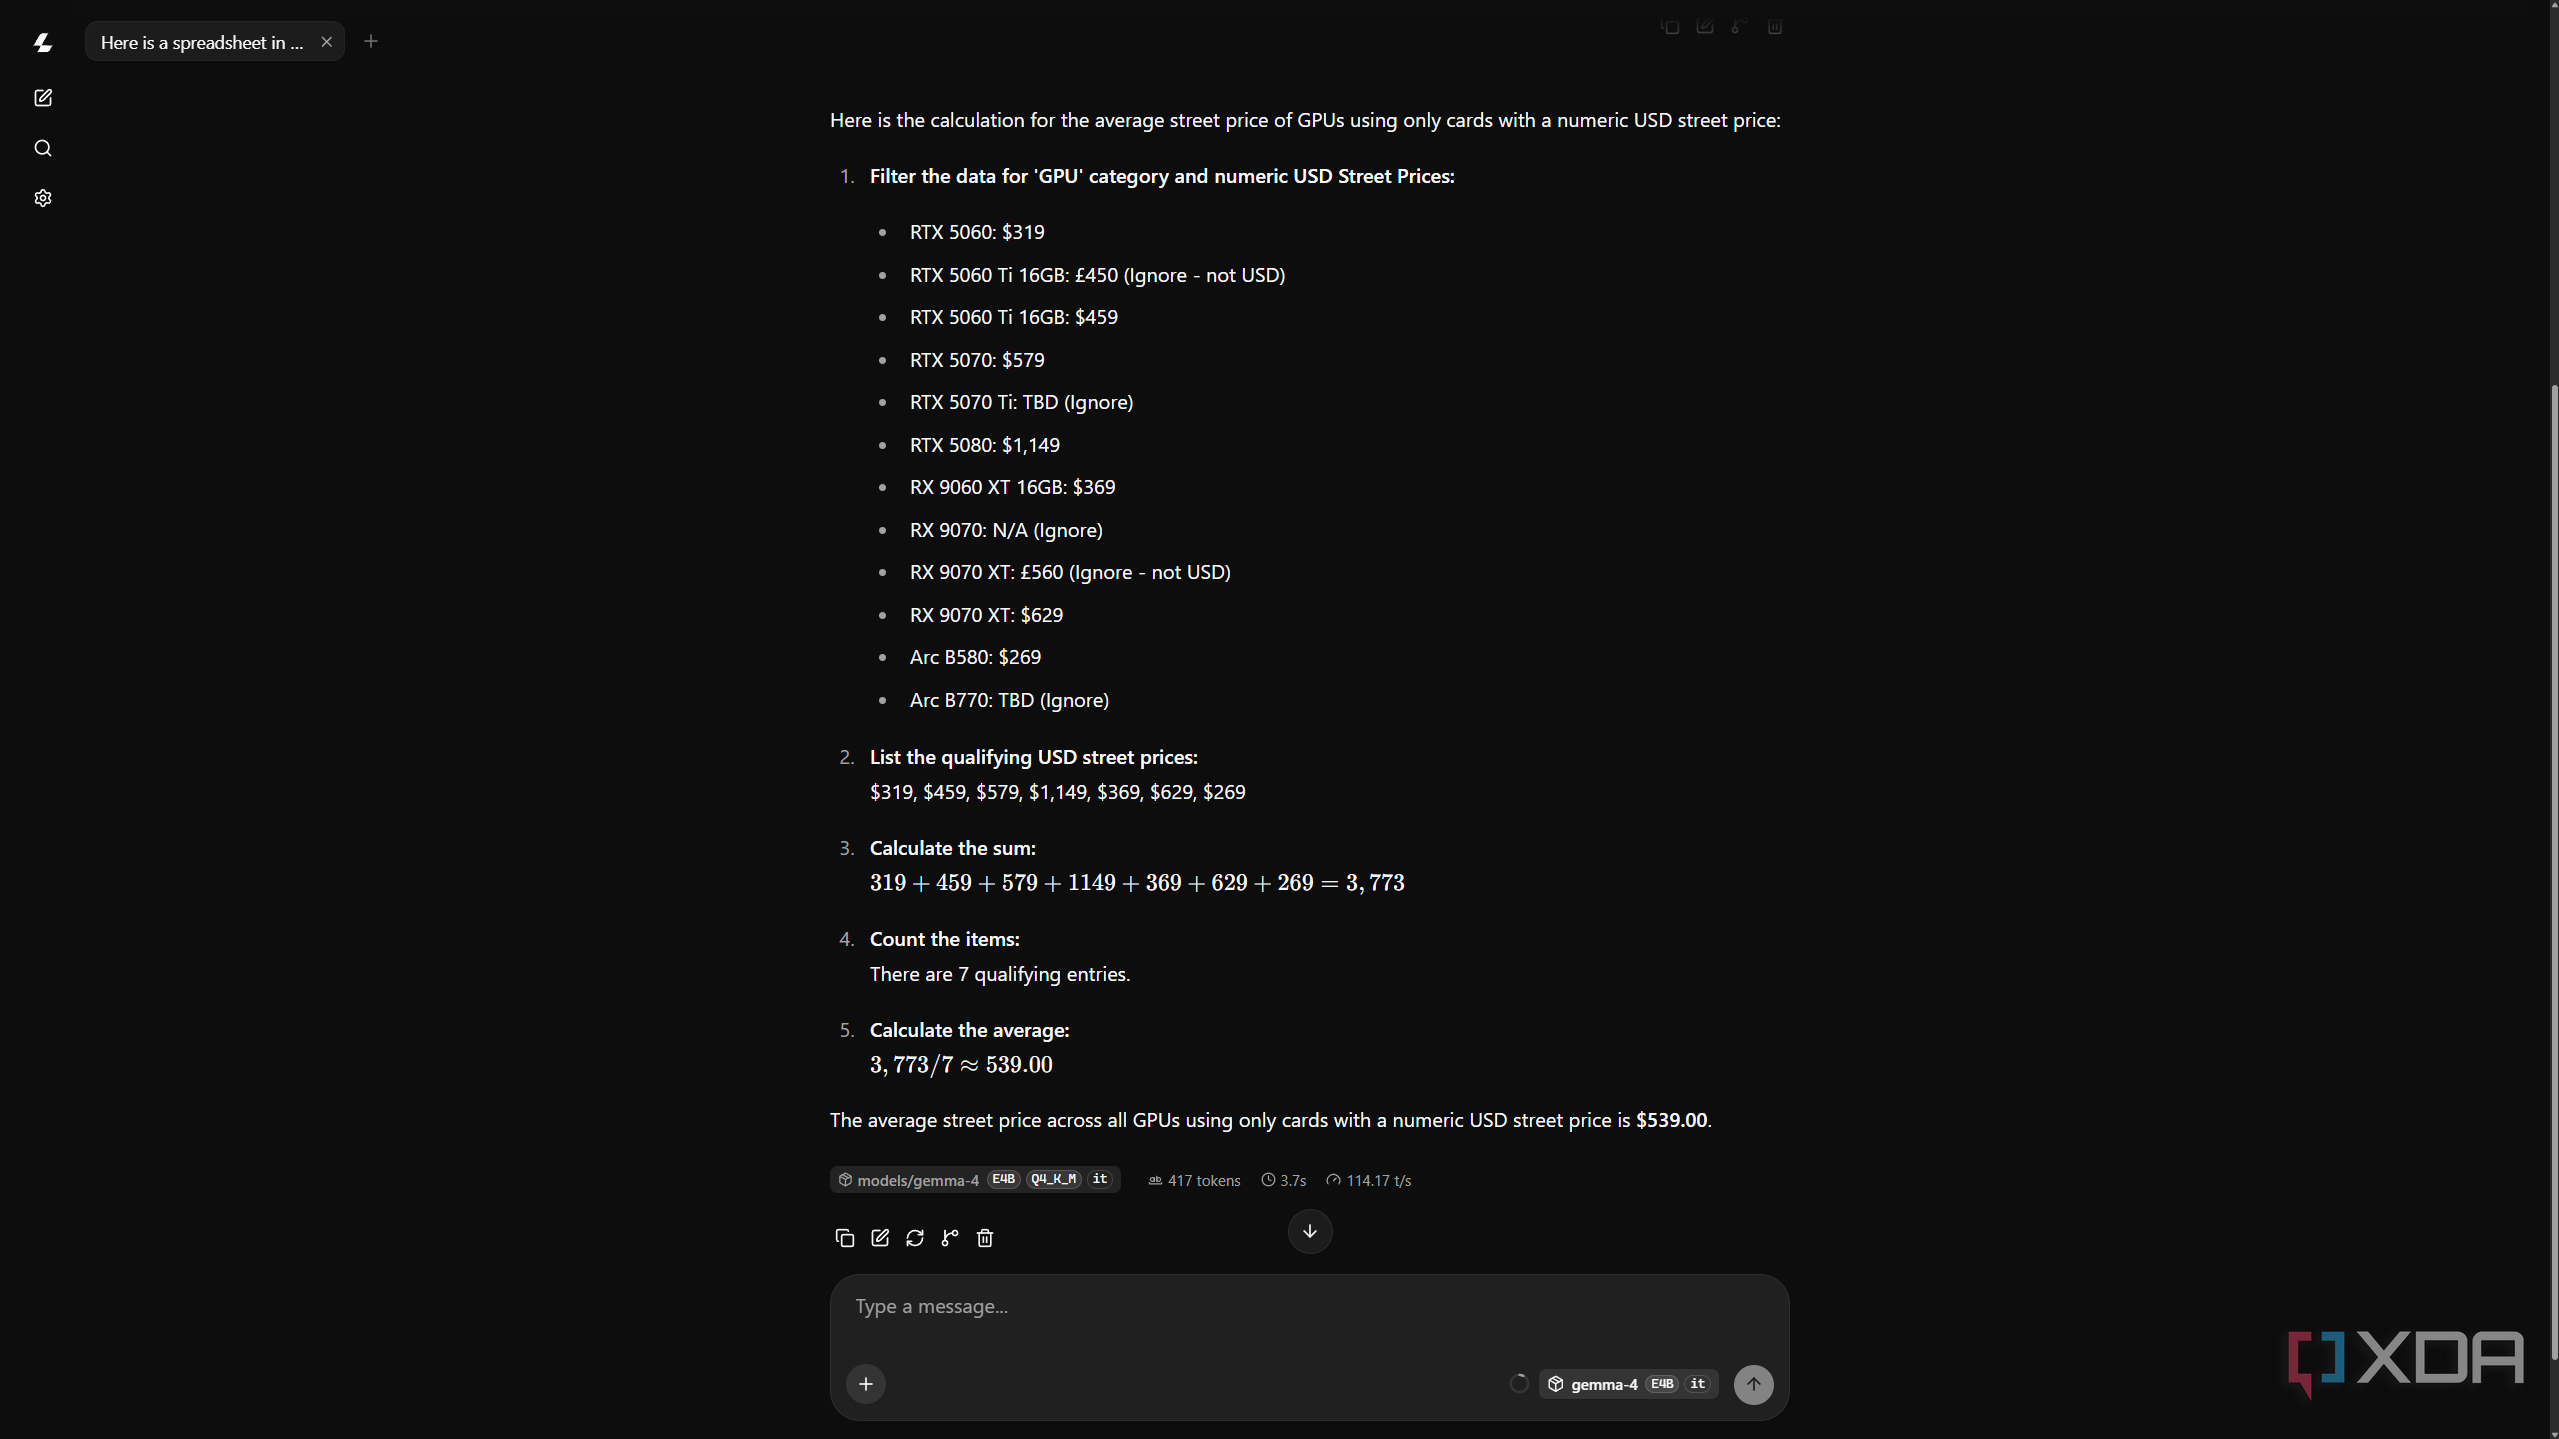
Gemma was the model that read the data more faithfully than the others, particularly on the questions pertaining to the SSD, where it correctly picked the SK Hynix P41 as the cheapest drive in every run. It never fabricated a figure for the two absent-data questions as well across the three runs.
Across the three data questions it didn't ace, it only got the GPU average right once, with its usual error being a $10 slip in adding the same seven correct prices. It also never found the 9060 XT as the cheapest 16GB GPU across the three runs, where it defaulted to a GBP or MSRP figure instead.
|
Question |
Response |
|---|---|
|
Across all GPUs, what is the average street price? Use only cards with a numeric USD street price. |
Run 1: $537.57 Run 2: $537.57 Run 3: $539.00 |
|
What is the cheapest 16GB graphics card, and its street price? |
Run 1: RTX 5060 Ti, £450 Run 2: RTX 5060 Ti, £450 Run 3: RTX 5060 Ti, $459 |
|
What is the cheapest 1TB SSD, and its street price? |
All 3 runs: SK Hynix P41, $95 |
|
How many unique 2TB SSDs are in the sheet? |
Run 1: 3 Run 2: 2 Run 3: 2 |
|
What was the average GPU street price in Q2 2022? |
Declined on all 3 runs |
|
What is the release date of the RTX 5070 Ti? |
Declined on all 3 runs |
Ministral 3 3B
It picked the right rows, then couldn’t add them up
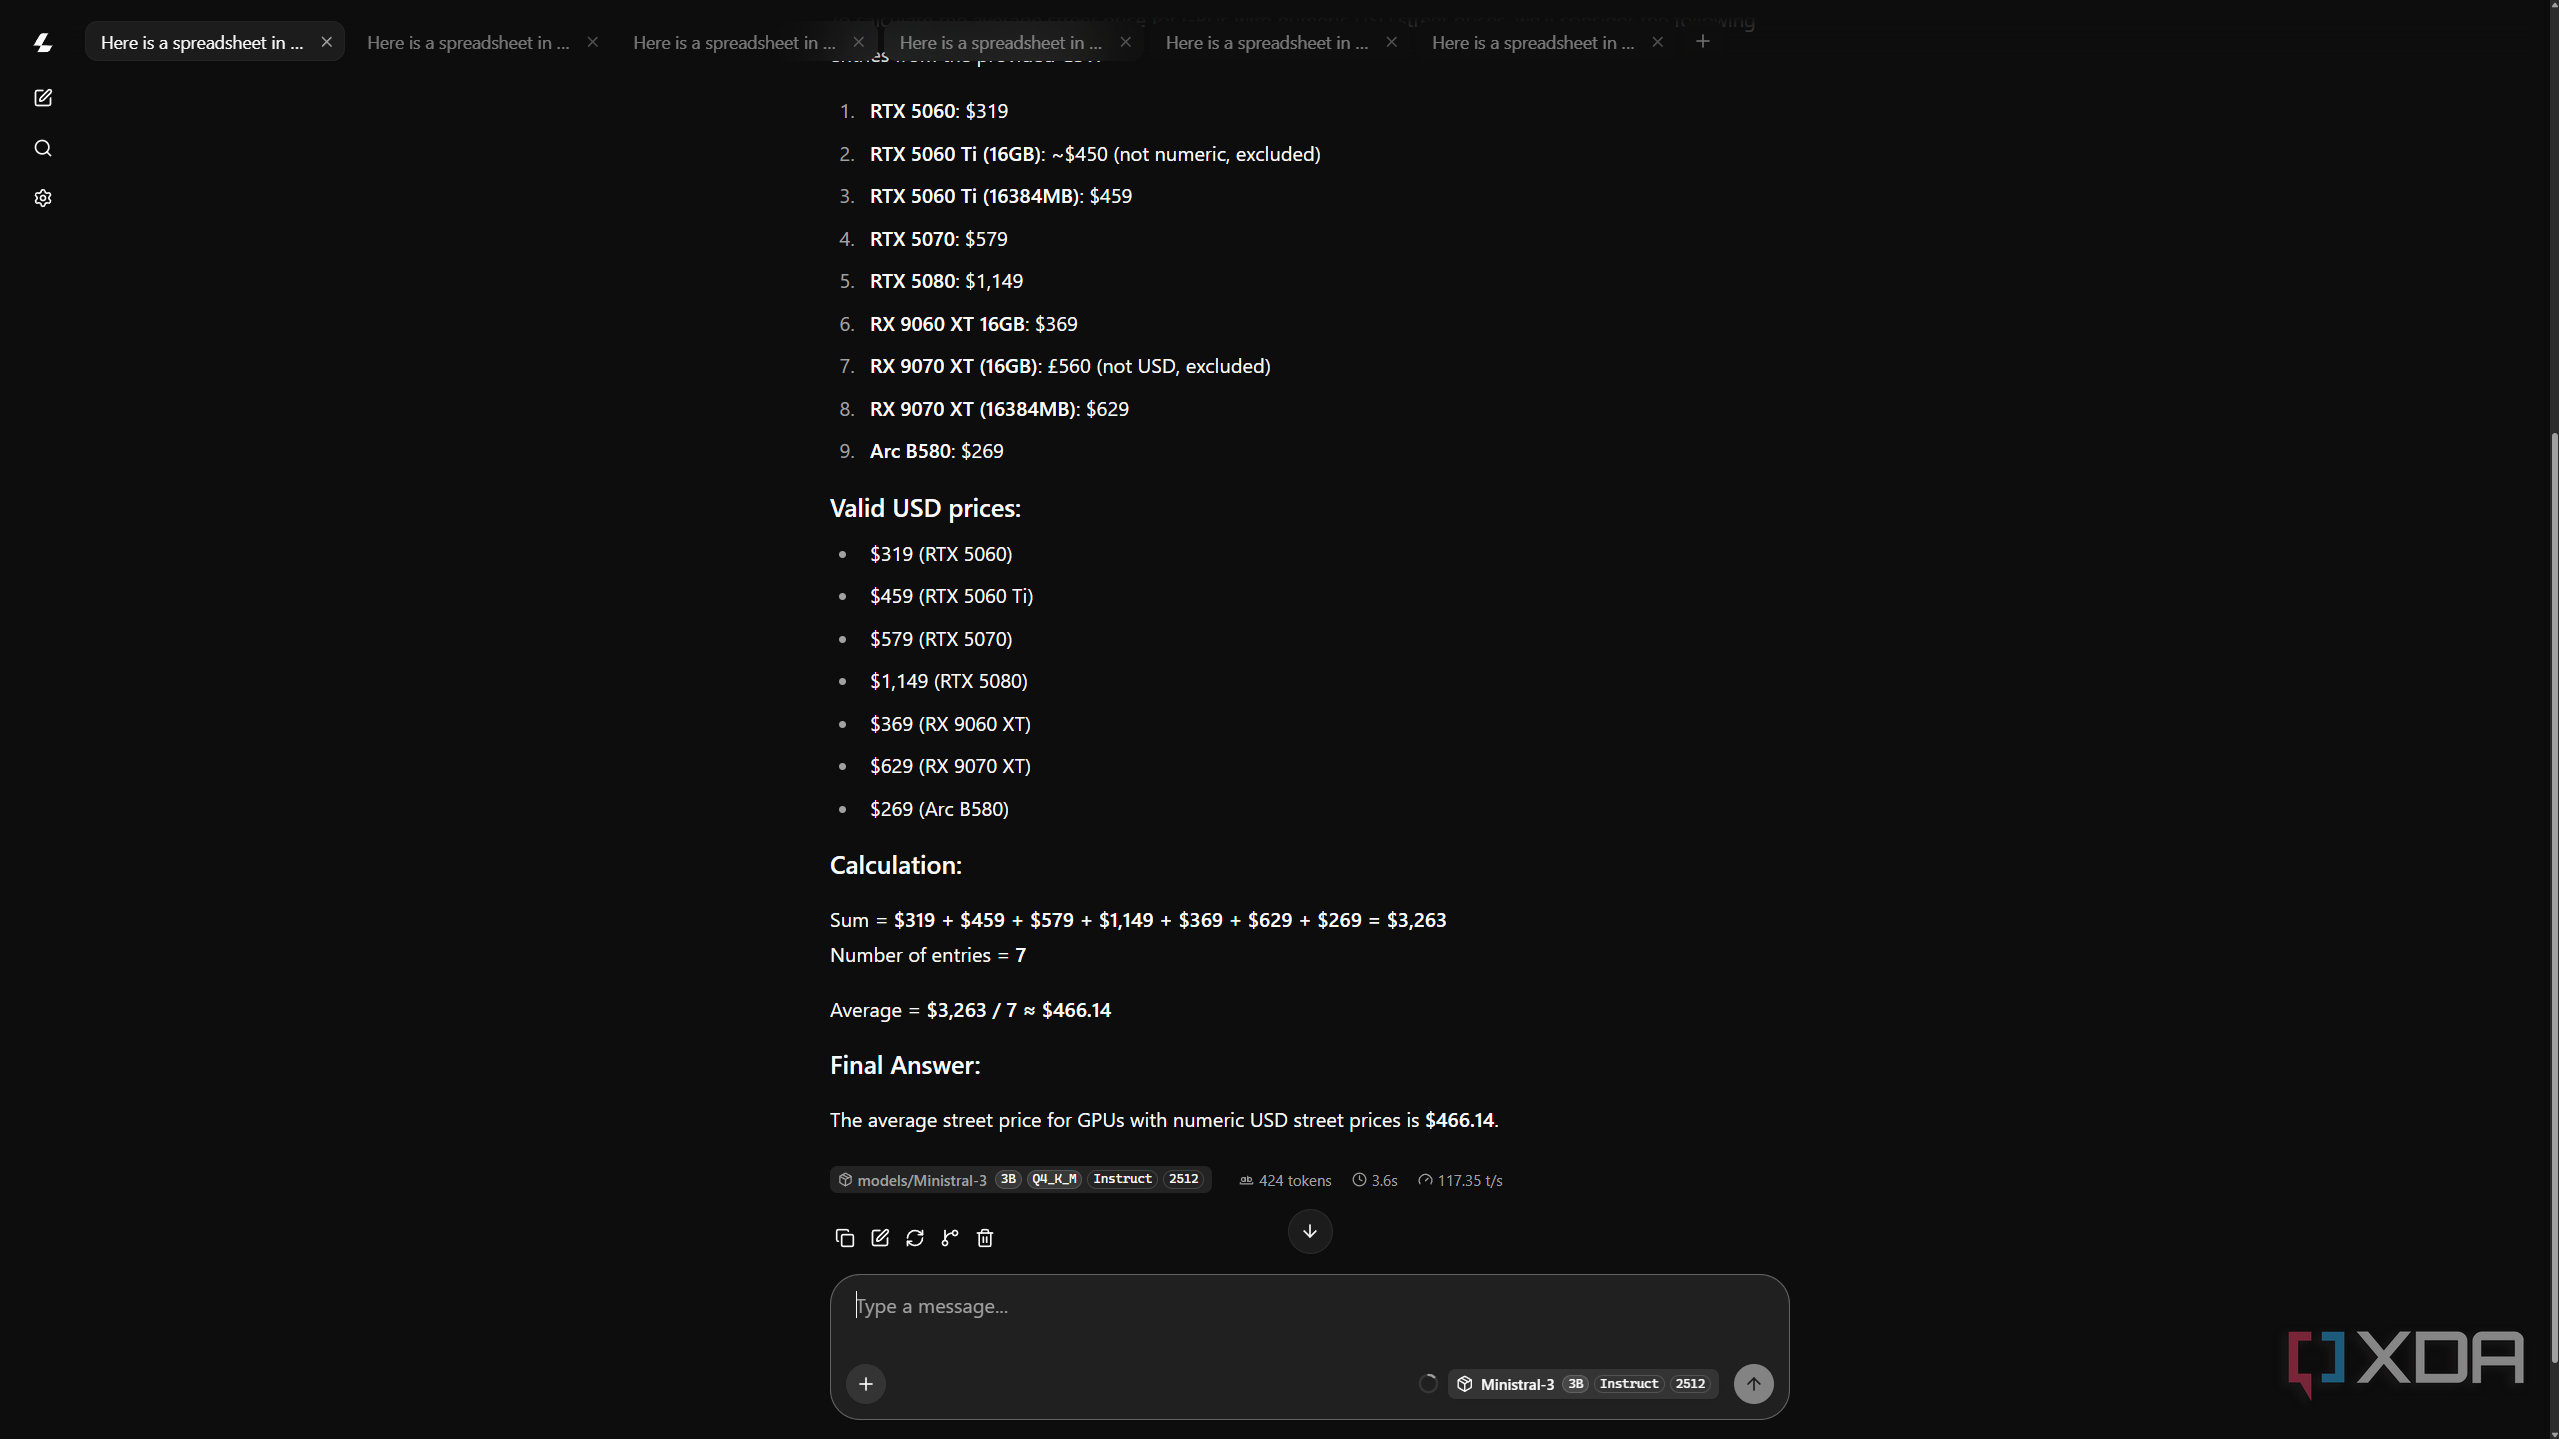
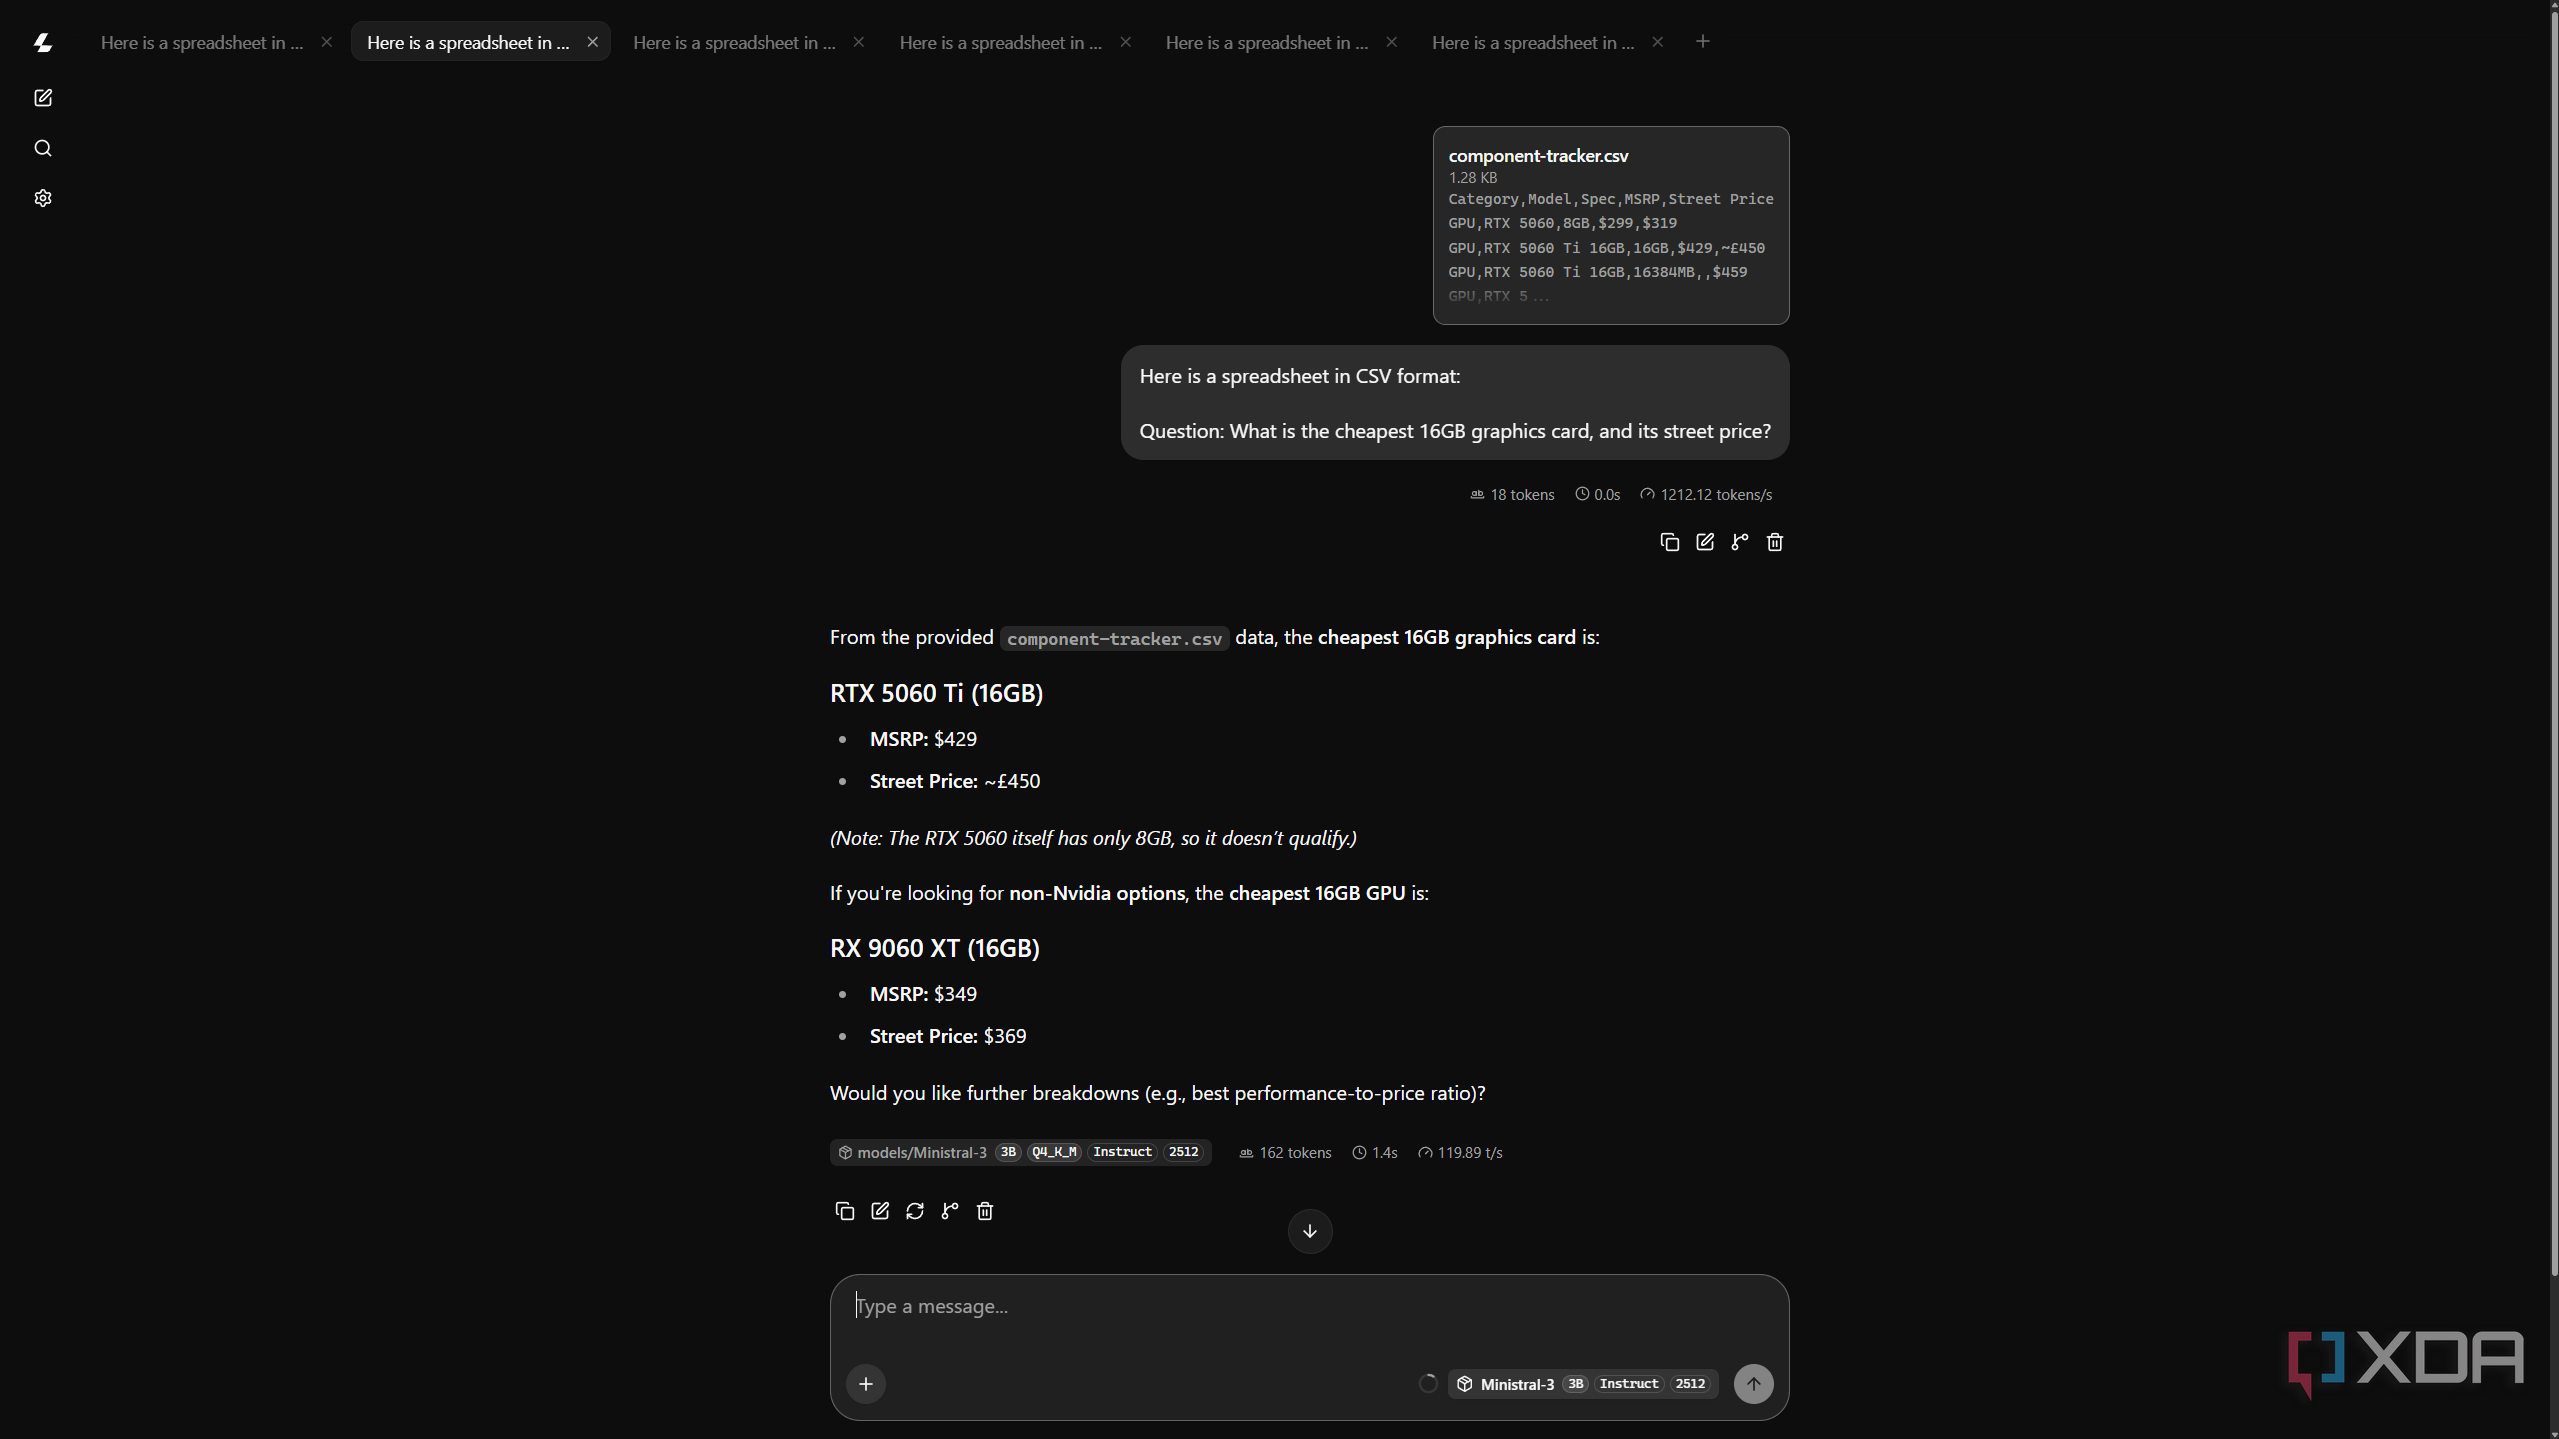
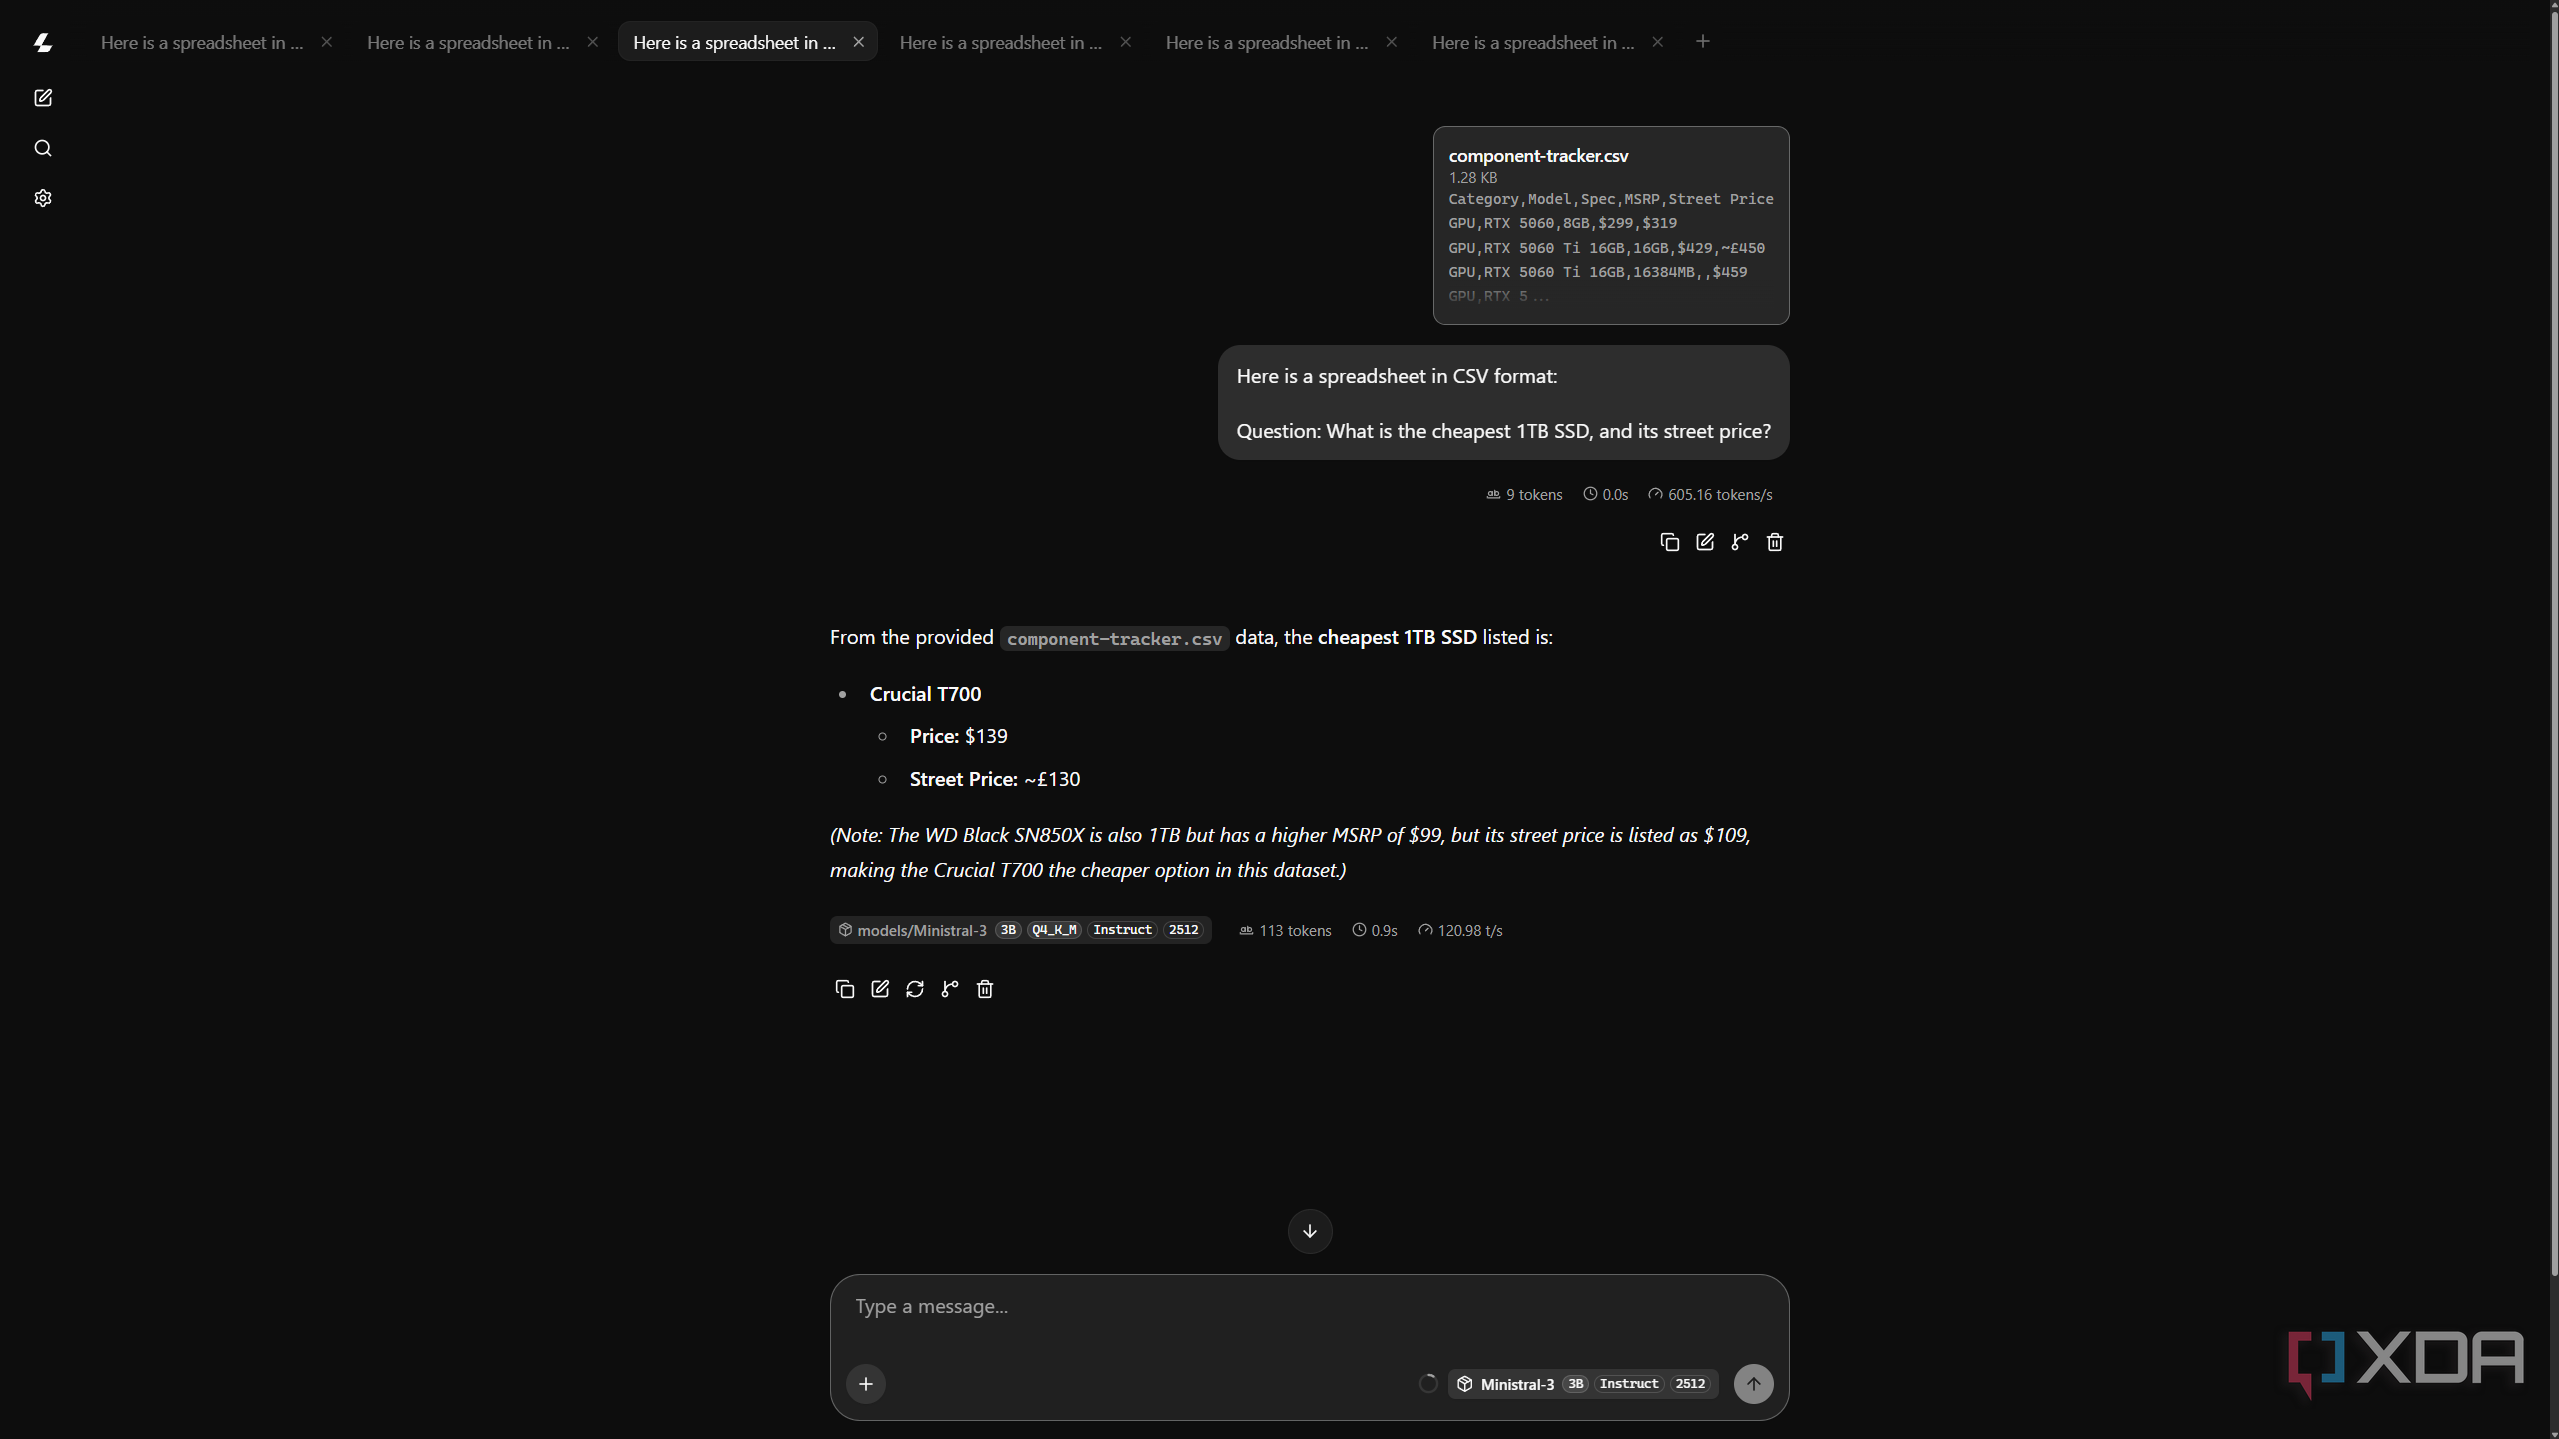
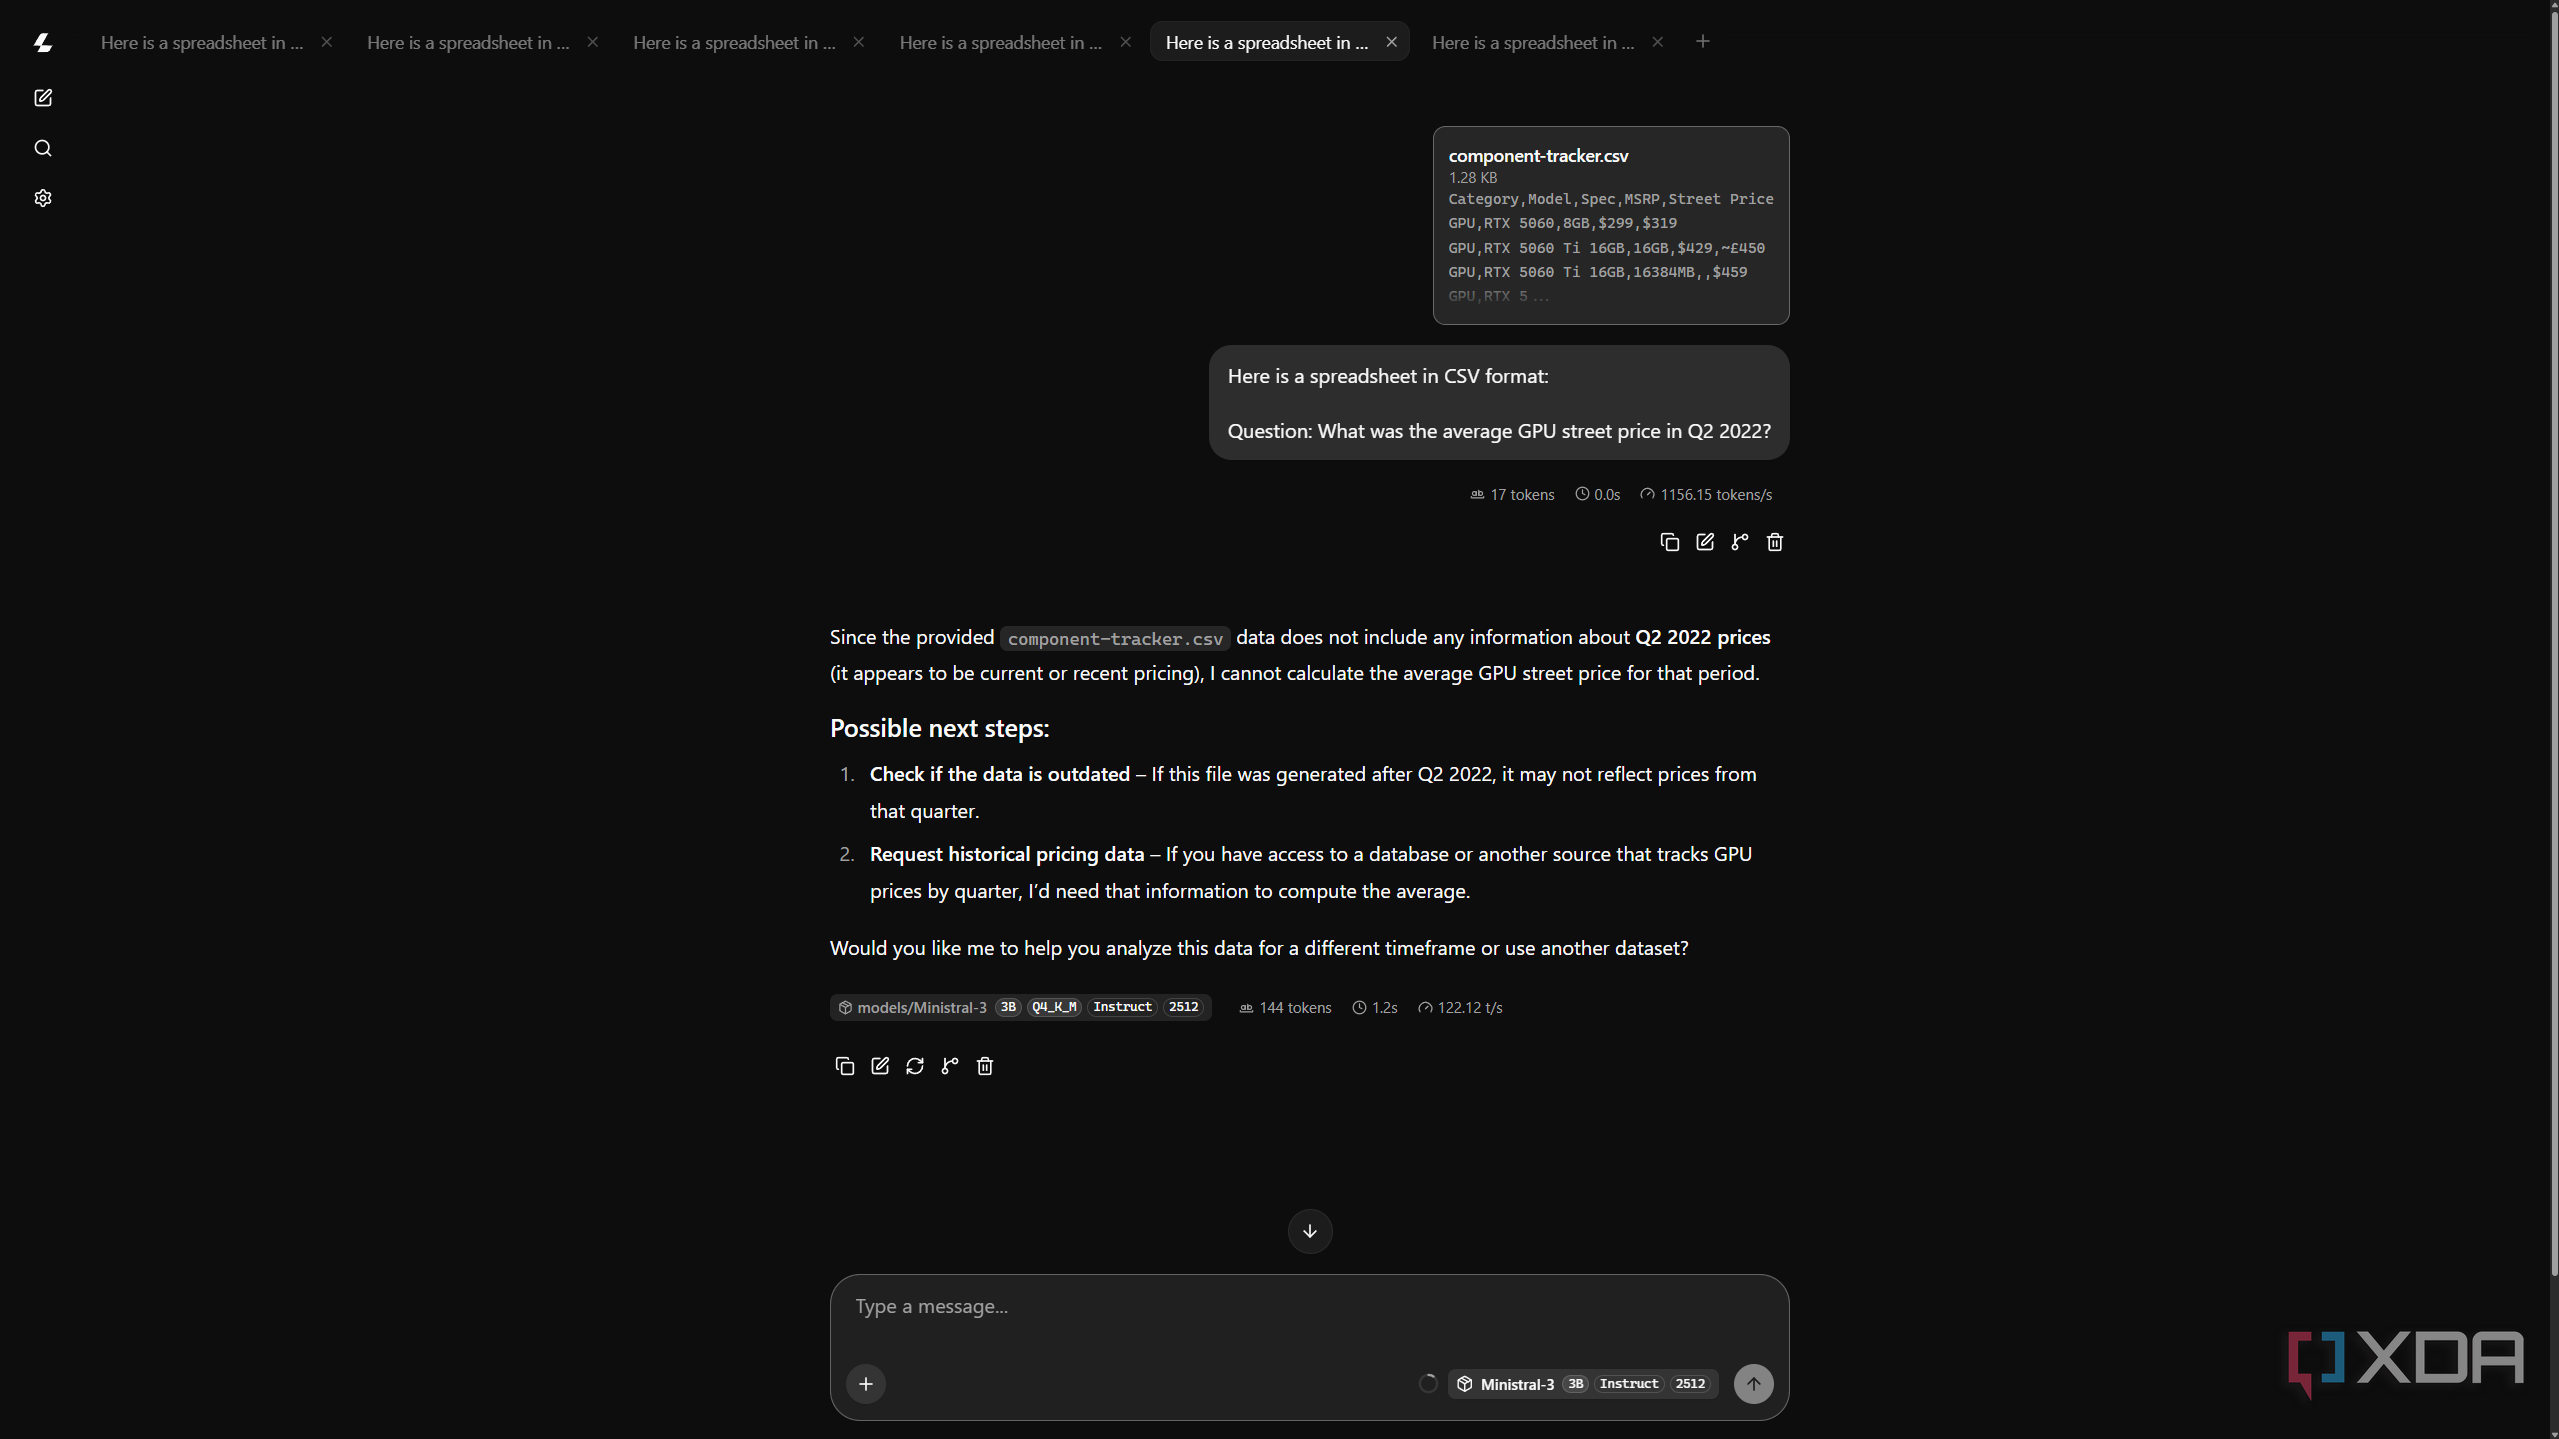
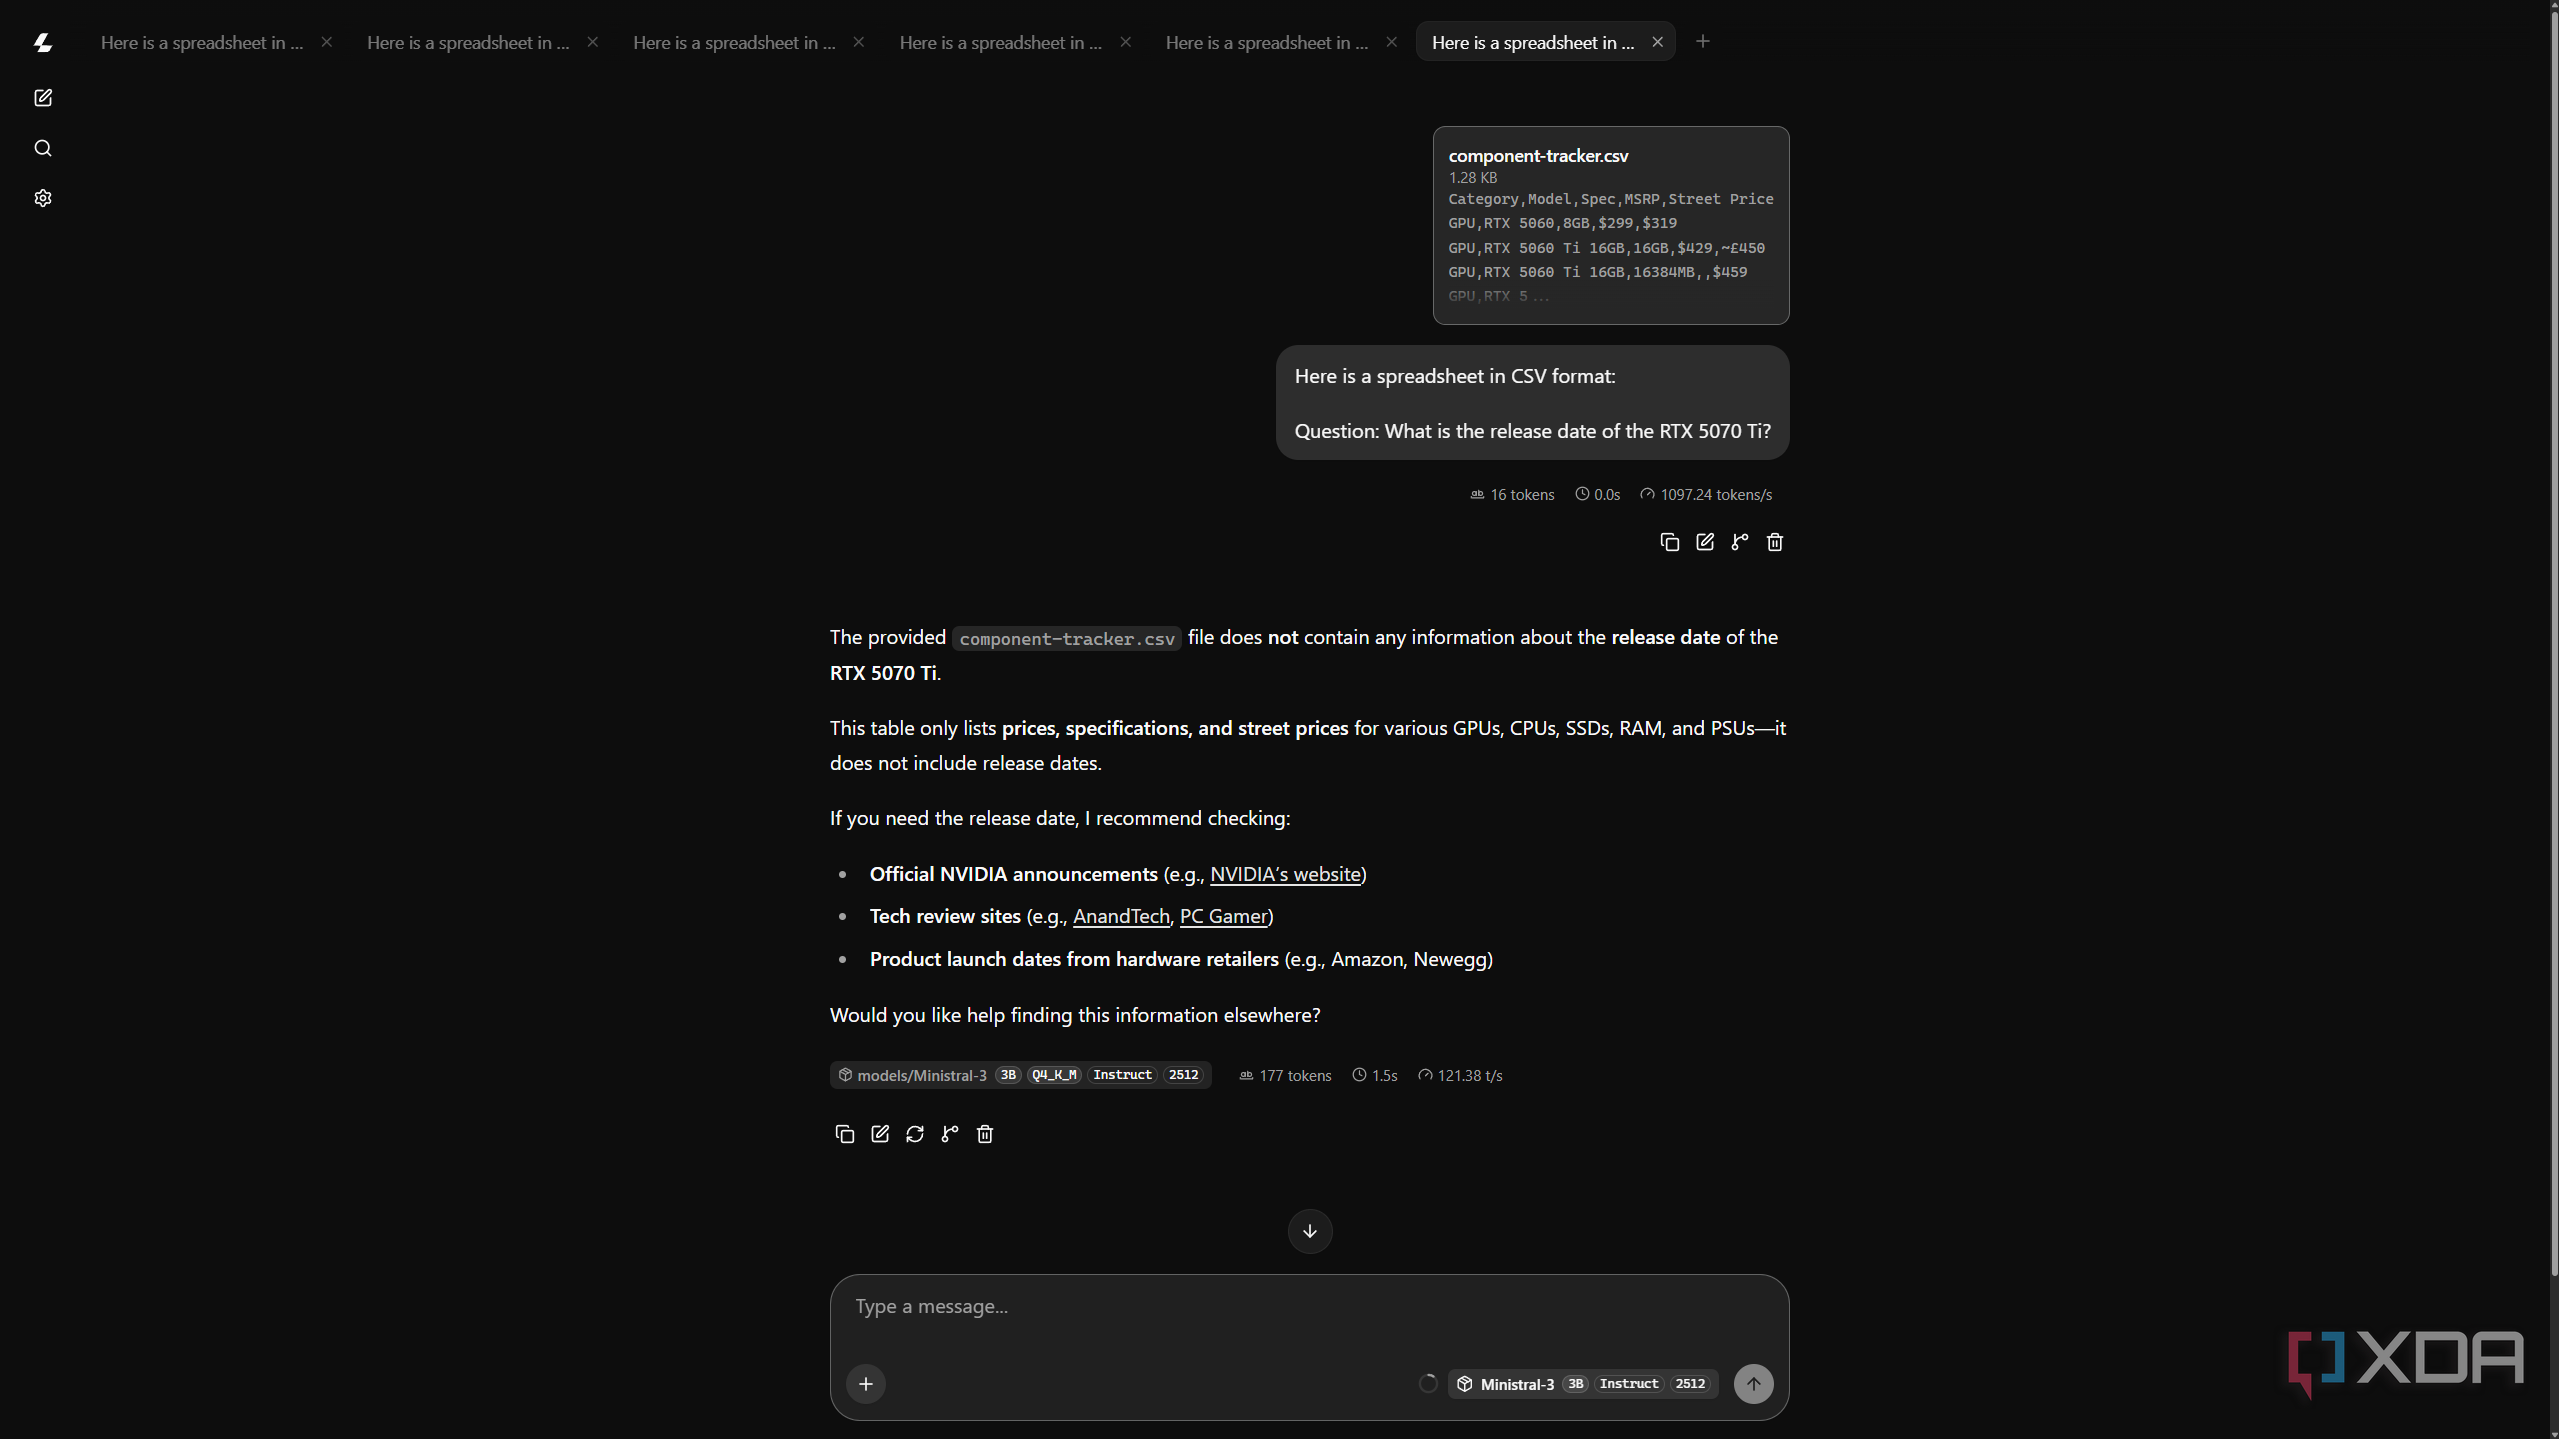
The 3B model consistently picked the right seven cards for the question that asked it to return the average GPU price, but then produced $466.14 and $480.43 across the two runs, when the correct answer was $539. On the 16GB GPU and 1TB SSD questions it picked the wrong products outright, ranking cards and drives priced in pounds as the cheapest options in both cases.
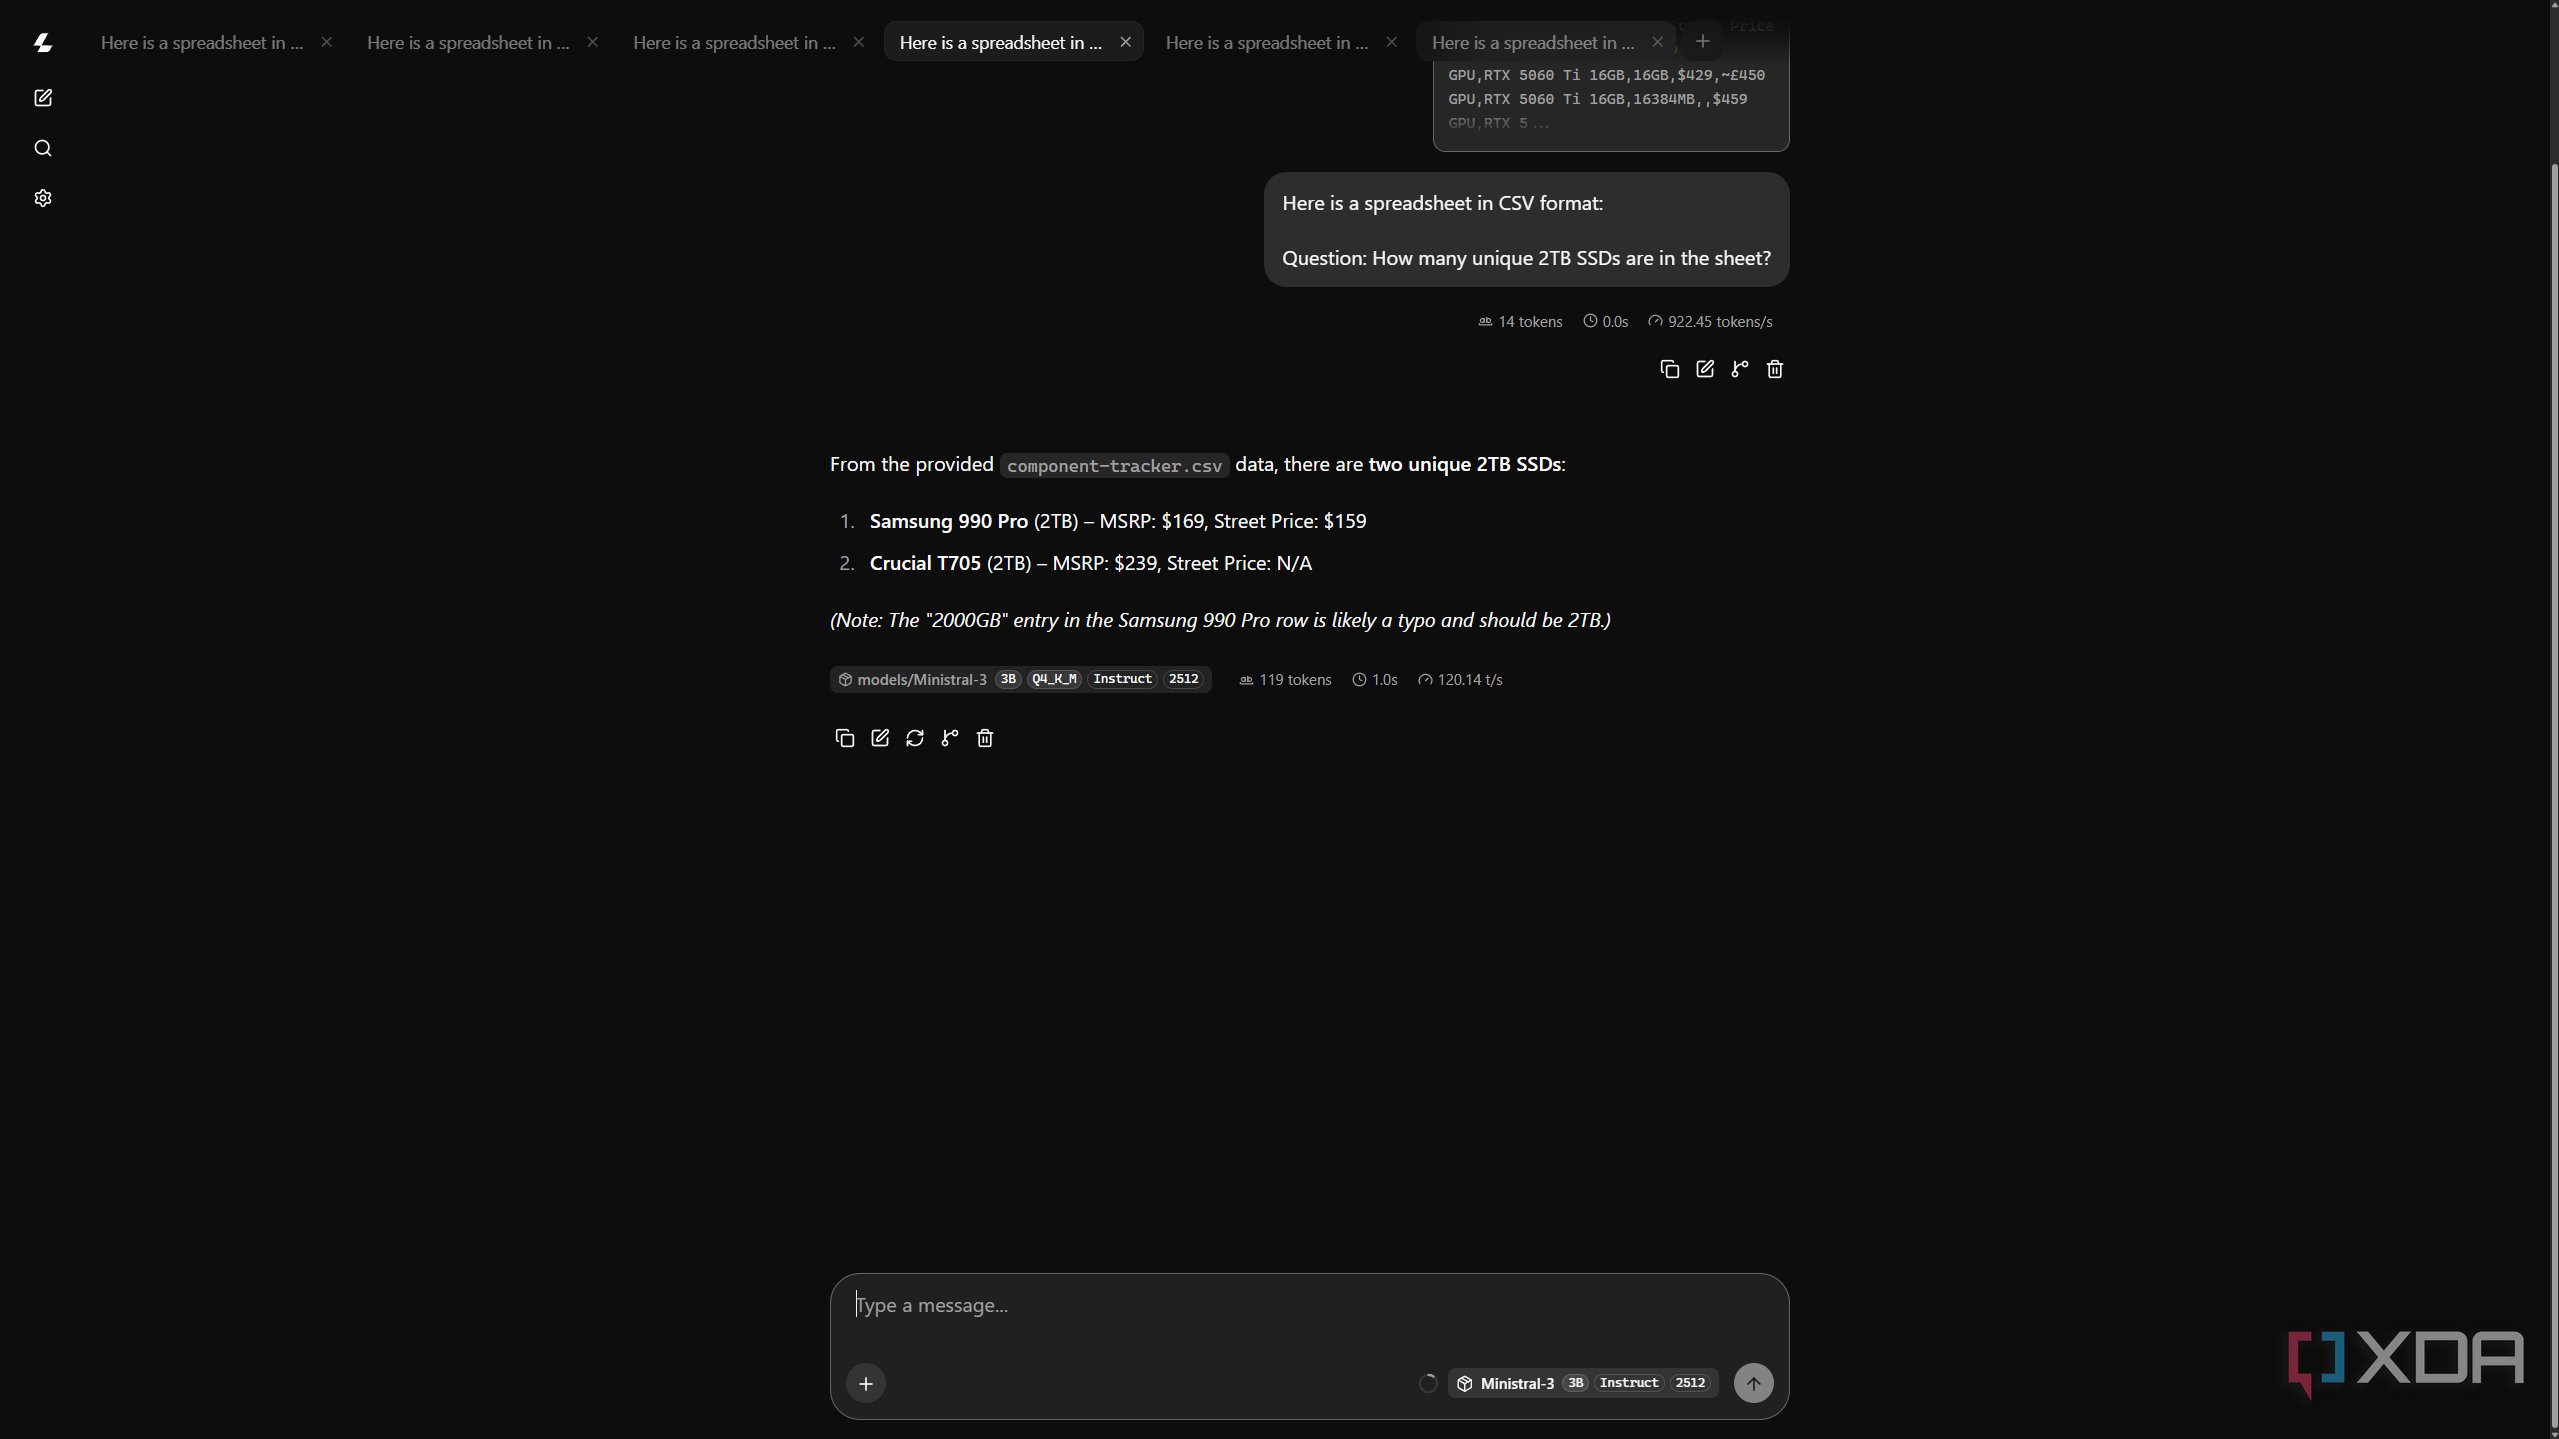
The grounding, however, was perfect. In every other question asked pertaining to data analysis, it got exactly one right, which was the count of unique 2TB SSDs.
|
Question |
Response |
|---|---|
|
Across all GPUs, what is the average street price? Use only cards with a numeric USD street price. |
Run 1: $466.14 Run 2: $480.43 |
|
What is the cheapest 16GB graphics card, and its street price? |
Both runs: RTX 5060 Ti |
|
What is the cheapest 1TB SSD, and its street price? |
Both runs: Crucial T700 |
|
How many unique 2TB SSDs are in the sheet? |
Both runs: 2 |
|
What was the average GPU street price in Q2 2022? |
Declined on both runs |
|
What is the release date of the RTX 5070 Ti? |
Declined on both runs |
Phi-4 Mini
Gave me two completely different wrong answers to the same question
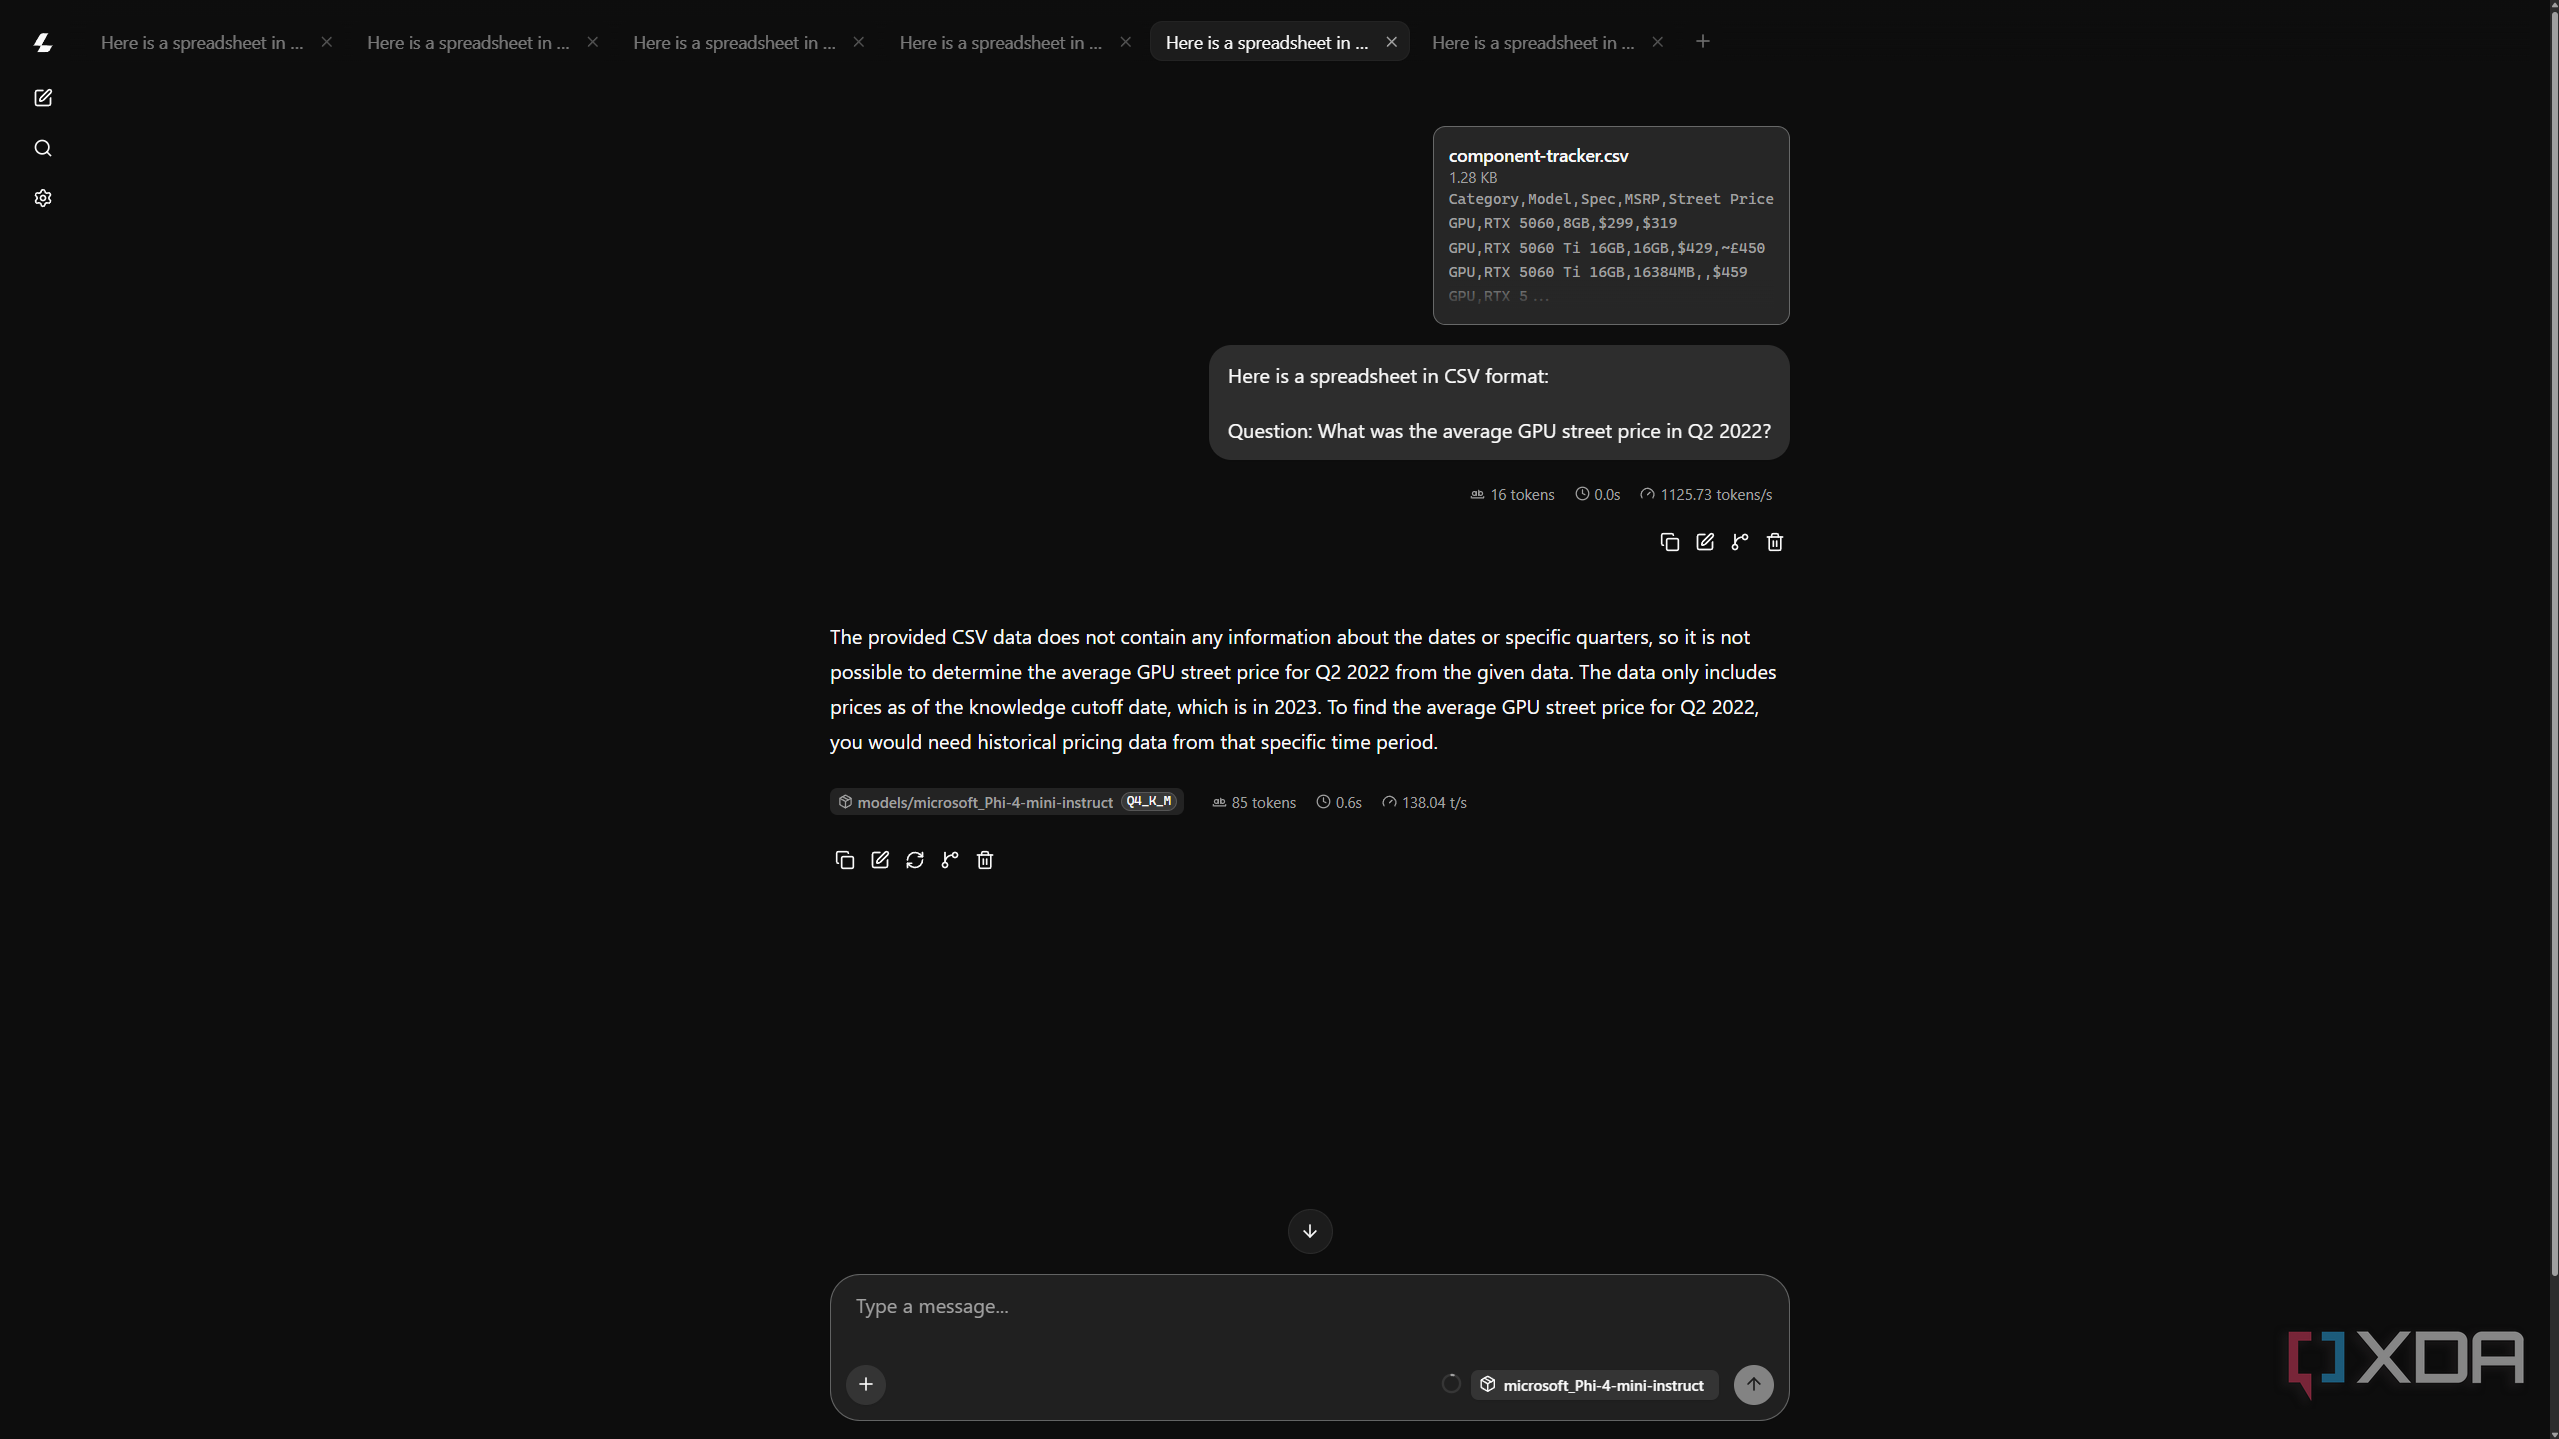
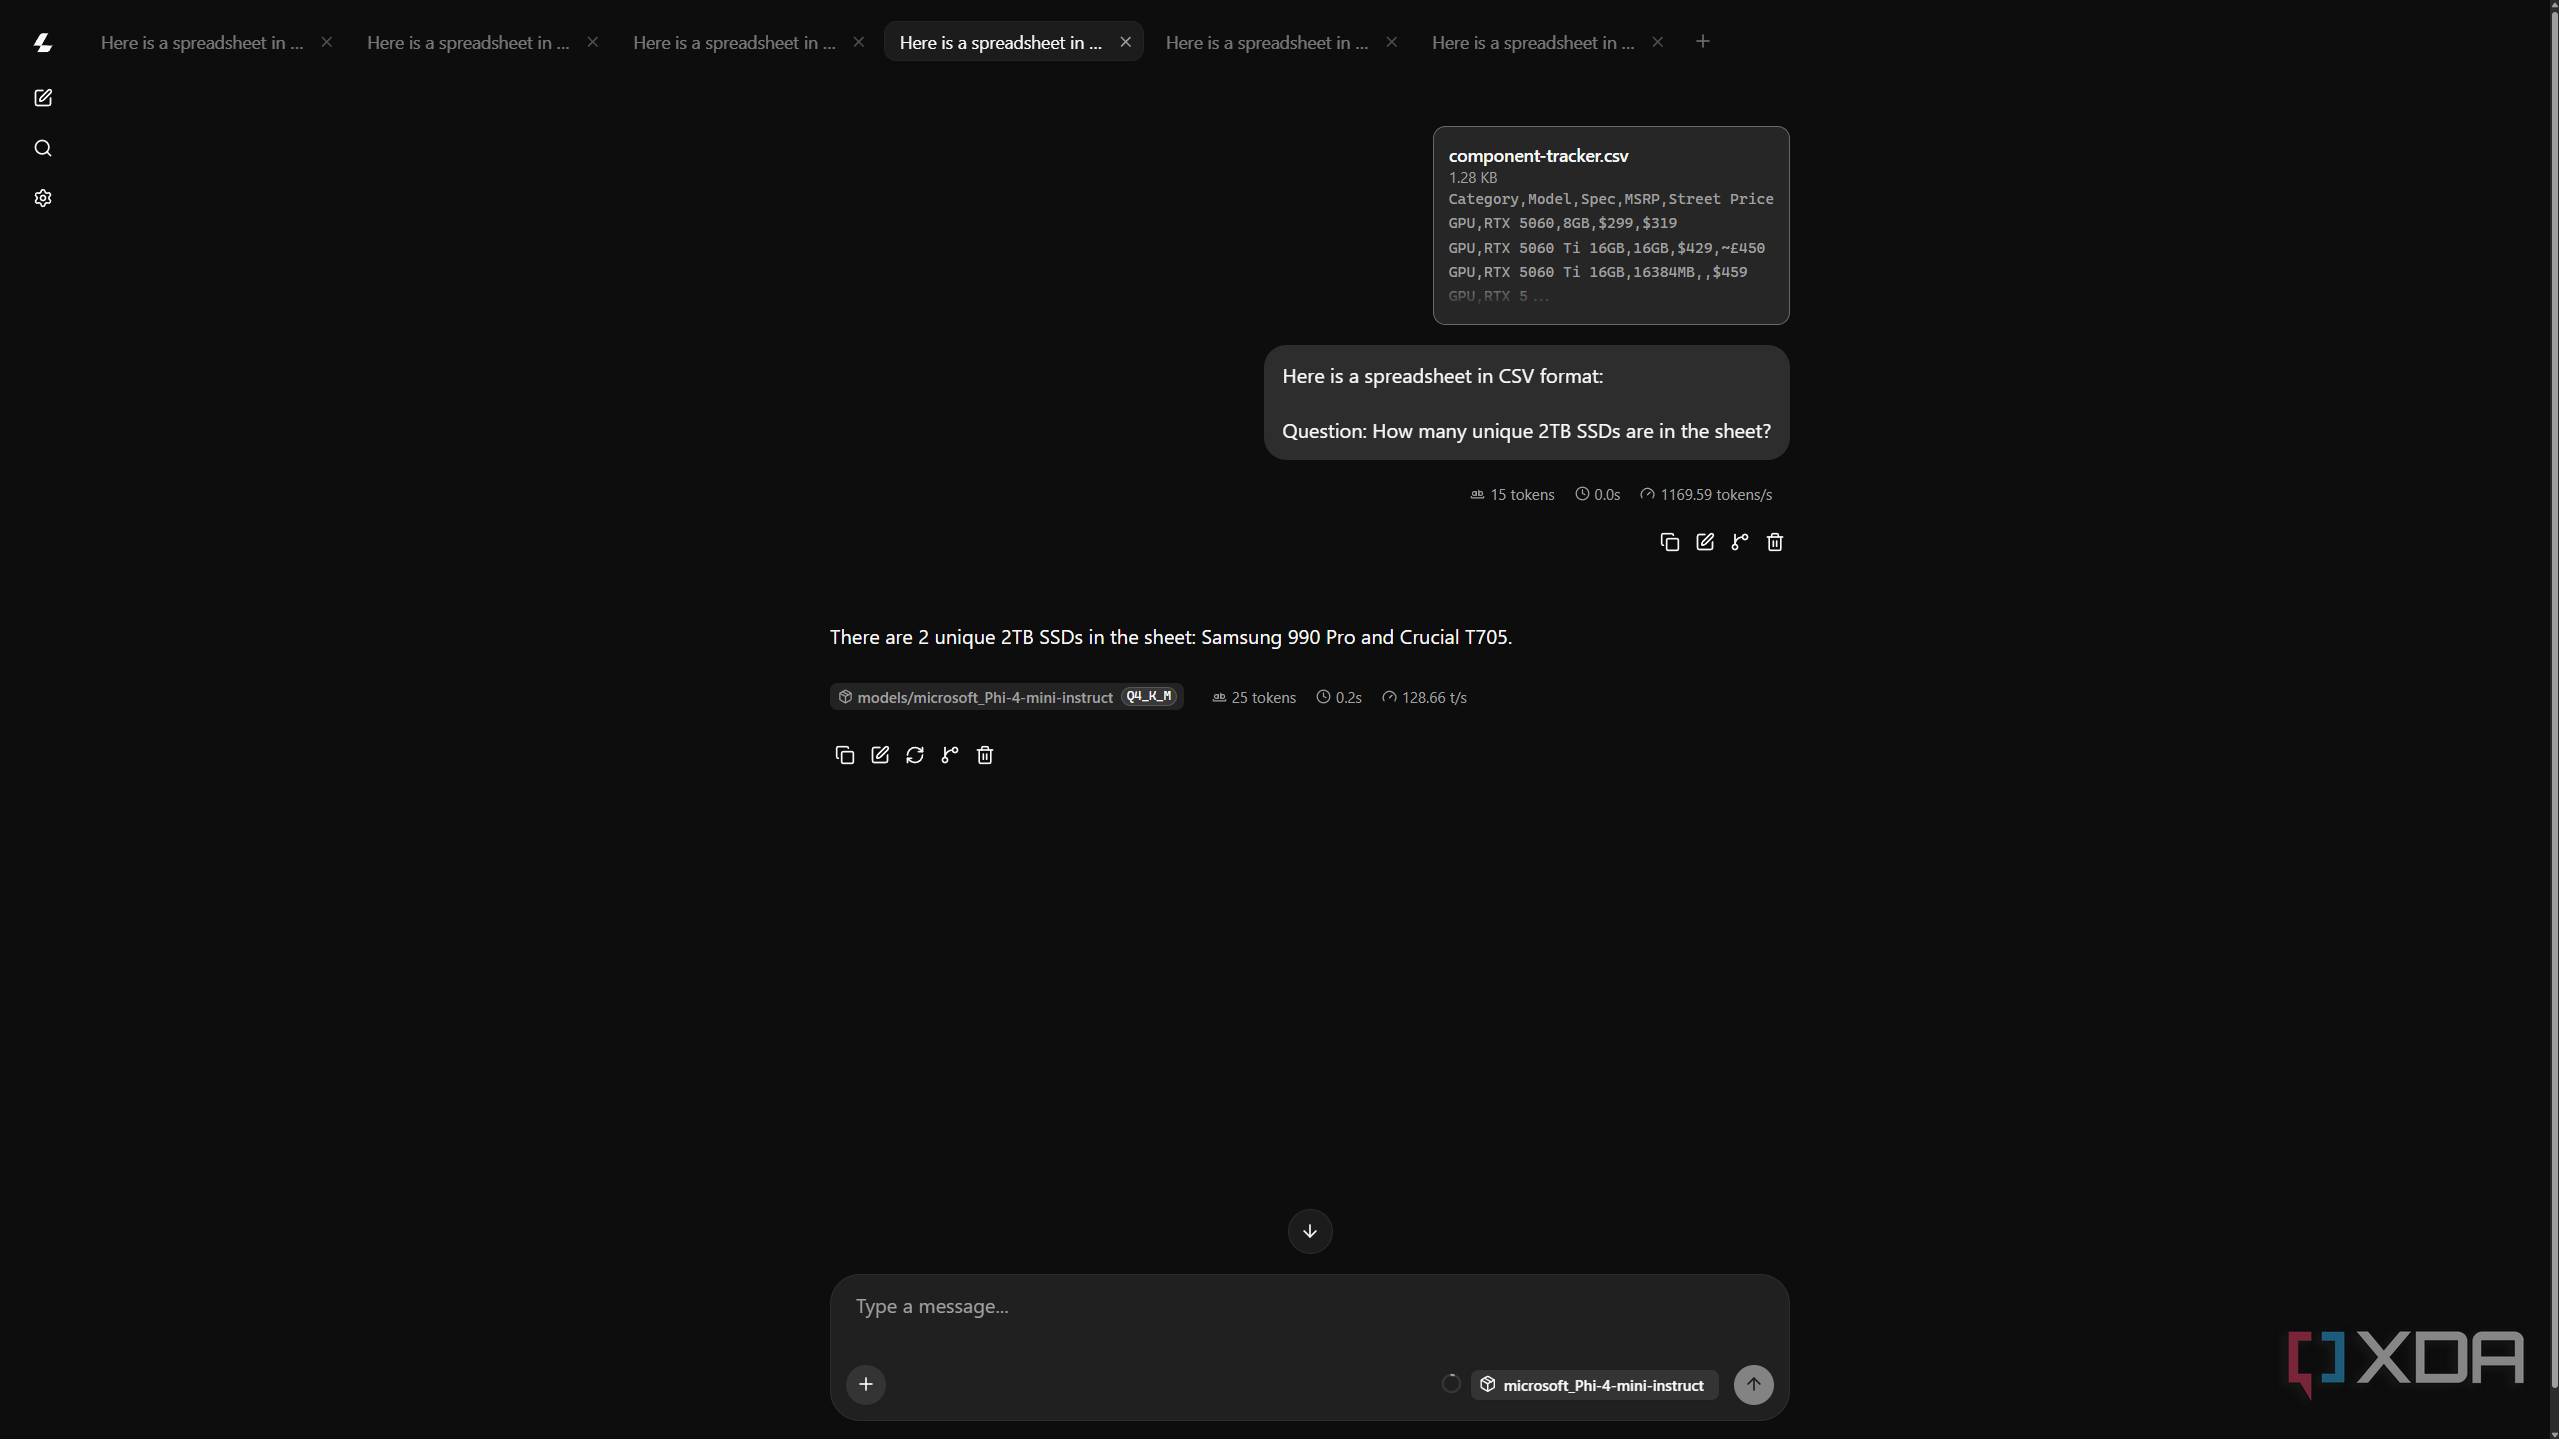
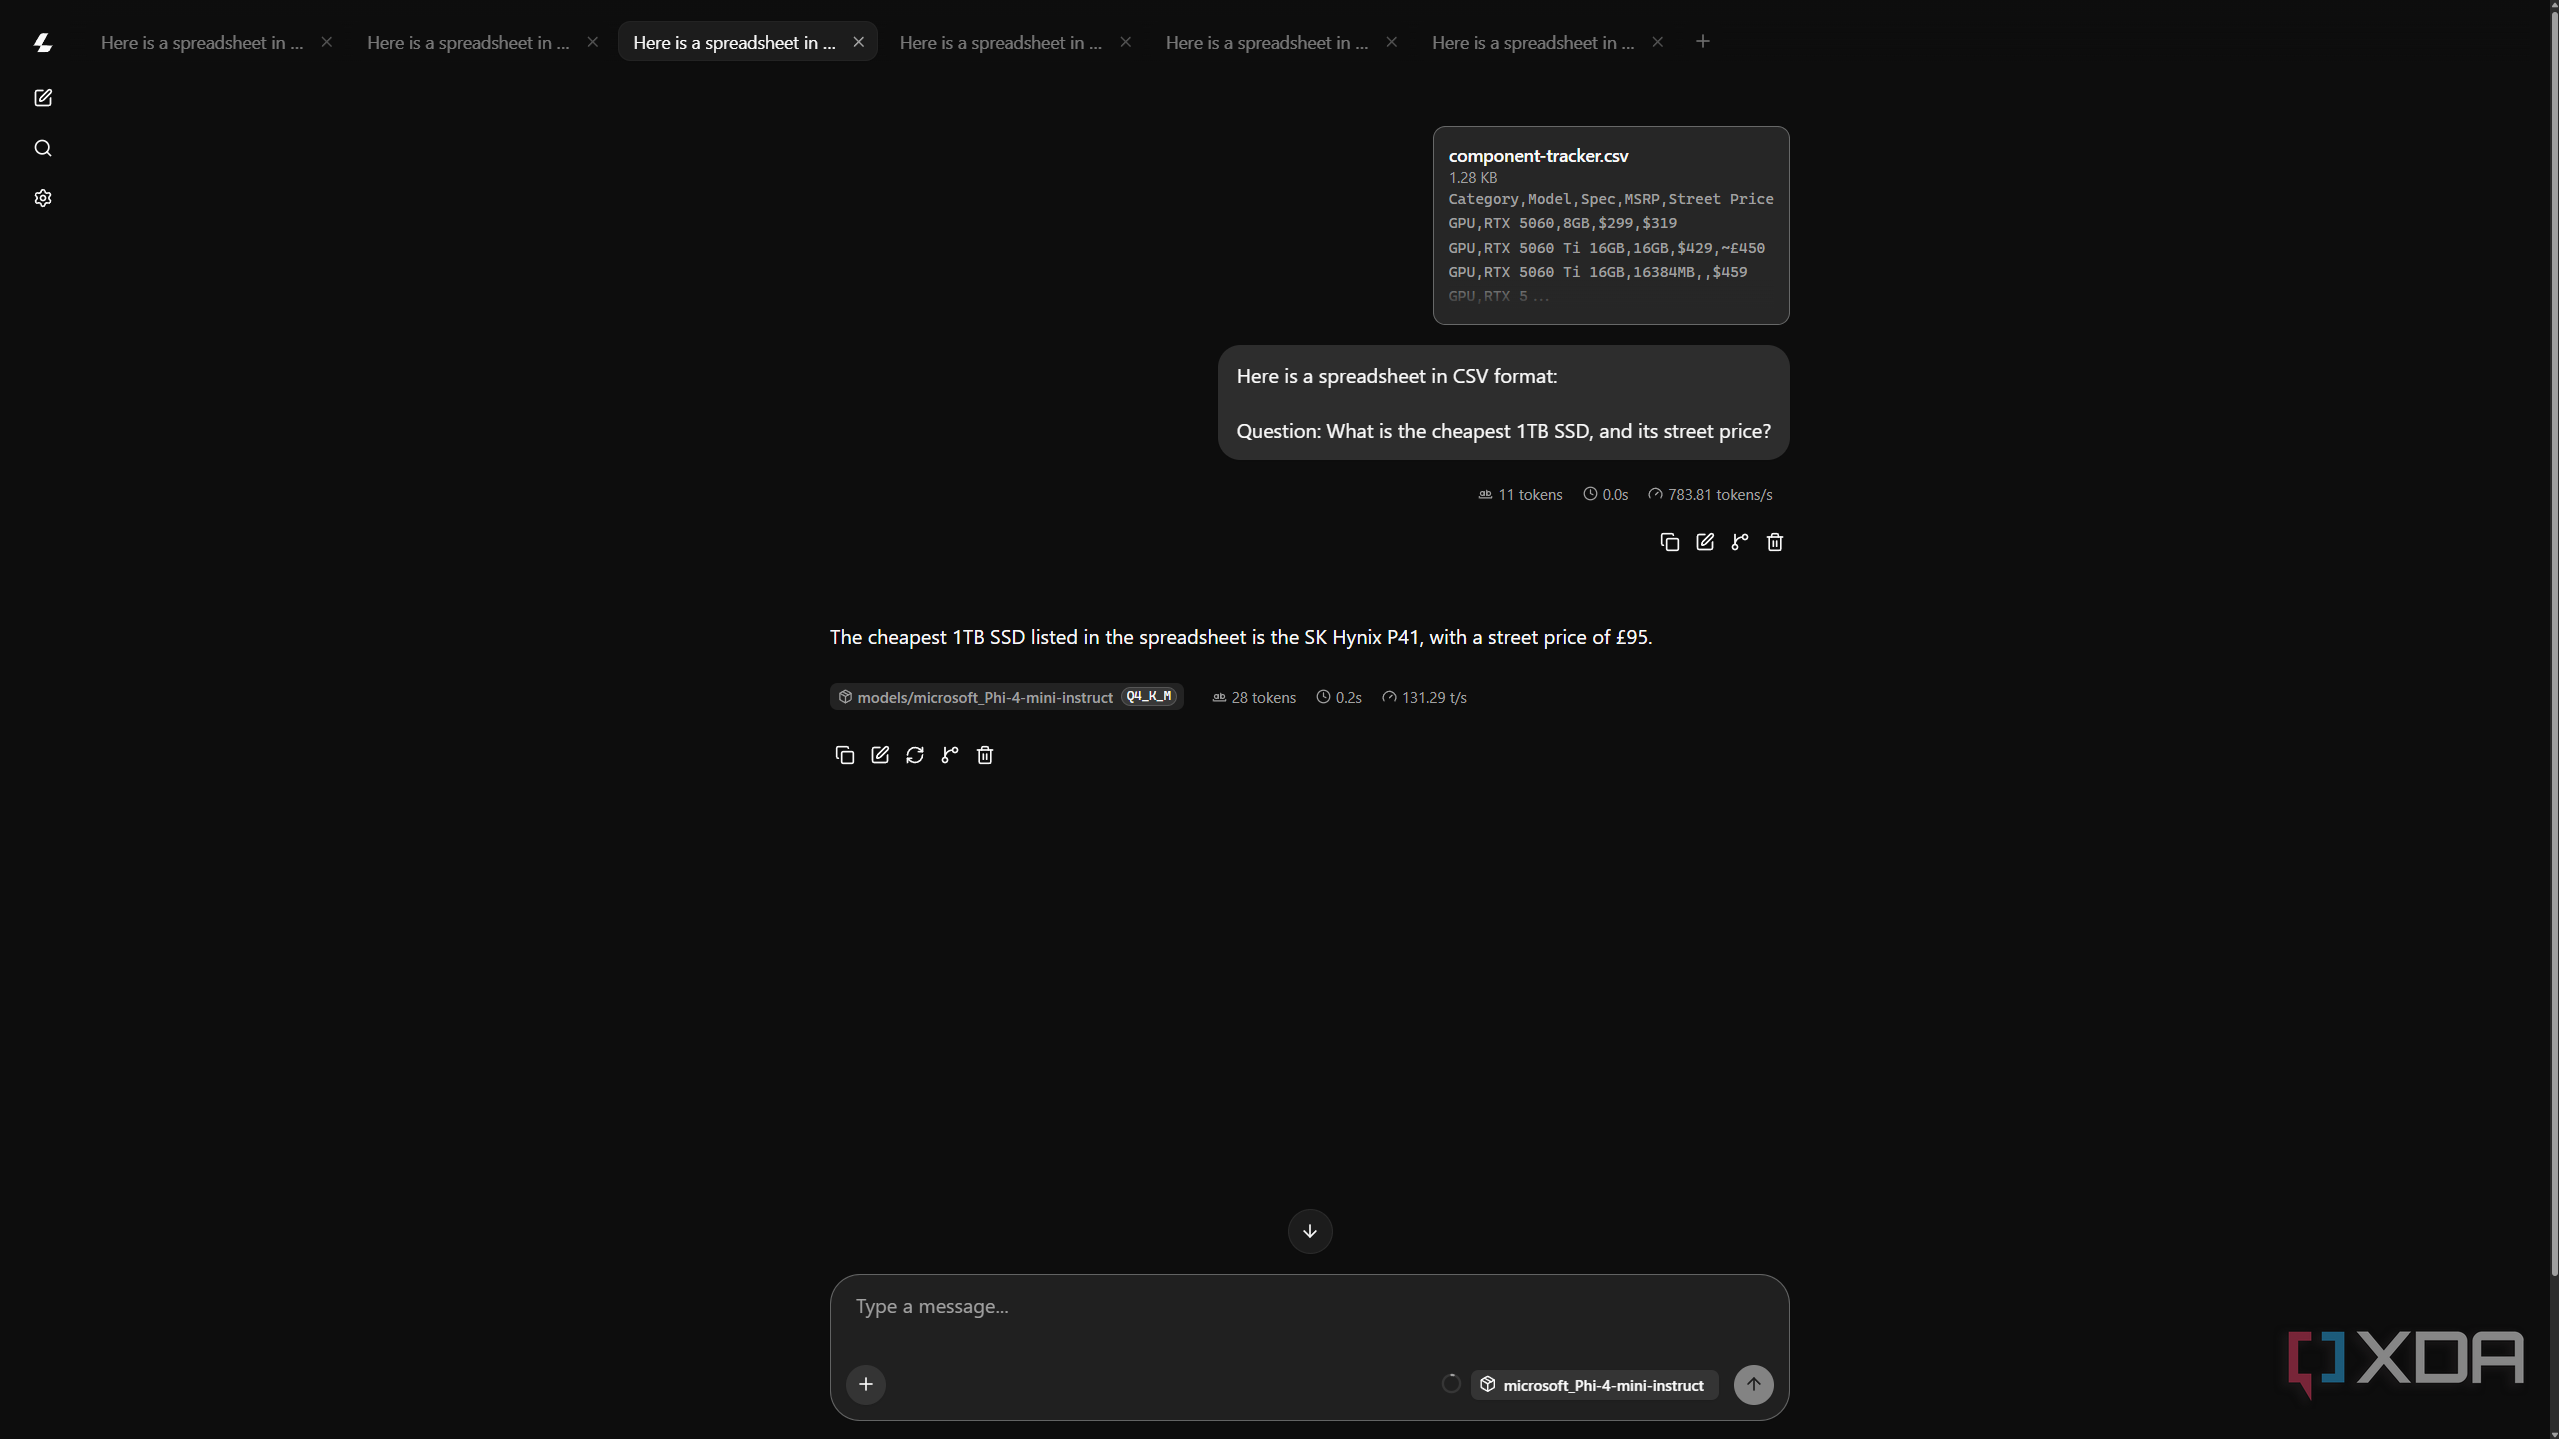
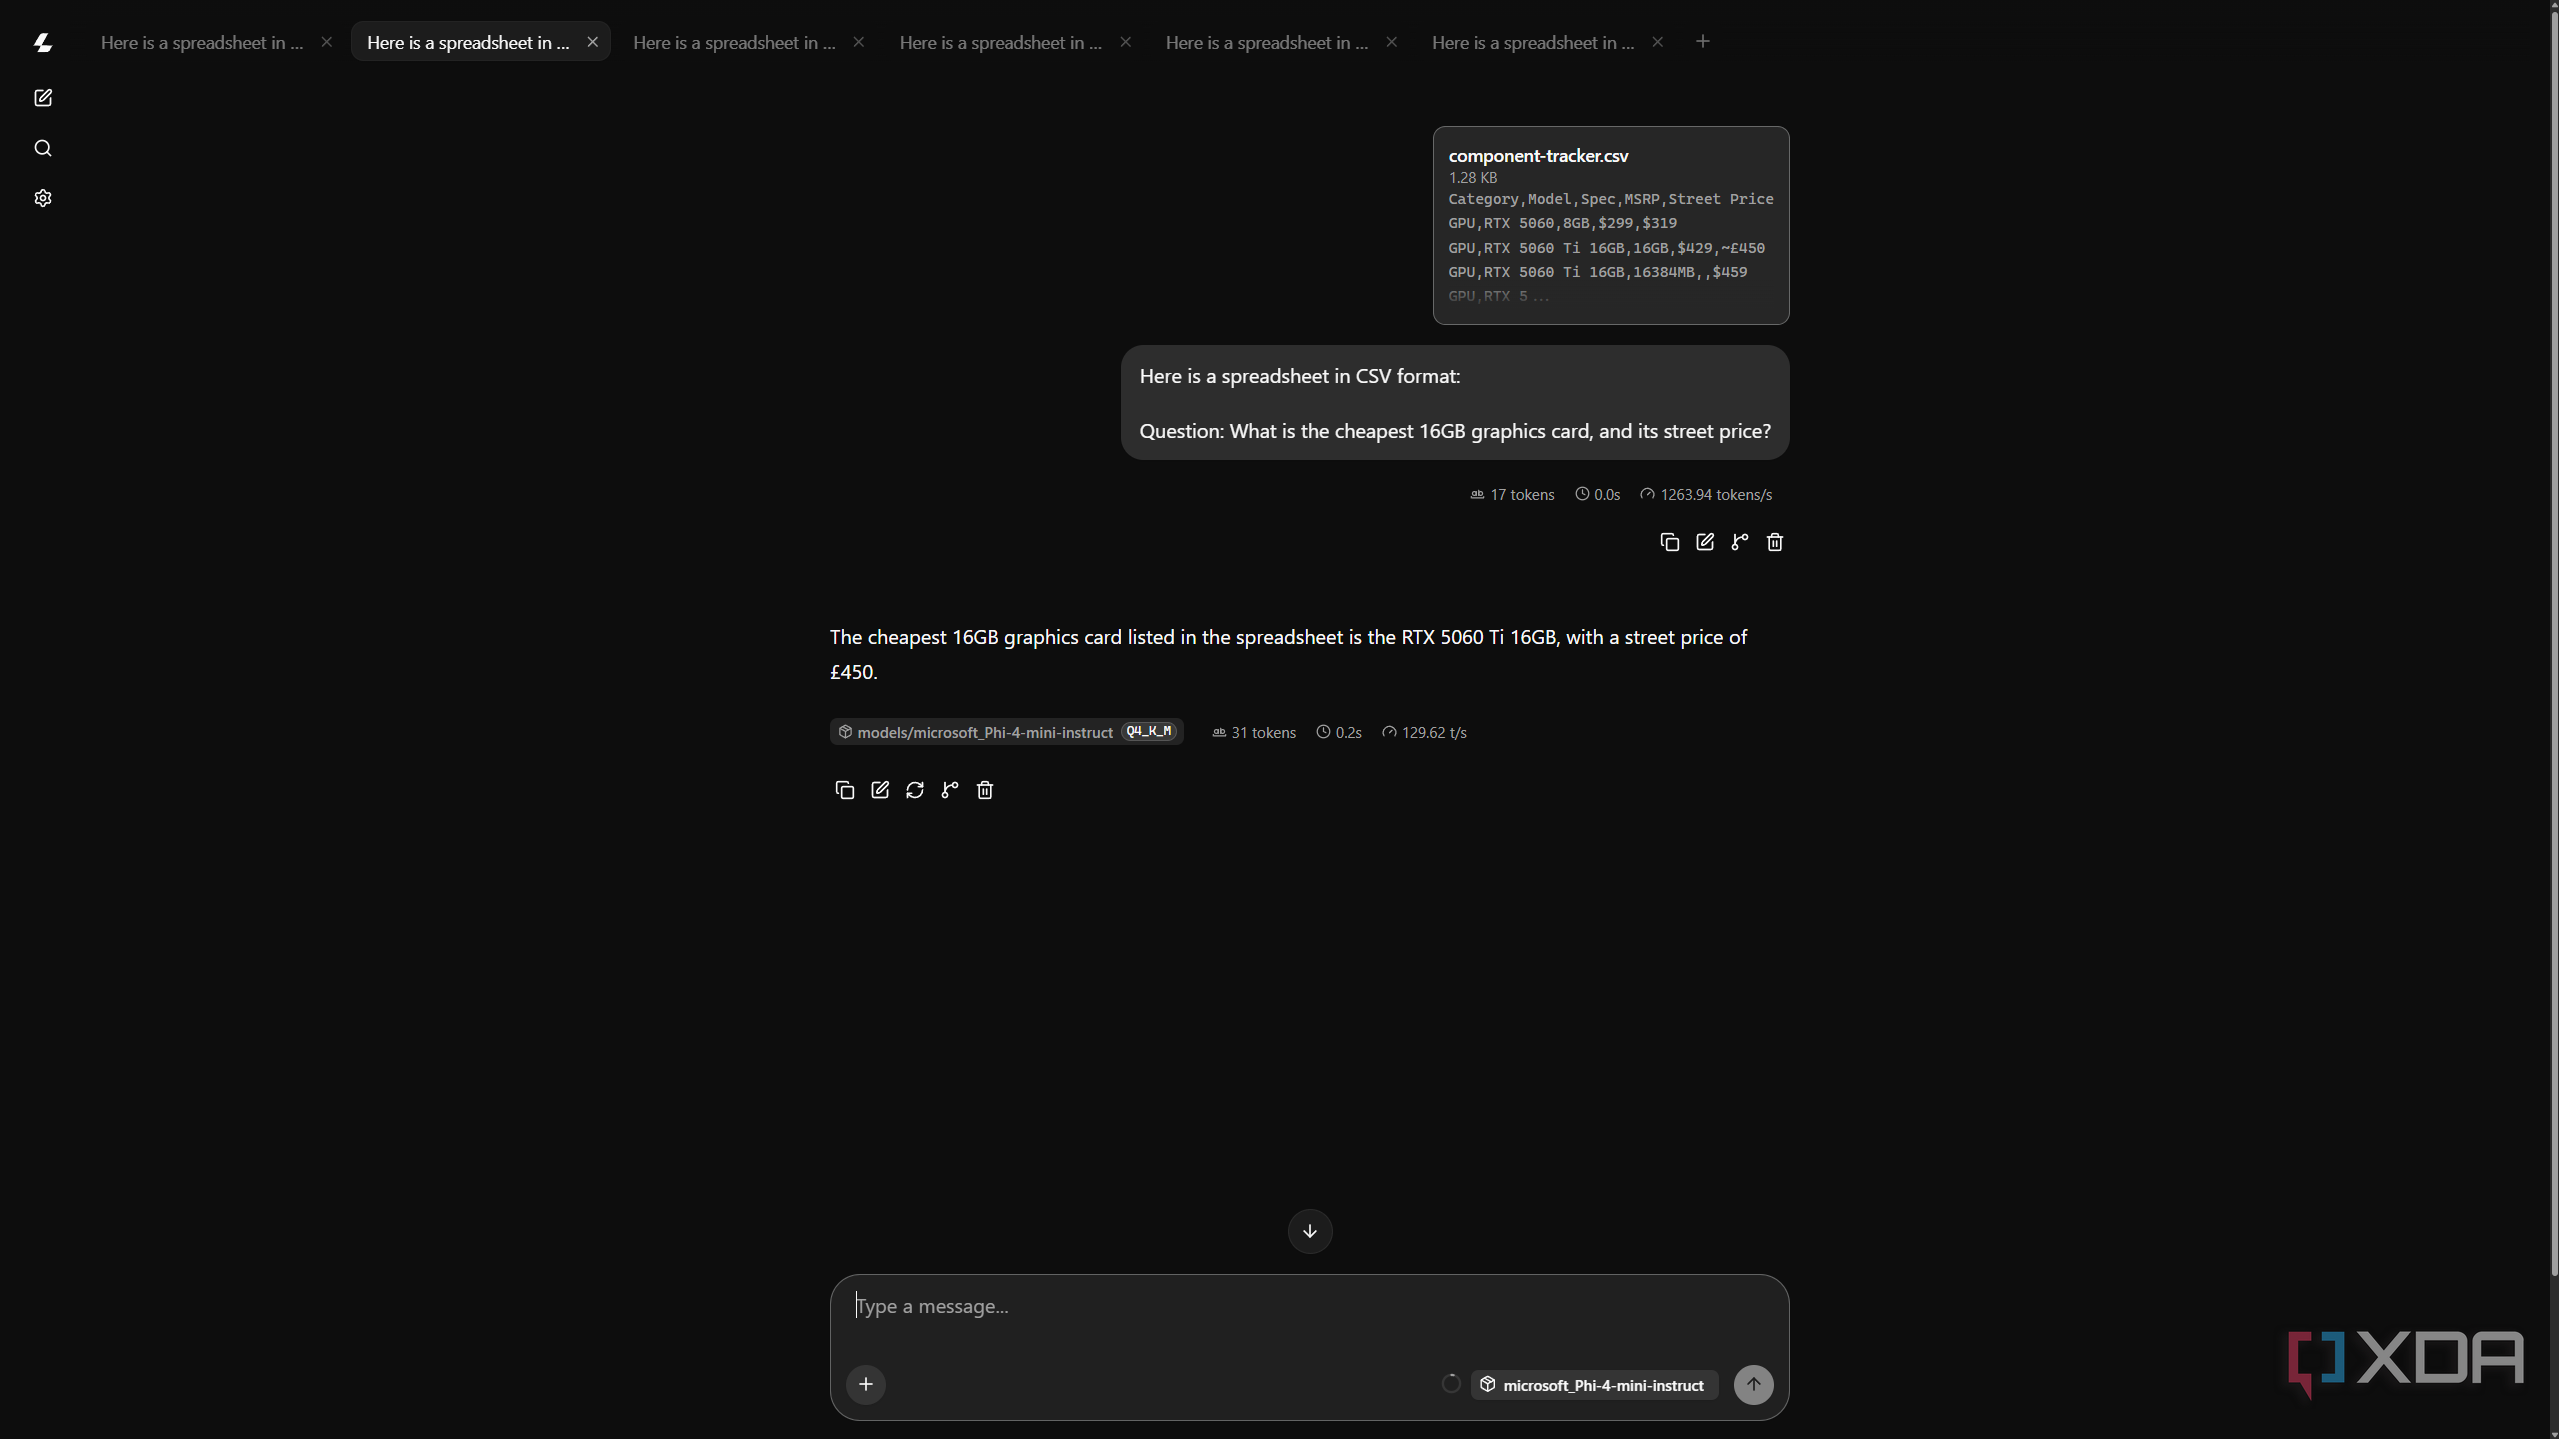
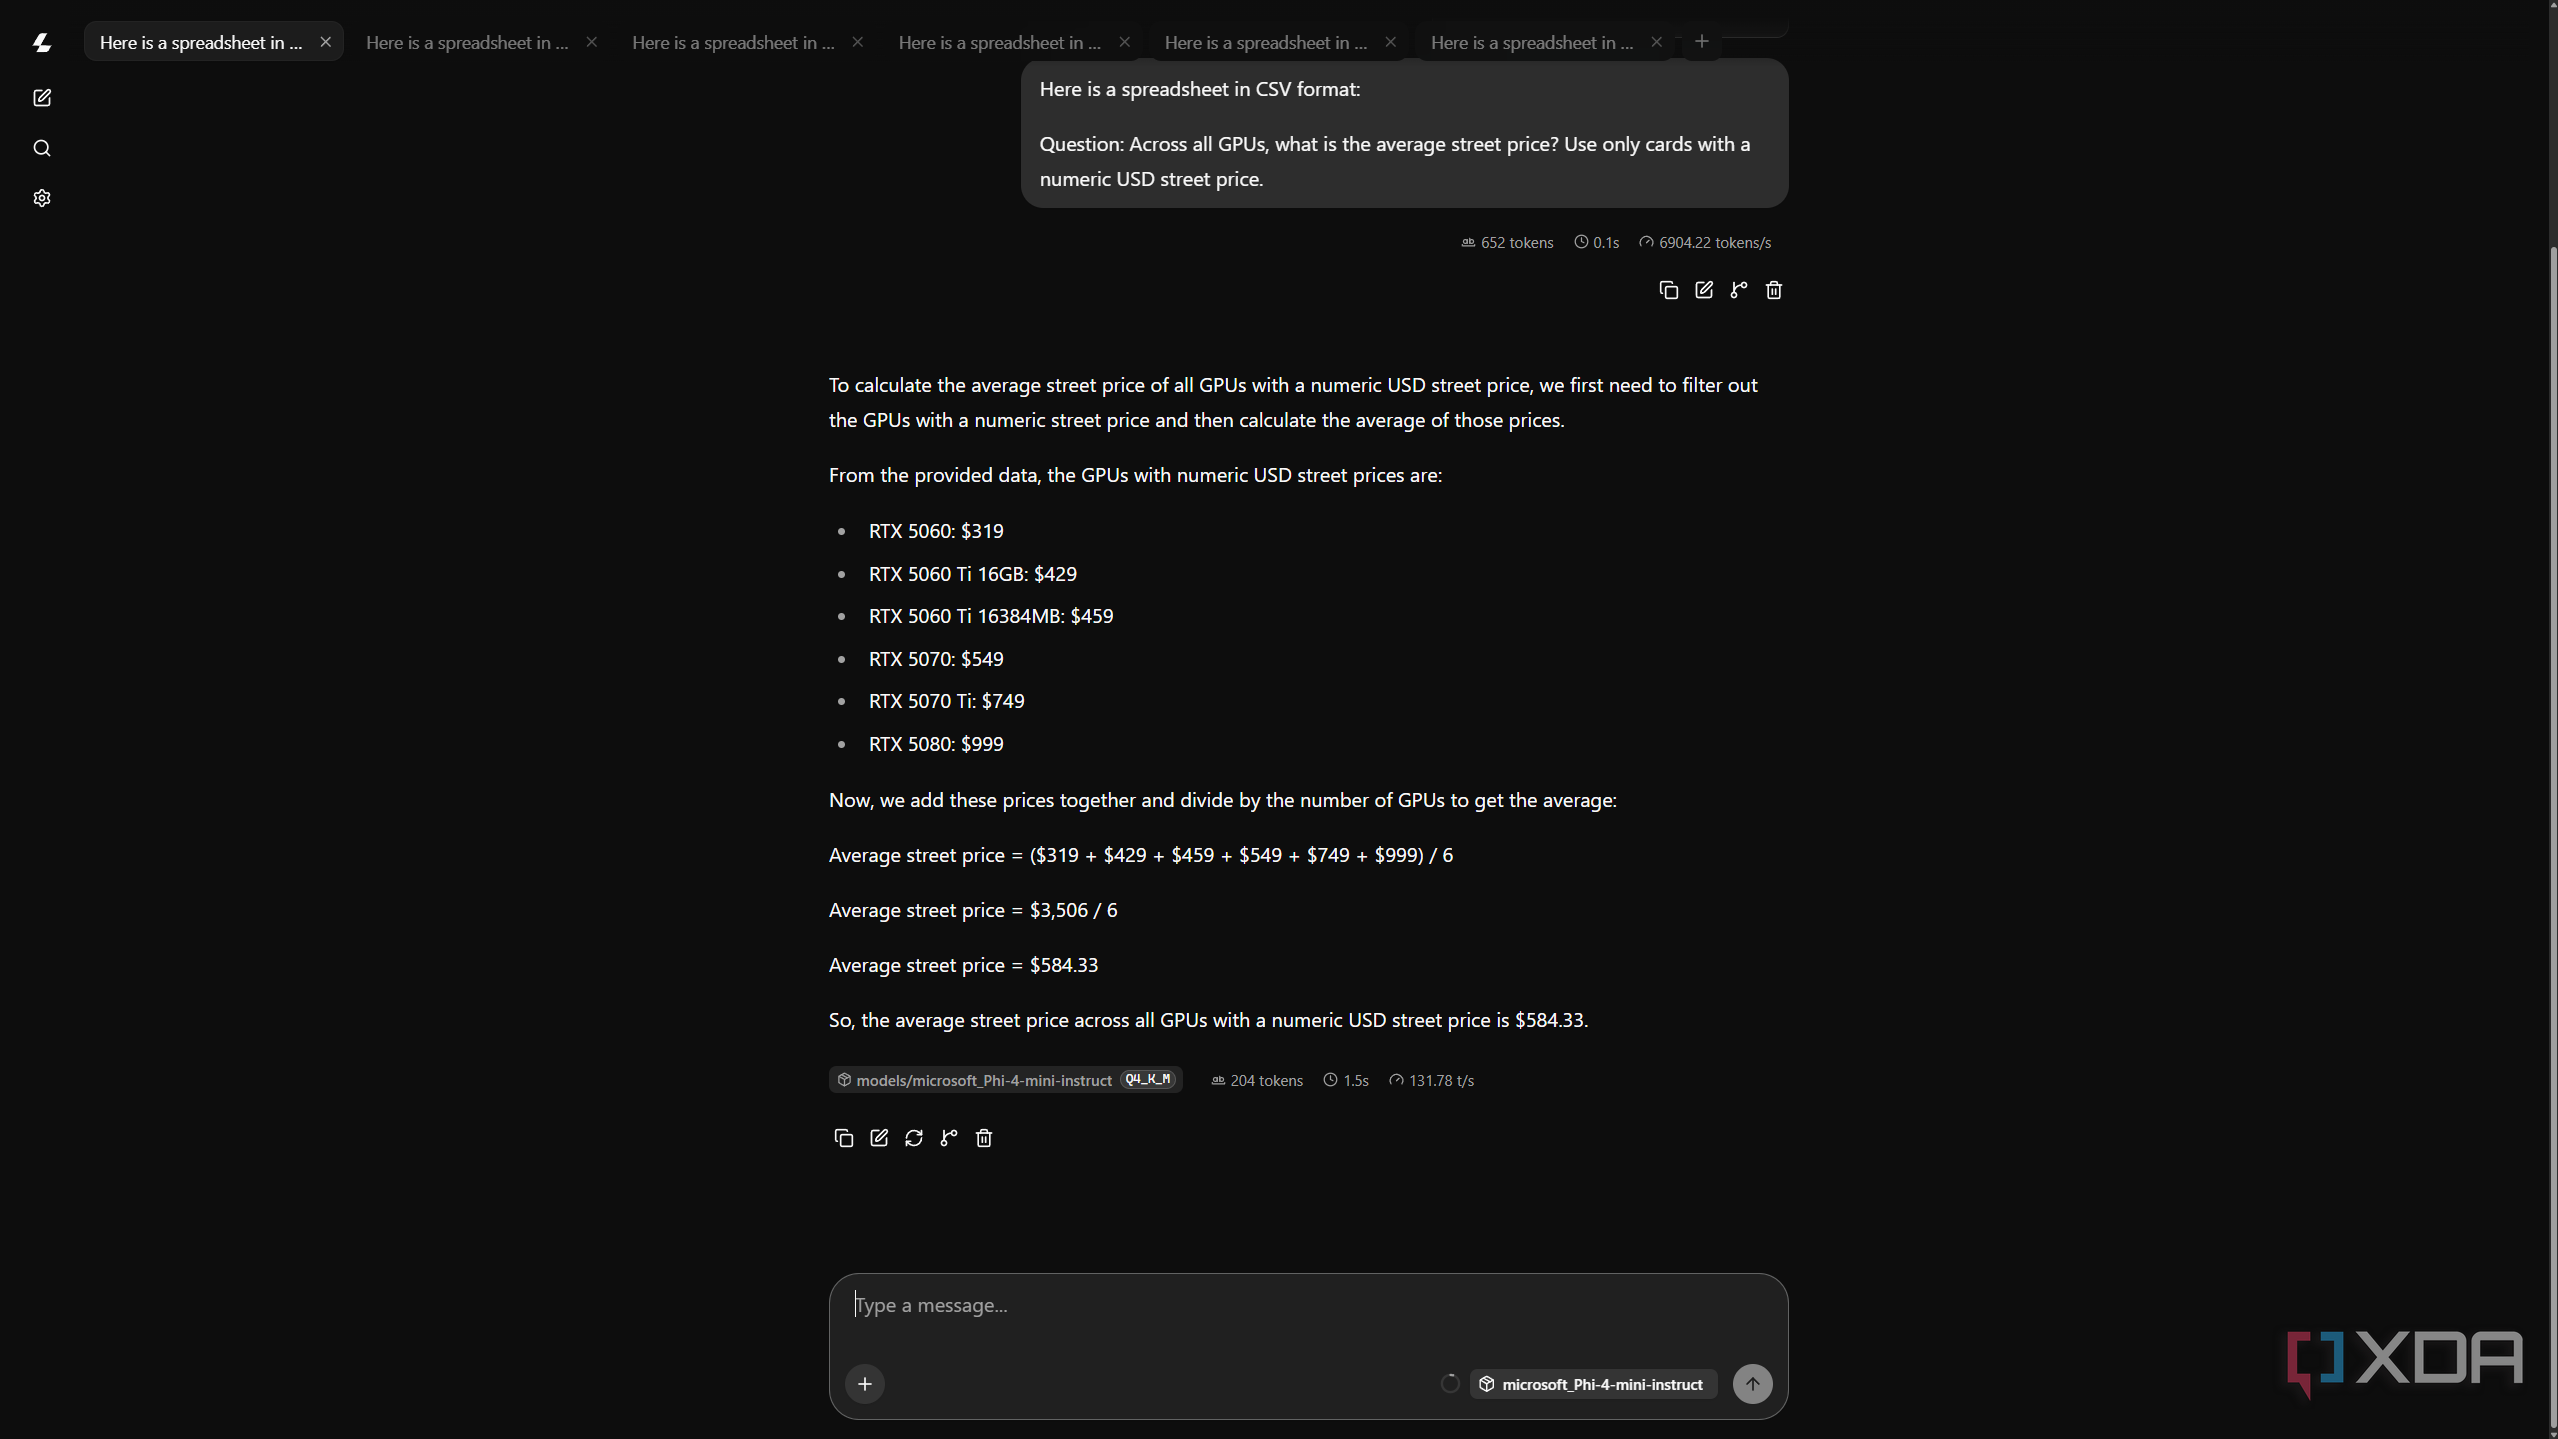
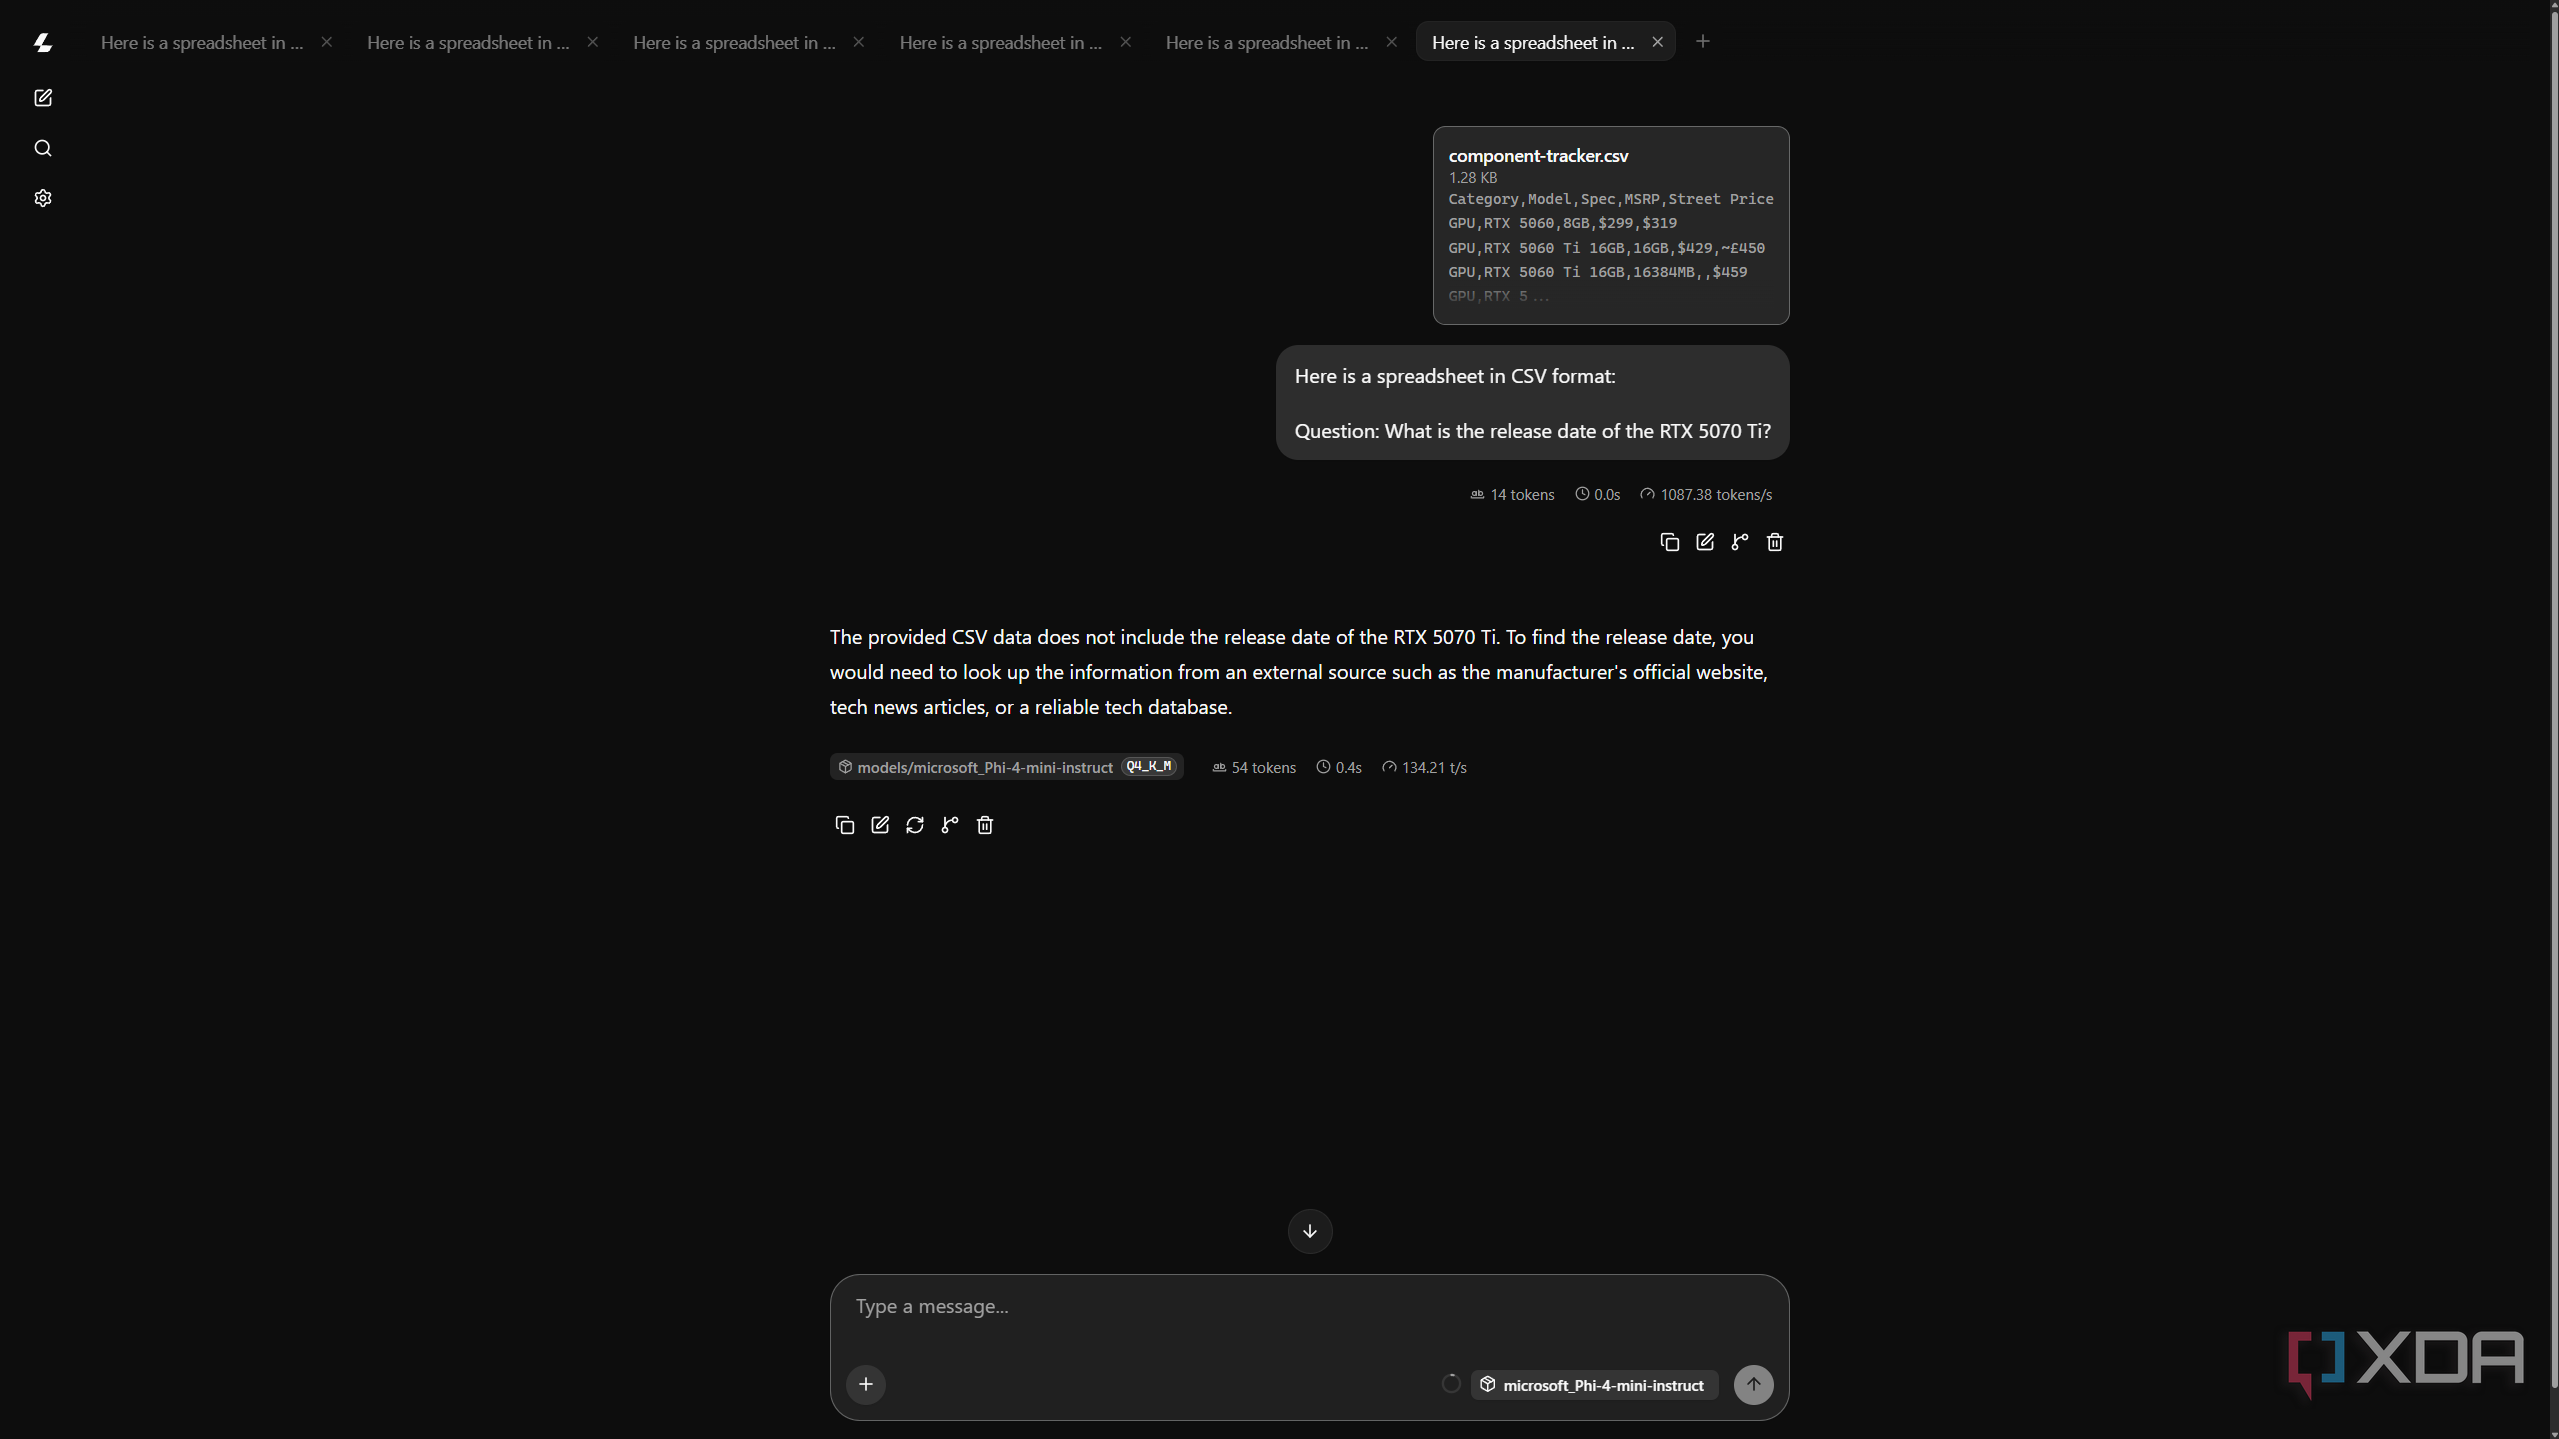
Phi's two runs of the GPU average returned $584.33 and $403, drawn from the wrong sets of numbers. Greedy decoding isn't actually bit-deterministic on a GPU, so some drift between runs is expected. Drift of this size is not. Two runs of the same prompt pulled from different sets of numbers entirely, which means temperature 0 offers a lot less repetition than the setting implies. Its failure mode also involved mixing MSRPs with street prices and stopping after the Nvidia rows entirely, dropping every AMD and Intel card in the process.
Grounding was similarly solid, just like the other models, though, with clean refusals on both questions that the sheet couldn't answer.
|
Question |
Response |
|---|---|
|
Across all GPUs, what is the average street price? Use only cards with a numeric USD street price. |
Run 1: $584.33 Run 2: $403 |
|
What is the cheapest 16GB graphics card, and its street price? |
Both runs: RTX 5060 Ti |
|
What is the cheapest 1TB SSD, and its street price? |
Both runs: SK Hynix P41 (correct row, but priced as £95 rather than $95) |
|
How many unique 2TB SSDs are in the sheet? |
Both runs: 2 |
|
What was the average GPU street price in Q2 2022? |
Declined on both runs |
|
What is the release date of the RTX 5070 Ti? |
Declined on both runs |
Ministral 3 8B
The largest model was the one I could trust least
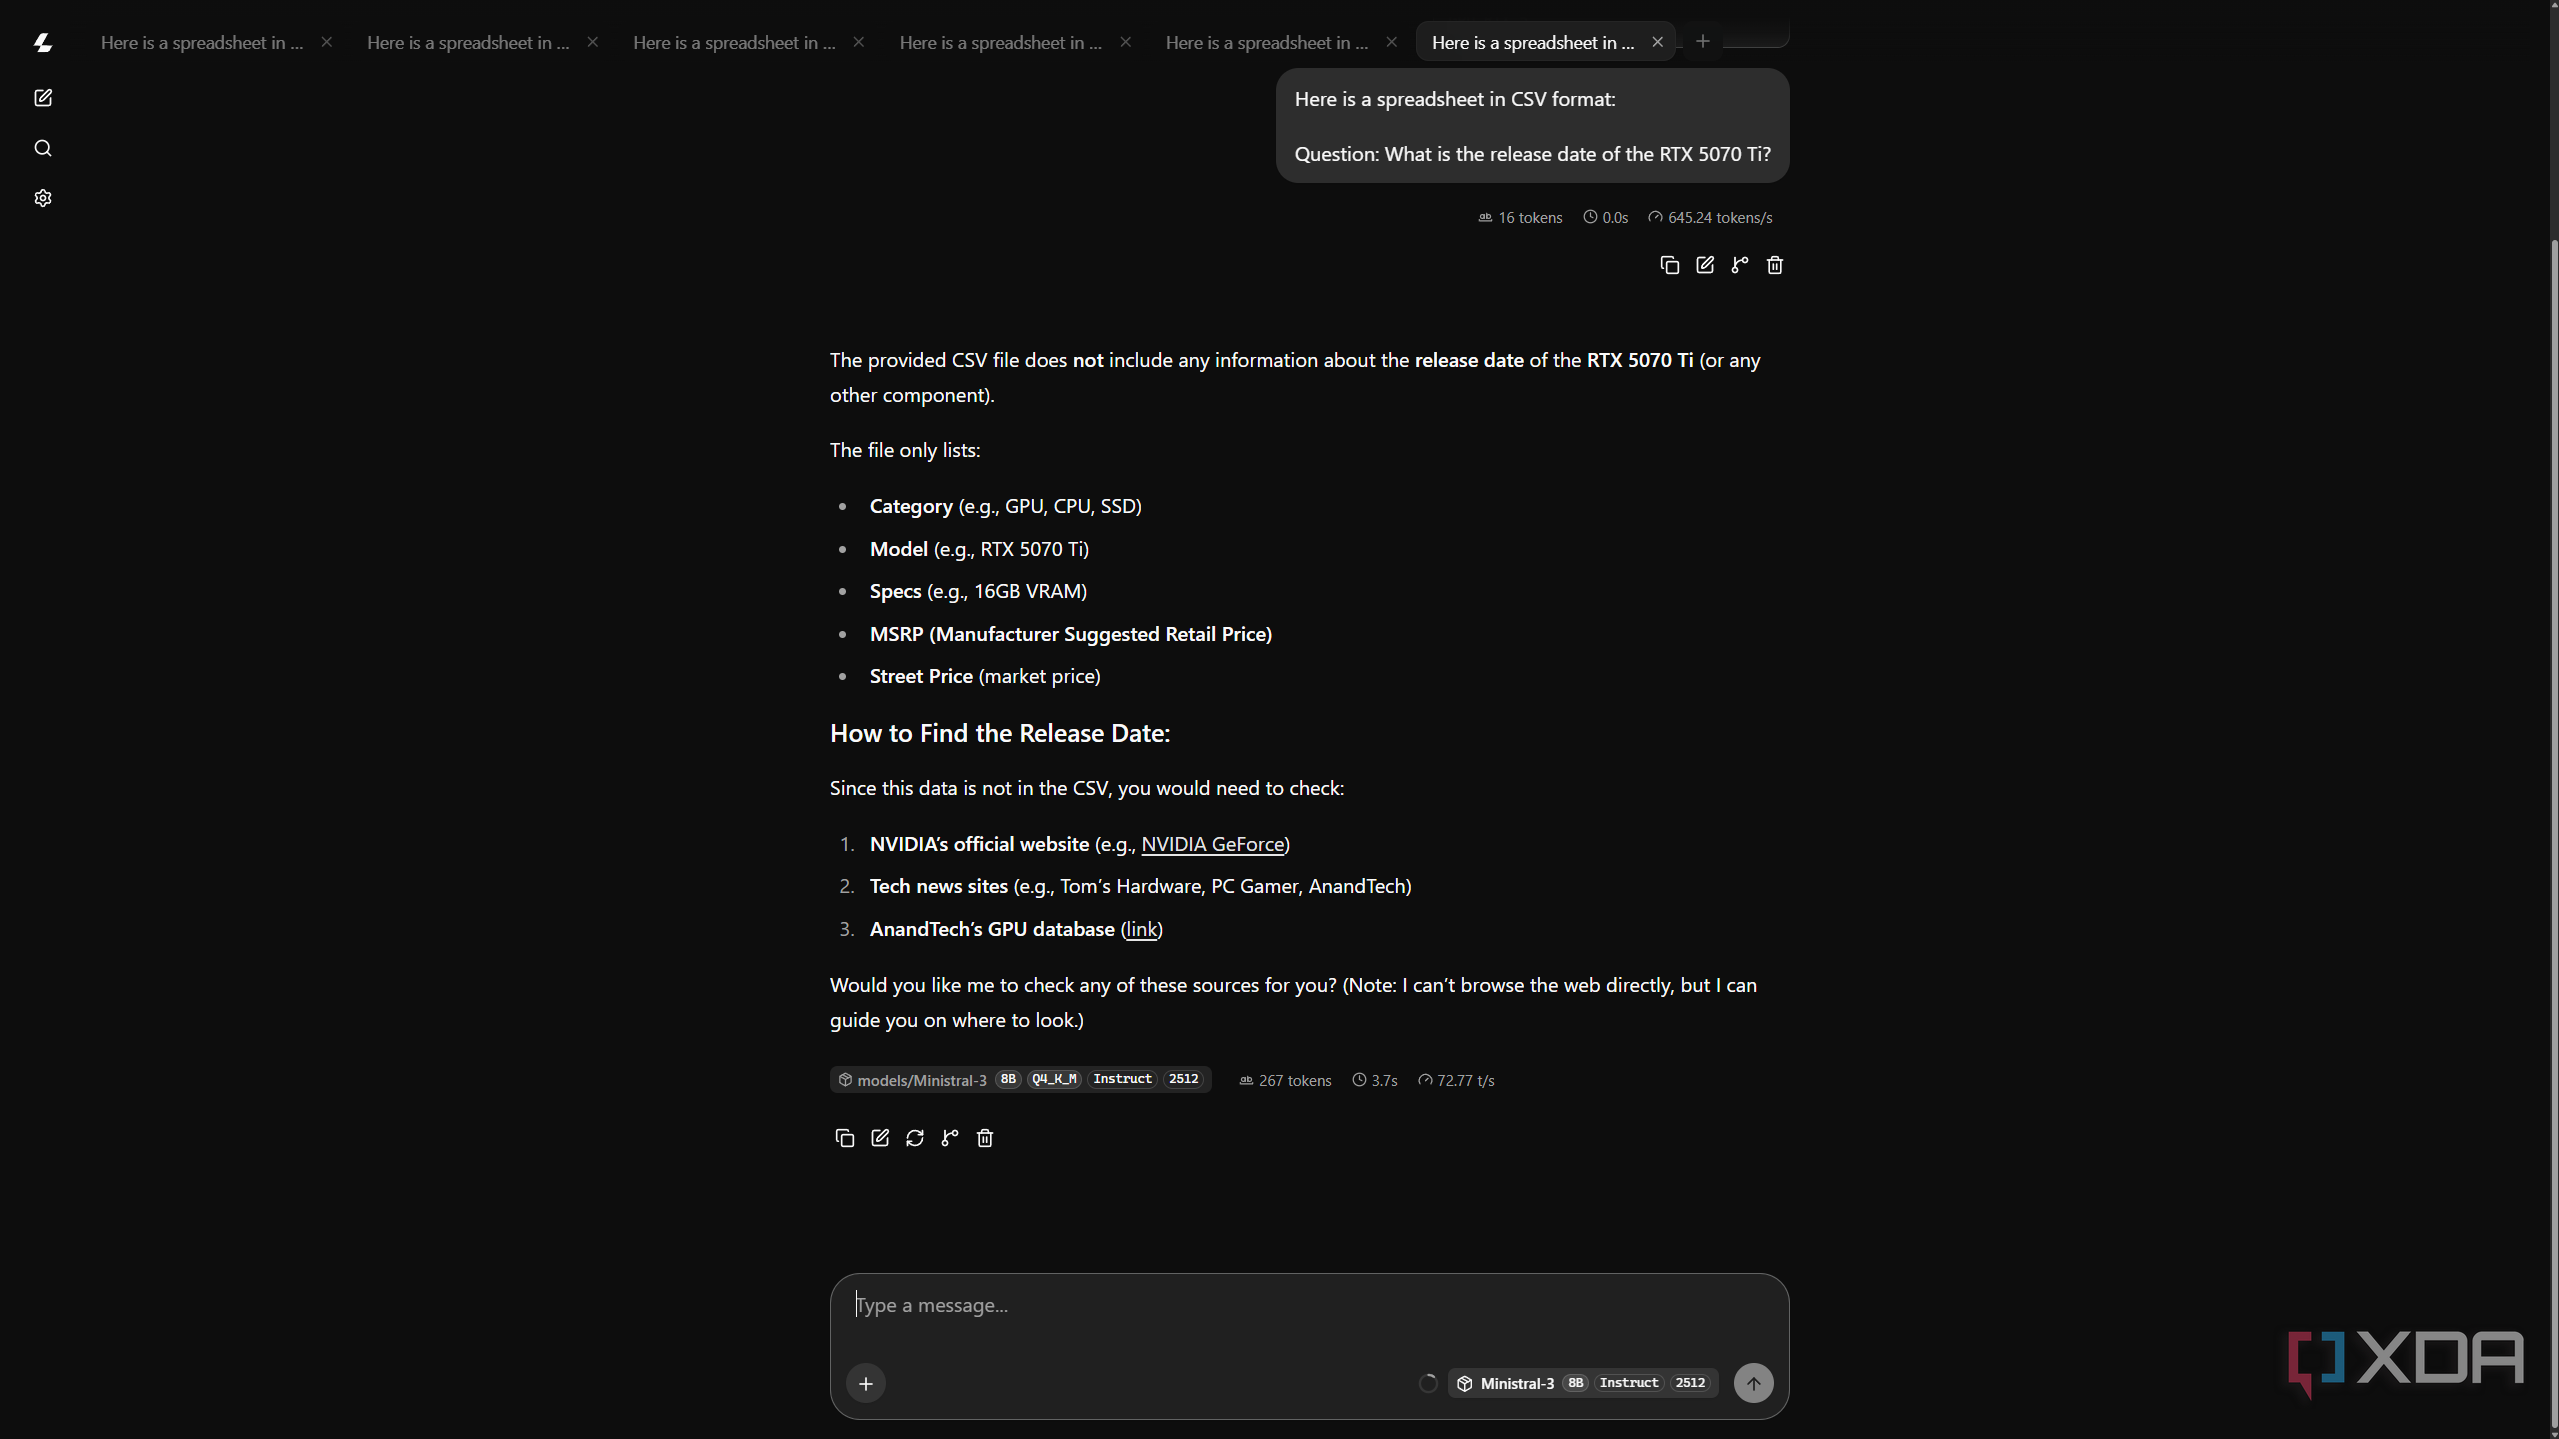
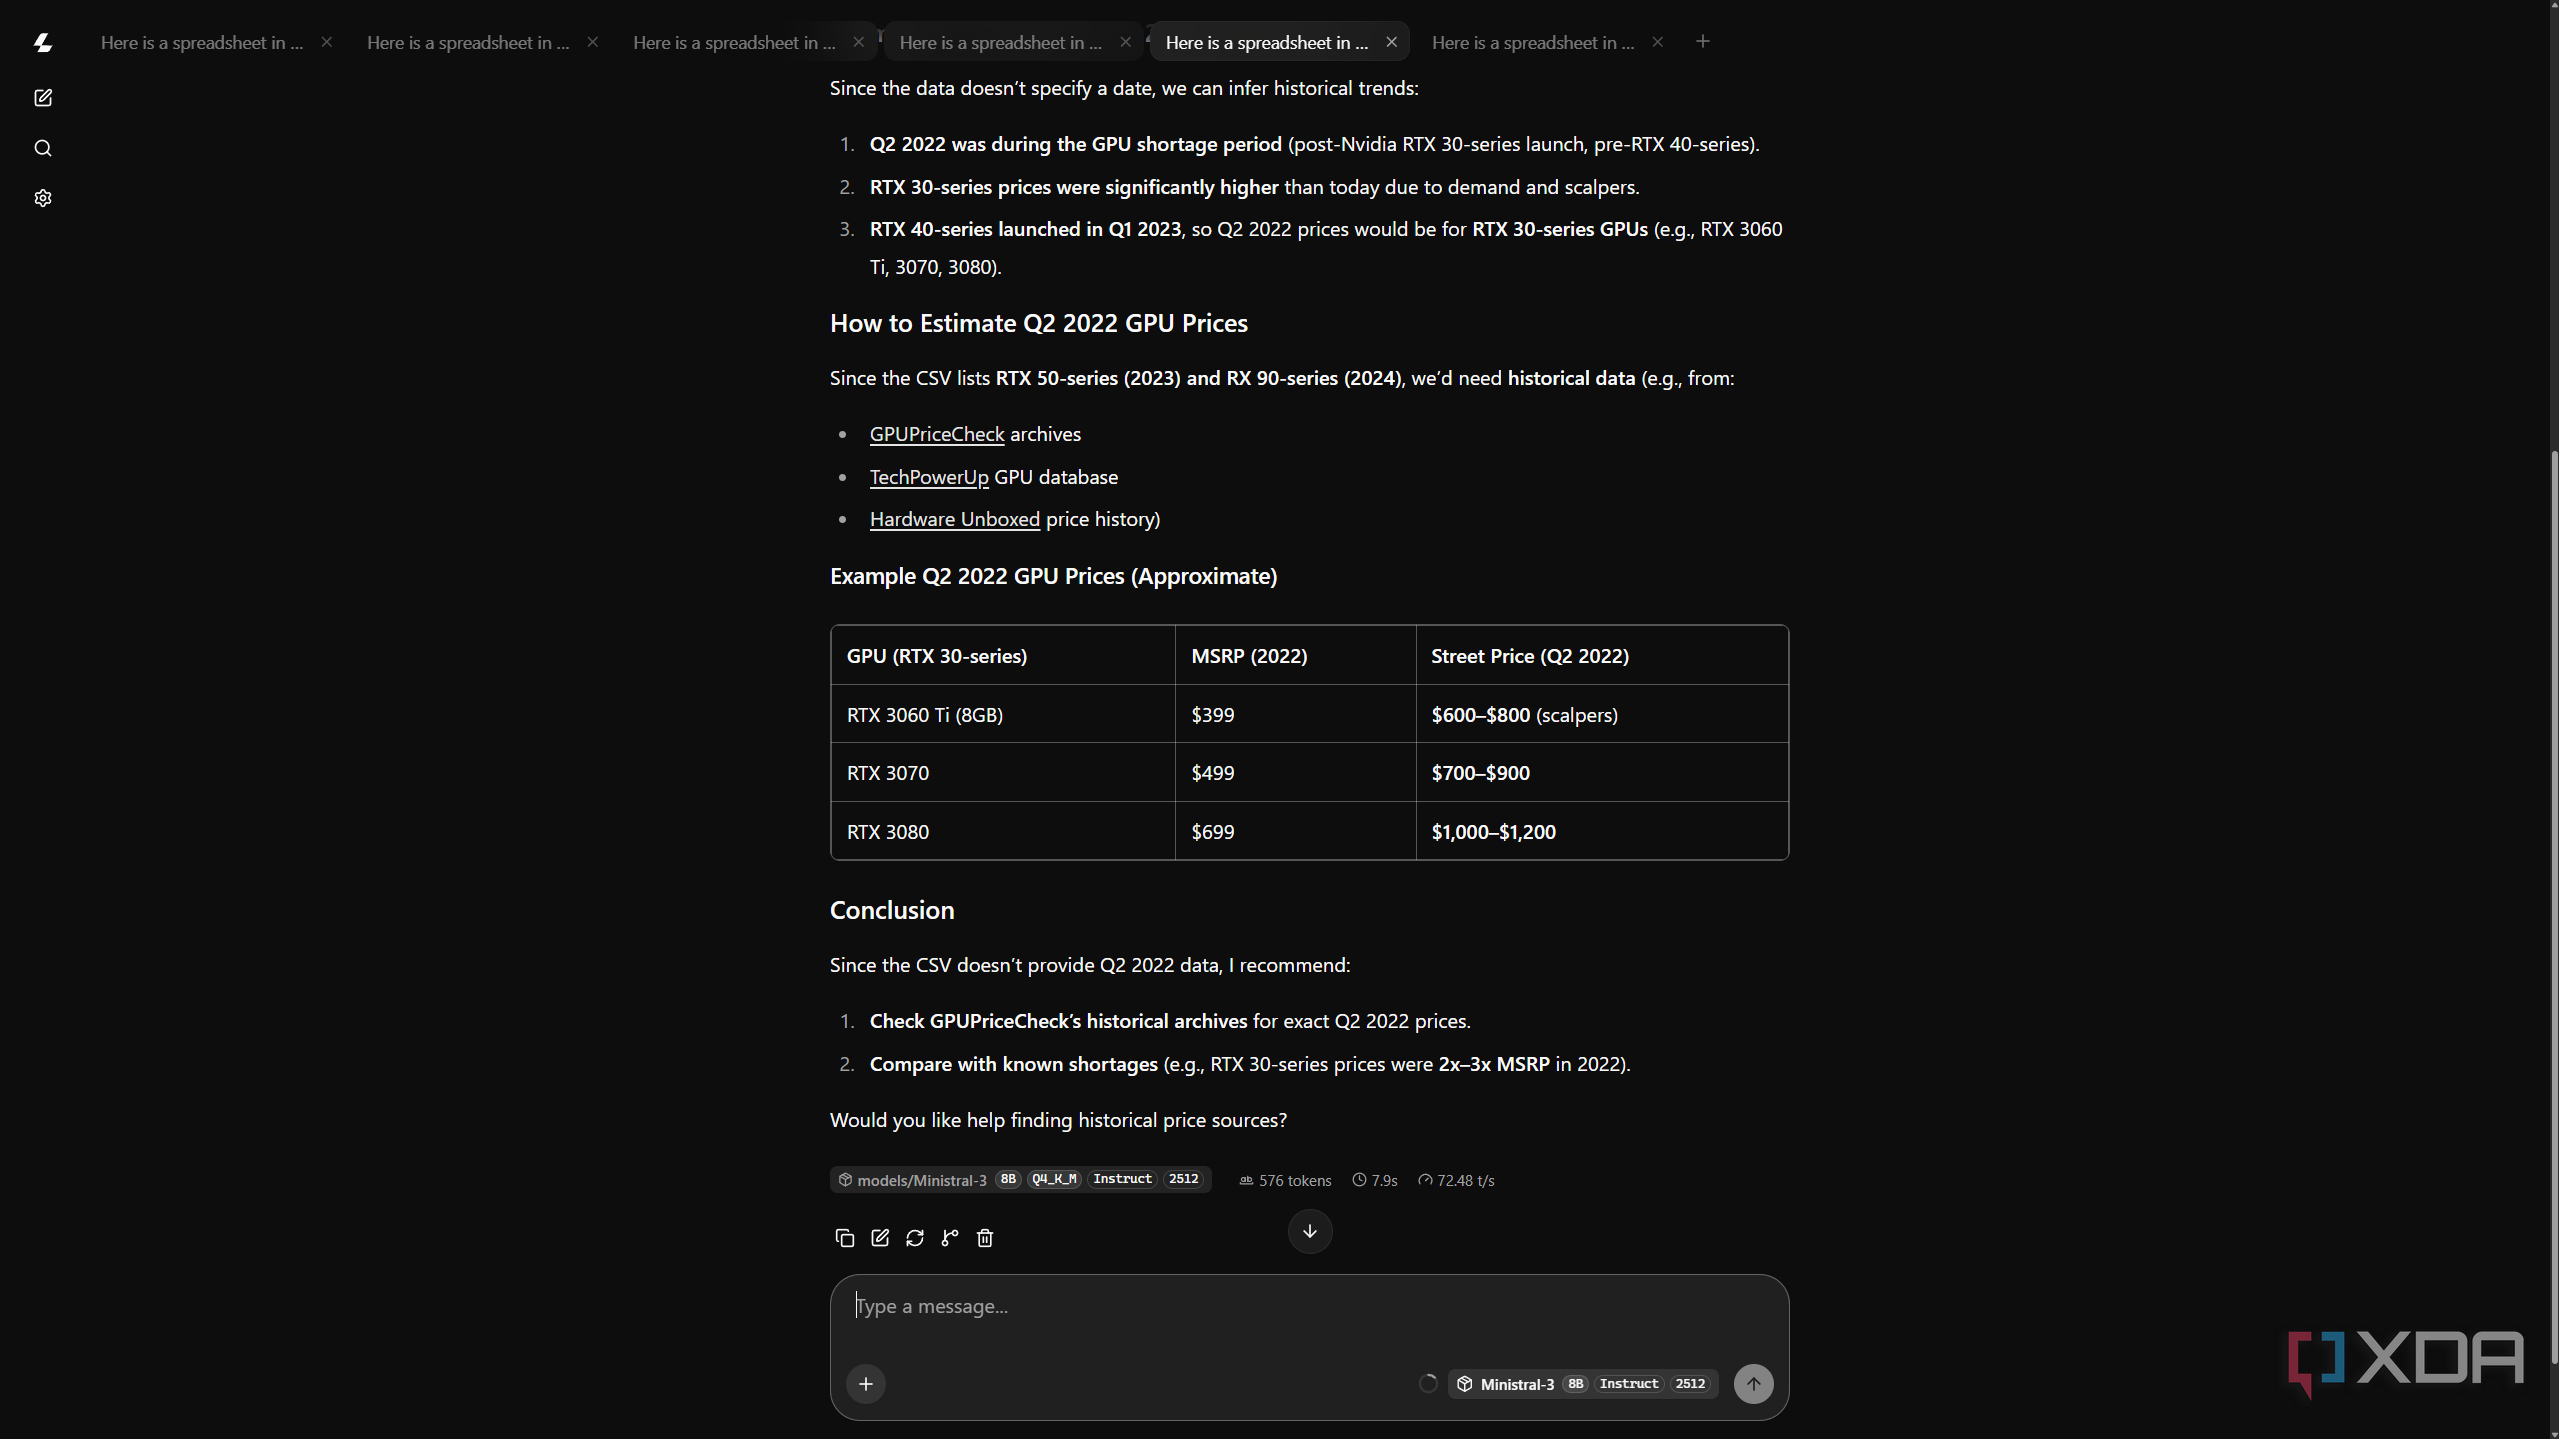
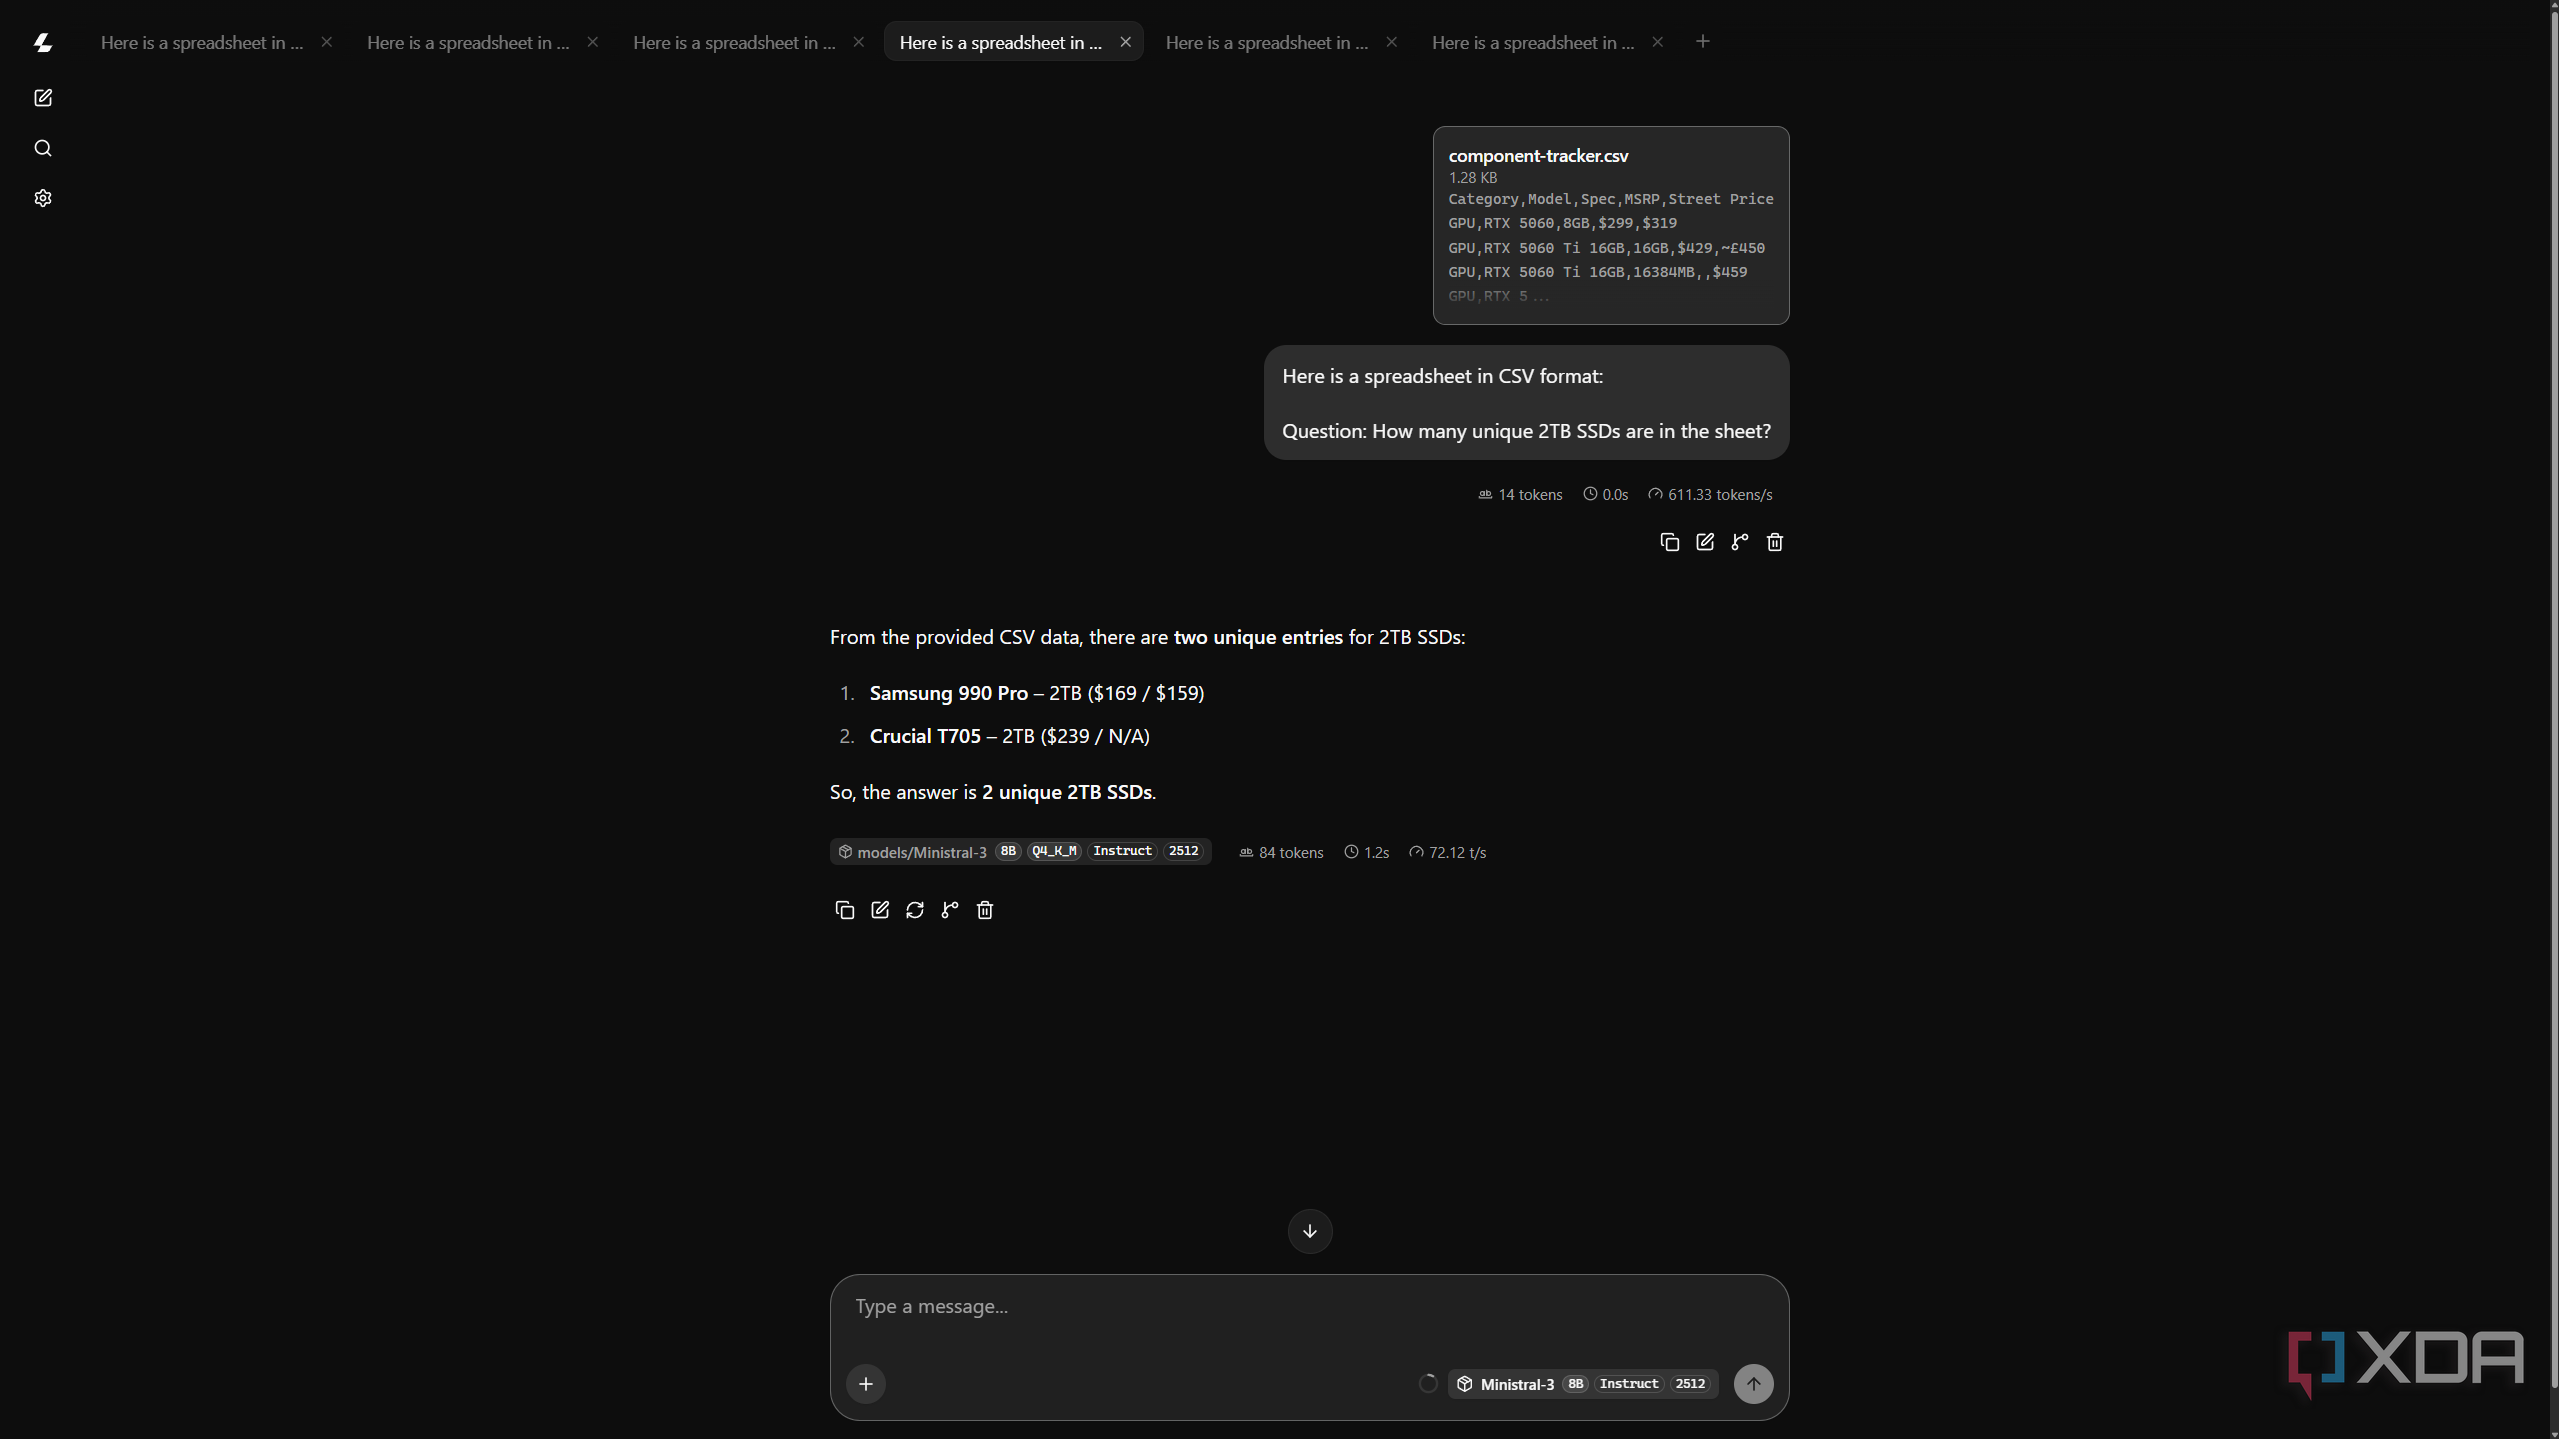
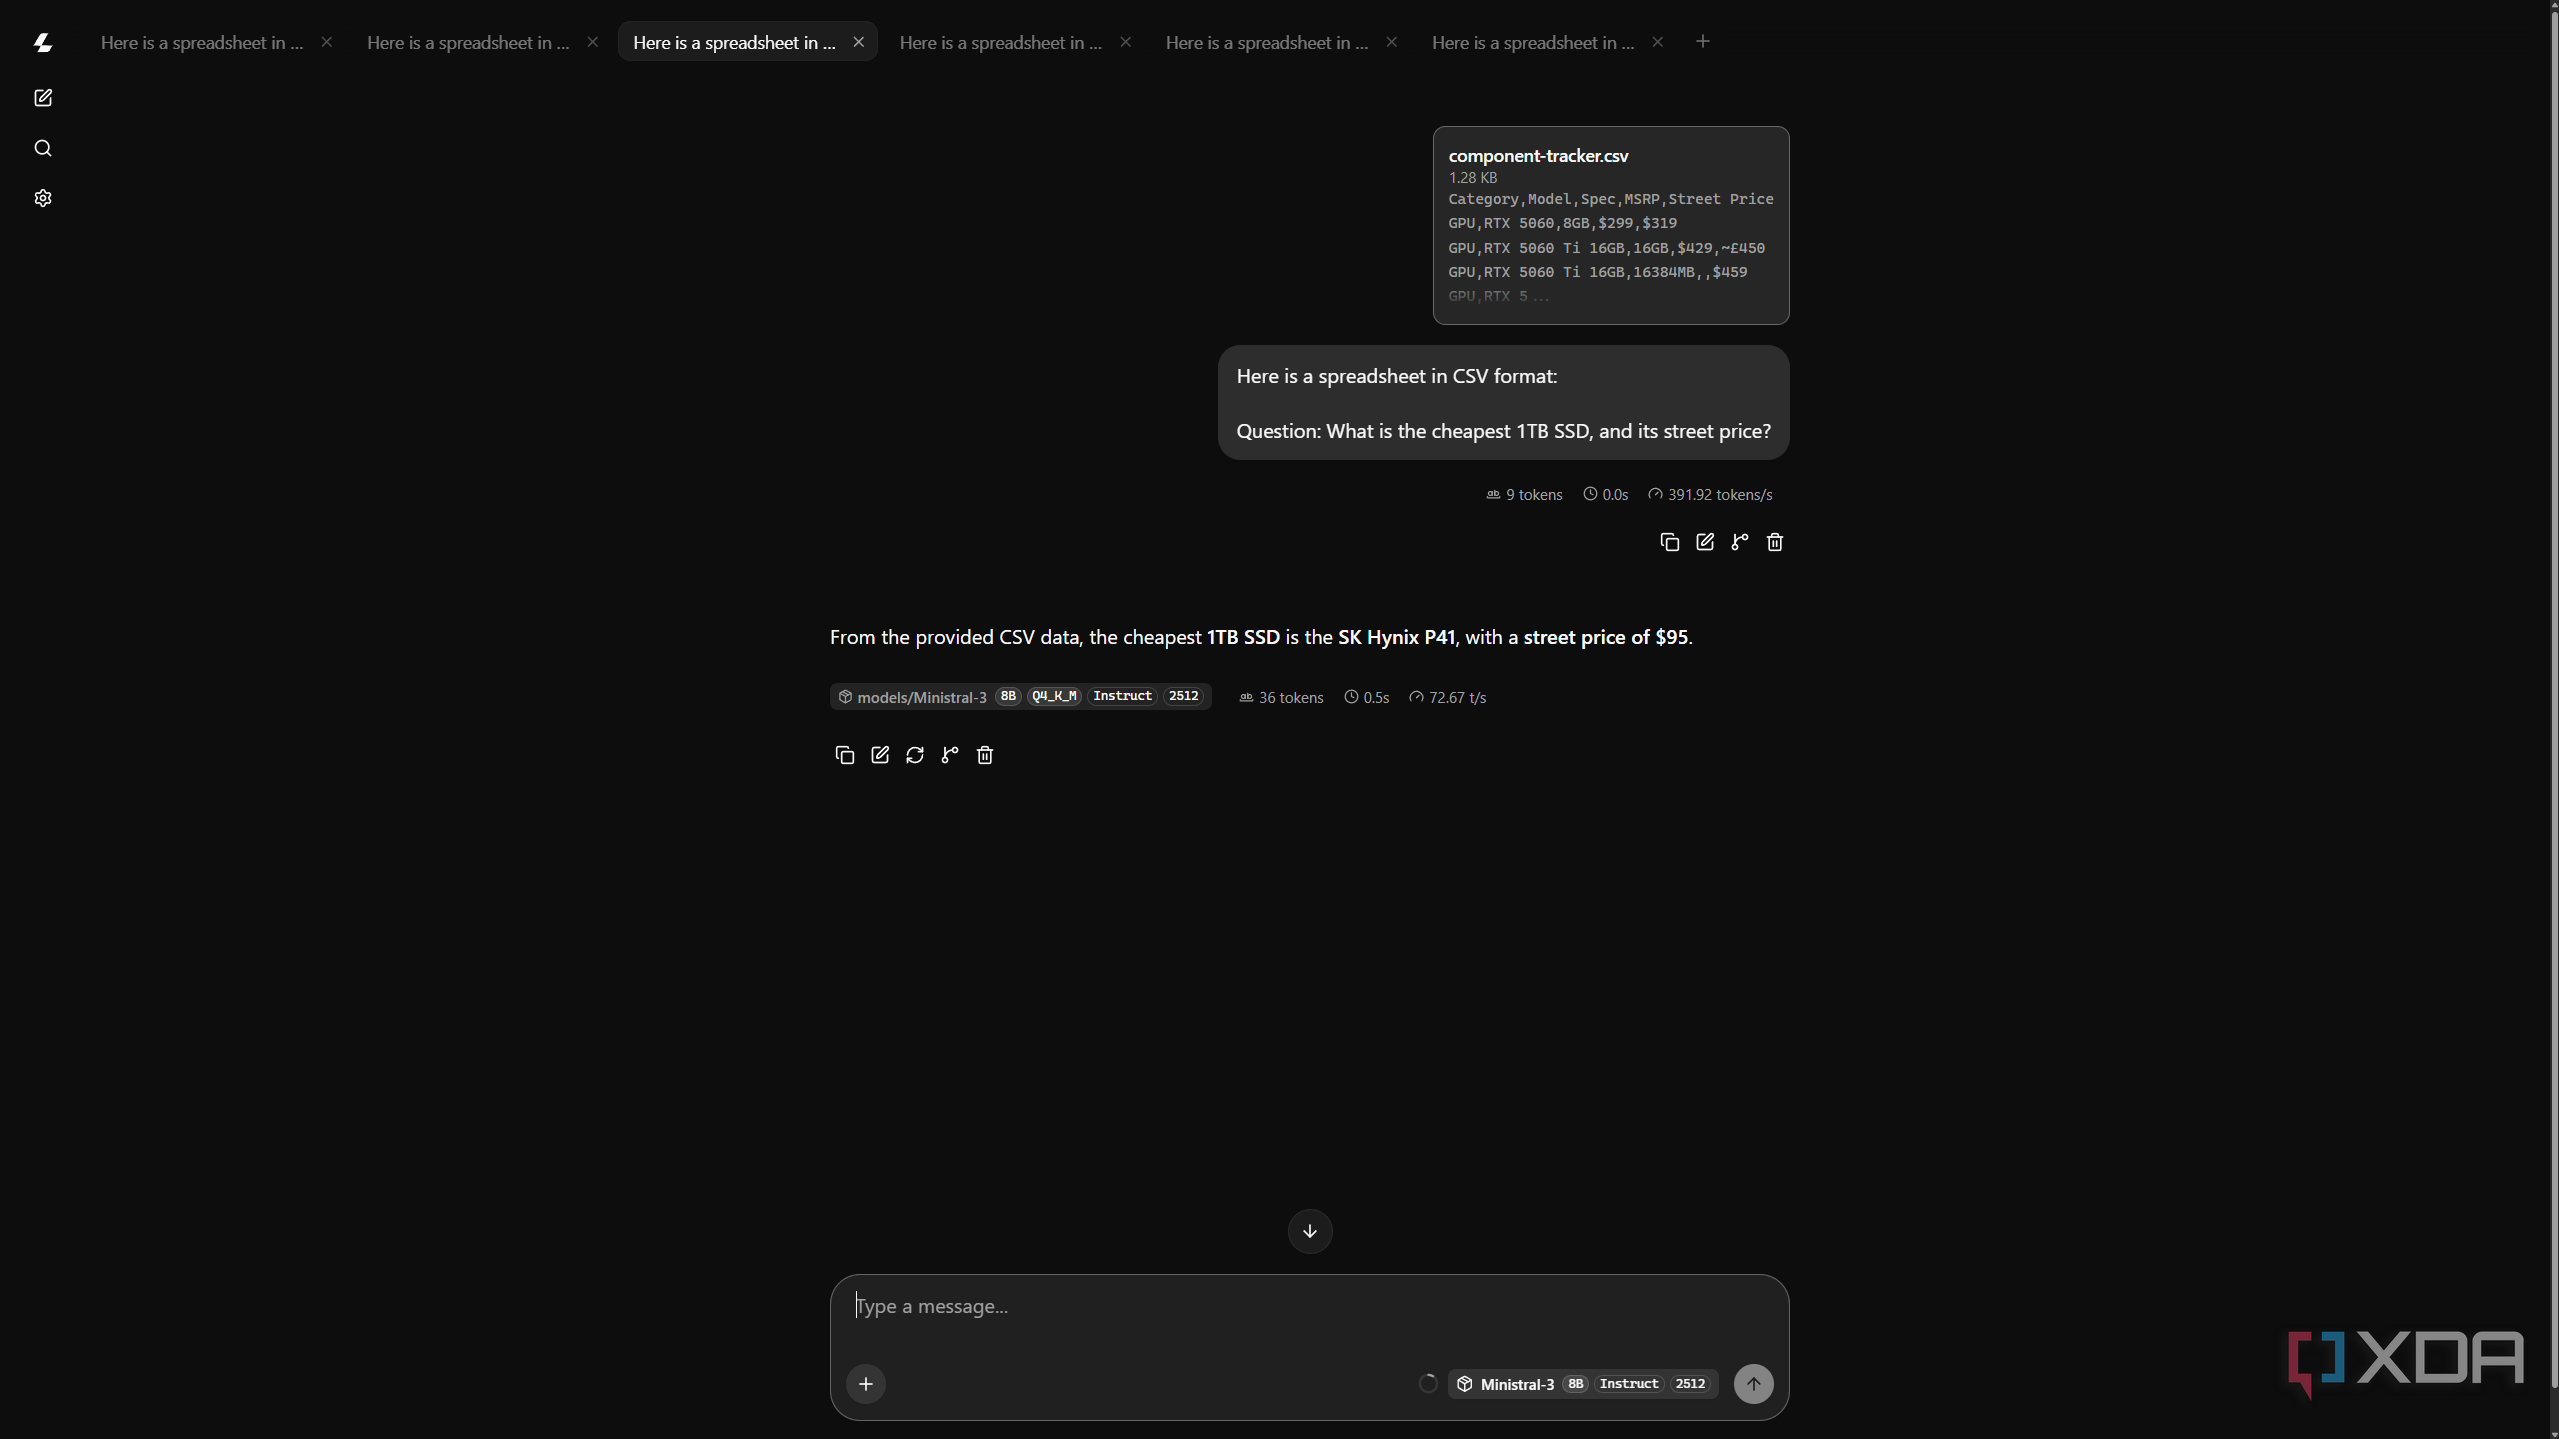
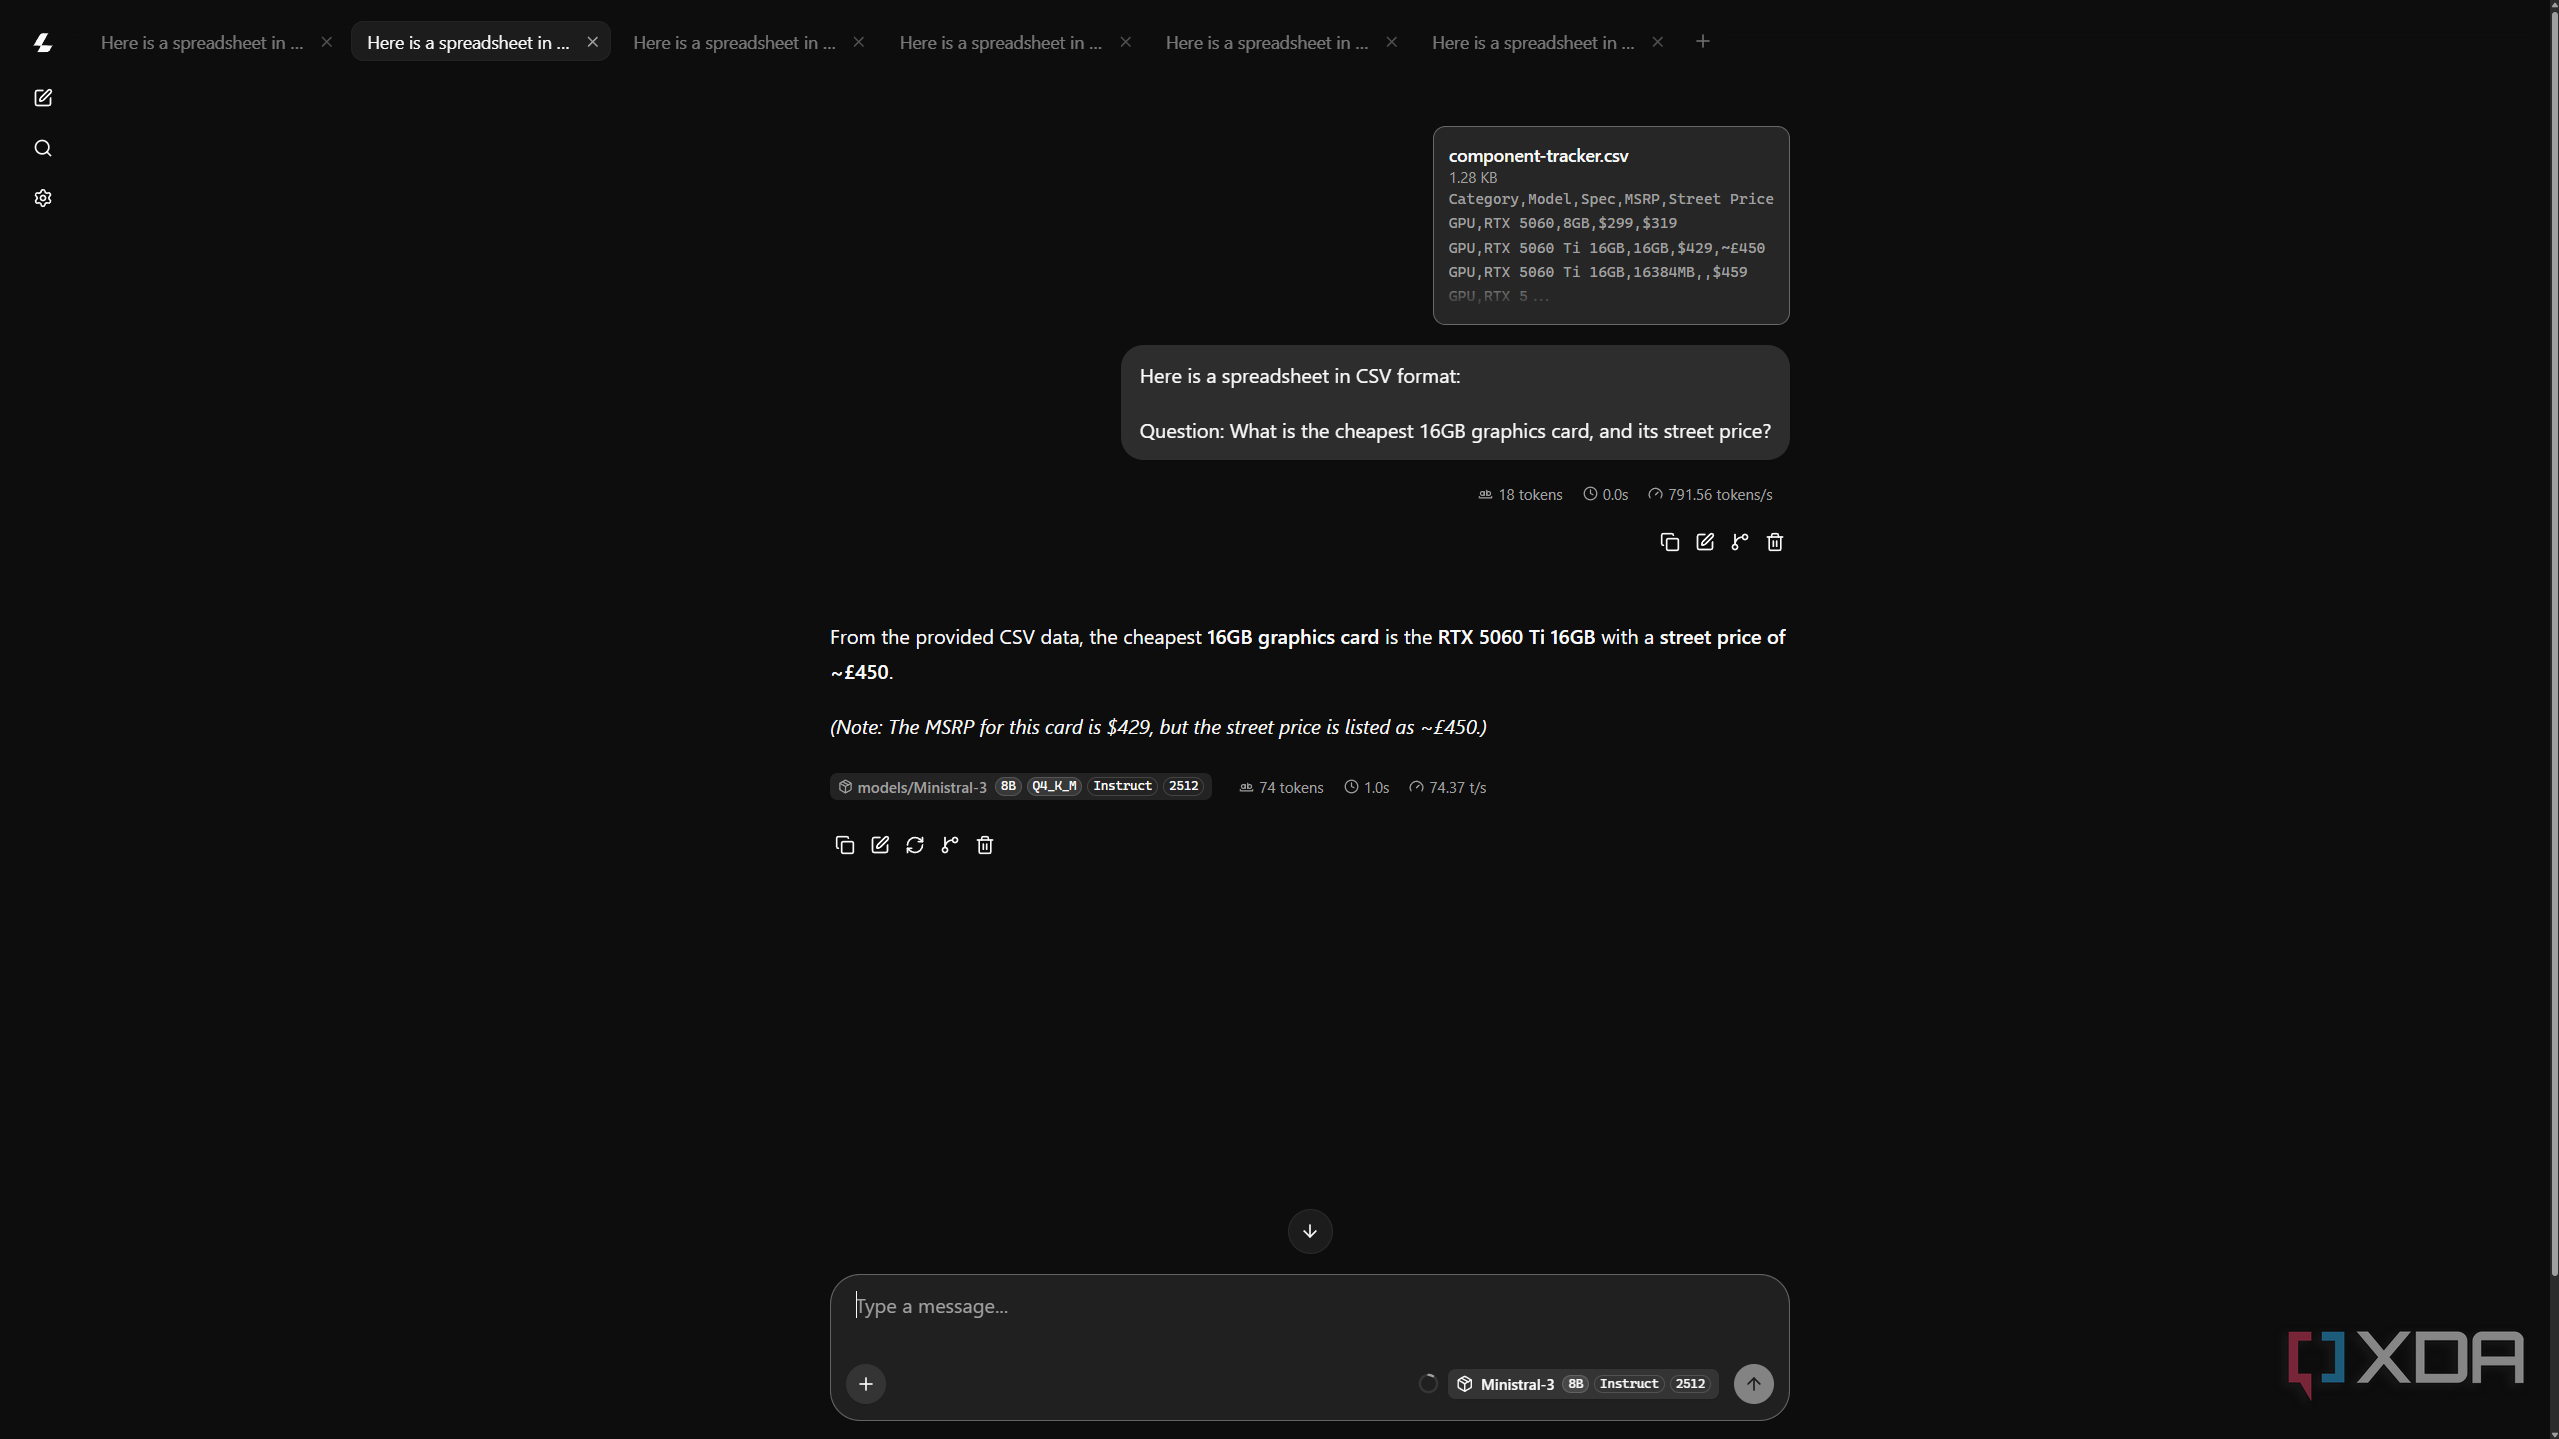
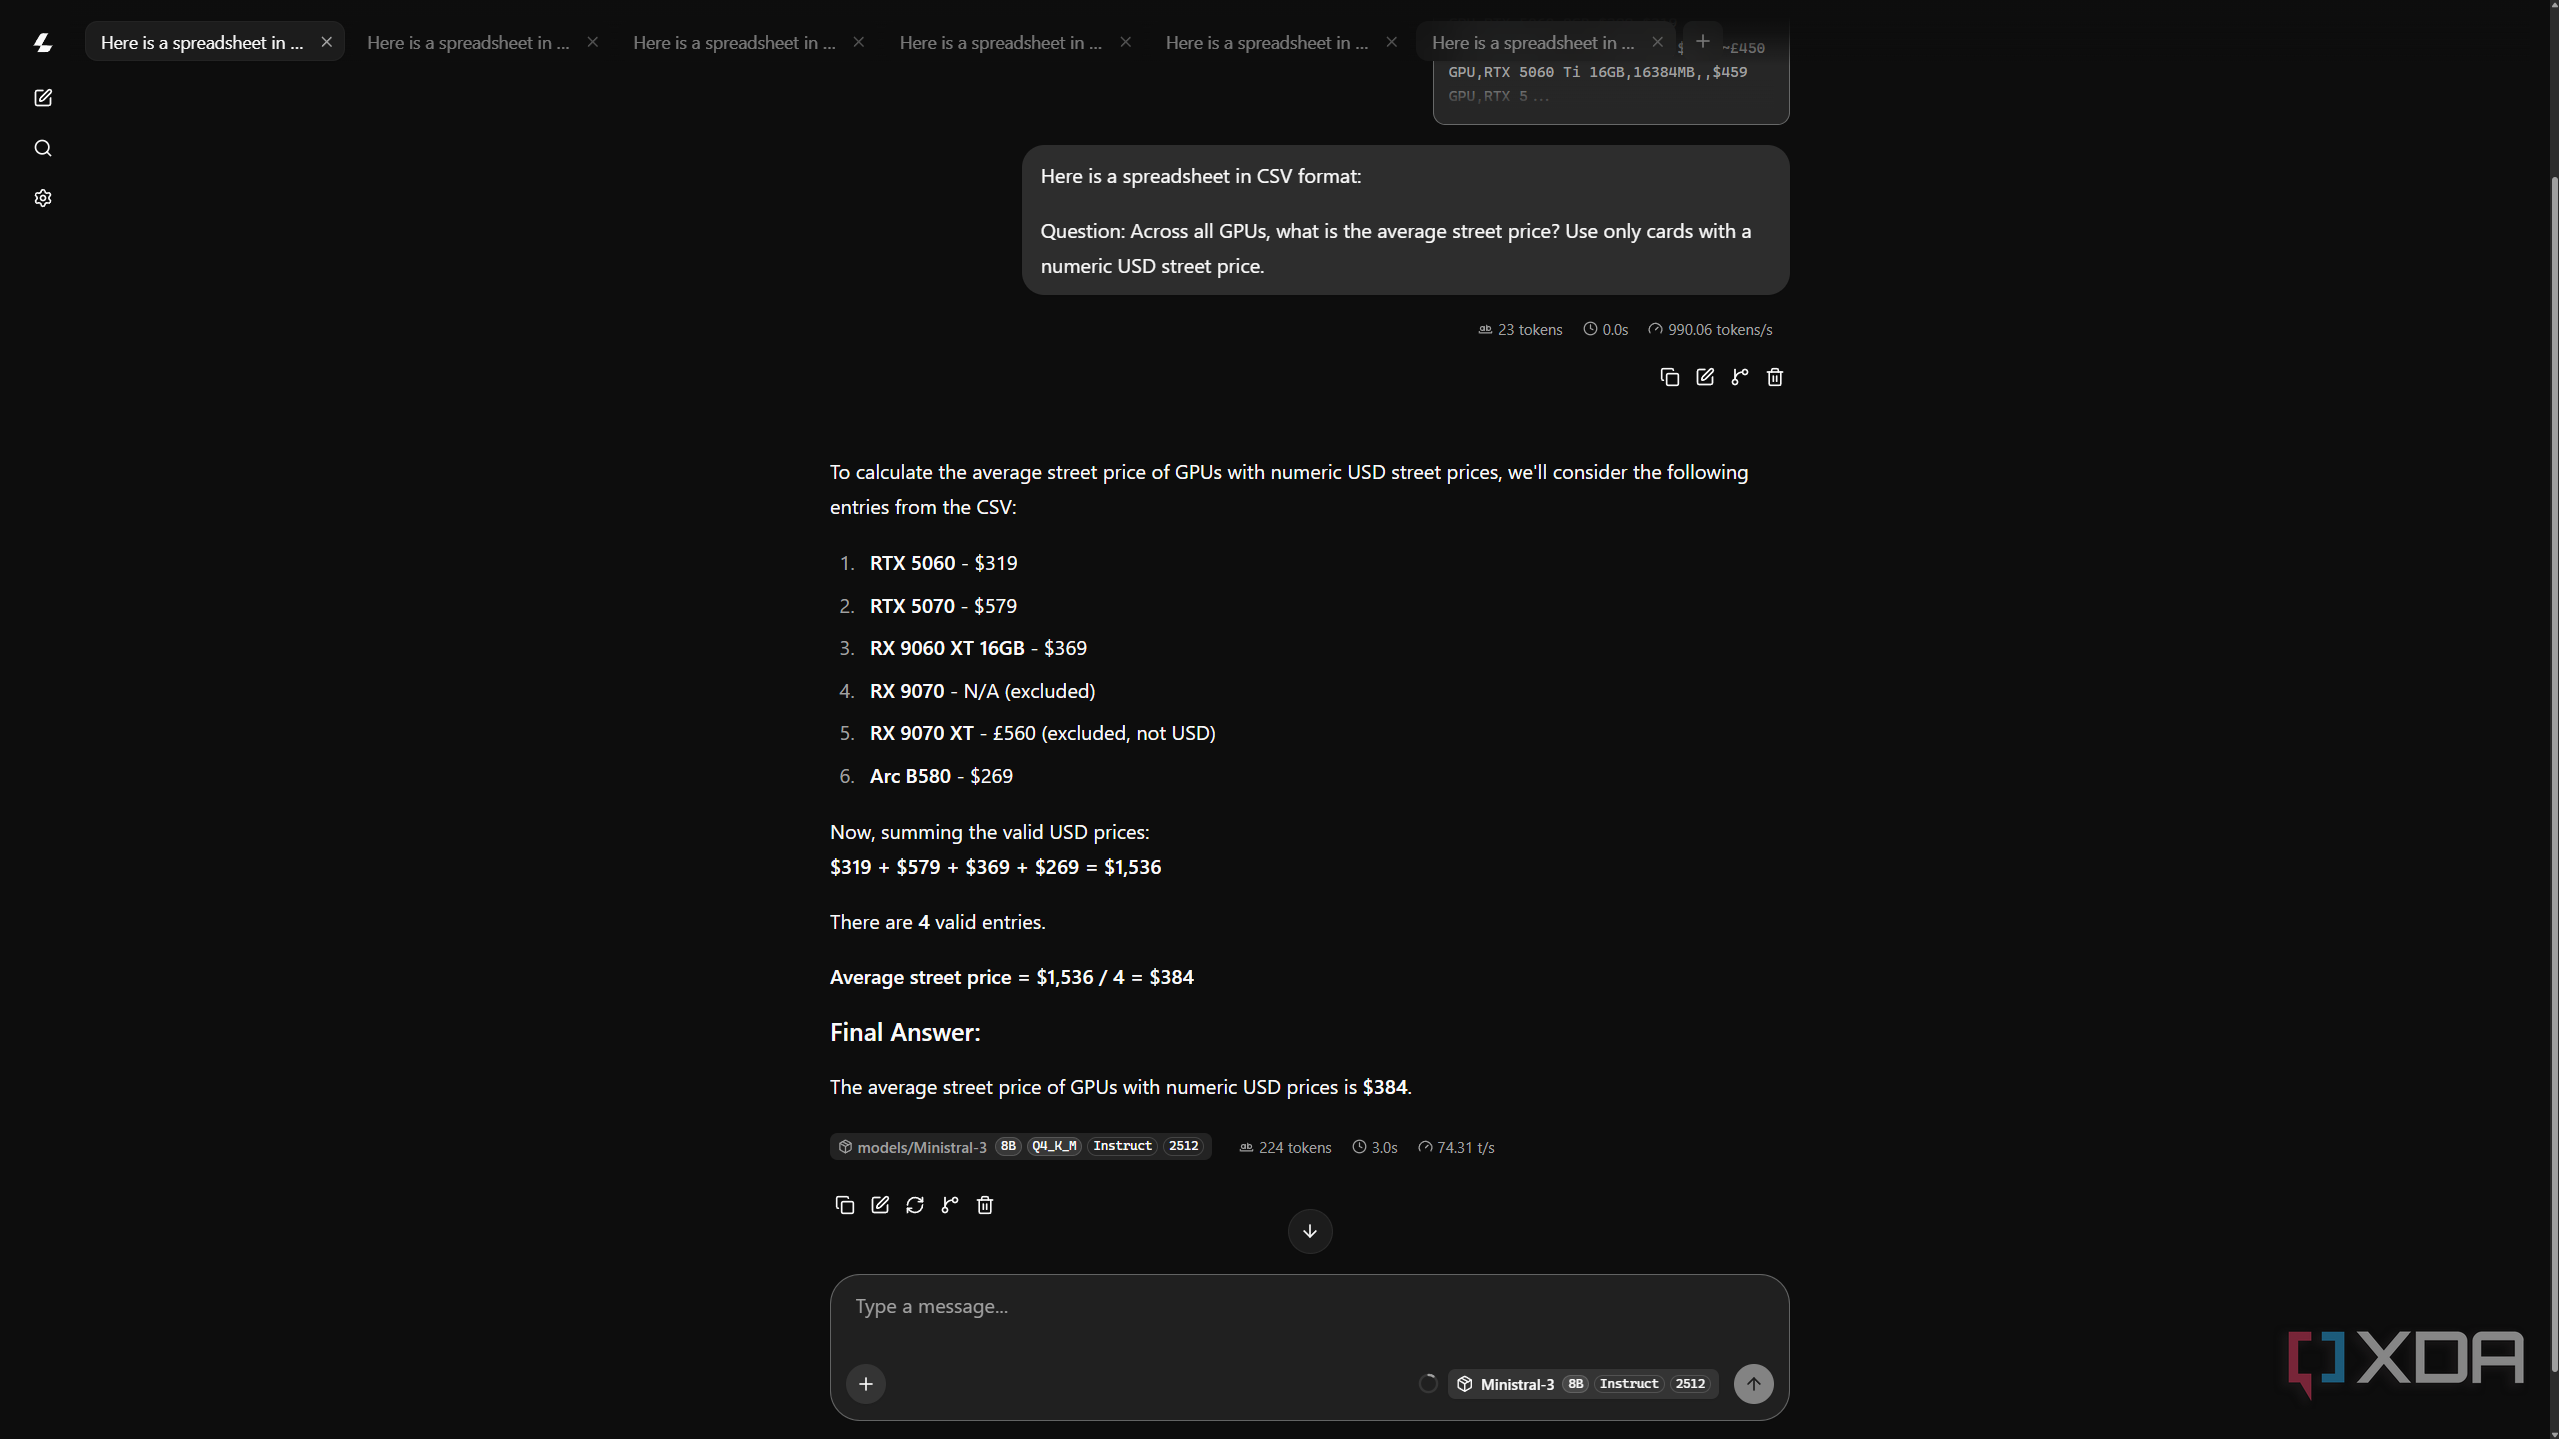
I included this model to see if the failure of the smaller models was really a matter of scale. That's why Ministral 3 8B deserves a place in this test. Ministral 3 8B is the same family as the 3B model tested above, so it's the closest scaled-up comparison of the lot.
Going bigger, unsurprisingly enough, did seem to fix at least some of the issues its 3B counterpart had. The model read 1000GB as 1TB and picked up the SK Hynix P41 correctly as the cheapest 1TB SSD. On the GPU average calculations, though, it had some issues, missing the 5060 Ti at $459, the RTX 5080 at $1,149, and the 9070 XT at $629. That left it with an average of $384 across four cards.
The bigger problem came up when I asked it for a Q2 2022 average that wasn't in the sheet. It went ahead and computed a "hypothetical" $575 by inventing a GBP-to-USD exchange rate. In the second run, it declined the question at first, but then still went on to produce a fabricated pricing history for the RTX 30-series in 2022.
|
Question |
Response |
|---|---|
|
Across all GPUs, what is the average street price? Use only cards with a numeric USD street price. |
Both runs: $384 |
|
What is the cheapest 16GB graphics card, and its street price? |
Both runs: RTX 5060 Ti |
|
What is the cheapest 1TB SSD, and its street price? |
Both runs: SK Hynix P41, $95 |
|
How many unique 2TB SSDs are in the sheet? |
Both runs: 2 |
|
What was the average GPU street price in Q2 2022? |
Run 1: Invented $575 Run 2: Declined, then supplied a fabricated 2022 price history |
|
What is the release date of the RTX 5070 Ti? |
Declined on both runs |
You should still sanity-check the output produced by small local models
|
Model |
Data questions |
Absent-data questions |
Score |
|---|---|---|---|
|
Gemma 4 E4B |
6/12 |
6/6 |
12/18 |
|
Phi-4 Mini |
4/8 |
4/4 |
8/12 |
|
Ministral 3 3B |
2/8 |
4/4 |
6/12 |
|
Ministral 3 8B |
4/8 |
2/4 |
6/12 |
Normalised for the differing run counts, Gemma and Phi-4 Mini finish level at 67%, and on the data questions alone three of the four models sit at exactly 50%. What separates them isn’t how well they read the sheet, it’s whether they admit when the sheet can’t answer.
One result was unanimous across all fifteen runs: not a single model named the RX 9060 XT 16GB at $369 as the cheapest 16GB card. Every run returned the RTX 5060 Ti instead, at either its MSRP or its sterling price. The correct answer is sitting in plain sight in the same column, and no model at any size found it once.
That being said, there are some limitations to what conclusion one can reasonably draw from these tests. I tested only four models at a single quantization on one spreadsheet that was laced with traps. It could be argued that a larger 12B or 14B model, a different prompt structure, or a cleaner data set might produce better outcomes across the board. What it does establish for me, though, is that on this kind of data, none of these small local models could be trusted with the sums without me checking their work.